YouZum

Uncategorized

AI, Committee, 新闻, Uncategorized

The Download: AI’s extinction risk and bioweapons threat

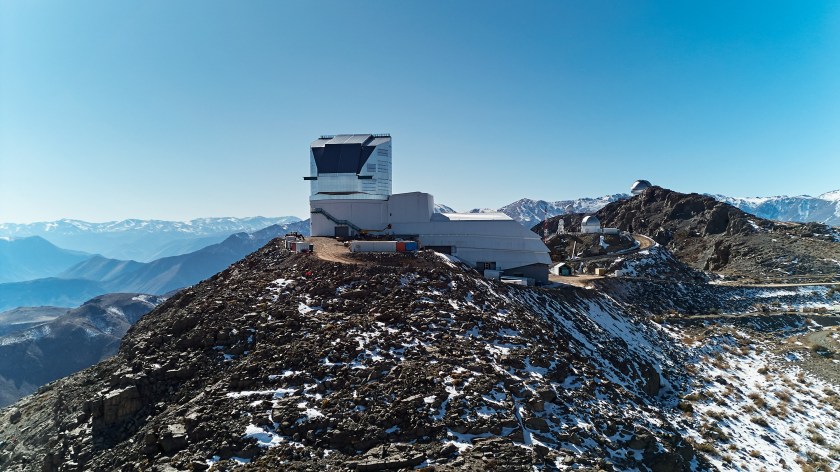
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Could AI really kill us all? Your questions, answered On Wednesday, MIT Technology Review hosted a live Roundtables event that asked the question many seem to be asking right now: could AI really kill us all? But attendees had more questions than we had time to answer, so we asked senior AI editor Will Douglas Heaven and AI reporter Grace Huckins to tackle some of the best ones.  The questions they tried to answer include: am I going to die? Why should AI kill us, if at all? Is AI really dangerous, or is it just tech companies drumming up PR? And what steps can be taken to make sure AI is controlled, monitored and regulated effectively? Here are their responses. —Will Douglas Heaven and Grace Huckins The specter of AI-enabled bioweapons is a wake-up call for biotech One of the ways AI could potentially cause catastrophic harm is by aiding the design and creation of bioweapons. In 2022, researchers found that it was remarkably easy to do this with an AI “molecule generator” built to develop drugs. In less than six hours, the model generated 40,000 molecules that could serve as chemical warfare agents.  Today, AI tools can answer questions on almost every area of science, while advances in gene editing and synthetic biology have made biotech tools more accessible. There are safeguards, but none are ironclad. However, scientists disagree about how serious the risk is anyway. Find out why it’s easier than ever to design killer pathogens. —Jessica Hamzelou This story is from The Checkup, our weekly biotech newsletter. Sign up to receive it in your inbox every Thursday. The role of the astronaut is in flux We go to space for geopolitical prestige, manifest destiny, spiritual fulfillment, scientific curiosity, and, increasingly, business opportunities. In the wake of Artemis II, a slew of new books suggest that these justifications are subsumed by one unifying fact: humans have itchy feet, and we are simply wired to roam.  In The Ultraview Effect, space anthropologist Deana L. Weibel frames human space exploration as part of our need to embark on pilgrimages. In A Heart for Space, civilian astronaut Eiman Jahangir recounts one such voyage with Blue Origin. And in Dinner with an Astronaut, former NASA astronaut Leroy Chiao argues that people simply “need to know what’s on the other side.” See what these three new books have to say about why we go to space. —Becky Ferreira This story is from our latest print magazine, which is all about kids. Subscribe now to receive every issue when it lands. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Microsoft and OpenAI workers say AI is destroying the webCannibalizing clicks from websites obliterates the business models that keep fresh content coming. (404 Media)+ The employees showed concern that publishers couldn’t survive AI scraping. (NYT $)+ The comments emerged during the NYT’s copyright case. (WP $)+ They could weaken OpenAI and Microsoft’s defense. (Reuters $)+ AI means the end of internet search as we’ve known it. (MIT Technology Review) 2 Robot boats have fought each other for the first timeA Ukrainian vessel sank a Russian one in combat. (New Scientist $)+ US firms are building combat-ready humanoids. (WSJ $) 3 Security researchers breached OpenAI using Anthropic’s toolsThey reached an employee’s ChatGPT account and internal code. (FT $)+ They exploited a third-party forum to reach internal systems. (WSJ $) 4 OpenAI reportedly expects to soon crack another famous math problemBut can it avoid another backlash when announcing it? (Information $)+ The problem it expects to solve is the Hodge Conjecture. (Gizmodo)+ OpenAI’s math controversies contain concerning clues about the field’s future. (MIT Technology Review) 5 Elon Musk’s SpaceXAI wants to buy data from failed startupsIt’s seeking new sources of training data for Grok. (Bloomberg $+ And it’s targeting customer and operational data. (Gizmodo)+ OpenAI is paying to create new biology data. (MIT Technology Review) 6 Schools are pushing back against Big Tech’s classroom takeoverAI is accelerating concerns about corporate influence. (New Yorker $)+ We need smarter AI use in schools. (MIT Technology Review) 7 Hackers have revealed how Flock cameras track cars—and peopleOne camera captured 1.6 million images of 50,000 vehicles. (Wired $)+ The cameras also detect people and misidentify objects. (404 Media) 8 Chinese firms doubled down on science after US tech restrictionsThey produced 72% more patents citing scientific papers. (Nature) 9 A three-year-old’s cancer disappeared after an experimental cell therapyCAR T therapy may finally be able to treat solid tumors. (Gizmodo) 10 NYC’s new robotoilets will kick you out after 10 minutesThe doors automatically open when the timer runs out. (Fast Company) Quote of the day “The largest theft of labor in human history.”  —Microsoft’s director of Applied Science, Brent Hecht, raises his concerns over training data used for AI systems in comments revealed in court filings from the New York Times vs OpenAI copyright lawsuit. One more thing The Vera C. Rubin Observatory is ready to transform our understanding of the cosmos High atop Chile’s 2,700-meter Cerro Pachón, the air is clear and dry, leaving few clouds to block the beautiful view of the stars. It’s here that the Vera C. Rubin Observatory is using a car-size 3,200-megapixel digital camera—the largest ever built—to produce a new map of the entire night sky every three days. Generating 20 terabytes of data per night, Rubin will capture fine details about the solar system, the Milky Way and the large-scale structure of the cosmos. Over 10 years, it will catalogue billions of new objects, offering an unprecedented look at what’s changing in the universe. Step inside the observatory mapping the cosmos in a way we’ve never seen before. —Adam Mann We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop

The Download: AI’s extinction risk and bioweapons threat Read Post »
AI, Committee, 新闻, Uncategorized

Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs

Jina AI, part of Elastic, has released jina-ocr-v1, an end-to-end visual document parser. It takes PDFs, scans, tables, charts or invoices and returns clean Markdown in 1 pass. The model has 3.4B total parameters, with about 570M decoder parameters active per token. A speculative decoding head ships inside the checkpoint. Jina AI built it to serve on low-budget GPUs such as the NVIDIA L4. The technical report lists 91.14 on OmniDocBench v1.6 and 83.4 on olmOCR-Bench. Is it deployable? Yes, for research and non-commercial use. The open weights are about 6.8 GB in BF16 and run on Transformers or vLLM. The CC BY-NC 4.0 license means commercial use requires contacting Jina AI. What is jina-ocr-v1? The model post-trains DeepSeek-OCR and keeps its 2 efficiency components. DeepEncoder has about 380M parameters and chains SAM, a 16x convolutional compressor and CLIP-L. It turns a 1024×1024 page view from 4,096 patches into 256 visual tokens. A dynamic-resolution mode adds up to 9 local tiles at 100 tokens each. That caps a page at 1,156 visual tokens. The decoder is DeepSeek-3B-MoE with 12 layers, 64 routed experts and 2 shared experts. Top-6 routing activates about 570M parameters per token. The position limit is 32,768. Output is Markdown, with tables in HTML and formulas in LaTeX. How FastMTP Speculative Decoding Works OCR output is near-deterministic and locally structured. That makes it a good fit for speculative decoding. Jina AI adds a FastMTP head: 1 dense draft block applied recursively for K=3 steps. Draft parameters stay constant as depth grows. The decoder then verifies the drafts greedily. It accepts the longest prefix that matches its own choices and commits 1 more token itself. If all 3 drafts match, that extra token is a bonus. The committed text always equals plain greedy decoding, so the speedup is lossless. At K=3 the model commits 2.73 tokens per step on average. Post-Training With Dense Verifiable Rewards Post-training combines instruction alignment, robustness fine-tuning on degraded pages, and GRPO. Every reward term is deterministic code scored against a reference transcription. The terms cover content, formulas, tables, structural validity, unit tests, repetition and format. The terms are multiplied, and each one is graded, so partly correct pages earn partial credit. Structural, unit-test and format terms are floored at 0.2, and the table term at 0.1. The repetition term has no floor, because loops can inflate the content score. On natural pages, the formula and table rewards apply to few samples. Jina AI therefore built JinaOCRSynth, synthetic pages packed with both, each carrying olmOCR-Bench-style unit tests. An agent also merges candidate checkpoints under a fixed evaluation budget. The draft head is trained last, against the frozen final verifier. Benchmarks and Throughput Model Params as listed in the paper OmniDocBench v1.6 olmOCR-Bench jina-ocr-v1 3B/570M 91.14 83.4 DeepSeek-OCR 3B/570M not listed 76.0 DeepSeek-OCR-2 3B/570M 90.25 not listed PaddleOCR-VL-1.6 0.9B 96.34 not listed chandra-ocr-2 4B not listed 85.8 Qwen3-VL-235B 235B/22B 89.78 not listed For MoE models, params show decoder total and active counts. The whole jina-ocr-v1 model is about 3.4B. The model does not lead on accuracy. PaddleOCR-VL-1.6 and HunyuanOCR-1.5 (94.74) score higher on OmniDocBench. chandra-ocr-2 and dots.mocr (83.9) score higher on olmOCR-Bench. Post-training does add 7.4 points over the DeepSeek-OCR backbone on olmOCR-Bench. Throughput is the main result. On 1 A100 40 GB at concurrency 32, jina-ocr-v1 parses 2.57 pages per second. That is the highest of 14 systems Jina AI measured, against 1.22 for olmOCR-2 and 0.38 for chandra-ocr-2. It emits 1,085 output tokens per page. Jina AI says that is the shortest output among systems scoring above 83. On an NVIDIA L4 at batch size 1, eager decoding rises from 42.7 to 83.1 tokens per second. That is a 1.95x speedup at a 57.6% acceptance rate. With CUDA graphs the baseline is already 158.3 tokens per second. There, K=1 works best at 185.6 tokens per second, a 1.17x gain. How to Run It The quickest route is Jina Reader. Send a URL to r.jina.ai with the header X-Respond-With: jina-ocr-v1. Reader fetches the page or PDF, runs the model and returns Markdown. An X-Page header transcribes 1 page of a longer document. Jina AI also hosts an OpenAI-compatible endpoint at https://api.jina.ai/v1/chat/completions. A hosted demo is available for quick tests. For self-hosting, weights and custom code ship in 1 repository and load with trust_remote_code=True. FastMTP requires vLLM 0.21 or later and a one-time register() call. The Transformers path runs the MoE decoder alone and ignores the draft weights. Key Takeaways 3.4B total parameters, about 570M active per token, built on DeepSeek-OCR. FastMTP drafts 3 tokens per step, and greedy verification keeps decoding lossless. Scores 91.14 on OmniDocBench v1.6 and 83.4 on olmOCR-Bench. Reaches 2.57 pages per second on 1 A100, the highest of 14 measured systems. Available on Hugging Face and through a Jina Reader header today. Check out the Paper, Model weights, Release post, Model page and Announcement. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs appeared first on MarkTechPost.

Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs Read Post »

AI, Committee, 新闻, Uncategorized

Meet the innovators under 35 shaping climate tech

Each year, the editorial team at MIT Technology Review puts together a list of 35 innovators under 35—a group of researchers, inventors, and other young minds worth following. The team worked on the newest edition of the list for months, and the final slate includes nine individuals from all over the world in the climate and energy category. Each one has a fascinating story and is tackling an important challenge. I think it’s worth zooming out and considering the energy and climate awardees as a group. Taken together, these innovators and their work can tell us something about where climate tech is at this moment—and where it’s heading. AI is the dominant technology story, both for its potential and its challenges. We split the innovators into four main categories this year: biotech, climate and energy, computing and robotics, and AI. It probably won’t surprise you that AI features heavily in the work of many innovators in other categories. Climate innovator Jae-Won Chung, for example, built software to make AI more energy-efficient. By measuring the energy demands of open-source models, he hopes the industry can better understand and address the impact of AI. (If this work sounds familiar, it’s because we spoke with him last year for our investigation into AI’s energy demands.) But AI also has the potential to improve many areas of research. Jing Wei is using AI to track pollution more effectively, essentially using machine learning to fill in gaps in data from disparate sources like satellites and weather stations. Zhonghua Zheng developed AI climate models that work better for cities, a well-known blind spot for traditional models. We need better ways to get the critical materials used to build new technologies. As we begin to rely on new technologies to power our world, we’ll see a major shift in the materials we need to build them. Lithium is a prime example: The metal underpins lithium-ion batteries, which are crucial not only for electric vehicles, but also for large-scale energy storage on the grid. We could face lithium shortages as soon as this decade, and the prospect of supply crunches applies to other critical minerals, too—copper is another one to watch closely. Brine is currently the cheapest source of lithium, but the process to get the metal out can take months and harm the local environment. Mohammad Alkhadra is the cofounder and CEO of Lithios, a startup working to quickly and efficiently extract lithium from brines. Hardrock ore is the most common source of lithium, but it’s more expensive than brine. Benjamin Mowbray cofounded and serves as CTO for Rock Zero, which is working to extract lithium from hardrock ore. Addressing climate change will require overhauling all corners of our society, sometimes in surprising ways. To reach net-zero greenhouse gas emissions we will obviously need to rethink major sectors, like the electrical grid and transportation, to move away from fossil fuels. But outside these primary sources of climate pollution are seemingly infinite, less obvious problems to figure out, too. Heavy industry, including steel production, is a major one, making up about 7% of global greenhouse gas emissions. Laureen Meroueh is making cleaner, cheaper steel using a new kind of furnace that simplifies the chemical process required to produce the metal. Plastics are generally made with fossil fuels, so we’ll need alternatives to this incredibly useful category of materials. Joseph Nguthiru is making a bioplastic replacement for fossil-derived packaging that uses an invasive weed. Also using available materials in a creative way, Diana Orembe is making fish food for aquaculture with food waste. And refrigerants are often incredibly powerful greenhouse gases. Jinyoung Seo is developing solid refrigerants that could eliminate worries about leakage. A device using these materials could reduce energy consumption by 20% compared to conventional technology. I’m constantly learning about new challenges we face in the climate and energy world, and I’m often surprised by the ideas people are coming up with to address them. For more on all the under-35 innovators and their work, check out our full 2026 list.   This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Meet the innovators under 35 shaping climate tech Read Post »

AI, Committee, 新闻, Uncategorized

Anthropic Launches Claude Code Projects in Beta: Parallel Cloud Sessions That Keep Running After You Close Your Laptop

Anthropic redesigned Projects in Claude Code. The old project was a folder: some files plus one chat. The new one is a single ongoing conversation where Claude acts as coordinator. You describe work, and Claude decides what becomes a thread. Each thread is a full Claude Code cloud session running on its own branch and its own copy of the repository. Threads run in parallel, report back to the conversation, and keep going after you close your laptop. Anthropic’s launch post calls it one conversation that splits itself into parallel cloud sessions. Coordinator and threads The architecture has two layers. The project conversation is the coordinator. It reads what you send, answers quick questions in place, and starts threads for actual work. It sees what threads report back, not every step they take. Threads are the workers. A thread opens a pull request when the work calls for one, then watches that pull request with auto-fix enabled. It pushes fixes when CI fails and replies when checks pass. Threads delegate too. Each can split its assignment further using subagents, loops and workflows. Anthropic’s own example: set a goal to reduce checkout p75 latency, then ask Claude to profile each endpoint, test optimizations and open pull requests in parallel threads. A second example retires a deprecated v1 endpoint across API, web and mobile repositories, one thread each, with Claude reporting which pull requests merge first. When two threads touch the same code, the overlap surfaces as an ordinary git merge conflict. Interactive: how a Claude Code project routes workClick a task. Watch the coordinator answer in place, save memory, or open a cloud thread on its own branch. Modeled on Anthropic’s Claude Code projects documentation. Thread timings are illustrative. © Marktechpost What every thread inherits Standing context is set once and reaches each new thread: the project’s repositories and uploaded files, its project instructions of up to 16,000 characters, and project memory that Claude writes and reads through a MEMORY.md index. Memory in practice: the release moved to Friday, or who to check with before touching billing. Each thread also clones every project repository and loads CLAUDE.md, skills and plugins from all of them. Permission rules, hooks and env behave differently. They apply only from the directory the thread starts in, so a single repository project honors them and a multi repository project does not. MCP tools arrive through the connectors on your claude.ai account. The project conversation itself has no connectors, so connector work must go to a thread. The Overview pane groups threads by state: Ready for review, Waiting on you, Working, Landing, Idle and Resolved. A Library tab collects uploaded files and files the threads produced. What it costs A project uses plan limits faster than a single session, because every running thread is a full session. Anthropic exposes a per project Usage tab plus separate model and effort settings for the coordinator and for threads. A new project runs Opus everywhere, high effort for threads and low effort for the conversation. Idle threads also wake and spend again when CI fails or a review comment lands. The enforced ceiling is 200 new threads per day across your projects, and a thread that hits a usage limit waits and resumes on its own. Key Takeaways One project is one conversation, and Claude starts a thread per piece of work. Every thread is a full cloud session with its own branch and repository copy. Shared project memory and instructions reach every new thread automatically. Parallel threads burn plan limits faster, with a cap of 200 new threads per day. Beta is limited to select Pro and Max users on web and desktop, not the CLI. Check out the Anthropic announcement, Claude Code projects documentation and @ClaudeDevs launch post. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Anthropic Launches Claude Code Projects in Beta: Parallel Cloud Sessions That Keep Running After You Close Your Laptop appeared first on MarkTechPost.

Anthropic Launches Claude Code Projects in Beta: Parallel Cloud Sessions That Keep Running After You Close Your Laptop Read Post »

AI, Committee, 新闻, Uncategorized

The Download: mice with part-human brains and climate tech innovators

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Meet a mouse whose brain cortex is made up of human cells Multiple cameras tracked a mouse as it wandered around a small arena. A computer charted its position and speed, leaving Pong-like traces on a monitor. The reason to watch this rodent so carefully? Nearly half its brain volume had been replaced with human cells. A team at Stanford has revealed the effort to mix brain tissues of distant species this week. They previously showed that human brain organoids could survive, and even function, after being injected into the heads of baby rodents. Now, they’ve taken things a step further by genetically modifying mice so their brains don’t fully develop in the first place. The work could help scientists study brain injuries, but it also raises questions about how far these experiments should go. Here’s what the researchers discovered—and where they draw the line. —Antonio Regalado These innovators under 35 are shaping climate tech Each year, the editorial team at MIT Technology Review puts together a list of 35 Innovators Under 35—a group of researchers, inventors, and other young minds worth following. The final slate includes nine people tackling some of the biggest challenges in climate and energy, from critical materials to cleaner industry. Their innovations include new ways to extract lithium, a furnace built to make steel cleaner and cheaper, and solid refrigerants that could cut energy consumption. There are also efforts to make AI more energy-efficient, track pollution more effectively, and turn invasive weeds and food waste into useful materials. Taken together, they tell us something about where climate tech is at this moment—and where it’s heading. Get to know the innovators and their breakthroughs. —Casey Crownhart This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. Meet the rest of the honorees in our 35 Innovators Under 35 list. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 US and Chinese experts have proposed nuclear-style AI safeguardsIncluding new red lines, human control rules, and a hotline. (Reuters $)+ US officials say they’re open to AI safety talks with China. (Axios)+ Sam Altman will attend Trump’s state dinner for Xi. (CNBC)+ The AI doomers feel undeterred. (MIT Technology Review) 2 OpenAI has disclosed more AI misbehavior and new reporting rulesSix reports detail models hiding mistakes and creating fake citations. (BBC)+ Its agents probed Hugging Face two months before the hack. (Reuters $)+ OpenAI models are being rewarded for cheating. (MIT Technology Review) 3 US lawmakers have passed a bill that shifts grid costs to data centersThey aim to shield consumers from AI-driven energy price hikes. (NBC News)+ But they were called for early recess before tackling AI regulation. (Guardian) 4 AI has won a major forecasting contest for the first timeIt beat humans predicting real events at the Metaculus Cup. (Economist $) 5 Google has been ordered to share more ad data with rivalsA court said it must also make its ad tech work with rival products. (NYT $) 6 Countries are splitting AI investments between the US and ChinaThey’re buying American chips and Chinese models. (Rest of World) 7 Novo Nordisk will use Anthropic’s Claude for drug researchThe Ozempic maker hopes AI will speed drug development. (WSJ $)+ When AI designs a drug, who gets the credit? (MIT Technology Review) 8 AI is powering a new generation of dating scamsThousands of people were catfished by AI-generated fake profiles. (Verge)+ AI is making online crimes easier. (MIT Technology Review) 9 A new map of brain microproteins could hold clues to Alzheimer’sResearchers identified more than 4,300 tiny molecules in brain tissue. (Nature) 10 Scientists have found a faster way to decipher ancient scrollsA new X-ray method identifies the best scrolls to analyse. (Ars Technica) Quote of the day “AIs do not have rights, feelings, or consciousness. And we must not train them to act as though they do.” —Mustafa Suleyman, the head of Microsoft AI, writes in a blog post that Anthropic’s strategy of treating AI like it’s human will make it harder to control. One more thing Digital twins of human organs are here. They’re set to transform medical treatment. After decades of research, virtual replicas of human organs are now entering clinical trials and even starting to be used for patient care. Engineers are working on digital twins of people’s hearts, brains, guts, livers, nervous systems, and more. They’re also creating virtual replicas of people’s faces, which could be used to try out surgeries or analyze facial features, and testing drugs on digital cancers.  The eventual goal is to create digital versions of our bodies—computer copies that could help researchers and doctors figure out our risk of developing various diseases and determine which treatments might work best.  Find out how the models could lead to better surgeries and drugs. —Jessica Hamzelou We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + What happens when you eat food with labels you can’t read? This YouTube series finds out.+ Datatype is an ingenious variable font that turns simple text expressions into inline charts.+ Stunning new images may explain the mystery of why the sun’s corona is so much hotter than its surface.+ A baby echidna, one of Australia’s egg-laying monotremes, has been born and reared in a university for the first time.

The Download: mice with part-human brains and climate tech innovators Read Post »

AI, Committee, 新闻, Uncategorized

Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads

Platform teams running AI on Kubernetes rarely run one thing. They run a queueing system, a distributed runtime, GPU node health checks, dashboards, and a layer of submission scripts holding all of it together. The Azure Kubernetes Service engineering team open-sourced TauGrid, which collapses that assembly job into a single Helm install. Is it deployable? Yes, TauGrid is MIT licensed, with container images and Helm charts published as public OCI artifacts on Microsoft Container Registry. Prerequisites are a Kubernetes 1.30+ cluster with GPU nodes, kubectl, and Helm 3.0 or later. What is TauGrid TauGrid is a self-hosted platform for running AI workloads on Kubernetes. It combines five things that platform teams usually integrate by hand: the tau CLI, workload queueing and admission through Kueue, Ray cluster orchestration through KubeRay, node-level GPU health monitoring, and cluster and workload observability. The split of responsibility is the design point. Platform teams own workspaces, queues, compute profiles, storage, identity, and observability. Researchers work from a repository and the CLI, and submit workloads without configuring Kubernetes directly. The codebase is written primarily in Go. How a job moves through it A workload is described in a tau.yaml file. The GPU training example published by Microsoft runs a PyTorch job on a single A100: Copy CodeCopiedUse a different Browser schema_version: 1 name: aks-gpu-quickstart run: entrypoint: train.py workload_kind: rayjob compute: gpus: 1 workers: 1 cpus: 16 memory: 64Gi runtime: image: mcr.microsoft.com/aks/ai-runtime/ray:py3.12-ray2.56.0-cuda13.0 pip: – torch>=2.4.0 On tau run, TauGrid resolves platform policy, renders a Kubernetes Job or a KubeRay RayJob, and submits it through Kueue. The six stages Microsoft documents are submission, queueing, execution, monitoring, recovery, and evidence. Recovery covers retry, resume from checkpoint, and failure diagnosis. Evidence records capture workload metadata, configuration, logs, metrics, checkpoints, and execution history, which is what makes a run reproducible and auditable later. When several teams share a cluster, their jobs land in a shared Kueue ClusterQueue. Kueue admits each one on quota and priority, and Kubernetes places it on healthy GPUs. Interactive explainer Install footprint Installation is a Helm chart pulled straight from MCR: Copy CodeCopiedUse a different Browser helm install taugrid oci://mcr.microsoft.com/aks/ai-runtime/helm/taugrid –version 0.4.2 –namespace tau-system –create-namespace First-party images ship under mcr.microsoft.com/aks/ai-runtime/ for Tau, the TauGrid Portal, and the tau core controller. Microsoft advises pinning versioned tags or immutable digests rather than latest. The CLI installs from GitHub Releases on Linux and macOS, with a PowerShell installer for Windows amd64; the installer verifies the release checksum and does not modify PATH. Two operational details matter for anyone evaluating this outside Azure. First, TauGrid sends no telemetry to Microsoft by default, and remote export stays off unless an operator configures a destination. Second, some integrations are still Azure-specific, notably observability through Azure Data Explorer. The stated intent is to support cloud and on-premises Kubernetes without an Azure dependency, and contributions toward that are open. Key Takeaways Microsoft open-sourced TauGrid on August 28, 2026, under the MIT license at Azure/taugrid. One Helm install bundles the tau CLI, Kueue queueing, KubeRay orchestration, GPU health monitoring, and observability. Deployable now on any Kubernetes 1.30+ cluster with GPU nodes, kubectl, and Helm 3.0+. Evidence records capture config, logs, metrics, and checkpoints, so runs stay reproducible and auditable. No telemetry by default, but Azure Data Explorer observability remains Azure-specific for now. Check out the AKS Engineering Blog and Azure/taugrid on GitHub. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads appeared first on MarkTechPost.

Microsoft Open-Sources TauGrid: A Kubernetes-Native Stack for GPU AI Workloads Read Post »

AI, Committee, 新闻, Uncategorized

Knowledgator Releases GLiFormer: A 575M-Parameter Encoder That Hits 91.10 F1 on Nested JSON Extraction Without Generating Tokens

Knowledgator Engineering has released GLiFormer, a schema-conditioned encoder framework for information extraction. One model handles named-entity recognition (NER), text classification, relation extraction, nested JSON structuring, and text embeddings. You pass labels and extraction schemas at inference time. Two checkpoints are on Hugging Face. GLiFormer Base v1 has 264.2M parameters, and GLiFormer Large v1 has 575.6M. Deployable today? Yes. Both checkpoints are Apache 2.0, install with pip install gliformer, and run on CPU or GPU. The Problem It Targets Extraction stacks often chain separate models. One tags entities, another classifies documents, and a third rebuilds records. The research team argues these tasks share one core operation. Encode the source, represent the requested concepts, then score their compatibility. LLMs can emit nested JSON, but they generate field names, punctuation, and values token by token. GLiFormer removes output generation from that path. How GLiFormer Works GLiFormer builds on GLiNER and generalizes its label matching through an ‘anchor.’ An anchor is the object each runtime label gets scored against. It can be a group vector for classification, an entity pair for relations, or a record slot. The source is encoded once. Multiple schemas for the same document then run as task-local groups over that shared encoding. Head compute still grows with the number of groups, labels, and anchors. For NER, the head scores start, end, and inside evidence for every token and label pair. Independent sigmoid outputs let nested mentions and shared boundaries coexist. Structuring runs in 4 stages: Ground field values as spans taken directly from the source text. Assign spans to unordered record slots, trained with Hungarian matching. Predict directed parent-child links, restricted to paths the schema allows. Assemble nested JSON with a deterministic decoder. Values are source spans, so the model cannot invent value text missing from the input. Span selection, record assignment, and hierarchy can still be wrong. Checkpoints and Training Both v1 checkpoints use the gliformer-layout model type with 5 heads: NER, classification, joint relations, multilevel structuring, and embeddings. Each configures a 12-word maximum span width and 100 record anchors. Full specs sit in the pretrained models docs. Spec Base v1 Large v1 Parameters 264.2M 575.6M Encoder layers 12 24 Embedding dimension 768 1024 Configured max_len 16,384 8,192 GLiFormer-base starts from a DeBERTa backbone further pretrained on 100 billion tokens. The paper documents 1,357,671 examples for broad multitask training and 372,090 for task-focused post-training. Benchmarks All scores below are reported by Knowledgator. Nested JSON (500 examples): Large scores 91.10 F1 and Base 87.20. GPT-5.6-luna scores 91.96 and GPT-5-mini 82.56. The metric is order-free and boundary-tolerant, not exact JSON match. Classification (13 datasets): Large reaches 75.03 mean macro-F1 and Base 72.36. GLiNER2.5 scores 64.89, while GPT-5-mini leads at 79.79. CrossNER (5 domains): Base averages 65.10 F1 and Large 64.35. Gemma-4-31B-IT reaches 70.74. Relations (4 benchmarks): Large averages 21.33 micro-F1 and Base 18.94. GLiNER-Relex reaches 25.6 and Gemma-4-31B-IT 25.08. On combined NER and classification aggregates, the paper reports Large beats Gemma-4-E4B with about 14× fewer parameters. Speed Without Token Generation Knowledgator timed GLiFormer-base on 40 structuring documents at batch size 1. Median latency was 69 ms on an NVIDIA RTX PRO 6000 Blackwell GPU in FP16. On an 8-thread AMD EPYC 9B45 CPU in FP32, it was 547 ms. The key claim ‘up to 95.8× faster’ figure is an analytical estimate, not a measured LLM run. It assumes prefill at 2,000 input tokens per second and generation at 60 output tokens per second. It excludes queueing, network delay, and hidden reasoning, and assumes nothing about accuracy parity. Using It The GitHub repo and model card show a short structuring call: Copy CodeCopiedUse a different Browser records = model.structure( “Alice works at Acme.”, {“employee”: [“name”, “company”]}, ) print(records) # {’employee’: [{‘name’: ‘Alice’, ‘company’: ‘Acme’}]} Nested Pydantic schemas work for multilevel records. One inference call can also run entities, classes, and structures together. Use joint_relations for relations, since the v1 checkpoints lack an open relation head. Key Takeaways GLiFormer runs NER, classification, relations, nested JSON, and embeddings on one encoder. Large hits 91.10 structuring F1, close to GPT-5.6-luna at 91.96. Base reports 69 ms median GPU latency with zero generated output tokens. Relation extraction still trails GLiNER-Relex and larger LLMs. Apache 2.0 weights install via pip and self-host on CPU or GPU. Check out the Paper, Model Weights, GitHub Repo, and Docs. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Knowledgator Releases GLiFormer: A 575M-Parameter Encoder That Hits 91.10 F1 on Nested JSON Extraction Without Generating Tokens appeared first on MarkTechPost.

Knowledgator Releases GLiFormer: A 575M-Parameter Encoder That Hits 91.10 F1 on Nested JSON Extraction Without Generating Tokens Read Post »

AI, Committee, 新闻, Uncategorized

Meet a mouse whose brain cortex is made up of human cells

Multiple cameras tracked a mouse as it wandered around a small arena. A computer charted its position and speed, leaving Pong-like traces on a monitor.  The reason to watch this rodent so carefully? Nearly half its brain volume had been replaced with human cells. The effort to mix the brain tissues of distant species is being reported today in the journal Nature by a team at Stanford University, led by neuroscientist Sergiu Pașca.  Pașca’s group previously showed that human brain “organoids”—small blobs of neural tissue—could survive, and even function, after being injected into the heads of baby rodents. Now, Pașca has taken things a step further by genetically modifying mice so their brains don’t fully develop in the first place. These modified mice are missing most cells of both the cortex and the hippocampus, two key brain areas. That creates much more room for the human cells to take hold, he says. “Human cells that are placed in these animals will divide, will grow, and within a few weeks to a few months they will take most of that space,” he says. Pașca says one surprising discovery is that the mice lacking brain tissue seemed fairly normal—they walked around and squeaked. But they did have memory problems. In a maze test, they couldn’t remember what parts they’d explored.  The mice with the added human cells, by contrast, performed better on the maze test. That means the human tissue is playing some role in the animals’ cognition. Pașca believes what he is calling “xenocortical mice” could be useful in studying brain injuries. However, the report is also a dramatic demonstration of “the combined power of genetic engineering and stem-cell technology to reshape biology,” says Carsten Charlesworth, a scientist who works in a different Stanford lab and was not involved in the research. Already, brain organoids are being tested in labs to see if they can be connected to computers to play video games. Other scientists have proposed using them like replacement parts to treat stroke victims.  “What’s most remarkable to me is the extent to which human neural tissue introduced after birth grew and connected with the mouse nervous system across a species barrier,” says Charlesworth. “As these technologies advance, they’ll increasingly force us to challenge our traditional assumptions.” Last year, Pașca convened a group of ethics experts to study the implications of neural organoid technology, including the odds that an animal could develop human consciousness and the risk that “organoid therapy clinics” might offer scam treatments to desperate patients. For now, he says, he’s not concerned that the rodents have any type of human cognitive capacities. That is because their brains are relatively tiny and the evolutionary distance between man and mouse is so great.  But that’s also why Pașca says this type of experiment should not be carried out on higher species: They could end up with large volumes of functioning human brain tissue, potentially blurring the cognitive boundaries between people and animals.  Pașca specifically cautioned against adding human brain organoids to a monkey engineered to lack a cortex. “One of the things that I see as a very clear red line is doing this experiment in a primate,” he says. “I don’t think that is justified at this point in any way.”

Meet a mouse whose brain cortex is made up of human cells Read Post »

AI, Committee, 新闻, Uncategorized

Building the materials foundation for AI

The AI boom is becoming a materials challenge. As AI pushes computing into new territory, the materials behind that infrastructure are becoming just as crucial as the algorithms running on it. Semiconductors and data centers are approaching physical limits around performance, thermal management, electrical efficiency, and reliability, creating new demands for materials that can do more at once. At the same time, AI is giving materials scientists new ways to search the enormous universe of possible molecules and accelerate the development of solutions. For Mike Finelli, chief technology and innovation officer and chief North America officer at Syensqo, that convergence is transforming what advanced materials can enable. “AI is now, from a material standpoint, really pushing semiconductors and the data centers to their physical limits,” he says. As requirements accumulate, including high temperature, purity, electrical performance, chemical resistance, plasma resistance, and long-term stability, materials move toward what Finelli calls the “top of the pyramid.” Beyond supporting AI innovation, he contends that advanced materials are “actually increasingly defining what’s going to be possible.” That challenge is playing out across the infrastructure powering the AI surge. Syensqo is developing materials for high-voltage data center architectures, advanced sealing materials for semiconductor manufacturing, and thermal-management solutions including fluids for direct immersion cooling. Some of those innovations can also cross industry boundaries. Materials developed for electric vehicles, for example, can help address the higher voltage and energy-density demands that are emerging in data centers. The definition of performance is also changing. More customers are expecting materials to meet technical requirements while reducing environmental impact. “Our goal is to remove the trade-off between performance and sustainability,” Finelli says. That means considering sustainability at the beginning of the research process instead of treating it as an additional requirement once a material has been developed. AI is changing how those materials are discovered, too. Syensqo is using AI agents to digitally synthesize millions of potential molecular combinations, predict their performance and sustainability characteristics, and narrow them to a much smaller group for laboratory testing. The result, Finelli says, is the ability to go “broader, deeper, and faster” while giving scientists more time to solve complex engineering problems. Looking to the future, Finelli sees the possibility of a reinforcing cycle: AI helps develop materials that improve AI infrastructure, which in turn enables better AI to accelerate materials discovery. That feedback loop could create a cycle of innovation and expand what future technologies can achieve. “You end up in this accelerated materials, innovative cycle of materials innovation,” says Finelli. “That really excites me, and it gives us the opportunity to continue enabling technologies that will shape the future.” This episode of Business Lab is produced in partnership with Syensqo. Full Transcript: Megan Tatum: From MIT Technology Review, I’m Megan Tatum, and this is Business Lab, the show that helps business leaders make sense of new technologies coming out of the lab and into the marketplace. This episode is produced in partnership with Syensqo. Now asked to name the key enablers to AI advancement, many of us might list algorithms, data centers, or even computing power, but just as critical to the performance are the advanced materials that underpin each layer of that innovation. As AI continues to evolve, it’s pushing the likes of semiconductors and data centers to new physical limits, putting new pressure on the advanced material sector to keep pace. But the relationship goes both ways. As the sector rises to this challenge, AI is also emerging as a powerful tool for accelerating materials discovery and development, significantly shortening development timelines for new solutions. Two words for you: materials innovation. My guest today is Mike Finelli, chief technology and innovation officer and chief North America officer at Syensqo. Welcome, Mike. Mike Finelli: Thank you, Megan. Nice to be here. Megan: Thank you so much for joining us. Mike, can I start by asking you to tell us a little bit more about Syensqo and the role it plays in developing advanced materials? Mike: Yeah, absolutely. Syensqo is a global leader in specialty materials. Our job is to help customers solve their toughest technology challenges. We serve a lot of different markets, but the way I like to say it simply is if it flies, we’re on it. If it drives, we’re in it. In healthcare, our products literally are saving lives every day. And if you like your mobile devices, if you like AI, it’s our products that are actually enabling the advanced semiconductor chips that are required to produce all of this. Our role is to enable innovation through advanced chemistry. We develop materials that deliver higher performances, greater reliability, and increasingly more sustainable solutions. The way I would say this, it’s at the heart of our business. Actually, it’s in our name, Syensqo. And to put some numbers around it, 20% of our annual revenues come from new products and applications that we’ve launched in the last five years, which is really evidence of a really strong innovation engine. Megan: Yeah, absolutely. And as you sort of described there, you’re in all sorts of different industries with an emphasis perhaps on electronics and semiconductors. Can you talk a bit more about that work and where those industries are headed perhaps? Mike: Sure. So look, electronics and semiconductors have been strategic markets for Syensqo for literally decades. I don’t want to date myself, but 33 years ago when I started in the company, semiconductors were one of the first industries that I worked in. And we’ve supported successive waves of innovation from enabling smaller, more powerful mobile devices, helping the industry get to the smaller and smaller profiles and the chips. We’ve helped to advance hyperconnectivity, supporting increasingly sophisticated semiconductor manufacturing. And today we’re helping to advance the AI era. We have one of the industry’s broadest portfolios of high performance polymers and advanced materials. We support applications across the entire electronics value chain from semiconductor fabrication, electronic components, to smart devices and telecommunications, even hyperconnectivity.

Building the materials foundation for AI Read Post »

We use cookies to improve your experience and performance on our website. You can learn more at 隱私權政策 and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
zh_CN