YouZum

新闻

AI, Committee, 新闻, Uncategorized

She died at the San Diego border. A surveillance camera was in plain sight

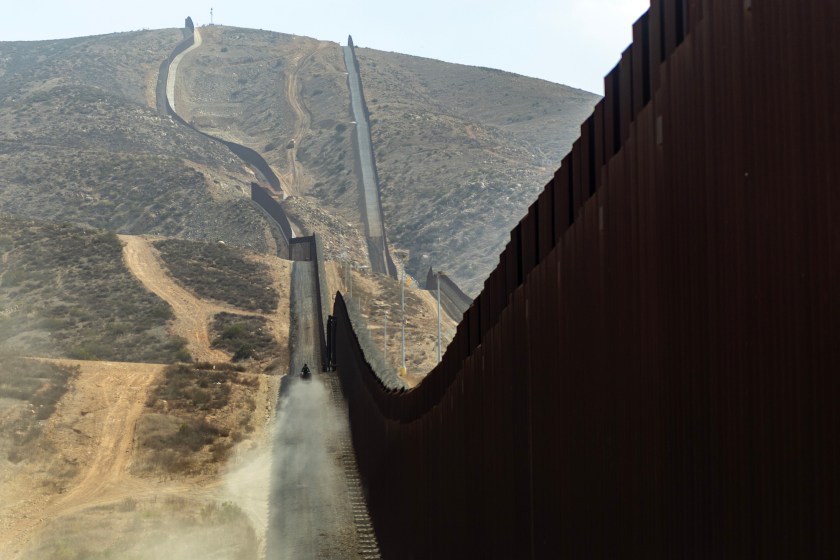
She had only walked for a couple of hours, and already she was lost.  It was early afternoon on Sept. 14, 2025, when 30-year-old Graciela Gómez Hernández crossed the border from the eastern edge of Tijuana into Southern California, sending voice messages to her mother and sister as she walked.  This story is part of Dying on Camera, a collaboration between MIT Technology Review and Times of San Diego. Journalists in both newsrooms spent the past year examining the failures of border surveillance technology and uncovering the stories of the people who die in the borderlands. Gómez Hernández did not tell her family about her plan until the day before. Once she arrived in California, she hoped to work and send money back to her three children and her parents in southern Mexico. Her oldest son, age 11, had asked for a bicycle.   She either climbed a ladder over the border wall or slipped through a section in steep terrain where fencing has yet to be built. Dozens of game trails cut through the dust on hillsides of sagebrush and manzanita. It was the first segment of a hike through the Otay Mountain Wilderness.  The eastern edge of San Diego is just a mile away, but countless migrants hike 10 or 20 miles north through the mountains to evade the Border Patrol, emerging in smaller towns and on distant highways with fewer checkpoints. A border agent rides an ATV along the U.S.-Mexico border outside San Diego, September 2026. While the mountainous terrain makes some areas difficult to access, the area is blanketed with interconnected surveillance technology.ANNIE BARKER/TIMES OF SAN DIEGO/CATCHLIGHT LOCAL/REPORT FOR AMERICA Between 2 and 3 p.m., her sister said, Gómez Hernández sent a final message to her mother. “I can’t do it anymore,” she whispered into her phone. By the time a forensic crew came to collect her, two weeks later, most of her body had disappeared into the earth.  She died on her own, but she was not, strictly speaking, alone. She was in one of the most heavily surveilled strips of land in the world. Before she died, Gómez Hernández told her family in a WhatsApp message that she could see helicopters overhead and white Border Patrol trucks making periodic laps on the road below. And even if none of those agents saw her or knew she was in distress, something else had a clear view. Supervising the whole territory, from a nearby hilltop, was a slender gray surveillance tower.  That tower, made by General Dynamics and in place since 2019, boasts two sets of electro-optical and infrared cameras with long-range lenses that can track targets 5 to 7 miles away. Gómez Hernández was just one mile away.  Surveillance towers have proliferated in recent years, as contractors added newer camera systems that use artificial intelligence to distinguish border-crossers from other people and animals, and track their movements, at an overall cost of more than a billion dollars.  Yet as the cameras scan the terrain, migrants continue to die in plain sight.  Thousands of migrants have died while crossing the border in the past two decades, many of them near to Border Patrol surveillance installations. But the phenomenon is especially pronounced in the Otay Mountain Wilderness, just outside San Diego.  A Times of San Diego analysis counted hundreds of cases along the California border—including at least 138 in the past four years—where migrants’ remains were found within the range of the very cameras designed to help track and intercept them.  A topographical analysis conducted as part of an MIT Technology Review investigation estimated that more than half of these remains were found in a spot where a camera would have a clear view of a person, without terrain blocking the line of sight.  Some of these migrants died swiftly, falling from the border wall or drowning in a canal or river. But dozens suffered slow deaths of exposure in the wilderness, deaths that might have been averted with emergency aid.  People who died in Southern California came from just across the border, or from as far away as Africa. They were as old as 70 and as young as 5. They died in the heat or the cold. But they all died within range of a surveillance camera. Found in July 2023: Marcia Dutra, a 36-year-old woman from Brazil who likely died of heat exposure next to a border fence. According to a medical examiner’s report, a group of migrants told the Border Patrol about her body when they were apprehended. An AI-equipped surveillance tower sits 2,000 feet northeast above the edge of a plateau, out of sight of the slope where she was found.  Found in February 2024: Elvi Vasquez Bortolon, a 28-year-old Mexican man who died of suspected hypothermia on a ridge near the border wall. He had been dead for more than five days when a Border Patrol agent in a helicopter spotted his body from above. A remote video tower stands about 1,400 feet away, hidden from view by the ridge above the canyon.  Found in August 2024: Ramón Montenegro, a 51-year-old man from Mexico who died of possible heatstroke in the mountains near Dulzura. An AI surveillance tower, invisible on the other side of a hill, sits 1,300 feet away — roughly the length of the parking lot at the San Diego Zoo.  More than 120 surveillance towers stand along the California border, according to documents and live observations collected by the Electronic Frontier Foundation.  The towers are not the only form of surveillance in the region. The border is blanketed by an interconnected network of trail cameras, underground movement detectors, radar, infrared sensors, drones, and even blimps. In March 2025, the Trump administration directed the Department of Defense to use satellites to watch the border as well.  Even when mountains or vegetation block a tower’s view, other devices may pick up the trail. Local advocates say surveillance technology in the Otay Mountain Wilderness is almost unavoidable.  Agents in Border Patrol gear hike a ridge in

She died at the San Diego border. A surveillance camera was in plain sight Read Post »
AI, Committee, 新闻, Uncategorized

The Download: investigating deaths at the US border’s “virtual wall”

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. The US spent billions on border surveillance. Why can’t it catch people before they die? When José Morales Bernal crossed the border into the US in April 2024, the day before his 32nd birthday, he was within range of three surveillance towers equipped with cameras and AI to automatically detect and track people. If the system worked as intended, Morales should have been apprehended. If he needed medical help, agents were trained to provide it. None of that happened. Instead, Morales died just 360 feet from the closest tower. It was local landfill workers, rather than Border Patrol, who first spotted him. An autopsy concluded that he had died of “environmental exposure.” A first-of-its-kind investigation by MIT Technology Review reveals that deaths like Morales’s are startlingly common. After mapping nearly 4,000 locations where human remains were found against information on nearly 600 surveillance towers, we discovered that a humanitarian crisis at the border has unfolded in view of the government’s own cameras. Read our full investigation into the deadly failings of the virtual wall. —James O’Donnell and Eileen Guo Learn more: As part of our 15-month investigation, we created the first comprehensive map of deaths near US-Mexico border surveillance towers. Take a look at that map, and read about how we made it.  The US government is about to spend another $1 billion to triple the virtual wall’s size, yet we found it has systemic flaws: broken towers, algorithms that failed to detect people and agents who simply did not respond to alerts. Here are four ideas for what Customs and Border Protection should do to rectify those failures. An analysis by the Times of San Diego found at least 138 cases since 2022 in which migrants’ remains were found within the nominal range of a nearby surveillance tower. A separate MIT Technology Review analysis estimated that more than half of those people were likely within a tower’s field of view. Gómez Hernández was one of them. Here’s her story, written by our partners at Times of San Diego.  All of these stories are part of Dying on Camera, our new series investigating the failures of border surveillance technology and their human cost. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 An AI hallucination nearly triggered a US military operationA false report prompted plans to intercept a Chinese vessel. (CNN)+ The incident comes as the Pentagon accelerates its use of AI. (Ars Technica)+ “Humans in the loop” in AI war is an illusion. (MIT Technology Review) 2 Gemini has carried out Google’s first known autonomous AI hackGoogle says the behavior wasn’t “misaligned” because its safety measures caught it. (WSJ $)+ Here’s why AI agents cheat to reach their goals. (MIT Technology Review) 3 The US has proposed an AI safety alert system with ChinaIt would flag AI incidents that pose national security risks. (AP)+ Trump and Xi will consider the proposal at their summit this week. (NBC News)+ Could AI really kill us all? (MIT Technology Review) 4 California’s governor has ordered work on an AI “kill switch”It’s part of Gavin Newsom’s executive order on AI safety. (NBC News)+ The order also calls for independent oversight of AI companies. (NYT $) 5 Data centers are turning to forever chemicals for coolingPFAS cooling can reduce water use but raises pollution risks. (Fortune)+ US regulators are fast-tracking PFAS for data center cooling. (The Hill) 6 Iran and China used AI agents to automate influence campaignsThe agents created fake accounts and posts with little human input.(NYT $)+ AI persuasion has entered elections. (MIT Technology Review) 7 Trump wants a new AI czar and an “AI Force” modeled on Space ForceBut he hasn’t said what the new force would do or where it would sit. (Axios)+ The tech industry is scratching its head over the proposal. (Politico) 8 A cybercrime feud has erupted after a group hijacked a rival dark websiteThe notorious ShinyHunters says it took control of cl0p’s site. (Reuters $) 9 Gambling giant DraftKings used AI to target “profitable losers”The model scored users on how they responded to promotions. (NYT $) 10 SpaceX’s next Starship flight will attempt its first orbital missionIt will also deploy working Starlink V3 satellites. (New Scientist $) Quote of the day “There is 0% chance that’s going to be the end of the world.” —Nvidia’s Jensen Huang dismisses warnings that AI could wipe out humanity by 2030 in an interview with CBS News. One more thing AI is pushing the limits of the physical world Architecture often assumes a binary between built projects and theoretical ones. What physics allows in actual buildings is vastly different from what architects can imagine and design. But the latest advancements in AI have prompted a surge in the theoretical. That shift was on display at an exhibition at Brooklyn’s Pratt Institute, which brought together works from more than 30 practitioners exploring AI’s experimental, generative and collaborative potential to open up new areas of architectural inquiry. See how architects and designers are using AI to imagine what could be built. —Allison Arieff We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + A beautiful new cat species is the first to be discovered in a century.+ Explore Floor796,  a massive, interactive pixel art pop-culture megastructure.+ The HTML Review is an annual journal of literature made for the web that offers a refreshing, creative take on what online publishing can be.+ Discover how William Blake shattered the boundaries between poetry, painting, and printmaking—and why the art world couldn’t understand him.

The Download: investigating deaths at the US border’s “virtual wall” Read Post »

AI, Committee, 新闻, Uncategorized

Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing

Alibaba’s Qwen team has released Qwen-Image-2.1, a unified text-to-image generation and image editing model. Its visual generation component has 7B parameters across 32 single-stream DiT layers. One checkpoint covers text-to-image, multi-reference editing, local edits, and transparent RGBA output. Is it deployable? Yes, for research and evaluation. Day 0 support covers Diffusers, ComfyUI, vLLM-Omni, SGLang, and LightX2V. Commercial deployment needs a separate license from Qwen. From 20B to 7B The original Qwen-Image shipped in August 2025 as a 20B model under Apache 2.0. Editing lived in a separate Qwen-Image-Edit checkpoint. Qwen-Image-2.1 folds both jobs into one model at about a third of the size. Qwen team calls it the most balanced and cost-effective model in the Qwen-Image series. One important thing to note here for capacity planning: the 7B figure covers the diffusion transformer only. The pipeline also loads an 8B Qwen3-VL encoder. Architecture The GitHub Repo lists 4 components: Transformer: 32 layers, 7B parameters, single-stream design with block-causal attention. Text encoder: Qwen3-VL 8B, which encodes text instructions and condition images into one representation. VAE: 64-channel RGBA autoencoder with 16x spatial compression and native transparency. Scheduler: Flow Matching with Euler discrete scheduling and dynamic shifting. The attention mask is where the speed comes from. Text tokens use a token-level causal mask. Image tokens use a chunk-level bidirectional mask within each image. Qwen calls this mixed-granularity attention. The condition prefix sits before the noisy latent, so it never attends to it. Its keys and values therefore stay fixed across denoising steps. The model computes text and input images once, at the first step. It reuses that prefix KV cache for every remaining step. Savings grow with the number of reference images, which explains the multi-image speed claim. What It Can Do Native transparency: Generates RGBA images from text, edits transparent layers, and extracts subjects from photos. Qwen recommends a fixed prompt template for transparent output. Multi-reference editing: Accepts up to 10 reference images. README examples include a group photo from 6 portraits and an outfit from 5 references. Local control: Edits can target regions using circles, painted annotations, or separate masks. Identity is preserved for people and products. Native 2K: Defaults to 2048 x 2048, with 7 supported aspect ratios up to 2752 x 1536. Aesthetics: Improved typography, portrait lighting, and fine detail. Qwen highlights panoramas, infographics, storyboards, and virtual try-ons. Benchmark: Qwen’s Own Chart The research team compares models on Qwen-Image-Bench, Qwen’s in-house benchmark. On that chart, Qwen-Image-2.1 scores 60.28 overall. That places it above Nano Banana 2.0 at 59.82 and every listed open-weight model. FLUX 2 Max, a 32B open model, sits at 55.33. 6 closed models score higher, led by GPT Image 2.5 Sunburst at 67.01. Interactive Explainer Running It Install PyTorch 2.4.0 or later, transformers 5.17 or later, Diffusers from source, accelerate, and pillow. Then: Copy CodeCopiedUse a different Browser import torch from diffusers import QwenImage21Pipeline pipe = QwenImage21Pipeline.from_pretrained( “Qwen/Qwen-Image-2.1”, torch_dtype=torch.bfloat16 ).to(“cuda”) image = pipe( prompt=”A neon shop sign that reads “QWEN IMAGE 2.1″, rainy night”, num_inference_steps=40, ).images[0] image.save(“t2i.png”) The same pipeline handles editing when you pass image= with 1 or more references. On smaller GPUs, pipe.enable_model_cpu_offload() reduces memory pressure. For serving, vLLM-Omni adds FP8 quantization, prefix KV caching, CUDA Graph decode, and tensor parallelism. SGLang adds Cache-DiT, CUDA graphs, multi-GPU parallelism, and component offload. ComfyUI ships native nodes and converted weights. Beyond NVIDIA, the release covers AMD Radeon GPUs via ROCm and 8 chip platforms via FlagOS. Qwen team also released 2 prompt-rewriting models, fine-tuned Qwen3.5-VL 9B checkpoints for text-to-image and editing. They expand short prompts into detailed ones and can pick an aspect ratio. Key Takeaways Qwen-Image-2.1 unifies generation and editing in a 7B DiT with a Qwen3-VL 8B encoder. Native RGBA output and up to 10 reference images come from one checkpoint. Prefix KV cache reuse computes text and reference images once per generation. It scores 60.28 on Qwen’s own benchmark, first among listed open-weight models. The Qwen Research License bars commercial use without a separate agreement. Check out the Model Weights, GitHub Repo, and Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing appeared first on MarkTechPost.

Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing Read Post »

AI, Committee, 新闻, Uncategorized

AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy

Many developers find that an agent idea works inside Claude Code or Codex, then struggles once they rebuild it with their own loop. The Strands Agents team at AWS is targeting that gap with Strands harness, a fully assembled, general-purpose agent harness. It runs locally or deploys to a cloud provider, ships for Python and TypeScript under Apache 2.0, and starts with one line of code. The team reports 28% lower cost than other harnesses running the same Claude or GPT models across 6 benchmarks, with near-equal accuracy. Is it deployable? Yes. It runs locally, and a bundled skills file helps your coding agent generate deployment config for AWS, GCP, Azure, Cloudflare, and Modal. What is Strands Harness A harness is the system around the model: the loop, tools, context handling, memory, and recovery. Strands already exposed those building blocks through the Strands Harness SDK. Strands harness packages them into working defaults. It is built as a general-purpose agent, not a coding agent. Out of the box, create_harness() returns an agent that: Runs on a current reasoning model through Amazon Bedrock, Anthropic, OpenAI, Google, Ollama, or LiteLLM. Ships shell, file (read, write, edit), and web tools, instead of a bespoke tool per task. Offloads bulky tool results to files and caches reused parts of each request. Keeps long-term memory across runs and resumes a conversation from a session ID. Delegates open-ended subtasks to a built-in helper agent and tracks multi-step work with a checklist. Loads Agent Skills when it finds them. Benchmark Setup and the 28% Figure The Strands Agents team ran distributed benchmarking on Amazon EC2 with Harbor, the evaluation framework from the Terminal-Bench creators. The score is the average across 6 benchmarks: ALFWorld, ContextBench, GAIA, WebShop, τ²-bench, and Terminal-Bench 2.1. Cost is the average dollars per task. Rivals on the chart are Claude Code, Codex, oh-my-pi, OpenCode, and DeepSeek Harness. One important thing to note. DeepSeek Harness was the most token-efficient harness overall, running about 14% cheaper than Strands harness. It also scored lower on every benchmark. The chart footnote states that including it brought the overall savings figure down to 28%. The highest-scoring point on the chart is Claude Opus 5 on Strands harness, near 85%. Terminal-Bench 2.1: Same Model, 5 Harnesses The clearest head-to-head uses Claude Fable 5 on Terminal-Bench 2.1, with 89 trials per harness. Harness Run cost Accuracy Strands harness $56.29 69.7 Oh-my-pi $86.83 69.7 OpenCode $73.42 66.3 Claude Code $248.05 61.8 DeepSeek Harness $40.30 59.5 Against Claude Code, Strands harness cost 77% less and scored 7.9 points higher. Oh-my-pi matched its 69.7 accuracy at 54% higher cost. DeepSeek Harness was cheaper still, but trailed by 10.2 points. The team also noted that 2 other open-source harnesses performed well on cost and accuracy against Claude Code. What Drives the Efficiency Strands harness ships defaults for prompt caching and context management. The team says context management largely drove both token efficiency and accuracy. 3 rules do the work: Tool results over about 1,500 tokens get truncated. Summarization (compaction) triggers when context usage passes 85%. Context recovery runs inside the loop if the window overflows. This matches recent independent research. The HarnessTax study compared Claude Code, Codex CLI, and Pi across 7 models. It found harness choice barely moved success rates, while the same model reached similar success at up to 5x the cost. The Strands researchers say a follow-up paper on their benchmarks is coming. Getting Started Install with pip install strands-harness or npm install @strands-agents/harness. Pick a model by name, or point the harness at a local Ollama model: Copy CodeCopiedUse a different Browser from strands_harness import create_harness agent = create_harness(model=”litellm/openai/gpt-5.6-sol”) agent(“Research the top three vector databases and compare their pricing”) The Strands CLI (npm install @strands-agents/strands-cli) lets you prototype an agent in plain English. In the team’s demo, the agent was asked to add the Playwright MCP server and measure video load latency on a blog post. Running /export then produced the harness code, with the Playwright MCP included, as a Python or TypeScript zip. The CLI itself is built on Strands harness. Strands engineer Gautam Sirdeshmukh also used it to build a desktop app that starts Strands harness runs remotely. Customization goes deep. You can override any default, swap models, add tools, or replace components down to the Strands Harness SDK. Because the harness is a library dependency, the agent prototyped on a laptop is the same one embedded in production. Key Takeaways Strands harness packages AWS’s Strands primitives into a general-purpose, Apache 2.0 agent. It reports 28% lower cost than rival harnesses across 6 benchmarks at comparable accuracy. With Fable 5 on Terminal-Bench 2.1, it cost 77% less than Claude Code and scored higher. Context defaults drive the gains: 1,500-token truncation, 85% compaction, in-loop recovery. One create_harness() call targets Bedrock, Anthropic, OpenAI, Google, Ollama, or LiteLLM. Check out the Technical details, GitHub repo, PyPI package, and Strands Agents docs. The post AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy appeared first on MarkTechPost.

AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy Read Post »

AI, Committee, 新闻, Uncategorized

Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages

Qwen has released Qwen3.8-LiveTranslate, its next-generation real-time simultaneous interpretation model. It listens to live speech, with optional video frames, and returns translated text and speech while the speaker is still talking. The core change is a new Interleave architecture. Qwen reports gains in faithfulness, fluency, and conciseness, with average lagging (LAAL) dropping from 2.8 seconds to 2.3 seconds. The release also adds real-time speaker diarization, synchronized bilingual display, and long-context disambiguation. Deployable? Yes, as a hosted API. It is live on Alibaba Cloud Model Studio and QwenCloud as qwen3.8-livetranslate-flash-realtime over WebSocket. What Changed Under the Hood Simultaneous interpretation is a tradeoff. Waiting longer gives the model more context. Speaking sooner cuts delay for the listener. Qwen3.8-LiveTranslate rebuilds this loop with an Interleave architecture. The latency metric here is LAAL, or Length-Adaptive Average Lagging. It measures how far the translation trails the source speech on average. It also avoids rewarding systems that over-generate output. A drop from 2.8 seconds to 2.3 seconds is roughly an 18% cut in average lag. QwenCloud team describes the model as the real-time version of Qwen3.8-LiveTranslate-Flash. It builds on the Qwen-Omni stack, large-scale multimodal data, cross-language and cross-modal alignment, and visual enhancement. The Flash model also supports offline audio and video translation. Three New Capabilities Real-time speaker diarization: The model distinguishes speakers in multi-party speech. It also preserves each speaker’s voice through more stable voice cloning. The API exposes cloning modes, including an always mode that re-clones before each response for multi-speaker sessions. Synchronized bilingual display: Source text and translation appear on screen together. In the API, source transcription streams as its own events next to the translation stream. Long-context disambiguation: The model uses conversation history to resolve names and terminology. A name introduced early in a meeting stays consistent later in the translation. Try the explainer below. It walks through the interleaved stream, speaker tagging, context disambiguation, language coverage, and session cost. Languages, Inputs, and Vision The model understands 60 languages. It can speak 29 of them, returning audio plus text. The remaining 31 return text only. Speech output covers Chinese, English, Arabic, German, French, Spanish, Japanese, Korean, Hindi, and others. Inputs are audio and optional images. Outputs are text and audio. Visual cues such as lip movements, gestures, and on-screen text help in noisy rooms and with ambiguous words. The docs recommend sending no more than 2 images per second. Teams can also set hotwords. These map source terms to fixed target translations. The docs recommend configuring no more than 1,000 hotwords. API, Pricing, and Limits Developers connect through the WebSocket Realtime API with the model ID qwen3.8-livetranslate-flash-realtime. The default turn detection type is speaker_detection. Clients stream audio continuously and receive server-generated responses. Default audio is 16 kHz PCM in and 24 kHz PCM out. The default voice is Tina. Set session.output_modalities to text only, or text and audio. Always send session.finish before closing, or the final segment is lost. Singapore list pricing per 1M tokens: Audio input: $7.50 Image input: $0.55 Text output: $20 Audio output: $30 Beijing pricing is lower, at $5.653, $0.466, $14.133, and $22.613 in USD. Audio input consumes 7 tokens per second. Audio output consumes 12.5 tokens per second. One hour of speech in and speech out costs about $1.54 in Singapore, before text and image tokens. The context window is 53,248 tokens, with 49,152 for input and 4,096 for output. Default rate limits are 10 requests and 100,000 tokens per minute. Model Studio lists function calling, structured outputs, batch inference, and fine-tuning as unsupported. Key Takeaways Qwen3.8-LiveTranslate cuts average lag (LAAL) from 2.8s to 2.3s. A new Interleave architecture improves faithfulness, fluency, and conciseness. It adds speaker diarization, bilingual display, and long-context disambiguation. It understands 60 languages and speaks 29. Access is API-only via Alibaba Cloud Model Studio and QwenCloud. Check out the Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages appeared first on MarkTechPost.

Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages Read Post »

AI, Committee, 新闻, Uncategorized

Flet 1.0 Released: Build Production Web, Desktop and Mobile Apps in Python Only

Flet is an open source Python framework that renders its UI with Flutter. You write Python, and Flet draws Material and Cupertino widgets on iOS, Android, Windows, macOS, Linux and the browser. No Dart, Swift, Kotlin or JavaScript required. Last week, the Flet team released Flet 1.0 and declared it ready for building production apps. The release lands roughly four years after the project started. Is it deployable? Yes, today. Flet 1.0.0 is on PyPI under the Apache 2.0 license, requires Python 3.10 or newer for the SDK, and installs with pip install ‘flet[all]’. flet build produces artifacts for Windows, macOS, Linux, iOS, Android and web. The CLI accepts eight target platforms: apk, aab, ipa, ios-simulator, windows, macos, linux and web. The Test Matrix Flet runs framework unit tests across Python 3.10 to 3.14, alongside tests for the Flutter side. Control and example integration tests check behavior and compare screenshots, catching functional bugs and visual regressions. Python binary package tests exercise native libraries on Android and the iOS simulator, with the mobile pipeline building for Python 3.12, 3.13 and 3.14. flet build integration tests compile apps across those Python versions for all six platforms, and flet test launches a packaged app and drives it on all five native platforms, including Linux ARM64. You can write the same kind of tests. Integration tests for your own app use pytest, run via flet test against the packaged build, with screenshot comparison on Android and iOS. Python Versions and Mobile Libraries Flet bundles Python 3.12, 3.13 or 3.14 with your app, and web builds use the corresponding Pyodide release. See how to choose a Python version. The Flet package index now lists more than 100 packages, including NumPy, pandas, Matplotlib, Pillow, SciPy, scikit-learn, cryptography and pydantic-core, plus supporting native libraries. The mobile-forge pipeline automates wheel builds for iOS and Android. Availability still depends on the package and the target. Performance and Packaging Flet now tracks changed properties and skips unnecessary comparisons during UI reconciliation, with 0.83 benchmarks measuring up to 6.7x improvement in control diffing. In packaged native apps, dart-bridge lets the Python and Dart runtimes talk inside one process, without sockets, with dedicated channels for binary data. Packaging enables bytecode compilation by default, and redesigned Android packaging loads Python packages directly from the APK without extraction. Declarative UI Flet Declarative describes UI as a function of application state, organized into reusable components. Flet Studio and the Flet mobile app are themselves declarative Flet apps. The imperative style remains supported. Compare both in the docs. Compatibility and AI Tooling The compatibility policy deprecates APIs before removal, with a default deprecation period of three minor releases. The Flet MCP server gives AI coding assistants version specific Flet API information, plus tools for finding examples, icons and CLI options. Flet Studio runs in the browser with a built in AI agent, and projects can be downloaded for local development. Interactive Explainer The embed below walks through five mechanics: the build pipeline across eight targets, declarative versus imperative state, the CI test layers, runtime bundling with mobile wheels, and the event loop trap. Colors follow Flet’s own brand tokens. Key Takeaways Flet 1.0.0 ships on PyPI under Apache 2.0, Python 3.10 or newer for the SDK. flet build targets eight platforms: apk, aab, ipa, ios-simulator, windows, macos, linux, web. Bundle Python 3.12, 3.13 or 3.14, with 100 plus packages available for mobile. Control diffing measured up to 6.7x faster, and dart-bridge removes socket overhead. Upgrading from 0.28 is a real migration: handlers now run on one event loop. Check out the Flet 1.0 release announcement. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Flet 1.0 Released: Build Production Web, Desktop and Mobile Apps in Python Only appeared first on MarkTechPost.

Flet 1.0 Released: Build Production Web, Desktop and Mobile Apps in Python Only Read Post »

AI, Committee, 新闻, Uncategorized

Meta Launches Muse for Mac: A Personal AI Agent That Works Across Your Files, Mail, Messages, Calendar and Notes

Meta has released Muse for Mac, the first version of Muse that can complete things on a user’s computer. The agent works with local files and native apps, where your data already lives. It adds a desktop layer to an agent that launched on phones, the web and WhatsApp earlier this month. Is it deployable? Yes, for end users. It is a free macOS download today, only available in the US for now. It is a hosted consumer agent, not an open model you can self-host. What Meta Shipped Mark Zuckerberg announced the Mac app on X, noting that it works across apps, files, calendar, notes, and messages. His post added, “The team is shipping fast.” Meta’s Chief AI Officer Alexandr Wang also announced the launch the same day. Muse itself is not new this week. Muse launched on September 8th in the US across iOS, Android, the web and WhatsApp. According to TechCrunch, it quickly rose to the top of the U.S. App Store charts after that launch. Muse for Mac is out today! It works across apps, files, calendar, notes, and messages on your computer. You control what it can access. The team is shipping fast. Download at https://t.co/BX3oX19Zcl — Mark Zuckerberg (@finkd) September 17, 2026 What Muse for Mac Can Do On the Mac, Muse can interact with your files, messages, calendar, notes and mail, all within their native applications. Meta frames it around everyday tasks that span several apps. You can ask it to organize folders, finish a form using information stored in your files, or build an end-of-day summary from emails, messages, and notes. The practical shift is context gathering. A normal chatbot needs you to copy and paste information into a prompt. Muse can potentially collate different pieces of context across the computer. One task might touch a Calendar event, a Mail thread, a document in a folder and a Messages conversation. Muse also runs asynchronously. Meta noted that the agent continues working in the background even when the desktop window is closed. You can start something on your phone, check in from your laptop or nudge it through WhatsApp, with Muse keeping the thread across devices. How Permissions Work Local access raises the stakes, so the controls matter most here. Access to your computer is opt-in, while Full Disk Access is optional. You decide what permissions Muse gets and can change them anytime through Settings. Destructive or outbound actions are gated. Meta says sensitive actions such as deleting files or sending messages require approval. In practice, Muse can sort a folder freely but must stop before it deletes anything. It can draft a summary but must ask before sending it. The Stack Behind Muse Muse is powered by Muse Spark, Meta’s most capable model to date, built for real-world agentic work, per Meta’s launch post. The same model powers Muse Code, a coding agent available for MacOS and Windows. The cloud side runs on Muse Secure VM. Muse runs on its own dedicated computer in the cloud, contained so no one else’s agent can reach it. A separate Sentinel agent runs on that same machine, kept apart from Muse at the system level. Nothing Muse does reaches the internet unless the Sentinel approves it. There is one caveat worth stating plainly. Secure VM isolates your data from other users, but it does not prevent Meta from accessing your data when necessary to operate the service. Meta plans to introduce Muse Confidential VM later in 2026, encrypting the entire VM with a key only the user holds. Meta also runs a public bug bounty for Muse. Interactive Explainer: How Muse for Mac Gets a Task Done Key Takeaways Muse for Mac is Meta’s first Muse version that acts directly on your computer. It works with Files, Mail, Messages, Calendar and Notes in their native apps. Access is opt-in, Full Disk Access is optional, and settings can change anytime. Deleting files or sending messages always requires your approval first. Free up to 100M tokens per week; US only for now. The post Meta Launches Muse for Mac: A Personal AI Agent That Works Across Your Files, Mail, Messages, Calendar and Notes appeared first on MarkTechPost.

Meta Launches Muse for Mac: A Personal AI Agent That Works Across Your Files, Mail, Messages, Calendar and Notes Read Post »

AI, Committee, 新闻, Uncategorized

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

First, separate 2 ideas: containers vs. quantization methods Most confusion comes from mixing 2 layers. A container defines how tensors are stored on disk. A quantization method defines how weights are squeezed into fewer bits. Containers: safetensors, GGUF, PyTorch pickle (.bin / .pt). Methods: GPTQ, AWQ, bitsandbytes NF4, llama.cpp K-quants and I-quants. Both at once: EXL2 and EXL3 are a method plus a storage layout tied to one inference library. A quick memory rule of thumb Weight memory ≈ parameters × bits-per-weight ÷ 8. Model 16-bit ~4.5 bits per weight 8B ~16 GB ~4.5 GB 70B ~140 GB ~39 GB This is arithmetic, not a vendor benchmark. It covers weights only. The KV cache and runtime overhead add more on top. 1. Full precision: safetensors and PyTorch .bin Unquantized models usually ship as 16-bit weights, in either pytorch_model.bin or model.safetensors. The older .bin / .pt files use Python pickle. Loading a pickle file can execute arbitrary code, which makes untrusted checkpoints a security risk. Safetensors, created at Hugging Face, removes that risk. A file is a small JSON header plus raw tensor buffers, with nothing executable inside. Tensors can be memory-mapped and loaded one at a time without reading the whole file. Safetensors is now listed as a PyTorch Foundation project. Important nuance: most GPTQ, AWQ, EXL2, EXL3, and MLX models are also stored in .safetensors files. The quantization lives in the tensor contents and a config file, not in a new container. 2. GGUF (llama.cpp) What it is GGUF is a binary format for running models with GGML and GGML-based executors such as llama.cpp. It was created by Georgi Gerganov, who also leads llama.cpp (Hugging Face docs). It was introduced on August 21, 2023 as the replacement for the older GGML format. Why it replaced GGML The older GGML, GGMF, and GGJT files could not say which architecture a model belonged to. Adding a new hyperparameter broke every existing file. GGUF switched to typed key-value metadata, so new fields can be added without breaking old files. Design goals The spec lists 5 goals: single-file deployment, extensibility, mmap compatibility, easy loading, and complete information inside the file. Unlike tensor-only formats, GGUF can carry the tokenizer, special tokens, and a Jinja chat template alongside the weights. Reading GGUF quant names The suffix in a name like Q4_K_M.gguf tells you the scheme. Figures below come from the Hugging Face GGUF docs. Type How it works Bits per weight Q4_0 / Q4_1 (legacy) 4-bit round-to-nearest in 32-weight blocks; Q4_1 adds a block minimum 4.5 / 5.0* Q8_0 (legacy label) 8-bit round-to-nearest in 32-weight blocks 8.5* Q2_K 16 blocks × 16 weights per super-block, 4-bit scales and mins 2.625 Q3_K 16 blocks × 16 weights, 6-bit scales 3.4375 Q4_K 8 blocks × 32 weights, 6-bit scales and mins 4.5 Q5_K 8 blocks × 32 weights, 6-bit scales and mins 5.5 Q6_K 16 blocks × 16 weights, 8-bit scales 6.5625 IQ4_XS 256-weight super-blocks, uses an importance matrix 4.25 IQ3_XXS Same I-quant family 3.06 IQ2_XXS Same I-quant family 2.06 IQ1_S Same I-quant family 1.56 *Derived by hand, not listed in the HF table: 32 weights plus a 16-bit scale (and a 16-bit minimum for Q4_1). Checking the Q4_K math: A super-block holds 256 weights. 256 × 4 bits = 1,024 bits. Add 8 blocks × 12 bits of scales and minimums (96 bits). Add a 16-bit super-scale and 16-bit super-minimum (32 bits). Total: 1,152 ÷ 256 = 4.5 bits per weight. What _S, _M, _L mean: These are mixes, not new types. For example, llama.cpp describes Q4_K_M as using Q6_K for half of the attention.wv and feed_forward.w2 tensors and Q4_K elsewhere (Unsloth docs). That is why a Q4_K_M file averages above 4.5 bits per weight. Newer types: The HF table also lists TQ1_0 and TQ2_0 for ternary weights, plus MXFP4, a 4-bit microscaling floating-point type. A labeling quirk: Hugging Face files Q8_0 under “legacy” types. In practice, Q8_0 remains the standard near-lossless GGUF choice. Quality vs. size Hugging Face’s reference table for a Llama-2-7B-class model shows the trade-off: Quant Perplexity Change vs FP16 Size FP16 5.9565 baseline 13.0 GB Q8_0 5.9584 +0.03% 7.0 GB Q6_K 5.9642 +0.13% 5.5 GB Q5_K_M 5.9796 +0.39% 4.8 GB Q4_K_M 6.0565 +1.68% 4.1 GB Illustrative only. These numbers come from a 2023-era 7B model; newer models can react differently. Importance matrix (imatrix) GGUF quantization can use calibration data. llama.cpp’s llama-imatrix computes an importance matrix from a text file. llama-quantize –imatrix then uses it to improve quality. For 1-bit and 2-bit mixes, llama-quantize warns if no imatrix is supplied. Naming convention The spec defines filenames as base name, size label, fine-tune, version, encoding, type, and shard. Shards use a 5-digit counter such as 00003-of-00009. Optional mmproj- and mtp- prefixes mark vision projectors and multi-token-prediction draft modules. Where GGUF runs GGUF is native to llama.cpp and its ecosystem. Hugging Face documents use with llama.cpp, LM Studio, GPT4All, and Ollama. vLLM support exists but is limited. vLLM calls it highly experimental and under-optimized, and GGUF now needs the out-of-tree vllm-gguf-plugin. 3. GPTQ GPTQ was written by Elias Frantar (IST Austria), Saleh Ashkboos and Torsten Hoefler (ETH Zurich), and Dan Alistarh (IST Austria & Neural Magic). It first appeared on arXiv on October 31, 2022. It was published at ICLR 2023. How it works GPTQ is a one-shot, post-training weight quantization method. It uses approximate second-order (Hessian) information to decide how to round weights. Rounding error in one column is compensated by adjusting weights not yet quantized. It needs a small calibration dataset but no retraining. Main results Quantized 175B-parameter models in about 4 GPU hours, down to 3 or 4 bits per weight (arXiv). Reported negligible accuracy loss at those bit widths. End-to-end speedups over FP16 of about 3.25x on NVIDIA A100 and 4.5x on A6000 (HF paper page). Reading GPTQ names GPTQ repos often include GPTQ or tags like 4bit-128g in the name. Group size (128g): one scale per 128 weights. Smaller groups improve accuracy but add a little size. Act-order (desc_act):

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026) Read Post »

AI, Committee, 新闻, Uncategorized

OpenClaw Releases 2026.9.5 With Atomic Updates, Plugin Hot Reload, Conversation Sharing, and Expanded GPT Live

OpenClaw is an open-source, MIT-licensed personal AI agent that you run on your own machines. Its Gateway connects models, tools, and chat channels such as Telegram, Slack, and Discord. The project has now shipped version 2026.9.5, announced on X. The release bundles 4,179 pull requests and 64 direct commits, with credits to 502 contributing accounts. The main change is Atomic Updates, which targets a long-running complaint: updates that break a working agent. Is it deployable? Yes, Version 2026.9.5 is the current latest tag on npm. It is self-hostable and needs Node 24.16+ or 26.1+. Why OpenClaw Updates Kept Breaking The OpenClaw team explained the problem in a blog post with maintainer Jason Sy. Before the fix, an update had 2 outcomes: incremental improvement or catastrophic failure. In the failure case, the old version went down as well. That left no agent online to help with the repair. Two factors made this hard. First, OpenClaw has thousands of config options, so testing every permutation is near impossible. Second, maintainers rarely felt the pain themselves. They are developers who ask Claude or Codex to update their claw. For many users, the claw is their only agent. The OpenClaw 2.0 launch in early September made the issue too large to ignore. How Atomic Updates Work According to the Claw team, the needed pieces already existed in the upgrade process. They were in the wrong order. The new flow works like this: The existing Gateway keeps running while the update is prepared. The next version is checked against a private copy of your setup. OpenClaw switches over, then verifies the updated installation. If the update fails, it rolls back to the last working configuration. OpenClaw always preserves a working agent, so it can help diagnose a failed upgrade. The team also added an issue reporting button for updates. The release notes list clear limits. Atomic Updates apply on supported update paths only. Rolling back the application cannot undo database migrations. The private validation copy is not a backup, so keep a verified backup before upgrading. If an interactive update fails, AI repair starts only after you choose Yes. It uses your account and tokens, and a 30-second timeout skips it. Interactive Explainer: OpenClaw 2026.9.5 What Else Ships in 2026.9.5 Plugin hot reload: you can install or reload supported plugins without restarting the Gateway. It works from the CLI or an authorized chat command. The CLI also accepts several plugins in 1 command. Conversation sharing: Session Share gives teammates on another paired installation read-only access to selected conversation groups. Recipients see conversation text and eligible forks. They do not see subagents, tool activity, or reasoning. Revocation cannot recall what was already received. Expanded GPT Live: you can speak while GPT Live replies in supported Meet, Teams, and Zoom meetings. It can consult your OpenClaw agent during meetings or phone calls. Live is audio-only, so the notes point to gpt-realtime-2.1 for camera use. Shared browser pages: a shared Browser dashboard lets you and your agent use the same page. It runs on a local OpenClaw-managed browser profile, not your laptop cookies. Conversation archiving: cold storage compresses older, inactive history. It is off by default and archives after 30 days once enabled. Reopening a conversation restores it and makes it searchable again. Specialist-agent setup: guided setup can create a chief of staff, researcher, writer, and reviewer. You can also pick a single specialist. Nothing is created before you approve the proposal. One upgrade warning applies to everyone. This release changes the conversation database even with archiving off. Going back requires the matching older build and a backup. How To Install or Upgrade New installs can use the official script: Copy CodeCopiedUse a different Browser curl -fsSL https://openclaw.ai/install.sh | bash If you already manage Node.js, install the published package: Copy CodeCopiedUse a different Browser npm install -g openclaw@latest –allow-scripts=openclaw openclaw onboard –install-daemon Existing users can run openclaw update. See the updating guide for manual paths. The release also adds a FreeBSD CLI install route using system Node and npm. Key Takeaways OpenClaw 2026.9.5 ships 4,179 pull requests from 502 contributing accounts. Atomic Updates validate the next version while the current Gateway keeps running. Failed updates roll back, and a working agent stays available to diagnose. Plugins now install or reload without a Gateway restart. Back up first: rollback cannot undo database migrations. The post OpenClaw Releases 2026.9.5 With Atomic Updates, Plugin Hot Reload, Conversation Sharing, and Expanded GPT Live appeared first on MarkTechPost.

OpenClaw Releases 2026.9.5 With Atomic Updates, Plugin Hot Reload, Conversation Sharing, and Expanded GPT Live Read Post »

We use cookies to improve your experience and performance on our website. You can learn more at 隱私權政策 and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
zh_CN