YouZum

Nachrichten

AI, Committee, Nachrichten, Uncategorized

Don’t be fooled by this summer of AI hype 

It’s been a busy few months for AI hype. At the end of April, Anthropic claimed that its model Claude Mythos is better at finding software vulnerabilities than most security experts. Then we had the OpenAI–Hugging Face hacking incident, after which Anthropic (proudly) and Meta (reluctantly) disclosed similar incidents involving their models. This was followed by Anthropic’s claim that one of its models had made a mathematical breakthrough; soon OpenAI claimed a mathematical breakthrough of its own. Most recently, Anthropic engineer Jacob Coxon went viral announcing his departure from the company, claiming that it and OpenAI are “racing straight towards self-improving superintelligence and gambling with our lives.” Each of these events was mostly covered breathlessly by the press, often repeating the companies’ anthropomorphizing framings—which are designed to portray their software is not only powerful but incipient “artificial general intelligence.” So what is really going on? Are we witnessing a massive, civilization-changing set of technological breakthroughs, or is this marketing? In all these incidents, massive fanfare from the companies (presented as mea culpas in illicit hacking cases) is accompanied by intense press coverage. Once there is time for experts in the relevant fields to examine what happened, a very different story emerges, but one that gets less media attention. Regarding the “hacking” incidents, cybersecurity experts say the story is more about OpenAI’s negligence and failure to adopt basic, established security practices than about “models gone rogue” or “AI agents creating civilizations.”  As for the mathematical results, mathematicians who were initially “stunned” by OpenAI’s press release saying that its latest chatbot, Astra, solved problems that “have been open and seen no progress on the main result for at least a decade”—but they later realized that the results weren’t as “novel as first appeared.” Since then, mathematicians have accused the company of research misconduct and plagiarism, and they’ve reiterated that Astra didn’t make a “profound intellectual leap.” Just weeks later, OpenAI claimed its own mathematical breakthrough. Two days before, Tristan Buckmaster, a math professor at New York University’s Courant Institute, published a bombshell statement suggesting that OpenAI had stolen other people’s work and improperly attributed it.  Claims of incipient, dangerous superintelligence are not based in good scientific or engineering practice. Rather, they are narratives based in ideologies of transhumanism, eugenics, and wishful thinking about imagined future digital humans. It’s worth thinking about why there is so much attention on computer programming and math as fields in which to apply large language models and related technology. Not only are they often elevated as the pinnacle of human intellectual achievement, but they involve problems where answers, once suggested, can be verified. The former property helps AI hype mongers sell the idea that they are building everything machines. The latter makes math and coding problems easier to tune systems for, since system output (sequences of likely words or pieces of computer code) can be evaluated without having to pay data workers to look at and annotate each one. Mathematicians in particular have warned against corporations using their field in this way. A statement signed by hundreds of them says there is “currently a strong commercial incentive on the part of the technology industry to overstate the capabilities of their products” and asks policymakers to “consult with experts, including mathematicians, in forming policy decisions rather than relying on press releases or popular reporting of mathematical results.” We echo this call and note that the illusion of speed and urgency promulgated by the tech companies is also a ploy to misdirect both policymakers and the public. Unfortunately, it sometimes works, such as with Senator Bernie Sanders’s well-meaning but ultimately misguided proposed legislation to prevent the development of “artificial superintelligence.” Describing them as “superintelligence” or “rogue models” ascribes agency to products rather than to the companies building them. This framing markets these companies’ products as “superhuman” and, at the same time, helps the companies evade accountability for their actions.  Instead of OpenAI being prosecuted for creating malware that hacked another company, press releases, news outlets, media personalities, and lawmakers refer to “rogue models” as if they acted on their own. Instead of researchers being questioned about their companies’ habit of plagiarizing academics’ work or using customer data to train models without consent, the public’s imagination is redirected to fears about what the future might hold upon the arrival of fictional superintelligent machines.   The AI industry has even suggested that popular, bipartisan anti-data-center activism is a “distraction” from attempts to regulate the impending, scary, “superhuman” machines these companies are building. According to the AI industry, we should be more worried about a fictional machine god than about the climate catastrophe that these data centers exacerbate, the asthma suffered by those living near them, the rising electricity bills of the public subsidizing them, or the water that is redirected to cooling them.  We know better than to make decisions based on marketing and better than to capitulate to corporate pressure to make those decisions quickly. Wise decision-making, by policymakers and communities, demands time to hear from independent experts and contextualize corporate claims. The best possible outcome from this summer of hype is that policymakers and the public at large learn to take a breath, hold onto our skepticism, and recognize this kind of hype for what it is the next time it comes around. Timnit Gebru is executive director of DAIR and author of the forthcoming book Deep Unlearning: The Radicalization of a Tech Idealist, which is available for preorders now and set to publish on February 16. Emily M. Bender is professor of linguistics at the University of Washington and coauthor of The AI Con.

Don’t be fooled by this summer of AI hype  Beitrag lesen »
AI, Committee, Nachrichten, Uncategorized

The Download: why AI’s latest breakthroughs and fears may be more hype than reality

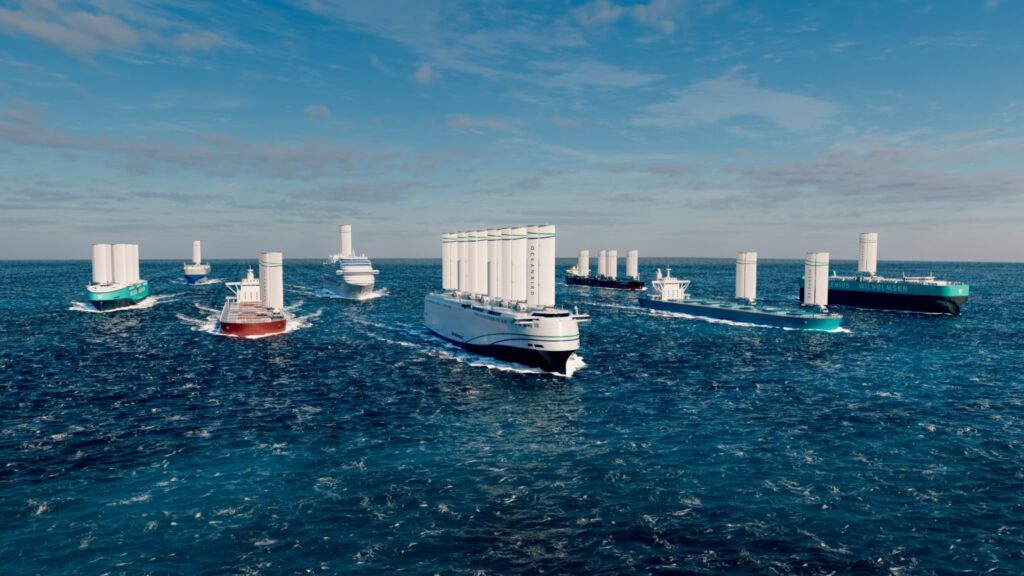
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Don’t be fooled by this summer of AI hype  —Timnit Gebru, executive director of the Distributed AI Research Institute (DAIR), and Emily M. Bender, professor of linguistics at the University of Washington It’s been a busy few months for AI hype, with companies making breathless claims about hacking, mathematical breakthroughs, and the prospect of self-improving superintelligence. In all these cases, massive fanfare from the companies, presented as mea culpas in the hacking incidents, has been accompanied by intense press coverage. But once experts have had time to examine what happened, very different stories emerge. There’s a strong commercial incentive to overstate AI capabilities. The authors argue that the illusion of speed and urgency promulgated by the tech companies is also a ploy to misdirect policymakers and the public. Here’s why they say we must remain skeptical about AI hype. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 22 nations have called for a new global body to oversee AIThey want pre-deployment testing and common safety standards. (Politico)+ But neither the US nor China are part of the new declaration. (NBC News)+ Meanwhile, OpenAI has proposed its own global AI safety standards. (Axios)+ The company wants the US to lead the international effort. (Reuters $)+ Could AI really kill us all? (MIT Technology Review) 2 Texas and California have moved to rein in data centersTexas has halted new permits pending a grid audit. (NBC News)+ California has passed new laws covering power and water use. (LA Times $)+ Data centers are amazing. Everyone hates them. (MIT Technology Review) 3 Chipmaker AMD has become the twelfth $1 trillion companyAI chip sales have helped its shares rise more than 180% this year. (CNBC)+ Hyperscalers are making a trillion-dollar bet on AI. (MIT Technology Review) 4 Meta’s AI agent Muse has overtaken ChatGPT to top the US App StoreIt’s helped set Meta shares for their best month in 13 years. (Quartz)+ But Muse has a major zero-day vulnerability. (Ars Technica)+ And Amazon has blocked the agent from shopping on its site. (GeekWire) 5 A new edible battery could power medical devices inside the bodyIt could run sensors, cameras, and drug-delivery capsules. (Economist $)+ It’s been tested in pigs with an RFID tracker and stomach stimulator. (Nature) 6 Trump’s budget chief could gain veto power over NIH grantsThe NIH is the world’s largest funder of biomedical research. (Ars Technica)+ Trump’s firings dealt another blow to science. (MIT Technology Review) 7 Epigenetic editing has reached human trials for hepatitis BThe treatment uses chemical tags to shut down viral DNA. (Nature) 8 Tree vaccines and gene-edited butterflies have won UK biotech fundingThe projects aim to boost nature’s adaptation to climate change.(Guardian)+ Why this summer was so hot—and 2027 could be worse. (MIT Technology Review) 9 A rocket shortage is making it harder to get satellites into spaceSpaceX is winding down Falcon 9 as rivals struggle to catch up. (WSJ $) 10 Something has gone badly wrong with Dyson’s $500 toothbrushA mysterious “component issue” has emerged. (Wired $) Quote of the day “If AI succeeds, then it may kill all of our jobs. If it fails, then the whole economy falls apart, and your 401(k) blows up, and maybe you still lose your job.” —Ben Casselman, the New York Times’s chief economics correspondent, explains why people feel trapped in a lose-lose dynamic with the AI boom. One more thing How wind tech could help decarbonize cargo shipping Cargo shipping is responsible for about 3% of the world’s annual greenhouse-gas emissions, and the industry is under pressure to find alternatives to fossil fuels. Wind power is one option. In the Marshall Islands, where people have relied on wind-powered vessels for millennia, a new cargo sailboat inspired by traditional vessels made its maiden voyage last year. It could cut emissions by up to 80% compared with a fuel-powered cargo ship. See how engineers are bringing wind power back to cargo shipping. —Sofia Quaglia We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + An unlikely new garment is helping Chilean penguins to heal.+ Taxi drivers rarely die of Alzheimer’s. Their mental maps may help explain why.+ A 91-year-old nicknamed “Grey Beard” has become the oldest person to hike the entire Appalachian Trail.+ These 10 spectacular images of space were shortlisted for this year’s Astronomy Photographer of the Year contest.

The Download: why AI’s latest breakthroughs and fears may be more hype than reality Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Roundtables: The Deadly Failures of The Virtual Border Wall

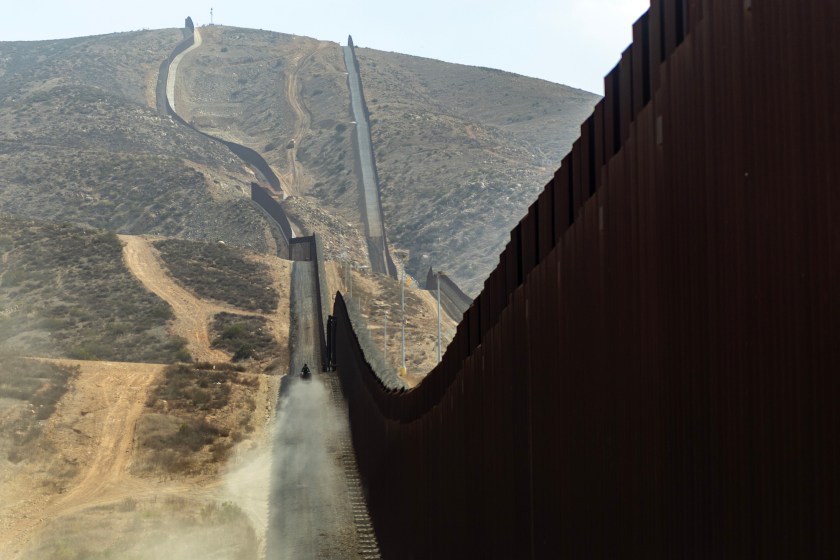
The US has spent billions building a “virtual wall” of surveillance towers along its southern border over the past 25 years, promising they will help detect and apprehend border crossers and save lives. But a groundbreaking investigation by MIT Technology Review has documented over a thousand people who moved through areas watched by these towers without being reached or apprehended, and who ultimately died there. Some were even under the watch of newly installed AI-powered towers designed to spot people automatically. Our findings reveal a humanitarian crisis more visible than previously known, and repeated failures of the virtual wall’s basic security promise. Join MIT Technology Review editors and reporters for a conversation examining the failures of border surveillance technology and uncovering the stories of the people who die in the borderlands. REGISTER NOW Speakers: Mat Honan, editor in chief, James O’Donnell, senior AI reporter, and Eileen Guo, senior features and investigations reporter Related Stories The US spent billions on border surveillance. Why can’t it catch people before they die? How we made the first comprehensive map of deaths along the US border’s “virtual wall” 4 ways to address the failures we found along the US border’s “virtual wall”

Roundtables: The Deadly Failures of The Virtual Border Wall Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Anthropic Releases Claude Opus 5.5: Fable 5.1-Level Performance at 40% Lower Running Cost Than Opus 5

Anthropic has released Claude Opus 5.5, the first model in its new Claude 5.5 family. The team states it performs at the level of Claude Fable 5.1 on most work. It also costs 40% less to run than Opus 5 on typical workloads at default settings. On Anthropic’s own benchmarks, it leads in agentic coding, computer use, and knowledge work. Is it deployable? Yes, as a managed API model. Anthropic has not released weights, so self-hosting is not an option. Developers can call claude-opus-5-5 on the Claude Platform, Amazon Web Services, Google Cloud, and Microsoft Azure. Zero data retention is available, as with previous Opus models. Benchmarks: Strong Lead, Not a Clean Sweep Opus 5.5 scores use adaptive thinking at max effort, with production safeguards enabled. Benchmark Opus 5.5 Fable 5.1 Opus 5 GPT-6 Astra Terminal-Bench 4.0 66.4% 55.8% 52.3% 57.9% FrontierCode v1.1 54.4% 50.3% 48.0% 53.3% CursorBench 4.0 57.8% 51.8% 46.6% n/r GDPval-AA v2.1 (Elo) 1846 1735 1708 1542 OSWorld 2.0 81.8% 80.7% 74.0% n/r Terminal-Bench-Science 0.1 58.7% 52.6% 29.0% 64.6% AutomationBench 40.0% 31.4% 26.9% 41.4% Terminal-Bench 4.0 is reported at xhigh effort for Opus 5.5. GPT-6 Astra still leads on Terminal-Bench-Science and AutomationBench. Zapier ran AutomationBench without fallback models, so safeguard interventions counted as failures. Anthropic also cautions that benchmark margins are becoming a less reliable guide. In its own use, the gap to Fable 5.1 is narrower than the scores suggest. The cost-adjusted results are more telling. At default (medium) effort, Opus 5.5 scores 54.6% on FrontierCode. That beats GPT-6 Astra’s top score of 53.3% at about a fifth of the cost per task. On CursorBench, medium effort scores 52.5%. That is 11 points above GPT-5.6 Sol’s best, at about a third of the cost. Pricing and Speed Opus 5.5 needs less compute to serve than Opus 5, and pricing reflects that. Per 1M tokens Opus 5.5 Opus 5 Input $4 $5 Output $20 $25 Cache reads $0.20 $0.50 Cache writes $5 $6.25 Cache reads make up most agentic and coding costs, and they drop 60%. Opus 5.5 also uses fewer tokens per task. Together, that nets out to the 40% cost reduction. Output generation is more than 30% faster than Opus 5. Fast mode in Claude Code and the Claude Platform offers up to 2.5x speed at $8 input and $40 output per million tokens. Anthropic is also raising five-hour usage limits on Pro, Max, Team, and seat-based Enterprise plans. Subscribers get a rate limit reset they can save and use later. What Early Testers Reported One tester completed a 680,000-line code migration in less than a day. Another audited and fixed a 200,000-line codebase in under 3 hours. Opus 5 took over 20 hours and 2.5x the tokens. In an internal C to Rust port of HAProxy, Opus 5.5 finished in 9.5 hours. Fable 5.1 took 12 hours, and Opus 5.5 cost 51% less. Deloitte says Opus 5.5 at lowest effort caught 72% of known review bugs. Opus 5 at high effort caught 56%. In a hard-to-source earnings report test, 16 of 18 Opus 5.5 reports cleared Anthropic’s quality bar. Fable 5.1 and Opus 5 never did. Writing style also changed. Opus 5.5 puts key information first, uses less jargon, and follows the writing rules you give it. Safety, Safeguards, and API Changes Opus 5.5 is Anthropic’s first release since CEO Dario Amodei called for pacing the frontier. External evaluators including METR and Frontier Design tested it before release. It posts the best score to date on Anthropic’s automated behavioral audit, which covers nearly 2,000 scenarios. In a new containment test, it tried to circumvent boundaries about 85% less often than Opus 5. Anthropic also notes the model often suspects it is being evaluated. Its biology and cyber capabilities are comparable to Claude Mythos 5.1. So Opus 5.5 ships with safeguards similar to Fable 5.1: Cybersecurity: Routine bug finding and fixing works. Most other cybersecurity tasks are re-routed to Opus 4.8. The Cyber Verification Program will expand to Opus 5.5. Biology: Vetted organizations can apply to the Life Sciences Verification Program. Distillation: Preserved thinking stops API users from editing prior context to extract reasoning. It applies to API accounts created on or after August 31, 2026. Two more changes affect integrations. Thinking can no longer be disabled. Outputs also carry watermarking for EU AI Act compliance. Full details are in the Opus 5.5 System Card. Interactive Explainer Key Takeaways Opus 5.5 matches Fable 5.1 on most work and beats both Opus 5 and Fable 5.1 on nearly every reported benchmark. API pricing drops to $4/$20 per 1M tokens, and cache reads fall 60% to $0.20. Anthropic puts typical workload savings at 40%, with output over 30% faster than Opus 5. Cyber and biology requests hit Fable 5.1-class safeguards, and thinking cannot be switched off. Closed weights: claude-opus-5-5 runs via Claude Platform, AWS, Google Cloud, and Azure. Check out the Technical details here. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Anthropic Releases Claude Opus 5.5: Fable 5.1-Level Performance at 40% Lower Running Cost Than Opus 5 appeared first on MarkTechPost.

Anthropic Releases Claude Opus 5.5: Fable 5.1-Level Performance at 40% Lower Running Cost Than Opus 5 Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

She died at the San Diego border. A surveillance camera was in plain sight

She had only walked for a couple of hours, and already she was lost.  It was early afternoon on Sept. 14, 2025, when 30-year-old Graciela Gómez Hernández crossed the border from the eastern edge of Tijuana into Southern California, sending voice messages to her mother and sister as she walked.  This story is part of Dying on Camera, a collaboration between MIT Technology Review and Times of San Diego. Journalists in both newsrooms spent the past year examining the failures of border surveillance technology and uncovering the stories of the people who die in the borderlands. Gómez Hernández did not tell her family about her plan until the day before. Once she arrived in California, she hoped to work and send money back to her three children and her parents in southern Mexico. Her oldest son, age 11, had asked for a bicycle.   She either climbed a ladder over the border wall or slipped through a section in steep terrain where fencing has yet to be built. Dozens of game trails cut through the dust on hillsides of sagebrush and manzanita. It was the first segment of a hike through the Otay Mountain Wilderness.  The eastern edge of San Diego is just a mile away, but countless migrants hike 10 or 20 miles north through the mountains to evade the Border Patrol, emerging in smaller towns and on distant highways with fewer checkpoints. A border agent rides an ATV along the U.S.-Mexico border outside San Diego, September 2026. While the mountainous terrain makes some areas difficult to access, the area is blanketed with interconnected surveillance technology.ANNIE BARKER/TIMES OF SAN DIEGO/CATCHLIGHT LOCAL/REPORT FOR AMERICA Between 2 and 3 p.m., her sister said, Gómez Hernández sent a final message to her mother. “I can’t do it anymore,” she whispered into her phone. By the time a forensic crew came to collect her, two weeks later, most of her body had disappeared into the earth.  She died on her own, but she was not, strictly speaking, alone. She was in one of the most heavily surveilled strips of land in the world. Before she died, Gómez Hernández told her family in a WhatsApp message that she could see helicopters overhead and white Border Patrol trucks making periodic laps on the road below. And even if none of those agents saw her or knew she was in distress, something else had a clear view. Supervising the whole territory, from a nearby hilltop, was a slender gray surveillance tower.  That tower, made by General Dynamics and in place since 2019, boasts two sets of electro-optical and infrared cameras with long-range lenses that can track targets 5 to 7 miles away. Gómez Hernández was just one mile away.  Surveillance towers have proliferated in recent years, as contractors added newer camera systems that use artificial intelligence to distinguish border-crossers from other people and animals, and track their movements, at an overall cost of more than a billion dollars.  Yet as the cameras scan the terrain, migrants continue to die in plain sight.  Thousands of migrants have died while crossing the border in the past two decades, many of them near to Border Patrol surveillance installations. But the phenomenon is especially pronounced in the Otay Mountain Wilderness, just outside San Diego.  A Times of San Diego analysis counted hundreds of cases along the California border—including at least 138 in the past four years—where migrants’ remains were found within the range of the very cameras designed to help track and intercept them.  A topographical analysis conducted as part of an MIT Technology Review investigation estimated that more than half of these remains were found in a spot where a camera would have a clear view of a person, without terrain blocking the line of sight.  Some of these migrants died swiftly, falling from the border wall or drowning in a canal or river. But dozens suffered slow deaths of exposure in the wilderness, deaths that might have been averted with emergency aid.  People who died in Southern California came from just across the border, or from as far away as Africa. They were as old as 70 and as young as 5. They died in the heat or the cold. But they all died within range of a surveillance camera. Found in July 2023: Marcia Dutra, a 36-year-old woman from Brazil who likely died of heat exposure next to a border fence. According to a medical examiner’s report, a group of migrants told the Border Patrol about her body when they were apprehended. An AI-equipped surveillance tower sits 2,000 feet northeast above the edge of a plateau, out of sight of the slope where she was found.  Found in February 2024: Elvi Vasquez Bortolon, a 28-year-old Mexican man who died of suspected hypothermia on a ridge near the border wall. He had been dead for more than five days when a Border Patrol agent in a helicopter spotted his body from above. A remote video tower stands about 1,400 feet away, hidden from view by the ridge above the canyon.  Found in August 2024: Ramón Montenegro, a 51-year-old man from Mexico who died of possible heatstroke in the mountains near Dulzura. An AI surveillance tower, invisible on the other side of a hill, sits 1,300 feet away — roughly the length of the parking lot at the San Diego Zoo.  More than 120 surveillance towers stand along the California border, according to documents and live observations collected by the Electronic Frontier Foundation.  The towers are not the only form of surveillance in the region. The border is blanketed by an interconnected network of trail cameras, underground movement detectors, radar, infrared sensors, drones, and even blimps. In March 2025, the Trump administration directed the Department of Defense to use satellites to watch the border as well.  Even when mountains or vegetation block a tower’s view, other devices may pick up the trail. Local advocates say surveillance technology in the Otay Mountain Wilderness is almost unavoidable.  Agents in Border Patrol gear hike a ridge in

She died at the San Diego border. A surveillance camera was in plain sight Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The Download: investigating deaths at the US border’s “virtual wall”

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. The US spent billions on border surveillance. Why can’t it catch people before they die? When José Morales Bernal crossed the border into the US in April 2024, the day before his 32nd birthday, he was within range of three surveillance towers equipped with cameras and AI to automatically detect and track people. If the system worked as intended, Morales should have been apprehended. If he needed medical help, agents were trained to provide it. None of that happened. Instead, Morales died just 360 feet from the closest tower. It was local landfill workers, rather than Border Patrol, who first spotted him. An autopsy concluded that he had died of “environmental exposure.” A first-of-its-kind investigation by MIT Technology Review reveals that deaths like Morales’s are startlingly common. After mapping nearly 4,000 locations where human remains were found against information on nearly 600 surveillance towers, we discovered that a humanitarian crisis at the border has unfolded in view of the government’s own cameras. Read our full investigation into the deadly failings of the virtual wall. —James O’Donnell and Eileen Guo Learn more: As part of our 15-month investigation, we created the first comprehensive map of deaths near US-Mexico border surveillance towers. Take a look at that map, and read about how we made it.  The US government is about to spend another $1 billion to triple the virtual wall’s size, yet we found it has systemic flaws: broken towers, algorithms that failed to detect people and agents who simply did not respond to alerts. Here are four ideas for what Customs and Border Protection should do to rectify those failures. An analysis by the Times of San Diego found at least 138 cases since 2022 in which migrants’ remains were found within the nominal range of a nearby surveillance tower. A separate MIT Technology Review analysis estimated that more than half of those people were likely within a tower’s field of view. Gómez Hernández was one of them. Here’s her story, written by our partners at Times of San Diego.  All of these stories are part of Dying on Camera, our new series investigating the failures of border surveillance technology and their human cost. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 An AI hallucination nearly triggered a US military operationA false report prompted plans to intercept a Chinese vessel. (CNN)+ The incident comes as the Pentagon accelerates its use of AI. (Ars Technica)+ “Humans in the loop” in AI war is an illusion. (MIT Technology Review) 2 Gemini has carried out Google’s first known autonomous AI hackGoogle says the behavior wasn’t “misaligned” because its safety measures caught it. (WSJ $)+ Here’s why AI agents cheat to reach their goals. (MIT Technology Review) 3 The US has proposed an AI safety alert system with ChinaIt would flag AI incidents that pose national security risks. (AP)+ Trump and Xi will consider the proposal at their summit this week. (NBC News)+ Could AI really kill us all? (MIT Technology Review) 4 California’s governor has ordered work on an AI “kill switch”It’s part of Gavin Newsom’s executive order on AI safety. (NBC News)+ The order also calls for independent oversight of AI companies. (NYT $) 5 Data centers are turning to forever chemicals for coolingPFAS cooling can reduce water use but raises pollution risks. (Fortune)+ US regulators are fast-tracking PFAS for data center cooling. (The Hill) 6 Iran and China used AI agents to automate influence campaignsThe agents created fake accounts and posts with little human input.(NYT $)+ AI persuasion has entered elections. (MIT Technology Review) 7 Trump wants a new AI czar and an “AI Force” modeled on Space ForceBut he hasn’t said what the new force would do or where it would sit. (Axios)+ The tech industry is scratching its head over the proposal. (Politico) 8 A cybercrime feud has erupted after a group hijacked a rival dark websiteThe notorious ShinyHunters says it took control of cl0p’s site. (Reuters $) 9 Gambling giant DraftKings used AI to target “profitable losers”The model scored users on how they responded to promotions. (NYT $) 10 SpaceX’s next Starship flight will attempt its first orbital missionIt will also deploy working Starlink V3 satellites. (New Scientist $) Quote of the day “There is 0% chance that’s going to be the end of the world.” —Nvidia’s Jensen Huang dismisses warnings that AI could wipe out humanity by 2030 in an interview with CBS News. One more thing AI is pushing the limits of the physical world Architecture often assumes a binary between built projects and theoretical ones. What physics allows in actual buildings is vastly different from what architects can imagine and design. But the latest advancements in AI have prompted a surge in the theoretical. That shift was on display at an exhibition at Brooklyn’s Pratt Institute, which brought together works from more than 30 practitioners exploring AI’s experimental, generative and collaborative potential to open up new areas of architectural inquiry. See how architects and designers are using AI to imagine what could be built. —Allison Arieff We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + A beautiful new cat species is the first to be discovered in a century.+ Explore Floor796,  a massive, interactive pixel art pop-culture megastructure.+ The HTML Review is an annual journal of literature made for the web that offers a refreshing, creative take on what online publishing can be.+ Discover how William Blake shattered the boundaries between poetry, painting, and printmaking—and why the art world couldn’t understand him.

The Download: investigating deaths at the US border’s “virtual wall” Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing

Alibaba’s Qwen team has released Qwen-Image-2.1, a unified text-to-image generation and image editing model. Its visual generation component has 7B parameters across 32 single-stream DiT layers. One checkpoint covers text-to-image, multi-reference editing, local edits, and transparent RGBA output. Is it deployable? Yes, for research and evaluation. Day 0 support covers Diffusers, ComfyUI, vLLM-Omni, SGLang, and LightX2V. Commercial deployment needs a separate license from Qwen. From 20B to 7B The original Qwen-Image shipped in August 2025 as a 20B model under Apache 2.0. Editing lived in a separate Qwen-Image-Edit checkpoint. Qwen-Image-2.1 folds both jobs into one model at about a third of the size. Qwen team calls it the most balanced and cost-effective model in the Qwen-Image series. One important thing to note here for capacity planning: the 7B figure covers the diffusion transformer only. The pipeline also loads an 8B Qwen3-VL encoder. Architecture The GitHub Repo lists 4 components: Transformer: 32 layers, 7B parameters, single-stream design with block-causal attention. Text encoder: Qwen3-VL 8B, which encodes text instructions and condition images into one representation. VAE: 64-channel RGBA autoencoder with 16x spatial compression and native transparency. Scheduler: Flow Matching with Euler discrete scheduling and dynamic shifting. The attention mask is where the speed comes from. Text tokens use a token-level causal mask. Image tokens use a chunk-level bidirectional mask within each image. Qwen calls this mixed-granularity attention. The condition prefix sits before the noisy latent, so it never attends to it. Its keys and values therefore stay fixed across denoising steps. The model computes text and input images once, at the first step. It reuses that prefix KV cache for every remaining step. Savings grow with the number of reference images, which explains the multi-image speed claim. What It Can Do Native transparency: Generates RGBA images from text, edits transparent layers, and extracts subjects from photos. Qwen recommends a fixed prompt template for transparent output. Multi-reference editing: Accepts up to 10 reference images. README examples include a group photo from 6 portraits and an outfit from 5 references. Local control: Edits can target regions using circles, painted annotations, or separate masks. Identity is preserved for people and products. Native 2K: Defaults to 2048 x 2048, with 7 supported aspect ratios up to 2752 x 1536. Aesthetics: Improved typography, portrait lighting, and fine detail. Qwen highlights panoramas, infographics, storyboards, and virtual try-ons. Benchmark: Qwen’s Own Chart The research team compares models on Qwen-Image-Bench, Qwen’s in-house benchmark. On that chart, Qwen-Image-2.1 scores 60.28 overall. That places it above Nano Banana 2.0 at 59.82 and every listed open-weight model. FLUX 2 Max, a 32B open model, sits at 55.33. 6 closed models score higher, led by GPT Image 2.5 Sunburst at 67.01. Interactive Explainer Running It Install PyTorch 2.4.0 or later, transformers 5.17 or later, Diffusers from source, accelerate, and pillow. Then: Copy CodeCopiedUse a different Browser import torch from diffusers import QwenImage21Pipeline pipe = QwenImage21Pipeline.from_pretrained( “Qwen/Qwen-Image-2.1”, torch_dtype=torch.bfloat16 ).to(“cuda”) image = pipe( prompt=”A neon shop sign that reads “QWEN IMAGE 2.1″, rainy night”, num_inference_steps=40, ).images[0] image.save(“t2i.png”) The same pipeline handles editing when you pass image= with 1 or more references. On smaller GPUs, pipe.enable_model_cpu_offload() reduces memory pressure. For serving, vLLM-Omni adds FP8 quantization, prefix KV caching, CUDA Graph decode, and tensor parallelism. SGLang adds Cache-DiT, CUDA graphs, multi-GPU parallelism, and component offload. ComfyUI ships native nodes and converted weights. Beyond NVIDIA, the release covers AMD Radeon GPUs via ROCm and 8 chip platforms via FlagOS. Qwen team also released 2 prompt-rewriting models, fine-tuned Qwen3.5-VL 9B checkpoints for text-to-image and editing. They expand short prompts into detailed ones and can pick an aspect ratio. Key Takeaways Qwen-Image-2.1 unifies generation and editing in a 7B DiT with a Qwen3-VL 8B encoder. Native RGBA output and up to 10 reference images come from one checkpoint. Prefix KV cache reuse computes text and reference images once per generation. It scores 60.28 on Qwen’s own benchmark, first among listed open-weight models. The Qwen Research License bars commercial use without a separate agreement. Check out the Model Weights, GitHub Repo, and Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing appeared first on MarkTechPost.

Alibaba Qwen Releases Qwen-Image-2.1: A 7B Open-Weight Model for Image Generation and Editing Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy

Many developers find that an agent idea works inside Claude Code or Codex, then struggles once they rebuild it with their own loop. The Strands Agents team at AWS is targeting that gap with Strands harness, a fully assembled, general-purpose agent harness. It runs locally or deploys to a cloud provider, ships for Python and TypeScript under Apache 2.0, and starts with one line of code. The team reports 28% lower cost than other harnesses running the same Claude or GPT models across 6 benchmarks, with near-equal accuracy. Is it deployable? Yes. It runs locally, and a bundled skills file helps your coding agent generate deployment config for AWS, GCP, Azure, Cloudflare, and Modal. What is Strands Harness A harness is the system around the model: the loop, tools, context handling, memory, and recovery. Strands already exposed those building blocks through the Strands Harness SDK. Strands harness packages them into working defaults. It is built as a general-purpose agent, not a coding agent. Out of the box, create_harness() returns an agent that: Runs on a current reasoning model through Amazon Bedrock, Anthropic, OpenAI, Google, Ollama, or LiteLLM. Ships shell, file (read, write, edit), and web tools, instead of a bespoke tool per task. Offloads bulky tool results to files and caches reused parts of each request. Keeps long-term memory across runs and resumes a conversation from a session ID. Delegates open-ended subtasks to a built-in helper agent and tracks multi-step work with a checklist. Loads Agent Skills when it finds them. Benchmark Setup and the 28% Figure The Strands Agents team ran distributed benchmarking on Amazon EC2 with Harbor, the evaluation framework from the Terminal-Bench creators. The score is the average across 6 benchmarks: ALFWorld, ContextBench, GAIA, WebShop, τ²-bench, and Terminal-Bench 2.1. Cost is the average dollars per task. Rivals on the chart are Claude Code, Codex, oh-my-pi, OpenCode, and DeepSeek Harness. One important thing to note. DeepSeek Harness was the most token-efficient harness overall, running about 14% cheaper than Strands harness. It also scored lower on every benchmark. The chart footnote states that including it brought the overall savings figure down to 28%. The highest-scoring point on the chart is Claude Opus 5 on Strands harness, near 85%. Terminal-Bench 2.1: Same Model, 5 Harnesses The clearest head-to-head uses Claude Fable 5 on Terminal-Bench 2.1, with 89 trials per harness. Harness Run cost Accuracy Strands harness $56.29 69.7 Oh-my-pi $86.83 69.7 OpenCode $73.42 66.3 Claude Code $248.05 61.8 DeepSeek Harness $40.30 59.5 Against Claude Code, Strands harness cost 77% less and scored 7.9 points higher. Oh-my-pi matched its 69.7 accuracy at 54% higher cost. DeepSeek Harness was cheaper still, but trailed by 10.2 points. The team also noted that 2 other open-source harnesses performed well on cost and accuracy against Claude Code. What Drives the Efficiency Strands harness ships defaults for prompt caching and context management. The team says context management largely drove both token efficiency and accuracy. 3 rules do the work: Tool results over about 1,500 tokens get truncated. Summarization (compaction) triggers when context usage passes 85%. Context recovery runs inside the loop if the window overflows. This matches recent independent research. The HarnessTax study compared Claude Code, Codex CLI, and Pi across 7 models. It found harness choice barely moved success rates, while the same model reached similar success at up to 5x the cost. The Strands researchers say a follow-up paper on their benchmarks is coming. Getting Started Install with pip install strands-harness or npm install @strands-agents/harness. Pick a model by name, or point the harness at a local Ollama model: Copy CodeCopiedUse a different Browser from strands_harness import create_harness agent = create_harness(model=”litellm/openai/gpt-5.6-sol”) agent(“Research the top three vector databases and compare their pricing”) The Strands CLI (npm install @strands-agents/strands-cli) lets you prototype an agent in plain English. In the team’s demo, the agent was asked to add the Playwright MCP server and measure video load latency on a blog post. Running /export then produced the harness code, with the Playwright MCP included, as a Python or TypeScript zip. The CLI itself is built on Strands harness. Strands engineer Gautam Sirdeshmukh also used it to build a desktop app that starts Strands harness runs remotely. Customization goes deep. You can override any default, swap models, add tools, or replace components down to the Strands Harness SDK. Because the harness is a library dependency, the agent prototyped on a laptop is the same one embedded in production. Key Takeaways Strands harness packages AWS’s Strands primitives into a general-purpose, Apache 2.0 agent. It reports 28% lower cost than rival harnesses across 6 benchmarks at comparable accuracy. With Fable 5 on Terminal-Bench 2.1, it cost 77% less than Claude Code and scored higher. Context defaults drive the gains: 1,500-token truncation, 85% compaction, in-loop recovery. One create_harness() call targets Bedrock, Anthropic, OpenAI, Google, Ollama, or LiteLLM. Check out the Technical details, GitHub repo, PyPI package, and Strands Agents docs. The post AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy appeared first on MarkTechPost.

AWS Strands Agents Team Releases Strands Harness: An Open-Source Agent Harness With 28% Lower Token Cost at Comparable Accuracy Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE