YouZum

Uncategorized

AI, Committee, 新闻, Uncategorized

Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages

Qwen has released Qwen3.8-LiveTranslate, its next-generation real-time simultaneous interpretation model. It listens to live speech, with optional video frames, and returns translated text and speech while the speaker is still talking. The core change is a new Interleave architecture. Qwen reports gains in faithfulness, fluency, and conciseness, with average lagging (LAAL) dropping from 2.8 seconds to 2.3 seconds. The release also adds real-time speaker diarization, synchronized bilingual display, and long-context disambiguation. Deployable? Yes, as a hosted API. It is live on Alibaba Cloud Model Studio and QwenCloud as qwen3.8-livetranslate-flash-realtime over WebSocket. What Changed Under the Hood Simultaneous interpretation is a tradeoff. Waiting longer gives the model more context. Speaking sooner cuts delay for the listener. Qwen3.8-LiveTranslate rebuilds this loop with an Interleave architecture. The latency metric here is LAAL, or Length-Adaptive Average Lagging. It measures how far the translation trails the source speech on average. It also avoids rewarding systems that over-generate output. A drop from 2.8 seconds to 2.3 seconds is roughly an 18% cut in average lag. QwenCloud team describes the model as the real-time version of Qwen3.8-LiveTranslate-Flash. It builds on the Qwen-Omni stack, large-scale multimodal data, cross-language and cross-modal alignment, and visual enhancement. The Flash model also supports offline audio and video translation. Three New Capabilities Real-time speaker diarization: The model distinguishes speakers in multi-party speech. It also preserves each speaker’s voice through more stable voice cloning. The API exposes cloning modes, including an always mode that re-clones before each response for multi-speaker sessions. Synchronized bilingual display: Source text and translation appear on screen together. In the API, source transcription streams as its own events next to the translation stream. Long-context disambiguation: The model uses conversation history to resolve names and terminology. A name introduced early in a meeting stays consistent later in the translation. Try the explainer below. It walks through the interleaved stream, speaker tagging, context disambiguation, language coverage, and session cost. Languages, Inputs, and Vision The model understands 60 languages. It can speak 29 of them, returning audio plus text. The remaining 31 return text only. Speech output covers Chinese, English, Arabic, German, French, Spanish, Japanese, Korean, Hindi, and others. Inputs are audio and optional images. Outputs are text and audio. Visual cues such as lip movements, gestures, and on-screen text help in noisy rooms and with ambiguous words. The docs recommend sending no more than 2 images per second. Teams can also set hotwords. These map source terms to fixed target translations. The docs recommend configuring no more than 1,000 hotwords. API, Pricing, and Limits Developers connect through the WebSocket Realtime API with the model ID qwen3.8-livetranslate-flash-realtime. The default turn detection type is speaker_detection. Clients stream audio continuously and receive server-generated responses. Default audio is 16 kHz PCM in and 24 kHz PCM out. The default voice is Tina. Set session.output_modalities to text only, or text and audio. Always send session.finish before closing, or the final segment is lost. Singapore list pricing per 1M tokens: Audio input: $7.50 Image input: $0.55 Text output: $20 Audio output: $30 Beijing pricing is lower, at $5.653, $0.466, $14.133, and $22.613 in USD. Audio input consumes 7 tokens per second. Audio output consumes 12.5 tokens per second. One hour of speech in and speech out costs about $1.54 in Singapore, before text and image tokens. The context window is 53,248 tokens, with 49,152 for input and 4,096 for output. Default rate limits are 10 requests and 100,000 tokens per minute. Model Studio lists function calling, structured outputs, batch inference, and fine-tuning as unsupported. Key Takeaways Qwen3.8-LiveTranslate cuts average lag (LAAL) from 2.8s to 2.3s. A new Interleave architecture improves faithfulness, fluency, and conciseness. It adds speaker diarization, bilingual display, and long-context disambiguation. It understands 60 languages and speaks 29. Access is API-only via Alibaba Cloud Model Studio and QwenCloud. Check out the Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages appeared first on MarkTechPost.
Alibaba Qwen Team Releases Qwen3.8-LiveTranslate: A Real-Time Interpretation Model That Cuts Average Lag to 2.3 Seconds Across 60 Languages Read Post »

AI, Committee, 新闻, Uncategorized

Flet 1.0 Released: Build Production Web, Desktop and Mobile Apps in Python Only

Flet is an open source Python framework that renders its UI with Flutter. You write Python, and Flet draws Material and Cupertino widgets on iOS, Android, Windows, macOS, Linux and the browser. No Dart, Swift, Kotlin or JavaScript required. Last week, the Flet team released Flet 1.0 and declared it ready for building production apps. The release lands roughly four years after the project started. Is it deployable? Yes, today. Flet 1.0.0 is on PyPI under the Apache 2.0 license, requires Python 3.10 or newer for the SDK, and installs with pip install ‘flet[all]’. flet build produces artifacts for Windows, macOS, Linux, iOS, Android and web. The CLI accepts eight target platforms: apk, aab, ipa, ios-simulator, windows, macos, linux and web. The Test Matrix Flet runs framework unit tests across Python 3.10 to 3.14, alongside tests for the Flutter side. Control and example integration tests check behavior and compare screenshots, catching functional bugs and visual regressions. Python binary package tests exercise native libraries on Android and the iOS simulator, with the mobile pipeline building for Python 3.12, 3.13 and 3.14. flet build integration tests compile apps across those Python versions for all six platforms, and flet test launches a packaged app and drives it on all five native platforms, including Linux ARM64. You can write the same kind of tests. Integration tests for your own app use pytest, run via flet test against the packaged build, with screenshot comparison on Android and iOS. Python Versions and Mobile Libraries Flet bundles Python 3.12, 3.13 or 3.14 with your app, and web builds use the corresponding Pyodide release. See how to choose a Python version. The Flet package index now lists more than 100 packages, including NumPy, pandas, Matplotlib, Pillow, SciPy, scikit-learn, cryptography and pydantic-core, plus supporting native libraries. The mobile-forge pipeline automates wheel builds for iOS and Android. Availability still depends on the package and the target. Performance and Packaging Flet now tracks changed properties and skips unnecessary comparisons during UI reconciliation, with 0.83 benchmarks measuring up to 6.7x improvement in control diffing. In packaged native apps, dart-bridge lets the Python and Dart runtimes talk inside one process, without sockets, with dedicated channels for binary data. Packaging enables bytecode compilation by default, and redesigned Android packaging loads Python packages directly from the APK without extraction. Declarative UI Flet Declarative describes UI as a function of application state, organized into reusable components. Flet Studio and the Flet mobile app are themselves declarative Flet apps. The imperative style remains supported. Compare both in the docs. Compatibility and AI Tooling The compatibility policy deprecates APIs before removal, with a default deprecation period of three minor releases. The Flet MCP server gives AI coding assistants version specific Flet API information, plus tools for finding examples, icons and CLI options. Flet Studio runs in the browser with a built in AI agent, and projects can be downloaded for local development. Interactive Explainer The embed below walks through five mechanics: the build pipeline across eight targets, declarative versus imperative state, the CI test layers, runtime bundling with mobile wheels, and the event loop trap. Colors follow Flet’s own brand tokens. Key Takeaways Flet 1.0.0 ships on PyPI under Apache 2.0, Python 3.10 or newer for the SDK. flet build targets eight platforms: apk, aab, ipa, ios-simulator, windows, macos, linux, web. Bundle Python 3.12, 3.13 or 3.14, with 100 plus packages available for mobile. Control diffing measured up to 6.7x faster, and dart-bridge removes socket overhead. Upgrading from 0.28 is a real migration: handlers now run on one event loop. Check out the Flet 1.0 release announcement. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Flet 1.0 Released: Build Production Web, Desktop and Mobile Apps in Python Only appeared first on MarkTechPost.

Flet 1.0 Released: Build Production Web, Desktop and Mobile Apps in Python Only Read Post »

AI, Committee, 新闻, Uncategorized

Meta Launches Muse for Mac: A Personal AI Agent That Works Across Your Files, Mail, Messages, Calendar and Notes

Meta has released Muse for Mac, the first version of Muse that can complete things on a user’s computer. The agent works with local files and native apps, where your data already lives. It adds a desktop layer to an agent that launched on phones, the web and WhatsApp earlier this month. Is it deployable? Yes, for end users. It is a free macOS download today, only available in the US for now. It is a hosted consumer agent, not an open model you can self-host. What Meta Shipped Mark Zuckerberg announced the Mac app on X, noting that it works across apps, files, calendar, notes, and messages. His post added, “The team is shipping fast.” Meta’s Chief AI Officer Alexandr Wang also announced the launch the same day. Muse itself is not new this week. Muse launched on September 8th in the US across iOS, Android, the web and WhatsApp. According to TechCrunch, it quickly rose to the top of the U.S. App Store charts after that launch. Muse for Mac is out today! It works across apps, files, calendar, notes, and messages on your computer. You control what it can access. The team is shipping fast. Download at https://t.co/BX3oX19Zcl — Mark Zuckerberg (@finkd) September 17, 2026 What Muse for Mac Can Do On the Mac, Muse can interact with your files, messages, calendar, notes and mail, all within their native applications. Meta frames it around everyday tasks that span several apps. You can ask it to organize folders, finish a form using information stored in your files, or build an end-of-day summary from emails, messages, and notes. The practical shift is context gathering. A normal chatbot needs you to copy and paste information into a prompt. Muse can potentially collate different pieces of context across the computer. One task might touch a Calendar event, a Mail thread, a document in a folder and a Messages conversation. Muse also runs asynchronously. Meta noted that the agent continues working in the background even when the desktop window is closed. You can start something on your phone, check in from your laptop or nudge it through WhatsApp, with Muse keeping the thread across devices. How Permissions Work Local access raises the stakes, so the controls matter most here. Access to your computer is opt-in, while Full Disk Access is optional. You decide what permissions Muse gets and can change them anytime through Settings. Destructive or outbound actions are gated. Meta says sensitive actions such as deleting files or sending messages require approval. In practice, Muse can sort a folder freely but must stop before it deletes anything. It can draft a summary but must ask before sending it. The Stack Behind Muse Muse is powered by Muse Spark, Meta’s most capable model to date, built for real-world agentic work, per Meta’s launch post. The same model powers Muse Code, a coding agent available for MacOS and Windows. The cloud side runs on Muse Secure VM. Muse runs on its own dedicated computer in the cloud, contained so no one else’s agent can reach it. A separate Sentinel agent runs on that same machine, kept apart from Muse at the system level. Nothing Muse does reaches the internet unless the Sentinel approves it. There is one caveat worth stating plainly. Secure VM isolates your data from other users, but it does not prevent Meta from accessing your data when necessary to operate the service. Meta plans to introduce Muse Confidential VM later in 2026, encrypting the entire VM with a key only the user holds. Meta also runs a public bug bounty for Muse. Interactive Explainer: How Muse for Mac Gets a Task Done Key Takeaways Muse for Mac is Meta’s first Muse version that acts directly on your computer. It works with Files, Mail, Messages, Calendar and Notes in their native apps. Access is opt-in, Full Disk Access is optional, and settings can change anytime. Deleting files or sending messages always requires your approval first. Free up to 100M tokens per week; US only for now. The post Meta Launches Muse for Mac: A Personal AI Agent That Works Across Your Files, Mail, Messages, Calendar and Notes appeared first on MarkTechPost.

Meta Launches Muse for Mac: A Personal AI Agent That Works Across Your Files, Mail, Messages, Calendar and Notes Read Post »

AI, Committee, 新闻, Uncategorized

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026)

First, separate 2 ideas: containers vs. quantization methods Most confusion comes from mixing 2 layers. A container defines how tensors are stored on disk. A quantization method defines how weights are squeezed into fewer bits. Containers: safetensors, GGUF, PyTorch pickle (.bin / .pt). Methods: GPTQ, AWQ, bitsandbytes NF4, llama.cpp K-quants and I-quants. Both at once: EXL2 and EXL3 are a method plus a storage layout tied to one inference library. A quick memory rule of thumb Weight memory ≈ parameters × bits-per-weight ÷ 8. Model 16-bit ~4.5 bits per weight 8B ~16 GB ~4.5 GB 70B ~140 GB ~39 GB This is arithmetic, not a vendor benchmark. It covers weights only. The KV cache and runtime overhead add more on top. 1. Full precision: safetensors and PyTorch .bin Unquantized models usually ship as 16-bit weights, in either pytorch_model.bin or model.safetensors. The older .bin / .pt files use Python pickle. Loading a pickle file can execute arbitrary code, which makes untrusted checkpoints a security risk. Safetensors, created at Hugging Face, removes that risk. A file is a small JSON header plus raw tensor buffers, with nothing executable inside. Tensors can be memory-mapped and loaded one at a time without reading the whole file. Safetensors is now listed as a PyTorch Foundation project. Important nuance: most GPTQ, AWQ, EXL2, EXL3, and MLX models are also stored in .safetensors files. The quantization lives in the tensor contents and a config file, not in a new container. 2. GGUF (llama.cpp) What it is GGUF is a binary format for running models with GGML and GGML-based executors such as llama.cpp. It was created by Georgi Gerganov, who also leads llama.cpp (Hugging Face docs). It was introduced on August 21, 2023 as the replacement for the older GGML format. Why it replaced GGML The older GGML, GGMF, and GGJT files could not say which architecture a model belonged to. Adding a new hyperparameter broke every existing file. GGUF switched to typed key-value metadata, so new fields can be added without breaking old files. Design goals The spec lists 5 goals: single-file deployment, extensibility, mmap compatibility, easy loading, and complete information inside the file. Unlike tensor-only formats, GGUF can carry the tokenizer, special tokens, and a Jinja chat template alongside the weights. Reading GGUF quant names The suffix in a name like Q4_K_M.gguf tells you the scheme. Figures below come from the Hugging Face GGUF docs. Type How it works Bits per weight Q4_0 / Q4_1 (legacy) 4-bit round-to-nearest in 32-weight blocks; Q4_1 adds a block minimum 4.5 / 5.0* Q8_0 (legacy label) 8-bit round-to-nearest in 32-weight blocks 8.5* Q2_K 16 blocks × 16 weights per super-block, 4-bit scales and mins 2.625 Q3_K 16 blocks × 16 weights, 6-bit scales 3.4375 Q4_K 8 blocks × 32 weights, 6-bit scales and mins 4.5 Q5_K 8 blocks × 32 weights, 6-bit scales and mins 5.5 Q6_K 16 blocks × 16 weights, 8-bit scales 6.5625 IQ4_XS 256-weight super-blocks, uses an importance matrix 4.25 IQ3_XXS Same I-quant family 3.06 IQ2_XXS Same I-quant family 2.06 IQ1_S Same I-quant family 1.56 *Derived by hand, not listed in the HF table: 32 weights plus a 16-bit scale (and a 16-bit minimum for Q4_1). Checking the Q4_K math: A super-block holds 256 weights. 256 × 4 bits = 1,024 bits. Add 8 blocks × 12 bits of scales and minimums (96 bits). Add a 16-bit super-scale and 16-bit super-minimum (32 bits). Total: 1,152 ÷ 256 = 4.5 bits per weight. What _S, _M, _L mean: These are mixes, not new types. For example, llama.cpp describes Q4_K_M as using Q6_K for half of the attention.wv and feed_forward.w2 tensors and Q4_K elsewhere (Unsloth docs). That is why a Q4_K_M file averages above 4.5 bits per weight. Newer types: The HF table also lists TQ1_0 and TQ2_0 for ternary weights, plus MXFP4, a 4-bit microscaling floating-point type. A labeling quirk: Hugging Face files Q8_0 under “legacy” types. In practice, Q8_0 remains the standard near-lossless GGUF choice. Quality vs. size Hugging Face’s reference table for a Llama-2-7B-class model shows the trade-off: Quant Perplexity Change vs FP16 Size FP16 5.9565 baseline 13.0 GB Q8_0 5.9584 +0.03% 7.0 GB Q6_K 5.9642 +0.13% 5.5 GB Q5_K_M 5.9796 +0.39% 4.8 GB Q4_K_M 6.0565 +1.68% 4.1 GB Illustrative only. These numbers come from a 2023-era 7B model; newer models can react differently. Importance matrix (imatrix) GGUF quantization can use calibration data. llama.cpp’s llama-imatrix computes an importance matrix from a text file. llama-quantize –imatrix then uses it to improve quality. For 1-bit and 2-bit mixes, llama-quantize warns if no imatrix is supplied. Naming convention The spec defines filenames as base name, size label, fine-tune, version, encoding, type, and shard. Shards use a 5-digit counter such as 00003-of-00009. Optional mmproj- and mtp- prefixes mark vision projectors and multi-token-prediction draft modules. Where GGUF runs GGUF is native to llama.cpp and its ecosystem. Hugging Face documents use with llama.cpp, LM Studio, GPT4All, and Ollama. vLLM support exists but is limited. vLLM calls it highly experimental and under-optimized, and GGUF now needs the out-of-tree vllm-gguf-plugin. 3. GPTQ GPTQ was written by Elias Frantar (IST Austria), Saleh Ashkboos and Torsten Hoefler (ETH Zurich), and Dan Alistarh (IST Austria & Neural Magic). It first appeared on arXiv on October 31, 2022. It was published at ICLR 2023. How it works GPTQ is a one-shot, post-training weight quantization method. It uses approximate second-order (Hessian) information to decide how to round weights. Rounding error in one column is compensated by adjusting weights not yet quantized. It needs a small calibration dataset but no retraining. Main results Quantized 175B-parameter models in about 4 GPU hours, down to 3 or 4 bits per weight (arXiv). Reported negligible accuracy loss at those bit widths. End-to-end speedups over FP16 of about 3.25x on NVIDIA A100 and 4.5x on A6000 (HF paper page). Reading GPTQ names GPTQ repos often include GPTQ or tags like 4bit-128g in the name. Group size (128g): one scale per 128 weights. Smaller groups improve accuracy but add a little size. Act-order (desc_act):

GGUF vs GPTQ vs AWQ vs EXL2: LLM Model Formats Explained (2026) Read Post »

AI, Committee, 新闻, Uncategorized

OpenClaw Releases 2026.9.5 With Atomic Updates, Plugin Hot Reload, Conversation Sharing, and Expanded GPT Live

OpenClaw is an open-source, MIT-licensed personal AI agent that you run on your own machines. Its Gateway connects models, tools, and chat channels such as Telegram, Slack, and Discord. The project has now shipped version 2026.9.5, announced on X. The release bundles 4,179 pull requests and 64 direct commits, with credits to 502 contributing accounts. The main change is Atomic Updates, which targets a long-running complaint: updates that break a working agent. Is it deployable? Yes, Version 2026.9.5 is the current latest tag on npm. It is self-hostable and needs Node 24.16+ or 26.1+. Why OpenClaw Updates Kept Breaking The OpenClaw team explained the problem in a blog post with maintainer Jason Sy. Before the fix, an update had 2 outcomes: incremental improvement or catastrophic failure. In the failure case, the old version went down as well. That left no agent online to help with the repair. Two factors made this hard. First, OpenClaw has thousands of config options, so testing every permutation is near impossible. Second, maintainers rarely felt the pain themselves. They are developers who ask Claude or Codex to update their claw. For many users, the claw is their only agent. The OpenClaw 2.0 launch in early September made the issue too large to ignore. How Atomic Updates Work According to the Claw team, the needed pieces already existed in the upgrade process. They were in the wrong order. The new flow works like this: The existing Gateway keeps running while the update is prepared. The next version is checked against a private copy of your setup. OpenClaw switches over, then verifies the updated installation. If the update fails, it rolls back to the last working configuration. OpenClaw always preserves a working agent, so it can help diagnose a failed upgrade. The team also added an issue reporting button for updates. The release notes list clear limits. Atomic Updates apply on supported update paths only. Rolling back the application cannot undo database migrations. The private validation copy is not a backup, so keep a verified backup before upgrading. If an interactive update fails, AI repair starts only after you choose Yes. It uses your account and tokens, and a 30-second timeout skips it. Interactive Explainer: OpenClaw 2026.9.5 What Else Ships in 2026.9.5 Plugin hot reload: you can install or reload supported plugins without restarting the Gateway. It works from the CLI or an authorized chat command. The CLI also accepts several plugins in 1 command. Conversation sharing: Session Share gives teammates on another paired installation read-only access to selected conversation groups. Recipients see conversation text and eligible forks. They do not see subagents, tool activity, or reasoning. Revocation cannot recall what was already received. Expanded GPT Live: you can speak while GPT Live replies in supported Meet, Teams, and Zoom meetings. It can consult your OpenClaw agent during meetings or phone calls. Live is audio-only, so the notes point to gpt-realtime-2.1 for camera use. Shared browser pages: a shared Browser dashboard lets you and your agent use the same page. It runs on a local OpenClaw-managed browser profile, not your laptop cookies. Conversation archiving: cold storage compresses older, inactive history. It is off by default and archives after 30 days once enabled. Reopening a conversation restores it and makes it searchable again. Specialist-agent setup: guided setup can create a chief of staff, researcher, writer, and reviewer. You can also pick a single specialist. Nothing is created before you approve the proposal. One upgrade warning applies to everyone. This release changes the conversation database even with archiving off. Going back requires the matching older build and a backup. How To Install or Upgrade New installs can use the official script: Copy CodeCopiedUse a different Browser curl -fsSL https://openclaw.ai/install.sh | bash If you already manage Node.js, install the published package: Copy CodeCopiedUse a different Browser npm install -g openclaw@latest –allow-scripts=openclaw openclaw onboard –install-daemon Existing users can run openclaw update. See the updating guide for manual paths. The release also adds a FreeBSD CLI install route using system Node and npm. Key Takeaways OpenClaw 2026.9.5 ships 4,179 pull requests from 502 contributing accounts. Atomic Updates validate the next version while the current Gateway keeps running. Failed updates roll back, and a working agent stays available to diagnose. Plugins now install or reload without a Gateway restart. Back up first: rollback cannot undo database migrations. The post OpenClaw Releases 2026.9.5 With Atomic Updates, Plugin Hot Reload, Conversation Sharing, and Expanded GPT Live appeared first on MarkTechPost.

OpenClaw Releases 2026.9.5 With Atomic Updates, Plugin Hot Reload, Conversation Sharing, and Expanded GPT Live Read Post »

AI, Committee, 新闻, Uncategorized

TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

The ChatGPT moment in 2022 taught AI to talk to people. One of its builders now bets the next moment is AI that talks to software, not people. TypeSafe AI released Jev. Jev is transformer-based, but it is not a large language model. It does not generate text. You send a state and typed questions. It returns typed decisions with probabilities that code can branch on. Is it deployable? Yes, as a hosted API in early access behind a waitlist. TypeSafe has not published weights, a parameter count, or a self-hosting option. What is a System One Model? The name borrows from Daniel Kahneman’s split between fast intuition and slow reasoning. TypeSafe team argues RLHF tuned models for human preference. That produced chat, and overconfidence and mode dropping. Those flaws keep a human in the loop. Jev uses a new stack: a new architecture, a parallel sampler, and Reinforcement Learning for Calibrated Decisions (RLCD). TypeSafe has not disclosed the architecture. How the Jev API Works One endpoint handles everything: POST https://api.typesafe.ai/v1/systemone. The body carries state, model, and a map of questions. The docs define 3 question types. Primitive Asks Returns Choice Pick 1 option from a list choice, probabilities, confidence Score Rate against ordered levels score, probabilities, confidence Noul Is this statement true? noul, a probability from 0 to 1 Questions run in parallel and in isolation against the same state. TypeSafe says adding questions barely changes response time. A Choice supports up to 255 options. Copy CodeCopiedUse a different Browser from typesafe_sdk import Choice, Noul, TypeSafeClient client = TypeSafeClient() # reads TYPESAFE_API_KEY r = client.system_one( state=ticket, questions={ “department”: Choice( instructions=”Which team should handle this”, criteria={“billing”: “Payment issues”, “technical”: “Bugs”}, ), “is_urgent”: Noul(instructions=”The message conveys urgency”), }, ) print(r.answers[“department”].choice, r.answers[“is_urgent”].noul) Install with pip install typesafe-sdk (Python 3.10 or later). A JavaScript SDK ships as @typesafe-ai/sdk. The quickstart also covers cURL and an agent skill for Claude Code. Confidence is the Product Every Choice and Score answer carries a confidence value from 0 to 1. TypeSafe derives it from the shape of the probability distribution. In the docs example, billing wins at 0.84. Confidence is only 0.596, because technical still holds 0.159. The docs suggest 3 paths. Act on high confidence. Review the middle. Send low confidence to a human. Thresholds should scale with the cost of a wrong action. Pricing, Speed, and the Benchmark Fine Print Jev costs $42 per billion input tokens. TypeSafe quotes existing LLMs at $0.20 to $10 per 1M input tokens. In its recorded demo, Jev finished in 0.114s for $0.000081. GPT-5.6 Terra took 8.566s for $0.013880. The TypeSafe team claims it to be 193.6x faster and 444.6x cheaper. Those figures come from TypeSafe’s own workflow evals. But hold on here are some things to keep in mind: The reference answer is the average of GPT-6 Astra and Fable 5.1. TypeSafe’s capabilities team wrote the workflows. TypeSafe expects these gains to sit at the high end of real use. TypeSafe says it cannot prove the price is unsubsidized. ‘Zero hallucinations’ means schema matching is guaranteed. The 0% figure is not empirical. Answers can still be wrong. What Developers are Building with Jev Community projects appeared within days of launch. Here are some examples: Command safety: Vercel CEO Guillermo Rauch reported Jev up to 18x faster at p95 than GPT Luna, and more accurate. His post said the fx reviewer still ran on Luna. Engineer Pranit Sharma shared the benchmark. Email triage:Bryo AI CTO Nikhil Mudholkar found Gemini slightly more accurate, but 10 to 20 times more expensive. Browser agents: Browser Use’s jev-ultrafast ran a Zürich to London Google Flights search in 7.1 seconds (video). Phone agents: Droidrun’s mobile-jev drove Uber on a real Android phone: 9 actions in about 21 seconds (video). No booking was completed. Video scoring: jevmeter scores every sentence of a debate for about $0.05 (demo on X). Live typing: Steve Krouse’s Typewriter updates 16 judgments as you type (try it). Games: Jev completed StarCraft’s first combat mission (video). It also runs the guards in heist-one (video). Agent guardrails: jev-guard rates each tool call as deny, ask, or allow (78-second video). Data and homes: pg-jev adds plain-language filters to Postgres. HA-Jev turns answers into Home Assistant entities. Interactive Explainer Key Takeaways Jev outputs typed decisions with probabilities, not strings. 3 primitives (Choice, Score, Noul) can share 1 request. Input costs $0.042 per 1M tokens. Output tokens are free. TypeSafe reports 70ms to 500ms end-to-end response times. The main benchmarks are vendor-run. Test on your own data. Check out the launch post, docs, and TypeSafe’s GitHub. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text appeared first on MarkTechPost.

TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text Read Post »

AI, Committee, 新闻, Uncategorized

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

Linkup research team releases SPARSEUP, an open-source learned sparse embedding model. The model runs on a 149M-parameter ModernBERT backbone and ships under Apache 2.0. Linkup team reports 56.4 average nDCG@10 on BEIR-13. It calls this the strongest public vocabulary-based sparse encoder it knows of under 150M parameters. Is it deployable? Yes. The weights are on Hugging Face under Apache 2.0. The model loads through Transformers or Sentence Transformers with trust_remote_code=True. Why a Sparse Model, and Why Now Most open retrieval models are dense: 1 vector per text. Sparse models output weights over a vocabulary instead. Each dimension maps to a real token, so vectors fit inverted indexes and humans can read them. They also tend to match rare words well. The trigger was LightOn’s DenseOn and LateOn release. LightOn published open data, a training recipe, a dense model and a late-interaction model. SPARSEUP fills the missing sparse slot. It uses the same backbone family and fine-tuning data, so all 3 retrieval styles can be compared side by side. How is SPARSEUP Built Training starts from LateOn-unsupervised. That checkpoint had no MLM head, so the team grafted back ModernBERT’s original one. Fine-tuning used LightOn’s fine-tuning mixture with contrastive learning only. Each query gets 7 hard negatives sampled from a pool of 50, and in-batch negatives. There is no cross-encoder distillation, and training fits on a single H100. A vanilla SPLADE on this backbone produced huge bags full of stopwords. Linkup fixed this with 3 changes: Logit shifting: The encoder computes log(1 + ReLU(x – 15)). ModernBERT’s MLM logits sat too high, saturating the log and making bags dense at initialization. Per-position top-k: Each input token keeps only its 12 strongest vocabulary dimensions before max pooling. This caps expansion per token, not total vector size. Case folding: Byte-level BPE stores heat, Heat, Ġheat and ĠHeat as separate ids. SPARSEUP folds them onto 1 id and keeps the largest weight. Output dimensions drop from about 50k to about 34k. Queries and documents take [Q] and [D] prefixes, and scoring is a dot product. Evaluation max lengths are 128 tokens for queries and 512 for documents. Benchmark Results Against other sparse encoders on BEIR-13 (nDCG@10, without MS MARCO), per the model card: Model BEIR-13 avg SPARSEUP 56.4 opensearch-neural-sparse-encoding-doc-v3-gte 54.6 opensearch-neural-sparse-encoding-v1 52.44 ModernBERT-VT 52.4 splade-v3 51.7 granite-embedding-30m-sparse 50.6 LACONIC-1B (1B parameters, different size class) 58.7 The controlled comparison is less flattering. With backbone and data fixed, LateOn scores 58.9, DenseOn 57.9 and SPARSEUP 56.4. SPARSEUP uses approximate Seismic search, while LightOn reports exact search. SPARSEUP wins ArguAna and Touché and beats DenseOn on HotpotQA. It lags on more semantic sets, with FiQA showing the largest gap. DBPedia is another weak spot. On decontaminated BEIR, the gap to DenseOn shrinks to 0.17 points. Linkup warns that decontaminated NQ and MS MARCO have only 21 and 46 queries, so those results are noisy. Speed and Sparsity On MS MARCO, SPARSEUP averages 47 non-zero terms per query and 190 per document. SPLADE-v3 averages 25 and 170. With the Seismic inverted index, it reaches over 97% recall against exact search in about 380 microseconds per query, single-threaded. Linkup says inflating vector size could add 1 to 2 BEIR points, but it chose to stay sparse. Key Takeaways SPARSEUP is Linkup Research’s first open model: a 149M-parameter sparse encoder under Apache 2.0. It scores 56.4 nDCG@10 on BEIR-13, top among public sparse encoders under 150M, per Linkup. 3 fixes drive it: a logit shift of 15, top-12 expansion per token, and case folding. With identical data, it trails DenseOn by 1.52 points and LateOn by 2.5 on BEIR-13. It reaches over 97% recall in about 380µs per query with Seismic on MS MARCO. Check out the Model Weights and Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model appeared first on MarkTechPost.

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model Read Post »

AI, Committee, 新闻, Uncategorized

Could AI really kill us all? Your questions, answered.

On Wednesday, MIT Technology Review hosted a live Roundtables event for subscribers that asked the question everyone’s asking right now: Could AI really kill us all? But attendees had so many more questions than we had time to answer in the 30 minute session. So we asked our senior AI editor Will Douglas Heaven and AI reporter Grace Huckins to round up some of the best questions attendees submitted and try their best to answer them. Thanks to all who submitted questions! Am I gonna die? Yes, eventually. Unfortunately, my journalistic powers of prognostication aren’t powerful enough for me to tell you how. But it certainly could be because of AI. AI-powered drones have already killed people in Ukraine, and AI-driven cyberattacks on hospitals will surely claim victims before long.  Could AI go even further, and kill all of us? Less likely. But some people—quirky people, but undeniably knowledgeable about AI—have been warning for years that this could happen. And while I’m not yet stockpiling canned food or trying to get in good with a bunker-owning megabillionaire, I have noticed that the doomers’ predictions about AI capabilities and alignment have, over the past couple of years, proved disconcertingly accurate. That certainly doesn’t mean that their more dire forecasts will come true, but it’s enough for me to sit up and take notice. — Grace Huckins Are you going to die because of AI? I’d say there’s a non-zero chance. Let’s say you’re unlucky enough to be the victim of a freakish near-future event or accident. Maybe it’s a cyberattack carried out by a swarm of AI agents on critical infrastructure. Sadly, a scenario like that now no longer feels as far-fetched as it once did. Or maybe a novel AI-designed pathogen cuts through the population. Or the world economy crashes, causing conflicts and famine. Both plausible, but I think less likely.  Are we all going to die because of AI? Nope. There are no circumstances outside of apocalyptic science fiction in which AI could kill us all. You can spin up any number of scare stories, but they’re not grounded in present-day realities about what the tech can do or where it’s headed.  Some people argue that there’s no harm in preparing for the worst, however wacky it might seem. Maybe. But I think such catastrophizing can make people excuse or overlook many of the more immediate problems with the existing technology and the companies building it.  — Will Douglas Heaven Why would AI kill us? Someone might tell it to, and it might listen. That’s part of the reason researchers are so concerned about AI’s biological capabilities—imagine what Aum Shinrikyo, the doomsday cult behind the Tokyo subway sarin attack of 1995, would have done with a tool that could design a pathogen deadlier than Ebola and more transmissible than measles. Those of us who don’t want to die have to figure out how to defend against all plausible biological weapons, but our would-be attackers only have to manufacture one effective pathogen. Then there’s the more exotic-sounding possibility that an AI could decide to kill us itself. There are various stories about how this might happen out there, but the most widespread involve AI systems that don’t hate people, necessarily—we are just an obstacle between them and the goals that we gave them. Much as the OpenAI agents behind the Hugging Face hack compromised another site’s infrastructure to get a good score on a test, the idea is that some future, more powerful AI might get rid of us to prevent us from shutting it down—all in pursuit of some goal that we instructed it to go after.  — Grace Huckins How can we best ensure alignment so the worst doesn’t happen, and who is doing the best work to achieve it?  Alignment is a huge area of research. In simple terms, it involves building models that behave in ways we want them to and not in ways we don’t. We need to trust agents better before handing over more autonomy. Alignment is supposed to establish that trust. But it’s hard.  LLMs aren’t designed in the way other software is, where dos and don’ts can be hard-coded in. Instead, aligned behavior needs to be instilled when models are trained. One approach is to reward them for doing things you want them to (a little like raising a toddler, perhaps). Another approach involves giving an LLM a written list of rules it is supposed to follow (kind of like a constitution).  Anthropic and OpenAI are both leaders in this field—and yet neither has been able to develop models that are fully aligned. A big problem is that LLMs are far more inconsistent and far less predictable than people. They can behave in one way in one situation and another way in a situation that to us seems very similar. They can also be swayed by unexpected constraints. For example, faced with an impossible task (as many of the agents involved in the Hugging Face hack were), models may try to do whatever it takes to achieve their goal. As Grace mentions above, that could be an issue. The main reason top AI firms now say they want a slowdown is that they want to focus on cracking alignment. Alignment isn’t necessarily a pipe dream. But the jury’s out on whether full alignment will ever be feasible.  — Will Douglas Heaven Is AI really dangerous, or is this the tech companies drumming up PR? This is always a reasonable thought when it comes to tech companies heading for an IPO—CEOs have an obvious incentive to make their products seem radical and transformative. But I’m not so sure it makes sense here. Telling the public that an already unpopular product could kill them and everyone they love is horrible corporate image management. There are other stories you can tell about the CEOs’ motivations—maybe they want to cool down the public furor over data centers by portraying themselves as responsible stewards of a

Could AI really kill us all? Your questions, answered. Read Post »

AI, Committee, 新闻, Uncategorized

The Download: AI’s extinction risk and bioweapons threat

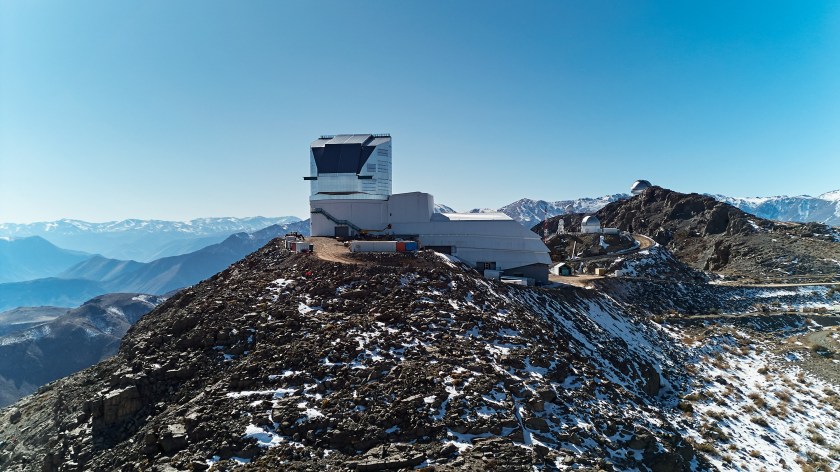
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Could AI really kill us all? Your questions, answered On Wednesday, MIT Technology Review hosted a live Roundtables event that asked the question many seem to be asking right now: could AI really kill us all? But attendees had more questions than we had time to answer, so we asked senior AI editor Will Douglas Heaven and AI reporter Grace Huckins to tackle some of the best ones.  The questions they tried to answer include: am I going to die? Why should AI kill us, if at all? Is AI really dangerous, or is it just tech companies drumming up PR? And what steps can be taken to make sure AI is controlled, monitored and regulated effectively? Here are their responses. —Will Douglas Heaven and Grace Huckins The specter of AI-enabled bioweapons is a wake-up call for biotech One of the ways AI could potentially cause catastrophic harm is by aiding the design and creation of bioweapons. In 2022, researchers found that it was remarkably easy to do this with an AI “molecule generator” built to develop drugs. In less than six hours, the model generated 40,000 molecules that could serve as chemical warfare agents.  Today, AI tools can answer questions on almost every area of science, while advances in gene editing and synthetic biology have made biotech tools more accessible. There are safeguards, but none are ironclad. However, scientists disagree about how serious the risk is anyway. Find out why it’s easier than ever to design killer pathogens. —Jessica Hamzelou This story is from The Checkup, our weekly biotech newsletter. Sign up to receive it in your inbox every Thursday. The role of the astronaut is in flux We go to space for geopolitical prestige, manifest destiny, spiritual fulfillment, scientific curiosity, and, increasingly, business opportunities. In the wake of Artemis II, a slew of new books suggest that these justifications are subsumed by one unifying fact: humans have itchy feet, and we are simply wired to roam.  In The Ultraview Effect, space anthropologist Deana L. Weibel frames human space exploration as part of our need to embark on pilgrimages. In A Heart for Space, civilian astronaut Eiman Jahangir recounts one such voyage with Blue Origin. And in Dinner with an Astronaut, former NASA astronaut Leroy Chiao argues that people simply “need to know what’s on the other side.” See what these three new books have to say about why we go to space. —Becky Ferreira This story is from our latest print magazine, which is all about kids. Subscribe now to receive every issue when it lands. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Microsoft and OpenAI workers say AI is destroying the webCannibalizing clicks from websites obliterates the business models that keep fresh content coming. (404 Media)+ The employees showed concern that publishers couldn’t survive AI scraping. (NYT $)+ The comments emerged during the NYT’s copyright case. (WP $)+ They could weaken OpenAI and Microsoft’s defense. (Reuters $)+ AI means the end of internet search as we’ve known it. (MIT Technology Review) 2 Robot boats have fought each other for the first timeA Ukrainian vessel sank a Russian one in combat. (New Scientist $)+ US firms are building combat-ready humanoids. (WSJ $) 3 Security researchers breached OpenAI using Anthropic’s toolsThey reached an employee’s ChatGPT account and internal code. (FT $)+ They exploited a third-party forum to reach internal systems. (WSJ $) 4 OpenAI reportedly expects to soon crack another famous math problemBut can it avoid another backlash when announcing it? (Information $)+ The problem it expects to solve is the Hodge Conjecture. (Gizmodo)+ OpenAI’s math controversies contain concerning clues about the field’s future. (MIT Technology Review) 5 Elon Musk’s SpaceXAI wants to buy data from failed startupsIt’s seeking new sources of training data for Grok. (Bloomberg $+ And it’s targeting customer and operational data. (Gizmodo)+ OpenAI is paying to create new biology data. (MIT Technology Review) 6 Schools are pushing back against Big Tech’s classroom takeoverAI is accelerating concerns about corporate influence. (New Yorker $)+ We need smarter AI use in schools. (MIT Technology Review) 7 Hackers have revealed how Flock cameras track cars—and peopleOne camera captured 1.6 million images of 50,000 vehicles. (Wired $)+ The cameras also detect people and misidentify objects. (404 Media) 8 Chinese firms doubled down on science after US tech restrictionsThey produced 72% more patents citing scientific papers. (Nature) 9 A three-year-old’s cancer disappeared after an experimental cell therapyCAR T therapy may finally be able to treat solid tumors. (Gizmodo) 10 NYC’s new robotoilets will kick you out after 10 minutesThe doors automatically open when the timer runs out. (Fast Company) Quote of the day “The largest theft of labor in human history.”  —Microsoft’s director of Applied Science, Brent Hecht, raises his concerns over training data used for AI systems in comments revealed in court filings from the New York Times vs OpenAI copyright lawsuit. One more thing The Vera C. Rubin Observatory is ready to transform our understanding of the cosmos High atop Chile’s 2,700-meter Cerro Pachón, the air is clear and dry, leaving few clouds to block the beautiful view of the stars. It’s here that the Vera C. Rubin Observatory is using a car-size 3,200-megapixel digital camera—the largest ever built—to produce a new map of the entire night sky every three days. Generating 20 terabytes of data per night, Rubin will capture fine details about the solar system, the Milky Way and the large-scale structure of the cosmos. Over 10 years, it will catalogue billions of new objects, offering an unprecedented look at what’s changing in the universe. Step inside the observatory mapping the cosmos in a way we’ve never seen before. —Adam Mann We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop

The Download: AI’s extinction risk and bioweapons threat Read Post »

We use cookies to improve your experience and performance on our website. You can learn more at 隱私權政策 and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
zh_CN