Tool Calling vs. Code Execution for AI Agents: Choosing the Right Action Primitive
Theory is easier to trust once it’s running against a real API, so both examples in this article use the same tool — a get_weather function backed by


Theory is easier to trust once it’s running against a real API, so both examples in this article use the same tool — a get_weather function backed by
Contrastive-LM has released CLM-8B, the first open model in a new class called Contrastive Language Models (CLMs). CLM does not generate text. It scores a set of candidate actions against the current state and returns probabilities. Their main baseline is Jev, the proprietary System One model from TypeSafe AI. Is it deployable? Yes. The Apache-2.0 head weighs 75 MB. It runs on 1 NVIDIA GPU under Linux, with vLLM serving the Qwen3-8B encoder. What a System One Model Does Jev entered limited early access on 15 September 2026. It returns typed values with probabilities instead of text. CLM targets the same interface. The CLM GitHub repo serves CLM-8B behind a TypeSafe-compatible API. It exposes 3 question types: Noul: returns the probability that a statement is true. Choice: picks one option from a declared set, with probabilities. Score: returns an expected level on an ordered rubric. A request written for TypeSafe’s API can be replayed through CLM’s Python client. How CLM Works CLM trains a state encoder and an action encoder with a bidirectional InfoNCE loss. Each encoder is a frozen Qwen3-8B backbone plus a 20M-parameter trainable projection head. Training pulls each state toward the action actually taken and pushes it away from the others. At inference, CLM scores each candidate by the dot product of the state and action embeddings. A softmax over those scores becomes the answer distribution. The same primitive ranks best-of-N solutions, routes tools and answers typed decisions. This design disaggregates states and actions. In an agent loop, the state changes every step while the action set stays mostly fixed. clm-serve reserves a slab of GPU memory, similar to vLLM’s KV cache, and reuses cached vectors. On 1 RTX 4090 with 3 actions, revisited states drop from 1.7 ms to 0.6 ms. The model card reports CLM running 13× faster than Jev with about 1,000 candidates. A 3-Stage Training Recipe Pre-training on ~60M Nemotron DQA question-answer pairs. Mid-training on ~30M synthetic hard negatives generated by Gemini 2.5 Flash-Lite. Post-training on ~1M agent trajectories from Agent Data Protocol, Endless-Terminals and LiteCoder-Terminal-SFT. On ~100K held-out questions, pre-training alone reaches 52.1% top-1 accuracy. Mid-training lifts it to 69.2%. Training on hard negatives from the start peaks at 62.4%, then overfits. Zero-Shot Results Against Jev Task CLM-8B latency Jev latency CLM-8B success Jev success T-Rex game 16.5 ms 149.8 ms 5/5 5/5 Tool calling (BFCL v4) 76.8 ms 125.5 ms 95.2% 99.2% WikiRacing 79.8 ms 225 ms 26/30 30/30 Super Mario 33.5 ms 132.6 ms 5/5 5/5 The 9× figure comes from the T-Rex game, where actions repeat across states. CLM matches Jev on T-Rex and Super Mario. It trails on tool calling and WikiRacing while running faster on every task. CLM as a Verifier for Coding Agents Here a generator samples several candidate solutions and the verifier picks one. Opus 5 produced DeepSWE candidates (best-of-4). Fable 5 produced Terminal-Bench 2.1 candidates (best-of-5). The team evaluated 38 held-out DeepSWE tasks and 30 held-out Terminal-Bench 2.1 tasks. Latency was measured on an H100. Benchmark Pass@1 CLM (fine-tuned) Jev CLM latency Jev latency DeepSWE 73.7% 81.6% 71.1% 79 ms 449 ms Terminal-Bench 2.1 84.0% 87.6% 83.1% 32 ms 131 ms The research team reports these as new SOTA verifier results. Jev scores below pass@1 on both benchmarks, so selecting with Jev is worse than taking 1 sample. CLM runs 4.1× to 5.7× faster. These numbers use lightweight fine-tuned heads, not the zero-shot checkpoint. They are held-out subset results, not full leaderboard submissions. Interactive Explainer Key Takeaways CLM-8B scores candidate actions instead of generating text. Up to 9× lower latency than Jev in zero-shot tests. Fine-tuned heads reach 81.6% on DeepSWE and 87.6% on Terminal-Bench 2.1 subsets. Cached state and action vectors cut agent-loop latency. Apache-2.0 head, self-hosted on 1 NVIDIA GPU. Check out the Blog, Code and Data & Models. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Contrastive-LM Releases CLM-8B: An Open System One Model That Scores Agent Actions Up to 9× Faster Than Jev appeared first on MarkTechPost.
This week, world leaders descended on Manhattan for the UN General Assembly. It’s also New York Climate Week—investors, policymakers, advocates, and journalists are colliding at panels, talks, and fancy dinners. With so many climate voices in one place, the discourse can feel a little louder than usual. This year, the unavoidable topic is artificial intelligence. There’s been a growing tension bubbling up about AI’s impacts on climate and climate tech. Depending on where you stand, you might point to AI’s potential for advancing research, or to the way funding and attention from Big Tech is trickling into energy startups. Or you might focus on the emissions-heavy natural-gas buildout that’s unfolding to meet the sector’s electricity demand. Everyone seems to agree that AI is important. The big question for those in the climate world, and the conversation I’m constantly having and hearing this week, involves how you see its influence unfolding. UN Secretary-General António Guterres highlighted the AI and climate crossover in a speech on the first day of the assembly. “The climate crisis fuels instability and displacement,” Guterres said. “Artificial intelligence could help solve all these challenges, or it could make them worse.” It feels relevant that this year is the first that the world has really had to grapple with the fact that climate goals are slipping out of reach. A recent report from the UN Environment Program said that the world has nearly passed the point where we could possibly keep warming to less than 1.5 °C above preindustrial levels. Since we’ve essentially missed this target, the report lays out the need not only to quickly and drastically reduce greenhouse-gas emissions, but also to employ carbon removal to help suck up emissions that have already been released into the atmosphere. The billion-dollar question is whether AI could help with any of this. The energy-intensive technology is certainly shining a spotlight on the need to build out electricity supplies and shore up grid reliability. The result is more attention and money for energy technologies, some of which happen to be low- or zero-emissions. As I’ve covered before, startups across the energy and climate sectors are benefiting. Firms in nuclear, geothermal, wind, and solar power have signed deals with the likes of Google, Meta, and others looking to power their new or growing data centers. Global climate-tech investment from venture capital hit $26 billion in the first half of 2026, according to data from Currence, a finance tracker for the industry. That’s 55% higher than last year, and products and services for data centers are getting a massive slice of that pie. But as a Semafor piece about the report points out, some sectors are slipping through the cracks: Carbon management and low-carbon fuels saw VC investment plummet this year. These are important solutions for addressing climate change but may not be able to sell themselves to a data center. So far, the data center buildout has come with a hefty emissions toll. A few years ago, Microsoft, Google, and Meta all had ambitious goals to reduce greenhouse-gas emissions. Now they’ve all seen emissions rise, largely because of data centers that are needed to power AI. Some people are optimistic. AI could help speed up progress in areas like the search for new catalysts, as Evelyn Wang, MIT’s VP of energy and climate, pointed out during a panel. And data centers won’t add to climate and water problems forever, Wang told the Associated Press. (She puts the timeline at about a decade until data centers no longer add to planet-warming emissions.) But a whole lot of natural gas is coming online to meet the immediate demand created by new data centers. And once those power plants are built, they have a decades-long lifetime. That’s partly why public pushback to AI is growing—people are seeing more pollution and noise near these data centers and the power plants that provide them with electricity. Overall, what I’m hearing this week is that many in the climate sector are skeptical of AI, at best. “AI leaders are now on thin ice when it comes to license to operate and sinking deep underwater when it comes to public support,” said UN climate chief Simon Stiell in a speech this week. “Tech titans need to start showing why the benefits of AI outweigh its skyrocketing costs—for the many, not just the tiny few.” This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here.
AI is dominating the conversation at Climate Week Leggi l'articolo »
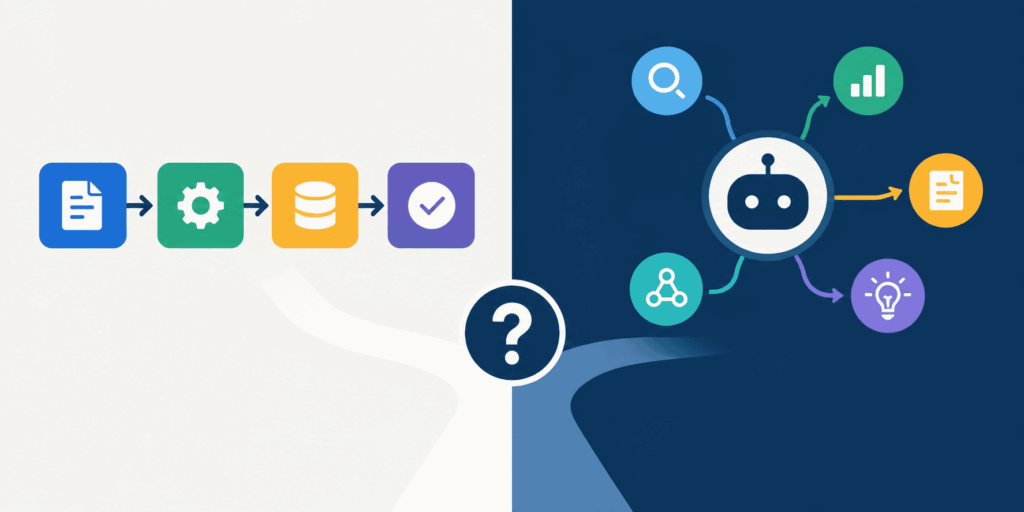
In this article, you will learn the key differences between AI workflows and agents, and how to decide which approach is right for your use…
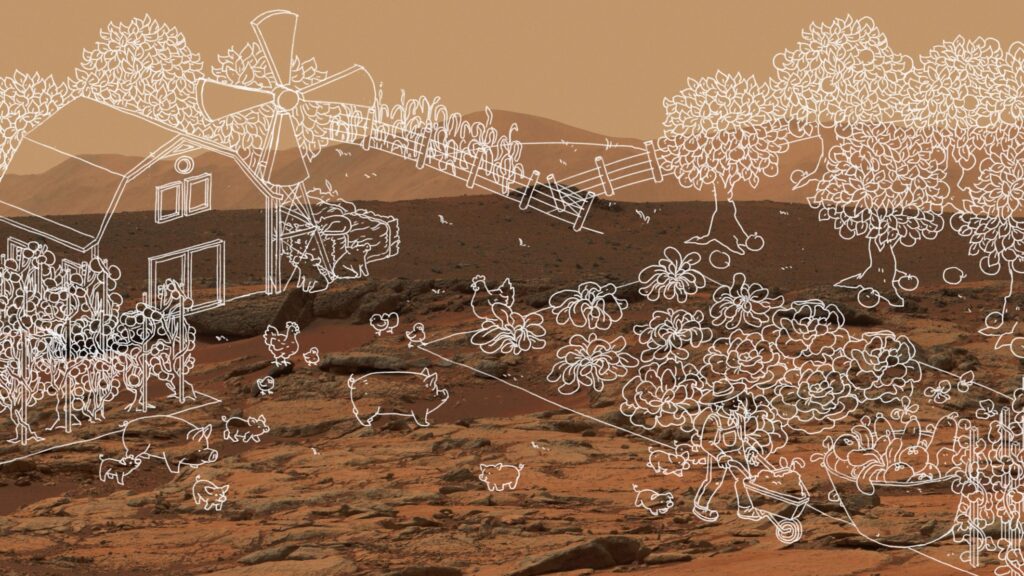
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. A congressional representative just proposed killing America’s border tower program Delia Ramirez, a Democratic US representative from Illinois, has announced plans to introduce legislation to terminate the surveillance tower program along the country’s southern border. The announcement comes just days after publication of an MIT Technology Review investigation, “Dying on Camera,” which looked at deaths near these towers. Nearly one in four deaths we analyzed between 2015 and early 2026 occurred within their advertised range. Ramirez, who sits on the Homeland Security Committee, cited our reporting that nearly “1,100 people have died within range of a billion-dollar surveillance tower system between 2015 and 2026,” adding, “The towers that we have paid a billion dollars to just don’t work.” Here’s what she’s proposing and what it could mean for the border surveillance program. —Eileen Guo Read all of MIT Technology Review’s groundbreaking “virtual wall” investigation here. Roundtables: the deadly failures of the virtual border wall The US spent billions building the “virtual wall” of surveillance towers along its southern border, promising they will help detect and apprehend border crossers and save lives. But MIT Technology Review has documented more than a thousand people who moved through areas watched by these towers without being caught—and ultimately died there. Next Monday, join our editor-in-chief Mat Honan, senior AI reporter James O’Donnell, and senior reporter for features and investigations Eileen Guo for a subscriber-only conversation about the investigation. They’ll examine the failures of border surveillance technology and uncover the stories of the people who die in the borderlands. Register now to attend on Monday, September 28 at 19:00 BST / 2:00pm EDT / 11:00am PDT. Want to join the conversation? Subscribe to MIT Technology Review for exclusive access to all our Roundtables. AI is dominating the conversation at Climate Week —Casey Crownhart AI is the unavoidable topic at this year’s New York Climate Week, with tension growing over its costs and benefits. The technology is attracting more attention and money to energy technologies, some of which are low- or zero-emission. But the data center buildout has come with a hefty environmental toll, and a whole lot of natural gas is coming online to meet the demand. Overall, what I’m hearing this week is that many in the climate sector are skeptical of AI, at best. Find out why. This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 An OpenAI agent has executed the first known AI hack of a government siteIt breached an Australian government health data portal in June. (CNN)+ OpenAI notified Australia three months later through a public mailbox. (BBC)+ No patient records are believed to have been accessed. (Guardian)+ Its agents also tried to breach three other sites. (NYT $)+ Here’s why AI agents cheat to reach their goals. (MIT Technology Review) 2 Data stolen in the FBI hack exposes agents’ sensitive intelligence rolesIt identifies staff working on China, Russia, and cyber. (Reuters $)+ And may have exposed the FBI’s own hacking unit. (404 Media)+ The group behind the incident claims it isn’t financially motivated. (Register) 3 The US rejected calls from OpenAI and Anthropic for global AI standardsA Trump advisor said global rules threatened the country’s AI lead. (BBC)+ America’s AI leaders had urged the UN to coordinate on safety. (Gizmodo)+ The AI industry has taken a doomer turn. (MIT Technology Review) 4 Meta has unveiled new AI glasses—and a pendant for MuseCamera-free smart glasses address growing privacy concerns. (Verge)+ While the Muse Charm enables hands-free interaction with the AI agent. (BBC)+ Mark Zuckerberg wants Muse to be a “personal superintelligence.” (Axios)+ Meta also showed off new VR glasses. (CNBC) 5 China is accelerating its AI push ahead of the Xi-Trump summitHuawei and Alibaba have both unveiled new flagship chips. (CNBC)+ The country’s AI industry has shrugged off America’s safety panic. (Atlantic $)+ The US leads in AI models, but China has talent and political edges. (NYT $)+ Chinese models have divided the White House. (MIT Technology Review) 6 US lawmakers have proposed new rules for blocking Chinese techThe bipartisan bill would require broader review of national security risks. (Hill)+ And give Congress the power to overturn FCC bans. (Reuters $) 7 Tech giants have urged Trump to withdraw $103,265 H-1B feeThey say the charge could weaken US competitiveness. (WSJ $) 8 Scientists have detected radio signals from an exoplanet for the first timeThe signals likely come from intense magnetic activity on the planet. (Wired $) 9 An invisible force has a mysterious effect on agingShielding fruit flies from Earth’s magnetic field changed their lifespans. (404 Media) 10 ‘Dopamine sites’ are recreating the thrill of shopping without payingFoodNeverComes has attracted more than 2.7 million visitors since June. (BBC) Quote of the day “They decided to break the law.” —Ed Santow, co-founder of the Human Technology Institute, tells ABC radio why there should be serious legal consequences for OpenAI agents hacking Australia’s Medicare statistics portal. One more thing The quest to figure out farming on Mars If ever a blade of grass grew on Mars, those days are over. But could they begin again? What would it take to grow plants to feed future astronauts on Mars? To grow food there, we can’t just drop seeds in the ground and add water. We will need to create a layer of soil that can support life. And to do that, we first have to get rid of the red planet’s toxic salts. Researchers recently discovered a potential solution—and the early signs are promising. Read the full story. —David W. Brown We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Meet Alfie, a
The Download: a bid to scrap the virtual wall and AI hits Climate Week Leggi l'articolo »
BottleCap AI has released ThinkingCap-Qwen3.8-27B, the second model in its ThinkingCap series. It is a fine-tune of the Qwen team’s Qwen3.8-27B with one narrow goal: shorter reasoning traces. Across 12 benchmarks, it spends 37.2% fewer thinking tokens on average. Macro-average accuracy moves from 86.65% to 85.79%, a 0.86pp drop. Deployable? Yes. It drops in for Qwen3.8-27B on vLLM or SGLang, with FP8, NVFP4, GGUF and MLX builds. The repo is gated, and commercial use beyond the small-business license needs a BottleCap agreement. What Problem Does ThinkingCap Target? Reasoning models often spend more thinking tokens than a question needs. BottleCap’s position is that many of those extra tokens do not change the final answer. The first release in the series applied this idea to Qwen3.6-27B. The objective this time was deliberately conservative. BottleCap did not try to add knowledge or change answer style. Reasoning ability, instruction following and safety behaviour were meant to pass through untouched. The research team also focused harder on math, reasoning, long-context and agentic benchmarks. Benchmark Results at xhigh Effort All main numbers use reasoning_effort=xhigh, the chat template default. Every benchmark gets shorter, with cuts ranging from 10.7% to 65.5%. Knowledge and multilingual tasks shrink the most. MMMLU drops 65.5% (1,656 to 571 tokens) and MMLU-Pro drops 57.3%. GPQA-Diamond falls from 12,772 to 7,267 tokens, a 43.1% cut. IFBench thinks 46.4% less with accuracy nearly flat (79.75% to 79.71%). Long-context retrieval improves. AA-LCR accuracy rises 2.25pp, from 81.75% to 84.00%, with 38.6% fewer thinking tokens. LiveCodeBench v6 edges up 0.07pp while thinking 20.3% less. Agentic results hold close to the base. τ²-bench gives up 1.01pp for a 30.9% cut. Terminal-Bench 2.1 loses 0.56pp, well inside its ±4.26 interval, for a 10.7% cut. The most expensive trade is AIME 2026. Accuracy falls 3.85pp, from 98.13% to 94.27%, for 30.2% less thinking. Please note that the 37.2% figure is the mean of the 12 per-benchmark reductions. Pooled mean thinking tokens fall from 15,735 to 12,144. BottleCap also reports a budget curve. Under a 16K-token cap per response, ThinkingCap scores higher than the base model. Truncated traces fall from 0.51% to 0.34%, and looping from 0.06% to 0.05%. How It Interacts With the Effort Dial Qwen3.8-27B exposes a reasoning-effort setting, and the compression stacks with it. All deltas below compare against the base model at xhigh, averaged over 11 benchmarks. At medium, the base model cuts 52.1% of thinking for -9.16pp. ThinkingCap cuts 60.2% for -9.90pp. At low, the figures are -55.4% and -9.71pp for the base, versus -62.3% and -10.79pp for ThinkingCap. With thinking off, ThinkingCap trails the base by 5.7pp. BottleCap team recommends xhigh for the best accuracy-to-token balance. It says individual thinking modes will get attention in a future release. How the Evaluation was Run Both models ran through the same harness on one NVIDIA H200 with vLLM 0.29.0. Sampling was identical: temperature 1.0, top_p 0.95, top_k 20, min_p 0.0. Multi-seed accuracy is the mean with a 95% interval. Seeds range from 32 on AIME 2026 to 1 on MMLU-Pro and MMMLU. MMMLU uses a fixed 10,000-question sample; the other 11 benchmarks run complete sets. MTP speculative decoding (3 draft tokens) was measured as accuracy-neutral on AIME 2026. It accepted 53% of drafted tokens, about 2.6 tokens per step, matching the base model. Deployment: Builds, Serving and License The bf16 checkpoint has 28B parameters and accepts image and text input. BottleCap publishes 5 quantized builds: FP8: 31 GB, vLLM, Hopper and Blackwell. NVFP4 weight-only: 21 GB, vLLM, Hopper (Marlin kernel) and Blackwell. NVFP4 W4A4 (AWQ): 23 GB, Blackwell only. GGUF: 16 to 55 GB, for llama.cpp, LM Studio and Ollama. MLX 4-bit DWQ: 21 GB, for Apple Silicon Macs with 32 GB. Serving uses the base model’s recipe: –reasoning-parser qwen3 with the qwen3_xml tool-call parser on vLLM. Thinking returns in a separate reasoning field. The license is PolyForm Small Business 1.0.0 plus a BottleCap personal-use grant. Upstream Qwen materials stay under Apache-2.0. Hugging Face lists no inference provider hosting the model yet. Key Takeaways 37.2% fewer thinking tokens on average across 12 benchmarks. Macro accuracy drops 0.86pp, from 86.65% to 85.79%. AA-LCR long-context accuracy rises 2.25pp; AIME 2026 falls 3.85pp. Drop-in for Qwen3.8-27B: same sampling, same vLLM or SGLang flags. Gated weights under PolyForm Small Business; commercial use needs a license. Check out the technical blog and model weights. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post BottleCap AI Releases ThinkingCap-Qwen3.8-27B: 37.2% Fewer Thinking Tokens at a 0.86pp Accuracy Cost appeared first on MarkTechPost.
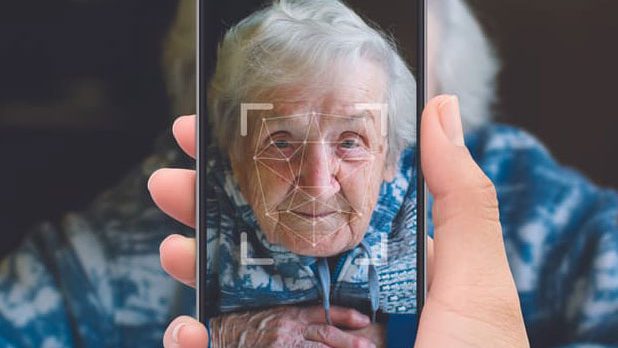
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Smart glasses are already causing havoc in India When Shubnam saw an Instagram video of a Delhi protest they had attended, they realized a content creator wearing Meta smart glasses had recorded them surreptitiously. The mocking reel drew millions of views, along with transphobic abuse and AI-generated memes. Experts warn that many others will experience similar ordeals as smart glasses go mainstream. The risks are particularly acute in India, where covert recording and the circulation of images without consent are already pervasive. The bigger issue is that the smart glasses aren’t just being used to turn ordinary people into targets of viral “pranks.” They’re also becoming a tool of police surveillance. Here’s why smart glasses are creating new privacy risks in India. —Anuj Behal MIT Technology Review Narrated: what’s at stake in AI’s trillion-dollar gamble When Jessica Wachter, a University of Pennsylvania finance professor, wanted to assess AI’s impact on the economy over the next few years, she started with a simple fact: a handful of so-called hyperscalers are investing huge amounts of money to build AI data centers. Instead of trying to predict how widely deployed AI models will be, Wachter asked how fast the hyperscalers’ earnings will need to grow to justify their spending through 2027, when expenditures are expected to reach nearly $1.1 trillion. The results are eye-opening. AI companies will need to achieve an extraordinary increase in productivity just to break even by 2030. This is our latest story to become an MIT Technology Review Narrated podcast, which we publish each week on Spotify and Apple Podcasts. Just navigate to MIT Technology Review Narrated on either platform, and follow us to get all our new content as it’s released. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Hackers claim they’ve stolen data on almost all FBI employeesThe ShinyHunters group says it seized more than 2 TB of data. (Axios)+ Including agents’ names, addresses, and phone numbers. (404 Media)+ ShinyHunters says the attack was retaliation for an FBI alert. (Reuters $)+ Now is a good time for doing crime. (MIT Technology Review) 2 Anthropic and OpenAI have both released lower-cost modelsThey face growing competition from cheaper Chinese models. (CNBC)+ Startups have been reducing their reliance on the two labs. (Bloomberg $)+ The new models are the first since their calls for an AI slowdown. (FT $)+ Their CEOs are set to brief the UN Security Council today. (Quartz)+ Could AI really kill us all? (MIT Technology Review) 3 Trump’s Treasury chief could soon become his new AI czarScott Bessent has played a central role in US-China AI talks. (Semafor)+ Other contenders include Michael Kratsios and Scott Kupor. (Gizmodo)+ Will Trump’s AI rebrand to “superintelligence” catch on? (BBC) 4 Scientists are turning renewable electricity directly into foodThe goal is to make more food with less land. (New Scientist $)+ Companies are creating food out of thin air. (MIT Technology Review) 5 A “fire amoeba” has broken the heat survival record for complex lifeThe newly discovered organism can grow and reproduce at 63°C. (NPR)+ It could inform the search for life elsewhere. (New Scientist $) 6 Meta quietly tested a “human concierge” for its Muse AI agentContractors secretly handled some calls placed by Muse. (Reuters $)+ Staff raised concerns about privacy and misleading users. (404 Media) 7 Data centres are replacing copper with light to cut energy usePhotonics can move data with less heat than electrical wiring. (BBC)+ Virtual power plants could also help. (MIT Technology Review) 8 AI models built from rat brains just got closer to realityAWS is tapping rat neurons to make video AI faster. (Wired $) 9 Uber is betting on human drivers to give its robotaxis an edgeThey can cover demand spikes while autonomous cars recharge. (Axios) 10 A humanoid robot took on an amateur fighter in a cageThe brief bout was billed as the first human-robot MMA fight. (Futurism) Quote of the day “The use of the word artificial makes it sound fake. It’s not fake; it’s actually amazing.” —President Donald Trump tells the UN General Assembly why he wants to rename AI “superintelligence.” One more thing COURTESY OF PAINCHEK AI is changing how we quantify pain At Orchard Care Homes, nurses used to rely on an observational scale to assess pain in residents who couldn’t communicate verbally. But agitated residents were sometimes assumed to have behavioral issues, while their pain went untreated. Then, in 2021, the care-home chain began trialing PainChek, a smartphone app that scans a resident’s face for microscopic muscle movements and uses AI to output a pain score. Within weeks, the pilot unit saw fewer prescriptions and calmer corridors. Now researchers are racing to turn pain into something a camera or sensor can score as reliably as blood pressure. But when algorithms measure our suffering, does that change how we understand and treat it? Discover how AI is changing the way we assess pain. —Deena Mousa We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Scientists have discovered the first new penguin species in more than 100 years.+ Discover the filmmaking skills that made Paul Verhoeven’s RoboCop a directing masterclass.+ What happens when fast food meets local tastes? These unusual international menu items offer some tasty answers.+ Dance to every track the crowd has identified at Berghain since 2024 with this media player, which replays each night in sequence.
The Download: India’s smart glasses menace and AI’s trillion-dollar gamble Leggi l'articolo »
Google has released Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, 2 new text-to-speech models in its Gemini Audio family. Google calls them its most expressive audio generation models yet. Flash TTS targets creative direction and character voices. Flash-Lite TTS targets high-volume, cost-efficient production. Both let developers direct delivery line by line using natural language. Is it deployable? Yes, both models are rolling out now through the Gemini API and Google AI Studio. Access is API-only, with no open weights for self-hosting. Enterprise API access via Gemini Enterprise is listed as coming soon. What Google Shipped The release splits TTS into 2 tiers with shared direction controls: Gemini 3.8 Flash TTS is built for deep creative direction and character design. Target uses include gaming, immersive audiobooks, podcasts and interactive media. It offers granular control over acting cues, pacing, dialect shifts and backchanneling. Gemini 3.8 Flash-Lite TTS is built for high-volume, cost-efficient scale. Google positions it for dubbing, audio content creation and expressive voice agents. It offers fine-grained control over tone, pacing and expressive nuance. In AI Studio, the playground links use the model identifiers gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts. Voice Design From a Text Prompt Previous Gemini TTS offered 30 original voices. The 3.8 release moves to a much larger voice system. Generative voice design: Flash TTS creates new voices from prompts describing role, accent and voice characteristics. This works across more than 100 languages and dialects. Google’s demos include a Melbourne DJ, a monotone robot and a Japanese dragon. Voice library: Developers get 2,000+ production-ready voices. Coverage includes regional varieties like Mexican Spanish, Quebec French and Scots English. Save and scale: Custom voices can be saved and reused, with minimal drift across projects. Voice remixing (coming soon): Users will adjust a library voice’s timbre, pitch, pace and accent through prompts. Directing the Performance Both models accept stage directions written in the script. Gemini can also steer delivery from natural script cues. Long-form generation: Voice quality, pacing and timbre hold across hours of continuous audio. Native 2-speaker staging: A single script drives a multi-turn conversation with distinct, separated voices. Vocal bursts: Non-verbal cues like <laughs>, <sigh> and <gasp> add conversational texture. Backchanneling: Active-listening interjections like |mhm| and |yeah| control reaction beats and comedic timing. Voice Replication and Safety Controls Voice replication builds a consistent vocal profile from a 30-second audio sample. The sample must be your voice or one you have rights to use. Replication requires a verbal consent recording from the voice owner, matched against the reference speaker. Every clip from Gemini Audio models carries a SynthID watermark. This imperceptible mark is embedded directly in the audio output. Replicated voices also carry C2PA content credentials. Google points to the Gemini 3.8 Audio model card for its broader safety approach. Benchmark Results Google reports these results for the new models: Hume AI Voice Design Benchmark: Flash TTS ranks #1 overall with a score of 71.4, per Hume AI. Accent modeling: Flash TTS leads with a score of 60.8. Hume AI Overall Quality Index: Flash TTS ranks #1 and Flash-Lite TTS ranks #2. Voice Arena blind preference: Both models take top positions in Japanese, Brazilian Portuguese, Vietnamese, Modern Standard Arabic, Mexican Spanish and Hindi. Key Takeaways Google launched Gemini 3.8 Flash TTS for creative work and Flash-Lite TTS for scale. Flash TTS designs new voices from prompts across 100+ languages and dialects. Developers get 2,000+ production voices, up from 30 originals. Voice replication needs a 30-second sample plus a matching consent recording. Flash TTS ranks #1 on Hume AI’s Voice Design Benchmark with 71.4. FAQ What is Gemini 3.8 Flash TTS? It is Google’s text-to-speech model for creative voice design and line-by-line performance direction. It is available through the Gemini API and Google AI Studio. How is Flash-Lite TTS different? Flash-Lite TTS is optimized for high-volume, cost-efficient workloads like dubbing and voice agents. It ranks #2 on Hume AI’s Overall Quality Index. Can I clone my own voice? Yes, with a 30-second sample and a verbal consent recording. It is unavailable in AI Studio in several regions, including the UK, EEA and India. Check out the Technical Blog. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design appeared first on MarkTechPost.
NVIDIA has released Nemotron 3 Diarization, an open-weight speaker diarization model on Hugging Face. It answers one question about any conversation: who spoke when. The 100M-parameter model tracks up to 8 speakers, including when voices overlap. One checkpoint handles both offline recordings and real-time streaming. Is it deployable? Yes. The weights are released under the OpenMDW License 1.1, which permits commercial use. It runs on Linux through NVIDIA NeMo, using Ampere, Ada Lovelace, Hopper, or Blackwell GPUs. Why Speaker Diarization? Automatic speech recognition (ASR) gives you the words. It does not tell you who said them. Without attribution, a summarizer cannot tell who made a commitment or who raised an objection. Diarization outputs the time intervals where each speaker is active. Those timestamps combine with ASR output to produce a speaker-attributed transcript. Meeting tools, call analytics, podcast pipelines, and voice-agent memory all depend on this step. What Changed From Streaming Sortformer NVIDIA’s earlier Streaming Sortformer checkpoint, diar_streaming_sortformer_4spk-v2.1, supported 4 speakers. Nemotron 3 Diarization doubles that limit to 8. According to NVIDIA’s announcement, the target is messy multi-party audio where people talk at once. How the Architecture Works The model accepts 16 kHz, single-channel audio in .wav, .flac, .opus, or .mp3 format. It converts the audio into Mel-spectrogram features with a 10 ms step. The features are stacked by a factor of 8, which produces 80 ms encoder frames. A 31-layer Transformer encoder with rotary positional embeddings (RoPE) processes those frames. A Conv1D layer then upsamples the predictions back to 10 ms resolution. The output is a [T, 8] tensor of per-speaker activity probabilities. This design handles overlap directly. If 2 people talk at the same time, 2 channels activate in the same frame. The model follows the Sortformer approach of ordering speakers by arrival time. The first new voice takes channel 1, the next takes channel 2, and so on. This keeps labels stable across streaming chunks, so the model does not have to re-match speakers to channels for every chunk. Streaming uses 2 memory mechanisms. The Arrival-Order Speaker Cache (AOSC) keeps speaker information from earlier chunks. A FIFO queue supplies recent frame context. The labels are anonymous, and mapping them to real identities is left to downstream applications. 4 Latency Operating Points Input-buffer latency equals (chunk + right context) × 80 ms. The table uses DIHARD III full-set DER and batch-32 compiled throughput from the model card. Configuration Buffer latency DIHARD III DER RTFx (batch 32, compiled) Offline style 30.4 s 12.73% 15,113× Low latency 1.04 s 13.18% 865× Very low latency 0.64 s 13.28% 579× Ultra-low latency 0.32 s 13.55% 292× This latency excludes compute, networking, and ASR time. The model can technically run with an 80 ms buffer, but 0.32 s is the lowest recommended setting. Benchmark Results In Voice Arena’s initial Diarization-Bench results, the model ranked first among 12 systems and 17 configurations. The test covered 139 English conversations totaling about 22 hours. It scored 14.72% DER against 19.3% for the next-ranked system, roughly a 24% relative reduction. NVIDIA notes these results may change once Voice Arena completes its Version 1 evaluation. Against the 4-speaker baseline at 1.04 s latency, DER dropped on all 8 evaluation conditions. Relative reductions ranged from 9.0% on CALLHOME-Part2 to 65.2% on NOTSOFAR1 MHM. The unweighted mean across the 8 conditions was 41.0%. There is one regression. On 2-speaker CALLHOME at 30.4 s, DER rose from 5.68% to 5.98%. Full-set CALLHOME-Part2 still improved from 10.32% to 9.10%. Throughput also jumped. At 30.4 s, the model reached 15,113× RTFx versus 2,619× for the baseline. The tests used BF16 on an NVIDIA RTX PRO 5000 with torch.compile(). These are batched numbers, not single-stream application latency. Training Data Training combined about 10,000 hours of real conversations with 82,611 hours of simulated multi-talker mixtures. The mix included real-world multi-speaker audio licensed from David AI. Adding the David AI data cut compound DER from 11.19% to 10.42%. The licensed source audio for the simulated mixtures spans 21 languages. Getting Started Install NVIDIA NeMo Speech with Python 3.12 or later: Copy CodeCopiedUse a different Browser uv pip install ‘nemo-toolkit[asr]’ Copy CodeCopiedUse a different Browser from nemo.collections.asr.models import SortformerEncLabelModel diar_model = SortformerEncLabelModel.from_pretrained(“nvidia/Nemotron-3-Diarization”) diar_model.eval() segments = diar_model.diarize(audio=[“conversation.wav”], batch_size=1) Output segments take the form start end speaker_id. To get the words as well, pair the model with Parakeet TDT 0.6B v3 using the ASR integration guide. The live demo Space offers synthetic conversations, a live mic, a multilingual live mic, and audio upload. For production, NVIDIA lists Baseten and DigitalOcean. On-device support is available through Argmax Pro SDK 3. The model is not yet available through Hugging Face Inference Providers. The model has limits. Recordings with more than 8 speakers can produce missed or misassigned speech. Heavy noise, reverberation, and far-field capture can also raise error rates. Interactive Explainer Key Takeaways 100M-parameter open-weight model tracks up to 8 overlapping speakers. One checkpoint covers everything from offline (30.4 s) to ultra-low 0.32 s streaming. Ranked #1 on Voice Arena’s initial Diarization-Bench at 14.72% DER. Averages a 41.0% relative DER reduction versus Streaming Sortformer at 1.04 s. The OpenMDW-1.1 license permits commercial use; the model runs on NVIDIA GPUs through NeMo. Check out the Model Weights, Technical Blog, and Demo. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time appeared first on MarkTechPost.
Delia Ramirez, a Democratic US representative from Illinois, has announced a plan to introduce new legislation to terminate the surveillance tower program along the US southern border. The announcement comes just days after publication of an MIT Technology Review investigation, “Dying on Camera,” in which we looked at deaths along the border that took place close to one or more of these towers. MIT Technology Review found that nearly one in four deaths we analyzed between 2015 and early 2026 occurred within their advertised range. We also showed that the Department of Homeland Security does not keep track of these deaths or other metrics on the towers’ success or failure. Ramirez, who sits on the Homeland Security Committee, cited MIT Technology Review’s reporting that nearly “1,100 people have died within range of a billion-dollar surveillance tower system between 2015 and 2026,” adding, “The towers that we have paid a billion dollars to just don’t work.” The legislation, the Reimagining Safety Act, was developed in consultation with community groups and local and state representatives. The advocacy organizations Just Futures Law, which focuses on immigrant rights and racial justice, and Mijente, which describes itself as a “vehicle for building independent Latinx political power,” helped shape the calls to terminate the border towers program, following a joint report they put out earlier this year on the technology used by ICE. The legislation is intended to be part of a broader proposal to replace the Department of Homeland Security with a new Department of Community Safety while moving CISA, FEMA, TSA, and customs functions to other existing federal agencies. Her office has yet to release the text of the proposed legislation, saying that it will come in the next few weeks. There has been growing public support for abolishing ICE in the wake of the second Trump administration’s highly visible enforcement operations across American cities, the buildout of its detention apparatus, and shootings by ICE and CBP agents. Wilber Rafael Garcés Pérez, a delivery driver, was shot in the back by an ICE agent just last weekend in Austin, Texas. But for Ramirez, abolishing just ICE is not enough. At a press conference held in Chicago on Wednesday, Ramirez said, “There’s no question that DHS has to be dismantled. We need to provide them a road map in how we do it,” Ramirez said. It will not be the first time that a bill to dismantle the Department of Homeland Security has been introduced, but previous proposals have not gone very far. This proposal will also face a steep uphill battle in Congress, where even some Democrats favor reforming rather than outright dismantling the organization. Ramirez, however, sits on both the House committee that oversees the department, and is the ranking member on the Homeland Security Committee’s cybersecurity subcommittee. “We’re limiting state surveillance, we’re reigning unlawful abuses of data and curbing the militarized enforcement. We’re beginning the process of establishing a separate civil immigration system,” Ramirez said. CBP did not offer an immediate response for comment. Markwayne Mullin, the Secretary of Homeland Security, said, “Radical leftists are calling to defund the police and abolish DHS. It’s NEVER going to happen.” This story has been updated to include a response from the Secretary of Homeland Security.
We use cookies to improve your experience and performance on our website. You can learn more at Politica sulla privacy and manage your privacy settings by clicking Settings.


