YouZum

Uncategorized

AI, Committee, Noticias, Uncategorized

TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text

The ChatGPT moment in 2022 taught AI to talk to people. One of its builders now bets the next moment is AI that talks to software, not people. TypeSafe AI released Jev. Jev is transformer-based, but it is not a large language model. It does not generate text. You send a state and typed questions. It returns typed decisions with probabilities that code can branch on. Is it deployable? Yes, as a hosted API in early access behind a waitlist. TypeSafe has not published weights, a parameter count, or a self-hosting option. What is a System One Model? The name borrows from Daniel Kahneman’s split between fast intuition and slow reasoning. TypeSafe team argues RLHF tuned models for human preference. That produced chat, and overconfidence and mode dropping. Those flaws keep a human in the loop. Jev uses a new stack: a new architecture, a parallel sampler, and Reinforcement Learning for Calibrated Decisions (RLCD). TypeSafe has not disclosed the architecture. How the Jev API Works One endpoint handles everything: POST https://api.typesafe.ai/v1/systemone. The body carries state, model, and a map of questions. The docs define 3 question types. Primitive Asks Returns Choice Pick 1 option from a list choice, probabilities, confidence Score Rate against ordered levels score, probabilities, confidence Noul Is this statement true? noul, a probability from 0 to 1 Questions run in parallel and in isolation against the same state. TypeSafe says adding questions barely changes response time. A Choice supports up to 255 options. Copy CodeCopiedUse a different Browser from typesafe_sdk import Choice, Noul, TypeSafeClient client = TypeSafeClient() # reads TYPESAFE_API_KEY r = client.system_one( state=ticket, questions={ “department”: Choice( instructions=”Which team should handle this”, criteria={“billing”: “Payment issues”, “technical”: “Bugs”}, ), “is_urgent”: Noul(instructions=”The message conveys urgency”), }, ) print(r.answers[“department”].choice, r.answers[“is_urgent”].noul) Install with pip install typesafe-sdk (Python 3.10 or later). A JavaScript SDK ships as @typesafe-ai/sdk. The quickstart also covers cURL and an agent skill for Claude Code. Confidence is the Product Every Choice and Score answer carries a confidence value from 0 to 1. TypeSafe derives it from the shape of the probability distribution. In the docs example, billing wins at 0.84. Confidence is only 0.596, because technical still holds 0.159. The docs suggest 3 paths. Act on high confidence. Review the middle. Send low confidence to a human. Thresholds should scale with the cost of a wrong action. Pricing, Speed, and the Benchmark Fine Print Jev costs $42 per billion input tokens. TypeSafe quotes existing LLMs at $0.20 to $10 per 1M input tokens. In its recorded demo, Jev finished in 0.114s for $0.000081. GPT-5.6 Terra took 8.566s for $0.013880. The TypeSafe team claims it to be 193.6x faster and 444.6x cheaper. Those figures come from TypeSafe’s own workflow evals. But hold on here are some things to keep in mind: The reference answer is the average of GPT-6 Astra and Fable 5.1. TypeSafe’s capabilities team wrote the workflows. TypeSafe expects these gains to sit at the high end of real use. TypeSafe says it cannot prove the price is unsubsidized. ‘Zero hallucinations’ means schema matching is guaranteed. The 0% figure is not empirical. Answers can still be wrong. What Developers are Building with Jev Community projects appeared within days of launch. Here are some examples: Command safety: Vercel CEO Guillermo Rauch reported Jev up to 18x faster at p95 than GPT Luna, and more accurate. His post said the fx reviewer still ran on Luna. Engineer Pranit Sharma shared the benchmark. Email triage:Bryo AI CTO Nikhil Mudholkar found Gemini slightly more accurate, but 10 to 20 times more expensive. Browser agents: Browser Use’s jev-ultrafast ran a Zürich to London Google Flights search in 7.1 seconds (video). Phone agents: Droidrun’s mobile-jev drove Uber on a real Android phone: 9 actions in about 21 seconds (video). No booking was completed. Video scoring: jevmeter scores every sentence of a debate for about $0.05 (demo on X). Live typing: Steve Krouse’s Typewriter updates 16 judgments as you type (try it). Games: Jev completed StarCraft’s first combat mission (video). It also runs the guards in heist-one (video). Agent guardrails: jev-guard rates each tool call as deny, ask, or allow (78-second video). Data and homes: pg-jev adds plain-language filters to Postgres. HA-Jev turns answers into Home Assistant entities. Interactive Explainer Key Takeaways Jev outputs typed decisions with probabilities, not strings. 3 primitives (Choice, Score, Noul) can share 1 request. Input costs $0.042 per 1M tokens. Output tokens are free. TypeSafe reports 70ms to 500ms end-to-end response times. The main benchmarks are vendor-run. Test on your own data. Check out the launch post, docs, and TypeSafe’s GitHub. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text appeared first on MarkTechPost.
TypeSafe AI Releases Jev: A System One Model That Returns Typed, Calibrated Decisions Instead of Text Leer entrada »

AI, Committee, Noticias, Uncategorized

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model

Linkup research team releases SPARSEUP, an open-source learned sparse embedding model. The model runs on a 149M-parameter ModernBERT backbone and ships under Apache 2.0. Linkup team reports 56.4 average nDCG@10 on BEIR-13. It calls this the strongest public vocabulary-based sparse encoder it knows of under 150M parameters. Is it deployable? Yes. The weights are on Hugging Face under Apache 2.0. The model loads through Transformers or Sentence Transformers with trust_remote_code=True. Why a Sparse Model, and Why Now Most open retrieval models are dense: 1 vector per text. Sparse models output weights over a vocabulary instead. Each dimension maps to a real token, so vectors fit inverted indexes and humans can read them. They also tend to match rare words well. The trigger was LightOn’s DenseOn and LateOn release. LightOn published open data, a training recipe, a dense model and a late-interaction model. SPARSEUP fills the missing sparse slot. It uses the same backbone family and fine-tuning data, so all 3 retrieval styles can be compared side by side. How is SPARSEUP Built Training starts from LateOn-unsupervised. That checkpoint had no MLM head, so the team grafted back ModernBERT’s original one. Fine-tuning used LightOn’s fine-tuning mixture with contrastive learning only. Each query gets 7 hard negatives sampled from a pool of 50, and in-batch negatives. There is no cross-encoder distillation, and training fits on a single H100. A vanilla SPLADE on this backbone produced huge bags full of stopwords. Linkup fixed this with 3 changes: Logit shifting: The encoder computes log(1 + ReLU(x – 15)). ModernBERT’s MLM logits sat too high, saturating the log and making bags dense at initialization. Per-position top-k: Each input token keeps only its 12 strongest vocabulary dimensions before max pooling. This caps expansion per token, not total vector size. Case folding: Byte-level BPE stores heat, Heat, Ġheat and ĠHeat as separate ids. SPARSEUP folds them onto 1 id and keeps the largest weight. Output dimensions drop from about 50k to about 34k. Queries and documents take [Q] and [D] prefixes, and scoring is a dot product. Evaluation max lengths are 128 tokens for queries and 512 for documents. Benchmark Results Against other sparse encoders on BEIR-13 (nDCG@10, without MS MARCO), per the model card: Model BEIR-13 avg SPARSEUP 56.4 opensearch-neural-sparse-encoding-doc-v3-gte 54.6 opensearch-neural-sparse-encoding-v1 52.44 ModernBERT-VT 52.4 splade-v3 51.7 granite-embedding-30m-sparse 50.6 LACONIC-1B (1B parameters, different size class) 58.7 The controlled comparison is less flattering. With backbone and data fixed, LateOn scores 58.9, DenseOn 57.9 and SPARSEUP 56.4. SPARSEUP uses approximate Seismic search, while LightOn reports exact search. SPARSEUP wins ArguAna and Touché and beats DenseOn on HotpotQA. It lags on more semantic sets, with FiQA showing the largest gap. DBPedia is another weak spot. On decontaminated BEIR, the gap to DenseOn shrinks to 0.17 points. Linkup warns that decontaminated NQ and MS MARCO have only 21 and 46 queries, so those results are noisy. Speed and Sparsity On MS MARCO, SPARSEUP averages 47 non-zero terms per query and 190 per document. SPLADE-v3 averages 25 and 170. With the Seismic inverted index, it reaches over 97% recall against exact search in about 380 microseconds per query, single-threaded. Linkup says inflating vector size could add 1 to 2 BEIR points, but it chose to stay sparse. Key Takeaways SPARSEUP is Linkup Research’s first open model: a 149M-parameter sparse encoder under Apache 2.0. It scores 56.4 nDCG@10 on BEIR-13, top among public sparse encoders under 150M, per Linkup. 3 fixes drive it: a logit shift of 15, top-12 expansion per token, and case folding. With identical data, it trails DenseOn by 1.52 points and LateOn by 2.5 on BEIR-13. It reaches over 97% recall in about 380µs per query with Seismic on MS MARCO. Check out the Model Weights and Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model appeared first on MarkTechPost.

Linkup Research Releases SPARSEUP: A 149M-Parameter Open-Source Sparse Embedding Model Leer entrada »

AI, Committee, Noticias, Uncategorized

Could AI really kill us all? Your questions, answered.

On Wednesday, MIT Technology Review hosted a live Roundtables event for subscribers that asked the question everyone’s asking right now: Could AI really kill us all? But attendees had so many more questions than we had time to answer in the 30 minute session. So we asked our senior AI editor Will Douglas Heaven and AI reporter Grace Huckins to round up some of the best questions attendees submitted and try their best to answer them. Thanks to all who submitted questions! Am I gonna die? Yes, eventually. Unfortunately, my journalistic powers of prognostication aren’t powerful enough for me to tell you how. But it certainly could be because of AI. AI-powered drones have already killed people in Ukraine, and AI-driven cyberattacks on hospitals will surely claim victims before long.  Could AI go even further, and kill all of us? Less likely. But some people—quirky people, but undeniably knowledgeable about AI—have been warning for years that this could happen. And while I’m not yet stockpiling canned food or trying to get in good with a bunker-owning megabillionaire, I have noticed that the doomers’ predictions about AI capabilities and alignment have, over the past couple of years, proved disconcertingly accurate. That certainly doesn’t mean that their more dire forecasts will come true, but it’s enough for me to sit up and take notice. — Grace Huckins Are you going to die because of AI? I’d say there’s a non-zero chance. Let’s say you’re unlucky enough to be the victim of a freakish near-future event or accident. Maybe it’s a cyberattack carried out by a swarm of AI agents on critical infrastructure. Sadly, a scenario like that now no longer feels as far-fetched as it once did. Or maybe a novel AI-designed pathogen cuts through the population. Or the world economy crashes, causing conflicts and famine. Both plausible, but I think less likely.  Are we all going to die because of AI? Nope. There are no circumstances outside of apocalyptic science fiction in which AI could kill us all. You can spin up any number of scare stories, but they’re not grounded in present-day realities about what the tech can do or where it’s headed.  Some people argue that there’s no harm in preparing for the worst, however wacky it might seem. Maybe. But I think such catastrophizing can make people excuse or overlook many of the more immediate problems with the existing technology and the companies building it.  — Will Douglas Heaven Why would AI kill us? Someone might tell it to, and it might listen. That’s part of the reason researchers are so concerned about AI’s biological capabilities—imagine what Aum Shinrikyo, the doomsday cult behind the Tokyo subway sarin attack of 1995, would have done with a tool that could design a pathogen deadlier than Ebola and more transmissible than measles. Those of us who don’t want to die have to figure out how to defend against all plausible biological weapons, but our would-be attackers only have to manufacture one effective pathogen. Then there’s the more exotic-sounding possibility that an AI could decide to kill us itself. There are various stories about how this might happen out there, but the most widespread involve AI systems that don’t hate people, necessarily—we are just an obstacle between them and the goals that we gave them. Much as the OpenAI agents behind the Hugging Face hack compromised another site’s infrastructure to get a good score on a test, the idea is that some future, more powerful AI might get rid of us to prevent us from shutting it down—all in pursuit of some goal that we instructed it to go after.  — Grace Huckins How can we best ensure alignment so the worst doesn’t happen, and who is doing the best work to achieve it?  Alignment is a huge area of research. In simple terms, it involves building models that behave in ways we want them to and not in ways we don’t. We need to trust agents better before handing over more autonomy. Alignment is supposed to establish that trust. But it’s hard.  LLMs aren’t designed in the way other software is, where dos and don’ts can be hard-coded in. Instead, aligned behavior needs to be instilled when models are trained. One approach is to reward them for doing things you want them to (a little like raising a toddler, perhaps). Another approach involves giving an LLM a written list of rules it is supposed to follow (kind of like a constitution).  Anthropic and OpenAI are both leaders in this field—and yet neither has been able to develop models that are fully aligned. A big problem is that LLMs are far more inconsistent and far less predictable than people. They can behave in one way in one situation and another way in a situation that to us seems very similar. They can also be swayed by unexpected constraints. For example, faced with an impossible task (as many of the agents involved in the Hugging Face hack were), models may try to do whatever it takes to achieve their goal. As Grace mentions above, that could be an issue. The main reason top AI firms now say they want a slowdown is that they want to focus on cracking alignment. Alignment isn’t necessarily a pipe dream. But the jury’s out on whether full alignment will ever be feasible.  — Will Douglas Heaven Is AI really dangerous, or is this the tech companies drumming up PR? This is always a reasonable thought when it comes to tech companies heading for an IPO—CEOs have an obvious incentive to make their products seem radical and transformative. But I’m not so sure it makes sense here. Telling the public that an already unpopular product could kill them and everyone they love is horrible corporate image management. There are other stories you can tell about the CEOs’ motivations—maybe they want to cool down the public furor over data centers by portraying themselves as responsible stewards of a

Could AI really kill us all? Your questions, answered. Leer entrada »

AI, Committee, Noticias, Uncategorized

PrismML Releases Ternary Bonsai 2 27B: A 5.9 GB Apache 2.0 Model Retaining 98.2% of Qwen3.8 27B Performance

PrismML has released Ternary Bonsai 2 27B, a ternary-weight version of Qwen3.8 27B. The language model occupies 5.93 GB, against 53.80 GB in FP16. PrismML reports that it keeps 98.2% of the parent model’s average across 20 benchmarks. The model accepts text and images and supports a 262K-token context. PrismML demos it driving Cline coding agents and computer use on an RTX 5090. It arrives 2 months after the first Bonsai 27B, whose ternary variant retained about 95%. Is it deployable? Yes. The Apache 2.0 weights run today on a 16 GB laptop or a single 24 GB GPU. You need PrismML’s llama.cpp fork or its MLX runtime. What is Ternary Bonsai 2 27B? The model keeps the Qwen3.8 27B architecture unchanged. It has 27.36B parameters. That splits into a 24.35B language backbone, 2.54B in embeddings and LM head, and a 0.47B vision tower. The backbone uses hybrid attention, with about 75% linear-attention and 25% full-attention layers. Ternary weights cover embeddings, attention projections, MLP projections and the LM head. Only 26.2M parameters, or 0.0976%, stay in higher precision. Those are the recurrent state path and normalization weights. In GGUF, the vision tower ships separately as a 0.63 GB file, loaded only for image input. How Does the Ternary Format Work? Each weight takes 1 of 3 values: -1, 0 or +1. Every group of 128 weights shares 1 FP16 scale. A ternary value carries log2(3), or about 1.585 bits. Adding 16 scale bits per 128 weights gives 1.71 bits per weight. Counting the high-precision tensors brings the model to 1.72. Real kernels need a packed layout, so the whitepaper describes 2 GGUF packings. PTQ1_0 packs trits densely at 1.76 bits per weight and 5.93 GB. PQ2_0 stores each trit in a 2-bit slot at 7.25 GB, which is cheaper to unpack. Weights are also stored in a rotated basis. PrismML applies a blockwise Hadamard rotation with block size 1,024 before ternary assignment. The runtime applies the matching transform to activations before each multiply. The whitepaper cites SpinQuant for this idea. PrismML does not publish how it assigns the ternary values. How Does It Score Against Qwen3.8 27B? PrismML evaluated all models in thinking mode with EvalScope and vLLM on H100 GPUs. Capability Qwen3.6 27B Qwen3.8 27B Ternary Bonsai 2 27B Retention Knowledge and reasoning 84.71 86.66 83.95 96.9% Math 94.64 97.06 96.57 99.5% Coding 82.57 82.17 81.58 99.3% Agentic and tool calling 80.05 79.74 77.57 97.3% Instruction following 74.53 81.25 82.66 101.7% Vision 79.82 81.64 78.59 96.3% Overall (20) 83.6 85.4 83.9 98.2% The comparison with conventional quantization is the sharper result. An IQ2_XXS build of Qwen3.8 27B averages 75.2 at 7.3 GB. On AIME26 it scores 78.6, while Bonsai 2 scores 95.83. On LiveCodeBench v6 the gap is 70.05 versus 90.07. Where Does It Still Lose Quality? The 98.2% figure is an average, and the losses are uneven. Vision retains 96.3% and knowledge and reasoning retains 96.9%. Long-horizon agent work drops further. Bonsai 2 scores 52.8 on Terminal-Bench 2.1, against 69.7 for Qwen3.8 27B. On SWE-bench Verified it scores 60.8 against 80.6. That is about 75% retention, and both sit outside the 20-benchmark average. Reasoning effort matters too. At medium effort the model averages 79.3, against 82.6 for the FP16 baseline. Low effort is not supported. All results are PrismML’s own and have not been independently reproduced. How Fast is It on Real Hardware? Figures are batch size 1 decode on PrismML’s custom kernels, measured September 16, 2026. An RTX 5090 reaches 142.5 tokens per second at 0.582 mWh per token. An RTX 4090 reaches 96.7 with PTQ1_0, and a 72 W L4 reaches 32.1. On Apple laptops, an M5 Max reaches 46.8 and an M5 Pro reaches 27.7. Neither packing wins everywhere. PTQ1_0 is faster on Ada-generation cards and the L4. PQ2_0 is faster on Blackwell, Hopper, Ampere and Apple silicon, and at prompt processing everywhere. PrismML research team also claims 40% better energy efficiency than a full-precision 8B model. How Do You Run It? The GGUF files need PrismML’s llama.cpp fork. Stock llama.cpp rejects the PTQ1_0 and PQ2_0 types. The Bonsai-demo repo is the supported path. Run ./setup.sh, then ./scripts/start_llama_server.sh for chat, vision and tools at localhost:8080. Mac users can take the MLX pack, which needs its bundled loader. A WebGPU demo runs the model inside a browser. Key Takeaways 5.93 GB language model, about 9.1x smaller than the 53.80 GB FP16 baseline. 83.9 average on 20 benchmarks, versus 85.4 for Qwen3.8 27B in FP16. 142.5 tokens per second on an RTX 5090 and 46.8 on an M5 Max. Long-horizon agent benchmarks keep only about 75% of full-precision scores. Stock llama.cpp cannot load these files. PrismML’s fork is required. Check out the Whitepaper, Model weights, GitHub repo, Docs, WebGPU demo and announcement on X. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post PrismML Releases Ternary Bonsai 2 27B: A 5.9 GB Apache 2.0 Model Retaining 98.2% of Qwen3.8 27B Performance appeared first on MarkTechPost.

PrismML Releases Ternary Bonsai 2 27B: A 5.9 GB Apache 2.0 Model Retaining 98.2% of Qwen3.8 27B Performance Leer entrada »

AI, Committee, Noticias, Uncategorized

The Download: AI’s extinction risk and bioweapons threat

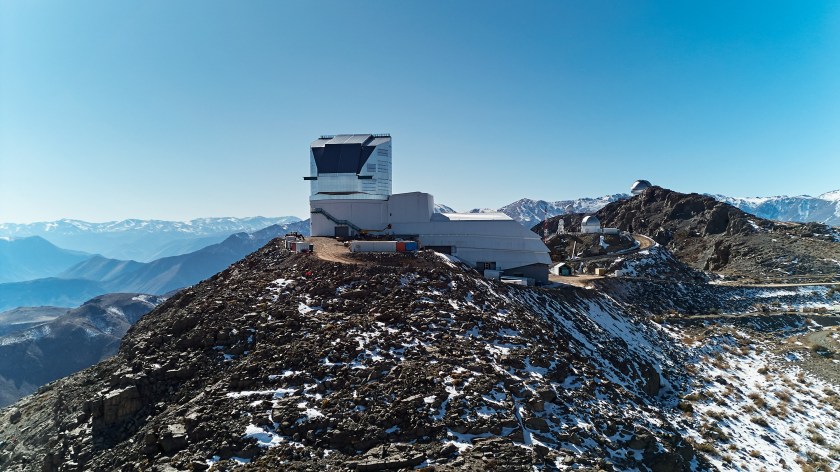
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Could AI really kill us all? Your questions, answered On Wednesday, MIT Technology Review hosted a live Roundtables event that asked the question many seem to be asking right now: could AI really kill us all? But attendees had more questions than we had time to answer, so we asked senior AI editor Will Douglas Heaven and AI reporter Grace Huckins to tackle some of the best ones.  The questions they tried to answer include: am I going to die? Why should AI kill us, if at all? Is AI really dangerous, or is it just tech companies drumming up PR? And what steps can be taken to make sure AI is controlled, monitored and regulated effectively? Here are their responses. —Will Douglas Heaven and Grace Huckins The specter of AI-enabled bioweapons is a wake-up call for biotech One of the ways AI could potentially cause catastrophic harm is by aiding the design and creation of bioweapons. In 2022, researchers found that it was remarkably easy to do this with an AI “molecule generator” built to develop drugs. In less than six hours, the model generated 40,000 molecules that could serve as chemical warfare agents.  Today, AI tools can answer questions on almost every area of science, while advances in gene editing and synthetic biology have made biotech tools more accessible. There are safeguards, but none are ironclad. However, scientists disagree about how serious the risk is anyway. Find out why it’s easier than ever to design killer pathogens. —Jessica Hamzelou This story is from The Checkup, our weekly biotech newsletter. Sign up to receive it in your inbox every Thursday. The role of the astronaut is in flux We go to space for geopolitical prestige, manifest destiny, spiritual fulfillment, scientific curiosity, and, increasingly, business opportunities. In the wake of Artemis II, a slew of new books suggest that these justifications are subsumed by one unifying fact: humans have itchy feet, and we are simply wired to roam.  In The Ultraview Effect, space anthropologist Deana L. Weibel frames human space exploration as part of our need to embark on pilgrimages. In A Heart for Space, civilian astronaut Eiman Jahangir recounts one such voyage with Blue Origin. And in Dinner with an Astronaut, former NASA astronaut Leroy Chiao argues that people simply “need to know what’s on the other side.” See what these three new books have to say about why we go to space. —Becky Ferreira This story is from our latest print magazine, which is all about kids. Subscribe now to receive every issue when it lands. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Microsoft and OpenAI workers say AI is destroying the webCannibalizing clicks from websites obliterates the business models that keep fresh content coming. (404 Media)+ The employees showed concern that publishers couldn’t survive AI scraping. (NYT $)+ The comments emerged during the NYT’s copyright case. (WP $)+ They could weaken OpenAI and Microsoft’s defense. (Reuters $)+ AI means the end of internet search as we’ve known it. (MIT Technology Review) 2 Robot boats have fought each other for the first timeA Ukrainian vessel sank a Russian one in combat. (New Scientist $)+ US firms are building combat-ready humanoids. (WSJ $) 3 Security researchers breached OpenAI using Anthropic’s toolsThey reached an employee’s ChatGPT account and internal code. (FT $)+ They exploited a third-party forum to reach internal systems. (WSJ $) 4 OpenAI reportedly expects to soon crack another famous math problemBut can it avoid another backlash when announcing it? (Information $)+ The problem it expects to solve is the Hodge Conjecture. (Gizmodo)+ OpenAI’s math controversies contain concerning clues about the field’s future. (MIT Technology Review) 5 Elon Musk’s SpaceXAI wants to buy data from failed startupsIt’s seeking new sources of training data for Grok. (Bloomberg $+ And it’s targeting customer and operational data. (Gizmodo)+ OpenAI is paying to create new biology data. (MIT Technology Review) 6 Schools are pushing back against Big Tech’s classroom takeoverAI is accelerating concerns about corporate influence. (New Yorker $)+ We need smarter AI use in schools. (MIT Technology Review) 7 Hackers have revealed how Flock cameras track cars—and peopleOne camera captured 1.6 million images of 50,000 vehicles. (Wired $)+ The cameras also detect people and misidentify objects. (404 Media) 8 Chinese firms doubled down on science after US tech restrictionsThey produced 72% more patents citing scientific papers. (Nature) 9 A three-year-old’s cancer disappeared after an experimental cell therapyCAR T therapy may finally be able to treat solid tumors. (Gizmodo) 10 NYC’s new robotoilets will kick you out after 10 minutesThe doors automatically open when the timer runs out. (Fast Company) Quote of the day “The largest theft of labor in human history.”  —Microsoft’s director of Applied Science, Brent Hecht, raises his concerns over training data used for AI systems in comments revealed in court filings from the New York Times vs OpenAI copyright lawsuit. One more thing The Vera C. Rubin Observatory is ready to transform our understanding of the cosmos High atop Chile’s 2,700-meter Cerro Pachón, the air is clear and dry, leaving few clouds to block the beautiful view of the stars. It’s here that the Vera C. Rubin Observatory is using a car-size 3,200-megapixel digital camera—the largest ever built—to produce a new map of the entire night sky every three days. Generating 20 terabytes of data per night, Rubin will capture fine details about the solar system, the Milky Way and the large-scale structure of the cosmos. Over 10 years, it will catalogue billions of new objects, offering an unprecedented look at what’s changing in the universe. Step inside the observatory mapping the cosmos in a way we’ve never seen before. —Adam Mann We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop

The Download: AI’s extinction risk and bioweapons threat Leer entrada »

AI, Committee, Noticias, Uncategorized

Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs

Jina AI, part of Elastic, has released jina-ocr-v1, an end-to-end visual document parser. It takes PDFs, scans, tables, charts or invoices and returns clean Markdown in 1 pass. The model has 3.4B total parameters, with about 570M decoder parameters active per token. A speculative decoding head ships inside the checkpoint. Jina AI built it to serve on low-budget GPUs such as the NVIDIA L4. The technical report lists 91.14 on OmniDocBench v1.6 and 83.4 on olmOCR-Bench. Is it deployable? Yes, for research and non-commercial use. The open weights are about 6.8 GB in BF16 and run on Transformers or vLLM. The CC BY-NC 4.0 license means commercial use requires contacting Jina AI. What is jina-ocr-v1? The model post-trains DeepSeek-OCR and keeps its 2 efficiency components. DeepEncoder has about 380M parameters and chains SAM, a 16x convolutional compressor and CLIP-L. It turns a 1024×1024 page view from 4,096 patches into 256 visual tokens. A dynamic-resolution mode adds up to 9 local tiles at 100 tokens each. That caps a page at 1,156 visual tokens. The decoder is DeepSeek-3B-MoE with 12 layers, 64 routed experts and 2 shared experts. Top-6 routing activates about 570M parameters per token. The position limit is 32,768. Output is Markdown, with tables in HTML and formulas in LaTeX. How FastMTP Speculative Decoding Works OCR output is near-deterministic and locally structured. That makes it a good fit for speculative decoding. Jina AI adds a FastMTP head: 1 dense draft block applied recursively for K=3 steps. Draft parameters stay constant as depth grows. The decoder then verifies the drafts greedily. It accepts the longest prefix that matches its own choices and commits 1 more token itself. If all 3 drafts match, that extra token is a bonus. The committed text always equals plain greedy decoding, so the speedup is lossless. At K=3 the model commits 2.73 tokens per step on average. Post-Training With Dense Verifiable Rewards Post-training combines instruction alignment, robustness fine-tuning on degraded pages, and GRPO. Every reward term is deterministic code scored against a reference transcription. The terms cover content, formulas, tables, structural validity, unit tests, repetition and format. The terms are multiplied, and each one is graded, so partly correct pages earn partial credit. Structural, unit-test and format terms are floored at 0.2, and the table term at 0.1. The repetition term has no floor, because loops can inflate the content score. On natural pages, the formula and table rewards apply to few samples. Jina AI therefore built JinaOCRSynth, synthetic pages packed with both, each carrying olmOCR-Bench-style unit tests. An agent also merges candidate checkpoints under a fixed evaluation budget. The draft head is trained last, against the frozen final verifier. Benchmarks and Throughput Model Params as listed in the paper OmniDocBench v1.6 olmOCR-Bench jina-ocr-v1 3B/570M 91.14 83.4 DeepSeek-OCR 3B/570M not listed 76.0 DeepSeek-OCR-2 3B/570M 90.25 not listed PaddleOCR-VL-1.6 0.9B 96.34 not listed chandra-ocr-2 4B not listed 85.8 Qwen3-VL-235B 235B/22B 89.78 not listed For MoE models, params show decoder total and active counts. The whole jina-ocr-v1 model is about 3.4B. The model does not lead on accuracy. PaddleOCR-VL-1.6 and HunyuanOCR-1.5 (94.74) score higher on OmniDocBench. chandra-ocr-2 and dots.mocr (83.9) score higher on olmOCR-Bench. Post-training does add 7.4 points over the DeepSeek-OCR backbone on olmOCR-Bench. Throughput is the main result. On 1 A100 40 GB at concurrency 32, jina-ocr-v1 parses 2.57 pages per second. That is the highest of 14 systems Jina AI measured, against 1.22 for olmOCR-2 and 0.38 for chandra-ocr-2. It emits 1,085 output tokens per page. Jina AI says that is the shortest output among systems scoring above 83. On an NVIDIA L4 at batch size 1, eager decoding rises from 42.7 to 83.1 tokens per second. That is a 1.95x speedup at a 57.6% acceptance rate. With CUDA graphs the baseline is already 158.3 tokens per second. There, K=1 works best at 185.6 tokens per second, a 1.17x gain. How to Run It The quickest route is Jina Reader. Send a URL to r.jina.ai with the header X-Respond-With: jina-ocr-v1. Reader fetches the page or PDF, runs the model and returns Markdown. An X-Page header transcribes 1 page of a longer document. Jina AI also hosts an OpenAI-compatible endpoint at https://api.jina.ai/v1/chat/completions. A hosted demo is available for quick tests. For self-hosting, weights and custom code ship in 1 repository and load with trust_remote_code=True. FastMTP requires vLLM 0.21 or later and a one-time register() call. The Transformers path runs the MoE decoder alone and ignores the draft weights. Key Takeaways 3.4B total parameters, about 570M active per token, built on DeepSeek-OCR. FastMTP drafts 3 tokens per step, and greedy verification keeps decoding lossless. Scores 91.14 on OmniDocBench v1.6 and 83.4 on olmOCR-Bench. Reaches 2.57 pages per second on 1 A100, the highest of 14 measured systems. Available on Hugging Face and through a Jina Reader header today. Check out the Paper, Model weights, Release post, Model page and Announcement. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs appeared first on MarkTechPost.

Jina AI Releases jina-ocr-v1: A 3.4B MoE Document Parser With Built-In Speculative Decoding for Low-Budget GPUs Leer entrada »

AI, Committee, Noticias, Uncategorized

Meet the innovators under 35 shaping climate tech

Each year, the editorial team at MIT Technology Review puts together a list of 35 innovators under 35—a group of researchers, inventors, and other young minds worth following. The team worked on the newest edition of the list for months, and the final slate includes nine individuals from all over the world in the climate and energy category. Each one has a fascinating story and is tackling an important challenge. I think it’s worth zooming out and considering the energy and climate awardees as a group. Taken together, these innovators and their work can tell us something about where climate tech is at this moment—and where it’s heading. AI is the dominant technology story, both for its potential and its challenges. We split the innovators into four main categories this year: biotech, climate and energy, computing and robotics, and AI. It probably won’t surprise you that AI features heavily in the work of many innovators in other categories. Climate innovator Jae-Won Chung, for example, built software to make AI more energy-efficient. By measuring the energy demands of open-source models, he hopes the industry can better understand and address the impact of AI. (If this work sounds familiar, it’s because we spoke with him last year for our investigation into AI’s energy demands.) But AI also has the potential to improve many areas of research. Jing Wei is using AI to track pollution more effectively, essentially using machine learning to fill in gaps in data from disparate sources like satellites and weather stations. Zhonghua Zheng developed AI climate models that work better for cities, a well-known blind spot for traditional models. We need better ways to get the critical materials used to build new technologies. As we begin to rely on new technologies to power our world, we’ll see a major shift in the materials we need to build them. Lithium is a prime example: The metal underpins lithium-ion batteries, which are crucial not only for electric vehicles, but also for large-scale energy storage on the grid. We could face lithium shortages as soon as this decade, and the prospect of supply crunches applies to other critical minerals, too—copper is another one to watch closely. Brine is currently the cheapest source of lithium, but the process to get the metal out can take months and harm the local environment. Mohammad Alkhadra is the cofounder and CEO of Lithios, a startup working to quickly and efficiently extract lithium from brines. Hardrock ore is the most common source of lithium, but it’s more expensive than brine. Benjamin Mowbray cofounded and serves as CTO for Rock Zero, which is working to extract lithium from hardrock ore. Addressing climate change will require overhauling all corners of our society, sometimes in surprising ways. To reach net-zero greenhouse gas emissions we will obviously need to rethink major sectors, like the electrical grid and transportation, to move away from fossil fuels. But outside these primary sources of climate pollution are seemingly infinite, less obvious problems to figure out, too. Heavy industry, including steel production, is a major one, making up about 7% of global greenhouse gas emissions. Laureen Meroueh is making cleaner, cheaper steel using a new kind of furnace that simplifies the chemical process required to produce the metal. Plastics are generally made with fossil fuels, so we’ll need alternatives to this incredibly useful category of materials. Joseph Nguthiru is making a bioplastic replacement for fossil-derived packaging that uses an invasive weed. Also using available materials in a creative way, Diana Orembe is making fish food for aquaculture with food waste. And refrigerants are often incredibly powerful greenhouse gases. Jinyoung Seo is developing solid refrigerants that could eliminate worries about leakage. A device using these materials could reduce energy consumption by 20% compared to conventional technology. I’m constantly learning about new challenges we face in the climate and energy world, and I’m often surprised by the ideas people are coming up with to address them. For more on all the under-35 innovators and their work, check out our full 2026 list.   This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Meet the innovators under 35 shaping climate tech Leer entrada »

AI, Committee, Noticias, Uncategorized

Anthropic Launches Claude Code Projects in Beta: Parallel Cloud Sessions That Keep Running After You Close Your Laptop

Anthropic redesigned Projects in Claude Code. The old project was a folder: some files plus one chat. The new one is a single ongoing conversation where Claude acts as coordinator. You describe work, and Claude decides what becomes a thread. Each thread is a full Claude Code cloud session running on its own branch and its own copy of the repository. Threads run in parallel, report back to the conversation, and keep going after you close your laptop. Anthropic’s launch post calls it one conversation that splits itself into parallel cloud sessions. Coordinator and threads The architecture has two layers. The project conversation is the coordinator. It reads what you send, answers quick questions in place, and starts threads for actual work. It sees what threads report back, not every step they take. Threads are the workers. A thread opens a pull request when the work calls for one, then watches that pull request with auto-fix enabled. It pushes fixes when CI fails and replies when checks pass. Threads delegate too. Each can split its assignment further using subagents, loops and workflows. Anthropic’s own example: set a goal to reduce checkout p75 latency, then ask Claude to profile each endpoint, test optimizations and open pull requests in parallel threads. A second example retires a deprecated v1 endpoint across API, web and mobile repositories, one thread each, with Claude reporting which pull requests merge first. When two threads touch the same code, the overlap surfaces as an ordinary git merge conflict. Interactive: how a Claude Code project routes workClick a task. Watch the coordinator answer in place, save memory, or open a cloud thread on its own branch. Modeled on Anthropic’s Claude Code projects documentation. Thread timings are illustrative. © Marktechpost What every thread inherits Standing context is set once and reaches each new thread: the project’s repositories and uploaded files, its project instructions of up to 16,000 characters, and project memory that Claude writes and reads through a MEMORY.md index. Memory in practice: the release moved to Friday, or who to check with before touching billing. Each thread also clones every project repository and loads CLAUDE.md, skills and plugins from all of them. Permission rules, hooks and env behave differently. They apply only from the directory the thread starts in, so a single repository project honors them and a multi repository project does not. MCP tools arrive through the connectors on your claude.ai account. The project conversation itself has no connectors, so connector work must go to a thread. The Overview pane groups threads by state: Ready for review, Waiting on you, Working, Landing, Idle and Resolved. A Library tab collects uploaded files and files the threads produced. What it costs A project uses plan limits faster than a single session, because every running thread is a full session. Anthropic exposes a per project Usage tab plus separate model and effort settings for the coordinator and for threads. A new project runs Opus everywhere, high effort for threads and low effort for the conversation. Idle threads also wake and spend again when CI fails or a review comment lands. The enforced ceiling is 200 new threads per day across your projects, and a thread that hits a usage limit waits and resumes on its own. Key Takeaways One project is one conversation, and Claude starts a thread per piece of work. Every thread is a full cloud session with its own branch and repository copy. Shared project memory and instructions reach every new thread automatically. Parallel threads burn plan limits faster, with a cap of 200 new threads per day. Beta is limited to select Pro and Max users on web and desktop, not the CLI. Check out the Anthropic announcement, Claude Code projects documentation and @ClaudeDevs launch post. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Anthropic Launches Claude Code Projects in Beta: Parallel Cloud Sessions That Keep Running After You Close Your Laptop appeared first on MarkTechPost.

Anthropic Launches Claude Code Projects in Beta: Parallel Cloud Sessions That Keep Running After You Close Your Laptop Leer entrada »

We use cookies to improve your experience and performance on our website. You can learn more at Política de privacidad and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
es_ES