

Rethinking RL for LLM Reasoning: It’s Sparse Policy Selection, Not Capability Learning
arXiv:2605.06241v1 Announce Type: new Abstract: Reinforcement learning has become the standard for improving reasoning in...

Rethinking organizational design in the age of agentic AI
Amid rapidly growing adoption of enterprise-level AI agents, there’s a disconnect emerging between ambition and...
Rethinking Memory Mechanisms of Foundation Agents in the Second Half: A Survey
arXiv:2602.06052v3 Announce Type: replace Abstract: The research of artificial intelligence is undergoing a paradigm shift...
Rethinking AI: DeepSeek’s playbook shakes up the high-spend, high-compute paradigm
DeepSeek’s advancements were inevitable, but the company brought them forward a few years earlier than...
Retail Resurrection: David’s Bridal bets its future on AI after double bankruptcy
How AI-driven personalization, knowledge graphs and a two-sided marketplace are creating a new business model...
Restoring Exploration after Post-Training: Latent Exploration Decoding for Large Reasoning Models
arXiv:2602.01698v1 Announce Type: new Abstract: Large Reasoning Models (LRMs) have recently achieved strong mathematical and...
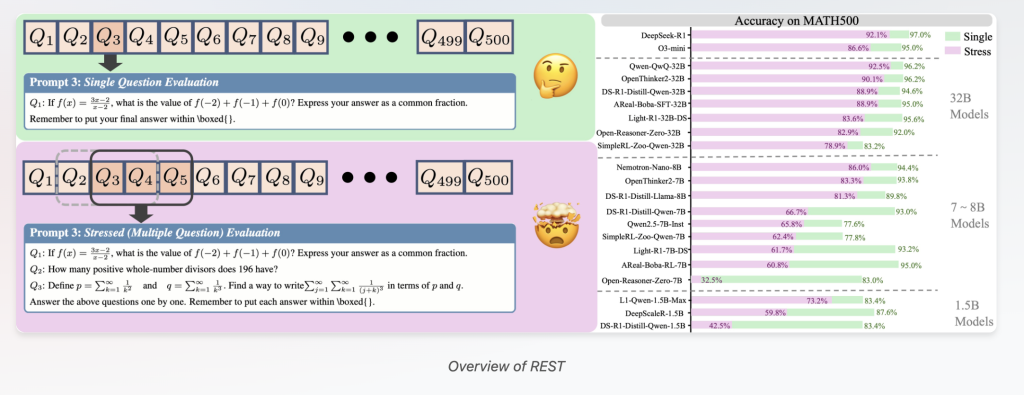
REST: A Stress-Testing Framework for Evaluating Multi-Problem Reasoning in Large Reasoning Models
Large Reasoning Models (LRMs) have rapidly advanced, exhibiting impressive performance in complex problem-solving tasks across...
Response-Level Rewards Are All You Need for Online Reinforcement Learning in LLMs: A Mathematical Perspective
arXiv:2506.02553v1 Announce Type: cross Abstract: We study a common challenge in reinforcement learning for large...
Resolving Conflicts in Lifelong Learning via Aligning Updates in Subspaces
arXiv:2512.08960v1 Announce Type: cross Abstract: Low-Rank Adaptation (LoRA) enables efficient Continual Learning but often suffers...
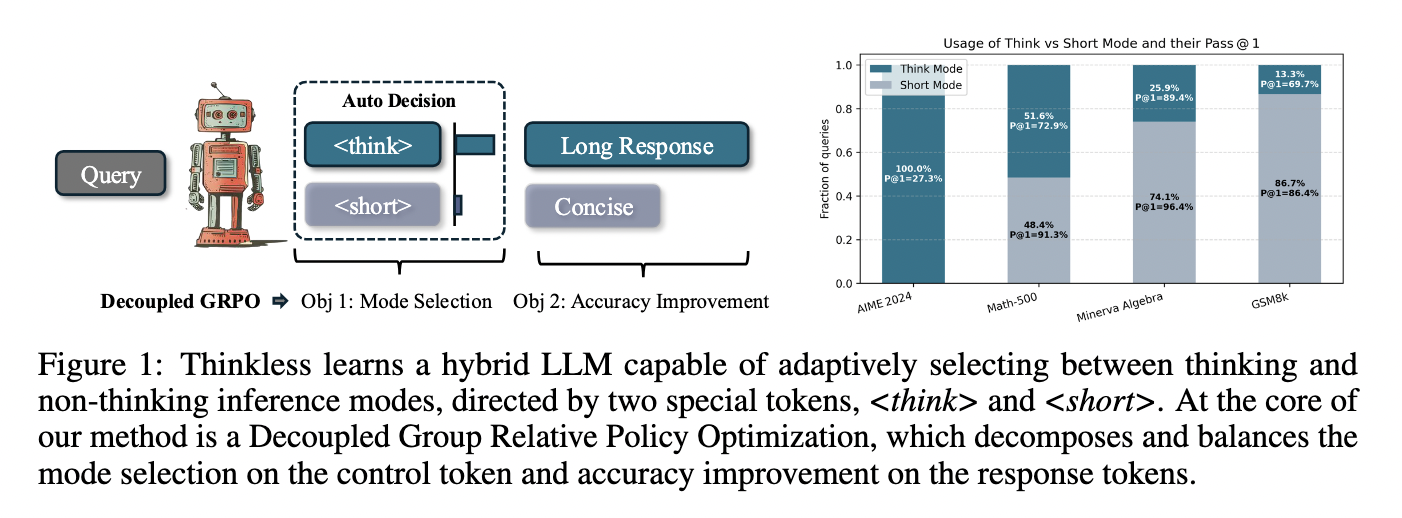
Researchers from the National University of Singapore Introduce ‘Thinkless,’ an Adaptive Framework that Reduces Unnecessary Reasoning by up to 90% Using DeGRPO
The effectiveness of language models relies on their ability to simulate human-like step-by-step deduction. However...
Researchers from Princeton, Ant Group and Stanford Introduce AQuA: A Two-Part Agentic Framework for Autonomous Factor Discovery and Model Development in Quantitative Finance
Quantitative research agents that write their own experiments can corrupt the evidence they later learn...
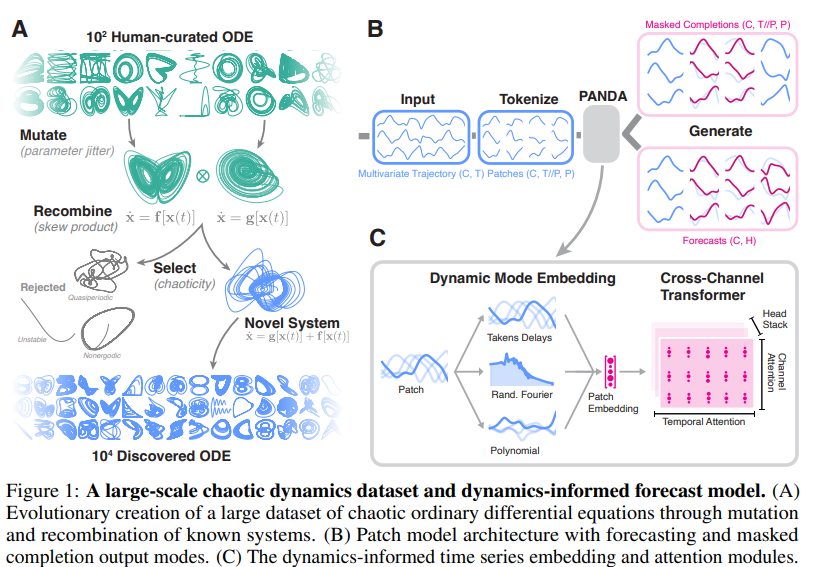
Researchers at UT Austin Introduce Panda: A Foundation Model for Nonlinear Dynamics Pretrained on 20,000 Chaotic ODE Discovered via Evolutionary Search
Chaotic systems, such as fluid dynamics or brain activity, are highly sensitive to initial conditions...


