

STEPER: Step-wise Knowledge Distillation for Enhancing Reasoning Ability in Multi-Step Retrieval-Augmented Language Models
arXiv:2510.07923v1 Announce Type: new Abstract: Answering complex real-world questions requires step-by-step retrieval and integration of...
Step-level Verifier-guided Hybrid Test-Time Scaling for Large Language Models
arXiv:2507.15512v3 Announce Type: replace Abstract: Test-Time Scaling (TTS) is a promising approach to progressively elicit...
Step by Step Guide to Build an End-to-End Model Optimization Pipeline with NVIDIA Model Optimizer Using FastNAS Pruning and Fine-Tuning
In this tutorial, we build a complete end-to-end pipeline using NVIDIA Model Optimizer to train...
Steering Language Models with Weight Arithmetic
arXiv:2511.05408v1 Announce Type: new Abstract: Providing high-quality feedback to Large Language Models (LLMs) on a...
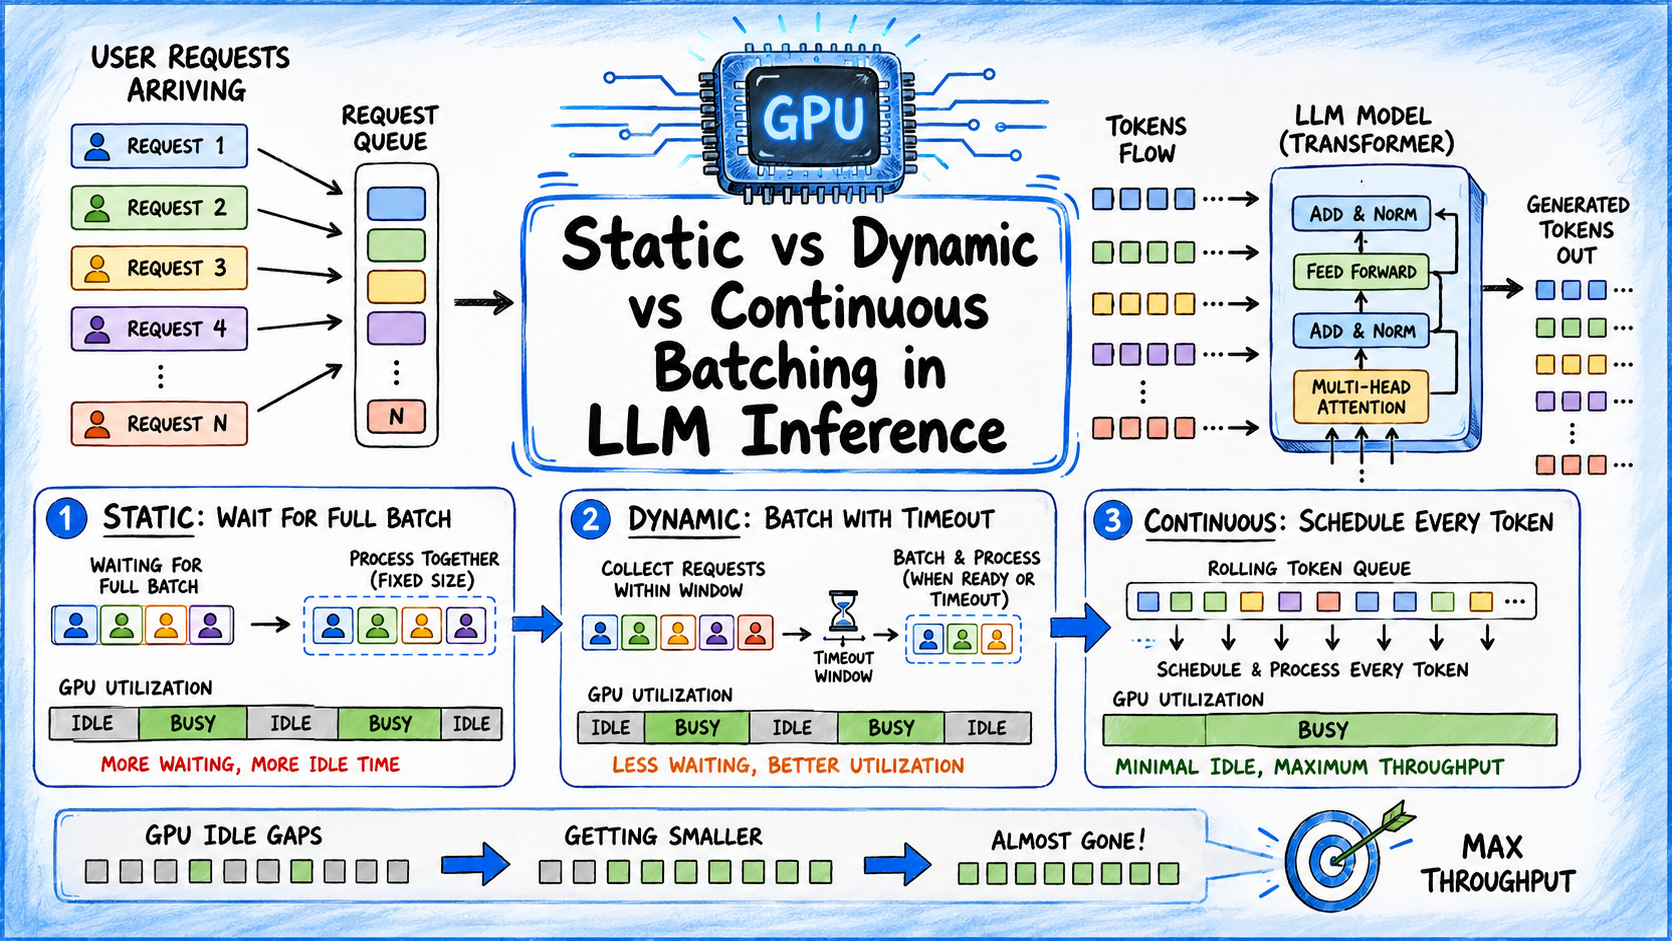
Static vs. Dynamic vs. Continuous Batching in LLM Inference
In this article, you will learn how static, dynamic, and continuous batching work in LLM...
Static vs. Dynamic vs. Continuous Batching in LLM Inference
In this article, you will learn how static, dynamic, and continuous batching work in LLM...

Stateful vs. Stateless Agent Design: Tradeoffs for Scalable Agentic Systems
In this article, you will learn how an agent’s approach to managing state — stateless...
Start Making Sense(s): A Developmental Probe of Attention Specialization Using Lexical Ambiguity
arXiv:2511.21974v1 Announce Type: new Abstract: Despite an in-principle understanding of self-attention matrix operations in Transformer...
STAR-Bench: Probing Deep Spatio-Temporal Reasoning as Audio 4D Intelligence
arXiv:2510.24693v2 Announce Type: replace-cross Abstract: Despite rapid progress in Multi-modal Large Language Models and Large...
Stanford Researchers Release Paper2Agent: Turning Research Papers Into AI Agents That Reproduce Results and Run on New Data
Computational papers ship code that readers must clone, install, configure and debug. That cost keeps...
Stanford Researchers Introduce TRACE: A Capability-Targeted Agentic Training System That Turns Recurrent Agent Failures Into Synthetic RL Environment
Agentic LLMs often fail the same way, again and again. A Stanford research team traced...
Stand Up for Research, Innovation, and Education
Right now, MIT alumni and friends are voicing their support for: America’s scientific and technological...


