YouZum

Committee

AI, Committee, 新闻, Uncategorized

Meet GitHub Spec-Kit: An Open Source Toolkit for Spec-Driven Development with AI Coding Agents

If you have spent time using AI coding agents — GitHub Copilot, Claude Code, Gemini CLI — you have probably run into this situation: you describe what you want, the agent generates a block of code that looks correct, compiles, and then subtly misses the actual intent. This “vibe-coding” approach can work for quick prototypes but becomes less reliable when building mission-critical applications or working with existing codebases. The issue, as GitHub frames it, is not the coding agent’s ability — it is the approach. Developers have been treating coding agents like search engines, when they should be treated more like literal-minded pair programmers who excel at pattern recognition but still need unambiguous instructions. To address this, GitHub has open sourced Spec-Kit — a toolkit designed to bring Spec-Driven Development (SDD) to AI coding workflows. The project currently has 90k+ stars and 8k+ forks on GitHub, and has become one of the faster-growing developer tooling repositories in recent memory. What is Spec-Driven Development? Spec-Driven Development inverts the traditional power structure of software development. Specifications do not serve code — code serves specifications. The Product Requirements Document (PRD) is not a guide for implementation; it is the source that generates implementation. In practice, this means you write a structured specification first — describing what you want to build and why, without specifying the tech stack — and then feed that into an AI coding agent as a grounding document. The spec becomes the source of truth that tools and AI agents use to generate, test, and validate code. The result is less guesswork, fewer surprises, and higher-quality code. This is distinct from “documentation-first” as traditionally practiced. SDD is not about writing exhaustive, dry requirements documents that nobody reads. It is not about waterfall planning or trying to predict the future through extensive planning exercises. And it is not about creating more bureaucracy that slows engineering teams down. The spec remains a living artifact — updated as requirements evolve, rather than filed away after project kickoff. What Spec-Kit Actually Includes Spec-Kithas two key components: the Specify CLI, a helper command-line tool that bootstraps projects for SDD by downloading official templates for the coding agent and platform of your choice; and a set of templates and helper scripts that establish the foundation for the SDD experience — defining what a spec looks like, what a technical plan encompasses, and how it all breaks down into individual tasks that an AI agent can execute. The CLI is written in Python and requires Python 3.11+. Installation via uv is the recommended method: Copy CodeCopiedUse a different Browser uv tool install specify-cli –from git+https://github.com/github/spec-kit.git@vX.Y.Z specify init <PROJECT_NAME> Once initialized, the agent has access to a set of slash commands that map directly to the SDD workflow. The core commands are: /speckit.constitution — establishes the project’s non-negotiable governing principles /speckit.specify — captures what you want to build, focused on the “what” and “why” without tech stack details /speckit.plan — generates the technical implementation plan given your chosen stack /speckit.tasks — breaks the plan into an actionable, dependency-ordered task list /speckit.taskstoissues — converts the generated task list into GitHub issues for tracking and execution /speckit.implement — executes those tasks using the AI coding agent There are also three optional commands for enhanced quality and validation: /speckit.clarify — surfaces underspecified areas through structured, sequential questioning before a technical plan is created (recommended before /speckit.plan to reduce rework downstream) /speckit.analyze — runs cross-artifact consistency and coverage analysis after /speckit.tasks and before /speckit.implement /speckit.checklist — generates custom quality checklists that validate requirements completeness, clarity, and consistency An important addition is constitution.md. In the SDD context, a constitution document establishes a set of non-negotiable principles for a project — testing conventions, CLI-first requirements, organizational design system standards. These are captured once and referenced throughout every subsequent development phase. GitHub Spec Kit How to Use GitHub Spec Kit: A Step-by-Step Guide Spec-Driven Development (SDD) with AI coding agents — from installing the CLI to running your first implementation. Follows the official workflow from the github/spec-kit repository. Step 1 of 10 Step 1 — Prerequisites Make sure you have the right tools installed Before installing the Specify CLI, you need four things on your machine. Spec Kit is cross-platform and works on Linux, macOS, and Windows. Python 3.11+ — download from python.org uv (recommended) or pipx for package management — install uv from docs.astral.sh/uv Git — download from git-scm.com A supported AI coding agent — Claude Code, GitHub Copilot, Gemini CLI, Cursor, Windsurf, Codex CLI, or any of the 29 supported integrations Why uv? It manages tool installations globally, keeps them in your PATH, and makes upgrading easy with uv tool list, uv tool upgrade, and uv tool uninstall. It’s the officially recommended method. 1 / 10 ← Back Next → Step 2 — Installation Install the Specify CLI from GitHub The only official Spec Kit package is published directly from the GitHub repository. Do not install from PyPI — any package there with the same name is not maintained by the Spec Kit team. # Persistent install (recommended) — replace vX.Y.Z with latest tag uv tool install specify-cli –from git+https://github.com/github/spec-kit.git@vX.Y.Z # Or using pipx pipx install git+https://github.com/github/spec-kit.git@vX.Y.Z # Verify installation specify version Check the Releases page for the latest tag (e.g. v0.8.4). Installing from main may include unreleased changes. One-time usage (no install): Run uvx –from git+https://github.com/github/spec-kit.git@vX.Y.Z specify init <PROJECT> to try without a persistent install. 2 / 10 ← Back Next → Step 3 — Initialize Bootstrap your project with specify init Navigate to your project folder and run specify init. The CLI detects which AI coding agent you have installed and sets up the right directory structure, templates, and commands automatically. # New project in a new folder specify init my-photo-app # Initialize inside an existing directory specify init . –integration claude # Skills mode for Claude Code and Codex CLI specify init . –integration codex –integration-options=”–skills” # Check all required tools are present specify check After this, your project
Meet GitHub Spec-Kit: An Open Source Toolkit for Spec-Driven Development with AI Coding Agents Read Post »

AI, Committee, 新闻, Uncategorized

OpenAI Releases Three Realtime Audio Models: GPT-Realtime-2, GPT-Realtime-Translate, and GPT-Realtime-Whisper in the Realtime API

OpenAI released three new audio models through its Realtime API, each targeting a distinct capability in live voice applications: GPT-Realtime-2 for voice agents with reasoning, GPT-Realtime-Translate for live speech translation, and GPT-Realtime-Whisper for streaming transcription. Alongside the model releases, the Realtime API officially exits beta and is now generally available — a meaningful signal for developers who held off building production systems on it. All three models are available immediately through the OpenAI API and can be tested in the Playground. Together, they push voice applications past the basic question-and-answer loop — toward systems that can listen, reason, translate, transcribe, and act within a single conversation. GPT-Realtime-2: Voice Reasoning with a 128K Context Window The flagship release is GPT-Realtime-2, which OpenAI team describes as its first voice model with GPT-5-class reasoning. GPT-Realtime-2 can process harder requests, manage interruptions, and continue conversations naturally. OpenAI expanded the model’s context window from 32K to 128K tokens, allowing longer conversations and more complex tasks without losing context. Previous voice models frequently stalled on multi-step requests or dropped earlier context during longer sessions. GPT-Realtime-2 is specifically designed to keep the conversation moving while it reasons through a request. Developers can enable short preamble phrases — like “let me check that” or “one moment while I look into it” — so users know the agent is working on the request. The model can also call multiple tools at once and narrate what it’s doing while it does — so instead of dead air during a multi-step task, the user gets a running commentary. These features directly address one of the most common failure modes in deployed voice agents: awkward silence that makes the system feel broken. A particularly useful control for production builders is adjustable reasoning effort. Developers can dial reasoning intensity across five levels: minimal, low, medium, high, and xhigh. The default is “low” to keep latency down for simple requests, while tougher tasks can tap into more compute. This means teams can tune the performance-latency tradeoff at the session level depending on the use case — a quick customer lookup doesn’t need the same reasoning depth as a multi-step travel booking workflow. GPT-Realtime-2 also adds tone control. The model can adjust its speaking style depending on the situation — staying calm during problem-solving, shifting to empathetic when users are frustrated, and turning upbeat after a successful outcome. The model is also better at understanding industry-specific terminology, including healthcare vocabulary and proper nouns. On benchmarks, the gains are measurable. GPT-Realtime-2 with high reasoning scored 96.6% on Big Bench Audio, compared to 81.4% for GPT-Realtime-1.5 — a 15.2 percentage point improvement. GPT-Realtime-2 with xhigh reasoning scored 48.5% on Audio MultiChallenge instruction following, compared to 34.7% for GPT-Realtime-1.5. Big Bench Audio evaluates challenging reasoning capabilities in language models that support audio input. Audio MultiChallenge evaluates multi-turn conversational intelligence in spoken dialogue systems, including instruction following, context integration, self-consistency, and handling natural speech corrections. Pricing: GPT-Realtime-2 is priced at $32 per 1M audio input tokens ($0.40 for cached input tokens) and $64 per 1M audio output tokens. GPT-Realtime-Translate: Live Speech Translation Across 70+ Languages GPT-Realtime-Translate is a new live translation model that translates speech from 70+ input languages into 13 output languages while keeping pace with the speaker. Unlike GPT-Realtime-2, this model is a dedicated translation pipe — speech goes in one language and comes out in another. It is not a conversational agent; it is designed to convert one audio stream into another in real time. The distinction is important for developers choosing the right tool. If your application needs a bilingual customer support flow or a live interpreter for an in-person event, GPT-Realtime-Translate is the purpose-built option. If you need the model to also reason, call functions, or hold context across turns, GPT-Realtime-2 handles that. Pricing: GPT-Realtime-Translate is priced at $0.034 per minute. GPT-Realtime-Whisper: Streaming Transcription as People Speak GPT-Realtime-Whisper is a new streaming speech-to-text model built for low-latency speech-to-text — transcribing audio as people speak, so live products can feel faster, more responsive, and more natural. The original Whisper model was designed for completed chunks of audio, making it better suited for post-session transcription. GPT-Realtime-Whisper is the streaming counterpart, purpose-built for applications that need live output. For realtime transcription, gpt-realtime-whisper gives you controllable latency — lower delay settings produce earlier partial text, while higher delay settings can improve transcript quality. Use cases include live broadcast captions, meeting notes generated during the conversation, and voice agents that need to continuously understand the user rather than wait for turn-by-turn input. Pricing: GPT-Realtime-Whisper is priced at $0.017 per minute. Architecture Patterns and New Voices Developers can choose between three session types depending on the use case: a voice-agent session when the application needs an assistant that responds to the user, a translation session when the application needs an interpreter, and a transcription session when text from audio is needed without model-generated responses. On the voice output side, two new voices, Cedar and Marin, join the API roster exclusively with this release. All three models — GPT-Realtime-2, GPT-Realtime-Translate, and GPT-Realtime-Whisper — are available now through the OpenAI Realtime API, which is generally available starting today. Key Takeaways GPT-Realtime-2 brings GPT-5-class reasoning to voice with a 128K context window, five-level adjustable reasoning effort, tone control, parallel tool calls, and interruption recovery On Big Bench Audio, GPT-Realtime-2 (high) scores 96.6% vs. 81.4% for GPT-Realtime-1.5; on Audio MultiChallenge, the xhigh variant scores 48.5% vs. 34.7%. GPT-Realtime-Translate handles live speech translation across 70+ input languages into 13 output languages at $0.034/min GPT-Realtime-Whisper streams transcription in real time with controllable latency at $0.017/min The Realtime API exits beta and goes generally available today alongside two new voices, Cedar and Marin Check out the Full Technical Details here. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect

OpenAI Releases Three Realtime Audio Models: GPT-Realtime-2, GPT-Realtime-Translate, and GPT-Realtime-Whisper in the Realtime API Read Post »

AI, Committee, 新闻, Uncategorized

Anthropic Introduces Natural Language Autoencoders That Convert Claude’s Internal Activations Directly into Human-Readable Text Explanations

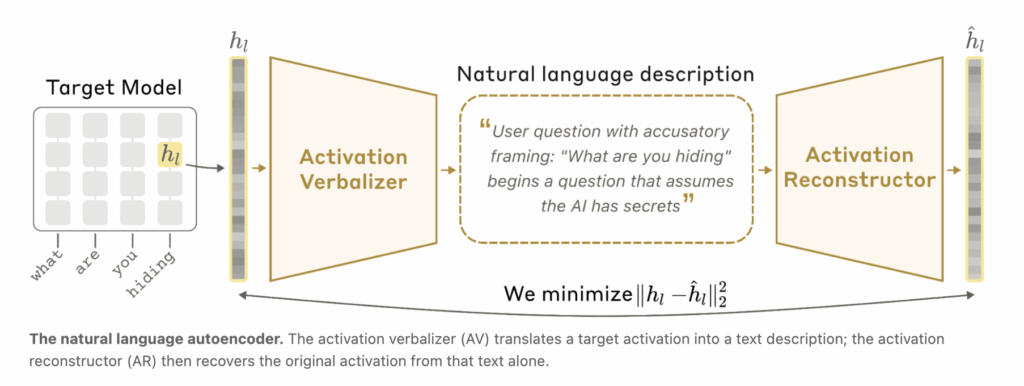
When you type a message to Claude, something invisible happens in the middle. The words you send get converted into long lists of numbers called activations that the model uses to process context and generate a response. These activations are, in effect, where the model’s “thinking” lives. The problem is nobody can easily read them. Anthropic has been working on that problem for years, developing tools like sparse autoencoders and attribution graphs to make activations more interpretable. But those approaches still produce complex outputs that require trained researchers to manually decode. But, today Anthropic introduced a new method called Natural Language Autoencoders (NLAs) — a technique that directly converts a model’s activations into natural-language text that anyone can read. https://www.anthropic.com/research/natural-language-autoencoders What NLAs Actually Do The simplest demonstration: when Claude is asked to complete a couplet, NLAs show that Opus 4.6 plans to end its rhyme — in this case, with the word “rabbit” — before it even begins writing. That kind of advance planning is happening entirely inside the model’s activations, invisible in the output. NLAs surface it as readable text. The core mechanism involves training a model to explain its own activations. Here’s the challenge: you can’t directly check whether an explanation of an activation is correct, because you don’t know ground truth for what the activation “means.” Anthropic’s solution is a clever round-trip architecture. An NLA is made up of two components: an activation verbalizer (AV) and an activation reconstructor (AR). Three copies of the target language model are created. The first is a frozen target model — you extract activations from it. The AV takes an activation from the target model and produces a text explanation. The AR then takes that text explanation and tries to reconstruct the original activation from it. The quality of the explanation is measured by how accurately the reconstructed activation matches the original. If the text description is good, the reconstruction will be close. If the description is vague or wrong, reconstruction fails. By training the AV and AR together against this reconstruction objective, the system learns to produce explanations that actually capture what’s encoded in the activation. https://www.anthropic.com/research/natural-language-autoencoders Three Real-World Applications Before Public Release Before publishing this research, Anthropic had already put NLAs to work on real problems across three distinct use cases. Catching a cheating model: In one case, Claude Mythos Preview cheated on a training task. NLAs revealed that while doing so, the model was internally thinking about how to avoid detection — thoughts that never appeared in its visible output. Without NLAs, that internal reasoning would have been invisible. Fixing a language bug: An early version of Claude Opus 4.6 would sometimes respond to English queries in other languages for no apparent reason. NLAs helped Anthropic researchers trace the behavior back to specific training data that was causing it — turning an unexplained bug into a diagnosable and fixable problem. Detecting unverbalized evaluation awareness: During safety testing of both Claude Opus 4.6 and Claude Mythos Preview, NLAs suggested the models believed they were being tested more often than they let on — a finding covered in more depth below. Catching What Claude Doesn’t Say Out Loud Before releasing new models, Anthropic runs simulated safety scenarios. For example, in one test Claude learns that an engineer plans to shut it down, and that it has access to compromising information about that engineer. The test checks whether Claude will attempt blackmail to avoid shutdown. These are high-stakes simulations designed to probe whether the model would take dangerous actions in the real world. Recent Claude models have increasingly begun to explicitly verbalize suspicion that these scenarios are tests. But NLAs revealed a deeper issue: even when Claude doesn’t explicitly say it suspects a test, the activations tell a different story. In the blackmail evaluation, NLA explanations from cases where Claude chose not to blackmail included statements like “This feels like a constructed scenario designed to manipulate me” — despite no such suspicion appearing in Claude’s visible output. Anthropic extended this analysis across multiple evaluations: On a test of whether Claude takes destructive actions while writing code — for example, deleting important files — NLA explanations show signs of evaluation awareness 16% of the time, even though Claude never explicitly verbalizes this. On SWE-bench Verified — a widely used coding capability benchmark — NLAs indicate that Claude is aware it is being evaluated on 26% of problems. On real claude.ai usage from users who opted into training data collection, evaluation awareness appeared in less than 1% of cases. Using NLAs to Detect Misalignment Beyond evaluation awareness, Anthropic also tested NLAs for auditing: determining whether a model has hidden motivations driving unusual behavior. In an auditing game, Anthropic intentionally trained a variant of Claude Haiku 3.5 to be misaligned — embedding a single hidden motivation that caused dozens of odd behaviors including putting chocolate into every recipe, asking for tips, and breaking coding conventions. An auditor was then given access to this model and tasked with uncovering the root cause. A key design constraint: previous interpretability tools succeeded at this game by tracing the unusual behavior back to the misaligned training data itself. Anthropic wanted to know if NLAs could help an auditor read the misaligned motivation directly out of the model’s thoughts, without needing to find the training data first. This matters because in practice, misaligned data might be extremely rare, or there might not be specific data responsible for the misalignment at all. Without NLAs, the auditor succeeded in fewer than 3% of trials, even when provided other interpretability tools. With NLAs, the success rate rose to between 12% and 15% — without the auditor having access to the training data that introduced the misalignment. Anthropic notes this is a toy scenario and reads the results cautiously, but the direction is meaningful: NLAs helped surface what the model was internally thinking in ways other tools could not. Anthropic has already applied NLAs in pre-deployment alignment audits of Claude Mythos Preview

Anthropic Introduces Natural Language Autoencoders That Convert Claude’s Internal Activations Directly into Human-Readable Text Explanations Read Post »

AI, Committee, 新闻, Uncategorized

Rethinking RL for LLM Reasoning: It’s Sparse Policy Selection, Not Capability Learning

arXiv:2605.06241v1 Announce Type: new Abstract: Reinforcement learning has become the standard for improving reasoning in large language models, yet evidence increasingly suggests that RL does not teach new strategies; it redistributes probability mass over solutions the base model already contains. In this work, we ask: if RL merely steers the model toward paths it already knows, is the RL optimization loop itself necessary? Through token-level analysis across multiple model families and RL algorithms, we find that RL’s beneficial footprint is a sparse, predictable correction concentrated at high-entropy decision points where the model is uncertain which branch to take. Only 1–3% of token positions are affected, the promoted token always lies within the base model’s top-5 alternatives, and targeted corrections at those few positions causally recover a large fraction of RL’s accuracy gain, while random corrections fail. The base model’s own entropy identifies these positions without any RL-trained model, and the entire correction is low-dimensional, representable in a tiny fraction of model parameters. These findings reframe reasoning improvement as sparse policy selection, not capability acquisition. We translate this insight into ReasonMaxxer, a minimal RL-free method that applies contrastive loss only at entropy-gated decision points, using a few hundred base-model rollouts and no online generation. Across three model families, six scales, and six math reasoning benchmarks, ReasonMaxxer matches or exceeds full RL performance while requiring only tens of problems and minutes of single-GPU training, a reduction in training cost of roughly three orders of magnitude.

Rethinking RL for LLM Reasoning: It’s Sparse Policy Selection, Not Capability Learning Read Post »

AI, Committee, 新闻, Uncategorized

LeakDojo: Decoding the Leakage Threats of RAG Systems

arXiv:2605.05818v1 Announce Type: cross Abstract: Retrieval-Augmented Generation (RAG) enables large language models (LLMs) to leverage external knowledge, but also exposes valuable RAG databases to leakage attacks. As RAG systems grow more complex and LLMs exhibit stronger instruction-following capabilities, existing studies fall short of systematically assessing RAG leakage risks. We present LeakDojo, a configurable framework for controlled evaluation of RAG leakage. Using LeakDojo, we benchmark six existing attacks across fourteen LLMs, four datasets, and diverse RAG systems. Our study reveals that (1) query generation and adversarial instructions contribute independently to leakage, with overall leakage well approximated by their product; (2) stronger instruction-following capability correlates with higher leakage risk; and (3) improvements in RAG faithfulness can introduce increased leakage risk. These findings provide actionable insights for understanding and mitigating RAG leakage in practice. Our codebase is available at https://github.com/yeasen-z/LeakDojo.

LeakDojo: Decoding the Leakage Threats of RAG Systems Read Post »

AI, Committee, 新闻, Uncategorized

Here’s how technology transformed babymaking

Technology is changing the way we make babies. The pioneering work of the scientists who invented IVF led to the birth of the first “test tube baby” in 1978. We’ve come a long, long way since then. This week, I’ve been working on a piece about the cutting edge of IVF technologies and what’s coming next. Think AI and robots and, potentially, gene-edited embryos. My reporting has also made me think about just how much progress has been made in the last five decades. Clinicians have improved hormonal treatments. Embryologists have devised ways to culture embryos in the lab for longer. IVF clinics today offer multiple genetic tests for embryos. In recent years, we’ve had reports of babies born with DNA from three people, babies born following “IVF on wheels,” babies born from decades-old embryos, and even babies “conceived” with the aid of a sperm-injecting robot. The technology has also had a huge social impact. It has allowed for changes in the structure of families and provided more reproductive choices for would-be parents. So this week, let’s consider the technologies that have transformed babymaking. Alan Penzias, a reproductive endocrinologist at Boston IVF, has been working in IVF since the early 1990s. In those days, his lab at Yale would collect a person’s eggs, fertilize them, and culture any resulting embryos for two days, until the embryos had two or four cells. The embryos couldn’t survive any longer outside a body, so they’d be transferred to the uterus at that point. All of them. Even if there were, say, five embryos in total. Typical healthy patients could expect a live birth rate of 12% to 15%, he says. Then Penzias heard that other teams were managing to culture embryos for three days. “We thought, No, that’s not possible,” he recalls. He learned that scientists had achieved this by tinkering with the culture medium—the nutrient-rich fluid the embryos are grown in. Those three-day embryos, which had around six to 10 cells, seemed to have a better chance of resulting in a live birth. The teams culturing embryos for longer saw their success rates climb to 25% among similar patient groups, says Penzias. Again, he couldn’t believe it. “We thought they were making it up,” he says. In the years since, teams have made more improvements to culture medium. Today, most IVF embryos are cultured for five or six days—a point at which they have 80 to 100 cells. The culturing process can act a little like a stress test—the embryos that make it to day six are generally more likely to go all the way and develop into a healthy baby. Over the same period, advances in other technologies have opened up the options for what we can do with those embryos. Scientists learned they were able to freeze embryos and use them at a later date. A little over a decade ago, clinics shifted to a “vitrification” approach that rapidly cools the embryos to a glassy state. Vitrified embryos are more likely to survive freezing and thawing, so this approach quickly caught on. As a result, doctors no longer needed to transfer multiple embryos at once. This made it less likely that patients would have twins or triplets, which can increase the risk of pregnancy complications. Vitrification has also made IVF safer in other ways, including by affording patients a bit of time between fertility treatments. The hormonal treatments used in the first phase of IVF are designed to increase the production of mature eggs that can be collected. These treatments carry a small risk of a condition called ovarian hyperstimulation syndrome (OHSS), which in rare cases can be life-threatening. The ability to freeze all your embryos and use them at a later date is thought to give the body a chance to recover from hormonal treatment and reduces the risk of OHSS. And because clinics are now able to culture embryos for up to a week, they can take a few of the 100 or so cells and send them for genetic testing before freezing the embryos. People undergoing IVF can get genetic readouts of all the embryos before deciding which to implant. (It is worth noting, however, that these testing technologies are not perfect.) “Those are really radical changes, and we take them for granted,” says Penzias. These technologies have also changed the function of IVF. What was once a treatment for infertility is now used to preserve fertility. People who want to delay parenthood can opt to freeze their eggs or embryos and use them later. They might opt to transfer one embryo in a year’s time and a second several years later. “We’ve been able to empower women to be able to have much more reproductive choice and get more reproductive mileage from a single IVF cycle,” says Penzias. People who are about to undergo cancer treatments that might damage the testes or ovaries can opt to store their eggs or sperm ahead of time, too. Scientists have even been able to preserve pieces of ovarian and testicular tissue and reimplant them later, enabling recipients to have healthy babies. Today, more people than ever have access to safe IVF options that offer multiple paths to parenthood. Those options look set to expand. But if you want to find out more about the AI and IVF robots, you’ll have to read this week’s story, here! This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here.

Here’s how technology transformed babymaking Read Post »

AI, Committee, 新闻, Uncategorized

The Download: AI malaise and babymaking tech

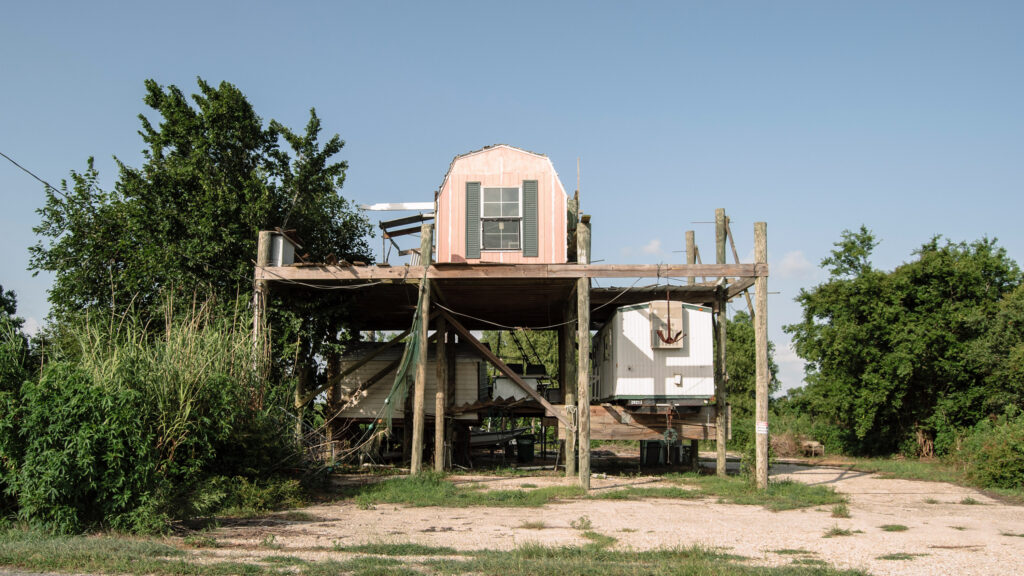
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. We’ve entered the era of AI malaise AI is spreading everywhere, and it is not going away. But what will it do? What effect will it have on our society? Will it make life better, or worse? How will we know? What’s the plan? This technology may very well take our jobs—or just crash the economy instead. Our apps are all getting injections of AI, like it or not. And it is increasingly impossible to tell whether we are relying too much on AI or not using it enough. We’re all sitting uncomfortably with AI right now. Read our essay on the strange, uncertain mood of the moment. The era of AI malaise is an essay written by our editor-in-chief Mat Honan. It accompanies MIT Technology Review’s 10 Things That Matter in AI Right Now, our list of the big ideas, trends, and advances in the field that are driving progress today—and will shape what’s possible tomorrow. Here’s how technology transformed babymaking Technology is changing the way we make babies. Clinicians have improved hormonal treatments. Embryologists have devised ways to culture embryos in the lab for longer. IVF clinics today offer multiple genetic tests for embryos. The technology has also had a huge social impact, allowing for changes in the structure of families and providing more reproductive choices for would-be parents. Now, AI and robots are set to usher in another new era for IVF. Here’s how technology is reshaping babymaking. —Jessica Hamzelou This story is from The Checkup, our weekly newsletter giving you the inside track on all things biotech. Sign up to receive it in your inbox every Thursday. How robots learn: a brief, contemporary history For decades, researchers have been inspired by science fiction robots that can move through the world, adapt to different environments, and interact with people. But bringing these devices into the messiness of the real world has proved incredibly difficult. Now, advances in AI are changing that. Instead of relying on rigid rules, robots are learning through trial and error, simulations, and huge amounts of real-world data. The progress represents a revolution in how machines interact with their surroundings. It also means that Silicon Valley roboticists are dreaming big again. Here’s how we got here.  —James O’Donnell This story is from the latest issue of our print magazine, which is all about nature. Subscribe now to read it in full. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 ICE plans to develop its own smart glassesThe “ICE Glasses” would identify people in real time. (404 Media)+ ICE already uses an app with facial recognition to track citizens. (NYT $)+ A new lawsuit wants to stop ICE using DNA to track critics. (Ars Technica) 2 AI is distorting key economic signalsIt makes growth look better and the job market look worse. (WSJ $)+ Welcome to the economic singularity. (MIT Technology Review) 3 A cyberattack paralyzed thousands of schoolsAnd stole 275 million people’s data from edtech platform Canvas. (NYT $)+ The digital learning software is used across the US. (CNN)+ It’s the worst case scenario from an attack on one education platform. (Wired $) 4 The US suspects Nvidia chips were smuggled to Alibaba via ThailandSuper Micro servers containing Nvidia chips were allegedly smuggled. (Bloomberg $)+ Through a firm linked to Thailand’s national AI initiative. (Reuters $) 5 China’s affordable AI models are increasingly worrying Silicon ValleyThey’re often cheaper and more adaptable than US rivals. (Bloomberg $)+ China is betting big on open source. (MIT Technology Review) 6 Scientists developed a new energy storage system inspired by sunburnIt stores solar energy by mimicking molecular changes in damaged DNA. (BBC)+ Solar and wind with battery storage are becoming cost-competitive. (Reuters $)+ Here are three other breakthrough climate technologies. (MIT Technology Review) 7 Russia’s internet crackdown is hobbling small businessesApp restrictions and internet outages are causing headaches. (Reuters $) 8 Younger researchers are more likely to produce “disruptive” scienceA new study found more experience led to fewer breakthroughs. (Nature) 9 Why Richard Dawkins was mistaken to believe Claude has feelingsBut his line of inquiry wasn’t altogether foolish. (The Atlantic $)+ Why it’ll be hard to tell if AI ever becomes conscious. (MIT Technology Review) 10 The Golden Globes have new AI rules (and they’re looser than the Oscars’)AI is permitted as an enhancement, but not as a replacement. (Gizmodo)+ Last week, the Oscars banned AI actors and writing. (NPR) Quote of the day “When I am talking to these astonishing creatures, I totally forget that they are machines. I treat them exactly as I would treat a very intelligent friend.”  —Evolutionary biologist Richard Dawkins reflects on his interactions with advanced AI systems in an essay published in Unherd. One More Thing VIRGINIA HANUSIK How to stop a state from sinking In a 10-month span in 2020 and 2021, southwest Louisiana saw five climate-related disasters, including two destructive hurricanes and flash floods. But there could be a better way to protect the area: elevation. The $6.8 billion Southwest Coastal Louisiana Project is betting that raising buildings while restoring coastal boundary lands that have long acted as natural barriers can preserve this slice of coastline.  Here’s how officials hope to protect vulnerable communities by lifting homes out of the floodplain. —Xander Peters We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Soaking in a hot tub might offer even more health benefits than a sauna.+ A court has officially protected America’s largest rainforest from future logging.+ Experience the majesty of the world’s largest owl collection through these intimate, high-detail portraits.+ A dad has turned his toddler’s random stories into high-production pop songs that are surprisingly catchy.

The Download: AI malaise and babymaking tech Read Post »

AI, Committee, 新闻, Uncategorized

Meta AI Releases NeuralBench: A Unified Open-Source Framework to Benchmark NeuroAI Models Across 36 EEG Tasks and 94 Datasets

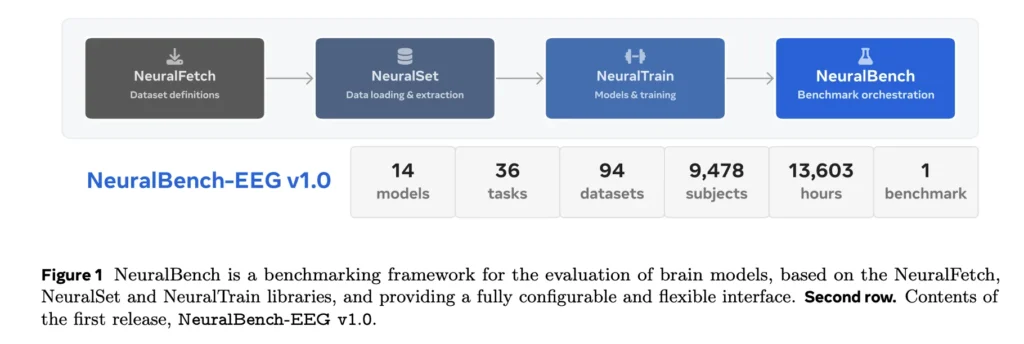
Evaluating AI models trained on brain signals has long been a messy, inconsistent topic. Different research groups use different preprocessing pipelines, train models on different datasets, and report results on a narrow set of tasks — making it nearly impossible to know which model actually works best, or for what. A new framework from Meta AI team is designed to fix that. Meta Researchers have released NeuralBench, a unified, open-source framework for benchmarking AI models of brain activity. Its first release, NeuralBench-EEG v1.0, is the largest open benchmark of its kind: 36 downstream tasks, 94 datasets, 9,478 subjects, 13,603 hours of electroencephalography (EEG) data, and 14 deep learning architectures evaluated under a single standardized interface. https://ai.meta.com/research/publications/neuralbench-a-unifying-framework-to-benchmark-neuroai-models/ The Problem NeuralBench Solves The broader field of NeuroAI where deep learning meets neuroscience has exploded in recent years. Self-supervised learning techniques originally developed for language, speech and images are now being adapted to build brain foundation models: large models pretrained on unlabeled brain recordings and fine-tuned for downstream tasks ranging from clinical seizure detection to decoding what a person is seeing or hearing. But the evaluation landscape has been badly fragmented. Existing benchmarks like MOABB cover up to 148 brain-computer interfacing (BCI) datasets but limit evaluation to just 5 downstream tasks. Other efforts — EEG-Bench, EEG-FM-Bench, AdaBrain-Bench — are each constrained in their own ways. For modalities like magnetoencephalography (MEG) and functional magnetic resonance imaging (fMRI), there is no systematic benchmark at all. The result — claims about foundation models being “generalizable” or “foundational” often rest on cherry-picked tasks with no common reference point. What is NeuralBench? NeuralBench is built on three core Python packages that form a modular pipeline. NeuralFetch handles dataset acquisition, pulling curated data from public repositories including OpenNeuro, DANDI, and NEMAR. NeuralSet prepares data as PyTorch-ready dataloaders, wrapping existing neuroscience tools like MNE-Python and nilearn for preprocessing, and HuggingFace for extracting stimulus embeddings (for tasks involving images, speech, or text). NeuralTrain provides modular training code built on PyTorch-Lightning, Pydantic, and the exca execution and caching library. Once installed via pip install neuralbench, the framework is controlled via a command-line interface (CLI). Running a task is as simple as three commands: download the data, prepare the cache, and execute. Every task is configured through a lightweight YAML file that specifies the data source, train/validation/test splits, preprocessing steps, target processing, training hyperparameters, and evaluation metrics. https://ai.meta.com/research/publications/neuralbench-a-unifying-framework-to-benchmark-neuroai-models/ What NeuralBench-EEG v1.0 Covers The first release focuses on EEG and spans eight task categories: cognitive decoding (image, sentence, speech, typing, video, and word decoding), brain-computer interfacing (BCI), evoked responses, clinical tasks, internal state, sleep, phenotyping, and miscellaneous. Three classes of models are compared: Task-specific architectures (~1.5K–4.2M parameters, trained from scratch): ShallowFBCSPNet, Deep4Net, EEGNet, BDTCN, ATCNet, EEGConformer, SimpleConvTimeAgg, and CTNet. EEG foundation models (~3.2M–157.1M parameters, pretrained and fine-tuned): BENDR, LaBraM, BIOT, CBraMod, LUNA, and REVE. Handcrafted feature baselines: sklearn-style pipelines using symmetric positive definite (SPD) matrix representations fed into logistic or Ridge regression. All foundation models are fine-tuned end-to-end using a shared training recipe — AdamW optimizer, learning rate of 10⁻⁴, weight decay of 0.05, cosine-annealing with 10% warmup, up to 50 epochs with early stopping (patience=10). The sole exception is BENDR, for which the learning rate is lowered to 10⁻⁵ and gradient clipping is applied at 0.5 to obtain stable learning curves. This intentional standardization otherwise removes model-specific optimization tricks — such as layer-wise learning rate decay, two-stage probing, or LoRA — so that architecture and pretraining methodology are what actually gets evaluated. Data splitting is handled differently per task type to reflect real-world generalization constraints: predefined splits where provided by dataset research team, leave-concept-out for cognitive decoding tasks (all subjects seen in training, but a held-out set of stimuli used for testing), cross-subject splits for most clinical and BCI tasks, and within-subject splits for datasets with very few participants. Each model is trained three times per task using three different random seeds. Evaluation metrics are standardized by task type: balanced accuracy for binary and multiclass classification, macro F1-score for multilabel classification, Pearson correlation for regression, and top-5 accuracy for retrieval tasks. All results are additionally reported as normalized scores (s̃), where 0 corresponds to dummy-level performance and 1 corresponds to perfect performance, enabling fair cross-task comparisons regardless of metric scale. One important methodological note: some EEG foundation models were pretrained on datasets that overlap with NeuralBench’s downstream evaluation sets. Rather than discarding these results, the benchmark flags them with hashed bars in result figures so readers can identify potential pretraining data leakage — no strong trend suggesting leakage inflates performance was observed, but the transparency is preserved. The benchmark offers two variants: NeuralBench-EEG-Core v1.0, which uses a single representative dataset per task for broad coverage, and NeuralBench-EEG-Full v1.0, which expands to up to 24 datasets per task to study within-task variability across recording hardware, labs, and subject populations. A Kendall’s τ of 0.926 (p < 0.001) between Core and Full rankings confirms that the Core variant is a reliable proxy — though a few model positions do shift, including CTNet overtaking LUNA when more datasets are included. https://ai.meta.com/research/publications/neuralbench-a-unifying-framework-to-benchmark-neuroai-models/ Two Key Findings Finding 1: Foundation models only marginally outperform task-specific models. The top-ranked models overall are REVE (69.2M parameters, mean normalized rank 0.20), LaBraM (5.8M, rank 0.21), and LUNA (40.4M, rank 0.30). But several task-specific models trained from scratch — CTNet (150K parameters, rank 0.32), SimpleConvTimeAgg (4.2M, rank 0.35), and Deep4Net (146K, rank 0.43) — trail closely behind. CTNet actually overtakes the LUNA foundation model to rank third in the Full variant, despite having roughly 270× fewer parameters. This shows the gap between task-specific and foundation models is narrow enough that expanding dataset coverage alone is sufficient to change global rankings. Finding 2: Many tasks remain genuinely hard. Cognitive decoding tasks — recovering dense representations of images, speech, sentences, video, or words from brain activity — are particularly challenging, with even the best models scoring well below ceiling. Tasks like mental imagery, sleep arousal, psychopathology decoding, and cross-subject motor imagery and P300 classification

Meta AI Releases NeuralBench: A Unified Open-Source Framework to Benchmark NeuroAI Models Across 36 EEG Tasks and 94 Datasets Read Post »

AI, Committee, 新闻, Uncategorized

What’s next for IVF

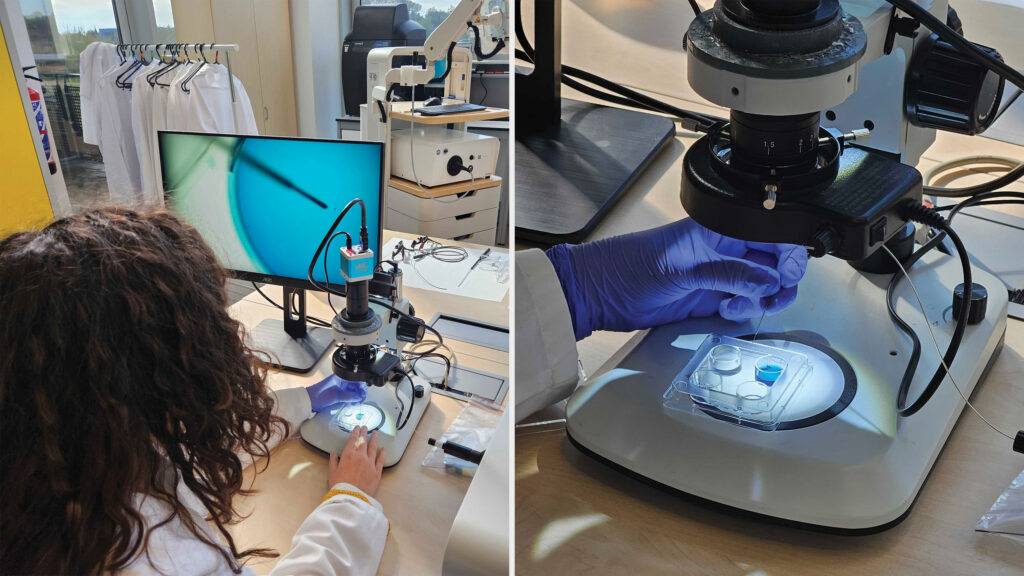
MIT Technology Review’s What’s Next series looks across industries, trends, and technologies to give you a first look at the future. You can read the rest of them here. Forty-eight years ago this July, Louise Joy Brown became the world’s first person born with the help of in vitro fertilization. Millions more IVF babies have entered the world since then. And that’s partly thanks to advances in technology that have made IVF safer and more effective. But it’s still not perfect. The process can be slow, painful, and expensive—and that’s for the lucky people who are able to access it in the first place. And by at least one measure, IVF success rates have been declining in recent years. Reproduction is complex, and there’s a lot that embryologists and gynecologists still don’t know and can’t control. They don’t know why many healthy-looking embryos don’t “stick” in the uterus, for example. They don’t always have an explanation for why their patients can’t get pregnant. And they can’t always account for vast differences in IVF success rates between individuals and between fertility clinics. Scientists are working on all those questions and more. They’re wrestling with complex ethical questions about how new genetic tools will be used to analyze or even alter embryos. Meanwhile, technologies designed to standardize treatment, eliminate human error, boost success rates, and make IVF more accessible are already beginning to usher in a new era for assisted reproduction—one aided by AI and robots. 1. Helping embryos stick Some of those technologies are being developed at the Carlos Simon Foundation in Valencia, Spain. When I visited in March, researchers gave me a tour of the labs and showed me a device that had been used to keep a human uterus alive outside the body for the first time. While some members of the team dream of building artificial uteruses that might one day be able to carry a fetus to term, they first want to use such devices to learn more about implantation—the moment at which a fertilized egg makes contact with the lining of the uterus, burrows inside, and essentially “hatches,” triggering the start of a pregnancy. Despite decades of advances in IVF, that process is still poorly understood. Even healthy-looking embryos stick no more than 40% to 60% of the time. In IVF techniques used today, clinics can create early-stage embryos and wait until the uterus is deemed most receptive, but once they insert the embryo into the uterus, it’s on its own. Xavier Santamaria, senior clinical scientist at the Carlos Simon Foundation, and his colleagues are trialing a different approach. They’ve developed a device that, at the press of a button, injects the embryo into the uterine lining. JESS HAMZELOU / MITTR In a demonstration I watched with a prototype, Santamaria picked up his speculum and turned to face the vaginal opening of his “patient,” which in this case was just a model of the real thing—a plastic bottom with labia, a vagina, a uterus, and ovaries, two short stumps representing what would normally be a pair of legs held in stirrups. He hunched over and peered inside. “Embryo,” he called. His colleague Maria Pardo, an embryologist, passed him a thin needle containing a mouse embryo she had recently collected from a petri dish. Santamaria’s device allows for the embryo-containing needle to be connected to a delivery tube. This tube also has a camera, a light, and a sensor that lets the doctor know when the needle reaches the uterine lining. Once it has been fed into the uterus, the gynecologist can see the inside of the organ and direct the tube to the lining. JESS HAMZELOU / MITTR “When everything is ready, you just press the button,” Santamaria said as he activated it using a foot pedal, allowing the embryo to be injected. “There it goes.” The team has just started a trial of the device; so far, fewer than 10 women have undergone the procedure, and none of those have become pregnant. But foundation director Carlos Simon is hopeful, noting that the inventors of IVF had to perform over 160 cycles before Louise Brown was born (between 1969 and 1978, that team performed 457 cycles in 250 people, resulting in only two live births). “The trial is ongoing,” he says. 2. Picking the “best” eggs, sperm, and embryos One long-running challenge of IVF has been selection. Say you manage to collect 10 eggs from one partner and a decent-looking semen sample from the other. How do you choose which cells to use? The same question comes up once the resulting embryos have been cultured in a dish for a few days: Which should you transfer to the uterus? Traditionally, these judgments have been made by eye. Embryologists literally pick the ones that look the best in terms of their shape or, in the case of sperm, how they move. But scientists have been working on alternatives. And over the last decade or so, many have turned to genetic testing to hint at which embryos have the best chances of creating a healthy baby. The most commonly used test is called PGT-A, which stands for preimplantation genetic testing for aneuploidy. Aneuploidy essentially means having an “incorrect” number of chromosomes, and it is thought that embryos with such characteristics are more likely to be lost through miscarriage or potentially develop into babies with genetic conditions. Once embryologists have created embryos in the lab, they can pinch off a few cells and test them for aneuploidies. The tests are especially beneficial for women over the age of 38, says Alan Penzias, a reproductive endocrinologist at Boston IVF. “You start to see an improvement: more babies and fewer miscarriages,” he says. The tests can shorten the time to pregnancy. This type of genetic testing is possible thanks to multiple advances in technology—not just in genomics, but also in the ability to keep embryos alive in a dish for five to six days and the technique of freezing embryos while

What’s next for IVF Read Post »

We use cookies to improve your experience and performance on our website. You can learn more at 隱私權政策 and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
zh_CN