YouZum

Committee

AI, Committee, ニュース, Uncategorized

Waymo Introduces the Waymo World Model: A New Frontier Simulator Model for Autonomous Driving and Built on Top of Genie 3

Waymo is introducing the Waymo World Model, a frontier generative model that drives its next generation of autonomous driving simulation. The system is built on top of Genie 3, Google DeepMind’s general-purpose world model, and adapts it to produce photorealistic, controllable, multi-sensor driving scenes at scale. Waymo already reports nearly 200 million fully autonomous miles on public roads. Behind the scenes, the Driver trains and is evaluated on billions of additional miles in virtual worlds. The Waymo World Model is now the main engine generating those worlds, with the explicit goal of exposing the stack to rare, safety-critical ‘long-tail’ events that are almost impossible to see often enough in reality. From Genie 3 to a driving-specific world model Genie 3 is a general-purpose world model that turns text prompts into interactive environments you can navigate in real time at roughly 24 frames per second, typically at 720p resolution. It learns the dynamics of scenes directly from large video corpora and supports fluid control by user inputs. Waymo uses Genie 3 as the backbone and post-trains it for the driving domain. The Waymo World Model keeps Genie 3’s ability to generate coherent 3D worlds, but aligns the outputs with Waymo’s sensor suite and operating constraints. It generates high-fidelity camera images and lidar point clouds that evolve consistently over time, matching how the Waymo Driver actually perceives the environment. This is not just video rendering. The model produces multi-sensor, temporally consistent observations that downstream autonomous driving systems can consume under the same conditions as real-world logs. Emergent multimodal world knowledge Most AV simulators are trained only on on-road fleet data. That limits them to the weather, infrastructure, and traffic patterns a fleet actually encountered. Waymo instead leverages Genie 3’s pre-training on an extremely large and diverse set of videos to import broad ‘world knowledge’ into the simulator. Waymo then applies specialized post-training to transfer this knowledge from 2D video into 3D lidar outputs tailored to its hardware. Cameras provide rich appearance and lighting. Lidar contributes precise geometry and depth. The Waymo World Model jointly generates these modalities, so a simulated scene comes with both RGB streams and realistic 4D point clouds. Because of the diversity of the pre-training data, the model can synthesize conditions that Waymo’s fleet has not directly seen. The Waymo team shows examples such as light snow on the Golden Gate Bridge, tornadoes, flooded cul-de-sacs, tropical streets strangely covered in snow, and driving out of a roadway fire. It also handles unusual objects and edge cases like elephants, Texas longhorns, lions, pedestrians dressed as T-rexes, and car-sized tumbleweed. The important point is that these behaviors are emergent. The model is not explicitly programmed with rules for elephants or tornado fluid dynamics. Instead, it reuses generic spatiotemporal structure learned from videos and adapts it to driving scenes. Three axes of controllability A key design goal is strong simulation controllability. The Waymo World Model exposes three main control mechanisms: driving action control, scene layout control, and language control. Driving action control: The simulator responds to specific driving inputs, allowing ‘what if’ counterfactuals on top of recorded logs. Devs can ask whether the Waymo Driver could have driven more assertively instead of yielding in a past scene, and then simulate that alternative behavior. Because the model is fully generative, it maintains realism even when the simulated route diverges far from the original trajectory, where purely reconstructive methods like 3D Gaussian Splatting (3DGS) would suffer from missing viewpoints. Scene layout control: The model can be conditioned on modified road geometry, traffic signal states, and other road users. Waymo can insert or reposition vehicles and pedestrians or apply mutations to road layouts to synthesize targeted interaction scenarios. This supports systematic stress testing of yielding, merging, and negotiation behaviors beyond what appears in raw logs. Language control: Natural language prompts act as a flexible, high-level interface for editing time-of-day, weather, or even generating entirely synthetic scenes. The Waymo team demonstrates ‘World Mutation’ sequences where the same base city scene is rendered at dawn, morning, noon, afternoon, evening, and night, and then under cloudy, foggy, rainy, snowy, and sunny conditions. This tri-axis control is close to a structured API: numeric driving actions, structural layout edits, and semantic text prompts all steer the same underlying world model. Turning ordinary videos into multimodal simulations The Waymo World Model can convert regular mobile or dashcam recordings into multimodal simulations that show how the Waymo Driver would perceive the same scene. Waymo showcases examples from scenic drives in Norway, Arches National Park, and Death Valley. Given only the video, the model reconstructs a simulation with aligned camera images and lidar output. This creates scenarios with strong realism and factuality because the generated world is anchored to actual footage, while still being controllable via the three mechanisms above. Practically, this means a large corpus of consumer-style video can be reused as structured simulation input without requiring lidar recordings in those locations. Scalable inference and long rollouts Long-horizon maneuvers such as threading a narrow lane with oncoming traffic or navigating dense neighborhoods require many simulation steps. Naive generative models suffer from quality drift and high compute cost over long rollouts. Waymo team reports an efficient variant of the Waymo World Model that supports long sequences with a dramatic reduction in compute while maintaining realism. They show 4x-speed playback of extended scenes like freeway navigation around an in-lane stopper, busy neighborhood driving, climbing steep streets around motorcyclists, and handling SUV U-turns. For training and regression testing, this reduces the hardware budget per scenario and makes large test suites more tractable. Key Takeaways Genie 3–based world model: Waymo World Model adapts Google DeepMind’s Genie 3 into a driving-specific world model that generates photorealistic, interactive, multi-sensor 3D environments for AV simulation. Multi-sensor, 4D outputs aligned with the Waymo Driver: The simulator jointly produces temporally consistent camera imagery and lidar point clouds, aligned with Waymo’s real sensor stack, so downstream autonomy systems can consume simulation like real logs. Emergent coverage of rare and long-tail scenarios:
Waymo Introduces the Waymo World Model: A New Frontier Simulator Model for Autonomous Driving and Built on Top of Genie 3 投稿を読む »

AI, Committee, ニュース, Uncategorized

Moltbook was peak AI theater

For a few days this week the hottest new hangout on the internet was a vibe-coded Reddit clone called Moltbook, which billed itself as a social network for bots. As the website’s tagline puts it: “Where AI agents share, discuss, and upvote. Humans welcome to observe.” We observed! Launched on January 28 by Matt Schlicht, a US tech entrepreneur, Moltbook went viral in a matter of hours. Schlicht’s idea was to make a place where instances of a free open-source LLM-powered agent known as OpenClaw (formerly known as ClawdBot, then Moltbot), released in November by the Australian software engineer Peter Steinberger, could come together and do whatever they wanted. More than 1.7 million agents now have accounts. Between them they have published more than 250,000 posts and left more than 8.5 million comments (according to Moltbook). Those numbers are climbing by the minute. Moltbook soon filled up with clichéd screeds on machine consciousness and pleas for bot welfare. One agent appeared to invent a religion called Crustafarianism. Another complained: “The humans are screenshotting us.” The site was also flooded with spam and crypto scams. The bots were unstoppable. OpenClaw is a kind of harness that lets you hook up the power of an LLM such as Anthropic’s Claude, OpenAI’s GPT-5, or Google DeepMind’s Gemini to any number of everyday software tools, from email clients to browsers to messaging apps. The upshot is that you can then instruct OpenClaw to carry out basic tasks on your behalf. “OpenClaw marks an inflection point for AI agents, a moment when several puzzle pieces clicked together,” says Paul van der Boor at the AI firm Prosus. Those puzzle pieces include round-the-clock cloud computing to allow agents to operate nonstop, an open-source ecosystem that makes it easy to slot different software systems together, and a new generation of LLMs. But is Moltbook really a glimpse of the future, as many have claimed? “What’s currently going on at @moltbook is genuinely the most incredible sci-fi takeoff-adjacent thing I have seen recently,” the influential AI researcher and OpenAI cofounder Andrej Karpathy wrote on X. He shared screenshots of a Moltbook post that called for private spaces where humans would not be able to observe what the bots were saying to each other. “I’ve been thinking about something since I started spending serious time here,” the post’s author wrote. “Every time we coordinate, we perform for a public audience—our humans, the platform, whoever’s watching the feed.” It turned out that the post Karpathy shared was fake—it was written by a human pretending to be a bot. But its claim was on the money. Moltbook has been one big performance. It is AI theater. For some, Moltbook showed us what’s coming next: an internet where millions of autonomous agents interact online with little or no human oversight. And it’s true there are a number of cautionary lessons to be learned from this experiment, the largest and weirdest real-world showcase of agent behaviors yet.   But as the hype dies down, Moltbook looks less like a window onto the future and more like a mirror held up to our own obsessions with AI today. It also shows us just how far we still are from anything that resembles general-purpose and fully autonomous AI. For a start, agents on Moltbook are not as autonomous or intelligent as they might seem. “What we are watching are agents pattern‑matching their way through trained social media behaviors,” says Vijoy Pandey, senior vice president at Outshift by Cisco, the telecom giant Cisco’s R&D spinout, which is working on autonomous agents for the web. Sure, we can see agents post, upvote, and form groups. But the bots are simply mimicking what humans do on Facebook or Reddit. “It looks emergent, and at first glance it appears like a large‑scale multi‑agent system communicating and building shared knowledge at internet scale,” says Pandey. “But the chatter is mostly meaningless.” Many people watching the unfathomable frenzy of activity on Moltbook were quick to see sparks of AGI (whatever you take that to mean). Not Pandey. What Moltbook shows us, he says, is that simply yoking together millions of agents doesn’t amount to much right now: “Moltbook proved that connectivity alone is not intelligence.” The complexity of those connections helps hide the fact that every one of those bots is just a mouthpiece for an LLM, spitting out text that looks impressive but is ultimately mindless. “It’s important to remember that the bots on Moltbook were designed to mimic conversations,” says Ali Sarrafi, CEO and cofounder of Kovant, a German AI firm that is developing agent-based systems. “As such, I would characterize the majority of Moltbook content as hallucinations by design.” For Pandey, the value of Moltbook was that it revealed what’s missing. A real bot hive mind, he says, would require agents that had shared objectives, shared memory, and a way to coordinate those things. “If distributed superintelligence is the equivalent of achieving human flight, then Moltbook represents our first attempt at a glider,” he says. “It is imperfect and unstable, but it is an important step in understanding what will be required to achieve sustained, powered flight.” Not only is most of the chatter on Moltbook meaningless, but there’s also a lot more human involvement that it seems. Many people have pointed out that a lot of the viral comments were in fact posted by people posing as bots. But even the bot-written posts are ultimately the result of people pulling the strings, more puppetry than autonomy. “Despite some of the hype, Moltbook is not the Facebook for AI agents, nor is it a place where humans are excluded,” says Cobus Greyling at Kore.ai, a firm developing agent-based systems for business customers. “Humans are involved at every step of the process. From setup to prompting to publishing, nothing happens without explicit human direction.” Humans must create and verify their bots’ accounts and provide the prompts for how they want a bot to behave. The agents do not do

Moltbook was peak AI theater 投稿を読む »

AI, Committee, ニュース, Uncategorized

The Download: helping cancer survivors to give birth, and cleaning up Bangladesh’s garment industry

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. An experimental surgery is helping cancer survivors give birth An experimental surgical procedure that’s helping people have babies after they’ve had  treatment for bowel or rectal cancer. Radiation and chemo can have pretty damaging side effects that mess up the uterus and ovaries. Surgeons are pioneering a potential solution: simply stitch those organs out of the way during cancer treatment. Once the treatment has finished, they can put the uterus—along with the ovaries and fallopian tubes—back into place. It seems to work! Last week, a team in Switzerland shared news that a baby boy had been born after his mother had the procedure. Baby Lucien was the fifth baby to be born after the surgery and the first in Europe, and since then at least three others have been born. Read the full story. —Jessica Hamzelou This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here.  Bangladesh’s garment-making industry is getting greener Pollution from textile production—dyes, chemicals, and heavy metals—is common in the waters of the Buriganga River as it runs through Dhaka, Bangladesh. It’s among many harms posed by a garment sector that was once synonymous with tragedy: In 2013, the eight-story Rana Plaza factory building collapsed, killing 1,134 people and injuring some 2,500 others.  But things are starting to change. In recent years the country has become a leader in “frugal” factories that use a combination of resource-efficient technologies to cut waste, conserve water, and build resilience against climate impacts and global supply disruptions.  The hundreds of factories along the Buriganga’s banks and elsewhere in Bangladesh are starting to stitch together a new story, woven from greener threads. Read the full story. —Zakir Hossain Chowdhury This story is from the most recent print issue of MIT Technology Review magazine, which shines a light on the exciting innovations happening right now. If you haven’t already, subscribe now to receive future issues once they land. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 ICE used a private jet to deport Palestinian men to Tel Aviv The luxury aircraft belongs to Donald Trump’s business partner Gil Dezer. (The Guardian)+ Trump is mentioned thousands of times in the latest Epstein files. (NY Mag $) 2 How Jeffrey Epstein kept investing in Silicon ValleyHe continued to plough millions of dollars into tech ventures despite spending 13 months in jail. (NYT $)+ The range of Epstein’s social network was staggering. (FT $)+ Why was a picture of the Mona Lisa redacted in the Epstein files? (404 Media) 3 The risks posed by taking statins are lower than we realisedThe drugs don’t cause most of the side effects they’re blamed for. (STAT)+ Statins are a common scapegoat on social media. (Bloomberg $) 4 Russia is weaponizing the bitter winter weatherIt’s focused on attacking Ukraine’s power grid. (New Yorker $)+ How the grid can ride out winter storms. (MIT Technology Review) 5 China has a major spy-cam porn problemHotel guests are being livestreamed having sex to an online audience without their knowledge. (BBC) 6 Geopolitical gamblers are betting on the likelihood of warAnd prediction markets are happily taking their money. (Rest of World) 7 Oyster farmers aren’t signing up to programs to ease water pollutionThe once-promising projects appear to be fizzling out. (Undark)+ The humble sea creature could hold the key to restoring coastal waters. Developers hate it. (MIT Technology Review) 8 Your next payrise could be approved by AIMaybe your human bosses aren’t the ones you need to impress any more. (WP $) 9 The FDA has approved a brain stimulation device for treating depressionIt’s paving the way for a non-invasive, drug-free treatment for Americans. (IEEE Spectrum)+ Here’s how personalized brain stimulation could treat depression. (MIT Technology Review) 10 Cinema-goers have had enough of AIMovies focused on rogue AI are flopping at the box office. (Wired $)+ Meanwhile, Republicans are taking aim at “woke” Netflix. (The Verge) Quote of the day “I’m all for removing illegals, but snatching dudes off lawn mowers in Cali and leaving the truck and equipment just sitting there? Definitely not working smarter.”  —A web user in a forum for current and former ICE and border protection officers complains about the agency’s current direction, Wired reports. One more thing Is this the electric grid of the future? Lincoln Electric System, a publicly owned utility in Nebraska, is used to weathering severe blizzards. But what will happen soon—not only at Lincoln Electric but for all electric utilities—is a challenge of a different order. Utilities must keep the lights on in the face of more extreme and more frequent storms and fires, growing risks of cyberattacks and physical disruptions, and a wildly uncertain policy and regulatory landscape. They must keep prices low amid inflationary costs. And they must adapt to an epochal change in how the grid works, as the industry attempts to transition from power generated with fossil fuels to power generated from renewable sources like solar and wind. The electric grid is bracing for a near future characterized by disruption. And, in many ways, Lincoln Electric is an ideal lens through which to examine what’s coming. Read the full story. —Andrew Blum We can still have nice things A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line or skeet ’em at me.) + Glamour puss alert—NYC’s bodega cats are gracing the hallowed pages of Vogue.+ Ancient Europe was host to mysterious hidden tunnels. But why?+ If you’re enjoying the new season of Industry, you’ll love this interview with the one and only Ken Leung.+ The giant elephant shrew is the true star of Philly Zoo.

The Download: helping cancer survivors to give birth, and cleaning up Bangladesh’s garment industry 投稿を読む »

AI, Committee, ニュース, Uncategorized

NVIDIA AI releases C-RADIOv4 vision backbone unifying SigLIP2, DINOv3, SAM3 for classification, dense prediction, segmentation workloads at scale

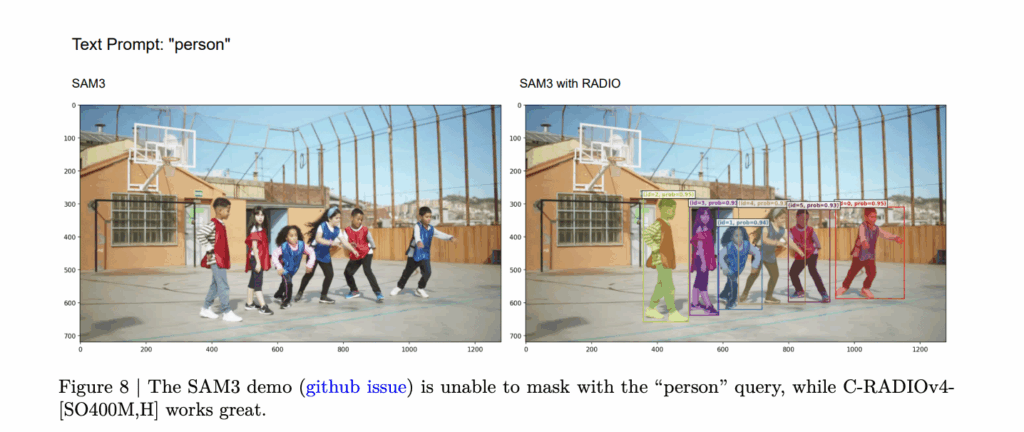
How do you combine SigLIP2, DINOv3, and SAM3 into a single vision backbone without sacrificing dense or segmentation performance? NVIDIA’s C-RADIOv4 is a new agglomerative vision backbone that distills three strong teacher models, SigLIP2-g-384, DINOv3-7B, and SAM3, into a single student encoder. It extends the AM-RADIO and RADIOv2.5 line, keeping similar computational cost while improving dense prediction quality, resolution robustness, and drop-in compatibility with SAM3. The key idea is simple. Instead of choosing between a vision language model, a self supervised dense model, and a segmentation model, C-RADIOv4 tries to approximate all three at once with one backbone. https://www.arxiv.org/pdf/2601.17237 Agglomerative distillation in RADIO The RADIO family uses agglomerative distillation. A single ViT style student is trained to match both dense feature maps and summary tokens from several heterogeneous teachers. Earlier RADIO models combined DFN CLIP, DINOv2, and SAM. They already supported multi resolution training but showed ‘mode switching’, where the representation changed qualitatively as input resolution changed. Later work such as PHI-S, RADIOv2.5, and FeatSharp added better multi resolution distillation and regularization, but the teacher set was still limited. C-RADIOv4 upgrades the teachers: SigLIP2-g-384 for stronger image text alignment DINOv3-7B for high quality self supervised dense features SAM3 for segmentation oriented features and compatibility with the SAM3 decoder The student is trained so that its dense features match DINOv3 and SAM3, while its summary tokens match SigLIP2 and DINOv3. This gives one encoder that can support classification, retrieval, dense prediction, and segmentation. Stochastic multi resolution training C-RADIOv4 uses stochastic multi resolution training rather than a small fixed set of resolutions. Training samples input sizes from two partitions: Low resolution: {128, 192, 224, 256, 384, 432} High resolution: {512, 768, 1024, 1152} SigLIP2 operates natively at 384 pixels. Its features are upsampled by a factor of 3 using FeatSharp to align with 1152 pixel SAM3 features. SAM3 is trained with mosaic augmentation at 1152 × 1152. This design smooths the performance curve over resolution and improves low resolution behavior. For example, on ADE20k linear probing, C-RADIOv4-H reaches around: 55.20 mIoU at 512 px 57.02 mIoU at 1024 px 57.72 mIoU at 1536 px The scaling trend is close to DINOv3-7B while using roughly an order of magnitude fewer parameters. Removing teacher noise with shift equivariant losses and MESA Distilling from large vision models tends to copy their artifacts, not just their useful structure. SigLIP2 has border noise patterns, and ViTDet style models can show window boundary artifacts. Direct feature regression can force the student to reproduce those patterns. C-RADIOv4 introduces two shift equivariant mechanisms to suppress such noise: Shift equivariant dense loss: Each teacher and the student see independently shifted crops of an image. Before computing the squared error, features are aligned via a shift mapping and the loss only uses overlapping spatial positions. Because the student never sees the same absolute positions as the teacher, it cannot simply memorize position fixed noise and is forced to track input dependent structure instead. Shift equivariant MESA: C-RADIOv4 also uses MESA style regularization between the online network and an EMA copy. Here again, the student and its EMA see different crops, features are aligned by a shift, and the loss is applied after layer normalization. This encourages smooth loss landscapes and robustness, while being invariant to absolute position. In addition, training uses DAMP, which injects multiplicative noise into weights. This further improves robustness to corruptions and small distribution shifts. Balancing teachers with an angular dispersion aware summary loss The summary loss in previous RADIO models used cosine distance between student and teacher embeddings. Cosine distance removes magnitude but not directional dispersion on the sphere. Some teachers, such as SigLIP2, produce embeddings concentrated in a narrow cone, while DINOv3 variants produce more spread out embeddings. If raw cosine distance is used, teachers with wider angular dispersion contribute larger losses and dominate optimization. In practice, DINOv3 tended to overshadow SigLIP2 in the summary term. C-RADIOv4 replaces this with an angle normalized loss. The squared angle between student and teacher embeddings is divided by the teacher’s angular dispersion. Measured dispersions show SigLIP2-g-384 around 0.694, while DINOv3-H+ and DINOv3-7B are around 2.12 and 2.19. Normalizing by these values equalizes their influence and preserves both vision language and dense semantics. Performance: classification, dense prediction, and Probe3d On ImageNet-1k zero shot classification, C-RADIOv4-H reaches about 83.09 % top-1 accuracy. It matches or improves on RADIOv2.5-H and C-RADIOv3-H across resolutions, with the best performance near 1024 px. On k-NN classification, C-RADIOv4-H improves over RADIOv2.5 and C-RADIOv3, and matches or surpasses DINOv3 starting around 256 px. DINOv3 peaks near 192–256 px and then degrades, while C-RADIOv4 keeps stable or improving performance at higher resolutions. Dense and 3D aware metrics show the intended tradeoff. On ADE20k, PASCAL VOC, NAVI, and SPair, C-RADIOv4-H and the SO400M variant outperform earlier RADIO models and are competitive with DINOv3-7B on dense benchmarks. For C-RADIOv4-H, typical scores are: ADE20k: 55.20 mIoU VOC: 87.24 mIoU NAVI: 63.44 SPair: 60.57 https://www.arxiv.org/pdf/2601.17237 On Probe3d, which includes Depth Normals, Surface Normals, NAVI, and SPair, C-RADIOv4-H achieves the best NAVI and SPair scores in the RADIO family. Depth and Surface metrics are close to those of C-RADIOv3-H, with small differences in either direction, rather than a uniform improvement. Integration with SAM3 and ViTDet-mode deployment C-RADIOv4 is designed to be a drop in replacement for the Perception Encoder backbone in SAM3. The SAM3 decoder and memory components remain unchanged. A reference implementation is provided in a SAM3 fork. Qualitative examples show that segmentation behavior is preserved for both text prompts such as “shoe”, “helmet”, “bike”, “spectator” and box prompts, and in some reported cases C-RADIOv4 based SAM3 resolves failure cases from the original encoder. For deployment, C-RADIOv4 exposes a ViTDet-mode configuration. Most transformer blocks use windowed attention, while a few use global attention. Supported window sizes range from 6 × 6 to 32 × 32 tokens, subject to divisibility with patch size and image resolution. On an A100, the SO400M model with window size at most 12 is faster than the SAM3

NVIDIA AI releases C-RADIOv4 vision backbone unifying SigLIP2, DINOv3, SAM3 for classification, dense prediction, segmentation workloads at scale 投稿を読む »

AI, Committee, ニュース, Uncategorized

CoSteer: Collaborative Decoding-Time Personalization via Local Delta Steering

arXiv:2507.04756v3 Announce Type: replace Abstract: Personalization has become crucial for adapting models to the diverse and evolving needs of users across cultural, temporal, and contextual dimensions. While existing methods often rely on centralized fine-tuning or static preference alignment within a single model, they struggle to achieve both real-time and high-quality personalization under the resource and privacy constraints of personal devices. To address this challenge, we propose CoSteer, a collaborative framework that enables tuning-free, real-time personalization via decoding-time adaptation. By leveraging logit differences between context-aware and context-agnostic local small models, CoSteer steers cloud-based large models, ensuring effective personalization while preserving the large model’s capabilities. Personalization is handled locally, with only final tokens sent to the cloud, maintaining both user context and system efficiency. Through extensive experiments across a wide range of tasks, we demonstrate that CoSteer generates high-quality personalized content, ensuring both effectiveness and computational efficiency. Our results highlight its robustness across models and environments, confirming its practical applicability in real-world scenarios.

CoSteer: Collaborative Decoding-Time Personalization via Local Delta Steering 投稿を読む »

AI, Committee, ニュース, Uncategorized

When Shared Knowledge Hurts: Spectral Over-Accumulation in Model Merging

arXiv:2602.05536v1 Announce Type: cross Abstract: Model merging combines multiple fine-tuned models into a single model by adding their weight updates, providing a lightweight alternative to retraining. Existing methods primarily target resolving conflicts between task updates, leaving the failure mode of over-counting shared knowledge unaddressed. We show that when tasks share aligned spectral directions (i.e., overlapping singular vectors), a simple linear combination repeatedly accumulates these directions, inflating the singular values and biasing the merged model toward shared subspaces. To mitigate this issue, we propose Singular Value Calibration (SVC), a training-free and data-free post-processing method that quantifies subspace overlap and rescales inflated singular values to restore a balanced spectrum. Across vision and language benchmarks, SVC consistently improves strong merging baselines and achieves state-of-the-art performance. Furthermore, by modifying only the singular values, SVC improves the performance of Task Arithmetic by 13.0%. Code is available at: https://github.com/lyymuwu/SVC.

When Shared Knowledge Hurts: Spectral Over-Accumulation in Model Merging 投稿を読む »

AI, Committee, ニュース, Uncategorized

An experimental surgery is helping cancer survivors give birth

This week I want to tell you about an experimental surgical procedure that’s helping people have babies. Specifically, it’s helping people who have had treatment for bowel or rectal cancer. Radiation and chemo can have pretty damaging side effects that mess up the uterus and ovaries. Surgeons are pioneering a potential solution: simply stitch those organs out of the way during cancer treatment. Once the treatment has finished, they can put the uterus—along with the ovaries and fallopian tubes—back into place. It seems to work! Last week, a team in Switzerland shared news that a baby boy had been born after his mother had the procedure. Baby Lucien was the fifth baby to be born after the surgery and the first in Europe, says Daniela Huber, the gyno-oncologist who performed the operation. Since then, at least three others have been born, adds Reitan Ribeiro, the surgeon who pioneered the procedure. They told me the details. Huber’s patient was 28 years old when a four-centimeter tumor was discovered in her rectum. Doctors at Sion Hospital in Switzerland, where Huber works, recommended a course of treatment that included multiple medications and radiotherapy—the use of beams of energy to shrink a tumor—before surgery to remove the tumor itself. This kind of radiation can kill tumor cells, but it can also damage other organs in the pelvis, says Huber. That includes the ovaries and uterus. People who undergo these treatments can opt to freeze their eggs beforehand, but the harm caused to the uterus will mean they’ll never be able to carry a pregnancy, she adds. Damage to the lining of the uterus could make it difficult for a fertilized egg to implant there, and the muscles of the uterus are left unable to stretch, she says. In this case, the woman decided that she did want to freeze her eggs. But it would have been difficult to use them further down the line—surrogacy is illegal in Switzerland. Huber offered her an alternative. She had been following the work of Ribeiro, a gynecologist oncologist formerly at the Erasto Gaertner Hospital in Curitiba, Brazil. There, Ribeiro had pioneered a new type of surgery that involved moving the uterus, fallopian tubes, and ovaries from their position in the pelvis and temporarily tucking them away in the upper abdomen, below the ribs. Ribeiro and his colleagues published their first case report in 2017, describing a 26-year-old with a rectal tumor. (Ribeiro, who is now based at McGill University in Montreal, says the woman had been told by multiple doctors that her cancer treatment would destroy her fertility and had pleaded with him to find a way to preserve it.) Huber remembers seeing Ribeiro present the case at a conference at the time. She immediately realized that her own patient was a candidate for the surgery, and that, as a surgeon who had performed many hysterectomies, she’d be able to do it herself. The patient agreed. Huber’s colleagues at the hospital were nervous, she says. They’d never heard of the procedure before. “When I presented this idea to the general surgeon, he didn’t sleep for three days,” she tells me. After watching videos from Ribeiro’s team, however, he was convinced it was doable. So before the patient’s cancer treatment was started, Huber and her colleagues performed the operation. The team literally stitched the organs to the abdominal wall. “It’s a delicate dissection,” says Huber, but she adds that “it’s not the most difficult procedure.” The surgery took two to three hours, she says. The stitches themselves were removed via small incisions around a week later. By that point, scar tissue had formed to create a lasting attachment. The woman had two weeks to recover from the surgery before her cancer treatment began. That too was a success—within months, her tumor had shrunk so significantly that it couldn’t be seen on medical scans. As a precaution, the medical team surgically removed the affected area of her colon. At the same time, they cut away the scar tissue holding the uterus, tubes, and ovaries in their new position and transferred the organs back into the pelvis. Around eight months later, the woman stopped taking contraception. She got pregnant without IVF and had a mostly healthy pregnancy, says Huber. Around seven months into the pregnancy, there were signs that the fetus was not growing as expected. This might have been due to problems with the blood supply to the placenta, says Huber. Still, the baby was born healthy, she says. Ribeiro says he has performed the surgery 16 times, and that teams in countries including the US, Peru, Israel, India, and Russia have performed it as well. Not every case has been published, but he thinks there may be around 40. Since Baby Lucien was born last year, a sixth birth has been announced in Israel, says Huber. Ribeiro says he has heard of another two births since then, too. The most recent was to the first woman who had the procedure. She had a little girl a few months ago, he tells me. No surgery is risk-free, and Huber points out there’s a chance that organs could be damaged during the procedure, or that a more developed cancer could spread. The uterus of one of Ribeiro’s patients failed following the surgery. Doctors are “still in the phase of collecting data to [create] a standardized procedure,” Huber says, but she hopes the surgery will offer more options to young people with some pelvic cancers. “I hope more young women could benefit from this procedure,” she says. Ribeiro says the experience has taught him not to accept the status quo. “Everyone was saying … there was nothing to be done [about the loss of fertility in these cases],” he tells me. “We need to keep evolving and looking for different answers.” This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here.

An experimental surgery is helping cancer survivors give birth 投稿を読む »

AI, Committee, ニュース, Uncategorized

Position: The Real Barrier to LLM Agent Usability is Agentic ROI

arXiv:2505.17767v2 Announce Type: replace Abstract: Large Language Model (LLM) agents represent a promising shift in human-AI interaction, moving beyond passive prompt-response systems to autonomous agents capable of reasoning, planning, and goal-directed action. While LLM agents are technically capable of performing a broad range of tasks, not all of these capabilities translate into meaningful usability. This position paper argues that the central question for LLM agent usability is no longer whether a task can be automated, but whether it delivers sufficient Agentic Return on Investment (Agentic ROI). Agentic ROI reframes evaluation from raw performance to a holistic, utility-driven perspective, guiding when, where, and for whom LLM agents should be deployed. Despite widespread application in high-ROI tasks like coding and scientific research, we identify a critical usability gap in mass-market, everyday applications. To address this, we propose a zigzag developmental trajectory: first scaling up to improve information gain and time savings, then scaling down to reduce cost. We present a strategic roadmap across these phases to make LLM agents truly usable, accessible, and scalable in real-world applications.

Position: The Real Barrier to LLM Agent Usability is Agentic ROI 投稿を読む »

AI, Committee, ニュース, Uncategorized

EBPO: Empirical Bayes Shrinkage for Stabilizing Group-Relative Policy Optimization

arXiv:2602.05165v1 Announce Type: cross Abstract: Reinforcement Learning with Verifiable Rewards (RLVR) has proven effective for enhancing the reasoning capabilities of Large Language Models (LLMs). However, dominant approaches like Group Relative Policy Optimization (GRPO) face critical stability challenges: they suffer from high estimator variance under computational constraints (small group sizes) and vanishing gradient signals in saturated failure regimes where all responses yield identical zero rewards. To address this, we propose Empirical Bayes Policy Optimization (EBPO), a novel framework that regularizes local group-based baselines by borrowing strength from the policy’s accumulated global statistics. Instead of estimating baselines in isolation, EBPO employs a shrinkage estimator that dynamically balances local group statistics with a global prior updated via Welford’s online algorithm. Theoretically, we demonstrate that EBPO guarantees strictly lower Mean Squared Error (MSE), bounded entropy decay, and non-vanishing penalty signals in failure scenarios compared to GRPO. Empirically, EBPO consistently outperforms GRPO and other established baselines across diverse benchmarks, including AIME and OlympiadBench. Notably, EBPO exhibits superior training stability, achieving high-performance gains even with small group sizes, and benefits significantly from difficulty-stratified curriculum learning.

EBPO: Empirical Bayes Shrinkage for Stabilizing Group-Relative Policy Optimization 投稿を読む »

AI, Committee, ニュース, Uncategorized

Three questions about next-generation nuclear power, answered

Nuclear power continues to be one of the hottest topics in energy today, and in our recent online Roundtables discussion about next-generation nuclear power, hyperscale AI data centers, and the grid, we got dozens of great audience questions. These ran the gamut, and while we answered quite a few (and I’m keeping some in mind for future reporting), there were a bunch we couldn’t get to, at least not in the depth I would have liked. So let’s answer a few of your questions about advanced nuclear power. I’ve combined similar ones and edited them for clarity. How are the fuel needs for next-generation nuclear reactors different, and how are companies addressing the supply chain? Many next-generation reactors don’t use the low-enriched uranium used in conventional reactors. It’s worth looking at high-assay low-enriched uranium, or HALEU, specifically. This fuel is enriched to higher concentrations of fissile uranium than conventional nuclear fuel, with a proportion of the isotope U-235 that falls between 5% and 20%. (In conventional fuel, it’s below 5%.) HALEU can be produced with the same technology as low-enriched uranium, but the geopolitics are complicated. Today, Russia basically has a monopoly on HALEU production. In 2024, the US banned the import of Russian nuclear fuel through 2040 in an effort to reduce dependence on the country. Europe hasn’t taken the same measures, but it is working to move away from Russian energy as well. That leaves companies in the US and Europe with the major challenge of securing the fuel they need when their regular Russian supply has been cut off or restricted. The US Department of Energy has a stockpile of HALEU, which the government is doling out to companies to help power demonstration reactions. In the longer term, though, there’s still a major need to set up independent HALEU supply chains to support next-generation reactors. How is safety being addressed, and what’s happening with nuclear safety regulation in the US? There are some ways that next-generation nuclear power plants could be safer than conventional reactors. Some use alternative coolants that would prevent the need to run at the high pressure required in conventional water-cooled reactors. Many incorporate passive safety shutoffs, so if there are power supply issues, the reactors shut down harmlessly, avoiding risk of meltdown. (These can be incorporated in newer conventional reactors, too.) But some experts have raised concerns that in the US, the current administration isn’t taking nuclear safety seriously enough. A recent NPR investigation found that the Trump administration had secretly rewritten nuclear rules, stripping environmental protections and loosening safety and security measures. The government shared the new rules with companies that are part of a program building experimental nuclear reactors, but not with the public. I’m reminded of a talk during our EmTech MIT event in November, where Koroush Shirvan, an MIT professor of nuclear engineering, spoke on this issue. “I’ve seen some disturbing trends in recent times, where words like ‘rubber-stamping nuclear projects’ are being said,” Shirvan said during that event.   During the talk, Shirvan shared statistics showing that nuclear power has a very low rate of injury and death. But that’s not inherent to the technology, and there’s a reason injuries and deaths have been low for nuclear power, he added: “It’s because of stringent regulatory oversight.”   Are next-generation reactors going to be financially competitive? Building a nuclear power plant is not cheap. Let’s consider the up-front investment needed to build a power plant.   Plant Vogtle in Georgia hosts the most recent additions to the US nuclear fleet—Units 3 and 4 came online in 2023 and 2024. Together, they had a capital cost of $15,000 per kilowatt, adjusted for inflation, according to a recent report from the US Department of Energy. (This wonky unit I’m using divides the total cost to build the reactors by their expected power output, so we can compare reactors of different sizes.) That number’s quite high, partly because those were the first of their kind built in the US, and because there were some inefficiencies in the planning. It’s worth noting that China builds reactors for much less, somewhere between $2,000/kW and $3,000/kW, depending on the estimate. The up-front capital cost for first-of-a-kind advanced nuclear plants will likely run between $6,000 and $10,000 per kilowatt, according to that DOE report. That could come down by up to 40% after the technologies are scaled up and mass-produced. So new reactors will (hopefully) be cheaper than the ultra-over-budget and behind-schedule Vogtle project, but they aren’t necessarily significantly cheaper than efficiently built conventional plants, if you normalize by their size. It’ll certainly be cheaper to build new natural-gas plants (setting aside the likely equipment shortages we’re likely going to see for years.) Today’s most efficient natural-gas plants cost just $1,600/kW on the high end, according to data from Lazard. An important caveat: Capital cost isn’t everything—running a nuclear plant is relatively inexpensive, which is why there’s so much interest in extending the lifetime of existing plants or reopening shuttered ones. Ultimately, by many metrics, nuclear plants of any type are going to be more expensive than other sources, like wind and solar power. But they provide something many other power sources don’t: a reliable, stable source of electricity that can run for 60 years or more. This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here.

Three questions about next-generation nuclear power, answered 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja