YouZum

Committee

AI, Committee, ニュース, Uncategorized

Mistral AI Launches Voxtral Transcribe 2: Pairing Batch Diarization And Open Realtime ASR For Multilingual Production Workloads At Scale

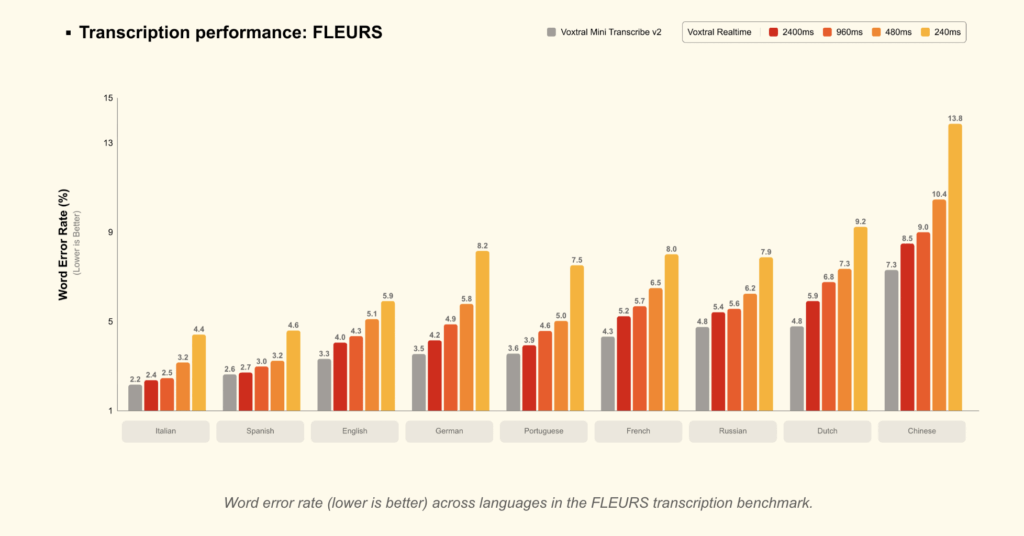
Automatic speech recognition (ASR) is becoming a core building block for AI products, from meeting tools to voice agents. Mistral’s new Voxtral Transcribe 2 family targets this space with 2 models that split cleanly into batch and realtime use cases, while keeping cost, latency, and deployment constraints in focus. The release includes: Voxtral Mini Transcribe V2 for batch transcription with diarization. Voxtral Realtime (Voxtral Mini 4B Realtime 2602) for low-latency streaming transcription, released as open weights. Both models are designed for 13 languages: English, Chinese, Hindi, Spanish, Arabic, French, Portuguese, Russian, German, Japanese, Korean, Italian, and Dutch. Model family: batch and streaming, with clear roles Mistral positions Voxtral Transcribe 2 as ‘two next-generation speech-to-text models’ with state-of-the-art transcription quality, diarization, and ultra-low latency. Voxtral Mini Transcribe V2 is the batch model. It is optimized for transcription quality and diarization across domains and languages and exposed as an efficient audio input model in the Mistral API. Voxtral Realtime is the streaming model. It is built with a dedicated streaming architecture and is released as an open-weights model under Apache 2.0 on Hugging Face, with a recommended vLLM runtime. A key detail: speaker diarization is provided by Voxtral Mini Transcribe V2, not by Voxtral Realtime. Realtime focuses strictly on fast, accurate streaming transcription. Voxtral Realtime: 4B-parameter streaming ASR with configurable delay Voxtral Mini 4B Realtime 2602 is a 4B-parameter multilingual realtime speech-transcription model. It is among the first open-weights models to reach accuracy comparable to offline systems with a delay under 500 ms. Architecture: ≈3.4B-parameter language model. ≈0.6B-parameter audio encoder. The audio encoder is trained from scratch with causal attention. Both encoder and LM use sliding-window attention, enabling effectively “infinite” streaming. Latency vs accuracy is explicitly configurable: Transcription delay is tunable from 80 ms to 2.4 s via a transcription_delay_ms parameter. The Mistral describes latency as “configurable down to sub-200 ms” for live applications. At 480 ms delay, Realtime matches leading offline open-source transcription models and realtime APIs on benchmarks such as FLEURS and long-form English. At 2.4 s delay, Realtime matches Voxtral Mini Transcribe V2 on FLEURS, which is appropriate for subtitling tasks where slightly higher latency is acceptable. From a deployment standpoint: The model is released in BF16 and is designed for on-device or edge deployment. It can run in realtime on a single GPU with ≥16 GB memory, according to the vLLM serving instructions in the model card. The main control knob is the delay setting: Lower delays (≈80–200 ms) for interactive agents where responsiveness dominates. Around 480 ms as the recommended “sweet spot” between latency and accuracy. Higher delays (up to 2.4 s) when you need accuracy as close as possible to the batch model. Voxtral Mini Transcribe V2: batch ASR with diarization and context biasing Voxtral Mini Transcribe V2 is a closed-weights audio input model optimized only for transcription. It is exposed in the Mistral API as voxtral-mini-2602 at $0.003 per minute. On benchmarks and pricing: Around 4% word error rate (WER) on the FLEURS transcription benchmark, averaged over the top 10 languages. “Best price-performance of any transcription API” at $0.003/min. Outperforms GPT-4o mini Transcribe, Gemini 2.5 Flash, Assembly Universal, and Deepgram Nova on accuracy in their comparisons. Processes audio ≈3× faster than ElevenLabs’ Scribe v2 while matching quality at one-fifth the cost. Enterprise-oriented features are concentrated in this model: Speaker diarization Outputs speaker labels with precise start and end times. Designed for meetings, interviews, and multi-party calls. For overlapping speech, the model typically emits a single speaker label. Context biasing Accepts up to 100 words or phrases to bias transcription toward specific names or domain terms. Optimized for English, with experimental support for other languages. Word-level timestamps Per-word start and end timestamps for subtitles, alignment, and searchable audio workflows. Noise robustness Maintains accuracy in noisy environments such as factory floors, call centers, and field recordings. Longer audio support Handles up to 3 hours of audio in a single request. Language coverage mirrors Realtime: 13 languages, with Mistral noting that non-English performance “significantly outpaces competitors” in their evaluation. https://mistral.ai/news/voxtral-transcribe-2 APIs, tooling, and deployment options The integration paths are straightforward and differ slightly between the two models: Voxtral Mini Transcribe V2 Served via the Mistral audio transcription API (/v1/audio/transcriptions) as an efficient transcription-only service. Priced at $0.003/min. (Mistral AI) Available in Mistral Studio’s audio playground and in Le Chat for interactive testing. Voxtral Realtime Available via the Mistral API at $0.006/min. Released as open weights on Hugging Face (mistralai/Voxtral-Mini-4B-Realtime-2602) under Apache 2.0, with official vLLM Realtime support. The audio playground in Mistral Studio lets users: Upload up to 10 audio files (.mp3, .wav, .m4a, .flac, .ogg) up to 1 GB each. Toggle diarization, choose timestamp granularity, and configure context bias terms. Key Takeaways Two-model family with clear roles: Voxtral Mini Transcribe V2 targets batch transcription and diarization, while Voxtral Realtime targets low-latency streaming ASR, both across 13 languages. Realtime model- 4B parameters with tunable delay: Voxtral Realtime uses a 4B architecture (≈3.4B LM + ≈0.6B encoder) with sliding-window and causal attention, and supports configurable transcription delay from 80 ms to 2.4 s. Latency vs accuracy trade-off is explicit: Around 480 ms delay, Voxtral Realtime reaches accuracy comparable to strong offline and realtime systems, and at 2.4 s it matches Voxtral Mini Transcribe V2 on FLEURS. Batch model adds diarization and enterprise features: Voxtral Mini Transcribe V2 provides diarization, context biasing with up to 100 phrases, word-level timestamps, noise robustness, and supports up to 3 hours of audio per request at $0.003/min. Deployment- closed batch API, open realtime weights: Mini Transcribe V2 is served via Mistral’s audio transcription API and playground, while Voxtral Realtime is priced at $0.006/min and also available as Apache 2.0 open weights with official vLLM Realtime support. Check out the Technical details and Model Weights. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Mistral AI Launches Voxtral Transcribe 2: Pairing Batch Diarization And

Mistral AI Launches Voxtral Transcribe 2: Pairing Batch Diarization And Open Realtime ASR For Multilingual Production Workloads At Scale 投稿を読む »

AI, Committee, ニュース, Uncategorized

No One-Size-Fits-All: Building Systems For Translation to Bashkir, Kazakh, Kyrgyz, Tatar and Chuvash Using Synthetic And Original Data

arXiv:2602.04442v1 Announce Type: new Abstract: We explore machine translation for five Turkic language pairs: Russian-Bashkir, Russian-Kazakh, Russian-Kyrgyz, English-Tatar, English-Chuvash. Fine-tuning nllb-200-distilled-600M with LoRA on synthetic data achieved chrF++ 49.71 for Kazakh and 46.94 for Bashkir. Prompting DeepSeek-V3.2 with retrieved similar examples achieved chrF++ 39.47 for Chuvash. For Tatar, zero-shot or retrieval-based approaches achieved chrF++ 41.6, while for Kyrgyz the zero-shot approach reached 45.6. We release the dataset and the obtained weights.

No One-Size-Fits-All: Building Systems For Translation to Bashkir, Kazakh, Kyrgyz, Tatar and Chuvash Using Synthetic And Original Data 投稿を読む »

AI, Committee, ニュース, Uncategorized

DeepAgent: A General Reasoning Agent with Scalable Toolsets

arXiv:2510.21618v2 Announce Type: replace-cross Abstract: Large reasoning models have demonstrated strong problem-solving abilities, yet real-world tasks often require external tools and long-horizon interactions. Existing agent frameworks typically follow predefined workflows, which limit autonomous and global task completion. In this paper, we introduce DeepAgent, an end-to-end deep reasoning agent that performs autonomous thinking, tool discovery, and action execution within a single, coherent reasoning process. To address the challenges of long-horizon interactions, particularly the context length explosion from multiple tool calls and the accumulation of interaction history, we introduce an autonomous memory folding mechanism that compresses past interactions into structured episodic, working, and tool memories, reducing error accumulation while preserving critical information. To teach general-purpose tool use efficiently and stably, we develop an end-to-end reinforcement learning strategy, namely ToolPO, that leverages LLM-simulated APIs and applies tool-call advantage attribution to assign fine-grained credit to the tool invocation tokens. Extensive experiments on eight benchmarks, including general tool-use tasks (ToolBench, API-Bank, TMDB, Spotify, ToolHop) and downstream applications (ALFWorld, WebShop, GAIA, HLE), demonstrate that DeepAgent consistently outperforms baselines across both labeled-tool and open-set tool retrieval scenarios. This work takes a step toward more general and capable agents for real-world applications. The code and demo are available at https://github.com/RUC-NLPIR/DeepAgent.

DeepAgent: A General Reasoning Agent with Scalable Toolsets 投稿を読む »

AI, Committee, ニュース, Uncategorized

Three questions about next-generation nuclear power, answered

Nuclear power continues to be one of the hottest topics in energy today, and in our recent online Roundtables discussion about next-generation nuclear power, hyperscale AI data centers, and the grid, we got dozens of great audience questions. These ran the gamut, and while we answered quite a few (and I’m keeping some in mind for future reporting), there were a bunch we couldn’t get to, at least not in the depth I would have liked. So let’s answer a few of your questions about advanced nuclear power. I’ve combined similar ones and edited them for clarity. How are the fuel needs for next-generation nuclear reactors different, and how are companies addressing the supply chain? Many next-generation reactors don’t use the low-enriched uranium used in conventional reactors. It’s worth looking at high-assay low-enriched uranium, or HALEU, specifically. This fuel is enriched to higher concentrations of fissile uranium than conventional nuclear fuel, with a proportion of the isotope U-235 that falls between 5% and 20%. (In conventional fuel, it’s below 5%.) HALEU can be produced with the same technology as low-enriched uranium, but the geopolitics are complicated. Today, Russia basically has a monopoly on HALEU production. In 2024, the US banned the import of Russian nuclear fuel through 2040 in an effort to reduce dependence on the country. Europe hasn’t taken the same measures, but it is working to move away from Russian energy as well. That leaves companies in the US and Europe with the major challenge of securing the fuel they need when their regular Russian supply has been cut off or restricted. The US Department of Energy has a stockpile of HALEU, which the government is doling out to companies to help power demonstration reactions. In the longer term, though, there’s still a major need to set up independent HALEU supply chains to support next-generation reactors. How is safety being addressed, and what’s happening with nuclear safety regulation in the US? There are some ways that next-generation nuclear power plants could be safer than conventional reactors. Some use alternative coolants that would prevent the need to run at the high pressure required in conventional water-cooled reactors. Many incorporate passive safety shutoffs, so if there are power supply issues, the reactors shut down harmlessly, avoiding risk of meltdown. (These can be incorporated in newer conventional reactors, too.) But some experts have raised concerns that in the US, the current administration isn’t taking nuclear safety seriously enough. A recent NPR investigation found that the Trump administration had secretly rewritten nuclear rules, stripping environmental protections and loosening safety and security measures. The government shared the new rules with companies that are part of a program building experimental nuclear reactors, but not with the public. I’m reminded of a talk during our EmTech MIT event in November, where Koroush Shirvan, an MIT professor of nuclear engineering, spoke on this issue. “I’ve seen some disturbing trends in recent times, where words like ‘rubber-stamping nuclear projects’ are being said,” Shirvan said during that event.   During the talk, Shirvan shared statistics showing that nuclear power has a very low rate of injury and death. But that’s not inherent to the technology, and there’s a reason injuries and deaths have been low for nuclear power, he added: “It’s because of stringent regulatory oversight.”   Are next-generation reactors going to be financially competitive? Building a nuclear power plant is not cheap. Let’s consider the up-front investment needed to build a power plant.   Plant Vogtle in Georgia hosts the most recent additions to the US nuclear fleet—Units 3 and 4 came online in 2023 and 2024. Together, they had a capital cost of $15,000 per kilowatt, adjusted for inflation, according to a recent report from the US Department of Energy. (This wonky unit I’m using divides the total cost to build the reactors by their expected power output, so we can compare reactors of different sizes.) That number’s quite high, partly because those were the first of their kind built in the US, and because there were some inefficiencies in the planning. It’s worth noting that China builds reactors for much less, somewhere between $2,000/kW and $3,000/kW, depending on the estimate. The up-front capital cost for first-of-a-kind advanced nuclear plants will likely run between $6,000 and $10,000 per kilowatt, according to that DOE report. That could come down by up to 40% after the technologies are scaled up and mass-produced. So new reactors will (hopefully) be cheaper than the ultra-over-budget and behind-schedule Vogtle project, but they aren’t necessarily significantly cheaper than efficiently built conventional plants, if you normalize by their size. It’ll certainly be cheaper to build new natural-gas plants (setting aside the likely equipment shortages we’re likely going to see for years.) Today’s most efficient natural-gas plants cost just $1,600/kW on the high end, according to data from Lazard. An important caveat: Capital cost isn’t everything—running a nuclear plant is relatively inexpensive, which is why there’s so much interest in extending the lifetime of existing plants or reopening shuttered ones. Ultimately, by many metrics, nuclear plants of any type are going to be more expensive than other sources, like wind and solar power. But they provide something many other power sources don’t: a reliable, stable source of electricity that can run for 60 years or more. This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here.

Three questions about next-generation nuclear power, answered 投稿を読む »

AI, Committee, ニュース, Uncategorized

Mistral AI Launches Voxtral Transcribe 2: Pairing Batch Diarization And Open Realtime ASR For Multilingual Production Workloads At Scale

Automatic speech recognition (ASR) is becoming a core building block for AI products, from meeting tools to voice agents. Mistral’s new Voxtral Transcribe 2 family targets this space with 2 models that split cleanly into batch and realtime use cases, while keeping cost, latency, and deployment constraints in focus. The release includes: Voxtral Mini Transcribe V2 for batch transcription with diarization. Voxtral Realtime (Voxtral Mini 4B Realtime 2602) for low-latency streaming transcription, released as open weights. Both models are designed for 13 languages: English, Chinese, Hindi, Spanish, Arabic, French, Portuguese, Russian, German, Japanese, Korean, Italian, and Dutch. Model family: batch and streaming, with clear roles Mistral positions Voxtral Transcribe 2 as ‘two next-generation speech-to-text models’ with state-of-the-art transcription quality, diarization, and ultra-low latency. Voxtral Mini Transcribe V2 is the batch model. It is optimized for transcription quality and diarization across domains and languages and exposed as an efficient audio input model in the Mistral API. Voxtral Realtime is the streaming model. It is built with a dedicated streaming architecture and is released as an open-weights model under Apache 2.0 on Hugging Face, with a recommended vLLM runtime. A key detail: speaker diarization is provided by Voxtral Mini Transcribe V2, not by Voxtral Realtime. Realtime focuses strictly on fast, accurate streaming transcription. Voxtral Realtime: 4B-parameter streaming ASR with configurable delay Voxtral Mini 4B Realtime 2602 is a 4B-parameter multilingual realtime speech-transcription model. It is among the first open-weights models to reach accuracy comparable to offline systems with a delay under 500 ms. Architecture: ≈3.4B-parameter language model. ≈0.6B-parameter audio encoder. The audio encoder is trained from scratch with causal attention. Both encoder and LM use sliding-window attention, enabling effectively “infinite” streaming. Latency vs accuracy is explicitly configurable: Transcription delay is tunable from 80 ms to 2.4 s via a transcription_delay_ms parameter. The Mistral describes latency as “configurable down to sub-200 ms” for live applications. At 480 ms delay, Realtime matches leading offline open-source transcription models and realtime APIs on benchmarks such as FLEURS and long-form English. At 2.4 s delay, Realtime matches Voxtral Mini Transcribe V2 on FLEURS, which is appropriate for subtitling tasks where slightly higher latency is acceptable. From a deployment standpoint: The model is released in BF16 and is designed for on-device or edge deployment. It can run in realtime on a single GPU with ≥16 GB memory, according to the vLLM serving instructions in the model card. The main control knob is the delay setting: Lower delays (≈80–200 ms) for interactive agents where responsiveness dominates. Around 480 ms as the recommended “sweet spot” between latency and accuracy. Higher delays (up to 2.4 s) when you need accuracy as close as possible to the batch model. Voxtral Mini Transcribe V2: batch ASR with diarization and context biasing Voxtral Mini Transcribe V2 is a closed-weights audio input model optimized only for transcription. It is exposed in the Mistral API as voxtral-mini-2602 at $0.003 per minute. On benchmarks and pricing: Around 4% word error rate (WER) on the FLEURS transcription benchmark, averaged over the top 10 languages. “Best price-performance of any transcription API” at $0.003/min. Outperforms GPT-4o mini Transcribe, Gemini 2.5 Flash, Assembly Universal, and Deepgram Nova on accuracy in their comparisons. Processes audio ≈3× faster than ElevenLabs’ Scribe v2 while matching quality at one-fifth the cost. Enterprise-oriented features are concentrated in this model: Speaker diarization Outputs speaker labels with precise start and end times. Designed for meetings, interviews, and multi-party calls. For overlapping speech, the model typically emits a single speaker label. Context biasing Accepts up to 100 words or phrases to bias transcription toward specific names or domain terms. Optimized for English, with experimental support for other languages. Word-level timestamps Per-word start and end timestamps for subtitles, alignment, and searchable audio workflows. Noise robustness Maintains accuracy in noisy environments such as factory floors, call centers, and field recordings. Longer audio support Handles up to 3 hours of audio in a single request. Language coverage mirrors Realtime: 13 languages, with Mistral noting that non-English performance “significantly outpaces competitors” in their evaluation. https://mistral.ai/news/voxtral-transcribe-2 APIs, tooling, and deployment options The integration paths are straightforward and differ slightly between the two models: Voxtral Mini Transcribe V2 Served via the Mistral audio transcription API (/v1/audio/transcriptions) as an efficient transcription-only service. Priced at $0.003/min. (Mistral AI) Available in Mistral Studio’s audio playground and in Le Chat for interactive testing. Voxtral Realtime Available via the Mistral API at $0.006/min. Released as open weights on Hugging Face (mistralai/Voxtral-Mini-4B-Realtime-2602) under Apache 2.0, with official vLLM Realtime support. The audio playground in Mistral Studio lets users: Upload up to 10 audio files (.mp3, .wav, .m4a, .flac, .ogg) up to 1 GB each. Toggle diarization, choose timestamp granularity, and configure context bias terms. Key Takeaways Two-model family with clear roles: Voxtral Mini Transcribe V2 targets batch transcription and diarization, while Voxtral Realtime targets low-latency streaming ASR, both across 13 languages. Realtime model- 4B parameters with tunable delay: Voxtral Realtime uses a 4B architecture (≈3.4B LM + ≈0.6B encoder) with sliding-window and causal attention, and supports configurable transcription delay from 80 ms to 2.4 s. Latency vs accuracy trade-off is explicit: Around 480 ms delay, Voxtral Realtime reaches accuracy comparable to strong offline and realtime systems, and at 2.4 s it matches Voxtral Mini Transcribe V2 on FLEURS. Batch model adds diarization and enterprise features: Voxtral Mini Transcribe V2 provides diarization, context biasing with up to 100 phrases, word-level timestamps, noise robustness, and supports up to 3 hours of audio per request at $0.003/min. Deployment- closed batch API, open realtime weights: Mini Transcribe V2 is served via Mistral’s audio transcription API and playground, while Voxtral Realtime is priced at $0.006/min and also available as Apache 2.0 open weights with official vLLM Realtime support. Check out the Technical details and Model Weights. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Mistral AI Launches Voxtral Transcribe 2: Pairing Batch Diarization And

Mistral AI Launches Voxtral Transcribe 2: Pairing Batch Diarization And Open Realtime ASR For Multilingual Production Workloads At Scale 投稿を読む »

AI, Committee, ニュース, Uncategorized

GFlowPO: Generative Flow Network as a Language Model Prompt Optimizer

arXiv:2602.03358v1 Announce Type: cross Abstract: Finding effective prompts for language models (LMs) is critical yet notoriously difficult: the prompt space is combinatorially large, rewards are sparse due to expensive target-LM evaluation. Yet, existing RL-based prompt optimizers often rely on on-policy updates and a meta-prompt sampled from a fixed distribution, leading to poor sample efficiency. We propose GFlowPO, a probabilistic prompt optimization framework that casts prompt search as a posterior inference problem over latent prompts regularized by a meta-prompted reference-LM prior. In the first step, we fine-tune a lightweight prompt-LM with an off-policy Generative Flow Network (GFlowNet) objective, using a replay-based training policy that reuses past prompt evaluations to enable sample-efficient exploration. In the second step, we introduce Dynamic Memory Update (DMU), a training-free mechanism that updates the meta-prompt by injecting both (i) diverse prompts from a replay buffer and (ii) top-performing prompts from a small priority queue, thereby progressively concentrating the search process on high-reward regions. Across few-shot text classification, instruction induction benchmarks, and question answering tasks, GFlowPO consistently outperforms recent discrete prompt optimization baselines.

GFlowPO: Generative Flow Network as a Language Model Prompt Optimizer 投稿を読む »

AI, Committee, ニュース, Uncategorized

Capturing Classic Authorial Style in Long-Form Story Generation with GRPO Fine-Tuning

arXiv:2512.05747v2 Announce Type: replace Abstract: Evaluating and optimising authorial style in long-form story generation remains challenging because style is often assessed with ad hoc prompting and is frequently conflated with overall writing quality. We propose a two-stage pipeline. First, we train a dedicated style-similarity judge by fine-tuning a sentence-transformer with authorship-verification supervision, and calibrate its similarity outputs into a bounded $[0,1]$ reward. Second, we use this judge as the primary reward in Group Relative Policy Optimization (GRPO) to fine-tune an 8B story generator for style-conditioned writing, avoiding the accept/reject supervision required by Direct Preference Optimization (DPO). Across four target authors (Mark Twain, Jane Austen, Charles Dickens, Thomas Hardy), the GRPO-trained 8B model achieves higher style scores than open-weight baselines, with an average style score of 0.893 across authors. These results suggest that AV-calibrated reward modelling provides a practical mechanism for controllable style transfer in long-form generation under a moderate model size and training budget.

Capturing Classic Authorial Style in Long-Form Story Generation with GRPO Fine-Tuning 投稿を読む »

AI, Committee, ニュース, Uncategorized

Proactive defense against LLM Jailbreak

arXiv:2510.05052v2 Announce Type: replace-cross Abstract: The proliferation of powerful large language models (LLMs) has necessitated robust safety alignment, yet these models remain vulnerable to evolving adversarial attacks, including multi-turn jailbreaks that iteratively search for successful queries. Current defenses, which are primarily reactive and static, often fail to handle these iterative attacks. In this paper, we introduce ProAct, a novel proactive defense framework designed to disrupt and mislead these iterative search jailbreak methods. Our core idea is to intentionally mislead these jailbreak methods into thinking that the model has been jailbroken with “spurious responses”. These misleading responses provide false signals to the attacker’s internal optimization loop, causing the adversarial search to terminate prematurely and effectively jailbreaking the jailbreak. By conducting extensive experiments across state-of-the-art LLMs, jailbreaking frameworks, and safety benchmarks, we demonstrate that our method consistently and significantly reduces attack success rates by up to 94% without affecting utility. When combined with other defense fraeworks, it further reduces the latest attack strategies’ success rate to 0%. ProActrepresents an orthogonal defense strategy that serves as an additional guardrail to enhance LLM safety against the most effective jailbreaking attacks.

Proactive defense against LLM Jailbreak 投稿を読む »

AI, Committee, ニュース, Uncategorized

TurkBench: A Benchmark for Evaluating Turkish Large Language Models

arXiv:2601.07020v2 Announce Type: replace Abstract: With the recent surge in the development of large language models, the need for comprehensive and language-specific evaluation benchmarks has become critical. While significant progress has been made in evaluating English-language models, benchmarks for other languages, particularly those with unique linguistic characteristics such as Turkish, remain less developed. Our study introduces TurkBench, a comprehensive benchmark designed to assess the capabilities of generative large language models in the Turkish language. TurkBench involves 8,151 data samples across 21 distinct subtasks. These are organized under six main categories of evaluation: Knowledge, Language Understanding, Reasoning, Content Moderation, Turkish Grammar and Vocabulary, and Instruction Following. The diverse range of tasks and the culturally relevant data would provide researchers and developers with a valuable tool for evaluating their models and identifying areas for improvement. We further publish our benchmark for online submissions at https://huggingface.co/turkbench

TurkBench: A Benchmark for Evaluating Turkish Large Language Models 投稿を読む »

AI, Committee, ニュース, Uncategorized

Pursuing Best Industrial Practices for Retrieval-Augmented Generation in the Medical Domain

arXiv:2602.03368v1 Announce Type: new Abstract: While retrieval augmented generation (RAG) has been swiftly adopted in industrial applications based on large language models (LLMs), there is no consensus on what are the best practices for building a RAG system in terms of what are the components, how to organize these components and how to implement each component for the industrial applications, especially in the medical domain. In this work, we first carefully analyze each component of the RAG system and propose practical alternatives for each component. Then, we conduct systematic evaluations on three types of tasks, revealing the best practices for improving the RAG system and how LLM-based RAG systems make trade-offs between performance and efficiency.

Pursuing Best Industrial Practices for Retrieval-Augmented Generation in the Medical Domain 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja