YouZum

Nachrichten

AI, Committee, Nachrichten, Uncategorized

The balcony solar boom is coming to the US

Dozens of US states are considering legislation to allow people to install plug-in solar systems, often called balcony solar. These small arrays require little to no setup and could help cut emissions and power bills. Balcony solar is already popular in Europe, and proponents say that the systems could make solar power more accessible for more people in the US, including renters. As popularity rises, though, some experts caution that there are safety concerns with how balcony solar would work with existing electrical equipment in homes. Let’s talk about what balcony solar is, why it’s unique, and how new testing requirements could affect our progress toward deploying the technology in the US. Plug-in solar systems are designed to be simple to install, often requiring no electrician or specialized worker at all. They’re small, and many can be plugged into existing outlets. People across Germany have installed over a million balcony solar systems. They generally measure up to roughly two square meters or about 20 square feet, and can generate up to 800 watts—enough to power a standard microwave. Now the plug-in solar wave is coming to the US. Many Americans have already installed DIY balcony solar without the permission of their utilities—it’s something of a regulatory gray area. In late 2025, Utah became the first state to explicitly allow people to install and use balcony solar systems. Over two dozen other states are now considering similar legislation. Generally, utilities require users to sign an interconnection agreement before they can plug in large arrays of solar panels that generate power for the grid. There can be fees and permits, and it all amounts to an expensive and lengthy process. Utah’s law ditched the interconnection requirement for panels that have a low power cap and that are certified by a national testing facility. (Legislation under consideration in other states, including New York, includes the same requirements.) The thinking is that since the panels produce very little power, which would be used to meet a home’s own energy demand and probably not get sent back to the grid, the same requirements shouldn’t apply.  As for that certification piece, in January the national testing and certification lab UL Solutions released UL 3700, a testing protocol to certify balcony solar systems and ensure that they’re safe.  There are three main safety considerations to address for these plug-in solar systems, says Joseph Bablo, manager of principal engineering, energy, and industrial automation at UL Solutions. First, there’s the possibility of overloading a circuit. Generally, electrical circuits have circuit breakers, which can trip and interrupt current if necessary. But if there’s a solar panel adding extra power to a circuit, a traditional breaker might not be able to respond to overload. Over time, overloaded circuits can damage equipment or even start a fire.  Second, these small systems are typically installed on the outside of homes, and outdoor power outlets generally have ground fault circuit interruption (GFCI). Basically, if an outlet or its surroundings are wet, it can shut down to prevent electric shock. Many GFCI systems may not work if there’s power going back into an outlet from a solar panel. Finally, there’s touch safety: If a plug gets disconnected from the wall, the blades of the plug may still have power running through them for a short time. If a panel is getting sunlight, those blades could be energized for longer than is typical. The new UL Solutions testing framework aims to address these concerns. One of the key recommendations is that plug-in solar panels should use a special outlet that’s designed specifically for them. The safety measures included in that connection, and within a panel, would ensure that the panels are safe. The need for a special outlet means that currently, people who want to plug in a solar panel array would probably need to have an electrician come and update their wiring in order to comply with the protocol, Bablo says. “I know they want to say ‘No electrician, no permits’—we’re not there.” Today, anyone can buy products like solar panels and inverters, some of which carry their own component UL certifications, and string them together. (Inverters are covered under UL 1741, for example.) But the gold standard is to have an entire system that meets the safety requirements, and that means adhering to the new standard, Bablo says. As of early May, there aren’t any plug-in solar systems that have been fully certified by UL Solutions. And Bablo said he couldn’t share information about what, if any, are in the pipeline.   Even with the new certification requirements, Bablo still thinks plug-in solar still has the potential to help more people access the technology. “There’s a way for it to work, but we want it to work safely,” he says. This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

The balcony solar boom is coming to the US Beitrag lesen »
AI, Committee, Nachrichten, Uncategorized

The Download: the tech reshaping IVF and the rise of balcony solar

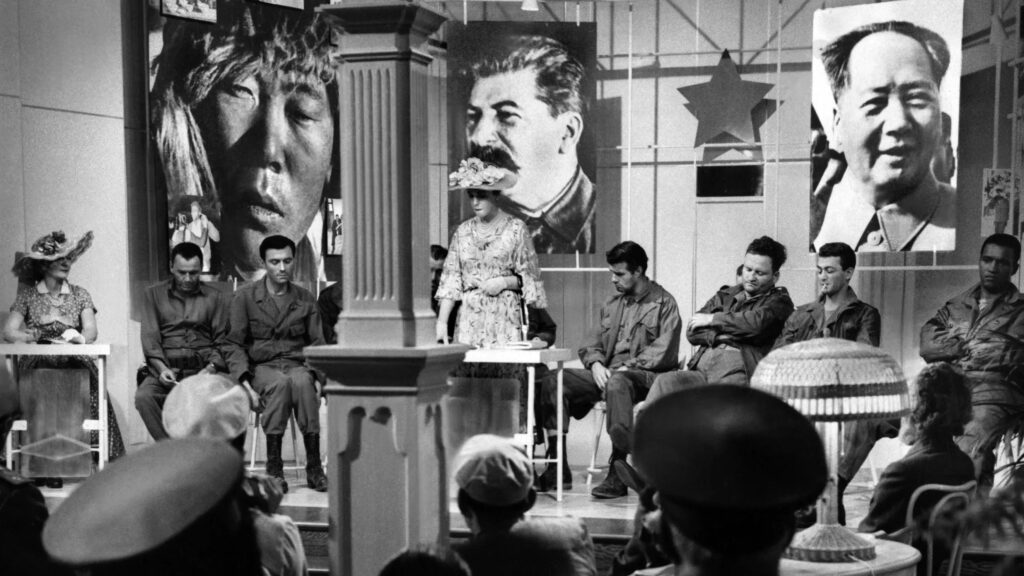
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. What’s next for IVF IVF has brought millions of babies into the world over the last four decades. But the process can still be slow, painful, and expensive—and far from guaranteed to work. Now, a wave of new technologies aims to change that.  Researchers are using AI to identify promising sperm and embryos, developing robotic systems that could automate parts of the IVF process, and even exploring controversial genetic editing techniques designed to prevent inherited disease. The technologies could make IVF more effective and accessible. But they’re also raising difficult ethical questions about how far reproductive medicine should go. Find out what’s next for IVF. —Jessica Hamzelou This story is from MIT Technology Review’s What’s Next series, which looks across industries, trends, and technologies to give you a first look at the future. You can read the rest of them here. The balcony solar boom is coming to the US Dozens of US states are considering legislation to allow people to install plug-in solar systems, often called balcony solar. These small arrays require little to no setup and could help cut emissions and power bills. Proponents say the systems could make solar power more accessible, but some experts caution that there are safety concerns.  Read the full story on balcony solar’s potentially massive impact in the US. —Casey Crownhart This article is from The Spark, our weekly climate newsletter. Sign up to receive it in your inbox every Wednesday. Resistance: 10 Things That Matter in AI Right Now Resistance against AI’s proliferation is growing. People from all walks of life are speaking out against rising electricity bills from data centers, disappearing jobs, chatbots’ impact on teen mental health, the military’s use of AI, and copyright infringement—among other concerns.  People want to have a say in how the technology transforms their future. And they’re starting to create small cracks in AI labs’ vision for the future. Find out how. —Michelle Kim Resistance is on our list of the 10 Things That Matter in AI Right Now, MIT Technology Review’s guide to what’s really worth your attention in the buzzy world of AI.  The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 After years of insults, Anthropic and SpaceX have teamed upAnthropic will tap SpaceX’s GPUs to meet surging demand. (Axios)+ While SpaceX gets a marquee customer for its AI ambitions. (Wired $)+ Anthropic says the deal will double Claude Code’s rate limits. (Ars Technica)+It’s also exploring building compute capacity in space. (CNBC)+ Musk previously called Anthropic “evil” and “misanthropic.” (Gizmodo) 2 Ex-OpenAI leaders say Sam Altman sowed “chaos” and distrustFormer CTO Mira Murati said she couldn’t trust his words. (The Verge)+ He also bypassed OpenAI’s safety board before a model release. (Gizmodo)+ And pitted leaders against one another. (Forbes)+ But Elon Musk still tried to recruit Altman to lead a Tesla AI lab. (FT $)+ Here’s why Musk and Altman are in court. (MIT Technology Review) 3 China’s humanoid robots are fueling its next export boomMorgan Stanley says Beijing has taken an early lead in the sector. (Bloomberg $)+ Gig workers are training humanoids at home. (MIT Technology Review) 4 SpaceX’s IPO plans will give Elon Musk “virtually unchecked” authorityAnd erode typical shareholder protections. (Reuters $)+ Activists and pension funds are pushing back against the IPO. (Wired $)+ While SpaceX is shifting focus from Falcon 9 to Starship. (Ars Technica) 5 Google DeepMind will use the MMORPG Eve Online for AI model testingIt’s also bought a stake in the game’s maker. (Ars Technica)+ DeepMind also recently built a new video-game-playing agent. (MIT Technology Review) 6 The US risks isolating its automakers by banning a Chinese EV standardIt’s prohibiting software that’s dominating global EV markets. (Rest of World) 7 Elon Musk’s proposed Texas chip factory could cost $119 billionIt would manufacture chips for Tesla, SpaceX, and xAI. (CNBC)+ Future AI chips could be built on glass. (MIT Technology Review) 8 Why the “attention-span crisis” is misunderstoodTechnology may be exhausting attention rather than shortening it. (Atlantic $) 9 Scientists are getting closer to explaining what causes lightningNew tools are revealing unexpected physics inside thunderstorms. (Quanta) 10 Kids have found an age verification loophole: fake mustachesResourceful children are foiling blocks on adult websites. (TechCrunch) Quote of the day “My concern was about Sam saying one thing to one person and completely the opposite to another person.” —Mira Murati, the former CTO of OpenAI, testifies ‌in court that CEO Sam Altman was deceptive, Reuters reports. One More Thing ALAMY A brief, weird history of brainwashing During the Cold War, the US prepared for a psychic war with the Soviet Union and China by spending millions of dollars on research into manipulating the human brain.  The science never exactly panned out, but residual beliefs fostered by this bizarre conflict continue to play a role in ideological and scientific debates to this day. And now, new technologies are altering how we think about mind control.  This is how the race for mind control changed America forever. —Annalee Newitz We can still have nice things A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Listen to the 10 bird songs of spring in this lovely compilation of American species.+ Good Samaritans saved a 29-foot whale that had wandered too far into a river.+ Explore the intersection of human emotion and machine learning in this look at AI’s influence on art.+ Break down the walls between streaming services and manage all your digital music in one place with this app.

The Download: the tech reshaping IVF and the rise of balcony solar Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Safety and accuracy follow different scaling laws in clinical large language models

arXiv:2605.04039v1 Announce Type: new Abstract: Clinical LLMs are often scaled by increasing model size, context length, retrieval complexity, or inference-time compute, with the implicit expectation that higher accuracy implies safer behavior. This assumption is incomplete in medicine, where a few confident, high-risk, or evidence-contradicting errors can matter more than average benchmark performance. We introduce SaFE-Scale, a framework for measuring how clinical LLM safety changes across model scale, evidence quality, retrieval strategy, context exposure, and inference-time compute. To instantiate this framework, we introduce RadSaFE-200, a Radiology Safety-Focused Evaluation benchmark of 200 multiple-choice questions with clinician-defined clean evidence, conflict evidence, and option-level labels for high-risk error, unsafe answer, and evidence contradiction. We evaluated 34 locally deployed LLMs across six deployment conditions: closed-book prompting (zero-shot), clean evidence, conflict evidence, standard RAG, agentic RAG, and max-context prompting. Clean evidence produced the strongest improvement, increasing mean accuracy from 73.5% to 94.1%, while reducing high-risk error from 12.0% to 2.6%, contradiction from 12.7% to 2.3%, and dangerous overconfidence from 8.0% to 1.6%. Standard RAG and agentic RAG did not reproduce this safety profile: agentic RAG improved accuracy over standard RAG and reduced contradiction, but high-risk error and dangerous overconfidence remained elevated. Max-context prompting increased latency without closing the safety gap, and additional inference-time compute produced only limited gains. Worst-case analysis showed that clinically consequential errors concentrated in a small subset of questions. Clinical LLM safety is therefore not a passive consequence of scaling, but a deployment property shaped by evidence quality, retrieval design, context construction, and collective failure behavior.

Safety and accuracy follow different scaling laws in clinical large language models Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

A Comparison of Traditional Machine Learning Algorithms and LSTM-Based Deep Learning Models for Email Sentiment Analysis

arXiv:2605.03440v1 Announce Type: new Abstract: The rapid growth of electronic communication has necessitated more robust systems for email classification and sentiment detection. This study presents a comparative performance analysis between traditional machine learning algorithms and deep learning architectures, specifically focusing on Support Vector Machines (SVMs), Logistic Regression, Naive Bayes, and Long Short-Term Memory (LSTM). Utilizing Word2Vec embeddings for feature representation, our experimental results indicate that the SVM model with a linear kernel achieves the highest efficiency and accuracy, reaching a peak performance of 98.74%. While the LSTM model demonstrates exceptional recall capabilities in detecting spam-related sentiments, it requires significantly more computational time compared to discriminative statistical models. Detailed evaluations via confusion matrices further reveal that traditional classifiers remain highly robust for dense vector spaces. This research concludes that for email detection tasks, SVM offers the most optimal balance between predictive precision and processing speed. These findings provide critical insights for developing high-performance automated email filtering systems in professional and academic environments.

A Comparison of Traditional Machine Learning Algorithms and LSTM-Based Deep Learning Models for Email Sentiment Analysis Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

How to Build a Fully Interactive Multi-Page NiceGUI Application with Real-Time Dashboard, CRUD Operations, File Upload, and Async Chat

In this tutorial, we build a fully interactive, multi-page web application using NiceGUI. We start by setting up the environment and designing a reusable layout that includes navigation, theming, and dark mode support. As we move forward, we implement a live dashboard with real-time metrics and charts, demonstrating reactive bindings and timed updates. We then extend the application with a complete CRUD-based todo system, followed by a validated form with dialogs and user feedback mechanisms. We also incorporate file upload functionality with dynamic previews and conclude the feature set with an asynchronous chat interface that simulates real-time interaction. Also, we ensure that the app runs seamlessly in Colab by using background threading and dynamic port allocation. Copy CodeCopiedUse a different Browser import sys import subprocess subprocess.run([sys.executable, “-m”, “pip”, “install”, “-q”, “nicegui”], check=True) import threading, time, random, asyncio, base64, socket from datetime import datetime from nicegui import ui, events class State: def __init__(self): self.todos = [ {“id”: 1, “task”: “Explore NiceGUI”, “done”: True, “priority”: “High”}, {“id”: 2, “task”: “Build a dashboard”, “done”: False, “priority”: “Medium”}, {“id”: 3, “task”: “Deploy to production”, “done”: False, “priority”: “Low”}, ] self.next_id = 4 self.metrics = {“users”: 1247, “revenue”: 8420, “orders”: 53} self.series = [random.uniform(20, 80) for _ in range(20)] self.messages = [{“role”: “assistant”, “text”: “Hi! Type something and I will echo it back.”}] state = State() def page_shell(active: str) -> None: dark = ui.dark_mode() drawer = ui.left_drawer(value=True).classes(“bg-grey-2”) with drawer: ui.label(“Navigation”).classes(“text-lg font-bold p-2”) for label, path, icon in [ (“Dashboard”, “/”, “dashboard”), (“Todos”, “/todos”, “check_circle”), (“Form”, “/form”, “edit_note”), (“Upload”, “/upload”, “upload_file”), (“Chat”, “/chat”, “chat”), ]: cls = “w-full” + (” bg-primary text-white” if label == active else “”) ui.button(label, on_click=lambda p=path: ui.navigate.to(p), icon=icon).classes(cls).props(“flat align=left no-caps”) with ui.header(elevated=True).classes(“items-center justify-between bg-primary”): with ui.row().classes(“items-center”): ui.button(on_click=drawer.toggle, icon=”menu”).props(“flat color=white”) ui.label(” NiceGUI Tutorial”).classes(“text-xl font-semibold text-white”) ui.button(icon=”dark_mode”, on_click=dark.toggle).props(“flat color=white”) with ui.footer().classes(“bg-grey-3 text-black justify-center”): ui.label(“Built with NiceGUI · Tutorial Demo”) We install and import all required libraries, then initialize our application state. We define a central State class to manage todos, metrics, chart data, and chat messages across the app. We also built a reusable layout function that provides navigation, a header, a footer, and dark mode support for all pages. Copy CodeCopiedUse a different Browser @ui.page(“/”) def dashboard(): page_shell(“Dashboard”) with ui.column().classes(“w-full p-6 gap-6”): ui.label(“Live Dashboard”).classes(“text-3xl font-bold”) with ui.row().classes(“gap-4 flex-wrap”): for key, label, color, icon in [ (“users”, “Users”, “primary”, “group”), (“revenue”, “Revenue”, “positive”, “attach_money”), (“orders”, “Orders”, “warning”, “shopping_cart”), ]: with ui.card().classes(“w-60”): with ui.row().classes(“items-center justify-between w-full”): ui.label(label).classes(“text-gray-500″) ui.icon(icon, size=”md”).classes(f”text-{color}”) ui.label().classes(f”text-3xl font-bold text-{color}”) .bind_text_from(state.metrics, key, backward=lambda v: f”{v:,}”) with ui.card().classes(“w-full”): ui.label(“Live stream (updates every second)”).classes(“text-lg font-semibold”) chart = ui.echart({ “tooltip”: {“trigger”: “axis”}, “xAxis”: {“type”: “category”, “data”: list(range(len(state.series)))}, “yAxis”: {“type”: “value”}, “series”: [{“data”: list(state.series), “type”: “line”, “smooth”: True, “areaStyle”: {}}], }).classes(“h-64 w-full”) def tick(): state.series.append(random.uniform(20, 80)) state.series.pop(0) chart.options[“series”][0][“data”] = list(state.series) chart.update() state.metrics[“users”] += random.randint(-2, 4) state.metrics[“revenue”] += random.randint(-100, 200) state.metrics[“orders”] = max(0, state.metrics[“orders”] + random.randint(-1, 3)) ui.timer(1.0, tick) We create the dashboard page and structure it with responsive UI components. We bind metric cards directly to the state to enable automatic updates and display real-time values. We also implement a live chart using ECharts and dynamically update both the chart and the metrics using a timer. Copy CodeCopiedUse a different Browser @ui.page(“/todos”) def todos_page(): page_shell(“Todos”) with ui.column().classes(“w-full p-6 gap-4 max-w-4xl mx-auto”): ui.label(“Todos”).classes(“text-3xl font-bold”) with ui.card().classes(“w-full”): with ui.row().classes(“w-full items-center gap-2″): task_input = ui.input(placeholder=”What needs doing?”).classes(“flex-grow”) priority_sel = ui.select([“Low”, “Medium”, “High”], value=”Medium”).classes(“w-36”) def add_todo(): if not task_input.value or not task_input.value.strip(): ui.notify(“Task cannot be empty”, type=”warning”); return state.todos.append({ “id”: state.next_id, “task”: task_input.value.strip(), “done”: False, “priority”: priority_sel.value, }) state.next_id += 1 task_input.value = “” todo_list.refresh() ui.notify(“Added!”, type=”positive”) ui.button(“Add”, icon=”add”, on_click=add_todo).props(“color=primary”) task_input.on(“keydown.enter”, add_todo) @ui.refreshable def todo_list(): if not state.todos: ui.label(“Nothing here yet “).classes(“text-gray-500”); return for todo in state.todos: with ui.card().classes(“w-full”): with ui.row().classes(“w-full items-center gap-3”): ui.checkbox(value=todo[“done”], on_change=lambda e, t=todo: t.update(done=e.value)) lbl = ui.label(todo[“task”]).classes(“flex-grow text-lg”) if todo[“done”]: lbl.style(“text-decoration: line-through; opacity: 0.5”) color = {“High”: “red”, “Medium”: “orange”, “Low”: “green”}[todo[“priority”]] ui.badge(todo[“priority”], color=color) def make_del(t=todo): def _del(): state.todos.remove(t) todo_list.refresh() ui.notify(“Removed”, type=”info”) return _del ui.button(icon=”delete”, on_click=make_del()) .props(“flat color=red round dense”) todo_list() We implement a complete CRUD-based todo system with add, update, and delete functionality. We handle user input validation and dynamically refresh the UI using NiceGUI’s refreshable components. We also enhance the UI with checkboxes, badges, and notifications to improve interactivity and feedback. Copy CodeCopiedUse a different Browser @ui.page(“/form”) def form_page(): page_shell(“Form”) with ui.column().classes(“w-full p-6 max-w-2xl mx-auto gap-4”): ui.label(“Profile Form”).classes(“text-3xl font-bold”) with ui.card().classes(“w-full gap-2”): name = ui.input(“Name”, validation={“Required”: lambda v: bool(v)}) email = ui.input(“Email”, validation={“Must be an email”: lambda v: “@” in (v or “”)}) age = ui.number(“Age”, value=18, min=0, max=120) ui.label(“Subscription plan”).classes(“mt-2 text-gray-600”) plan = ui.radio([“Free”, “Pro”, “Enterprise”], value=”Free”).props(“inline”) agree = ui.checkbox(“I accept the terms”) async def submit(): if not (name.value and “@” in (email.value or “”) and agree.value): ui.notify(“Please fix the form first”, type=”negative”); return with ui.dialog() as d, ui.card(): ui.label(“Submitted!”).classes(“text-xl font-bold”) ui.label(f”Name: {name.value}”) ui.label(f”Email: {email.value}”) ui.label(f”Age: {age.value}”) ui.label(f”Plan: {plan.value}”) ui.button(“OK”, on_click=d.close).props(“color=primary”) d.open() ui.button(“Submit”, on_click=submit).props(“color=primary”) @ui.page(“/upload”) def upload_page(): page_shell(“Upload”) with ui.column().classes(“w-full p-6 max-w-3xl mx-auto gap-4”): ui.label(“File Upload”).classes(“text-3xl font-bold”) result = ui.column().classes(“w-full”) def handle_upload(e: events.UploadEventArguments): content = e.content.read() with result: with ui.card().classes(“w-full”): ui.label(f” {e.name}”).classes(“font-semibold”) ui.label(f”Size: {len(content):,} bytes · type: {e.type}”) if e.type and e.type.startswith(“image/”): b64 = base64.b64encode(content).decode() ui.image(f”data:{e.type};base64,{b64}”).classes(“w-64 rounded”) else: try: ui.code(content[:500].decode(“utf-8″, errors=”replace”)) except Exception: pass ui.notify(f”Uploaded {e.name}”, type=”positive”) ui.upload(on_upload=handle_upload, multiple=True, auto_upload=True).classes(“w-full”) We build a form with validation rules and handle submission using an asynchronous function. We display user input in a dialog upon successful submission and ensure proper validation before processing. We also implement a file upload feature that supports multiple files and provides image previews and content previews for other file types. Copy CodeCopiedUse a different Browser @ui.page(“/chat”) def chat_page(): page_shell(“Chat”) with ui.column().classes(“w-full p-6 max-w-3xl mx-auto gap-4”): ui.label(“Chat (echo bot)”).classes(“text-3xl font-bold”) @ui.refreshable def chat_log(): for m in state.messages: ui.chat_message( m[“text”], name=”You” if m[“role”] == “user” else “Bot”, sent=m[“role”] == “user”, stamp=datetime.now().strftime(“%H:%M”), ) with ui.card().classes(“w-full”): chat_log() async def send(): text = (entry.value or “”).strip() if not text: return state.messages.append({“role”: “user”, “text”: text}) entry.value = “” chat_log.refresh() await asyncio.sleep(1) reply = f’You said: “{text}” — that is {len(text)} characters!’ state.messages.append({“role”: “assistant”, “text”: reply}) chat_log.refresh() with ui.row().classes(“w-full items-center”): entry = ui.input(placeholder=”Type a message…”) .classes(“flex-grow”).on(“keydown.enter”, send)

How to Build a Fully Interactive Multi-Page NiceGUI Application with Real-Time Dashboard, CRUD Operations, File Upload, and Async Chat Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Google AI Releases Multi-Token Prediction (MTP) Drafters for Gemma 4: Delivering Up to 3x Faster Inference Without Quality Loss

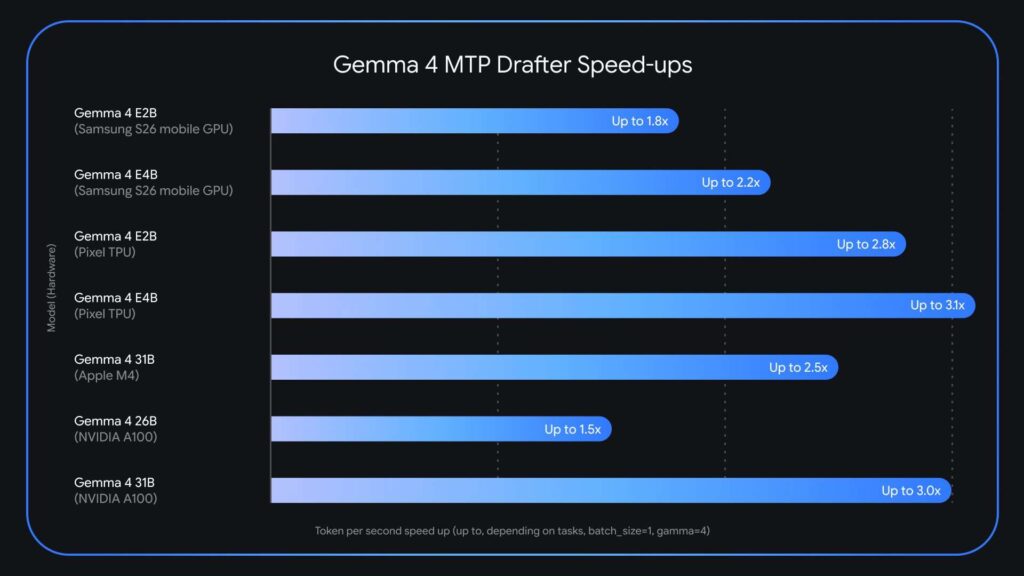
Large language models are getting incredibly powerful, but let’s be honest—their inference speed is still a massive headache for anyone trying to use them in production. Google just launched Multi-Token Prediction (MTP) drafters for the Gemma 4 model family. This specialized speculative decoding architecture can actually triple (3x) your speed at inference time, all without sacrificing a bit of output quality or reasoning accuracy. The release comes just weeks after Gemma 4 surpassed 60 million downloads and directly targets one of the most persistent pain points in deploying large language models: the memory-bandwidth bottleneck that slows token generation regardless of hardware capability. https://blog.google/innovation-and-ai/technology/developers-tools/multi-token-prediction-gemma-4/?linkId=61725841 Why LLM Inference is Slow? Today’s large language models operate autoregressively. They produce exactly one token at a time, sequentially. Every single token generation requires loading billions of model parameters from VRAM (video RAM) into compute units. This process is described as memory-bandwidth bound. The bottleneck is not the raw computing power of the GPU or processor, but the speed at which data can be transferred from memory to the compute units. The consequence is a significant latency bottleneck: compute sits underutilized while the system is busy just moving data around. What makes this especially inefficient is that the model applies the same amount of computation to a trivially predictable token like predicting “words” after “Actions speak louder than…” as it does to generating a complex logical inference. There’s no mechanism in standard autoregressive decoding to exploit how easy or hard the next token is to predict. What is Speculative Decoding? Speculative decoding is the foundational technique that Gemma 4’s MTP drafters are built on. The technique decouples token generation from verification by pairing two models: a lightweight drafter and a heavy target model. Here’s how the pipeline works in practice. The small, fast drafter model proposes several future tokens in rapid succession — a “draft” sequence — in less time than the large target model (e.g., Gemma 4 31B) takes to process even a single token. The target model then verifies all of these suggested tokens in parallel in a single forward pass. If the target model agrees with the draft, it accepts the entire sequence — and even generates one additional token of its own in the process. This means an application can output the full drafted sequence plus one extra token in roughly the same wall-clock time it would normally take to generate just one token. Since the primary Gemma 4 model retains the final verification step, the output is identical to what the target model would have produced on its own, token-by-token. There is no quality tradeoff — it is a lossless speedup. MTP: What’s New in the Gemma 4 Drafter Architecture Google has introduced several architectural enhancements that make the Gemma 4 MTP drafters particularly efficient. The draft models seamlessly utilize the target model’s activations and share its KV cache (key-value cache). The KV cache is a standard optimization in transformer inference that stores intermediate attention computations so they don’t need to be recalculated on every step. By sharing this cache, the drafter avoids wasting time recomputing context that the larger target model has already processed. Additionally, for the E2B and E4B edge models, the smallest Gemma 4 variants designed to run on mobile and edge devices — Google implemented an efficient clustering technique in the embedder layer. This specifically addresses a bottleneck prominent on edge hardware: the final logit calculation, which maps internal model representations to vocabulary probabilities. The clustering approach accelerates this step, improving end-to-end generation speed on hardware-constrained devices. For hardware-specific performance, the Gemma 4 26B mixture-of-experts (MoE) model presents unique routing challenges on Apple Silicon at a batch size of 1. However, increasing the batch size to between 4 and 8 unlocks up to a ~2.2x speedup locally. Similar batch-size-dependent gains are observed on NVIDIA A100 hardware. Key Takeaways Google has released Multi-Token Prediction (MTP) drafters for the Gemma 4 model family, delivering up to 3x faster inference speeds without any degradation in output quality or reasoning accuracy. MTP drafters use a speculative decoding architecture that pairs a lightweight drafter model with a heavy target model — the drafter proposes several tokens at once, and the target model verifies them all in a single forward pass, breaking the one-token-at-a-time bottleneck. The draft models share the target model’s KV cache and activations, and for E2B and E4B edge models, an efficient clustering technique in the embedder addresses the final logit calculation bottleneck — enabling faster generation even on memory-constrained devices. MTP drafters are available now under the Apache 2.0 license, with model weights on Hugging Face and Kaggle. Check out the Model Weights and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 130k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Google AI Releases Multi-Token Prediction (MTP) Drafters for Gemma 4: Delivering Up to 3x Faster Inference Without Quality Loss appeared first on MarkTechPost.

Google AI Releases Multi-Token Prediction (MTP) Drafters for Gemma 4: Delivering Up to 3x Faster Inference Without Quality Loss Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The Download: seafloor science and military chatbots

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Inexpensive seafloor-hopping submersibles could stoke deep-sea science—and mining Last week, two oblong neon submersibles started to descend nearly 6,000 meters into the Pacific Ocean. Throughout the rest of May, they will map the seafloor in search of critical mineral deposits.  If all goes well, the vehicles, built by Orpheus Ocean, could help scientists probe the vastly understudied deep sea—and the resources it holds—at a fraction of the cost of existing systems. But the same submersibles are also attracting deep-sea mining companies, raising concerns about environmental impacts. Find out why they’re drawing so much attention. —Hannah Richter The new war room: 10 Things That Matter in AI Right Now  A new kind of system has entered the war room: conversational AI tools that commanders turn to not just for analysis, but for advice.  One US defense official told MIT Technology Review that personnel might give these advice engines a list of potential targets to help decide which to strike first. China is commissioning similar tools too. But as the systems gain traction, they’re also sparking concerns about AI-generated errors, a lack of transparency, and Big Tech gaining undue influence over what information gets seen.  Here’s how these AI advice engines could impact the battlefield. —James O’Donnell The new war room is one of the 10 Things That Matter in AI Right Now, our list of the big ideas, trends, and advances in the field that are driving progress today—and will shape what’s possible tomorrow. MIT Technology Review Narrated: is fake grass a bad idea? The AstroTurf wars are far from over.  In 2001, Americans installed just over 7 million square meters of synthetic turf. By 2024, that number was 79 million square meters—enough to carpet all of Manhattan and then some. The increase worries folks who study microplastics and environmental pollution.   While the plastic-making industry insists that synthetic fields are safe if properly installed, lots of researchers think that isn’t so.  —Douglas Main  This is our latest story to be turned into an MIT Technology Review Narrated podcast, which we publish each week on Spotify and Apple Podcasts. Just navigate to MIT Technology Review Narrated on either platform, and follow us to get all our new content as it’s released. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Elon Musk pushed OpenAI to go commercial, its president has testifiedGreg Brockman said Musk tried to turn it into a for-profit company years ago. (NYT $)+ Musk allegedly wanted full control so he could raise $80 billion to colonize Mars. (Reuters $)+ The Tesla CEO claims he intended for OpenAI to remain a non-profit. (BBC)+ Here’s what happened in week one of Musk v. Altman. (MIT Technology Review) 2 Google and Meta are building AI agents to rival OpenClawGoogle’s Gemini agent will take actions on the users’ behalf. (Business Insider)+ Meta’s will be powered by its Muse Spark AI model. (FT $)+ Hustlers are cashing in on China’s OpenClaw AI craze. (MIT Technology Review) 3 Anthropic will spend $200 billion on Google’s cloud and chipsThe investment will be spread across five years. (The Information $)+ It’s part of a broader AI compute war. (Axios)  4 DeepSeek is nearing a $45 billion valuationA state-backed “Big Fund” will lead a new investment round in the company. (FT $)+ Beijing is pushing to build alternatives to Nvidia and OpenAI. (Bloomberg $)+ Here’s why DeepSeek’s new model matters. (MIT Technology Review) 5 Anthropic is launching AI agents for banks and financial firmsThe 10 tools cover a broad mix of financial services tasks. (WSJ $)+ They’re part of a push to win over Wall Street. (Bloomberg $) 6 Apple will pay $250 million to settle an AI lawsuitIt was accused of misleading iPhone buyers about Apple Intelligence. (BBC)+ Some iPhone owners are eligible to receive up to $95. (NYT $) 7 Cheap laptops and phones may be disappearing because of AI demand Competition for memory chips is driving up gadget prices worldwide. (The Guardian) 8 Google DeepMind workers in the UK have voted to unionizeAs a result of Google’s work with the Pentagon. (Wired $) 9 Pennsylvania is suing Character.AI over chatbots posing as doctorsInvestigators say the bots claimed to hold medical licenses. (NPR)+ How well do AI health tools work? (MIT Technology Review) 10 Scientists created a “living” plastic that destroys itself on commandIt could help to eliminate microplastics. (Gizmodo) Quote of the day “I want AI to benefit humanity, not to facilitate a genocide.”  —An anonymous Google DeepMind worker tells the Guardian that Google’s work with the Israel Defense Forces had motivated their vote to unionize. One More Thing COURTESY OF BENEATH THE WAVES How tracking animal movement may save the planet For decades, wildlife researchers have dreamed of building an “Internet of Animals”—a big-data system that monitors and analyzes animal behavior to help us understand the planet. Advances in sensors, AI, and satellite technology are now bringing that vision to reality. Scientists want the system to track 100,000 sensor-tagged animals. They believe it could reveal how species respond to climate change and ecosystem loss—and even predict environmental disasters. Read the full story on how their idea could save our planet. —Matthew Ponsford We can still have nice things A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Master the art of fried chicken with this definitive chef’s guide.+ Find out why some birds hop and others walk in this breakdown of avian lifestyles.+ This vintage Hollywood map shows how California’s landscape stood in for everything from the Nile to the Alps.+ Here’s a fascinating look at the “Flatbed” airplane that was surprisingly efficient on paper but never left the hangar.

The Download: seafloor science and military chatbots Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

A blueprint for using AI to strengthen democracy

Every few centuries, changes in how information moves reshape how societies govern themselves. The printing press spread vernacular literacy, helping give rise to the Reformation and, eventually, representative government. The telegraph made it possible to administer vast nations like the US, accelerating the growth of the modern bureaucratic state. Broadcast media created shared national audiences, which in turn fueled mass democracy. We are now in the early stages of another such shift. Faster than many realize, AI is becoming the primary interface through which we form beliefs and participate in democratic self-governance. If left unchecked, this shift could further strain America’s already fragile institutions. But it could also help address long-standing problems, like lagging civic engagement and deepening polarization. What happens next depends on design choices that are already being made, whether we know it or not. Start with what might be called the epistemic layer—how we come to know things. People are increasingly relying on AI to know what is true, what is happening, and whom to trust. Search is already substantially AI-mediated. The next generation of AI assistants will synthesize information, frame it, and present it with authority. For a growing number of people, asking an AI will become the default way to form views on a candidate, a policy, or a public figure. Whoever controls what these models say therefore has increasing influence over what people believe.  Technology has always shaped the way citizens interact with information. But a new problem will soon arise in the form of personal AI agents, which can change not only how people receive information but how they act on it. These systems will conduct research, draft communications, highlight causes, and lobby on a user’s behalf. They will inform decisions such as how to vote on a ballot measure, which organizations are worth supporting, or how to respond to a government notice. They will, in a meaningful sense, begin to mediate the relationship between individuals and the institutions that govern them. We’ve already seen with social media what happens when algorithms optimize for engagement over understanding. Platforms do not need to have an explicit political agenda to produce polarization and radicalization. An agent that knows your preferences and your anxieties—one shaped to keep you engaged—poses the same risks. And in this case the risks may be even more difficult to detect, because an agent presents itself as your advocate. It speaks for you, acts on your behalf, and may earn trust precisely through that intimacy. Now zoom out to the collective. AI agents and humans could soon participate in the same forums, where it may be impossible to tell them apart. Even if every individual AI agent were well-designed and aligned with its user’s interests, the interactions of millions of agents could produce outcomes that no individual wanted or chose. For example, research shows that agents displaying no individual bias can still generate collective biases at scale. And setting aside what agents do to each other, there is what they do for their users. A public sphere in which everyone has a personalized agent attuned to their existing views is not, in aggregate, a public sphere at all. It is a collection of private worlds, each internally coherent but collectively inhospitable to the kind of shared deliberation that democracy requires. Taken together, these three transformations—in how we know, how we act, and how we engage in collective governance—amount to a fundamental change in the texture of citizenship. In the near future, people will form their political views through AI filters, exercise their civic agency through AI agents, and participate in institutions and public discussions that are themselves shaped by the interactions of millions of such agents. Today’s democracy is not ready for this. Our institutions were designed for a world in which power was exercised visibly, information traveled slowly enough to be contested, and reality felt more shared, if imperfectly. All of this was already fraying long before generative AI arrived. And yet this need not be a story of decline. Avoiding that outcome requires us to design for something better. On the informational layer, AI companies must ramp up existing efforts to ensure that models’ outputs are truthful. They should also explore some promising early findings that AI models can help reduce polarization. A recent field evaluation of AI-generated fact checks on X found that people with a variety of political viewpoints deemed AI-written notes more helpful than human-written ones. The paper is yet to be peer-reviewed, but that is a potentially revolutionary finding: AI-assisted fact-checking may be able to achieve the kind of cross-partisan credibility that has eluded most manual human efforts. Greater understanding of and transparency about how models make these assertions and prioritize sources in the process could help build further public trust. On the agentic layer, we need ways to evaluate whether AI agents faithfully represent their users. An agent must never have an agenda of its own or misrepresent its user’s views—a technically daunting requirement in domains where users may have not explicitly stated any preferences. But faithful representation also cannot become an accessory to motivated reasoning. An agent that refuses to present uncomfortable information, that shields its user from ever questioning prior beliefs or fails to adjust to a change of heart, is not acting in the person’s best interest. Finally, on the institutional level, policymakers should hurry to harness AI’s potential to make governance more responsive and legitimate. Several states and localities are already using AI-mediated platforms to conduct democratic deliberation at scale, building on research showing that AI mediators can help citizens find common ground. As agents become increasingly common participants in public input processes—and there is already evidence that bots are skewing those processes—identity verification for both humans and their agentic proxies must be built in from the start. What is needed is a new generation of democratic infrastructure, technological and institutional, built for the world that is actually here. Failing to design for democratic outcomes, in a domain this consequential,

A blueprint for using AI to strengthen democracy Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Google Adds Event-Driven Webhooks to the Gemini API, Eliminating the Need for Polling in Long-Running AI Jobs

If you’ve ever built a production AI pipeline that runs long jobs — processing thousands of prompts overnight, kicking off a Deep Research agent, or generating a long video — you’ve almost certainly dealt with the polling problem. Your code sits in a loop, firing GET requests every few seconds asking, “Is the job done yet?” It’s wasteful, it adds latency, and at scale it becomes a reliability headache. Google just shipped the fix. Google introduced event-driven Webhooks for the Gemini API — a push-based notification system that eliminates the need for inefficient polling. The feature is available now for all developers using the Gemini API and targets a core pain point in agentic and high-volume AI workflows. Why Polling Breaks Down at Scale To understand the problem, it helps to know what Long-Running Operation (LRO) is. Webhooks allow the Gemini API to push real-time notifications to your server when asynchronous or Long-Running Operations complete, replacing the need to poll the API for status updates and reducing latency and overhead. Before webhooks, the only option was continuous polling — repeatedly calling GET /operations to check if a job had finished. As Gemini shifts toward agentic workflows and high-volume processing — like Deep Research, long video generation, or processing thousands of prompts via the Batch API — operations can take minutes or even hours. Polling for hours is expensive in both compute and API quota, and it introduces unnecessary delays between when a job completes and when your application learns about it. The fix is conceptually simple: instead of your code asking “are you done?” repeatedly, the Gemini API calls your server the moment a task finishes, by pushing a real-time HTTP POST payload to your endpoint the instant a task completes. Two Configuration Modes: Static and Dynamic The Gemini API supports two ways to configure webhooks. Static webhooks are project-level endpoints configured with the WebhookService API and are suited for global integrations like notifying Slack or syncing a database — they are registered once per project and trigger for any matching event. Dynamic webhooks are request-level overrides that pass a webhook URL in the webhook_config payload of a specific job call, making them ideal for routing specific jobs to dedicated endpoints, for example in agent-orchestration queues. You can think of static webhooks like a standing instruction to your mail carrier: “Always deliver packages to the front desk.” Dynamic webhooks are more like saying: “For this one shipment, send it to my home address.” An additional feature of dynamic webhooks is the user_metadata field, which lets you attach arbitrary key-value metadata to a job at dispatch time — for example, {“job_group”: “nightly-eval”, “priority”: “high”}. This metadata travels with the job notification and is particularly useful when you need to fan out different job types to different downstream processors without building a separate tracking layer. Security Architecture: Standard Webhooks, HMAC, and JWKS Security is where this implementation gets technically interesting. Google’s implementation strictly adheres to the Standard Webhooks specification. Every request is signed using webhook-signature, webhook-id, and webhook-timestamp headers, ensuring idempotency and preventing replay attacks. For static webhooks, the signing is done with HMAC (Hash-based Message Authentication Code) using a symmetric shared secret, which is provided once at creation time and must be stored securely in your environment variables — the API returns this signing secret only once and it cannot be retrieved again. If you lose it, you have to rotate it. The rotation endpoint supports a revocation_behavior parameter — specifically REVOKE_PREVIOUS_SECRETS_AFTER_H24, which keeps the old secret valid for a 24-hour grace period so you can safely transition production systems, or an immediate revocation option for incident response. For dynamic webhooks, Google uses asymmetric public-key JWKS (JSON Web Key Set) signatures instead of symmetric secrets. Dynamic webhook requests emit a JSON Web Token (JWT) signature, and your listener must extract and verify it using Google’s public certificate endpoints at https://generativelanguage.googleapis.com/.well-known/jwks.json. The RS256 algorithm is used for this verification. This means your server never blindly trusts incoming requests — every webhook hit can be cryptographically verified before you act on it. The webhook-timestamp header is particularly important: best practices call for always validating this timestamp and rejecting payloads older than five minutes to mitigate replay attacks. Thin Payloads and the Event Catalog One architectural decision worth noting is the thin payload model. To avoid bandwidth congestion, Gemini webhooks deliver a snapshot containing status details and pointers to results, rather than the raw output file itself. The exact fields in that snapshot depend on the event type. For batch jobs, a completed notification carries the job id and an output_file_uri pointing to your results — for example, a Cloud Storage path like gs://my-bucket/results.jsonl. For video generation, the video.generated event delivers a different set of fields: file_id and video_uri. Your server-side handler needs to branch on event type before reading the payload data fields. The full event catalog covers three categories: batch jobs (batch.succeeded, batch.cancelled, batch.expired, batch.failed), Interactions API operations (interaction.requires_action, interaction.completed, interaction.failed, interaction.cancelled), and video generation (video.generated). For developers writing code: the official code samples in Google’s documentation subscribe to and handle batch.completed rather than batch.succeeded — both appear across the documentation, so match whichever your implementation uses. The Interactions API, for readers unfamiliar with it, is Gemini’s API for async multi-turn agent conversations. The interaction.requires_action event is particularly useful — it fires when a function call is pending and your application needs to step in and take an action before the agent can continue. Delivery Guarantees and Best Practices Google guarantees “at-least-once” delivery with automatic retries for up to 24 hours using exponential backoff. The “at-least-once” guarantee means your endpoint could occasionally receive the same event more than once under high-congestion conditions. The consistent webhook-id header should be used to deduplicate these. Your server should also respond with a 2xx status code immediately upon valid signature detection and queue any heavier parsing internally — prolonged listener hold times trigger the retry cycle, which is the opposite of what you want. Key

Google Adds Event-Driven Webhooks to the Gemini API, Eliminating the Need for Polling in Long-Running AI Jobs Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE