YouZum

Nachrichten

AI, Committee, Nachrichten, Uncategorized

Train Your Large Model on Multiple GPUs with Tensor Parallelism

This article is divided into five parts; they are: • An Example of Tensor Parallelism • Setting Up Tensor Parallelism • Preparing Model for Tensor Parallelism • Train a Model with Tensor Parallelism • Combining Tensor Parallelism with FSDP Tensor parallelism originated from the Megatron-LM paper.

Train Your Large Model on Multiple GPUs with Tensor Parallelism Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

MedKGI: Iterative Differential Diagnosis with Medical Knowledge Graphs and Information-Guided Inquiring

arXiv:2512.24181v1 Announce Type: new Abstract: Recent advancements in Large Language Models (LLMs) have demonstrated significant promise in clinical diagnosis. However, current models struggle to emulate the iterative, diagnostic hypothesis-driven reasoning of real clinical scenarios. Specifically, current LLMs suffer from three critical limitations: (1) generating hallucinated medical content due to weak grounding in verified knowledge, (2) asking redundant or inefficient questions rather than discriminative ones that hinder diagnostic progress, and (3) losing coherence over multi-turn dialogues, leading to contradictory or inconsistent conclusions. To address these challenges, we propose MedKGI, a diagnostic framework grounded in clinical practices. MedKGI integrates a medical knowledge graph (KG) to constrain reasoning to validated medical ontologies, selects questions based on information gain to maximize diagnostic efficiency, and adopts an OSCE-format structured state to maintain consistent evidence tracking across turns. Experiments on clinical benchmarks show that MedKGI outperforms strong LLM baselines in both diagnostic accuracy and inquiry efficiency, improving dialogue efficiency by 30% on average while maintaining state-of-the-art accuracy.

MedKGI: Iterative Differential Diagnosis with Medical Knowledge Graphs and Information-Guided Inquiring Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

IELTS Writing Revision Platform with Automated Essay Scoring and Adaptive Feedback

arXiv:2512.24460v1 Announce Type: new Abstract: This paper presents the design, development, and evaluation of a proposed revision platform assisting candidates for the International English Language Testing System (IELTS) writing exam. Traditional IELTS preparation methods lack personalised feedback, catered to the IELTS writing rubric. To address these shortcomings, the platform features an attractive user interface (UI), an Automated Essay Scoring system (AES), and targeted feedback tailored to candidates and the IELTS writing rubric. The platform architecture separates conversational guidance from a dedicated writing interface to reduce cognitive load and simulate exam conditions. Through iterative, Design-Based Research (DBR) cycles, the study progressed from rule-based to transformer-based with a regression head scoring, mounted with adaptive feedback. Early cycles (2-3) revealed fundamental limitations of rule-based approaches: mid-band compression, low accuracy, and negative $R^2$ values. DBR Cycle 4 implemented a DistilBERT transformer model with a regression head, yielding substantial improvements with MAE of 0.66 and positive $R^2$. This enabled Cycle 5’s adaptive feedback implementation, which demonstrated statistically significant score improvements (mean +0.060 bands, p = 0.011, Cohen’s d = 0.504), though effectiveness varied by revision strategy. Findings suggest automated feedback functions are most suited as a supplement to human instruction, with conservative surface-level corrections proving more reliable than aggressive structural interventions for IELTS preparation contexts. Challenges remain in assessing higher-band essays, and future work should incorporate longitudinal studies with real IELTS candidates and validation from official examiners.

IELTS Writing Revision Platform with Automated Essay Scoring and Adaptive Feedback Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Large Emotional World Model

arXiv:2512.24149v1 Announce Type: new Abstract: World Models serve as tools for understanding the current state of the world and predicting its future dynamics, with broad application potential across numerous fields. As a key component of world knowledge, emotion significantly influences human decision-making. While existing Large Language Models (LLMs) have shown preliminary capability in capturing world knowledge, they primarily focus on modeling physical-world regularities and lack systematic exploration of emotional factors. In this paper, we first demonstrate the importance of emotion in understanding the world by showing that removing emotionally relevant information degrades reasoning performance. Inspired by theory of mind, we further propose a Large Emotional World Model (LEWM). Specifically, we construct the Emotion-Why-How (EWH) dataset, which integrates emotion into causal relationships and enables reasoning about why actions occur and how emotions drive future world states. Based on this dataset, LEWM explicitly models emotional states alongside visual observations and actions, allowing the world model to predict both future states and emotional transitions. Experimental results show that LEWM more accurately predicts emotion-driven social behaviors while maintaining comparable performance to general world models on basic tasks.

Large Emotional World Model Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

OpenSIR: Open-Ended Self-Improving Reasoner

arXiv:2511.00602v2 Announce Type: replace Abstract: Recent advances in large language model (LLM) reasoning through reinforcement learning rely on annotated datasets for verifiable rewards, which may limit models’ ability to surpass human-level performance. While self-play offers a promising alternative, existing approaches depend on external verifiers or cannot learn open-endedly. We present Open-Ended Self-Improving Reasoner (OpenSIR), a self-play framework where an LLM learns to generate and solve novel problems by alternating teacher and student roles without external supervision. To generate novel problems, OpenSIR optimises for both difficulty and diversity, rewarding problems that challenge appropriately while exploring distinct concepts, enabling open-ended mathematical discovery. Starting from a single trivial seed problem, OpenSIR substantially improves instruction models: Llama-3.2-3B-Instruct advances from 73.9 to 78.3 on GSM8K, and from 28.8 to 34.4 on College Math, while Gemma-2-2B-Instruct rises from 38.5 to 58.7 on GSM8K. Our analyses reveal that OpenSIR achieves open-ended learning through co-evolving teacher-student roles that adaptively calibrate difficulty and drive diverse exploration, progressing autonomously from basic to advanced mathematics.

OpenSIR: Open-Ended Self-Improving Reasoner Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

CubeBench: Diagnosing Interactive, Long-Horizon Spatial Reasoning Under Partial Observations

arXiv:2512.23328v2 Announce Type: replace-cross Abstract: Large Language Model (LLM) agents, while proficient in the digital realm, face a significant gap in physical-world deployment due to the challenge of forming and maintaining a robust spatial mental model. We identify three core cognitive challenges hindering this transition: spatial reasoning, long-horizon state tracking via mental simulation, and active exploration under partial observation. To isolate and evaluate these faculties, we introduce CubeBench, a novel generative benchmark centered on the Rubik’s Cube. CubeBench uses a three-tiered diagnostic framework that progressively assesses agent capabilities, from foundational state tracking with full symbolic information to active exploration with only partial visual data. Our experiments on leading LLMs reveal critical limitations, including a uniform 0.00% pass rate on all long-horizon tasks, exposing a fundamental failure in long-term planning. We also propose a diagnostic framework to isolate these cognitive bottlenecks by providing external solver tools. By analyzing the failure modes, we provide key insights to guide the development of more physically-grounded intelligent agents.

CubeBench: Diagnosing Interactive, Long-Horizon Spatial Reasoning Under Partial Observations Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Alibaba Tongyi Lab Releases MAI-UI: A Foundation GUI Agent Family that Surpasses Gemini 2.5 Pro, Seed1.8 and UI-Tars-2 on AndroidWorld

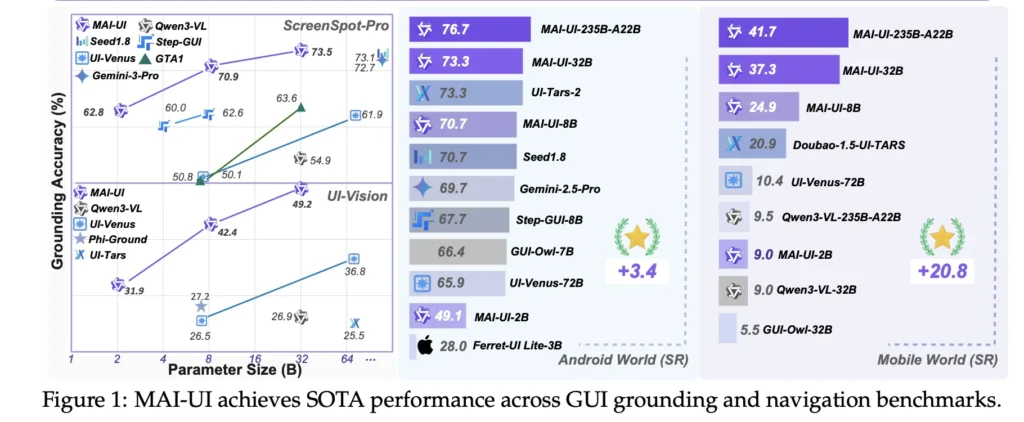
Alibaba Tongyi Lab have released MAI-UI—a family of foundation GUI agents. It natively integrates MCP tool use, agent user interaction, device–cloud collaboration, and online RL, establishing state-of-the-art results in general GUI grounding and mobile GUI navigation, surpassing Gemini-2.5-Pro, Seed1.8, and UI-Tars-2 on AndroidWorld. The system targets three specific gaps that early GUI agents often ignore, native agent user interaction, MCP tool integration, and a device cloud collaboration architecture that keeps privacy sensitive work on device while still using large cloud models when needed. https://arxiv.org/pdf/2512.22047 What is MAI-UI? MAI-UI is a family of multimodal GUI agents built on Qwen3 VL, with model sizes 2B, 8B, 32B and 235B A22B. These models take natural language instructions and rendered UI screenshots as input, then output structured actions for a live Android environment. The action space covers standard operations such as clicking elements, swiping, entering text and pressing system buttons. On top of that, MAI-UI introduces explicit actions for answering user questions, asking the user for clarification when the goal is ambiguous, and invoking external tools through MCP tool calls. This makes the agent capable of mixing GUI steps, direct language responses and API level operations in a single trajectory. From a modeling perspective, MAI UI unifies three components, a self evolving navigation data pipeline that includes user interaction and MCP cases, an online RL framework that scales to hundreds of parallel Android instances and long contexts, and a native device cloud collaboration system that routes execution based on task state and privacy constraints. https://arxiv.org/pdf/2512.22047 GUI grounding with instruction reasoning A core requirement for any GUI agent is grounding, mapping free form language like ‘open monthly billing settings’ to the correct on screen control. MAI-UI adopts a UI grounding strategy inspired by the earlier UI-Ins work on multi perspective instruction descriptions. For each UI element, the training pipeline does not rely on a single caption. Instead, it generates several views of the same element, for example appearance, function, spatial location and user intent. These multiple instructions are treated as reasoning evidence for the model, which must select a point inside the correct bounding box. This reduces the impact of flawed or underspecified instructions, an issue that UI Ins quantified in existing datasets. Ground truth boxes are collected from a mix of curated GUI datasets and large scale exploration of virtualized operating systems in containerized environments. Accessibility trees or OCR based parsers are used to align textual metadata with pixel locations. The training objective combines supervised fine tuning with a simple reinforcement signal that rewards correct point in box predictions and valid output format. On public GUI grounding benchmarks, the resulting MAI-UI models reach 73.5 percent accuracy on ScreenSpot Pro with adaptive zoom in, 91.3 percent on MMBench GUI L2, 70.9 percent on OSWorld G and 49.2 percent on UI Vision. These numbers surpass Gemini 3 Pro and Seed1.8 on ScreenSpot Pro, and significantly outperform earlier open models on UI Vision. https://arxiv.org/pdf/2512.22047 Self evolving navigation data and MobileWorld Navigation is harder than grounding because the agent must maintain context across many steps, possibly across applications, while interacting with the user and tools. To build robust navigation behavior, Tongyi Lab uses a self evolving data pipeline. Seed tasks come from app manuals, hand designed scenarios and filtered public data. Parameters such as dates, limits and filter values are perturbed to expand coverage, and object level substitutions are applied while staying within the same use case. Multiple agents, together with human annotators, execute these tasks in Android environments to produce trajectories. A judge model then evaluates these trajectories, keeps the longest correct prefixes and filters out low quality segments. The next supervised training round uses the union of fresh human traces and high quality model rollouts, so the data distribution gradually follows the current policy. MAI UI is evaluated on MobileWorld, a benchmark from the same team that includes 201 tasks across 20 applications. MobileWorld explicitly mixes three categories, pure GUI tasks, agent user interaction tasks that require natural language back and forth with the user, and MCP augmented tasks that require tool calls. On MobileWorld, MAI UI reaches 41.7 percent overall success, a gain of about 20.8 points over the strongest end to end GUI baselines, and competitive with agentic frameworks that use larger proprietary planners such as Gemini 3 Pro. Online RL in containerized Android environments Static data is not enough for robustness in dynamic mobile apps. MAI-UI therefore uses an online RL framework where the agent interacts directly with containerized Android Virtual Devices. The environment stack packs rooted AVD images and backend services into Docker containers, exposes standard reset and step operations over a service layer and supports more than 35 self hosted apps from e commerce, social, productivity and enterprise categories. The RL setup uses an asynchronous on policy method, GRPO, implemented on top of verl. It combines tensor, pipeline and context parallelism, similar to Megatron style training, so that the model can learn from trajectories with up to 50 steps and very long token sequences. Rewards come from rule based verifiers or model judges that detect task completion, along with penalties for obvious looping behaviors. Only recent successful trajectories are kept in task specific buffers to stabilize learning. Scaling this RL environment matters in practice. The research team shows that increasing the number of parallel GUI environments from 32 to 512 yields about 5.2 percentage points improvement on navigation success, and increasing the allowed environment steps from 15 to 50 adds about 4.3 points. On the AndroidWorld benchmark, which evaluates online navigation in a standard Android app suite, the largest MAI UI variant reaches 76.7 percent success, surpassing UI-Tars-2, Gemini 2.5 Pro and Seed1.8. Key Takeaways Unified GUI agent family for mobile: MAI-UI is a Qwen3 VL based family of GUI agents from 2B to 235B A22B, designed specifically for real world mobile deployment with native agent user interaction, MCP tool calls and device cloud routing, rather than only static benchmarks. State of the art GUI grounding and navigation: The models

Alibaba Tongyi Lab Releases MAI-UI: A Foundation GUI Agent Family that Surpasses Gemini 2.5 Pro, Seed1.8 and UI-Tars-2 on AndroidWorld Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Train Your Large Model on Multiple GPUs with Fully Sharded Data Parallelism

This article is divided into five parts; they are: • Introduction to Fully Sharded Data Parallel • Preparing Model for FSDP Training • Training Loop with FSDP • Fine-Tuning FSDP Behavior • Checkpointing FSDP Models Sharding is a term originally used in database management systems, where it refers to dividing a database into smaller units, called shards, to improve performance.

Train Your Large Model on Multiple GPUs with Fully Sharded Data Parallelism Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

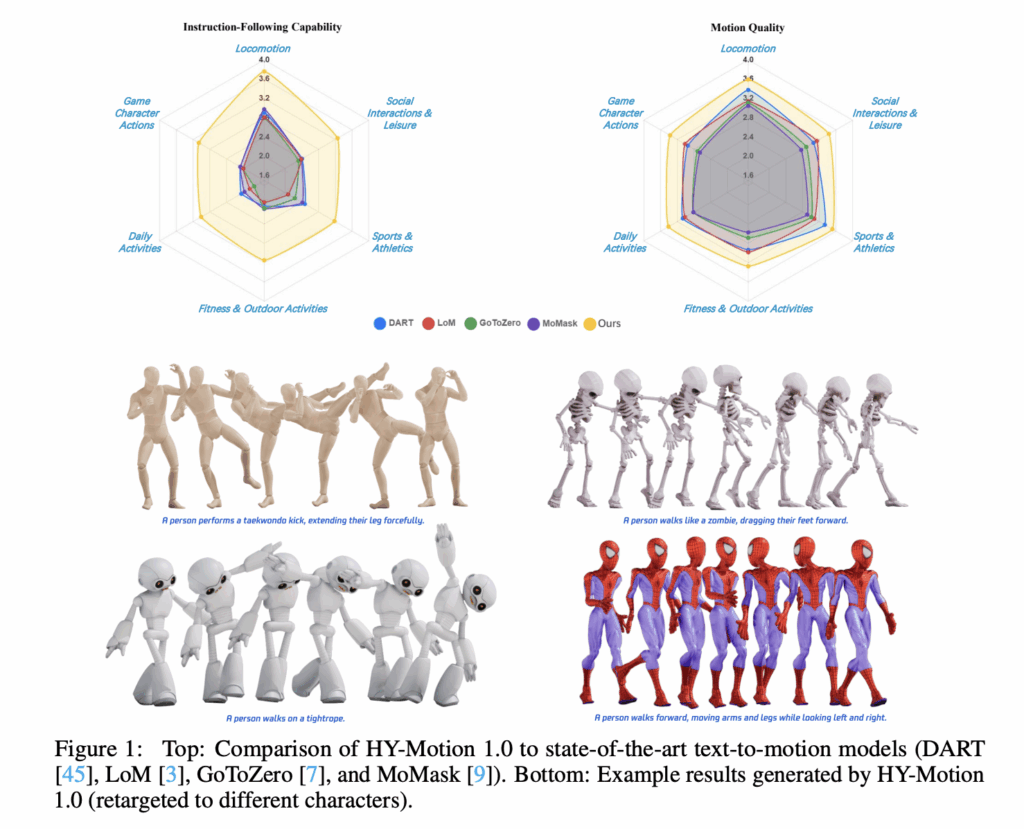
Tencent Released Tencent HY-Motion 1.0: A Billion-Parameter Text-to-Motion Model Built on the Diffusion Transformer (DiT) Architecture and Flow Matching

Tencent Hunyuan’s 3D Digital Human team has released HY-Motion 1.0, an open weight text-to-3D human motion generation family that scales Diffusion Transformer based Flow Matching to 1B parameters in the motion domain. The models turn natural language prompts plus an expected duration into 3D human motion clips on a unified SMPL-H skeleton and are available on GitHub and Hugging Face with code, checkpoints and a Gradio interface for local use. https://arxiv.org/pdf/2512.23464 What HY-Motion 1.0 provides for developers? HY-Motion 1.0 is a series of text-to-3D human motion generation models built on a Diffusion Transformer, DiT, trained with a Flow Matching objective. The model series showcases 2 variants, HY-Motion-1.0 with 1.0B parameters as the standard model and HY-Motion-1.0-Lite with 0.46B parameters as a lightweight option. Both models generate skeleton based 3D character animations from simple text prompts. The output is a motion sequence on an SMPL-H skeleton that can be integrated into 3D animation or game pipelines, for example for digital humans, cinematics and interactive characters. The release includes inference scripts, a batch oriented CLI and a Gradio web app, and supports macOS, Windows and Linux. Data engine and taxonomy The training data comes from 3 sources, in the wild human motion videos, motion capture data and 3D animation assets for game production. The research team starts from 12M high quality video clips from HunyuanVideo, runs shot boundary detection to split scenes and a human detector to keep clips with people, then applies the GVHMR algorithm to reconstruct SMPL X motion tracks. Motion capture sessions and 3D animation libraries contribute about 500 hours of additional motion sequences. All data is retargeted onto a unified SMPL-H skeleton through mesh fitting and retargeting tools. A multi stage filter removes duplicate clips, abnormal poses, outliers in joint velocity, anomalous displacements, long static segments and artifacts such as foot sliding. Motions are then canonicalized, resampled to 30 fps and segmented into clips shorter than 12 seconds with a fixed world frame, Y axis up and the character facing the positive Z axis. The final corpus contains over 3,000 hours of motion, of which 400 hours are high quality 3D motion with verified captions. On top of this, the research team defines a 3 level taxonomy. At the top level there are 6 classes, Locomotion, Sports and Athletics, Fitness and Outdoor Activities, Daily Activities, Social Interactions and Leisure and Game Character Actions. These expand into more than 200 fine grained motion categories at the leaves, which cover both simple atomic actions and concurrent or sequential motion combinations. Motion representation and HY-Motion DiT HY-Motion 1.0 uses the SMPL-H skeleton with 22 body joints without hands. Each frame is a 201 dimensional vector that concatenates global root translation in 3D space, global body orientation in a continuous 6D rotation representation, 21 local joint rotations in 6D form and 22 local joint positions in 3D coordinates. Velocities and foot contact labels are removed because they slowed training and did not help final quality. This representation is compatible with animation workflows and close to the DART model representation. The core network is a hybrid HY Motion DiT. It first applies dual stream blocks that process motion latents and text tokens separately. In these blocks, each modality has its own QKV projections and MLP, and a joint attention module allows motion tokens to query semantic features from text tokens while keeping modality specific structure. The network then switches to single stream blocks that concatenate motion and text tokens into one sequence and process them with parallel spatial and channel attention modules to perform deeper multimodal fusion. For text conditioning, the system uses a dual encoder scheme. Qwen3 8B provides token level embeddings, while a CLIP-L model provides global text features. A Bidirectional Token Refiner fixes the causal attention bias of the LLM for non autoregressive generation. These signals feed the DiT through adaptive layer normalization conditioning. Attention is asymmetric, motion tokens can attend to all text tokens, but text tokens do not attend back to motion, which prevents noisy motion states from corrupting the language representation. Temporal attention inside the motion branch uses a narrow sliding window of 121 frames, which focuses capacity on local kinematics while keeping cost manageable for long clips. Full Rotary Position Embedding is applied after concatenating text and motion tokens to encode relative positions across the whole sequence. Flow Matching, prompt rewriting and training HY-Motion 1.0 uses Flow Matching instead of standard denoising diffusion. The model learns a velocity field along a continuous path that interpolates between Gaussian noise and real motion data. During training, the objective is a mean squared error between predicted and ground truth velocities along this path. During inference, the learned ordinary differential equation is integrated from noise to a clean trajectory, which gives stable training for long sequences and fits the DiT architecture. A separate Duration Prediction and Prompt Rewrite module improves instruction following. It uses Qwen3 30B A3B as the base model and is trained on synthetic user style prompts generated from motion captions with a VLM and LLM pipeline, for example Gemini 2.5 Pro. This module predicts a suitable motion duration and rewrites informal prompts into normalized text that is easier for the DiT to follow. It is trained first with supervised fine tuning and then refined with Group Relative Policy Optimization, using Qwen3 235B A22B as a reward model that scores semantic consistency and duration plausibility. Training follows a 3 stage curriculum. Stage 1 performs large scale pretraining on the full 3,000 hour dataset to learn a broad motion prior and basic text motion alignment. Stage 2 fine tunes on the 400 hour high quality set to sharpen motion detail and improve semantic correctness with a smaller learning rate. Stage 3 applies reinforcement learning, first Direct Preference Optimization using 9,228 curated human preference pairs sampled from about 40,000 generated pairs, then Flow GRPO with a composite reward. The reward combines a semantic score from a Text Motion Retrieval model and a physics score that penalizes artifacts like foot

Tencent Released Tencent HY-Motion 1.0: A Billion-Parameter Text-to-Motion Model Built on the Diffusion Transformer (DiT) Architecture and Flow Matching Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE