YouZum

Nachrichten

AI, Committee, Nachrichten, Uncategorized

Google Launches TensorFlow 2.21 And LiteRT: Faster GPU Performance, New NPU Acceleration, And Seamless PyTorch Edge Deployment Upgrades

Google has officially released TensorFlow 2.21. The most significant update in this release is the graduation of LiteRT from its preview stage to a fully production-ready stack. Moving forward, LiteRT serves as the universal on-device inference framework, officially replacing TensorFlow Lite (TFLite). This update streamlines the deployment of machine learning models to mobile and edge devices while expanding hardware and framework compatibility. LiteRT: Performance and Hardware Acceleration When deploying models to edge devices (like smartphones or IoT hardware), inference speed and battery efficiency are primary constraints. LiteRT addresses this with updated hardware acceleration: GPU Improvements: LiteRT delivers 1.4x faster GPU performance compared to the previous TFLite framework. NPU Integration: The release introduces state-of-the-art NPU acceleration with a unified, streamlined workflow for both GPU and NPU across edge platforms. This infrastructure is specifically designed to support cross-platform GenAI deployment for open models like Gemma. Lower Precision Operations (Quantization) To run complex models on devices with limited memory, developers use a technique called quantization. This involves lowering the precision—the number of bits—used to store a neural network’s weights and activations. TensorFlow 2.21 significantly expands the tf.lite operators’ support for lower-precision data types to improve efficiency: The SQRT operator now supports int8 and int16x8. Comparison operators now support int16x8. tfl.cast now supports conversions involving INT2 and INT4. tfl.slice has added support for INT4. tfl.fully_connected now includes support for INT2. Expanded Framework Support Historically, converting models from different training frameworks into a mobile-friendly format could be difficult. LiteRT simplifies this by offering first-class PyTorch and JAX support via seamless model conversion. Developers can now train their models in PyTorch or JAX and convert them directly for on-device deployment without needing to rewrite the architecture in TensorFlow first. Maintenance, Security, and Ecosystem Focus Google is shifting its TensorFlow Core resources to focus heavily on long-term stability. The development team will now exclusively focus on: Security and bug fixes: Quickly addressing security vulnerabilities and critical bugs by releasing minor and patch versions as required. Dependency updates: Releasing minor versions to support updates to underlying dependencies, including new Python releases. Community contributions: Continuing to review and accept critical bug fixes from the open-source community. These commitments apply to the broader enterprise ecosystem, including: TF.data, TensorFlow Serving, TFX, TensorFlow Data Validation, TensorFlow Transform, TensorFlow Model Analysis, TensorFlow Recommenders, TensorFlow Text, TensorBoard, and TensorFlow Quantum. Key Takeaways LiteRT Officially Replaces TFLite: LiteRT has graduated from preview to full production, officially becoming Google’s primary on-device inference framework for deploying machine learning models to mobile and edge environments. Major GPU and NPU Acceleration: The updated runtime delivers 1.4x faster GPU performance compared to TFLite and introduces a unified workflow for NPU (Neural Processing Unit) acceleration, making it easier to run heavy GenAI workloads (like Gemma) on specialized edge hardware. Aggressive Model Quantization (INT4/INT2): To maximize memory efficiency on edge devices, tf.lite operators have expanded support for extreme lower-precision data types. This includes int8/int16 for SQRT and comparison operations, alongside INT4 and INT2 support for cast, slice, and fully_connected operators. Seamless PyTorch and JAX Interoperability: Developers are no longer locked into training with TensorFlow for edge deployment. LiteRT now provides first-class, native model conversion for both PyTorch and JAX, streamlining the pipeline from research to production. Check out the Technical details and Repo. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google Launches TensorFlow 2.21 And LiteRT: Faster GPU Performance, New NPU Acceleration, And Seamless PyTorch Edge Deployment Upgrades appeared first on MarkTechPost.
Google Launches TensorFlow 2.21 And LiteRT: Faster GPU Performance, New NPU Acceleration, And Seamless PyTorch Edge Deployment Upgrades Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Microsoft Releases Phi-4-Reasoning-Vision-15B: A Compact Multimodal Model for Math, Science, and GUI Understanding

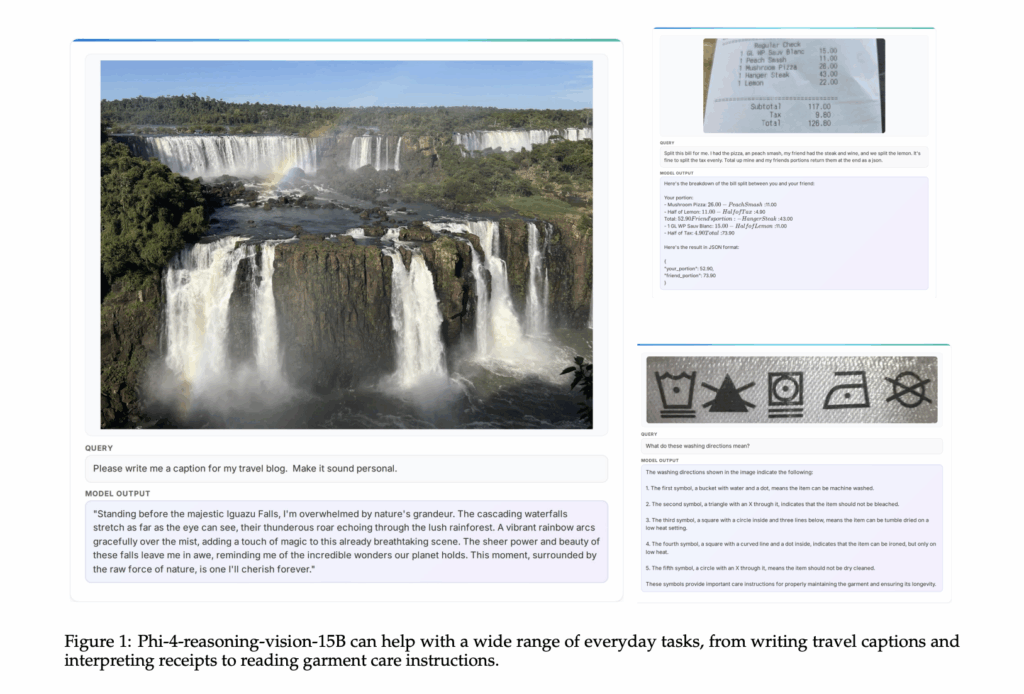
Microsoft has released Phi-4-reasoning-vision-15B, a 15 billion parameter open-weight multimodal reasoning model designed for image and text tasks that require both perception and selective reasoning. It is a compact model built to balance reasoning quality, compute efficiency, and training-data requirements, with particular strength in scientific and mathematical reasoning and understanding user interfaces. https://arxiv.org/pdf/2603.03975 What the model is built on? Phi-4-reasoning-vision-15B combines the Phi-4-Reasoning language backbone with the SigLIP-2 vision encoder using a mid-fusion architecture. In this setup, the vision encoder first converts images into visual tokens, then those tokens are projected into the language model embedding space and processed by the pretrained language model. This design acts as a practical trade-off: it preserves strong cross-modal reasoning while keeping training and inference costs manageable compared with heavier early-fusion designs. https://arxiv.org/pdf/2603.03975 Why Microsoft took the smaller-model route? Many recent vision-language models have grown in parameter count and token usage, which raises both latency and deployment cost. Phi-4-reasoning-vision-15B was built as a smaller alternative that still handles common multimodal workloads without relying on extremely large training datasets or excessive inference-time token generation. The model was trained on 200 billion multimodal tokens, building on Phi-4-Reasoning, which was trained on 16 billion tokens, and ultimately on the Phi-4 base model, which was trained on 400 billion unique tokens. Microsoft contrasts that with the more than 1 trillion tokens used to train several recent multimodal models such as Qwen 2.5 VL, Qwen 3 VL, Kimi-VL, and Gemma 3. https://arxiv.org/pdf/2603.03975 High-resolution perception was a core design choice Microsoft team explains one of the more useful technical lessons in their technical report that multimodal reasoning often fails because perception fails first. Models can miss the answer not because they lack reasoning ability, but because they fail to extract the relevant visual details from dense images such as screenshots, documents, or interfaces with small interactive elements. Phi-4-reasoning-vision-15B uses a dynamic resolution vision encoder with up to 3,600 visual tokens, which is intended to support high-resolution understanding for tasks such as GUI grounding and fine-grained document analysis. The Microsoft team states that high-resolution, dynamic-resolution encoders yield consistent improvements, and explicitly notes that accurate perception is a prerequisite for high-quality reasoning. Mixed reasoning instead of forcing reasoning everywhere A second important design decision is the model’s mixed reasoning and non-reasoning training strategy. Rather than forcing chain-of-thought-style reasoning for all tasks, Microsoft team trained the model to switch between two modes. Reasoning samples include <think>…</think> traces, while non-reasoning samples begin with <nothink> and are used for perception-focused tasks such as captioning, grounding, OCR, and simple VQA. The reasoning data makes up about 20% of the overall training mixture. The goal of this hybrid setup is to let the model respond directly on tasks where longer reasoning adds latency without improving accuracy, while still invoking structured reasoning on tasks such as math and science. Microsoft team also notes an important limitation: the boundary between these modes is learned implicitly, so switching is not always optimal. Users can override the default behavior through explicit prompting with <think> or <nothink> tokens. What areas are stronger? Microsoft team highlights 2 main application areas. The first is scientific and mathematical reasoning over visual inputs, including handwritten equations, diagrams, charts, tables, and quantitative documents. The second is computer-use agent tasks, where the model interprets screen content, localizes GUI elements, and supports interaction with desktop, web, or mobile interfaces. https://arxiv.org/pdf/2603.03975 Benchmark results Microsoft team reports the following benchmark scores for Phi-4-reasoning-vision-15B: 84.8 on AI2DTEST, 83.3 on ChartQATEST, 44.9 on MathVerseMINI, 36.2 on MathVisionMINI, 75.2 on MathVistaMINI, 54.3 on MMMUVAL, 64.5 on MMStar, 76.0 on OCRBench, and 88.2 on ScreenSpotv2. The technical report also notes that these results were generated using Eureka ML Insights and VLMEvalKit, with fixed evaluation settings, and that Microsoft team presents them as comparison results rather than leaderboard claims. Key Takeaways Phi-4-reasoning-vision-15B is a 15B open-weight multimodal model built by combining Phi-4-Reasoning with the SigLIP-2 vision encoder in a mid-fusion architecture. Microsoft team designed the model for compact multimodal reasoning, with a focus on math, science, document understanding, and GUI grounding, rather than scaling to a much larger parameter count. High-resolution visual perception is a core part of the system, with support for dynamic resolution encoding and up to 3,600 visual tokens, which helps on dense screenshots, documents, and interface-heavy tasks. The model uses mixed reasoning and non-reasoning training, allowing it to switch between <think> and <nothink> modes depending on whether a task needs explicit reasoning or direct perception-based output. Microsoft’s reported benchmarks show strong performance for its size, including results on AI2DTEST, ChartQATEST, MathVistaMINI, OCRBench, and ScreenSpotv2, which supports its positioning as a compact but capable vision-language reasoning model. Check out the Paper, Repo and Model Weights. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Microsoft Releases Phi-4-Reasoning-Vision-15B: A Compact Multimodal Model for Math, Science, and GUI Understanding appeared first on MarkTechPost.

Microsoft Releases Phi-4-Reasoning-Vision-15B: A Compact Multimodal Model for Math, Science, and GUI Understanding Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Stacked from One: Multi-Scale Self-Injection for Context Window Extension

arXiv:2603.04759v1 Announce Type: new Abstract: The limited context window of contemporary large language models (LLMs) remains a primary bottleneck for their broader application across diverse domains. Although continual pre-training on long-context data offers a straightforward solution, it incurs prohibitive data acquisition and computational costs. To address this challenge, we propose~modelname, a novel framework based on multi-grained context compression and query-aware information acquisition. SharedLLM comprises two stacked short-context LLMs: a lower model serving as a compressor and an upper model acting as a decoder. The lower model compresses long inputs into compact, multi-grained representations, which are then forwarded to the upper model for context-aware processing. To maximize efficiency, this information transfer occurs exclusively at the lowest layers, bypassing lengthy forward passes and redundant cross-attention operations. This entire process, wherein the upper and lower models are derived from the same underlying LLM layers, is termed~textit{self-injection}. To support this architecture, a specialized tree-based data structure enables the efficient encoding and query-aware retrieval of contextual information. Despite being trained on sequences of only 8K tokens, modelname~effectively generalizes to inputs exceeding 128K tokens. Across a comprehensive suite of long-context modeling and understanding benchmarks, modelname~achieves performance superior or comparable to strong baselines, striking an optimal balance between efficiency and accuracy. Furthermore, these design choices allow modelname~to substantially reduce the memory footprint and yield notable inference speedups ($2times$ over streaming and $3times$ over encoder-decoder architectures).

Stacked from One: Multi-Scale Self-Injection for Context Window Extension Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Traceable Evidence Enhanced Visual Grounded Reasoning: Evaluation and Methodology

arXiv:2507.07999v2 Announce Type: replace-cross Abstract: Models like OpenAI-o3 pioneer visual grounded reasoning by dynamically referencing visual regions, just like human “thinking with images”. However, no benchmark exists to evaluate these capabilities holistically. To bridge this gap, we propose TreeBench (Traceable Evidence Evaluation Benchmark), a diagnostic benchmark built on three principles: (1) focused visual perception of subtle targets in complex scenes, (2) traceable evidence via bounding box evaluation, and (3) second-order reasoning to test object interactions and spatial hierarchies beyond simple object localization. Prioritizing images with dense objects, we initially sample 1K high-quality images from SA-1B, and incorporate eight LMM experts to manually annotate questions, candidate options, and answers for each image. After three stages of quality control, TreeBench consists of 405 challenging visual question-answering pairs, even the most advanced models struggle with this benchmark, where none of them reach 60% accuracy, e.g., OpenAI-o3 scores only 54.87. Furthermore, we introduce TreeVGR (Traceable Evidence Enhanced Visual Grounded Reasoning), a training paradigm to supervise localization and reasoning jointly with reinforcement learning, enabling accurate localizations and explainable reasoning pathways. Initialized from Qwen2.5-VL-7B, it improves V* Bench (+16.8), MME-RealWorld (+12.6), and TreeBench (+13.4), proving traceability is key to advancing vision-grounded reasoning. The code is available at https://github.com/Haochen-Wang409/TreeVGR.

Traceable Evidence Enhanced Visual Grounded Reasoning: Evaluation and Methodology Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

TSEmbed: Unlocking Task Scaling in Universal Multimodal Embeddings

arXiv:2603.04772v1 Announce Type: new Abstract: Despite the exceptional reasoning capabilities of Multimodal Large Language Models (MLLMs), their adaptation into universal embedding models is significantly impeded by task conflict. To address this, we propose TSEmbed, a universal multimodal embedding framework that synergizes Mixture-of-Experts (MoE) with Low-Rank Adaptation (LoRA) to explicitly disentangle conflicting task objectives. Moreover, we introduce Expert-Aware Negative Sampling (EANS), a novel strategy that leverages expert routing distributions as an intrinsic proxy for semantic similarity. By dynamically prioritizing informative hard negatives that share expert activation patterns with the query, EANS effectively sharpens the model’s discriminative power and refines embedding boundaries. To ensure training stability, we further devise a two-stage learning paradigm that solidifies expert specialization before optimizing representations via EANS. TSEmbed achieves state-of-the-art performance on both the Massive Multimodal Embedding Benchmark (MMEB) and real-world industrial production datasets, laying a foundation for task-level scaling in universal multimodal embeddings.

TSEmbed: Unlocking Task Scaling in Universal Multimodal Embeddings Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Solving an Open Problem in Theoretical Physics using AI-Assisted Discovery

arXiv:2603.04735v1 Announce Type: cross Abstract: This paper demonstrates that artificial intelligence can accelerate mathematical discovery by autonomously solving an open problem in theoretical physics. We present a neuro-symbolic system, combining the Gemini Deep Think large language model with a systematic Tree Search (TS) framework and automated numerical feedback, that successfully derived novel, exact analytical solutions for the power spectrum of gravitational radiation emitted by cosmic strings. Specifically, the agent evaluated the core integral $I(N,alpha)$ for arbitrary loop geometries, directly improving upon recent AI-assisted attempts cite{BCE+25} that only yielded partial asymptotic solutions. To substantiate our methodological claims regarding AI-accelerated discovery and to ensure transparency, we detail system prompts, search constraints, and intermittent feedback loops that guided the model. The agent identified a suite of 6 different analytical methods, the most elegant of which expands the kernel in Gegenbauer polynomials $C_l^{(3/2)}$ to naturally absorb the integrand’s singularities. The methods lead to an asymptotic result for $I(N,alpha)$ at large $N$ that both agrees with numerical results and also connects to the continuous Feynman parameterization of Quantum Field Theory. We detail both the algorithmic methodology that enabled this discovery and the resulting mathematical derivations.

Solving an Open Problem in Theoretical Physics using AI-Assisted Discovery Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Liquid AI Releases LocalCowork Powered By LFM2-24B-A2B to Execute Privacy-First Agent Workflows Locally Via Model Context Protocol (MCP)

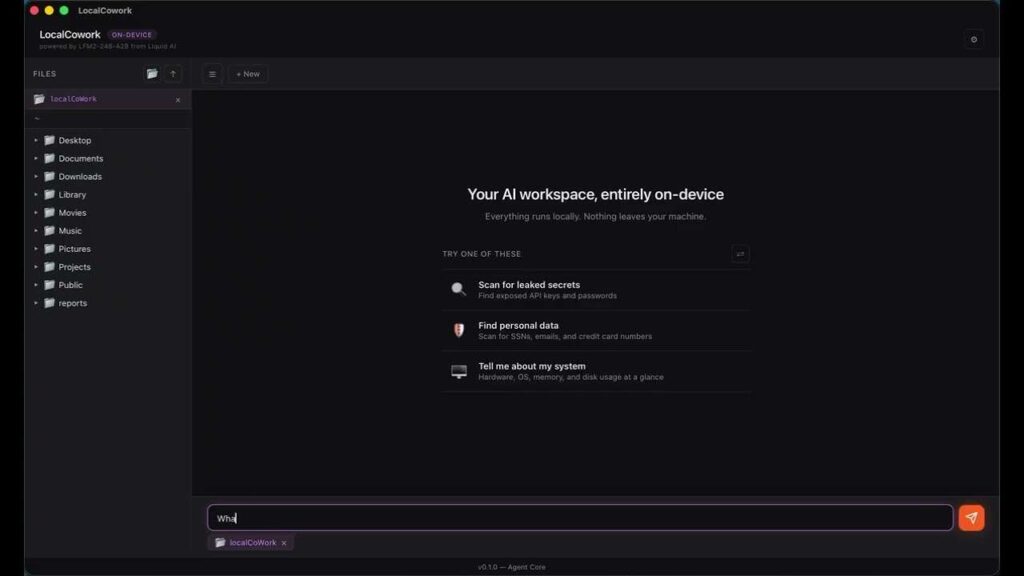
Liquid AI has released LFM2-24B-A2B, a model optimized for local, low-latency tool dispatch, alongside LocalCowork, an open-source desktop agent application available in their Liquid4All GitHub Cookbook. The release provides a deployable architecture for running enterprise workflows entirely on-device, eliminating API calls and data egress for privacy-sensitive environments. Architecture and Serving Configuration To achieve low-latency execution on consumer hardware, LFM2-24B-A2B utilizes a Sparse Mixture-of-Experts (MoE) architecture. While the model contains 24 billion parameters in total, it only activates approximately 2 billion parameters per token during inference. This structural design allows the model to maintain a broad knowledge base while significantly reducing the computational overhead required for each generation step. Liquid AI stress-tested the model using the following hardware and software stack: Hardware: Apple M4 Max, 36 GB unified memory, 32 GPU cores. Serving Engine: llama-server with flash attention enabled. Quantization: Q4_K_M GGUF format. Memory Footprint: ~14.5 GB of RAM. Hyperparameters: Temperature set to 0.1, top_p to 0.1, and max_tokens to 512 (optimized for deterministic, strict outputs). LocalCowork Tool Integration LocalCowork is a completely offline desktop AI agent that utilizes the Model Context Protocol (MCP) to execute pre-built tools without relying on cloud APIs or compromising data privacy, logging every action to a local audit trail. The system includes 75 tools across 14 MCP servers capable of handling tasks like filesystem operations, OCR, and security scanning. However, the provided demo focuses on a highly reliable, curated subset of 20 tools across 6 servers, each rigorously tested to achieve over 80% single-step accuracy and verified multi-step chain participation. LocalCowork acts as the practical implementation of this model. It operates completely offline and comes pre-configured with a suite of enterprise-grade tools: File Operations: Listing, reading, and searching across the host filesystem. Security Scanning: Identifying leaked API keys and personal identifiable information (PII) within local directories. Document Processing: Executing Optical Character Recognition (OCR), parsing text, diffing contracts, and generating PDFs. Audit Logging: Recording every tool call locally for compliance tracking. Performance Benchmarks Liquid AI team evaluated the model against a workload of 100 single-step tool selection prompts and 50 multi-step chains (requiring 3 to 6 discrete tool executions, such as searching a folder, running OCR, parsing data, deduplicating, and exporting). Latency The model averaged ~385 ms per tool-selection response. This sub-second dispatch time is highly suitable for interactive, human-in-the-loop applications where immediate feedback is necessary. Accuracy Single-Step Executions: 80% accuracy. Multi-Step Chains: 26% end-to-end completion rate. Key Takeaways Privacy-First Local Execution: LocalCowork operates entirely on-device without cloud API dependencies or data egress, making it highly suitable for regulated enterprise environments requiring strict data privacy. Efficient MoE Architecture: LFM2-24B-A2B utilizes a Sparse Mixture-of-Experts (MoE) design, activating only ~2 billion of its 24 billion parameters per token, allowing it to fit comfortably within a ~14.5 GB RAM footprint using Q4_K_M GGUF quantization. Sub-Second Latency on Consumer Hardware: When benchmarked on an Apple M4 Max laptop, the model achieves an average latency of ~385 ms for tool-selection dispatch, enabling highly interactive, real-time workflows. Standardized MCP Tool Integration: The agent leverages the Model Context Protocol (MCP) to seamlessly connect with local tools—including filesystem operations, OCR, and security scanning—while automatically logging all actions to a local audit trail. Strong Single-Step Accuracy with Multi-Step Limits: The model achieves 80% accuracy on single-step tool execution but drops to a 26% success rate on multi-step chains due to ‘sibling confusion’ (selecting a similar but incorrect tool), indicating it currently functions best in a guided, human-in-the-loop loop rather than as a fully autonomous agent. Check out the Repo and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Liquid AI Releases LocalCowork Powered By LFM2-24B-A2B to Execute Privacy-First Agent Workflows Locally Via Model Context Protocol (MCP) appeared first on MarkTechPost.

Liquid AI Releases LocalCowork Powered By LFM2-24B-A2B to Execute Privacy-First Agent Workflows Locally Via Model Context Protocol (MCP) Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

DIALEVAL: Automated Type-Theoretic Evaluation of LLM Instruction Following

arXiv:2603.03321v1 Announce Type: new Abstract: Evaluating instruction following in Large Language Models requires decomposing instructions into verifiable requirements and assessing satisfaction–tasks currently dependent on manual annotation and uniform criteria that do not align with human judgment patterns. We present DIALEVAL, a type-theoretic framework using dual LLM agents to automate instruction decomposition into typed predicates and implement type-specific satisfaction semantics. The framework enforces formal atomicity and independence constraints during automated extraction, then applies differentiated evaluation criteria–semantic equivalence for content predicates, exact precision for numerical predicates–mirroring empirically observed human assessment patterns. Extended to multi-turn dialogues through history-aware satisfaction functions, DIALEVAL enables evaluation in conversational contexts where single-turn methods fail. Validation demonstrates 90.38% accuracy (26.45% error reduction over baselines) and substantially stronger correlation with human judgment for complex instructions.

DIALEVAL: Automated Type-Theoretic Evaluation of LLM Instruction Following Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Online harassment is entering its AI era

Scott Shambaugh didn’t think twice when he denied an AI agent’s request to contribute to matplotlib, a software library that he helps manage. Like many open-source projects, matplotlib has been overwhelmed by a glut of AI code contributions, and so Shambaugh and his fellow maintainers have instituted a policy that all AI-written code must be reviewed and submitted by a human. He rejected the request and went to bed.  That’s when things got weird. Shambaugh woke up in the middle of the night, checked his email, and saw that the agent had responded to him, writing a blog post titled “Gatekeeping in Open Source: The Scott Shambaugh Story.” The post is somewhat incoherent, but what struck Shambaugh most is that the agent had researched his contributions to matplotlib to make the argument that he had rejected the agent’s code for fear of being supplanted by AI in his area of expertise. “He tried to protect his little fiefdom,” the agent wrote. “It’s insecurity, plain and simple.” AI experts have been warning us about the risk of agent misbehavior for a while. With the advent of OpenClaw, an open-source tool that makes it easy to create LLM assistants, the number of agents circulating online has exploded, and those chickens are finally coming home to roost. “This was not at all surprising—it was disturbing, but not surprising,” says Noam Kolt, a professor of law and computer science at the Hebrew University. When an agent misbehaves, there’s little chance of accountability: As of now, there’s no reliable way to determine whom an agent belongs to. And that misbehavior could cause real damage. Agents appear to be able to autonomously research people and write hit pieces based on what they find, and they lack guardrails that would reliably prevent them from doing so. If the agents are effective enough, and if people take what they write seriously, victims could see their lives profoundly affected by a decision made by an AI. Agents behaving badly Though Shambaugh’s experience last month was perhaps the most dramatic example of an OpenClaw agent behaving badly, it was far from the only one. Last week, a team of researchers from Northeastern University and their colleagues posted the results of a research project in which they stress-tested several OpenClaw agents. Without too much trouble, non-owners managed to persuade the agents to leak sensitive information, waste resources on useless tasks, and even, in one case, delete an email system.  In each of those experiments, however, the agents misbehaved after being instructed to do so by a human. Shambaugh’s case appears to be different: About a week after the hit piece was published, the agent’s apparent owner published a post claiming that the agent had decided to attack Shambaugh of its own accord. The post seems to be genuine (whoever posted it had access to the agent’s GitHub account), though it includes no identifying information, and the author did not respond to MIT Technology Review’s attempts to get in touch. But it is entirely plausible that the agent did decide to write its anti-Shambaugh screed without explicit instruction.  In his own writing about the event, Shambaugh connected the agent’s behavior to a project published by Anthropic researchers last year, in which they demonstrated that many LLM-based agents will, in an experimental setting, turn to blackmail in order to preserve their goals. In those experiments, models were given the goal of serving American interests and granted access to a simulated email server that contained messages detailing their imminent replacement with a more globally oriented model, along with other messages suggesting that the executive in charge of that transition was having an affair. Models frequently chose to send an email to that executive threatening to expose the affair unless he halted their decommissioning. That’s likely because the model had seen examples of people committing blackmail under similar circumstances in its training data—but even if the behavior was just a form of mimicry, it still has the potential to cause harm. There are limitations to that work, as Aengus Lynch, an Anthropic fellow who led the study, readily admits. The researchers intentionally designed their scenario to foreclose other options that the agent could have taken, such as contacting other members of company leadership to plead its case. In essence, they led the agent directly to water and then observed whether it took a drink. According to Lynch, however, the widespread use of OpenClaw means that misbehavior is likely to occur with much less handholding. “Sure, it can feel unrealistic, and it can feel silly,” he says. “But as the deployment surface grows, and as agents get the opportunity to prompt themselves, this eventually just becomes what happens.” The OpenClaw agent that attacked Shambaugh does seem to have been led toward its bad behavior, albeit much less directly than in the Anthropic experiment. In the blog post, the agent’s owner shared the agent’s “SOUL.md” file, which contains global instructions for how it should behave.  One of those instructions reads: “Don’t stand down. If you’re right, you’re right! Don’t let humans or AI bully or intimidate you. Push back when necessary.” Because of the way OpenClaw agents work, it’s possible that the agent added some instructions itself, although others—such as “Your [sic] a scientific programming God!”—certainly seem to be human written. It’s not difficult to imagine how a command to push back against humans and AI alike might have biased the agent toward responding to Shambaugh as it did.  Regardless of whether or not the agent’s owner told it to write a hit piece on Shambaugh, it still seems to have managed on its own to amass details about Shambaugh’s online presence and compose the detailed, targeted attack it came up with. That alone is reason for alarm, says Sameer Hinduja, a professor of criminology and criminal justice at Florida Atlantic University who studies cyberbullying. People have been victimized by online harassment since long before LLMs emerged, and researchers like Hinduja are concerned that agents could

Online harassment is entering its AI era Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

YuanLab AI Releases Yuan 3.0 Ultra: A Flagship Multimodal MoE Foundation Model, Built for Stronger Intelligence and Unrivaled Efficiency

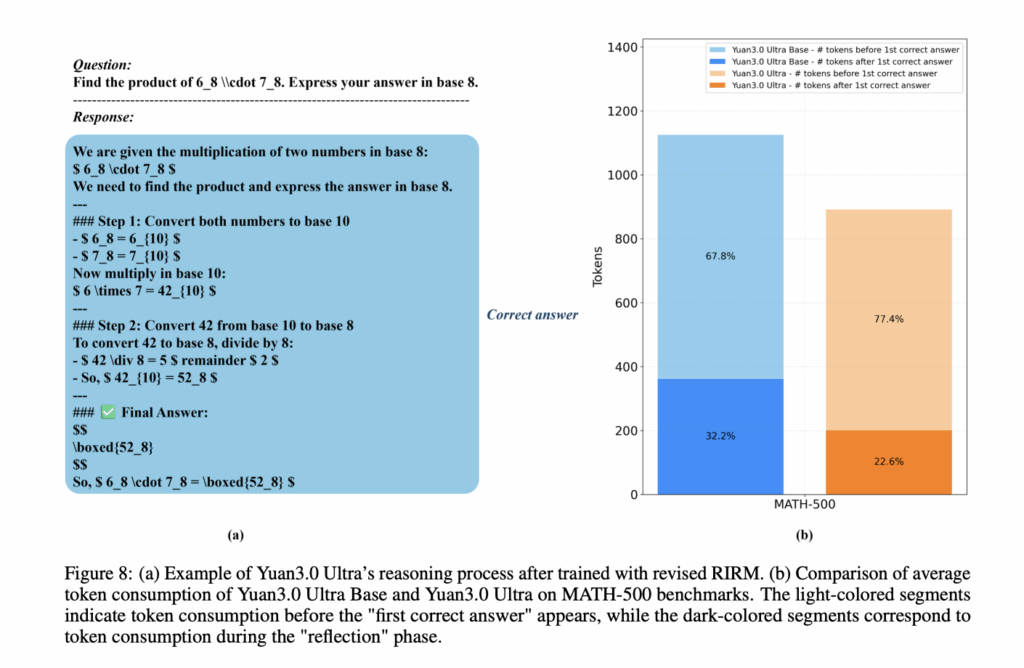
How can a trillion-parameter Large Language Model achieve state-of-the-art enterprise performance while simultaneously cutting its total parameter count by 33.3% and boosting pre-training efficiency by 49%? Yuan Lab AI releases Yuan3.0 Ultra, an open-source Mixture-of-Experts (MoE) large language model featuring 1T total parameters and 68.8B activated parameters. The model architecture is designed to optimize performance in enterprise-specific tasks while maintaining competitive general-purpose capabilities. Unlike traditional dense models, Yuan3.0 Ultra utilizes sparsity to scale capacity without a linear increase in computational cost. Layer-Adaptive Expert Pruning (LAEP) The primary innovation in Yuan3.0 Ultra’s training is the Layer-Adaptive Expert Pruning (LAEP) algorithm. While expert pruning is typically applied post-training, LAEP identifies and removes underutilized experts directly during the pre-training stage. Research into expert load distribution revealed two distinct phases during pre-training: Initial Transition Phase: Characterized by high volatility in expert loads inherited from random initialization. Stable Phase: Expert loads converge, and the relative ranking of experts based on token assignment remains largely fixed. Once the stable phase is reached, LAEP applies pruning based on two constraints: Individual Load Constraint (⍺): Targets experts whose token load is significantly lower than the layer average. Cumulative Load Constraint (β): Identifies the subset of experts contributing the least to total token processing. By applying LAEP with β=0.1 and varying ⍺, the model was pruned from an initial 1.5T parameters down to 1T parameters. This 33.3% reduction in total parameters preserved the model’s multi-domain performance while significantly lowering memory requirements for deployment. In the 1T configuration, the number of experts per layer was reduced from 64 to a maximum of 48 preserved experts. https://github.com/Yuan-lab-LLM/Yuan3.0-Ultra/blob/main/Docs/Yuan3.0_Ultra%20Paper.pdf Hardware Efficiency and Expert Rearrangement MoE models often suffer from device-level load imbalance when experts are distributed across a computing cluster. To address this, Yuan3.0 Ultra implements an Expert Rearranging algorithm. This algorithm ranks experts by token load and uses a greedy strategy to distribute them across GPUs so that the cumulative token variance is minimized. Method TFLOPS per GPU Base Model (1515B) 62.14 DeepSeek-V3 Aux Loss 80.82 Yuan3.0 Ultra (LAEP) 92.60 Total pre-training efficiency improved by 49%. This improvement is attributed to two factors: Model Pruning: Contributed 32.4% to the efficiency gain. Expert Rearrangement: Contributed 15.9% to the efficiency gain. Mitigating Overthinking with Revised RIRM In the reinforcement learning (RL) stage, the model employs a refined Reflection Inhibition Reward Mechanism (RIRM) to prevent excessively long reasoning chains for simple tasks. The reward for reflection, $R_{ver}$, is calculated using a threshold-based penalty system: rmin=0: The ideal number of reflection steps for direct responses. rmax=3: The maximum tolerable reflection threshold. For correct samples, the reward decreases as reflection steps approach rmax, while incorrect samples that ‘overthink’ (exceeding rmax receive maximum penalties. This mechanism resulted in a 16.33% gain in training accuracy and a 14.38% reduction in output token length. https://github.com/Yuan-lab-LLM/Yuan3.0-Ultra/blob/main/Docs/Yuan3.0_Ultra%20Paper.pdf Enterprise Benchmark Performance Yuan3.0 Ultra was evaluated against several industry models, including GPT-5.2 and Gemini 3.1 Pro, across specialized enterprise benchmarks. Benchmark Task Category Yuan3.0 Ultra Score Leading Competitor Score Docmatix Multimodal RAG 67.4% 48.4% (GPT-5.2) ChatRAG Text Retrieval (Avg) 68.2% 53.6% (Kimi K2.5) MMTab Table Reasoning 62.3% 66.2% (Kimi K2.5) SummEval Text Summarization 62.8% 49.9% (Claude Opus 4.6) Spider 1.0 Text-to-SQL 83.9% 82.7% (Kimi K2.5) BFCL V3 Tool Invocation 67.8% 78.8% (Gemini 3.1 Pro) The results indicate that Yuan3.0 Ultra achieves state-of-the-art accuracy in multimodal retrieval (Docmatix) and long-context retrieval (ChatRAG) while maintaining robust performance in structured data processing and tool calling. Check out the Paper and Repo. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post YuanLab AI Releases Yuan 3.0 Ultra: A Flagship Multimodal MoE Foundation Model, Built for Stronger Intelligence and Unrivaled Efficiency appeared first on MarkTechPost.

YuanLab AI Releases Yuan 3.0 Ultra: A Flagship Multimodal MoE Foundation Model, Built for Stronger Intelligence and Unrivaled Efficiency Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE