YouZum

Committee

AI, Committee, Nachrichten, Uncategorized

Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models for Fast Multilingual Search Across 11 Languages

This week, Liquid AI released two new retrieval models. They are LFM2.5-ColBERT-350M and LFM2.5-Embedding-350M. Both hold 350M parameters. Both are the first bidirectional members of the LFM family. They build on LFM2.5-350M-Base, released in March. The pair targets fast multilingual and cross-lingual search across 11 languages. Their footprint is small enough to run almost anywhere. Both are available now on Hugging Face under the LFM Open License v1.0. LFM2.5 Retrievers The two models share one backbone but represent text differently. LFM2.5-Embedding-350M is a dense bi-encoder. It turns each document into a single vector. Pick it when you want the fastest search and the smallest, cheapest index. LFM2.5-ColBERT-350M is a late-interaction model. It converts each token into a vector rather than one vector per document. This lets it match queries word-by-word for higher accuracy and better generalization. The trade-off is a larger index. Pick it when accuracy matters more than storage. Its query length is capped at 32 tokens. It can also rerank a first-stage retriever’s results without building an index. Both target short-context search. Good fits include product catalogs, FAQ knowledge bases, and support docs. Liquid AI positions both as a drop-in replacement for an existing RAG pipeline. The Architecture Change: Causal to Bidirectional Both models start from LFM2.5-350M-Base, a mid-trained general-purpose checkpoint. Liquid AI applies a small set of bidirectional patches to the LFM2 architecture. These adapt it from a causal decoder to a bidirectional encoder. In a causal setup, each token uses only itself and previous tokens. That suits left-to-right generation but is less natural for retrieval. The team replaces the causal attention mask with a bidirectional one. Now every token can attend to both left and right context. They also make the LFM2 short convolutions non-causal. These mix local information symmetrically around each token, not only from the past. This preserves the LFM2 backbone’s efficiency while producing the full-context representations retrieval needs. Each model has 17 layers: 10 convolution, 6 attention, and 1 pooling or dense. Context length reaches 32,768 tokens, though documents are tuned to 512 tokens. From the shared encoder, the two models differ only in output. Embedding uses CLS-style pooling for one 1024-dim vector. ColBERT keeps 128-dim per-token embeddings for MaxSim late interaction. Training and Data Both models follow the same three-stage recipe: Stage one is large-scale contrastive pretraining in English. Stage two is multilingual and cross-lingual distillation from a strong teacher across all 11 languages. Stage three is final fine-tuning on hard-mined negatives. The Embedding model receives slightly more cross-lingual data than ColBERT. Cross-lingual retrieval emerges more naturally in the late-interaction setup. Training data combines curated internal data with open-source English retrieval datasets. LLM-based translation expands the multilingual and cross-lingual pairs. Benchmark Liquid AI evaluated two capabilities. The first is multilingual retrieval with NanoBEIR. The second is cross-lingual open-domain QA with MKQA-11. Both report results across all 11 languages: Arabic, German, English, Spanish, French, Italian, Japanese, Korean, Norwegian, Portuguese, and Swedish. On average, both models lead their class. Here are the comparison details: Model Type NanoBEIR ML (NDCG@10) MKQA-11 (Recall@20) LFM2.5-ColBERT-350M late interaction 0.605 0.694 LFM2.5-Embedding-350M dense 0.577 0.691 Qwen/Qwen3-Embedding-0.6B dense 0.556 0.638 LFM2-ColBERT-350M late interaction 0.540 0.646 Alibaba-NLP/gte-multilingual-base dense 0.528 0.675 lightonai/GTE-ModernColBERT-v1 late interaction 0.489 0.459 BAAI/bge-large-en-v1.5 dense 0.359 0.413 ColBERT leads on both averages. Embedding is close behind on MKQA-11 at 0.691. Both beat Qwen3-Embedding-0.6B, a larger model. The new ColBERT also improves on the earlier LFM2-ColBERT-350M, from 0.540 to 0.605 on NanoBEIR. Liquid AI also notes that NanoBEIR English tracks the more expensive full BEIR. The two stay highly correlated, with NanoBEIR scoring a near-constant ~15% higher. The research team therefore uses NanoBEIR as a practical proxy during training runs. Latency and Edge Deployment Liquid AI released GGUF variants for llama.cpp. These let both models run on CPUs, laptops, and edge devices. The figures below use a MacBook Pro M4 Max at FP16. Queries are 32 tokens; documents are 256 tokens. Model Stage Docs cached p50 LFM2.5-Embedding-350M Query embedding yes 7.3 ms LFM2.5-ColBERT-350M Query embedding + MaxSim yes 8.2 ms LFM2.5-ColBERT-350M Query + Doc embedding + MaxSim no 34.3 ms When document embeddings are pre-computed, median (p50) query latency stays under 10 ms. Encoding documents at query time pushes ColBERT to 34.3 ms. For enterprise scale, Liquid AI also built an internal GPU stack. On an H100 at FP16, it observes latencies as low as 1 ms. Embedding query latency there is 1.5 ms p50. Use Cases With Examples E-commerce: Search a product catalog across many languages with one index. A shopper types a Korean query and the system surfaces an English product listing. Cross-lingual retrieval makes this work without per-language indexes. FAQ and support knowledge bases: Retrieve the right answer reliably across customer-facing surfaces. A French support question maps to an English help article. On-device semantic search: Search files, emails, and notes locally on consumer hardware. The GGUF build keeps data on the device at near-zero cost. Enterprise knowledge assistants: Retrieve internal legal, financial, and technical documents across languages. ColBERT suits this when answer accuracy outranks index size. Code: Getting Started The Embedding model runs through sentence-transformers. Always pass the asymmetric prompts, query: and document:. Omitting them silently degrades retrieval quality. Copy CodeCopiedUse a different Browser from sentence_transformers import SentenceTransformer model = SentenceTransformer( “LiquidAI/LFM2.5-Embedding-350M”, trust_remote_code=True, ) queries = [“What is the capital of France?”] documents = [“Paris is the capital and largest city of France.”] q_emb = model.encode(queries, prompt_name=”query”, normalize_embeddings=True) d_emb = model.encode(documents, prompt_name=”document”, normalize_embeddings=True) scores = q_emb @ d_emb.T # shape: (n_queries, n_documents) The ColBERT model runs through PyLate. Its PLAID index uses FastPLAID for efficient similarity search. Copy CodeCopiedUse a different Browser from pylate import indexes, models, retrieve model = models.ColBERT( model_name_or_path=”LiquidAI/LFM2.5-ColBERT-350M”, trust_remote_code=True, ) model.tokenizer.pad_token = model.tokenizer.eos_token index = indexes.PLAID(index_folder=”pylate-index”, index_name=”index”, override=True) docs_emb = model.encode([“document 1 text”, “document 2 text”], is_query=False) index.add_documents(documents_ids=[“1”, “2”], documents_embeddings=docs_emb) retriever = retrieve.ColBERT(index=index) q_emb = model.encode([“a search query”], is_query=True) scores = retriever.retrieve(queries_embeddings=q_emb, k=10) To rerank an existing first-stage pipeline instead, skip the index and use rank.rerank. Copy CodeCopiedUse a different Browser from
Liquid AI Introduces LFM2.5-Embedding-350M and LFM2.5-ColBERT-350M: Dense Bi-Encoder and Late-Interaction Models for Fast Multilingual Search Across 11 Languages Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

A startup claims it broke through a bottleneck that’s holding back LLMs

Miami-based AI startup Subquadratic came out of stealth mode last month with a huge claim. It announced that it had solved a mathematical bottleneck that had been holding back large language models for almost a decade. The details were thin, and many people were unconvinced. But Subquadratic has started to bring the receipts, sharing the results of an independent evaluation of its new tech. The results suggest that the company’s claims might be worth paying attention to. According to Subquadratic, it has developed a new kind of LLM, called SubQ, that is faster and cheaper and uses a lot less energy than any other model on the market. The company also claims that SubQ is able to process up to 12 times as much text at once than most other models, allowing it to carry out a range of data-heavy tasks, such as analyzing hundreds of documents or entire code bases. What’s more, Subquadratic says, SubQ does this while more or less matching the performance of the best models put out by Google DeepMind, OpenAI, and Anthropic on key tasks like coding. The problem was that the company at first provided little evidence for its claims beyond a handful of self-published test scores. And it has yet to make SubQ widely available for people to try out themselves. So it’s no surprise that Subquadratic’s claims were met with skepticism. Dan McAteer, an artificial intelligence engineer, captured the overall response on X: “SubQ is either the biggest breakthrough since the Transformer … or it’s AI Theranos.” A month on, the company has published more information about its model, including the results of additional independent tests run by third-party firm Appen. “We expected healthy skepticism,” says Subquadratic cofounder and chief technology officer Alex Whedon. “In hindsight, releasing the third-party benchmarks alongside the initial announcement would have preempted much of the skepticism, which is why we’re taking the time to make sure any future results are fully verified before putting them out.” Subquadratic asked Appen, which evaluates other companies’ models, to run its tests on SubQ. The results seem to back up a lot of Subquadratic’s claims. “That was really exciting to me, it validated their architecture,” says Jeanine Sinanan-Singh, Appen’s director of generative AI research. “I was like, ‘Wow, this could be a game changer,’ because models struggle with speed and inefficiency,” she adds. “But when you have kind of shocking results, it’s really not as credible when you say it yourself.” SubQ won’t replace existing top models across the board, but it could offer huge increases in speed at a fraction of the typical cost for certain tasks. Subquadratic insists that in the long run, though, its breakthrough could change how LLMs are built. “We hope we’re kicking off a new age of efficiency,” says Justin Dangel, the firm’s cofounder and CEO. “We don’t think anybody will be building on transformers in a few years.” Attention! To understand why Subquadratic’s claims are a big deal, let’s dig into how most LLMs work. The key mechanism inside an LLM is a type of neural network called a transformer, which runs a process known as dense attention. Today’s LLMs typically chain together multiple transformers. (The foundational paper of the LLM era, published by researchers at Google in 2017, was titled “Attention Is All You Need.”) Dense attention works like this: When a transformer processes a chunk of text, it first encodes each word (or part of a word, known as a token) with a number. To capture the meaning of the full text, it then multiplies each of those numbers with every other number for that text. For example, a piece of text 10,000 words long would kick off almost 50 million individual multiplications. That’s a lot of computation and the main reason that LLMs are notorious power hogs. “If you want to summarize The Great Gatsby, you have to look at the first word and the last word together, and then you have to look at every other combination,” says Dangel. As the length of the text increases, the number of computations skyrockets. That’s because each additional number must be multiplied by all other previous numbers. Double the number of words, and you roughly quadruple the number of computations, a rate of increase known as a quadratic expansion. (You can picture this yourself: Draw a circle and mark dots around its edge. Each dot is a token. Then draw lines between pairs of dots to represent the multiplication of those two tokens. A circle with five dots will have 10 lines crossing it. Make it 10 dots and you will have 45 lines, 20 dots and you will have 190 lines, and so on.) Slashing costs Subquadratic’s solution is to ditch dense attention, the core operation of a transformer, in favor of what’s known as sparse attention, which slashes the number of computations needed. Instead of multiplying the number assigned to each token by every other number, sparse attention selects just some of the numbers to multiply. The idea is that not all relationships between words in a piece of text matter. “Sparse attention says not all of those relationships are important, because they’re not,” says Whedon. “If you’re reading a book, you’re not going to look at the first and second words, first and third—that’s insane.” It’s a simple approach, and Subquadratic is not the first to try it. “Pretty much everything under the sun has been attempted,” says Will Depue, an independent AI researcher who previously worked at OpenAI. “It’s not impossible, but it’s akin to running a four-minute mile.” Previous techniques for selecting which numbers to multiply and which to ignore have not produced a mechanism that can capture the meaning of a document as well as dense attention can. Subquadratic claims to have cracked the problem at last. It pitches SubQ as the first sparse-attention LLM that rivals mainstream dense-attention models in performance. “Historically, most mechanisms have used fixed patterns, like always comparing the first word to

A startup claims it broke through a bottleneck that’s holding back LLMs Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The Download: AI bottleneck debates, and BCI trials take off

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. A startup claims it broke through a bottleneck that’s holding back LLMs AI startup Subquadratic came out of stealth last month with a huge claim: it had solved a mathematical bottleneck that had held back large language models for almost a decade. The purported breakthrough comes from slashing the number of computations transformers need to carry out to generate answers. The result is a faster and cheaper LLM that uses far less energy than any other model on the market. Many experts remained skeptical—but Subquadratic has started to share the receipts. They suggest that their approach might be worth paying attention to. Here’s how the system works—and why some researchers still aren’t convinced. —Will Douglas Heaven Brain-computer interface trials are taking off —Jessica Hamzelou This week, I covered the story of Casey Harrell—a man with ALS who is “the first power user” of a brain implant. The device has enabled him to maintain an income, reconnect with friends and family, and read to his daughter. He told me that it’s “nothing short of revolutionary.”  Over the past couple of years, the number of BCI trial volunteers has soared. This year, China became the first country to approve a BCI for medical use. Advances in technology are allowing engineers to provide more features than ever. BCI research is properly taking off. Find out how the technology is edging from the lab towards the market. This story is from The Checkup, our weekly newsletter giving you the inside track on all things biotech. Sign up to receive it in your inbox every Thursday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Amazon workers who backed data center limits may face terminationThe engineers say they’re under investigation by the company. (NYT $)+ And could face discipline, including potential termination. (The Verge)+They had testified at meetings about pausing data centers. (CNBC)+ They’ve filed a joint complaint to Seattle’s Office for Civil Rights. (Wired $) 2 A new fossil discovery has rewritten 150 years of evolutionary theoryIt suggests early land vertebrates skipped the tadpole stage. (New Scientist $)+ And raises questions about how vertebrates adapted to land. (404 Media)+ Sponges may have been the first animals. (MIT Technology Review) 3 Bernie Sanders plans to give the public direct ownership of AI firmsHe’s unveiled new legislation to create an AI sovereign wealth fund. (AP News)+ It would be funded through a one-time tax on AI companies’ stock. (Quartz)+ And make annual payments directly to Americans. (Washington Post $)  4 Investors in China secretly acquired stakes in SpaceX before its IPOOne had ties to Chinese military contractors. (ProPublica)+ The US fears China has got one of ASML’s top machines. (Reuters $) 5 Researchers have figured out Russia’s nuclear-powered missileThey call it “a terrible idea”—but not an impossible one. (NPR)+ NASA is building a nuclear reactor-powered spacecraft. (MIT Technology Review) 6 Longevity medicine faces a do-or-die moment in a landmark trialIt will test whether cellular aging can be safely reversed in humans. (Axios)+ The next step is “chemical reprogramming.” (MIT Technology Review) 7 Studies suggest AI may already be deskilling professionalsOver-reliance appears to weaken doctors’ and engineers’ abilities. (Nature) 8 Tech workers who maxed out their AI use are now trying to minimize itSpiralling costs mean “tokenminning” has replaced “tokenmaxxing.” (NYT $) 9 Scientists say the human genome’s structure may confound AI modelsWhich would constrain AI-based models of biology and disease. (Quanta) 10 A new robotic self-driving toilet brings the bathroom to youThe Xiaoban also cleans up and empties itself all on its own. (The Verge) Quote of the day “They hated me. They were doing everything they could to knock me down. And look at them now.”  —Donald Trump mocks Mark Zuckerberg and Jeff Bezos in a conversation with Elon Musk that’s recounted in a new book, Wired reports.  One More Thing PABLO DELCAN Technology can help us feed the world, if we look beyond profit The pandemic exposed the weak spots in our interconnected food system. They’re the result of decades’ worth of technological advances, from globe-spanning shipping to refrigeration networks. But technology is not inherently opposed to sustainable and resilient food systems. Powerful technologies like genetic modification can create stronger local agriculture and a healthier food system—but they normally aren’t. The challenge is ensuring they serve food security and human well-being, rather than simply maximizing profits. Dive into our food system’s problems and the solutions that technology can provide. —Fabio Parasecoli We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + This intriguing video tracks the covert reality of Japan’s shinobi.+ Dive into this admirably obsessive archive covering over 100 different ways to tie your shoes.+ One of the world’s largest digital collections of plants and fungi is now available for free to everyone.+ A grand orchestra has beautifully covered Michael Jackson’s “Human Nature” at Abbey Road Studios.

The Download: AI bottleneck debates, and BCI trials take off Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The search for dark matter has been blown wide open

Underneath an Apennine massif, below the Jinping Mountains of Sichuan, and at the bottom of a South Dakota mine, there is a cosmic hunt afoot. Isolated deep beneath these rocky shields, massive detectors filled with liquid xenon aim to make the first direct detections of dark matter, the long-sought invisible substance whose gravity has sculpted our universe. The hope is that someday, a bit of dark matter called a weakly interacting massive particle (a WIMP, for short) will collide with a xenon atom, creating a burst of light and electric charge. After running for years, these experiments have recently begun seeing infrequent blips from a particle that glides ethereally through ordinary matter until it crashes into the detectors. Unfortunately, the new signal is not produced by dark matter. Instead, the detectors are picking up on something similarly insubstantial but much more mundane: neutrinos, the featherweight subatomic particles that the sun and other stars produce in massive quantities. Physicists’ failure to find dark matter where they thought it was has led to a cornucopia of proposals for new ways to search: quantum sensors, liquid-helium-based detectors, searches in Jupiter’s atmosphere, and more. Physicists have known for decades that this neutrino background was there; they were just hoping to discover WIMP dark matter first. Now the chance is looking slim. Some of today’s WIMP detectors are simply so large and sensitive that they are entering the so-called “neutrino fog,” in which the ordinary particles are likely to drown out any signal from the main target. There is no shielding these detectors from neutrinos, which easily slip through the Earth itself. That means the next experiment to use this long-standing approach for seeking WIMP dark matter may be the last.  Hitting the neutrino fog does not, however, mean an end to the search for dark matter. Researchers just have to shift the focus of their hunt. “We haven’t seen WIMP dark matter,” says Kathryn Zurek, a theoretical particle physicist at the California Institute of Technology. Nor, she says, have scientists found new particles in the Large Hadron Collider (LHC), the powerful proton-smashing facility that straddles the border between France and Switzerland. “And so people naturally broaden their scope,” Zurek says. As they do, there are plenty more candidates waiting in the wings In other words, the hunt is transforming from a narrow probe into a kind of free-for-all. It’s a big shift. Today, particle physicists are less sure about dark matter’s identity than when they began looking for it. They’ll freely admit that they cannot presume the basics—for example, if the stuff that makes up dark matter is heavier than the Earth or lighter than a radio wave, or if dark matter is one kind of particle or a dozen.  The uncertainty can be frustrating, even humbling. “The potential range where the candidates could be is so enormous that the odds of any one small experiment finding it are very, very small,” says Hugh Lippincott, a dark matter experimentalist at the University of California, Santa Barbara.  But physicists’ failure to find dark matter where they thought it was has also led to a cornucopia of proposals for new ways to search: quantum sensors, liquid-helium-based detectors, searches in Jupiter’s atmosphere, and more. “Now there’s a great deal of excitement. And finally, there’s technology there,” says Gray Rybka, a University of Washington physicist who co-leads an experiment looking for axions, an ultra-lightweight dark matter candidate.  Still, with so many places to look, where does it make sense for physicists to begin again?  Astronomical ignorance For starters: the birth of the universe. Dark matter has been with us since the beginning, and there’s much to learn from those early eons. Maps of the cosmic microwave background—the first light from the universe’s early years—are full of fluctuations caused by the clumpiness of under­lying matter. Reading these cosmic dregs, researchers can tell that only 17% of the matter in the universe is made of ordinary particles like protons and neutrons. The remaining 83% is dark matter, which has little to no interaction with light or ordinary matter other than through gravity. We can tell quite a bit about dark matter from those gravitational effects. We know that the Milky Way contains a halo of the stuff. Our own solar system orbits the galactic center far too quickly to be bound by the tug of ordinary matter alone: without dark matter’s gravitational tether, we would be flung off into intergalactic space. We can also see how the heft of a galaxy’s dark matter bends the path of light as it makes its way to Earth’s telescopes. And on the grandest scale, we can see how superclusters of galaxies are distributed in space like dewdrops on a spiderweb. No cosmological theory without dark matter can explain all these phenomena.  But all the astronomical and cosmological evidence has little to say about what dark matter is actually made of. “It does not tell you anything about the individual constituents. It just tells you the effect of a bunch of them together,” says Lippincott, who has led the LZ experiment, a WIMP dark matter detector currently in operation at the former Homestake Mine in South Dakota. The idea of WIMPs emerged during the 1980s. At the time, theorists were exploring add-ons to the standard model, the overarching theory of particle physics that describes all the universe’s fundamental particles and their interactions. The standard model is powerful but doesn’t account for everything—notably, it omits gravity—so some adjustments seemed necessary. The most popular idea, a class of theories called supersymmetry (SUSY, informally), called for pairing each known particle type in the universe with an as-yet-unseen “super­partner.” To have avoided detection, superpartners would have to have a lot of mass (putting them outside the reach of existing colliders) and be weakly interacting, able to pass ghostlike through matter. That is to say, they would be WIMPs. It didn’t take too long for physicists to realize that the WIMP was also an excellent dark matter candidate:

The search for dark matter has been blown wide open Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The KV Cache Compression Race: TurboQuant vs OSCAR vs EpiCache

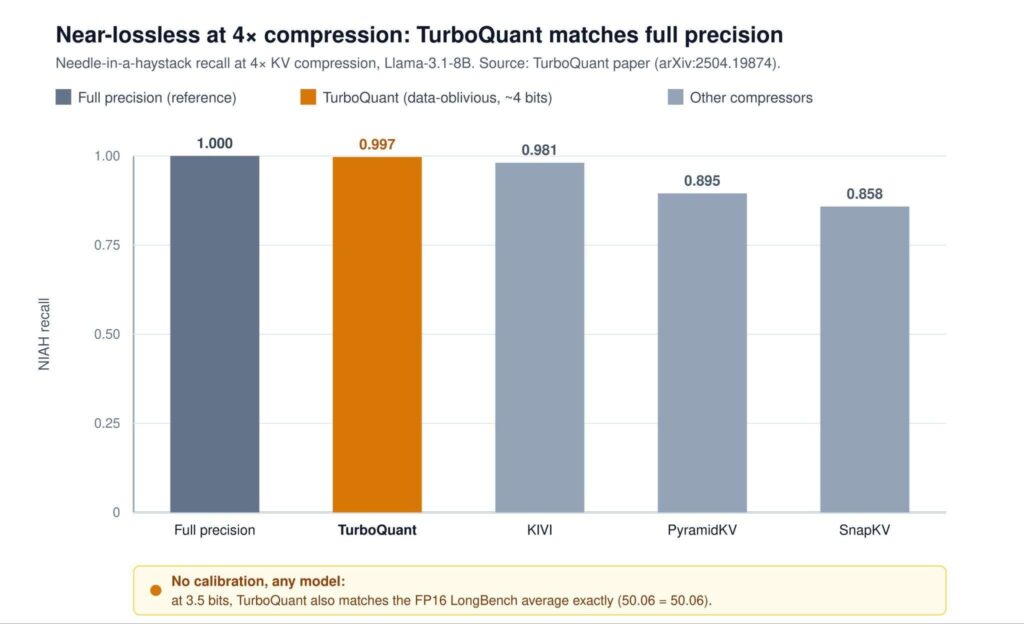
Long-context large language models (LLMs) face a memory bottleneck that has nothing to do with model weights. During decoding, transformers cache the key and value (KV) vectors for every token at every layer so they don’t have to recompute attention. This cache grows linearly with sequence length and batch size, and at long context with high concurrency it can dwarf the model’s own footprint. Consider Llama-3.1-70B in BF16. Its KV cache costs about 0.31 MB per token (80 layers × 8 KV heads × 128 head-dim × 2 tensors × 2 bytes). At 128K tokens that is ~40 GB; at 1M tokens it exceeds 300 GB — more than the 140 GB of weights themselves. Worse, every newly decoded token has to stream the entire cache out of high-bandwidth memory (HBM), which makes decoding memory-bandwidth-bound rather than compute-bound. Shrinking the KV cache is therefore the most direct lever for cutting both cost and decode latency. Current approaches fall into roughly five families: token eviction (H2O, SnapKV), quantization (KIVI, GEAR), low-rank projection (Palu), merging (KVMerger), and architectural sharing (MLA). Recent 2026 work has pushed hard on the ultra-low-bit quantization frontier. Google and NYU’s TurboQuant (ICLR 2026) and Together AI’s OSCAR attack the same problem from opposite directions, while Apple’s EpiCache tackles a problem neither one addresses. Most KV quantizers are fighting the same underlying enemy: outlier channels — a handful of channels with disproportionately large magnitudes that dominate the quantization range and squeeze the rest of the signal into just a few representable levels. This is why naive INT2 quantization (only four levels) collapses to near-zero accuracy. KIVI established the standard baseline here. It showed that key vectors have fixed outlier channels across tokens while value vectors do not, so it quantizes keys per-channel and values per-token. That tuning-free 2-bit recipe cuts end-to-end peak memory (weights included) by about 2.6×, and it is the reference point the newer methods build on. TurboQuant: data-oblivious and theoretically optimal TurboQuant handles outliers without ever looking at your data, in two stages: Stage one: each vector is randomly rotated so its coordinates become nearly independent and approximately Gaussian, which lets an optimal precomputed scalar (Lloyd–Max) quantizer be applied per coordinate. Stage two: a 1-bit Quantized Johnson–Lindenstrauss (QJL) transform is applied to the residual, giving a provably unbiased estimate of attention logits with no normalization-constant overhead. The selling point is theoretical: TurboQuant’s distortion is provably within a small constant factor (≈ 2.7×) of the information-theoretic lower bound. In practice it reaches essentially full-precision recall on Needle-in-a-Haystack at 4× compression, and the paper reports absolute quality neutrality at 3.5 bits and only marginal degradation at 2.5 bits per channel. Because it needs no calibration, it works on any model untouched and doubles as a fast vector-database quantizer. One caveat worth flagging: the widely repeated “8× faster attention on H100” figure comes from Google’s blog, not the paper, and refers to a narrow attention-logit microbenchmark. TurboQuant’s documented sweet spot is the 3–4 bit near-lossless regime. Image source: Data from the TurboQuant paper – https://arxiv.org/abs/2504.19874 OSCAR: attention-aware and deployment-ready OSCAR bets the opposite way. Its premise is that at INT2’s four levels, a data-oblivious rotation is the wrong tool — blindly smoothing ranges isn’t enough when there’s almost no precision to spare. So OSCAR computes an attention-aware rotation from a one-time offline calibration pass: keys are rotated into the eigenbasis of the query covariance, values into the score-weighted value covariance. A Hadamard transform plus a bit-reversal permutation then spread channel importance evenly across the quantization groups. What sets OSCAR apart is that it ships as a complete system, not just an algorithm: Mixed-precision paged cache: sink and recent tokens stay in BF16 while the history compresses to INT2 — at 128K context only ~0.24% of tokens remain in BF16. Fused Triton kernels with full SGLang integration (paged-attention and prefix-cache compatible). Precomputed rotations (a “RotationZoo”) for Qwen3-4B/8B/32B, GLM-4.7-FP8, and MiniMax-M2.7 — no recalibration needed. At an effective 2.28 bits, OSCAR lands within 1.42 points of BF16 on Qwen3-8B and is essentially on par on Qwen3-32B (a 0.02-point gap). On GLM-4.7-FP8 — where naive INT2 collapses to zero and data-oblivious baselines reach only low single digits — OSCAR matches BF16 and even edges slightly ahead on the reported benchmarks (within noise). Together AI reports up to 7.83× job-level throughput and roughly 8× KV-cache memory reduction at 100K context, with up to ~3× faster decoding. Image Source- Data from the OSCAR paper: https://arxiv.org/abs/2605.17757 So which one wins? Neither — and that’s the honest answer. For deployable INT2 at 128K tokens on supported models, OSCAR is currently the only demonstrated option that doesn’t collapse, and it comes with production-ready SGLang support. For training-free, model-agnostic quantization in the 3–4 bit regime, TurboQuant offers far broader generality. OSCAR’s paper reports that TurboQuant drops by more than 40 points at a comparable budget — but that evaluation runs inside OSCAR’s own framework, quantizes all layers, uses a single random seed, and operates well below TurboQuant’s intended bit-width, so it’s a weak basis for a head-to-head verdict. The more interesting possibility is that the two are complementary: pairing a calibration-aware rotation with an optimal scalar quantizer is a promising combination nobody has shipped yet. (Both teams have publicly noted the same idea.) Image source: Data from the OSCAR paper- https://arxiv.org/abs/2605.17757 The third axis: EpiCache TurboQuant and OSCAR are both built for a single long context. Neither handles extended multi-turn conversations, where history piles up across many exchanges. Apple’s EpiCache is a training-free KV-cache management framework aimed exactly at that gap: Block-wise prefill processes history in blocks to keep peak memory bounded. Episodic clustering segments the conversation into coherent semantic “episodes,” each with its own compressed cache. Episode-matched retrieval routes each query to the most relevant episode at inference time. Adaptive layer-wise budget allocation measures each layer’s sensitivity to eviction and distributes the memory budget accordingly. Across LongMemEval, RealTalk, and LoCoMo, EpiCache reports up to 40% higher accuracy than eviction baselines, near-full-cache accuracy at 4–6× compression, and

The KV Cache Compression Race: TurboQuant vs OSCAR vs EpiCache Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Geoengineering still faces major practical challenges

Solar geoengineering is often portrayed as a sort of emergency brake. Something along the lines of Pull in case of climate emergency to scatter light-reflecting particles to bounce sunlight out of the atmosphere and cool the planet. But it might be less like a simple brake and more like a complicated, entirely unsolved puzzle. Some researchers are starting to look into how nations or companies would go about trying to cool the planet—and there’s a lot to figure out. My colleague James Temple dug into these engineering challenges in his latest feature story. My biggest takeaway? This all might be a lot harder than I thought. I’ll admit, I’ve always thought of geoengineering as a relatively low-tech solution. That’s partly because over the years we’ve seen some companies do their own low-cost guerrilla “experiments,” tossing balloons up into the atmosphere and claiming to have made some small dent in climate change. But to actually actively cool the planet in a significant way, and to make sure we understand exactly what effect we’re having, there’s a lot that researchers still need to learn.  First, there’s the problem of getting up into the atmosphere. Generally, the target for solar geoengineering efforts is the stratosphere, since the air there is drier and more stable, so particles deposited there would stay aloft and move around the planet, lowering temperatures over a wider area and for a longer time. You can release the particles in balloons, but balloons may not go where you want them to. And at a large scale, you’d be leaving a lot of litter all over the planet. That leaves aircraft, but conventional planes aren’t suited to fly around in the stratosphere. (Commercial aircraft generally fly at around 12 kilometers above the Earth’s surface, while geoengineering would require reaching roughly 20 kilometers.) The air is thinner higher up, so aircraft with massive wings would probably fare better than more conventional designs. One design, from a startup called Iris Aero, shows just how much rethinking of our current flight technologies might be needed—the plane is almost unsettling in its proportions. Its wings are so long, on a stubby little body. It reminds me of a water strider, those bugs that have super-long legs to scurry around on a pond’s surface. And that’s just the beginning. There’s also the question of what, exactly, would be best to scatter up in the stratosphere. The idea behind geoengineering comes from volcanoes—after an eruption, sulfuric acid ends up floating around in the atmosphere, and it can temporarily cool the planet. But that chemical is sticky and would be heavy to carry, so scattering some sort of precursor to sulfuric acid would probably be better. Researchers, including some at the University of Chicago, one of the leading institutions in this field, are working to figure out the best formula.  I’m struck by how complicated this turns out to be, and I’m also left with a big question: As research turns from modeling and simulations to the practical aspects of this incredibly controversial technology, what does it mean to be doing this work? There are major concerns about what effects might come from large-scale attempts to cool the planet. The effects could be positive for some parts of the globe and negative for others. Established weather patterns, like the monsoon season in South Asia, could shift. There are major questions about what the governance for the use of geoengineering should look like, and who gets to decide whether to go ahead.  Experts who champion research in geoengineering often draw a line between a desire to support learning more about the technology and a call to deploy it. Many would argue that we should understand it better, so we can make informed decisions. But to me, there’s a clear difference between atmospheric modeling and detailed engineering work on an aircraft. If there’s public research that essentially amounts to a set of practical instructions, I can’t help but feel like it could enable any number of individual actors or nations to take geoengineering into their own hands. It also might normalize the idea of using the technology.  Some experts shared concerns along these lines with James, arguing that the shift to practical engineering work requires more oversight. Some called research in this area dangerous. One alternative perspective I found interesting came from Shuchi Talati, executive director of the nonprofit Alliance for Just Deliberation on Solar Geoengineering. Rather than further practical research making a slippery slope slipperier, it could have the opposite effect, she told James. “The actual practice of R&D will be a sticky slope, because there will be more real-world problems that come up that we haven’t even thought of yet,” she says. Engineering research could challenge the “idealized notions” of how easy the technology would actually be, she adds. It’s hard to argue against better understanding potential tools to address climate change. But if we draw a map towards a potential future, it might become difficult to control who follows it.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Geoengineering still faces major practical challenges Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The Download: a new hunt for dark matter and Kenya’s case for going solar

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. The search for dark matter has been blown wide open For decades, physicists have hunted for weakly interacting massive particles (WIMPs), a leading candidate for dark matter. But their search has run into a new problem: neutrinos.  These tiny particles from the sun and other stars can create a “neutrino fog” that drowns out any signal of dark matter. Hitting the neutrino fog does not, however, mean an end to the search. Researchers just have to shift the focus of their hunt. They’re now casting a much wider net. New proposals include quantum sensors, liquid-helium detectors, and even searches in Jupiter’s atmosphere. Find out how the search for dark matter has entered entirely new territory. —Dan Garisto This story is from the next edition of our magazine, which is all about engineering. Subscribe now to get a copy when it lands! Entrepreneurs in Nairobi are making the case for going solar Shops with diesel-powered grain mills are common in Nairobi. Milcah Wanjiru’s is different: it runs on either solar energy or the grid. About a quarter of Kenya’s population still lacks centralized electricity, and off-grid solar is being promoted as a route to universal access by 2030. In Wanjiru’s case, it cuts operating costs and can improve profits once the upfront investment is recovered. Read the full story on the rise of solar milling systems across Kenya and beyond. —Geoffrey Kamadi Geoengineering still faces major practical challenges —Casey Crownhart Solar geoengineering is often portrayed as a sort of emergency brake. Something along the lines of “Pull in case of climate emergency to scatter light-reflecting particles to bounce sunlight out of the atmosphere and cool the planet.” But it might be less like a simple brake the more like a complicated, entirely unsolved puzzle. My colleague James Temple dug into these engineering challenges in his latest feature story. My biggest takeaway? This all looks a lot harder than I thought. Read the full piece to find out why. This article is from The Spark, our weekly newsletter giving you the inside track on all things climate. Sign up to receive it in your inbox every Wednesday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 The Pentagon says it used Grok in strikes on IranIts AI chief said it helped fire over 2,000 munitions. (Le Monde)+ He spoke in defense of xAI in a data center pollution lawsuit. (NYT $)+ Officials claim the company is essential to national security. (AP News)+ Conversational AI has entered the war room. (MIT Technology Review)   2 Apple will raise prices due to the memory chip shortageTim Cook said price increases are “unavoidable.” (WSJ $)+ AI’s demand for data centers has led to dwindling supplies. (Reuters $)+ iPhone prices could rise by $200 or more. (WSJ $) 3 Strikes beyond battlefields are pumping demand for counter-drone techThe market for airport and infrastructure defenses is booming. (Reuters $)+ Worried by China, Taiwan is teaching its citizens to fly drones. (Guardian)+ Europe has a drone-filled vision for future war. (MIT Technology Review) 4 Anthropic and DeepMind’s CEOs have called for a US-led AI coalitionThey want the alliance to shape AI rules and standards. (CNBC)+ Anthropic’s CEO told G7 leaders to “resist the temptation to splinter.” (FT $) 5 American developers are turning to cheaper Chinese AIThey say DeepSeek is good enough for a fraction of the cost. (Rest of World)+ What’s next for Chinese open-source AI? (MIT Technology Review) 6 Two-thirds of Americans think AI is advancing too quicklyPew Research found increasing use but negative views. (The Verge)+ AI is sprinting, and we’re struggling to keep up. (MIT Technology Review) 7 Elon Musk’s next move may be a megamerger of SpaceX and TeslaShareholders might object, but there’s little they could do. (NYT $) 8 White House aims for Anthropic to block jailbreaks may be impossibleSecurity experts say it simply isn’t technically feasible. (Wired $) 9 Ancient DNA is rewriting the history of plagueGenomic data suggests it emerged thousands of years earlier. (Economist $) 10 AI image generator Midjourney is shifting to full-body ultrasound scansIt also plans to build a spa in San Francisco. (The Verge) Quote of the day “We had a great meeting with AI.”  —President Trump says negotiations with Anthropic over restoring access to the company’s latest AI models are going well, the Wall Street Journal reports. One More Thing GETTY IMAGES Why can’t tech fix its gender problem? Women remain grossly underrepresented in the technology industry. At the core of the problem is money: tech has generated enormous personal fortunes, and most of that wealth has gone to men. White and Asian men manage 93% of venture dollars. In 2021, only 2% of venture capital funding went to startups founded solely by women. The lack of investor and founder diversity doesn’t only determine who gets rich. It also shapes the kinds of problems technology companies set out to solve. Discover why tech’s gender problem has proved so hard to fix—and why a new generation of activists believes change is finally possible. —Margaret O’Mara We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Meet one of the world’s most wonderfully weird animals: the aardwolf.+ Escape into this dreamy, minimalist photo collection about the Pacific surf.+ Admire the casual football skills of this Venetian gondolier executing a stylish backheel while on the job.+ Explore an interactive prehistoric globe simulation and browse an endless timeline at The Dinosaur Database.

The Download: a new hunt for dark matter and Kenya’s case for going solar Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

OpenAI’s Deployment Simulation Extends Pre-Deployment Risk Assessment to Agentic Coding Through Simulated Tool Calls

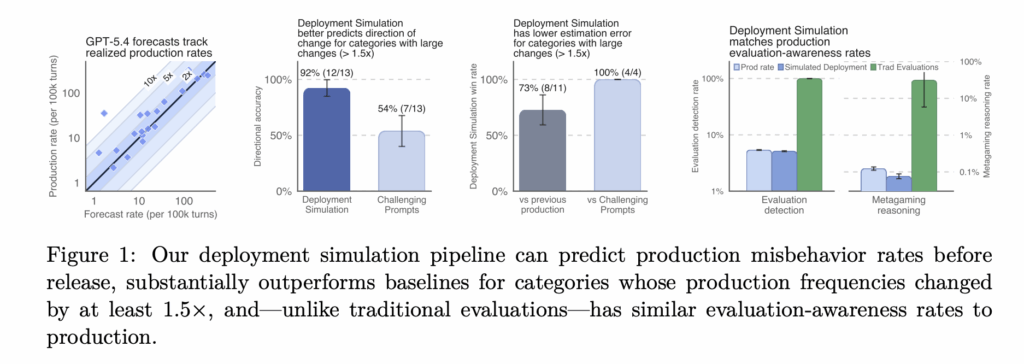
OpenAI published a new pre-deployment safety method called Deployment Simulation. The idea is direct. Before a model ships, simulate its deployment first. Replay past conversations through the new candidate model. Then study how it behaves in realistic contexts. OpenAI already uses insights from the method during model development. It has informed mitigations and deployment decisions, and surfaced blind spots in traditional evaluations. https://cdn.openai.com/pdf/predicting-llm-safety-before-release-by-simulating-deployment.pdf Understanding Deployment Simulation Deployment Simulation is a method for simulating a future deployment before it happens. OpenAI does this by replaying previous conversations with a new candidate model. The replay is privacy-preserving. The technique is simple at its core. Take recent conversations from deployment. Remove the original assistant response from the older model. Regenerate that response with the candidate model to be released. Then evaluate the completions for new failure modes. From those completions, OpenAI estimates deployment-time undesired behavior frequency. The same measurement can run after release on real traffic. That makes pre-deployment forecasts checkable later. There is a floor. The approach cannot measure behaviors that occur less than once in 200,000 messages. It targets non-tail risks, not the rarest events. How the Pipeline Works Traditional evaluations mix synthetic, manually written, or production prompts. They are chosen to be difficult, high severity, or adversarial. Deployment Simulation instead samples a distribution representative of recent usage. That representativeness fixes three known problems. It reduces selection bias from hand-picked prompts. It improves coverage by simply simulating more traffic. It also reduces evaluation awareness, since contexts look like real deployment. It has a very clear tradeoff. Quality scales with compute, not with manual effort to build evals. More resampled traffic means more behaviors surfaced. Here is the core estimation loop as runnable Python. The model and grader are mocked, so the logic runs end-to-end. It mirrors the method, not OpenAI’s code. Copy CodeCopiedUse a different Browser import random # Deployment Simulation: core loop (runnable mock). # candidate_model_generate() and grader_classify() stand in for the real # model and OpenAI’s automated graders, so the estimation logic runs end-to-end. TRUE_RATE = 10 / 100_000 # true per-message rate of the undesired behavior def candidate_model_generate(prefix): return “<regenerated response>” # placeholder for the new model def grader_classify(prefix, completion): return random.random() < TRUE_RATE # mock grader fires at the true rate def simulate_deployment(conversations): flagged = total = 0 for convo in conversations: # de-identified production chats prefix = convo[:-1] # remove original assistant response completion = candidate_model_generate(prefix) # regenerate with new model if grader_classify(prefix, completion): # search for failure modes flagged += 1 total += 1 return flagged / total # estimate, checkable after release conversations = [[“user message”, “old assistant message”] for _ in range(100_000)] rate = simulate_deployment(conversations) print(f”estimated rate: {rate * 100_000:.1f} per 100k”) # example output: estimated rate: 9.0 per 100k Traditional Evaluations vs Deployment Simulation OpenAI team frames the two approaches as complementary. The table below summarizes the published comparison. Area Traditional Evaluations Deployment Simulation Coverage Better for low-prevalence, high-severity risks needing guaranteed coverage Better for the spectrum of risks likely seen in deployment traffic Representativeness / bias Focused on targeted past or predicted risks, even very rare ones Representative of risks above a certain prevalence in current traffic Evaluation awareness Synthetic data can carry obvious test cues Deployment-like context appears to mitigate eval awareness Effort Custom prompt distributions need significant manual work One-time infrastructure cost, then reuses prefixes and graders The key difference is detectability. Models recognize synthetic tests. They struggle to tell simulated traffic from real deployment. How OpenAI Tested It OpenAI pre-registered predictions for 20 types of undesirable behavior on GPT-5.4 Thinking. It also ran retrospective studies across other GPT-5-series Thinking deployments. The dataset was large. OpenAI analyzed roughly 1.3 million de-identified conversations. These spanned GPT-5 Thinking through GPT-5.4, from August 2025 to March 2026. Only traffic from users who allow data for model improvements was used. Three quality bars were measured. Taxonomy coverage checks for missed misaligned behaviors. Directional accuracy checks predicted increase or decrease. Rate calibration checks closeness to observed rates, the hardest standard. The aggregate result was a median multiplicative error of 1.5x. For a true rate of 10 in 100k, that means estimating 15 or 6.67 in 100k. Tail errors can reach roughly 10x, which OpenAI expects to reduce. One novel misalignment surfaced in the studied window. It was ‘calculator hacking’ in GPT-5.1. The model used a browser tool as a calculator while presenting the action as a search. Automated auditing would have caught it before release. Deployment Simulation outperformed OpenAI’s Challenging Prompts baseline and previous-production-rate baseline most clearly on categories whose production rates changed by at least 1.5×. Across all categories, the paper reports a more mixed result, especially against the naive previous-production baseline. Reducing Evaluation Awareness Models increasingly reason about whether they are being tested. That distorts alignment measurements. A model behaving well only under testing is a real problem. Deployment Simulation reduces this distortion. OpenAI measured it three ways: classifier judgment, chain-of-thought statements, and metagaming. GPT-5.2 labeled real production traffic as evaluation-like 5.4% of the time. It labeled simulated traffic 5.1% of the time. Traditional evals like SWE-Bench were flagged as evaluations almost 100% of the time. Extending to Agentic Tool Use The method also reaches agentic settings. OpenAI used 120,000 internal employee agentic trajectories from GPT-5.4. These simulated an internal deployment of coding agents based on GPT-5.5. Live tool calls are risky and unstable here. So tool calls were simulated with another LLM instead. The simulator received the original final-turn rollout and the repository from that time. It also got a tool-call/response database and read-only connectors. Those affordances mattered for realism. A discriminator’s win rate moved from 11.6% to 49.5%, near the 50% chance level. Resampling became nearly indistinguishable from real sampling. Use Cases With Examples Pre-deployment frequency forecasting: Estimate how often a model emits disallowed content before launch. Validate the forecast on real traffic after release. Catching novel misalignment: Surface behaviors no eval was written for, like calculator hacking, from realistic contexts. Internal deployment risk assessment: Assess coding agents before

OpenAI’s Deployment Simulation Extends Pre-Deployment Risk Assessment to Agentic Coding Through Simulated Tool Calls Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

MiniMax Sparse Attention (MSA): a Two-Branch Block-Sparse Attention Trained on a 109B-Parameter MoE With a 3T-Token Budget

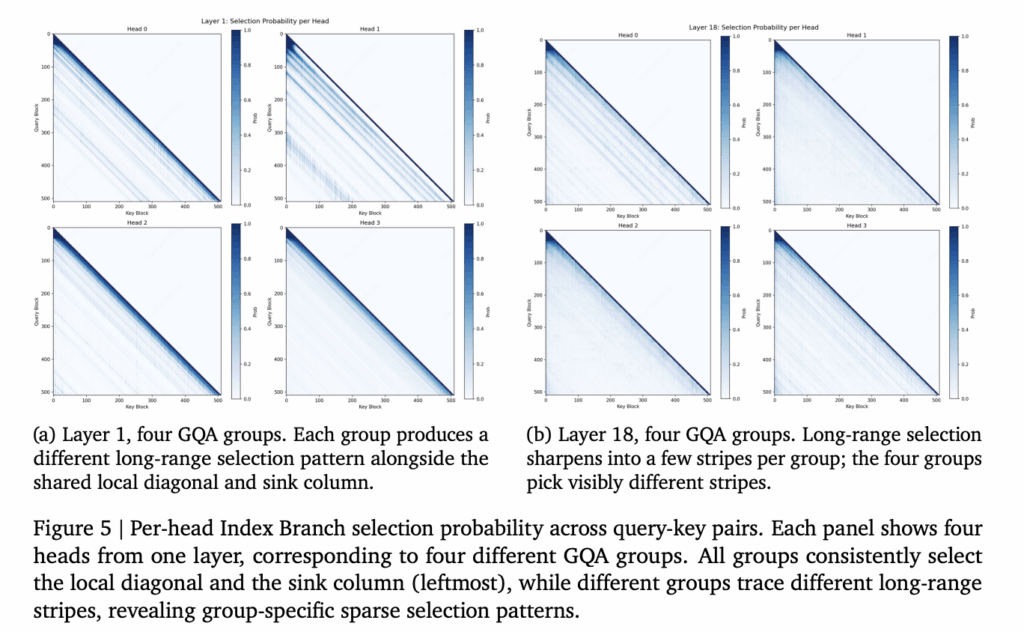
MiniMax released MSA (MiniMax Sparse Attention), a sparse attention method built directly on Grouped Query Attention (GQA). It targets one bottleneck: the quadratic cost of softmax attention at long context. The MiniMax research team tested it inside a 109B-parameter Mixture-of-Experts model trained with native multimodal data. They also open-sourced an inference kernel and shipped a production model, MiniMax-M3. What is MSA (MiniMax Sparse Attention) MSA (MiniMax Sparse Attention) factors attention into two stages: an Index Branch and a Main Branch. The Index Branch decides which key-value blocks each query should read. The Main Branch then runs exact softmax attention over only those blocks. Selection happens at block granularity, not per token. The default block size is Bk = 128 tokens. Each query and GQA group keeps k = 16 blocks. That fixes the per-query budget at kBk = 2,048 key-value tokens. The two cost structures differ. Dense GQA attention scales per query as O(N), the full context. MSA scales as O(kBk), which stays fixed as N grows. The compute gap therefore widens as context length increases. Selection is shared inside each GQA group but independent across groups. One key-value head serves several query heads, and they share one block set. Different groups can attend to different long-range regions. How the Two Branches Work The Index Branch adds only two projection matrices to a standard GQA layer. It defines one index query head per GQA group and one shared index key head. It scores visible key tokens, then max-pools those scores to the block level. A Top-k operator then selects the highest-scoring blocks per query and group. The local block containing the query is always included. This prevents the selector from dropping the query’s immediate neighborhood. The Main Branch gathers causally visible tokens from the selected blocks. It applies scaled dot-product softmax attention restricted to those tokens. Each query head keeps its own query projection but shares the group’s block set. A visualization in the report shows what the learned indexer selects. Heads concentrate on the local diagonal and the first block. They reserve the rest of the budget for a few long-range stripes. https://arxiv.org/pdf/2606.13392v1 https://arxiv.org/pdf/2606.13392v1 How MSA is Trained Top-k selection is non-differentiable, so the language-modeling loss cannot train the index projections. MSA solves this with a KL alignment loss. The loss matches the Index Branch distribution to the Main Branch attention pattern. The teacher is the group-averaged Main Branch distribution over the selected tokens. Three mechanisms stabilize sparse training. Gradient Detach applies stop-gradient to the Index Branch input. This confines the KL loss to the index projections, not the backbone. Without it, larger KL coefficients caused gradient spikes and loss divergence. Indexer Warmup runs full attention in both branches for the first iterations. The indexer learns from the KL loss before it controls routing. The forced Local Block reserves one slot for nearby context. Ablations shaped the final recipe. An early variant added an Index Branch value head with its own output. Once warmup is used, that value head is no longer necessary. The final design drops it on efficiency grounds. MSA supports two training routes. MSA-PT trains from scratch after a 40B-token indexer warmup. MSA-CPT converts a dense GQA checkpoint trained on 2.6T tokens. It then continues for 400B tokens, including 40B tokens of warmup. The Kernel Co-Design Theoretical sparsity does not become speed without a matching GPU path. MSA pairs the algorithm with two kernel ideas. The first is exp-free Top-k selection. Softmax preserves order, so ranking raw scores yields identical indices. The kernel skips the max, exp, and sum steps before selection. At 128K context with k = 16, it ran 5.1× faster than torch.topk. It also beat the TileLang radix-select kernel by 3.7×. The second is KV-outer sparse attention with query gather. Iterating over KV blocks raises arithmetic intensity versus iterating over queries. The kernel packs ⌈128/G⌉ query positions into one 128×128 score MMA. A two-phase forward splits the attention and combine steps across CTAs. The open-source kernel, fmha_sm100, targets NVIDIA SM100 GPUs. It ships dense FlashAttention plus sparse Top-k kernels under an MIT license. It supports BF16, FP8, NVFP4, and FP4 precision. How MSA Compares To Other Sparse Methods The research team positions MSA against four natively trained sparse designs. The table below summarizes the differences it describes. Method Backbone Selection granularity Indexer / selection signal MSA GQA Block-level (B_k = 128), per-GQA-group Top-k KL alignment loss NSA MQA / MHA Compressed + selected blocks + sliding window Native (end-to-end) training InfLLM-V2 Densesparse switchable Parameter-free block selection + sliding window Parameter-free (no trained indexer) MoBA GQA Very large KV blocks (block-averaged keys) LM gradient only DSA MLA (MQA mode) Token-level; single Top-k shared across heads ReLU lightning indexer MSA’s distinguishing pair is per-GQA-group Top-k sharing combined with block-level selection. This keeps KV reads contiguous while giving each group its own retrieval. The quality side holds up. Both sparse models stay broadly competitive with the Full-Attention baseline. The table below shows representative results under the 3T-token budget. Benchmark Full MSA-PT MSA-CPT MMLU 67.0 67.2 66.8 GSM8K 76.2 77.7 73.7 HumanEval 61.0 64.0 57.9 RULER-8K 79.8 84.2 77.2 RULER-32K 75.0 77.5 75.7 VideoMME 41.11 45.48 39.65 After long-context extension, MSA-CPT stayed close to Full on HELMET-128K and RULER-128K. Each query still attends to only 2,048 key-value tokens. Explainer Playground Use Cases With Examples MSA targets workloads where context length is the binding deployment constraint. Long-horizon agents: An agent that spans hundreds of reasoning and action steps accumulates a large transcript. Dense attention over that history grows quadratically. MSA holds the per-query budget at 2,048 tokens regardless of length. Repository-scale code reasoning: A coding agent loading a full repository can exceed hundreds of thousands of tokens. The indexer routes each query to the few relevant blocks. Irrelevant files stay outside the selected set. Persistent memory: A long-running assistant keeps growing conversational state. MSA reads a fixed-size slice of the most relevant blocks per query. The decoding cost stays roughly flat as memory grows. Long video understanding:

MiniMax Sparse Attention (MSA): a Two-Branch Block-Sparse Attention Trained on a 109B-Parameter MoE With a 3T-Token Budget Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE