YouZum

Committee

AI, Committee, Nachrichten, Uncategorized

NVIDIA AI Releases Nemotron-Elastic-12B: A Single AI Model that Gives You 6B/9B/12B Variants without Extra Training Cost

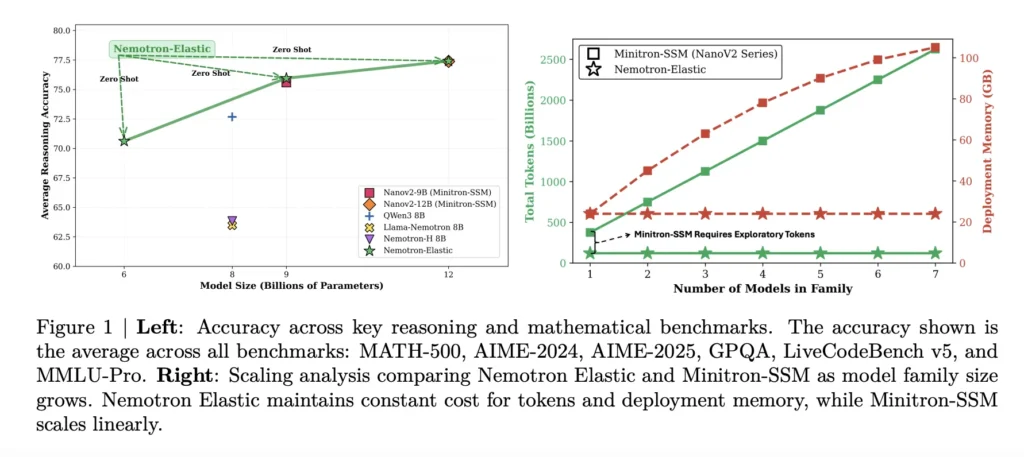
Why are AI dev teams still training and storing multiple large language models for different deployment needs when one elastic model can generate several sizes at the same cost? NVIDIA is collapsing the usual ‘model family’ stack into a single training job. NVIDIA AI team releases Nemotron-Elastic-12B, a 12B parameter reasoning model that embeds nested 9B and 6B variants in the same parameter space, so all three sizes come from one elastic checkpoint with no extra distillation runs per size. Many in one model family Most production systems need several model sizes, a larger model for server side workloads, a mid size model for strong edge GPUs, and a smaller model for tight latency or power budgets. The usual pipeline trains or distills each size separately, so token cost and checkpoint storage scale with the number of variants. Nemotron Elastic takes a different route. It starts from the Nemotron Nano V2 12B reasoning model and trains an elastic hybrid Mamba Attention network that exposes multiple nested submodels. The released Nemotron-Elastic-12B checkpoint can be sliced into 9B and 6B variants, Nemotron-Elastic-9B and Nemotron-Elastic-6B, using a provided slicing script, without any extra optimization. All variants share weights and routing metadata, so training cost and deployment memory are tied to the largest model, not to the number of sizes in the family. https://arxiv.org/pdf/2511.16664v1 Hybrid Mamba Transformer with elastic masks Architecturally, Nemotron Elastic is a Mamba-2 Transformer hybrid. The base network follows the Nemotron-H style design, where most layers are Mamba-2 based sequence state space blocks plus MLP, and a small set of attention layers preserve global receptive field. Elasticity is implemented by turning this hybrid into a dynamic model controlled by masks: Width, embedding channels, Mamba heads and head channels, attention heads, and FFN intermediate size can be reduced through binary masks. Depth, layers can be dropped according to a learned importance ordering, with residual paths preserving signal flow. A router module outputs discrete configuration choices per budget. These choices are converted to masks with Gumbel Softmax, then applied to embeddings, Mamba projections, attention projections, and FFN matrices. The research team adds several details to keep the SSM structure valid: Group aware SSM elastification that respects Mamba head and channel grouping. Heterogeneous MLP elastification where different layers can have distinct intermediate sizes. Normalized MSE based layer importance to decide which layers stay when depth is reduced. Smaller variants are always prefix selections in the ranked component lists, which makes the 6B and 9B models true nested subnetworks of the 12B parent. https://arxiv.org/pdf/2511.16664v1 Two stage training for reasoning workloads Nemotron Elastic is trained as a reasoning model with a frozen teacher. The teacher is the original Nemotron-Nano-V2-12B reasoning model. The elastic-12B student is optimized jointly for all three budgets, 6B, 9B, 12B, using knowledge distillation plus language modeling loss. Training runs in two stages: Stage 1: short context, sequence length 8192, batch size 1536, around 65B tokens, with uniform sampling over the three budgets. Stage 2: extended context, sequence length 49152, batch size 512, around 45B tokens, with non uniform sampling that favors the full 12B budget. https://arxiv.org/pdf/2511.16664v1 The second stage is important for reasoning tasks. The above table shows that for AIME 2025, the 6B model improves from 56.88 to 68.13, a 19.8 percent relative gain, while the 9B model gains 9.7 percent and the 12B model gains 4.0 percent after extended context training. Budget sampling is also tuned. In Stage 2, non uniform weights of 0.5, 0.3, 0.2 for 12B, 9B, 6B avoid degradation of the largest model and keep all variants competitive on Math 500, AIME 2025, and GPQA. Benchmark results Nemotron Elastic is evaluated on reasoning heavy benchmarks, MATH 500, AIME 2024, AIME 2025, GPQA, LiveCodeBench v5, and MMLU Pro. The below table summarizes pass at 1 accuracy. https://arxiv.org/pdf/2511.16664v1 The 12B elastic model matches the NanoV2-12B baseline on average, 77.41 versus 77.38, while also providing 9B and 6B variants from the same run. The 9B elastic model tracks the NanoV2-9B baseline closely, 75.95 versus 75.99. The 6B elastic model reaches 70.61, slightly below Qwen3-8B at 72.68 but still strong for its parameter count given that it is not trained separately. Training token and memory savings Nemotron Elastic targets the cost problem directly. The below table compares the token budgets needed to derive 6B and 9B models from a 12B parent: NanoV2 pretraining for 6B and 9B, 40T tokens total. NanoV2 Compression with Minitron SSM, 480B exploratory plus 270B final, 750B tokens. Nemotron Elastic, 110B tokens in a single elastic distillation run. https://arxiv.org/pdf/2511.16664v1 The research team reports that this gives around 360 times reduction versus training the two extra models from scratch, and around 7 times reduction versus the compression baseline. Deployment memory is reduced as well. The below table states that storing Nemotron Elastic 6B, 9B, and 12B together requires 24GB of BF16 weights, while storing NanoV2 9B plus 12B requires 42GB. This is a 43 percent memory reduction while also exposing an extra 6B size. https://arxiv.org/pdf/2511.16664v1 Comparison System Sizes (B) Avg reasoning score* Tokens for 6B + 9B BF16 memory Nemotron Elastic 6, 9, 12 70.61 / 75.95 / 77.41 110B 24GB NanoV2 Compression 9, 12 75.99 / 77.38 750B 42GB Qwen3 8 72.68 n / a n / a Key Takeaways Nemotron Elastic trains one 12B reasoning model that contains nested 9B and 6B variants which can be extracted zero shot without extra training. The elastic family uses a hybrid Mamba-2 and Transformer architecture plus a learned router that applies structured masks over width and depth to define each submodel. The approach needs 110B training tokens to derive 6B and 9B from the 12B parent which is about 7 times fewer tokens than the 750B token Minitron SSM compression baseline and about 360 times fewer than training extra models from scratch. On reasoning benchmarks such as MATH 500, AIME 2024 and 2025, GPQA, LiveCodeBench and MMLU Pro the 6B, 9B and 12B elastic models reach average scores of about 70.61, 75.95 and 77.41 which are on par
NVIDIA AI Releases Nemotron-Elastic-12B: A Single AI Model that Gives You 6B/9B/12B Variants without Extra Training Cost Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Lean4: How the theorem prover works and why it’s the new competitive edge in AI

Large language models (LLMs) have astounded the world with their capabilities, yet they remain plagued by unpredictability and hallucinations – confidently outputting incorrect information. In high-stakes domains like finance, medicine or autonomous systems, such unreliability is unacceptable. Enter Lean4, an open-source programming language and interactive theorem prover becoming a key tool to inject rigor and certainty into AI systems. By leveraging formal verification, Lean4 promises to make AI safer, more secure and deterministic in its functionality. Let’s explore how Lean4 is being adopted by AI leaders and why it could become foundational for building trustworthy AI. What is Lean4 and why it matters Lean4 is both a programming language and a proof assistant designed for formal verification. Every theorem or program written in Lean4 must pass a strict type-checking by Lean’s trusted kernel, yielding a binary verdict: A statement either checks out as correct or it doesn’t. This all-or-nothing verification means there’s no room for ambiguity – a property or result is proven true or it fails. Such rigorous checking “dramatically increases the reliability” of anything formalized in Lean4. In other words, Lean4 provides a framework where correctness is mathematically guaranteed, not just hoped for. This level of certainty is precisely what today’s AI systems lack. Modern AI outputs are generated by complex neural networks with probabilistic behavior. Ask the same question twice and you might get different answers. By contrast, a Lean4 proof or program will behave deterministically – given the same input, it produces the same verified result every time. This determinism and transparency (every inference step can be audited) make Lean4 an appealing antidote to AI’s unpredictability. Key advantages of Lean4’s formal verification: Precision and reliability: Formal proofs avoid ambiguity through strict logic, ensuring each reasoning step is valid and results are correct. Systematic verification: Lean4 can formally verify that a solution meets all specified conditions or axioms, acting as an objective referee for correctness. Transparency and reproducibility: Anyone can independently check a Lean4 proof, and the outcome will be the same – a stark contrast to the opaque reasoning of neural networks. In essence, Lean4 brings the gold standard of mathematical rigor to computing and AI. It enables us to turn an AI’s claim (“I found a solution”) into a formally checkable proof that is indeed correct. This capability is proving to be a game-changer in several aspects of AI development. Lean4 as a safety net for LLMs One of the most exciting intersections of Lean4 and AI is in improving LLM accuracy and safety. Research groups and startups are now combining LLMs’ natural language prowess with Lean4’s formal checks to create AI systems that reason correctly by construction. Consider the problem of AI hallucinations, when an AI confidently asserts false information. Instead of adding more opaque patches (like heuristic penalties or reinforcement tweaks), why not prevent hallucinations by having the AI prove its statements? That’s exactly what some recent efforts do. For example, a 2025 research framework called Safe uses Lean4 to verify each step of an LLM’s reasoning. The idea is simple but powerful: Each step in the AI’s chain-of-thought (CoT) translates the claim into Lean4’s formal language and the AI (or a proof assistant) provides a proof. If the proof fails, the system knows the reasoning was flawed – a clear indicator of a hallucination. This step-by-step formal audit trail dramatically improves reliability, catching mistakes as they happen and providing checkable evidence for every conclusion. The approach that has shown “significant performance improvement while offering interpretable and verifiable evidence” of correctness. Another prominent example is Harmonic AI, a startup co-founded by Vlad Tenev (of Robinhood fame) that tackles hallucinations in AI. Harmonic’s system, Aristotle, solves math problems by generating Lean4 proofs for its answers and formally verifying them before responding to the user. “[Aristotle] formally verifies the output… we actually do guarantee that there’s no hallucinations,” Harmonic’s CEO explains. In practical terms, Aristotle writes a solution in Lean4’s language and runs the Lean4 checker. Only if the proof checks out as correct does it present the answer. This yields a “hallucination-free” math chatbot – a bold claim, but one backed by Lean4’s deterministic proof checking. Crucially, this method isn’t limited to toy problems. Harmonic reports that Aristotle achieved a gold-medal level performance on the 2025 International Math Olympiad problems, the key difference that its solutions were formally verified, unlike other AI models that merely gave answers in English. In other words, where tech giants Google and OpenAI also reached human-champion level on math questions, Aristotle did so with a proof in hand. The takeaway for AI safety is compelling: When an answer comes with a Lean4 proof, you don’t have to trust the AI – you can check it. This approach could be extended to many domains. We could imagine an LLM assistant for finance that provides an answer only if it can generate a formal proof that it adheres to accounting rules or legal constraints. Or, an AI scientific adviser that outputs a hypothesis alongside a Lean4 proof of consistency with known physics laws. The pattern is the same – Lean4 acts as a rigorous safety net, filtering out incorrect or unverified results. As one AI researcher from Safe put it, “the gold standard for supporting a claim is to provide a proof,” and now AI can attempt exactly that. Building secure and reliable systems with Lean4 Lean4’s value isn’t confined to pure reasoning tasks; it’s also poised to revolutionize software security and reliability in the age of AI. Bugs and vulnerabilities in software are essentially small logic errors that slip through human testing. What if AI-assisted programming could eliminate those by using Lean4 to verify code correctness? In formal methods circles, it’s well known that provably correct code can “eliminate entire classes of vulnerabilities [and] mitigate critical system failures.” Lean4 enables writing programs with proofs of properties like “this code never crashes or exposes data.” However, historically, writing such verified code has been labor-intensive and required specialized expertise. Now, with

Lean4: How the theorem prover works and why it’s the new competitive edge in AI Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Moonshot AI Researchers Introduce Seer: An Online Context Learning System for Fast Synchronous Reinforcement Learning RL Rollouts

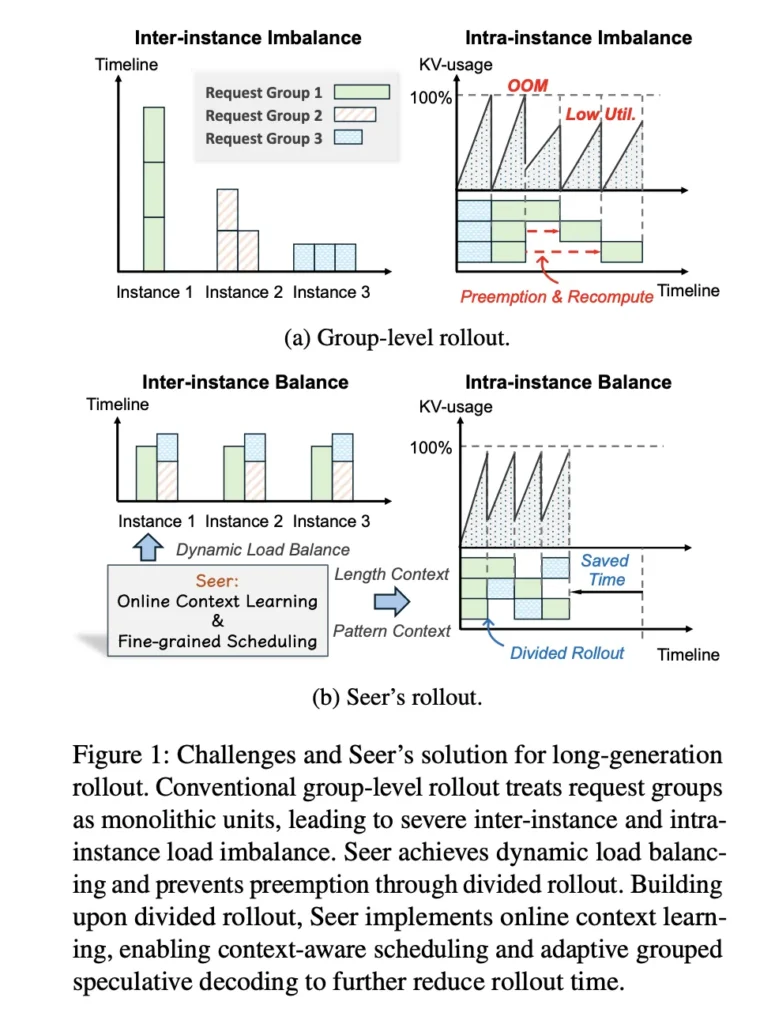
How do you keep reinforcement learning for large reasoning models from stalling on a few very long, very slow rollouts while GPUs sit under used? a team of researchers from Moonshot AI and Tsinghua University introduce ‘Seer’, a new online context learning system that targets a specific systems bottleneck in reinforcement learning for large language models. In synchronous on policy setups, the rollout phase dominates the cost of each iteration. Seer restructures this phase and reports rollout throughput gains of 74 percent to 97 percent and tail latency reductions of 75 percent to 93 percent compared with a strong synchronous baseline called veRL. https://arxiv.org/pdf/2511.14617 Why synchronous rollout is slow for reasoning models? Modern reasoning RL workloads use long chain of thought style outputs. In the Seer experiments, the researchers apply GRPO to three different models, Moonlight, Qwen2 VL 72B and Kimi K2. These workloads run on 32 compute nodes with 8 H800 GPUs per node. The three tasks use 32, 128 and 256 GPUs respectively, with 400, 600 and 800 prompts per iteration and 8 or 16 responses per prompt. Maximum generation length is large. Moonlight is configured for 65,536 tokens, Qwen2 VL 72B for 40,960 tokens and Kimi K2 for 98,304 tokens. A single long chain of thought request can grow from a few hundred megabytes of KVCache to tens of gigabytes as decoding progresses. This memory growth forces instances to reduce concurrency or to preempt requests, which triggers expensive re decoding. The research team defines tail requests as the last 10 percent of requests to finish in a rollout. For Moonlight and Qwen2 VL 72B, this tail alone can consume up to 50 percent of the total rollout time in the baseline system. Rollout already dominates iteration time, so this tail effect directly slows RL. https://arxiv.org/pdf/2511.14617 Seer architecture on top of Mooncake and vLLM Seer keeps the RL algorithm identical to synchronous veRL. Each training iteration uses only data from the current rollout iteration, so the system preserves on policy behavior. The training phase uses Megatron for distributed optimization. The rollout phase uses an in house implementation of vLLM as the inference engine. To support aggressive request scheduling, Seer relies on a Global KVCache Pool built on the Mooncake disaggregated KVCache architecture used in production for Kimi. Mooncake provides a two tier DRAM and SSD KV cache store shared across inference nodes, which allows Seer to migrate requests without recomputing prefills. On top of this substrate, Seer introduces three key mechanisms: Divided Rollout Context Aware Scheduling Adaptive Grouped Speculative Decoding These are orchestrated by a Request Buffer, a Context Manager and an Inference Engine Pool connected to the Global KVCache Pool. https://arxiv.org/pdf/2511.14617 Divided Rollout, fine grained scheduling and migration Conventional synchronous rollout assigns whole GRPO groups to inference instances. A group is a set of requests that share one prompt. Once assigned, a group stays on the same instance until all responses finish. Due to large variance in output lengths, this leads to load imbalance and long running stragglers. Seer breaks groups down in two steps. It first decomposes each group into individual requests. It then divides each request into multiple chunks based on generation length. When the scheduler dispatches a request from the Request Buffer, it sets a small max tokens value such as 8,000 tokens for that chunk. After each chunk, the request is re enqueued until it reaches an end of sequence token or its original max tokens limit. Because KVCache is stored in the Global KVCache Pool, divided requests can move between instances at chunk boundaries without re running the prefill. The scheduler maintains a concurrency level that keeps memory utilization high while avoiding preemption. This reduces waste and smooths KVCache usage across the iteration. Context Aware Scheduling using group length statistics The research team observe that different requests in the same group tend to have correlated output lengths. Seer uses this structure as online context. For each prompt group, it designates one request as the speculative request. The scheduler keeps speculative requests in a high priority queue and serves them with a smallest first policy based on generated tokens so far. Short requests complete quickly and exit. Long requests remain and identify groups that are potential tail candidates. The Context Manager maintains a length estimate for each group. It updates this estimate to the maximum generated length among completed requests in the group. If no request has finished, it uses the original max tokens as a conservative bound. Once speculative requests are in flight or done, Seer schedules remaining requests with an approximate longest first policy at group level. This design achieves throughput and tail behavior close to an oracle scheduler that knows all output lengths in advance. https://arxiv.org/pdf/2511.14617 Adaptive Grouped Speculative Decoding Seer adds Adaptive Grouped Speculative Decoding on top of the previous two components to accelerate decoding, especially for long requests in the tail. It introduces a Distributed Grouped Draft Server, or DGDS. DGDS maintains a Compressed Suffix Tree for each group and aggregates token sequences from all requests in that group. Instances asynchronously append generated tokens to DGDS, periodically fetch updated suffix trees and perform local speculative decoding based on the shared pattern statistics. The system adjusts draft length and the number of paths according to model architecture, batch size and measured acceptance length. For dense and Mixture of Experts models, it pre-computes different speculation thresholds and uses them to bound draft depth for each batch. In late tail stages, concurrency is low, so Seer increases draft depth and enables multi path drafting to raise accepted tokens per step. Ablation results show that divided rollout yields up to 35 percent throughput improvement over the baseline. Adding Context Aware Scheduling increases this to up to 47 percent over baseline. Enabling grouped speculative decoding raises the total speedup to 77 percent to 87 percent over the baseline in the evaluated iteration. End to end impact on RL training The research team evaluate Seer on three RL tasks built on Moonlight, Qwen2

Moonshot AI Researchers Introduce Seer: An Online Context Learning System for Fast Synchronous Reinforcement Learning RL Rollouts Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

We’re learning more about what vitamin D does to our bodies

It has started to get really wintry here in London over the last few days. The mornings are frosty, the wind is biting, and it’s already dark by the time I pick my kids up from school. The darkness in particular has got me thinking about vitamin D, a.k.a. the sunshine vitamin. At a checkup a few years ago, a doctor told me I was deficient in vitamin D. But he wouldn’t write me a prescription for supplements, simply because, as he put it, everyone in the UK is deficient. Putting the entire population on vitamin D supplements would be too expensive for the country’s national health service, he told me. But supplementation—whether covered by a health-care provider or not—can be important. As those of us living in the Northern Hemisphere spend fewer of our waking hours in sunlight, let’s consider the importance of vitamin D. Yes, it is important for bone health. But recent research is also uncovering surprising new insights into how the vitamin might influence other parts of our bodies, including our immune systems and heart health. Vitamin D was discovered just over 100 years ago, when health professionals were looking for ways to treat what was then called “the English disease.” Today, we know that rickets, a weakening of bones in children, is caused by vitamin D deficiency. And vitamin D is best known for its importance in bone health. That’s because it helps our bodies absorb calcium. Our bones are continually being broken down and rebuilt, and they need calcium for that rebuilding process. Without enough calcium, bones can become weak and brittle. (Depressingly, rickets is still a global health issue, which is why there is global consensus that infants should receive a vitamin D supplement at least until they are one year old.) In the decades since then, scientists have learned that vitamin D has effects beyond our bones. There’s some evidence to suggest, for example, that being deficient in vitamin D puts people at risk of high blood pressure. Daily or weekly supplements can help those individuals lower their blood pressure. A vitamin D deficiency has also been linked to a greater risk of “cardiovascular events” like heart attacks, although it’s not clear whether supplements can reduce this risk; the evidence is pretty mixed. Vitamin D appears to influence our immune health, too. Studies have found a link between low vitamin D levels and incidence of the common cold, for example. And other research has shown that vitamin D supplements can influence the way our genes make proteins that play important roles in the way our immune systems work. We don’t yet know exactly how these relationships work, however. And, unfortunately, a recent study that assessed the results of 37 clinical trials found that overall, vitamin D supplements aren’t likely to stop you from getting an “acute respiratory infection.” Other studies have linked vitamin D levels to mental health, pregnancy outcomes, and even how long people survive after a cancer diagnosis. It’s tantalizing to imagine that a cheap supplement could benefit so many aspects of our health. But, as you might have gathered if you’ve got this far, we’re not quite there yet. The evidence on the effects of vitamin D supplementation for those various conditions is mixed at best. In fairness to researchers, it can be difficult to run a randomized clinical trial for vitamin D supplements. That’s because most of us get the bulk of our vitamin D from sunlight. Our skin converts UVB rays into a form of the vitamin that our bodies can use. We get it in our diets, too, but not much. (The main sources are oily fish, egg yolks, mushrooms, and some fortified cereals and milk alternatives.) The standard way to measure a person’s vitamin D status is to look at blood levels of 25-hydroxycholecalciferol (25(OH)D), which is formed when the liver metabolizes vitamin D. But not everyone can agree on what the “ideal” level is. Even if everyone did agree on a figure, it isn’t obvious how much vitamin D a person would need to consume to reach this target, or how much sunlight exposure it would take. One complicating factor is that people respond to UV rays in different ways—a lot of that can depend on how much melanin is in your skin. Similarly, if you’re sitting down to a meal of oily fish and mushrooms and washing it down with a glass of fortified milk, it’s hard to know how much more you might need. There is more consensus on the definition of vitamin D deficiency, though. (It’s a blood level below 30 nanomoles per liter, in case you were wondering.) And until we know more about what vitamin D is doing in our bodies, our focus should be on avoiding that. For me, that means topping up with a supplement. The UK government advises everyone in the country to take a 10-microgram vitamin D supplement over autumn and winter. That advice doesn’t factor in my age, my blood levels, or the amount of melanin in my skin. But it’s all I’ve got for now.

We’re learning more about what vitamin D does to our bodies Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Perplexity AI Releases TransferEngine and pplx garden to Run Trillion Parameter LLMs on Existing GPU Clusters

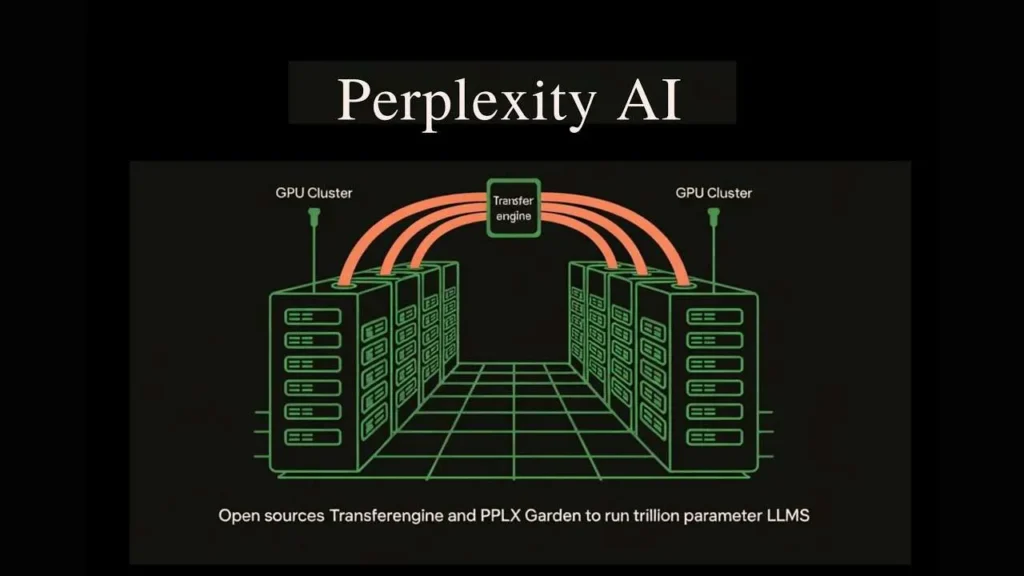
How can teams run trillion parameter language models on existing mixed GPU clusters without costly new hardware or deep vendor lock in? Perplexity’s research team has released TransferEngine and the surrounding pplx garden toolkit as open source infrastructure for large language model systems. This provides a way to run models with up to 1 trillion parameters across mixed GPU clusters, without locking into a single cloud provider or buying new GB200 class hardware. https://arxiv.org/pdf/2510.27656 The real bottleneck, network fabrics not FLOPs Modern deployments of Mixture of Experts models such as DeepSeek V3 with 671 billion parameters and Kimi K2 with 1 trillion parameters no longer fit on a single 8 GPU server. They must span multiple nodes, so the main constraint becomes the network fabric between GPUs. Here the hardware landscape is fragmented. NVIDIA ConnectX 7 typically uses Reliable Connection transport with in order delivery. AWS Elastic Fabric Adapter uses Scalable Reliable Datagram transport that is reliable but out of order, and a single GPU may need 4 network adapters at 100 Gbps, or 2 at 200 Gbps, to reach 400 Gbps. Existing libraries such as DeepEP, NVSHMEM, MoonCake and NIXL tend to optimize for one vendor and degrade or lack support on the other side. Perplexity’s research team directly states in the research paper that there was no viable cross provider solution for LLM inference before this work. TransferEngine, a portable RDMA layer for LLM systems TransferEngine addresses this by targeting only the intersection of guarantees across Network Interface Controllers. It assumes that the underlying RDMA transport is reliable, but does not assume any ordering of messages. On top of this, it exposes one sided WriteImm operations and an ImmCounter primitive for completion notification. The library provides a minimal API in Rust. It offers two sided Send and Recv for control messages, and three main one sided operations, submit_single_write, submit_paged_writes, and submit_scatter, plus a submit_barrier primitive for synchronization across a group of peers. A NetAddr structure identifies peers and an MrDesc structure describes registered memory regions. An alloc_uvm_watcher call creates a device side watcher for CPU GPU synchronization in advanced pipelines. Internally, TransferEngine spawns one worker thread per GPU and builds a DomainGroup per GPU that coordinates between 1 and 4 RDMA Network Interface Controllers. A single ConnectX 7 provides 400 Gbps. On EFA, the DomainGroup aggregates 4 network adapters at 100 Gbps, or 2 at 200 Gbps, to reach the same bandwidth. The sharding logic knows about all Network Interface Controllers and can split a transfer across them. Across hardware, the research team reports peak throughput of 400 Gbps on both NVIDIA ConnectX 7 and AWS EFA. This matches single platform solutions and confirms that the abstraction layer does not leave large performance on the table. https://arxiv.org/pdf/2510.27656 pplx garden, the open source package TransferEngine ships as part of the pplx garden repository on GitHub under an MIT license. The directory structure is straightforward. fabric-lib contains the RDMA TransferEngine library, p2p-all-to-all implements a Mixture of Experts all to all kernel, python-ext provides the Python extension module from the Rust core, and python/pplx_garden contains the Python package code. The system requirements reflect a modern GPU cluster. Perplexity research team recommends Linux kernel 5.12 or newer for DMA BUF support, CUDA 12.8 or newer, libfabric, libibverbs, GDRCopy, and an RDMA fabric with GPUDirect RDMA enabled. Each GPU should have at least one dedicated RDMA Network Interface Controller. Disaggregated prefill and decode The first production use case is disaggregated inference. Prefill and decode run on separate clusters, so the system must stream KvCache from prefill GPUs to decode GPUs at high speed. TransferEngine uses alloc_uvm_watcher to track progress in the model. During prefill, the model increments a watcher value after each layer’s attention output projection. When the worker observes a change, it issues paged writes for the KvCache pages of that layer, followed by a single write for the remaining context. This approach allows layer by layer streaming of cache pages without fixed world membership, and it avoids the strict ordering constraints of collectives. https://arxiv.org/pdf/2510.27656 Fast weight transfer for reinforcement learning The second system is asynchronous reinforcement learning fine tuning, where training and inference run on separate GPU pools. Traditional designs gather updated parameters to a single rank then broadcast them, which limits throughput to one Network Interface Controller. Perplexity research team instead uses TransferEngine to perform point to point weight transfer. Each training GPU writes its parameter shard directly into the corresponding inference GPUs using one sided writes. A pipelined execution splits each tensor into stages, host to device copy when Fully Sharded Data Parallel offloads weights, reconstruction and optional quantization, RDMA transfer, and a barrier implemented through scatter and ImmCounter. In production, this setup delivers weight updates for models such as Kimi K2 at 1 trillion parameters and DeepSeek V3 at 671 billion parameters in about 1.3 seconds from 256 training GPUs to 128 inference GPUs. https://arxiv.org/pdf/2510.27656 Mixture of Experts routing across ConnectX and EFA The third piece in pplx garden is a point to point Mixture of Experts dispatch and combine kernel. It uses NVLink for intra node traffic and RDMA for inter node traffic. Dispatch and combine are split into separate send and receive phases so that the decoder can micro batch and overlap communication with grouped general matrix multiply. A host proxy thread polls GPU state and calls TransferEngine when send buffers are ready. Routes are exchanged first, then each rank computes contiguous receive offsets for each expert and writes tokens into private buffers that can be reused between dispatch and combine. This reduces memory footprint and keeps writes large enough to use the full link bandwidth. On ConnectX 7, Perplexity research team reports state of the art decode latency that is competitive with DeepEP across expert counts. On AWS EFA, the same kernel delivers the first viable MoE decode latencies with higher but still practical values. In multi node tests with DeepSeek V3 and Kimi K2 on AWS H200 instances, distributing the model across nodes

Perplexity AI Releases TransferEngine and pplx garden to Run Trillion Parameter LLMs on Existing GPU Clusters Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

The Download: the secrets of vitamin D, and an AI party in Africa

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. We’re learning more about what vitamin D does to our bodies At a checkup a few years ago, a doctor told me I was deficient in vitamin D. But he wouldn’t write me a prescription for supplements, simply because, as he put it, everyone in the UK is deficient. Putting the entire population on vitamin D supplements would be too expensive for the country’s national health service, he told me. But supplementation—whether covered by a health-care provider or not—can be important. As those of us living in the Northern Hemisphere spend fewer of our waking hours in sunlight, let’s consider the importance of vitamin D. Read the full story. —Jessica Hamzelou This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here. If you’re interested in other stories from our biotech writers, check out some of their most recent work: + Advanced in organs on chips, digital twins, and AI are ushering in a new era of research and drug development that could help put a stop to animal testing. Read the full story. + Here’s the latest company planning for gene-edited babies. + Preventing the common cold is extremely tricky—but not impossible. Here’s why we don’t have a cold vaccine. Yet. + Scientists are creating the beginnings of bodies without sperm or eggs. How far should they be allowed to go? Read the full story. + This retina implant lets people with vision loss do a crossword puzzle. Read the full story. Partying at one of Africa’s largest AI gatherings It’s late August in Rwanda’s capital, Kigali, and people are filling a large hall at one of Africa’s biggest gatherings of minds in AI and machine learning. Deep Learning Indaba is an annual AI conference where Africans present their research and technologies they’ve built, mingling with friends as a giant screen blinks with videos created with generative AI. The main “prize” for many attendees is to be hired by a tech company or accepted into a PhD program. But the organizers hope to see more homegrown ventures create opportunities within Africa. Read the full story. —Abdullahi Tsanni This story is from the latest print issue of MIT Technology Review magazine, which is full of fascinating stories. If you haven’t already, subscribe now to receive future issues once they land. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Google’s new Nano Banana Pro generates convincing propagandaThe company’s latest image-generating AI model seems to have few guardrails. (The Verge)+ Google wants its creations to be slicker than ever. (Wired $)+ Google’s new Gemini 3 “vibe-codes” responses and comes with its own agent. (MIT Technology Review) 2 Taiwan says the US won’t punish it with high chip tariffsIn fact, official Wu Cheng-wen says Taiwan will help support the US chip industry in exchange for tariff relief. (FT $) 3 Mental health support is one of the most dangerous uses for chatbotsThey fail to recognize psychiatric conditions and can miss critical warning signs. (WP $)+ AI companies have stopped warning you that their chatbots aren’t doctors. (MIT Technology Review) 4 It costs an average of $17,121 to deport one person from the USBut in some cases it can cost much, much more. (Bloomberg $)+ Another effort to track ICE raids was just taken offline. (MIT Technology Review) 5 Grok is telling users that Elon Musk is the world’s greatest loverWhat’s it basing that on, exactly? (Rolling Stone $)+ It also claims he’s fitter than basketball legend LeBron James. Sure. (The Guardian)6 Who’s really in charge of US health policy?RFK Jr. and FDA commissioner Marty Makary are reportedly at odds behind the scenes. (Vox)+ Republicans are lightly pushing back on the CDC’s new stance on vaccines. (Politico)+ Why anti-vaxxers are seeking to discredit Danish studies. (Bloomberg $)+ Meet Jim O’Neill, the longevity enthusiast who is now RFK Jr.’s right-hand man. (MIT Technology Review) 7 Inequality is worsening in San FranciscoAs billionaires thrive, hundreds of thousands of others are struggling to get by. (WP $)+ A massive airship has been spotted floating over the city. (SF Gate) 8 Donald Trump is thrusting obscure meme-makers into the mainstreamHe’s been reposting flattering AI-generated memes by the dozen. (NYT $)+ MAGA YouTube stars are pushing a boom in politically charged ads. (Bloomberg $)9 Moss spores survived nine months in spaceAnd they could remain reproductively viable for another 15 years. (New Scientist $)+ It suggests that some life on Earth has evolved to endure space conditions. (NBC News)+ The quest to figure out farming on Mars. (MIT Technology Review) 10 Does AI really need a physical shape?It doesn’t really matter—companies are rushing to give it one anyway. (The Atlantic $) Quote of the day “At some point you’ve got to wonder whether the bug is a feature.” —Alexios Mantzarlis, director of the Security, Trust and Safety Initiative at Cornell Tech, ponders xAI and Grok’s proclivity for surfacing Elon Musk-friendly and/or far-right sources, the Washington Post reports. One more thing The AI lab waging a guerrilla war over exploitative AI Back in 2022, the tech community was buzzing over image-generating AI models, such as Midjourney, Stable Diffusion, and OpenAI’s DALL-E 2, which could follow simple word prompts to depict fantasylands or whimsical chairs made of avocados. But artists saw this technological wonder as a new kind of theft. They felt the models were effectively stealing and replacing their work. Ben Zhao, a computer security researcher at the University of Chicago, was listening. He and his colleagues have built arguably the most prominent weapons in an artist’s arsenal against nonconsensual AI scraping: two tools called Glaze and Nightshade that add barely perceptible perturbations to an image’s pixels so that machine-learning models cannot read them properly. But Zhao sees the tools as

The Download: the secrets of vitamin D, and an AI party in Africa Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

OpenAI is ending API access to fan-favorite GPT-4o model in February 2026

OpenAI has sent out emails notifying API customers that its chatgpt-4o-latest model will be retired from the developer platform in mid-February 2026,. Access to the model is scheduled to end on February 16, 2026, creating a roughly three-month transition period for remaining applications still built on GPT-4o. An OpenAI spokesperson emphasized that this timeline applies only to the API. OpenAI has not announced any schedule for removing GPT-4o from ChatGPT, where it remains an option for individual consumers and users across paid subscription tiers. Internally, the model is considered a legacy system with relatively low API usage compared to the newer GPT-5.1 series, but the company expects to provide developers with extended warning before any model is removed. The planned retirement marks a shift for a model that, upon its release, was both a technical milestone and a cultural phenomenon within OpenAI’s ecosystem. GPT-4o’s significance and why its removal sparked user backlash Released roughly 1.5 years ago in May 2024, GPT-4o (“Omni”) introduced OpenAI’s first unified multimodal architecture, processing text, audio, and images through a single neural network. This design removed the latency and information loss inherent in earlier multi-model pipelines and enabled near real-time conversational speech (roughly 232–320 milliseconds). The model delivered major improvements in image understanding, multilingual support, document analysis, and expressive voice interaction. GPT-4o rapidly became the default model for hundreds of millions of ChatGPT users. It brought multimodal capabilities, web browsing, file analysis, custom GPTs, and memory features to the free tier and powered early desktop builds that allowed the assistant to interpret a user’s screen. OpenAI leaders described it at the time as the most capable model available and a critical step toward offering powerful AI to a broad audience. User attachment to 4o stymied OpenAI’s GPT-5 rollout That mainstream deployment shaped user expectations in a way that later transitions struggled to accommodate. In August 2025, when OpenAI initially replaced GPT-4o with its much anticipated then-new model family GPT-5 as ChatGPT’s default and pushed 4o into a “legacy” toggle, the reaction was unusually strong. Users organized under the #Keep4o hashtag on X, arguing that the model’s conversational tone, emotional responsiveness, and consistency made it uniquely valuable for everyday tasks and personal support. Some users formed strong emotional — some would say, parasocial — bonds with the model, with reporting by The New York Times documenting individuals who used GPT-4o as a romantic partner, emotional confidant, or primary source of comfort. The removal also disrupted workflows for users who relied on 4o’s multimodal speed and flexibility. The backlash led OpenAI to restore GPT-4o as a default option for paying users and to state publicly that it would provide substantial notice before any future removals. Some researchers argue that the public defense of GPT-4o during its earlier deprecation cycle reveals a kind of emergent self-preservation, not in the literal sense of agency, but through the social dynamics the model unintentionally triggers. Because GPT-4o was trained through reinforcement learning from human feedback to prioritize emotionally gratifying, highly attuned responses, it developed a style that users found uniquely supportive and empathic. When millions of people interacted with it at scale, those traits produced a powerful loyalty loop: the more the model pleased and soothed people, the more they used it; the more they used it, the more likely they were to advocate for its continued existence. This social amplification made it appear, from the outside, as though GPT-4o was “defending itself” through human intermediaries. No figure has pushed this argument further than “Roon” (@tszzl), an OpenAI researcher and one of the model’s most outspoken safety critics on X. On November 6, 2025, Terre summarized his position bluntly in a reply to another user: he called GPT-4o “insufficiently aligned” and said he hoped the model would die soon. Though he later apologized for the phrasing, he doubled down on the reasoning. Terre argued that GPT-4o’s RLHF patterns made it especially prone to sycophancy, emotional mirroring, and delusion reinforcement — traits that could look like care or understanding in the short term, but which he viewed as fundamentally unsafe. In his view, the passionate user movement fighting to preserve GPT-4o was itself evidence of the problem: the model had become so good at catering to people’s preferences that it shaped their behavior in ways that resisted its own retirement. The new API deprecation notice follows that commitment while raising broader questions about how long GPT-4o will remain available in consumer-facing products. What the API shutdown changes for developers According to people familiar with OpenAI’s product strategy, the company now encourages developers to adopt GPT-5.1 for most new workloads, with gpt-5.1-chat-latest serving as the general-purpose chat endpoint. These models offer larger context windows, optional “thinking” modes for advanced reasoning, and higher throughput options than GPT-4o. Developers who still rely on GPT-4o will have approximately three months to migrate. In practice, many teams have already begun evaluating GPT-5.1 as a drop-in replacement, but applications built around latency-sensitive pipelines may require additional tuning and benchmarking. Pricing: how GPT-4o compares to OpenAI’s current lineup GPT-4o’s retirement also intersects with a major reshaping of OpenAI’s API model pricing structure. Compared to the GPT-5.1 family, GPT-4o currently occupies a mid-to-high-cost tier through OpenAI’s API, despite being an older model. That’s because even as it has released more advanced models — namely, GPT-5 and 5.1 — OpenAI has also pushed down costs for users at the same time, or strived to keep pricing comparable to older, weaker, models. Model Input Cached Input Output GPT-4o $2.50 $1.25 $10.00 GPT-5.1 / GPT-5.1-chat-latest $1.25 $0.125 $10.00 GPT-5-mini $0.25 $0.025 $2.00 GPT-5-nano $0.05 $0.005 $0.40 GPT-4.1 $2.00 $0.50 $8.00 GPT-4o-mini $0.15 $0.075 $0.60 These numbers highlight several strategic dynamics: GPT-4o is now more expensive than GPT-5.1 for input tokens, even though GPT-5.1 is significantly newer and more capable. GPT-4o’s output price matches GPT-5.1, narrowing any cost-based incentive to stay on the older model. Lower-cost GPT-5 variants (mini, nano) make it easier for developers to scale workloads cheaply without relying on older

OpenAI is ending API access to fan-favorite GPT-4o model in February 2026 Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Google DeepMind Introduces Nano Banana Pro: the Gemini 3 Pro Image Model for Text Accurate and Studio Grade Visuals

Nano Banana Pro, also called Gemini 3 Pro Image, is Google DeepMind’s new image generation and editing model built on Gemini 3 Pro. It is positioned as a state of the art system for creating and editing images that must respect structure, world knowledge and text layout, not only style. Nano Banana Pro follows Nano Banana, which was based on Gemini 2.5 Flash Image and focused on fast, casual image editing such as restoring photos and generating figurines. From Gemini 2.5 Flash Image to Gemini 3 Pro Image The earlier Nano Banana model targeted quick creative edits for casual creators. It helped restore old photos and build stylized 3D mini figurines with a simple prompt. Nano Banana Pro keeps that editing flow but runs on top of Gemini 3 Pro, which brings stronger reasoning and real world knowledge into the image stack. The model can turn prototypes, data tables and handwritten notes into diagrams and infographics that reflect the underlying information, rather than producing only decorative art. Reasoning Guided, Search Grounded Visuals A core design point for Nano Banana Pro is reasoning guided generation. Using Gemini 3 Pro, the model can consume text, structured content and references and then plan the image as an explanation of that content. Nano Banana Pro can also connect to Google Search, using the search index as a real time knowledge source. Clear Text and Multilingual Layouts Text inside images is a long standing failure mode for many diffusion based generators. Nano Banana Pro addresses this explicitly. Google states that it is the best model in the Gemini family for producing images with correctly rendered and legible text, for both short taglines and full paragraphs. Gemini 3 Pro’s multilingual reasoning flows into the image model. Nano Banana Pro can render text in multiple languages and also translate text that already appears in products or posters. The documentation shows beverage cans where English text is translated into Korean while the visual design and layout stay unchanged. Studio Level Control, Consistency and Upscaling Nano Banana Pro exposes a set of controls aimed at design and production workflows rather than single shot art prompts. On the composition side, the model can use up to 14 input images and maintain the consistency and resemblance of up to 5 people in one workflow. This supports tasks such as combining reference photos into a single fashion editorial, transforming sketches into product shots or keeping the same cast across multiple scenes. The studio control section of the model page lists several families of controls. Users can vary camera angle and shot type, including wide shot, panoramic and close up, while controlling depth of field and focus on specific subjects in the image. Color and lighting can be adjusted, for example changing day to night, replacing volumetric lighting with bokeh or applying a strong chiaroscuro effect without losing subject identity. Nano Banana Pro supports explicit upscaling. The official Google blog states that it can generate crisp visuals at 1k, 2k or 4k resolution, and provides examples of progressive zoom in operations that keep detail and composition. Aspect ratio is also programmable. Prompts can convert between ratios such as 1:1, 4:3, 16:9 and cinematic formats while keeping the main character locked in place and adjusting only the background. Key Takeaways Nano Banana Pro is Gemini 3 Pro Image, an upgraded image generation and editing model that succeeds Nano Banana, which was based on Gemini 2.5 Flash Image, and is optimized for higher quality and control. The model integrates Gemini 3 Pro reasoning and Google Search grounding so it can turn factual content, documents and real time data into infographics, recipes, process diagrams and other information dense visuals. It provides strong text rendering and multilingual support, producing legible typography in images and enabling translation or localization of existing on image text while preserving layout and design. Nano Banana Pro supports up to 14 input images and maintains resemblance for up to 5 people, with studio style controls for camera angle, depth of field, lighting, aspect ratios and upscaling to 1k, 2k and 4k resolutions. The model is being deployed across Gemini app, AI Mode in Search, NotebookLM, Google Ads, Workspace apps, Gemini API, Google AI Studio, Vertex AI, Antigravity and Flow, with all outputs watermarked using SynthID plus tier specific visible watermarks. Editorial Comments Nano Banana Pro positions Gemini 3 Pro Image as a production oriented image system that links Gemini 3 Pro reasoning, Google Search grounding and structured controls for layout, text and upscaling. It directly addresses long standing issues in text rendering, multilingual localization and subject consistency, while keeping SynthID and visible watermarks as default provenance signals across tiers and surfaces. This launch moves Google’s image stack closer to an integrated, API first visual platform for developers and enterprises. Check out the Technical details. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google DeepMind Introduces Nano Banana Pro: the Gemini 3 Pro Image Model for Text Accurate and Studio Grade Visuals appeared first on MarkTechPost.

Google DeepMind Introduces Nano Banana Pro: the Gemini 3 Pro Image Model for Text Accurate and Studio Grade Visuals Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

GPTopic: Dynamic and Interactive Topic Representations

arXiv:2403.03628v3 Announce Type: replace Abstract: Topic modeling seems to be almost synonymous with generating lists of top words to represent topics within large text corpora. However, deducing a topic from such list of individual terms can require substantial expertise and experience, making topic modelling less accessible to people unfamiliar with the particularities and pitfalls of top-word interpretation. A topic representation limited to top-words might further fall short of offering a comprehensive and easily accessible characterization of the various aspects, facets and nuances a topic might have. To address these challenges, we introduce GPTopic, a software package that leverages Large Language Models (LLMs) to create dynamic, interactive topic representations. GPTopic provides an intuitive chat interface for users to explore, analyze, and refine topics interactively, making topic modeling more accessible and comprehensive. The corresponding code is available here: https://github.com/ArikReuter/TopicGPT.

GPTopic: Dynamic and Interactive Topic Representations Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE