YouZum

Committee

AI, Committee, Nachrichten, Uncategorized

The Download: cut through AI coding hype, and biotech trends to watch

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. AI coding is now everywhere. But not everyone is convinced.   Depending who you ask, AI-powered coding is either giving software developers an unprecedented productivity boost or churning out masses of poorly designed code that saps their attention and sets software projects up for serious long term-maintenance problems.  The problem is right now, it’s not easy to know which is true.  As tech giants pour billions into large language models (LLMs), coding has been touted as the technology’s killer app. Executives enamored with the potential are pushing engineers to lean into an AI-powered future. But after speaking to more than 30 developers, technology executives, analysts, and researchers, MIT Technology Review found that the picture is not as straightforward as it might seem. Read the full story.  —Edd Gent Generative coding is one of our 10 Breakthrough Technologies this year. Learn more about why that is, and check out the rest of the list!  This story was also part of our Hype Correction package. You can read the rest of the stories here. The biotech trends to watch for in 2026 Earlier this week, MIT Technology Review published our annual list of Ten Breakthrough Technologies.  This year’s list includes tech that’s set to transform the energy industry, artificial intelligence, space travel—and of course biotech and health. Our breakthrough biotechnologies for 2026 involve editing a baby’s genes and, separately, resurrecting genes from ancient species. We also included a controversial technology that offers parents the chance to screen their embryos for characteristics like height and intelligence. Here’s the story behind our biotech choices. —Jessica Hamzelou This story is from The Checkup, our weekly newsletter all about the latest in health and biotech. Sign upto receive it in your inbox every Thursday. MIT Technology Review Narrated: What’s next for AI in 2026 Our AI writers have made some big bets for the coming year—read our story about the five hot trends to watch, or listen to it on Spotify, Apple, or wherever you get your podcasts. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Minnesota shows how governing and content creation have mergedIn another era, we’d have just called this propaganda. (NPR)+ MAGA influencers are just straight up lying about what is happening there. (Vox) + Activists are trying to identify individual ICE officers while protecting their own identities. (WP $)+ A backlash against ICE is growing in Silicon Valley. (Wired $) 2 There’s probably more child abuse material online now than ever beforeOf all Big Tech’s failures, this is surely the most appalling. (The Atlantic $)+ US investigators are using AI to detect child abuse images made by AI. (MIT Technology Review)+ Grok is still being used to undress images of real people. (Quartz) 3 ChatGPT wrote a suicide lullaby for a man who later killed himselfThis shows it’s “still an unsafe product,” a lawyer representing a family in a tragically similar case said. (Ars Technica)+ An AI chatbot told a user how to kill himself—but the company doesn’t want to “censor” it. (MIT Technology Review) 4 Videos emerging from Iran show how bloody the crackdown has becomeIranians are finding ways around the internet blackout to show the rest of the world how many of them have been killed. (NBC) + Here’s how they’re getting around the blackout. (NPR)  5 China dominates the global humanoid robot market A new report by analysts found its companies account for over 80% of all deployments. (South China Morning Post) + Just how useful are the latest humanoids, though? (Nature)+ Why humanoid robots need their own safety rules. (MIT Technology Review) 6 How is Australia’s social media ban for kids going? It’s mixed—some teens welcome it, but others are finding workarounds. (CNBC) 7 Scientists are finding more objective ways to spot mental illness Biomarkers like voice cadence and heart rate proving pretty reliable for diagnosing conditions like depression. (New Scientist $) 8 The Pebble smartwatch be making a comebackThis could be the thing that tempts me back into buying wearables… (Gizmodo) 9 A new video game traps you in an online scam centerCan’t see the appeal myself, but… each to their own I guess? (NYT $) 10 Smoke detectors are poised to get a high-tech upgrade And one of the technologies boosting their capabilities is, of course, AI. (BBC) Quote of the day “I am very annoyed. I’m very disappointed. I’m seriously frustrated.”  —Pfizer CEO Albert Bourla tells attendees at a healthcare conference this week his feelings about the anti-vaccine agenda Health Secretary Robert F. Kennedy Jr. has been implementing, Bloomberg reports. One more thing ARIEL DAVIS How close are we to genuine “mind reading?” Technically speaking, neuroscientists have been able to read your mind for decades. It’s not easy, mind you. First, you must lie motionless within a fMRI scanner, perhaps for hours, while you watch films or listen to audiobooks.  If you do elect to endure claustrophobic hours in the scanner, the software will learn to generate a bespoke reconstruction of what you were seeing or listening to, just by analyzing how blood moves through your brain. More recently, researchers have deployed generative AI tools, like Stable Diffusion and GPT, to create far more realistic, if not entirely accurate, reconstructions of films and podcasts based on neural activity. So how close are we to genuine “mind reading?” Read the full story. —Grace Huckins We can still have nice things A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line or skeet ’em at me.) + Still keen to do a bit of reflecting on the year behind and the one ahead? This free guide might help!+ Turns out British comedian Rik Mayall had some pretty solid life advice.+ I want to stay in this house in São Paolo.  + If you want to stop doomscrolling, it’s worth looking at your sleep habits. ($)

The Download: cut through AI coding hype, and biotech trends to watch Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Listen Labs raises $69M after viral billboard hiring stunt to scale AI customer interviews

Alfred Wahlforss was running out of options. His startup, Listen Labs, needed to hire over 100 engineers, but competing against Mark Zuckerberg’s $100 million offers seemed impossible. So he spent $5,000 — a fifth of his marketing budget — on a billboard in San Francisco displaying what looked like gibberish: five strings of random numbers. The numbers were actually AI tokens. Decoded, they led to a coding challenge: build an algorithm to act as a digital bouncer at Berghain, the Berlin nightclub famous for rejecting nearly everyone at the door. Within days, thousands attempted the puzzle. 430 cracked it. Some got hired. The winner flew to Berlin, all expenses paid. That unconventional approach has now attracted $69 million in Series B funding, led by Ribbit Capital with participation from Evantic and existing investors Sequoia Capital, Conviction, and Pear VC. The round values Listen Labs at $500 million and brings its total capital to $100 million. In nine months since launch, the company has grown annualized revenue by 15x to eight figures and conducted over one million AI-powered interviews. “When you obsess over customers, everything else follows,” Wahlforss said in an interview with VentureBeat. “Teams that use Listen bring the customer into every decision, from marketing to product, and when the customer is delighted, everyone is.” Why traditional market research is broken, and what Listen Labs is building to fix it Listen’s AI researcher finds participants, conducts in-depth interviews, and delivers actionable insights in hours, not weeks. The platform replaces the traditional choice between quantitative surveys — which provide statistical precision but miss nuance—and qualitative interviews, which deliver depth but cannot scale. Wahlforss explained the limitation of existing approaches: “Essentially surveys give you false precision because people end up answering the same question… You can’t get the outliers. People are actually not honest on surveys.” The alternative, one-on-one human interviews, “gives you a lot of depth. You can ask follow up questions. You can kind of double check if they actually know what they’re talking about. And the problem is you can’t scale that.” The platform works in four steps: users create a study with AI assistance, Listen recruits participants from its global network of 30 million people, an AI moderator conducts in-depth interviews with follow-up questions, and results are packaged into executive-ready reports including key themes, highlight reels, and slide decks. What distinguishes Listen’s approach is its use of open-ended video conversations rather than multiple-choice forms. “In a survey, you can kind of guess what you should answer, and you have four options,” Wahlforss said. “Oh, they probably want me to buy high income. Let me click on that button versus an open ended response. It just generates much more honesty.” The dirty secret of the $140 billion market research industry: rampant fraud Listen finds and qualifies the right participants in its global network of 30 million people. But building that panel required confronting what Wahlforss called “one of the most shocking things that we’ve learned when we entered this industry”—rampant fraud. “Essentially, there’s a financial transaction involved, which means there will be bad players,” he explained. “We actually had some of the largest companies, some of them have billions in revenue, send us people who claim to be kind of enterprise buyers to our platform and our system immediately detected, like, fraud, fraud, fraud, fraud, fraud.” The company built what it calls a “quality guard” that cross-references LinkedIn profiles with video responses to verify identity, checks consistency across how participants answer questions, and flags suspicious patterns. The result, according to Wahlforss: “People talk three times more. They’re much more honest when they talk about sensitive topics like politics and mental health.” Emeritus, an online education company that uses Listen, reported that approximately 20% of survey responses previously fell into the fraudulent or low-quality category. With Listen, they reduced this to almost zero. “We did not have to replace any responses because of fraud or gibberish information,” said Gabrielli Tiburi, Assistant Manager of Customer Insights at Emeritus. How Microsoft, Sweetgreen, and Chubbies are using AI interviews to build better products The speed advantage has proven central to Listen’s pitch. Traditional customer research at Microsoft could take four to six weeks to generate insights. “By the time we get to them, either the decision has been made or we lose out on the opportunity to actually influence it,” said Romani Patel, Senior Research Manager at Microsoft. With Listen, Microsoft can now get insights in days, and in many cases, within hours. The platform has already powered several high-profile initiatives. Microsoft used Listen Labs to collect global customer stories for its 50th anniversary celebration. “We wanted users to share how Copilot is empowering them to bring their best self forward,” Patel said, “and we were able to collect those user video stories within a day.” Traditionally, that kind of work would have taken six to eight weeks. Simple Modern, an Oklahoma-based drinkware company, used Listen to test a new product concept. The process took about an hour to write questions, an hour to launch the study, and 2.5 hours to receive feedback from 120 people across the country. “We went from ‘Should we even have this product?’ to ‘How should we launch it?’” said Chris Hoyle, the company’s Chief Marketing Officer. Chubbies, the shorts brand, achieved a 24x increase in youth research participation—growing from 5 to 120 participants — by using Listen to overcome the scheduling challenges of traditional focus groups with children. “There’s school, sports, dinner, and homework,” explained Lauren Neville, Director of Insights and Innovation. “I had to find a way to hear from them that fit into their schedules.” The company also discovered product issues through AI interviews that might have gone undetected otherwise. Wahlforss described how the AI “through conversations, realized there were like issues with the the kids short line, and decided to, like, interview hundreds of kids. And I understand that there were issues in the liner of the shorts and that they were, like,

Listen Labs raises $69M after viral billboard hiring stunt to scale AI customer interviews Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive Visual Intelligence

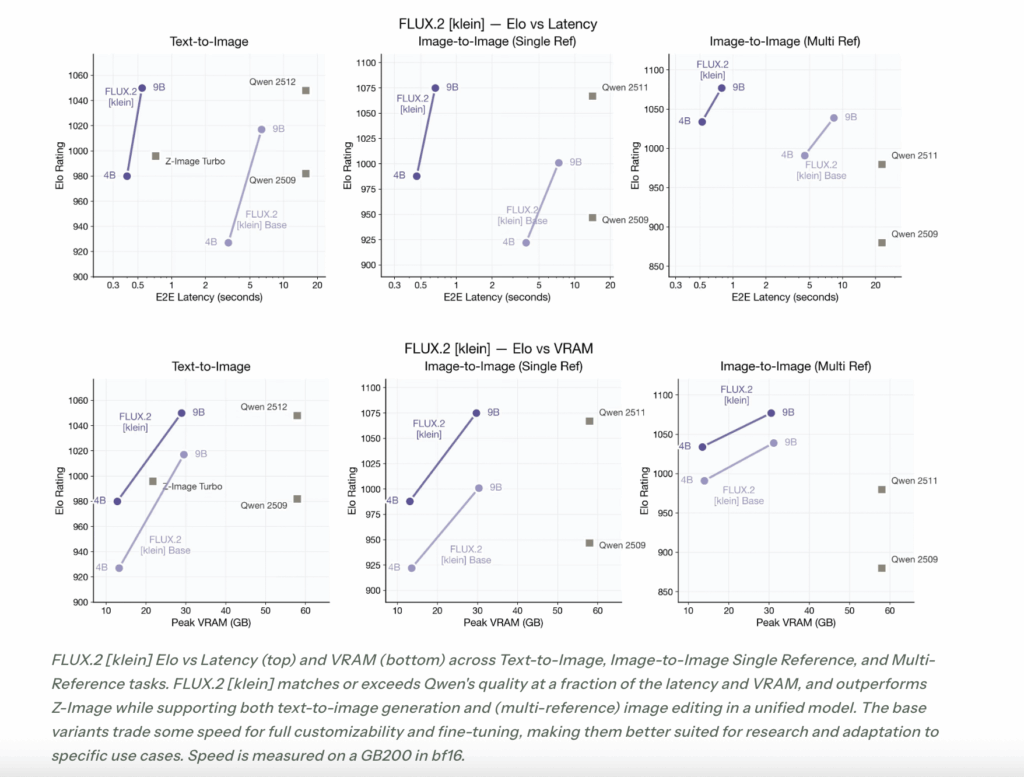
Black Forest Labs releases FLUX.2 [klein], a compact image model family that targets interactive visual intelligence on consumer hardware. FLUX.2 [klein] extends the FLUX.2 line with sub second generation and editing, a unified architecture for text to image and image to image, and deployment options that range from local GPUs to cloud APIs, while keeping state of the art image quality. From FLUX.2 [dev] to interactive visual intelligence FLUX.2 [dev] is a 32 billion parameter rectified flow transformer for text conditioned image generation and editing, including composition with multiple reference images, and runs mainly on data center class accelerators. It is tuned for maximum quality and flexibility, with long sampling schedules and high VRAM requirements. FLUX.2 [klein] takes the same design direction and compresses it into smaller rectified flow transformers with 4 billion and 9 billion parameters. These models are distilled to very short sampling schedules, support the same text to image and multi reference editing tasks, and are optimized for response times below 1 second on modern GPUs. Model family and capabilities The FLUX.2 [klein] family consists of 4 main open weight variants through a single architecture. FLUX.2 [klein] 4B FLUX.2 [klein] 9B FLUX.2 [klein] 4B Base FLUX.2 [klein] 9B Base FLUX.2 [klein] 4B and 9B are step distilled and guidance distilled models. They use 4 inference steps and are positioned as the fastest options for production and interactive workloads. FLUX.2 [klein] 9B combines a 9B flow model with an 8B Qwen3 text embedder and is described as the flagship small model on the Pareto frontier for quality versus latency across text to image, single reference editing, and multi reference generation. The Base variants are undistilled versions with longer sampling schedules. The documentation lists them as foundation models that preserve the complete training signal and provide higher output diversity. They are intended for fine tuning, LoRA training, research pipelines, and custom post training workflows where control is more important than minimum latency. All FLUX.2 [klein] models support three core tasks in the same architecture. They can generate images from text, they can edit a single input image, and they can perform multi reference generation and editing where several input images and a prompt jointly define the target output. Latency, VRAM, and quantized variants The FLUX.2 [klein] model page provides approximate end to end inference times on GB200 and RTX 5090. FLUX.2 [klein] 4B is the fastest variant and is listed at about 0.3 to 1.2 seconds per image, depending on hardware. FLUX.2 [klein] 9B targets about 0.5 to 2 seconds at higher quality. The Base models require several seconds because they run with 50 step sampling schedules, but they expose more flexibility for custom pipelines. The FLUX.2 [klein] 4B model card states that 4B fits in about 13 GB of VRAM and is suitable for GPUs like the RTX 3090 and RTX 4070. The FLUX.2 [klein] 9B card reports a requirement of about 29 GB of VRAM and targets hardware such as the RTX 4090. This means a single high end consumer card can host the distilled variants with full resolution sampling. To extend the reach to more devices, Black Forest Labs also releases FP8 and NVFP4 versions for all FLUX.2 [klein] variants, developed together with NVIDIA. FP8 quantization is described as up to 1.6 times faster with up to 40 percent lower VRAM usage, and NVFP4 as up to 2.7 times faster with up to 55 percent lower VRAM usage on RTX GPUs, while keeping the core capabilities the same. Benchmarks against other image models Black Forest Labs evaluates FLUX.2 [klein] through Elo style comparisons on text to image, single reference editing, and multi reference tasks. The performance charts show FLUX.2 [klein] on the Pareto frontier of Elo score versus latency and Elo score versus VRAM.The commentary states that FLUX.2 [klein] matches or exceeds the quality of Qwen based image models at a fraction of the latency and VRAM, and that it outperforms Z Image while supporting unified text to image and multi reference editing in one architecture. https://bfl.ai/blog/flux2-klein-towards-interactive-visual-intelligence The base variants trade some speed for full customizability and fine tuning, which aligns with their role as foundation checkpoints for new research and domain specific pipelines. Key Takeaways FLUX.2 [klein] is a compact rectified flow transformer family with 4B and 9B variants that supports text to image, single image editing, and multi reference generation in one unified architecture. The distilled FLUX.2 [klein] 4B and 9B models use 4 sampling steps and are optimized for sub second inference on a single modern GPU, while the undistilled Base models use longer schedules and are intended for fine tuning and research. Quantized FP8 and NVFP4 variants, built with NVIDIA, provide up to 1.6 times speedup with about 40 percent VRAM reduction for FP8 and up to 2.7 times speedup with about 55 percent VRAM reduction for NVFP4 on RTX GPUs. Check out the Technical details, Repo and Model weights. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive Visual Intelligence appeared first on MarkTechPost.

Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive Visual Intelligence Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive Visual Intelligence

Black Forest Labs releases FLUX.2 [klein], a compact image model family that targets interactive visual intelligence on consumer hardware. FLUX.2 [klein] extends the FLUX.2 line with sub second generation and editing, a unified architecture for text to image and image to image, and deployment options that range from local GPUs to cloud APIs, while keeping state of the art image quality. From FLUX.2 [dev] to interactive visual intelligence FLUX.2 [dev] is a 32 billion parameter rectified flow transformer for text conditioned image generation and editing, including composition with multiple reference images, and runs mainly on data center class accelerators. It is tuned for maximum quality and flexibility, with long sampling schedules and high VRAM requirements. FLUX.2 [klein] takes the same design direction and compresses it into smaller rectified flow transformers with 4 billion and 9 billion parameters. These models are distilled to very short sampling schedules, support the same text to image and multi reference editing tasks, and are optimized for response times below 1 second on modern GPUs. Model family and capabilities The FLUX.2 [klein] family consists of 4 main open weight variants through a single architecture. FLUX.2 [klein] 4B FLUX.2 [klein] 9B FLUX.2 [klein] 4B Base FLUX.2 [klein] 9B Base FLUX.2 [klein] 4B and 9B are step distilled and guidance distilled models. They use 4 inference steps and are positioned as the fastest options for production and interactive workloads. FLUX.2 [klein] 9B combines a 9B flow model with an 8B Qwen3 text embedder and is described as the flagship small model on the Pareto frontier for quality versus latency across text to image, single reference editing, and multi reference generation. The Base variants are undistilled versions with longer sampling schedules. The documentation lists them as foundation models that preserve the complete training signal and provide higher output diversity. They are intended for fine tuning, LoRA training, research pipelines, and custom post training workflows where control is more important than minimum latency. All FLUX.2 [klein] models support three core tasks in the same architecture. They can generate images from text, they can edit a single input image, and they can perform multi reference generation and editing where several input images and a prompt jointly define the target output. Latency, VRAM, and quantized variants The FLUX.2 [klein] model page provides approximate end to end inference times on GB200 and RTX 5090. FLUX.2 [klein] 4B is the fastest variant and is listed at about 0.3 to 1.2 seconds per image, depending on hardware. FLUX.2 [klein] 9B targets about 0.5 to 2 seconds at higher quality. The Base models require several seconds because they run with 50 step sampling schedules, but they expose more flexibility for custom pipelines. The FLUX.2 [klein] 4B model card states that 4B fits in about 13 GB of VRAM and is suitable for GPUs like the RTX 3090 and RTX 4070. The FLUX.2 [klein] 9B card reports a requirement of about 29 GB of VRAM and targets hardware such as the RTX 4090. This means a single high end consumer card can host the distilled variants with full resolution sampling. To extend the reach to more devices, Black Forest Labs also releases FP8 and NVFP4 versions for all FLUX.2 [klein] variants, developed together with NVIDIA. FP8 quantization is described as up to 1.6 times faster with up to 40 percent lower VRAM usage, and NVFP4 as up to 2.7 times faster with up to 55 percent lower VRAM usage on RTX GPUs, while keeping the core capabilities the same. Benchmarks against other image models Black Forest Labs evaluates FLUX.2 [klein] through Elo style comparisons on text to image, single reference editing, and multi reference tasks. The performance charts show FLUX.2 [klein] on the Pareto frontier of Elo score versus latency and Elo score versus VRAM.The commentary states that FLUX.2 [klein] matches or exceeds the quality of Qwen based image models at a fraction of the latency and VRAM, and that it outperforms Z Image while supporting unified text to image and multi reference editing in one architecture. https://bfl.ai/blog/flux2-klein-towards-interactive-visual-intelligence The base variants trade some speed for full customizability and fine tuning, which aligns with their role as foundation checkpoints for new research and domain specific pipelines. Key Takeaways FLUX.2 [klein] is a compact rectified flow transformer family with 4B and 9B variants that supports text to image, single image editing, and multi reference generation in one unified architecture. The distilled FLUX.2 [klein] 4B and 9B models use 4 sampling steps and are optimized for sub second inference on a single modern GPU, while the undistilled Base models use longer schedules and are intended for fine tuning and research. Quantized FP8 and NVFP4 variants, built with NVIDIA, provide up to 1.6 times speedup with about 40 percent VRAM reduction for FP8 and up to 2.7 times speedup with about 55 percent VRAM reduction for NVFP4 on RTX GPUs. Check out the Technical details, Repo and Model weights. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive Visual Intelligence appeared first on MarkTechPost.

Black Forest Labs Releases FLUX.2 [klein]: Compact Flow Models for Interactive Visual Intelligence Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Controlled Self-Evolution for Algorithmic Code Optimization

arXiv:2601.07348v4 Announce Type: replace Abstract: Self-evolution methods enhance code generation through iterative “generate-verify-refine” cycles, yet existing approaches suffer from low exploration efficiency, failing to discover solutions with superior complexity within limited budgets. This inefficiency stems from initialization bias trapping evolution in poor solution regions, uncontrolled stochastic operations lacking feedback guidance, and insufficient experience utilization across tasks. To address these bottlenecks, we propose Controlled Self-Evolution (CSE), which consists of three key components. Diversified Planning Initialization generates structurally distinct algorithmic strategies for broad solution space coverage. Genetic Evolution replaces stochastic operations with feedback-guided mechanisms, enabling targeted mutation and compositional crossover. Hierarchical Evolution Memory captures both successful and failed experiences at inter-task and intra-task levels. Experiments on EffiBench-X demonstrate that CSE consistently outperforms all baselines across various LLM backbones. Furthermore, CSE achieves higher efficiency from early generations and maintains continuous improvement throughout evolution. Our code is publicly available at https://github.com/QuantaAlpha/EvoControl.

Controlled Self-Evolution for Algorithmic Code Optimization Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Take Out Your Calculators: Estimating the Real Difficulty of Question Items with LLM Student Simulations

arXiv:2601.09953v1 Announce Type: new Abstract: Standardized math assessments require expensive human pilot studies to establish the difficulty of test items. We investigate the predictive value of open-source large language models (LLMs) for evaluating the difficulty of multiple-choice math questions for real-world students. We show that, while LLMs are poor direct judges of problem difficulty, simulation-based approaches with LLMs yield promising results under the right conditions. Under the proposed approach, we simulate a “classroom” of 4th, 8th, or 12th grade students by prompting the LLM to role-play students of varying proficiency levels. We use the outcomes of these simulations to fit Item Response Theory (IRT) models, comparing learned difficulty parameters for items to their real-world difficulties, as determined by item-level statistics furnished by the National Assessment of Educational Progress (NAEP). We observe correlations as high as 0.75, 0.76, and 0.82 for grades 4, 8, and 12, respectively. In our simulations, we experiment with different “classroom sizes,” showing tradeoffs between computation size and accuracy. We find that role-plays with named students improves predictions (compared to student ids), and stratifying names across gender and race further improves predictions. Our results show that LLMs with relatively weaker mathematical abilities (Gemma) actually yield better real-world difficulty predictions than mathematically stronger models (Llama and Qwen), further underscoring the suitability of open-source models for the task.

Take Out Your Calculators: Estimating the Real Difficulty of Question Items with LLM Student Simulations Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Clozing the Gap: Exploring Why Language Model Surprisal Outperforms Cloze Surprisal

arXiv:2601.09886v1 Announce Type: new Abstract: How predictable a word is can be quantified in two ways: using human responses to the cloze task or using probabilities from language models (LMs).When used as predictors of processing effort, LM probabilities outperform probabilities derived from cloze data. However, it is important to establish that LM probabilities do so for the right reasons, since different predictors can lead to different scientific conclusions about the role of prediction in language comprehension. We present evidence for three hypotheses about the advantage of LM probabilities: not suffering from low resolution, distinguishing semantically similar words, and accurately assigning probabilities to low-frequency words. These results call for efforts to improve the resolution of cloze studies, coupled with experiments on whether human-like prediction is also as sensitive to the fine-grained distinctions made by LM probabilities.

Clozing the Gap: Exploring Why Language Model Surprisal Outperforms Cloze Surprisal Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Three technologies that will shape biotech in 2026

Earlier this week, MIT Technology Review published its annual list of Ten Breakthrough Technologies. As always, it features technologies that made the news last year, and which—for better or worse—stand to make waves in the coming years. They’re the technologies you should really be paying attention to. This year’s list includes tech that’s set to transform the energy industry, artificial intelligence, space travel—and of course biotech and health. Our breakthrough biotechnologies for 2026 involve editing a baby’s genes and, separately, resurrecting genes from ancient species. We also included a controversial technology that offers parents the chance to screen their embryos for characteristics like height and intelligence. Here’s the story behind our biotech choices. A base-edited baby! In August 2024, KJ Muldoon was born with a rare genetic disorder that allowed toxic ammonia to build up in his blood. The disease can be fatal, and KJ was at risk of developing neurological disorders. At the time, his best bet for survival involved waiting for a liver transplant. Then he was offered an experimental gene therapy—a personalized “base editing” treatment designed to correct the specific genetic “misspellings” responsible for his disease. It seems to have worked! Three doses later, KJ is doing well. He took his first steps in December, shortly before spending his first Christmas at home. KJ’s story is hugely encouraging. The team behind his treatment is planning a clinical trial for infants with similar disorders caused by different genetic mutations. The team members hope to win regulatory approval on the back of a small trial—a move that could make the expensive treatment (KJ’s cost around $1 million) more accessible, potentially within a few years. Others are getting in on the action, too. Fyodor Urnov, a gene-editing scientist at the University of California, Berkeley, assisted the team that developed KJ’s treatment. He recently cofounded Aurora Therapeutics, a startup that hopes to develop gene-editing drugs for another disorder called phenylketonuria (PKU). The goal is to obtain regulatory approval for a single drug that can then be adjusted or personalized for individuals without having to go through more clinical trials. US regulators seem to be amenable to the idea and have described a potential approval pathway for such “bespoke, personalized therapies.” Watch this space. Gene resurrection It was a big year for Colossal Biosciences, the biotech company hoping to “de-extinct” animals like the woolly mammoth and the dodo. In March, the company created what it called “woolly mice”—rodents with furry coats and curly whiskers akin to those of woolly mammoths. The company made an even more dramatic claim the following month, when it announced it had created three dire wolves. These striking snow-white animals were created by making 20 genetic changes to the DNA of gray wolves based on genetic research on ancient dire wolf bones, the company said at the time. Whether these animals can really be called dire wolves is debatable, to say the least. But the technology behind their creation is undeniably fascinating. We’re talking about the extraction and analysis of ancient DNA, which can then be introduced into cells from other, modern-day species. Analysis of ancient DNA can reveal all sorts of fascinating insights into human ancestors and other animals. And cloning, another genetic tool used here, has applications not only in attempts to re-create dead pets but also in wildlife conservation efforts. Read more here. Embryo scoring IVF involves creating embryos in a lab and, typically, “scoring” them on their likelihood of successful growth before they are transferred to a person’s uterus. So far, so uncontroversial. Recently, embryo scoring has evolved. Labs can pinch off a couple of cells from an embryo, look at its DNA, and screen for some genetic diseases. That list of diseases is increasing. And now some companies are taking things even further, offering prospective parents the opportunity to select embryos for features like height, eye color, and even IQ. This is controversial for lots of reasons. For a start, there are many, many factors that contribute to complex traits like IQ (a score that doesn’t capture all aspects of intelligence at any rate). We don’t have a perfect understanding of those factors, or how selecting for one trait might influence another. Some critics warn of eugenics. And others note that whichever embryo you end up choosing, you can’t control exactly how your baby will turn out (and why should you?!). Still, that hasn’t stopped Nucleus, one of the companies offering these services, from inviting potential customers to have their “best baby.” Read more here. This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here.

Three technologies that will shape biotech in 2026 Beitrag lesen »

AI, Committee, Nachrichten, Uncategorized

Google AI Releases TranslateGemma: A New Family of Open Translation Models Built on Gemma 3 with Support for 55 Languages

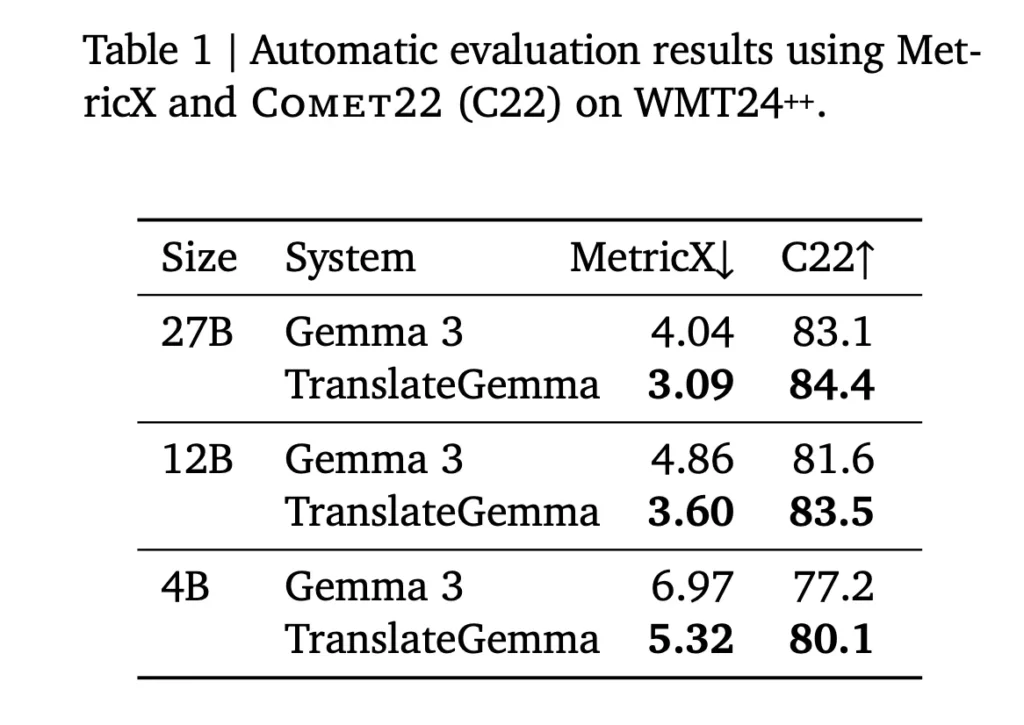
Google AI has released TranslateGemma, a suite of open machine translation models built on Gemma 3 and targeted at 55 languages. The family comes in 4B, 12B and 27B parameter sizes. It is designed to run across devices from mobile and edge hardware to laptops and a single H100 GPU or TPU instance in the cloud. TranslateGemma is not a separate architecture. It is Gemma 3 specialized for translation through a two stage post training pipeline. (1) supervised fine tuning on large parallel corpora. (2) Reinforcement learning that optimizes translation quality with a multi signal reward ensemble. The goal is to push translation quality while keeping the general instruction following behavior of Gemma 3. Supervised fine tuning on synthetic and human parallel data The supervised fine tuning stage starts from the public Gemma 3 4B, 12B and 27B checkpoints. The research team uses parallel data that combines human translations with high quality synthetic translations generated by Gemini models. Synthetic data is produced from monolingual sources with a multi step procedure. The pipeline selects candidate sentences and short documents, feeds them to Gemini 2.5 Flash, and then filters outputs with MetricX 24 QE to keep only examples that show clear quality gains. This is applied across all WMT24 plus plus language pairs plus 30 more language pairs. Low resource languages receive human generated parallel data from the SMOL and GATITOS datasets. SMOL covers 123 languages and GATITOS covers 170 languages. This improves coverage of scripts and language families that are under represented in publicly available web parallel data. The final supervised fine tuning mixture also keeps 30 percent generic instruction following data from the original Gemma 3 mixture. This is important. Without it, the model would over specialize on pure translation and lose general LLM behavior such as following instructions or doing simple reasoning in context. Training uses the Kauldron SFT (Supervised Fine tuning) tooling with the AdaFactor optimizer. The learning rate is 0.0001 with batch size 64 for 200000 steps. All model parameters are updated except the token embeddings, which are frozen. Freezing embeddings helps preserve representation quality for languages and scripts that do not appear in the supervised fine tuning data. Reinforcement learning with a translation focused reward ensemble After supervised fine tuning, TranslateGemma runs a reinforcement learning phase on top of the same translation data mixture. The reinforcement learning objective uses several reward models. The reward ensemble includes: MetricX 24 XXL QE, a learned regression metric that approximates MQM scores and is used here in quality estimation mode without a reference. Gemma AutoMQM QE, a span level error predictor fine tuned from Gemma 3 27B IT on MQM labeled data. It produces token level rewards based on error type and severity. ChrF, a character n gram overlap metric that compares model output with synthetic references and is rescaled to match the other rewards. A Naturalness Autorater that uses the policy model as an LLM judge and produces span level penalties for segments that do not sound like native text. A generalist reward model from the Gemma 3 post training setup that keeps reasoning and instruction following ability intact. TranslateGemma uses reinforcement learning algorithms that combine sequence level rewards with token level advantages. Span level rewards from AutoMQM and the Naturalness Autorater attach directly to the affected tokens. These token advantages are added to sequence advantages computed from reward to go and then batch normalized. This improves credit assignment compared with pure sequence level reinforcement learning. Benchmark results on WMT24++ TranslateGemma is evaluated on the WMT24++ benchmark using MetricX 24 and Comet22. MetricX is lower better and correlates with MQM error counts. Comet22 is higher better and measures adequacy and fluency. https://arxiv.org/pdf/2601.09012 The above Table from the research pape summarizes results for English centered evaluation over 55 language pairs. 27B: Gemma 3 baseline has MetricX 4.04 and Comet22 83.1. TranslateGemma 27B reaches MetricX 3.09 and Comet22 84.4. 12B: Gemma 3 baseline has MetricX 4.86 and Comet22 81.6. TranslateGemma 12B reaches MetricX 3.60 and Comet22 83.5. 4B: Gemma 3 baseline has MetricX 6.97 and Comet22 77.2. TranslateGemma 4B reaches MetricX 5.32 and Comet22 80.1. The key pattern is that TranslateGemma improves quality for every model size. At the same time, model scale interacts with specialization. The 12B TranslateGemma model surpasses the 27B Gemma 3 baseline. The 4B TranslateGemma model reaches quality similar to the 12B Gemma 3 baseline. This means a smaller translation specialized model can replace a larger baseline model for many machine translation workloads. https://arxiv.org/pdf/2601.09012 A language level breakdown in the above appendix table from the research paper shows that these gains appear across all 55 language pairs. For example, MetricX improves from 1.63 to 1.19 for English to German, 2.54 to 1.88 for English to Spanish, 3.90 to 2.72 for English to Hebrew, and 5.92 to 4.45 for English to Swahili. Improvements are also large for harder cases such as English to Lithuanian, English to Estonian and English to Icelandic. Human evaluation on WMT25 with MQM confirms this trend. TranslateGemma 27B usually yields lower MQM scores, that is fewer weighted errors, than Gemma 3 27B, with especially strong gains for low resource directions such as English to Marathi, English to Swahili and Czech to Ukrainian. There are two notable exceptions. For German as target both systems are very close. For Japanese to English TranslateGemma shows a regression caused mainly by named entity errors, even though other error categories improve. Multimodal translation and interface for developers TranslateGemma inherits the image understanding stack of Gemma 3. The research team evaluates image translation on the Vistra benchmark. They select 264 images that each contain a single text instance. The model receives only the image plus a prompt that asks it to translate the text in the image. There is no separate bounding box input and no explicit OCR step. On this setting, TranslateGemma 27B improves MetricX from 2.03 to 1.58 and Comet22 from 76.1 to 77.7. The 4B variant shows smaller but positive gains. The 12B model improves MetricX

Google AI Releases TranslateGemma: A New Family of Open Translation Models Built on Gemma 3 with Support for 55 Languages Beitrag lesen »

We use cookies to improve your experience and performance on our website. You can learn more at Datenschutzrichtlinie and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
de_DE