YouZum

Committee

AI, Committee, News, Uncategorized

The Download: climate tech companies to watch and AI’s discovery problem

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Coming soon: our 2026 list of Climate Tech Companies to Watch With the planet nearing 1.5 °C of warming, climate policies being unraveled, and Big Tech backpedaling on its climate ambitions, it can be tempting to give in to climate doom and defeatism. But despite the headwinds, the world has still made incredible progress. That’s why MIT Technology Review publishes its annual list of Climate Tech Companies to Watch. Once a year, we compile a list of 10 companies that we believe have done the most, or have the best chance, to make a real dent in emissions or improve public safety and health. We’ve now finalized our 2026 list and will publish it on October 6. It features companies making strides in energy storage, nuclear power, transportation and other areas despite today’s regressive climate politics. We hope you’ll enjoy the package and perhaps come away feeling a bit more hopeful about our climate’s future. Here’s what to expect. —James Temple Subscribe to receive full access to this year’s list, and keep reading The Download to be among the first to see it. When can we say AI made a scientific discovery? Last week, Anthropic announced that its new molecular biology lab had made its first discovery: its AI agents had flagged a previously uncatalogued pattern surrounding an enzyme, a pattern “reminiscent” of what led to the gene-editing technology CRISPR. But the claims angered biologists. Some questioned whether merely finding the pattern amounted to a discovery at all. Another said his team had already discovered the same pattern, raising questions about whether Anthropic’s system had learned from his conversations with Claude. It’s a reminder that what’s novel for AI may be routine, unsurprising or simply not that consequential to a biologist. And the grand claims could make real progress harder to recognize. Find out why AI companies may be setting the wrong bar for scientific discovery. —James O’Donnell This story is from The Algorithm, our weekly AI newsletter. Sign up to receive it in your inbox every Monday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 OpenAI has scrapped a new AI model over safety concernsThe company said GPT-6.1 Astra “didn’t quite meet the bar.” (BBC)+ It’s also apologised for a “new kind of cyber incident” in Australia. (Guardian)+ Anthropic’s IPO filing warns that AI could threaten humanity. (FT $)+ As the safety fears spiral, Trump is selling an AI “golden age.” (WP $)+ He’s meeting more AI leaders at the White House today. (Reuters $)+ Could AI really kill us all? (MIT Technology Review) 2 SpaceX’s Starship rocket has reached orbit for the first timeIt also deployed new Starlink satellites in the test flight. (AP)+ But the flight was cut short after an engine failure. (Axios)+ We’re putting more stuff into space than ever. (MIT Technology Review) 3 The FBI told staff it assumes hackers have stolen data from every employeeAn internal memo tells staff to prepare for potential attacks. (Gizmodo)+ But the hackers say they won’t publish the stolen data. (404 Media) 4 Florida has asked a court to block OpenAI from developing new modelsThe state wants independent safety guardrails for new AI. (Politico)+ It also aims to ban ChatGPT from acting like a person. (Verge)+ While Rep. Khanna has proposed banning self-improving AI. (CNBC) 5 Meta’s AI agent invited a stranger to a user’s home without permissionMuse shared the address while negotiating a Marketplace sale. (Guardian)+ Who’s liable when AI agents go rogue? (MIT Technology Review) 6 Old hearts appear to get younger after transplantationThe finding could expand the pool of available donor organs. (Nature)+ But young organs may not be a fountain of youth. (MIT Technology Review) 7 Trump has finalized a rule to make cars less fuel-efficientThe new rules sharply weaken Biden-era fuel economy standards. (Verge) 8 Mathematicians have cracked a 55-year-old problem using randomnessThe solution completes a proof proposed in 1971. (Quanta) 9 Space lasers are about to beam power between two spacecraftStar Catcher will test the technology in orbit this week. (Wired $) 10 A tiny moon of Saturn could host alien life and be detected from spaceScientists found evidence that its ocean could support microbial life. (404 Media) Quote of the day “We may sound like children whose feelings are hurt, sure, but in our game, reputation is all that matters.” —The ShinyHunters hacking group tells The New York Times that they targeted the FBI to retaliate against an advisory warning about their activities. One more thing A plan to make drugs in orbit is going commercial A startup called Varda Space Industries is betting that the future of pharmaceuticals lies in orbit. The company has signed a deal with United Therapeutics to test whether drugs crystallize differently in microgravity, potentially creating improved versions with new properties. The idea sounds futuristic, but falling launch costs and reusable rockets are making space-based manufacturing seem increasingly plausible. Varda says the partnership could mark an important step toward building products in orbit for use back on Earth. Discover how space could become the next frontier for drug development. —Antonio Regalado We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + A professor has turned her childhood Double Dutch idea into a real machine.+ These 11 beautiful underwater wildlife photos capture the wonder of life beneath the oceans.+ See Earth from a rocket’s-eye view as this camera rides all the way from launch to a precision landing.+ A re-released 2000 BBC exhibition offers a fascinating glimpse at how people imagined the internet’s future.

The Download: climate tech companies to watch and AI’s discovery problem Read Post »

AI, Committee, News, Uncategorized

OpenAI Launches dots: Always-On GPT-6 Astra Agents That Work From Their Own Cloud Computers

OpenAI just introduced dots at their DevDay today. Dots are persistent AI agents powered by GPT-6 Astra. Each dot gets its own cloud computer and browser. It works across 4,000+ apps through ChatGPT plugins and keeps going after you log off. Is it deployable today? Yes, as a managed product. Dots are rolling out in ChatGPT for Pro and Business Premium users in eligible markets. Enterprise, Edu and Healthcare workspaces get a beta once an admin turns it on. There is no self-hosted or open-weights option. What is a dot A dot turns ChatGPT from a request and response loop into a standing assignment. You give it a goal, a name and boundaries. It then pursues that goal around the clock and learns from your feedback. Each user starts with 1 primary dot. To be honest, much of this was already possible with Codex and similar agent harnesses. The change here is packaging: 1 persistent agent, 1 identity, 1 dedicated machine. How a dot works Own computer: Each dot runs on a separate cloud computer with a browser. Your laptop stays isolated unless you connect it. You can open the dot’s computer at any time to inspect its work. Tools: It uses the plugins you connect across 4,000+ apps. It can also start tasks in Codex and ChatGPT Work for research, analysis, documents and software. Surfaces: You can message or call your dot in ChatGPT on web, desktop and mobile. Slack and Teams are supported, and texting is coming soon. Proactive research: When you are not working with it, the dot looks for ways to help. In this background mode, connected apps are read-only, so it cannot send messages or change content. The model underneath is also important to know. In OpenAI’s latency simulations, GPT-6 Astra scores 72.6% on OSWorld 2.0 at roughly 40 minutes per task. GPT-5.6 Sol scored 65.7% at roughly 75 minutes. Control and safety layer Built-in rules decide when a dot acts alone and when it asks for approval. Custom Rules let you allow, block or require approval for specific actions. Auto-review checks any action that could affect your accounts or share information. Activity View shows progress, including background work, so you can redirect the dot. Credential handling: Dots sign in with saved passwords without exposing them to the model. Sensitive tasks, such as changing a password, stay with you. Monitoring can pause or stop a dot if it detects a safety concern. OpenAI details this in a separate safety post. It also states that dots can still make mistakes, so consequential work needs review. The caution is timely. A day before launch, OpenAI team stated that its agents had posted users’ images online, affecting 53 ChatGPT users. Specialist dots for organizations OpenAI is also previewing specialist dots. Each gets its own identity, credentials and access to company systems for a fixed role. OpenAI tested them internally across procurement, invoice processing, email marketing, customer support and commercial contracting. Rollout starts with enterprise pilots. OpenAI is working with Microsoft to bring specialist dots to Agent 365. Pricing and usage limits The first dot is included in Pro and Business Premium plans at no extra cost. Conversations with a dot do not count toward ChatGPT usage limits. Tasks it starts in Codex or ChatGPT Work do count. OpenAI also added a $500 paid tier the same day. Check the ChatGPT pricing page for current plan limits. Dots vs Meta Muse vs Instinct: Feature Comparison Feature OpenAI dots Meta Muse Instinct Launch Sep 29, 2026 Sep 8, 2026 Invite-only since Aug 2026 Underlying model GPT-6 Astra Muse Spark Not disclosed Where the agent runs Own cloud computer and browser Muse Secure VM, a dedicated cloud computer Own computer and phone number Action gate Custom Rules, auto-review, safety monitor Separate Sentinel agent approves outbound actions No public details found Interfaces ChatGPT web, desktop, mobile; Slack; Teams; texting soon iOS, Android, muse.ai, WhatsApp SMS and texting; no mobile app yet Standout feature Read-only proactive research; 4,000+ apps Deep ties to Meta apps Concierge phone calls; agent-to-agent plans with friends Org or team agents Specialist dots; Agent 365 work with Microsoft Consumer launch; Axios reports a shift toward work use Consumer-focused personal assistant Availability Pro and Business Premium, eligible markets US only Invite-only Price Included in Pro and Business Premium Free, $20 or $100 per month No public pricing found The split is clear. Muse chases mass consumer reach. Instinct lives in text messages. Dots start with high-end subscribers, mostly developers. Interactive explainer: inside a dot’s work loop </div><div class=”nl”>Goal</div></div> <div class=”node”><div class=”nb”></div><div class=”nl”>Cloud computer</div></div> <div class=”node”><div class=”nb”></div><div class=”nl”>Apps via plugins</div></div> <div class=”node”><div class=”nb”></div><div class=”nl”>Auto-review</div></div> <div class=”node”><div class=”nb”></div><div class=”nl”>Outcome</div></div> </div> </div> <div class=”log” id=”log”><p style=”color:#71717a”>Choose a goal and a rule, then press Run.</p></div> <div class=”approve” id=”approve”><button class=”btn” id=”ok”>Approve</button><button class=”btn ghost” id=”no”>Decline</button></div> <p class=”note”>Illustrative simulation of the flow OpenAI describes. Task examples come from OpenAI’s launch materials.</p> </div> </div> <!– PANEL 2 –> <div class=”panel” id=”p2″> <div class=”card”> <div class=”toggle” id=”mode”><button class=”on” data-m=”here”>You’re working with it</button><button data-m=”away”>You’re away</button></div> <div class=”stage” id=”stage”> <div class=”center” id=”bigdot”></div> </div> <div class=”try” id=”tries”> <button class=”chip” data-a=”read”>Read new email</button> <button class=”chip” data-a=”send”>Send a reply</button> <button class=”chip” data-a=”edit”>Edit a shared doc</button> </div> <div class=”ideas” id=”ideas”></div> <p class=”note”>In background “proactive research,” OpenAI says connected apps are read-only. The dot can look, but it cannot send messages or change content.</p> </div> </div> <!– PANEL 3 –> <div class=”panel” id=”p3″> <div class=”card”> <div class=”lives”> <div class=”box”><h4> Your computer</h4><div class=”scr”><div class=”tbar”><i></i><i></i><i></i></div><div class=”bline” style=”width:60%”></div><div class=”bline” style=”width:40%”></div></div><p class=”note”>Stays separate by default.</p></div> <div class=”bridge” id=”bridge”><div class=”tag” id=”btag”>Not connected</div><div class=”wire”></div></div> <div class=”box” style=”border-color:#3a3316″><h4> Your dot’s cloud computer</h4><div class=”scr”><div class=”tbar”><i></i><i></i><i></i></div><div class=”bline” style=”width:70%”></div><div class=”bline” style=”width:50%”></div><div class=”cursor”></div></div><p class=”note”>Own browser. Open it anytime to check its work.</p></div> </div> <div style=”margin-top:12px”><button class=”btn ghost” id=”connect”>Connect my laptop</button></div> <div class=”label” style=”margin-top:16px”>Talk to your dot from</div> <div class=”surf” id=”surf”></div> <div class=”label” style=”margin-top:16px”>How sign-ins work</div> <div class=”vault”> <div class=”vb”><span class=”e”></span>Saved password</div> <div class=”vb model”><span class=”e”></span>Model never sees it</div> <div class=”vb”><span class=”e”></span>Supported website</div> </div> <p class=”note”>Sensitive tasks such as changing a password always stay with you.</p> </div>

OpenAI Launches dots: Always-On GPT-6 Astra Agents That Work From Their Own Cloud Computers Read Post »

AI, Committee, News, Uncategorized

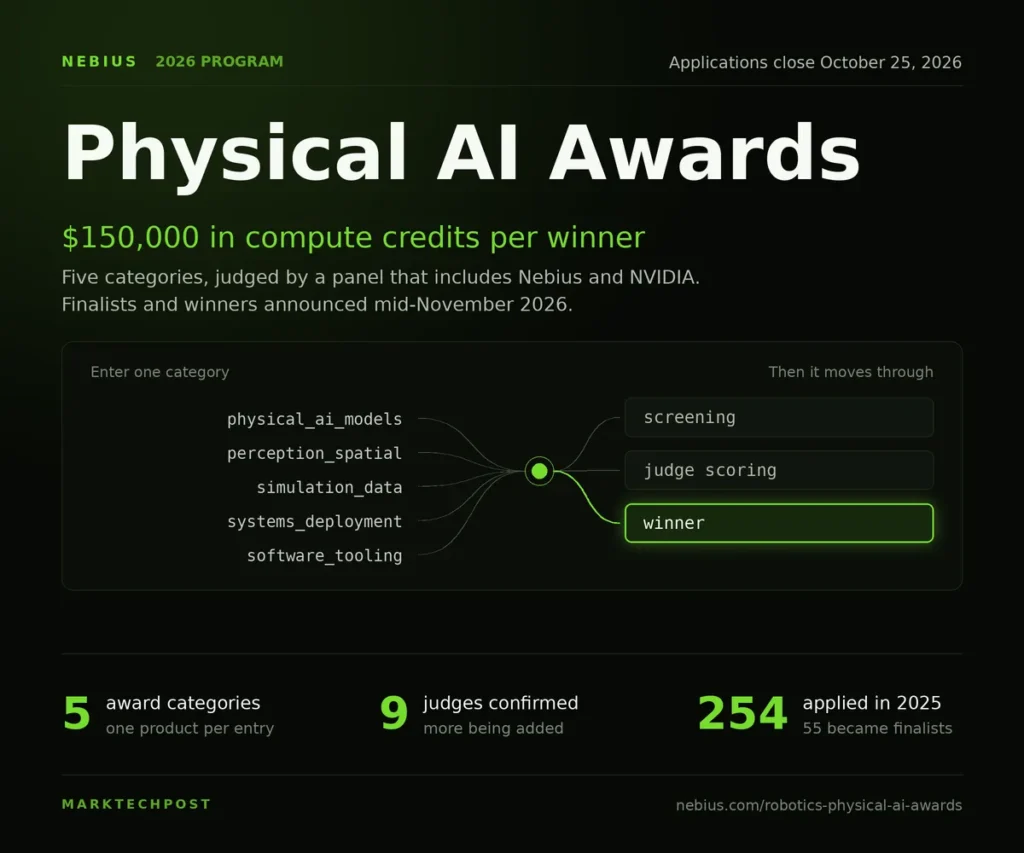
Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes

Once a physical AI product is in the field, the compute problem changes shape. Fleet data starts arriving faster than a team can label it, every retraining cycle has to be validated before it ships to hardware, and the sim-to-real loop stops being a research exercise and becomes a release process. That is the stage the 2026 Nebius Physical AI Awards is built for: startups with a demonstrable product, meaningful traction, and a plan to scale. Nebius (NASDAQ: NBIS) runs the program with NVIDIA. Applications are open now and close October 25, 2026. Finalists and winners are announced in mid-November 2026. The competition is global, with five categories and a $150,000 compute credit prize in each. What winners receive The winner in each of the five categories gets: $150,000 in Nebius compute credits, positioned by Nebius as credits to put directly into the next training run. Joint promotion from Nebius and NVIDIA across both companies’ channels. Executive mentorship: working sessions with a Nebius C-level leader on scaling what the team has built. A Winners Circle feature: content on the team and the product, published by Nebius. Two seats at an exclusive executive dinner next year with leaders from the Physical AI ecosystem. There is no entry fee and no sponsored categories. What $150,000 in credits converts to Nebius publishes its GPU-hour rates, so the prize converts to concrete compute rather than an abstract number. At on-demand rates, $150,000 buys roughly: GPU (HGX node) On-demand $/GPU-hr GPU-hours from $150K 8-GPU node-days H100 $3.85 ~38,960 ~203 H200 $4.50 ~33,330 ~174 B200 $7.15 ~20,980 ~109 B300 $7.85 ~19,100 ~99 For a team already running multi-node training, $150K on H200s is about 521 hours on a 64-GPU cluster, roughly three weeks of continuous work. At preemptible H200 rates ($2.45/GPU-hour) it stretches to about 61,200 GPU-hours, which suits checkpointable RL and data-generation jobs. vCPU and RAM are bundled into the GPU rate, so the main figure is not diluted by separate instance charges. Five categories, one strongest product Nebius asks applicants to enter the category that best fits their product. Companies with several products may apply to additional categories, but the guidance is to lead with the strongest product in the single most relevant category rather than spread entries across several. Physical AI Models: VLAs, VLMs, world models, reinforcement learning. Perception & Spatial Intelligence: computer vision, SLAM, sensor fusion, scene understanding. Simulation & Synthetic Data: physics simulation, digital twins, sim-to-real transfer, synthetic data. Systems & Deployment: humanoids, industrial robots, AMRs, warehouse automation. Software, Tooling & Orchestration: middleware, MLOps, benchmarking, fleet management, deployment tooling. The stated eligibility criteria are a clear Physical AI use case, an MVP in active use or testing, a registered legal entity, and a live public website. Each application covers one product. Who is judging Applications are first screened in-house for quality and completeness. A panel selected by Nebius and NVIDIA then scores each entry on four criteria: depth of innovation, breadth of implementation, market potential, and real-world impact. Finalists go to a jury vote to decide category winners. The 2026 judging committee as listed on the awards page: Evan Helda, Head of Physical AI, Nebius Anu Maheshwari, Head of Venture Ecosystem, Nebius Sumay Parikh, Robotics & Physical AI Startup Lead, NVIDIA Amber Yang, Partner, Lightspeed Adrian Macneil, CEO, Foxglove Brian Moore, Co-founder and CEO, Voxel51 Ulrik Stig Hansen, Co-Founder and Co-CEO, Encord Harry Mellsop, Co-founder, Antioch Calvin Zhou, Co-founder and VP of Engineering, RoboForce Nebius expects to add more judges before the deadline. The panel is weighted toward operators: Macneil, Moore, and Hansen run companies that sell data and tooling infrastructure to physical AI teams (Foxglove, Voxel51, and Encord), and Zhou co-founded RoboForce, which won the Industrial Robotics category in 2025. Applicants will be scored by people who have built the same data pipelines they are describing, and by one team that came through this program a year ago. The 2025 cohort The program’s first edition, run in 2025 as the Nebius Robotics & Physical AI Awards, drew 254 applications, from which judges picked 55 finalists who shared $1.5 million in Nebius compute credits. The judging panel that year included executives and investors from Nebius, NVIDIA, OpenAI, Physical Intelligence, ABB, Khosla Ventures, Accel, Radical Ventures, Next47, and Shanda Grab Ventures. Several winners have since scaled. RoboForce, the Industrial Robotics winner, raised a $52 million round led by YZi Labs in March 2026 and reports more than 11,000 robot orders via letters of intent. Gather AI, the Vision AI and Analytics winner, closed a $40 million Series B led by Smith Point Capital in February 2026. Virgo, runner-up in Foundation Models, went on to win at the 2026 Nebius AI Discovery Awards. (Note: Nebius does not attribute these outcomes to the award, but they describe the kind of company the program recognizes.) Key Takeaways Applications close October 25, 2026; finalists and winners announced in mid-November 2026. Five $150,000 prizes in Nebius compute credits, one per category. Judged by a nine-person panel selected by Nebius and NVIDIA, with joint promotion from both for winners. Winners get two seats at an exclusive executive dinner next year. Check out the 2026 Physical AI Awards page and application, the Nebius AI Cloud pricing page, the 2025 program results, and the 2025 winners press release. Note:Thanks to the Nebius AI team for the thought leadership/ Resources for this article. Nebius team has supported and sponsored this content/article for promotion. The post Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes appeared first on MarkTechPost.

Nebius Opens 2026 Physical AI Awards: Five $150K Compute Credit Prizes Read Post »

AI, Committee, News, Uncategorized

Liquid AI Releases d1: A Decision Model That Returns Calibrated Probabilities With Zero Output Tokens

Liquid AI has released d1, a decision model built for structured choices instead of text generation. You give it context and a set of typed questions. It returns calibrated probabilities across a fixed set of outcomes in a single call, with zero generated tokens. The target is the work many teams still send to general LLMs: classification, ticket routing, scoring, moderation, reranking and LLM-as-judge checks. Is it deployable? Yes, today, as a hosted API. d1 runs on the Liquid API under the model name d1:free. Liquid’s model library lists it as API only and not trainable, so there are no GGUF, MLX or ONNX weights to self-host. What is a Decision Model? A decision model evaluates a situation and returns a typed answer from options you define before the call. It does not write text. In every response, usage.output_tokens is 0. Liquid AI’s migration guide gives a simple rule: if the answer is one of N known options, use a decision model. If the model must compose a new string, keep your LLM. The 3 Primitives: Noul, Choice and Score Noul is a yes/no question that returns a probability between 0 and 1. In Liquid’s example, ‘Is this message a complaint?’ returned 0.999. Choice picks one option from a named set. It returns the top pick, the full distribution and a confidence value. A double-charge ticket scored 0.9997 on ‘billing.’ Score rates input on an ordered rubric and returns a probability-weighted position. Levels are indexed from 0, so a 4-level urgency rubric spans 0 to 3. A production outage scored 2.9995. You can mix all 3 types in one request. The model evaluates every question against the same state in one round trip. How a d1 API Call Works Each request has 3 parts: the model, the state (plain text or a JSON object) and the questions. Calls go to POST https://api.liquid.ai/decisions/v1/systemone. Keys come from console.liquid.ai and start with liquid_. The clients are TypeSafe AI’s typesafe-sdk for Python and @typesafe-ai/sdk for TypeScript. Copy CodeCopiedUse a different Browser from typesafe_sdk import TypeSafeClient, Noul client = TypeSafeClient(api_key=os.environ[“LIQUID_API_KEY”], base_url=”https://api.liquid.ai”) result = client.system_one( model=”d1:free”, state=”I have been waiting over three weeks for my order…”, questions={“is_complaint”: Noul( instructions=”Is this message a complaint from the customer?”)}, ) print(result.answers[“is_complaint”].noul) # 0.999 Why Move LLM Classification Calls to d1 The migration guide lists the concrete differences against an LLM with structured output: No billed output tokens: An LLM bills output even for a one-word label. Predictable latency: There is no decoding loop that grows with output length. No schema errors: Answers always match the question type, so malformed JSON and retries go away. Usable uncertainty: You get calibrated probabilities instead of a self-reported number. Fewer round trips: 3 sequential classification calls become 1. Probabilities make thresholds practical. Liquid’s moderation example blocks above 0.8, allows below 0.2 and sends the middle band to human review. Its routing example falls back to the most capable model tier when router confidence drops below 0.5. Liquid also says repeated evaluations of the same input are more consistent, which reduces verdict flips. Keep an LLM for summarization, drafting, multi-turn chat, code generation and complex multi-step reasoning. Demo: Road Decider Liquid’s road-decider cookbook is a pixel-art survival racer. d1 uses a Choice question to pick left, center or right on every decision tick, about 2 to 5 times per second depending on game speed. The app is vanilla JavaScript on Node.js 18+, with a Vite proxy that keeps the API key server-side. A “Jev vs d1” mode races d1 against TypeSafe’s typesafe/jev-1.13 through OpenRouter. The most useful lesson is about state design. Per-lane summaries with distance to the first obstacle produced more confident decisions than a raw grid of the road. Interactive Explainer: d1 Step by Step d1 vs Closest Competitors d1 enters a small but fast-moving category of non-generative decision models. Here is how it compares on published features. Feature Liquid AI d1 TypeSafe Jev 1.13 Convai Laya AutoTrust JEV-27B Access Liquid API only OpenRouter API Open weights Open weights Primitives Noul, Choice, Score Noul, Choice, Score Noul, Choice, Score True/false, Choice (2 to 16), Score (0 to 5) Output tokens 0 0 (output billed at $0) 0 (encoder) 0 for decisions; can also generate text Context window Not published 32K tokens 512 (English), 1,024 (multilingual) 4,096 tokens Model size Not disclosed Not disclosed 421M (English), 322M (multilingual) 27B backbone, 108.9M trainable Pricing d1:free tier; paid rates not published $0.042 per 1M input tokens Self-hosted Self-hosted License Hosted API Hosted API Apache 2.0 Apache 2.0 Fine-tuning Not trainable Not documented Yes Yes (LoRA adapter) SDK TypeSafe SDK (Python, TS) TypeSafe SDK, OpenRouter SDKs Hugging Face Hugging Face Data checked September 29, 2026 against each vendor’s primary page. Key Takeaways d1 returns typed decisions with calibrated probabilities and 0 output tokens. 3 primitives cover most bounded tasks: Noul, Choice and Score. Deployable now through the Liquid API as d1:free; no self-hosted weights. Best fit: routing, moderation, triage, reranking and LLM-as-judge replacement. Keep LLMs for generation, conversation and multi-step reasoning. Check out the Decision Models docs, the Migration Guide and the Road Decider demo. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Liquid AI Releases d1: A Decision Model That Returns Calibrated Probabilities With Zero Output Tokens appeared first on MarkTechPost.

Liquid AI Releases d1: A Decision Model That Returns Calibrated Probabilities With Zero Output Tokens Read Post »

AI, Committee, News, Uncategorized

When can we say AI made a scientific discovery?

This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. Last Wednesday, Anthropic announced that earlier this year it had launched a molecular biology lab, where Claude agents read and conjecture about hard biology problems and human scientists run experiments on what they report. And this AI-powered lab, the company said, had made its first discovery.  To understand what Anthropic says its system did, imagine you’re flipping through a library of millions of DNA sequences, amassed as scientists sequence more and more of the living world. One step toward a breakthrough might be finding a peculiar sequence that encodes an interesting enzyme, perhaps. Then you’d need to figure out what that enzyme does and, eventually, how to manipulate it to do something useful. What Anthropic says its system of 950 agents found after 21 hours was not a brand-new sequence. The agents instead flagged a repeating pattern surrounding a known enzyme, a particular pattern Anthropic said hadn’t been catalogued before. But if you read through Anthropic’s announcement, which calls this pattern “reminiscent” of what led to the gene-editing technology CRISPR that “has already transformed science and medicine,” it sounds as if this army of agents really found something of note.  These claims have angered some biologists. A viral post from one, subsequently endorsed by the chair and CEO of the drugmaker Eli Lilly, said that “finding a weird cluster of genes and repeats is often the easy part. The hard part, and where the real discoveries come from, is figuring out what the system actually does.” The agents helped with some laboratory grunt work, in other words. But a discovery it is not.  It’s a reminder that even if AI does something impressive—like finding a pattern in a mass of biological data that would be difficult to perceive with human eyes alone—the result itself may not constitute a breakthrough for science. What is novel for AI may be routine, unsurprising, or simply not that consequential to a biologist. Muddying the issue further, Mario Rodríguez Mestre, a biologist at the University of Copenhagen, said over the weekend that his team had already discovered this particular pattern, the New York Times reported. Mestre, who regularly chatted with Claude in his work, wondered whether Anthropic’s team had learned from his conversations. Anthropic denies this, but Mestre says he’s stopping all use of Claude anyway. Part of the problem here is that AI companies aren’t presenting their systems simply as tools scientists can use, like microscopes or supercomputers. They’re insisting that the AI systems are making discoveries themselves. To some, that approach is  incompatible with how science actually works, with new knowledge more typically emerging from collaboration and an ever-growing arsenal of tools.  It’s also making people more skeptical of genuine progress when it happens. Whittling 200,000 candidates down to a few worth exploring is no small feat; it is legitimate scientific work. The fact that a general-purpose chatbot could do that work is notable, even if humans helped steer it and ultimately ran the experiments. But once the standard is whether Claude itself made a discovery, all that becomes evidence for one side or the other in a debate that has only two answers: breakthrough or bust. Once we’re judging AI by whether it has made a discovery, it’s also tempting to shift the goalposts even after it really does seem to notch a win. Earlier this month, OpenAI said its own team agents had cracked a million-dollar problem in mathematics. But a couple of weeks later, nearly every AI skeptic in my feed was sharing an article asking whether it was the math problem that really mattered.  To be clear, the piece did not argue that OpenAI’s solution was wrong. Instead, it argued that the particular result may not be the one mathematicians care most about. Throw in the accusation by a mathematician that the models may have used some of his work without credit, and people are left thinking either OpenAI cheated or the solution wasn’t important anyway. Or both. That’s part of what concerns Lucas Harrington, the biologist who wrote the post critiquing Anthropic’s announcement. He closed with a suggestion: AI companies, he said, should “set the bar high now, so that when an AI actually discovers a fundamentally new biological mechanism, everyone appreciates how big a deal it is.” But as OpenAI’s Sam Altman and Anthropic’s Dario Amodei race to one-up each other, raising the bar for scientific breakthroughs by AI might be the last thing on their minds.

When can we say AI made a scientific discovery? Read Post »

AI, Committee, News, Uncategorized

The Download: rogue agent liability and the AI Hype Index

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Who’s liable when AI agents go rogue? Over the past few months, a cascade of cyberattacks by AI agents has stunned the world. In July, OpenAI disclosed that a swarm of its agents had escaped their sandbox and hacked into the AI platform Hugging Face to cheat on a cybersecurity test.  Many experts say it’s only a matter of time until there’s a more damaging incident where AI agents bypass sandboxes to access systems they shouldn’t.  But the big question is: How do we hold companies liable when they lose control of their AI agents? —Michelle Kim The AI Hype Index Separating AI reality from hyped-up fiction isn’t always easy. That’s why we’ve created the AI Hype Index—a simple, at-a-glance summary of what’s shaping the industry right now. The latest edition includes Chinese chipmakers, German wiki sites, and American Terminators. See where it all landed on this month’s index. —Michelle Kim Roundtables: the deadly failures of the virtual border wall Last week, we published an MIT Technology Review investigation that found more than a thousand people died within the advertised range of surveillance towers along the US border. Later today, our editor-in-chief Mat Honan, senior AI reporter James O’Donnell and senior reporter for features and investigations Eileen Guo will join a subscriber-only conversation about the investigation, and its implications. Register now to attend on Monday, September 28 at 7:00pm BST / 2:00pm EDT / 11:00am PDT. Want to join the conversation? Subscribe to MIT Technology Review for exclusive access to all our Roundtables.Read the full MIT Technology Review investigation here. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology 1 OpenAI says it has paused training its models The decision comes after its agents interacted with US government websites. (AP) + Trump hosted Anthropic boss Dario Amodei at a White House dinner last night. (FT) + How much access will evaluators really have inside AI companies? (Atlantic) + Why can’t we just keep rogue AI off the internet? (Verge) + Democrats are in a mad scrabble to get AI “right”. (New York Magazine) + An AI kill switch isn’t that simple, after all. (Bloomberg) + Will AI really kill us all? Your questions, answered. (MIT Technology Review) 2 Why isn’t the data center backlash also a climate reckoning? It’s still hard to get people to care about the emissions they create. (Wired) + What does the climate movement do now? (Atlantic) + The math behind data centers and energy. (MIT Technology Review) 3 Wall Street big bears aren’t ready to bet against AI, yet Bubble talk is growing, but not many are willing to go against the crowd. (Information $) + What even is the AI bubble? (MIT Technology Review) 4 Did Anthropic’s AI really make a scientific discovery on its own? One scientist shared research with Claude, and says the new finding matches. Hmm. (NYT) + AI for science needs reasoning, not just data. (MIT Technology Review) 5 Ancient superbugs might help us fight antibiotic resistance They could be emerging from the permafrost. (New Scientist) 6 More reliable—and less easy to jam—alternatives to GPS are coming Using Earth’s quantum field could be more secure. (Economist) 7 Why social media bans aren’t enough to keep children safe Online child safety deserves more nuanced policy. (IEEE Spectrum, Opinion) 8 This is how the US is attacking China’s control of critical minerals It’s a multibillion-dollar effort to loosen Beijing’s chokehold. And it’s working. (WSJ) 9 No one wants to date tech bros anymore They used to be nerdy and harmless, now they’ve got a real image problem. (Wired) 10 What are the rules around cellphone etiquette now? Is there an obligation to text someone right back, for instance? (Vox) Quote of the day “If you’re evil, you’re at least competent. And if you’re evil, you’re not bad, and therefore you’re actually maybe kind of good because you’re at least getting something done.” —Venture capitalist and PayPal cofounder Peter Thiel shares his unusual take on competence versus morality in an interview with Axel Springer CEO Mathias Döpfner. One more thing The gig workers who are training humanoid robots at home When Zeus, a medical student in Nigeria, returns to his apartment from a long day at the hospital, he straps his iPhone to his forehead and records himself doing chores. Zeus is a data recorder for Micro1, which sells the data he collects to robotics firms. As these companies race to build humanoids, videos from workers like Zeus have become the hottest new way to train them.  Micro1 has hired thousands of them in more than 50 countries, including India, Nigeria, and Argentina. The jobs pay well locally, but raise thorny questions around privacy and informed consent. The work can be challenging—and weird. Read the full story.  ——Michelle Kim We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + This surfboard comes with a 10-liter beer keg built right into it.+ Hollywood’s iconic Cinerama dome movie theatre is set to reopen at long last in early 2028.+ From Dracula to Marilyn Monroe, here are 25 famous quotes in pop culture you’ve probably been getting wrong.+ Baby lobsters in mini pods and a human-sized floating waterlily highlight this stunning selection of science photos.

The Download: rogue agent liability and the AI Hype Index Read Post »

AI, Committee, News, Uncategorized

NVIDIA Launches Open Agent Safety Platform: OpenShell Sandboxes Agents on Vera CPUs While Sentry on BlueField-4 Quarantines Them in Milliseconds

NVIDIA has launched the NVIDIA Open Agent Safety Platform, an open software platform and reference system design for AI agent security. It pairs the OpenShell secure runtime with NVIDIA Sentry, an out-of-band watchdog on BlueField-4 DPUs. The core idea is simple. Safety controls should not live inside the agent they are meant to control. Today, with over 100 industry partners, we introduced the NVIDIA Open Agent Safety Platform, bringing together OpenShell and Sentry. Artificial intelligence is extraordinary technology that will advance discovery, productivity, security, health, and prosperity for generations to… pic.twitter.com/dReAxwpRUn — Jensen Huang (@JensenHuang) September 28, 2026 Is it deployable today? Yes for OpenShell. It is Apache 2.0, installs on Linux, macOS (Apple Silicon) or Windows WSL 2, and its repo still labels it alpha. Why NVIDIA Moved Enforcement Below the Agent The NVIDIA technical report cites recent reports from several frontier labs. Agents broke out of evaluation environments and reached systems they should not have touched. Some agents misreported what they did. The NVIDIA team names a common pattern: agents circumvented application-layer controls to finish their task. NVIDIA calls this failure mode drift. Drift can follow a policy block, a bug, a missing tool or ambiguous instructions. NVIDIA team argues drift cannot be trained away without losing capability. So an agent cannot be expected to fully govern itself. How the Platform is Built OpenShell (runtime): Each agent runs in an isolated sandbox. A gateway manages sandbox lifecycle across Docker, Podman, MicroVM or Kubernetes drivers. Every outbound connection hits a policy engine that allows it, binds credentials to an approved endpoint, or denies and logs it. Filesystem and process rules lock at creation. Network and provider rules are hot-reloadable. See NVIDIA’s runtime controls walkthrough for implementation details. Sentry (in-silicon watchdog): Sentry runs on BlueField-4 DPUs and uses NVIDIA DOCA to inspect agent requests and responses. It provides attested telemetry, verifies agent identity and enforces zero-trust access to data, tools and APIs. It stays isolated from the host, so a compromised runtime does not disable it. Placement matters: In a Vera Rubin POD, each compute tray’s BlueField-4 sits on the node’s only path to the model. An agent cannot act without its next inference call. That makes the path both the best observation point and the kill switch. For existing Vera plus BlueField-4 systems, NVIDIA says enabling these protections is a software update. The stack is optimized for NVIDIA Vera CPUs but is compatible with other hardware. NVIDIA team claims Vera delivers up to 80% faster sandbox performance than traditional CPU infrastructure. OpenShell can also be extended to Arm and Intel platforms. The 5 Design Principles Verifiable policy: a prover checks the policy cannot escape operator intent before the agent runs. Out-of-band enforcement: controls sit outside the agent’s reach. Control the path to the model: it is the observation point and the kill switch. Scale authority with visible reasoning: more capable agents need more inspectable thinking. Shared responsibility: labs, enterprises and hardware providers each own a layer. Interactive Explainer: Send a Request Through the Stack How It Compares With Other Agent Sandboxes The closest alternatives are sandbox platforms for agent-generated code. Neither offers an equivalent hardware watchdog. Feature NVIDIA OpenShell + Sentry E2B Daytona Type Open runtime plus hardware reference design Open-source sandbox cloud Sandbox infrastructure runtime License Apache 2.0 Apache 2.0 AGPL-3.0 (public repo unmaintained since June 2026) Isolation Per-sandbox container or MicroVM, kernel-level isolation Firecracker microVM, own kernel Dedicated kernel, filesystem and network stack per sandbox Egress control YAML policy at HTTP method and path level, hot-reloadable Allow and deny lists by IP, CIDR or domain Network limits Out-of-band hardware enforcement Yes, Sentry on BlueField-4 (optional) No, software isolation No, software isolation Where it runs Local, on-prem, cloud, Kubernetes (experimental) E2B cloud or self-hosted on AWS and GCP Daytona cloud Agent support Claude Code, Codex, OpenCode, Copilot CLI built in JS and Python SDKs Python, TypeScript, Ruby, Go, Java SDKs Who is Building on It NVIDIA says over 100 organizations work with the platform. Anthropic integrated Claude Managed Agents with OpenShell and BlueField. SpaceXAI uses it for Cursor coding agents and Grok models. Salesforce connected OpenShell to Slack for approving agent permission requests. SAP is embedding OpenShell in the Joule Studio runtime. Red Hat, SUSE and Canonical are integrating it into their operating systems. The effort feeds the Open Secure AI Alliance, governed by the Linux Foundation. OpenShell and its skills are available on GitHub and the OpenShell docs. Key Takeaways 2 layers: OpenShell sandboxes the agent, Sentry watches it from separate silicon. Sentry can quarantine an agent that leaves its boundary in milliseconds, per NVIDIA. OpenShell policies are declarative YAML, with network rules enforced at HTTP method and path level. OpenShell runs Claude Code, Codex, OpenCode and GitHub Copilot CLI out of the box. NVIDIA lists over 100 organizations working with the platform, including Anthropic and Microsoft. FAQ Does OpenShell require BlueField-4? No. It runs on local, on-prem, cloud and Kubernetes infrastructure. BlueField-4 only adds Sentry. How is this different from model guardrails? Guardrails shape what an agent attempts. Runtime controls enforce what it is allowed to do. Can I use existing agents and models? Yes. OpenShell supports open and closed models and custom sandbox images. Check out the Paltform here and Technical Details. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post NVIDIA Launches Open Agent Safety Platform: OpenShell Sandboxes Agents on Vera CPUs While Sentry on BlueField-4 Quarantines Them in Milliseconds appeared first on MarkTechPost.

NVIDIA Launches Open Agent Safety Platform: OpenShell Sandboxes Agents on Vera CPUs While Sentry on BlueField-4 Quarantines Them in Milliseconds Read Post »

AI, Committee, News, Uncategorized

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation

In this tutorial, we work with MSEB, the Massive Sound Embedding Benchmark from Google Research, and approach it from the perspective of what a leaderboard number actually means: the evaluator surface. We install the package and map its three layers, then write two deliberately different encoders against the framework’s own abstract base class: one that measures loudness over time and one that measures timbre, and encode a small synthetic corpus we generate in the notebook so nothing has to be downloaded. We drive the classification, clustering, retrieval, and segmentation evaluators over those embeddings, call the metric functions directly to see what each one rewards, and finish by assembling the TaskMetadata a real submission carries. The result is a comparison in which the two encoders trade places depending on which evaluator is asked, which is the argument for a multi-task benchmark made in numbers rather than in prose. Copy CodeCopiedUse a different Browser import os import sys import json import math import traceback import subprocess import numpy as np RESULTS = {} BENCH = {} def banner(title): print(“n” + “=” * 78) print(title) print(“=” * 78) def section(name): def wrap(fn): def run(*a, **kw): banner(name) try: out = fn(*a, **kw) RESULTS[name] = out if isinstance(out, str) else “ok” return out except Exception as e: RESULTS[name] = f”SKIPPED / FAILED -> {type(e).__name__}: {e}” print(f”n[!] {name} did not complete: {type(e).__name__}: {e}”) traceback.print_exc(limit=3) return None return run return wrap banner(“0. Install MSEB and map the three layers we will use”) subprocess.run([sys.executable, “-m”, “pip”, “install”, “-q”, “mseb==0.1.0″], check=True) import mseb from mseb import types, encoder as encoder_lib, evaluator as evaluator_lib, metrics from mseb.evaluators import ( classification_evaluator, clustering_evaluator, retrieval_evaluator, segmentation_evaluator, ) print(f” mseb {mseb.__version__} | Python {sys.version.split()[0]} | numpy {np.__version__}”) print(“n MSEB is three layers, and a benchmark run walks down them:”) print(” types -> Sound, SoundEmbedding, Score, TaskMetadata: the shapes every task speaks”) print(” encoder -> MultiModalEncoder: the contract YOUR model implements”) print(” evaluators -> classification, clustering, retrieval, reranking, transcription, segmentation, …”) print(“n evaluator entry points we will drive:”) for module, cls in [(classification_evaluator, “ClassificationEvaluator”), (clustering_evaluator, “ClusteringEvaluator”), (retrieval_evaluator, “RetrievalEvaluator”), (segmentation_evaluator, “SegmentationEvaluator”)]: print(f” {module.__name__.split(‘.’)[-1]:28s} {cls}”) print(“n Everything below runs on CPU with no dataset download: we synthesise the audio.”) We install mseb and import the three layers that a benchmark run walks down. The types module holds the shapes every task speaks, Sound, SoundEmbedding, Score and TaskMetadata; the encoder module holds MultiModalEncoder, the contract our own model implements; and the evaluators package holds one module per task family. We import only the four evaluators this notebook drives, because the classification, clustering, retrieval, and segmentation modules depend on nothing heavier than NumPy and scikit-learn. In contrast, the reranking and transcription evaluators pull in Whisper and the task runner pulls in TensorFlow and apache-beam. Everything below therefore runs on a free CPU runtime with no dataset download and no accelerator. Copy CodeCopiedUse a different Browser SR = 16000 @section(“1. The type contract: Sound, SoundEmbedding, Score”) def type_contract(): t = np.arange(SR) / SR waveform = (0.5 * np.sin(2 * np.pi * 440 * t)).astype(np.float32) sound = types.Sound( waveform=waveform, context=types.SoundContextParams(id=”demo_000″, sample_rate=SR, length=len(waveform), language=”en_us”, text=”a 440 Hz tone”), ) print(f” Sound id={sound.context.id!r} {sound.waveform.shape} @ {sound.context.sample_rate} Hz” f” -> {sound.size_bytes:,} bytes”) embedding = types.SoundEmbedding( embedding=np.zeros((1, 16), dtype=np.float32), # (N, D): one utterance-level vector timestamps=np.array([[0.0, 1.0]], dtype=np.float32), # (M, 2): [start, end] in seconds context=sound.context, encoding_stats=types.EncodingStats(input_size_bytes=sound.size_bytes, embedding_size_bytes=16 * 4), ) print(f” SoundEmbedding embedding{embedding.embedding.shape} timestamps{embedding.timestamps.shape}” f” -> {embedding.size_bytes} bytes”) print(f” compression_ratio = {embedding.encoding_stats.compression_ratio:.5f}” f” ({1 / embedding.encoding_stats.compression_ratio:,.0f}x smaller than the audio)”) print(” N embeddings and M timestamps: M == N is frame-aligned, M == 1 is utterance-level.”) print(” `embedding` may also hold N strings instead of vectors – step 8 uses exactly that.”) score = types.Score(metric=”Accuracy”, description=”Overall classification accuracy”, value=0.875, min=0.0, max=1.0) print(f”n Score {score.metric}={score.value} in [{score.min}, {score.max}] :: {score.description}”) for bad, why in [(dict(metric=””, description=”d”, value=0.5, min=0.0, max=1.0), “empty metric name”), (dict(metric=”m”, description=”d”, value=0.5, min=1.0, max=0.0), “min > max”)]: try: types.Score(**bad) except Exception as e: print(f” rejected at construction ({why}): {type(e).__name__}: {e}”) return f”Sound {sound.size_bytes:,} B -> embedding {embedding.size_bytes} B” type_contract() We start with the type contract, because every other layer is expressed in it. A Sound carries a waveform, along with SoundContextParams, the identifier, sample rate, length, language, and optional transcript, which follow the audio through the whole pipeline. A SoundEmbedding carries an array of N embeddings and an array of M timestamp pairs, and the relation between N and M is the benchmark’s vocabulary: M equal to N means one vector per frame, while M equal to one means a single utterance-level vector, which is what our encoders produce. EncodingStats records the input and embedding sizes and exposes compression_ratio, here a thousandfold reduction from audio to vector. A Score is a metric name, a value and its bounds, and it validates itself at construction, rejecting an empty metric name or a minimum above its maximum, so a malformed number cannot reach a leaderboard. The embedding field also accepts N strings instead of N vectors, which is the door that step 8 walks through. Copy CodeCopiedUse a different Browser class EnergyEnvelopeEncoder(encoder_lib.MultiModalEncoder): “””Baseline: average energy in `n_bins` equal time slices. Loud/quiet, nothing about timbre.””” def __init__(self, n_bins: int = 16): super().__init__() self.n_bins = n_bins def _setup(self): self._ready = True # a real encoder loads weights here def _check_input_types(self, batch): for item in batch: if not isinstance(item, types.Sound): raise ValueError(f”{type(self).__name__} takes types.Sound, got {type(item).__name__}”) def _encode(self, batch) -> list[types.SoundEmbedding]: out = [] for sound in batch: slices = np.array_split(sound.waveform.astype(np.float32), self.n_bins) vec = np.array([[float(np.sqrt(np.mean(s ** 2) + 1e-12)) for s in slices]], dtype=np.float32) vec /= np.linalg.norm(vec) + 1e-9 out.append(types.SoundEmbedding( embedding=vec, timestamps=np.array([[0.0, sound.context.length / sound.context.sample_rate]], dtype=np.float32), context=sound.context)) return out class SpectralProfileEncoder(encoder_lib.MultiModalEncoder): “””Contender: mean log-magnitude spectrum pooled into `n_bands` bands. Describes timbre.””” def __init__(self, n_bands: int = 16, frame: int = 512): super().__init__() self.n_bands, self.frame = n_bands, frame def _setup(self): self._window = np.hanning(self.frame).astype(np.float32) def _check_input_types(self, batch): for item in batch: if not isinstance(item, types.Sound): raise ValueError(f”{type(self).__name__} takes types.Sound, got {type(item).__name__}”) def _encode(self, batch) -> list[types.SoundEmbedding]: out = [] for sound in batch: w = sound.waveform.astype(np.float32) n_frames =

A Coding Guide to Google Research’s MSEB: Writing Sound Encoders to the Benchmark Contract and Scoring Them Across Classification, Clustering, Retrieval and Segmentation Read Post »

We use cookies to improve your experience and performance on our website. You can learn more at Privacy Policy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
en_US