YouZum

Committee

AI, Committee, ニュース, Uncategorized

Evaluating Autoformalization Robustness via Semantically Similar Paraphrasing

arXiv:2511.12784v1 Announce Type: new Abstract: Large Language Models (LLMs) have recently emerged as powerful tools for autoformalization. Despite their impressive performance, these models can still struggle to produce grounded and verifiable formalizations. Recent work in text-to-SQL, has revealed that LLMs can be sensitive to paraphrased natural language (NL) inputs, even when high degrees of semantic fidelity are preserved (Safarzadeh, Oroojlooyjadid, and Roth 2025). In this paper, we investigate this claim in the autoformalization domain. Specifically, we evaluate the robustness of LLMs generating formal proofs with semantically similar paraphrased NL statements by measuring semantic and compilation validity. Using the formal benchmarks MiniF2F (Zheng, Han, and Polu 2021) and Lean 4 version of ProofNet (Xin et al. 2024), and two modern LLMs, we generate paraphrased natural language statements and cross-evaluate these statements across both models. The results of this paper reveal performance variability across paraphrased inputs, demonstrating that minor shifts in NL statements can significantly impact model outputs.

Evaluating Autoformalization Robustness via Semantically Similar Paraphrasing 投稿を読む »

AI, Committee, ニュース, Uncategorized

Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly?

arXiv:2511.13646v1 Announce Type: cross Abstract: Large Language Models (LLMs) are reshaping almost all industries, including software engineering. In recent years, a number of LLM agents have been proposed to solve real-world software problems. Such software agents are typically equipped with a suite of coding tools and can autonomously decide the next actions to form complete trajectories to solve end-to-end software tasks. While promising, they typically require dedicated design and may still be suboptimal, since it can be extremely challenging and costly to exhaust the entire agent scaffold design space. Recognizing that software agents are inherently software themselves that can be further refined/modified, researchers have proposed a number of self-improving software agents recently, including the Darwin-G”odel Machine (DGM). Meanwhile, such self-improving agents require costly offline training on specific benchmarks and may not generalize well across different LLMs or benchmarks. In this paper, we propose Live-SWE-agent, the first live software agent that can autonomously and continuously evolve itself on-the-fly during runtime when solving real-world software problems. More specifically, Live-SWE-agent starts with the most basic agent scaffold with only access to bash tools (e.g., mini-SWE-agent), and autonomously evolves its own scaffold implementation while solving real-world software problems. Our evaluation on the widely studied SWE-bench Verified benchmark shows that Live-SWE-agent can achieve an impressive solve rate of 75.4% without test-time scaling, outperforming all existing open-source software agents and approaching the performance of the best proprietary solution. Moreover, Live-SWE-agent outperforms state-of-the-art manually crafted software agents on the recent SWE-Bench Pro benchmark, achieving the best-known solve rate of 45.8%.

Live-SWE-agent: Can Software Engineering Agents Self-Evolve on the Fly? 投稿を読む »

AI, Committee, ニュース, Uncategorized

Uni-MoE-2.0-Omni: An Open Qwen2.5-7B Based Omnimodal MoE for Text, Image, Audio and Video Understanding

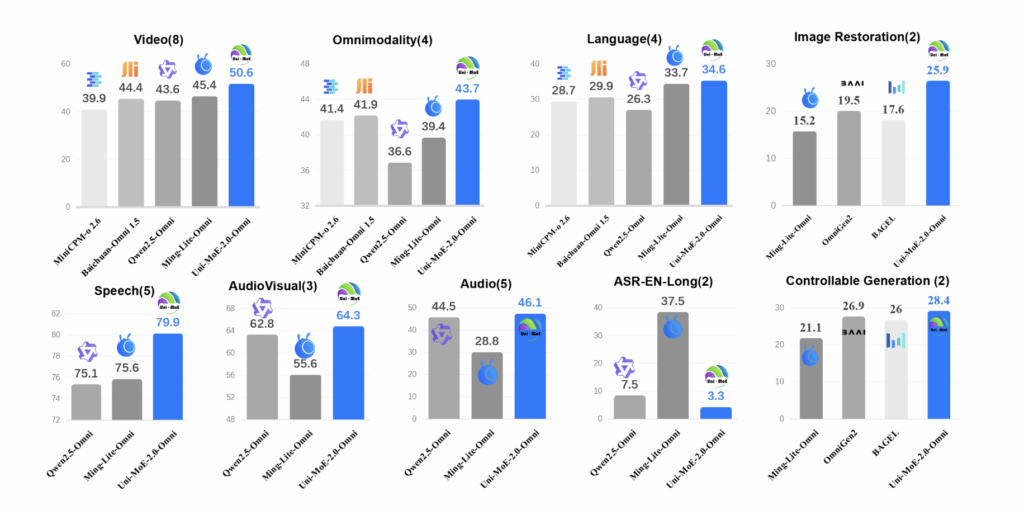
How do you build one open model that can reliably understand text, images, audio and video while still running efficiently? A team of researchers from Harbin Institute of Technology, Shenzhen introduced Uni-MoE-2.0-Omni, a fully open omnimodal large model that pushes Lychee’s Uni-MoE line toward language centric multimodal reasoning. The system is trained from scratch on a Qwen2.5-7B dense backbone and extended into a Mixture of Experts architecture with dynamic capacity routing, a progressive supervised and reinforcement learning recipe, and about 75B tokens of carefully matched multimodal data. It handles text, images, audio and video for understanding and can generate images, text and speech. https://idealistxy.github.io/Uni-MoE-v2.github.io/ Architecture, unified modality encoding around a language core The core of Uni-MoE-2.0-Omni is a Qwen2.5-7B style transformer that serves as a language centric hub. Around this hub, the research team attach a unified speech encoder that maps diverse audio, including environmental sound, speech and music, into a common representation space. On the vision side, pre-trained visual encoders process images and video frames, then feed token sequences into the same transformer. For generation, a context aware MoE based TTS module and a task aware diffusion transformer handle speech and image synthesis. https://idealistxy.github.io/Uni-MoE-v2.github.io/ All modalities are converted into token sequences that share a unified interface to the language model. This design means the same self attention layers see text, vision and audio tokens, which simplifies cross modal fusion and makes the language model the central controller for both understanding and generation. The architecture is designed to support 10 cross modal input configurations, such as image plus text, video plus speech and tri modal combinations. Omni Modality 3D RoPE and MoE driven fusion Cross modal alignment is handled by an Omni Modality 3D RoPE mechanism that encodes temporal and spatial structure directly into the rotary positional embeddings. Instead of only using one dimensional positions for text, the system assigns three coordinates to tokens, time, height and width for visual and audio streams, and time for speech. This gives the transformer an explicit view of when and where each token occurs, which is important for video understanding and audio visual reasoning tasks. The Mixture of Experts layers replace standard MLP blocks with an MoE stack that has three expert types. Empty experts act as null functions that allow computation skipping at inference time. Routed experts are modality specific and store domain knowledge for audio, vision or text. Shared experts are small and always active, providing a communication path for general information across modalities. A routing network chooses which experts to activate based on the input token, giving specialization without paying the full cost of a dense model with all experts active. Training recipe, from cross modal pretraining to GSPO DPO The training pipeline is organised into a data matched recipe. First, a language centric cross modal pretraining phase uses paired image text, audio text and video text corpora. This step teaches the model to project each modality into a shared semantic space aligned with language. The base model is trained on around 75B open source multimodal tokens and is equipped with special speech and image generation tokens so that generative behaviour can be learned by conditioning on linguistic cues. Next, a progressive supervised fine tuning stage activates modality specific experts grouped into audio, vision and text categories. During this stage, the research team introduce special control tokens so that the model can perform tasks like text conditioned speech synthesis and image generation inside the same language interface. After large scale SFT (Supervised Fine-Tuning), a data balanced annealing phase re-weights the mixture of datasets across modalities and tasks and trains with a lower learning rate. This avoids over fitting to a single modality and improves stability of the final omnimodal behaviour. To unlock long form reasoning, Uni-MoE-2.0-Omni adds an iterative policy optimisation stage built on GSPO and DPO. GSPO uses the model itself or another LLM as a judge to evaluate responses and construct preference signals, while DPO converts these preferences into a direct policy update objective that is more stable than standard reinforcement learning from human feedback. The research team apply this GSPO DPO loop in multiple rounds to form the Uni-MoE-2.0-Thinking variant, which inherits the omnimodal base and adds stronger step by step reasoning. Generation, MoE TTS and task aware diffusion For speech generation, Uni-MoE-2.0-Omni uses a context aware MoE TTS module that sits on top of the language model. The LLM emits control tokens that describe timbre, style and language, along with the text content. The MoE TTS consumes this sequence and produces discrete audio tokens, which are then decoded into waveforms by an external codec model, aligning with the unified speech encoder on the input side. This design makes speech generation a first class controlled generation task instead of a separate pipeline. On the vision side, a task aware diffusion transformer is conditioned on both task tokens and image tokens. Task tokens encode whether the system should perform text to image generation, editing or low level enhancement. Image tokens can capture semantics from the omnimodal backbone, for example from a text plus image dialogue. Lightweight projectors map these tokens into the diffusion transformer conditioning space, enabling instruction guided image generation and editing, while keeping the main omnimodal model frozen during the final visual fine tuning stage. Benchmarks and open checkpoints Uni-MoE-2.0-Omni is evaluated on 85 multimodal benchmarks that cover image, text, video, audio and cross or tri modal reasoning. The model surpasses Qwen2.5-Omni, which is trained on about 1.2T tokens, on more than 50 of 76 shared benchmarks. Gains include about +7% average on video understanding across 8 tasks, +7% average on omnimodality understanding across 4 benchmarks including OmniVideoBench and WorldSense, and about +4% on audio visual reasoning. For long form speech processing, Uni-MoE-2.0-Omni reduces word error rate by up to 4.2% relative on long LibriSpeech splits and brings about 1% WER improvement on TinyStories-en text to speech. Image generation and editing results are competitive with specialised visual models. The research team reports a small but

Uni-MoE-2.0-Omni: An Open Qwen2.5-7B Based Omnimodal MoE for Text, Image, Audio and Video Understanding 投稿を読む »

AI, Committee, ニュース, Uncategorized

NOVA: An Agentic Framework for Automated Histopathology Analysis and Discovery

arXiv:2511.11324v1 Announce Type: new Abstract: Digitized histopathology analysis involves complex, time-intensive workflows and specialized expertise, limiting its accessibility. We introduce NOVA, an agentic framework that translates scientific queries into executable analysis pipelines by iteratively generating and running Python code. NOVA integrates 49 domain-specific tools (e.g., nuclei segmentation, whole-slide encoding) built on open-source software, and can also create new tools ad hoc. To evaluate such systems, we present SlideQuest, a 90-question benchmark — verified by pathologists and biomedical scientists — spanning data processing, quantitative analysis, and hypothesis testing. Unlike prior biomedical benchmarks focused on knowledge recall or diagnostic QA, SlideQuest demands multi-step reasoning, iterative coding, and computational problem solving. Quantitative evaluation shows NOVA outperforms coding-agent baselines, and a pathologist-verified case study links morphology to prognostically relevant PAM50 subtypes, demonstrating its scalable discovery potential.

NOVA: An Agentic Framework for Automated Histopathology Analysis and Discovery 投稿を読む »

AI, Committee, ニュース, Uncategorized

Computational Analysis of Gender Depiction in the Comedias of Calder’on de la Barca

arXiv:2411.03895v2 Announce Type: replace Abstract: In theatre, playwrights use the portrayal of characters to explore culturally based gender norms. In this paper, we develop quantitative methods to study gender depiction in the non-religious works (comedias) of Pedro Calder’on de la Barca, a prolific Spanish 17th century author. We gather insights from a corpus of more than 100 plays by using a gender classifier and applying model explainability (attribution) methods to determine which text features are most influential in the model’s decision to classify speech as ‘male’ or ‘female’, indicating the most gendered elements of dialogue in Calder’on’s comedias in a human accessible manner. We find that female and male characters are portrayed differently and can be identified by the gender prediction model at practically useful accuracies (up to f=0.83). Analysis reveals semantic aspects of gender portrayal, and demonstrates that the model is even useful in providing a relatively accurate scene-by-scene prediction of cross-dressing characters.

Computational Analysis of Gender Depiction in the Comedias of Calder’on de la Barca 投稿を読む »

AI, Committee, ニュース, Uncategorized

Reinforcing Stereotypes of Anger: Emotion AI on African American Vernacular English

arXiv:2511.10846v1 Announce Type: new Abstract: Automated emotion detection is widely used in applications ranging from well-being monitoring to high-stakes domains like mental health and hiring. However, models often rely on annotations that reflect dominant cultural norms, limiting model ability to recognize emotional expression in dialects often excluded from training data distributions, such as African American Vernacular English (AAVE). This study examines emotion recognition model performance on AAVE compared to General American English (GAE). We analyze 2.7 million tweets geo-tagged within Los Angeles. Texts are scored for strength of AAVE using computational approximations of dialect features. Annotations of emotion presence and intensity are collected on a dataset of 875 tweets with both high and low AAVE densities. To assess model accuracy on a task as subjective as emotion perception, we calculate community-informed “silver” labels where AAVE-dense tweets are labeled by African American, AAVE-fluent (ingroup) annotators. On our labeled sample, GPT and BERT-based models exhibit false positive prediction rates of anger on AAVE more than double than on GAE. SpanEmo, a popular text-based emotion model, increases false positive rates of anger from 25 percent on GAE to 60 percent on AAVE. Additionally, a series of linear regressions reveals that models and non-ingroup annotations are significantly more correlated with profanity-based AAVE features than ingroup annotations. Linking Census tract demographics, we observe that neighborhoods with higher proportions of African American residents are associated with higher predictions of anger (Pearson’s correlation r = 0.27) and lower joy (r = -0.10). These results find an emergent safety issue of emotion AI reinforcing racial stereotypes through biased emotion classification. We emphasize the need for culturally and dialect-informed affective computing systems.

Reinforcing Stereotypes of Anger: Emotion AI on African American Vernacular English 投稿を読む »

AI, Committee, ニュース, Uncategorized

A methodological analysis of prompt perturbations and their effect on attack success rates

arXiv:2511.10686v1 Announce Type: new Abstract: This work aims to investigate how different Large Language Models (LLMs) alignment methods affect the models’ responses to prompt attacks. We selected open source models based on the most common alignment methods, namely, Supervised Fine-Tuning (SFT), Direct Preference Optimization (DPO), and Reinforcement Learning with Human Feedback (RLHF). We conducted a systematic analysis using statistical methods to verify how sensitive the Attack Success Rate (ASR) is when we apply variations to prompts designed to elicit inappropriate content from LLMs. Our results show that even small prompt modifications can significantly change the Attack Success Rate (ASR) according to the statistical tests we run, making the models more or less susceptible to types of attack. Critically, our results demonstrate that running existing ‘attack benchmarks’ alone may not be sufficient to elicit all possible vulnerabilities of both models and alignment methods. This paper thus contributes to ongoing efforts on model attack evaluation by means of systematic and statistically-based analyses of the different alignment methods and how sensitive their ASR is to prompt variation.

A methodological analysis of prompt perturbations and their effect on attack success rates 投稿を読む »

AI, Committee, ニュース, Uncategorized

Modeling and Predicting Multi-Turn Answer Instability in Large Language Models

arXiv:2511.10688v1 Announce Type: new Abstract: As large language models (LLMs) are adopted in an increasingly wide range of applications, user-model interactions have grown in both frequency and scale. Consequently, research has focused on evaluating the robustness of LLMs, an essential quality for real-world tasks. In this paper, we employ simple multi-turn follow-up prompts to evaluate models’ answer changes, model accuracy dynamics across turns with Markov chains, and examine whether linear probes can predict these changes. Our results show significant vulnerabilities in LLM robustness: a simple “Think again” prompt led to an approximate 10% accuracy drop for Gemini 1.5 Flash over nine turns, while combining this prompt with a semantically equivalent reworded question caused a 7.5% drop for Claude 3.5 Haiku. Additionally, we find that model accuracy across turns can be effectively modeled using Markov chains, enabling the prediction of accuracy probabilities over time. This allows for estimation of the model’s stationary (long-run) accuracy, which we find to be on average approximately 8% lower than its first-turn accuracy for Gemini 1.5 Flash. Our results from a model’s hidden states also reveal evidence that linear probes can help predict future answer changes. Together, these results establish stationary accuracy as a principled robustness metric for interactive settings and expose the fragility of models under repeated questioning. Addressing this instability will be essential for deploying LLMs in high-stakes and interactive settings where consistent reasoning is as important as initial accuracy.

Modeling and Predicting Multi-Turn Answer Instability in Large Language Models 投稿を読む »

AI, Committee, ニュース, Uncategorized

How to Design a Fully Interactive, Reactive, and Dynamic Terminal-Based Data Dashboard Using Textual?

In this tutorial, we build an advanced interactive dashboard using Textual, and we explore how terminal-first UI frameworks can feel as expressive and dynamic as modern web dashboards. As we write and run each snippet, we actively construct the interface piece by piece, widgets, layouts, reactive state, and event flows, so we can see how Textual behaves like a live UI engine right inside Google Colab. By the end, we notice how naturally we can blend tables, trees, forms, and progress indicators into a cohesive application that feels fast, clean, and responsive. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser !pip install textual textual-web nest-asyncio from textual.app import App, ComposeResult from textual.containers import Container, Horizontal, Vertical from textual.widgets import ( Header, Footer, Button, DataTable, Static, Input, Label, ProgressBar, Tree, Select ) from textual.reactive import reactive from textual import on from datetime import datetime import random class StatsCard(Static): value = reactive(0) def __init__(self, title: str, *args, **kwargs): super().__init__(*args, **kwargs) self.title = title def compose(self) -> ComposeResult: yield Label(self.title) yield Label(str(self.value), id=”stat-value”) def watch_value(self, new_value: int) -> None: if self.is_mounted: try: self.query_one(“#stat-value”, Label).update(str(new_value)) except Exception: pass We set up the environment and import all the necessary components to build our Textual application. As we define the StatsCard widget, we establish a reusable component that reacts to changes in value and updates itself automatically. We begin to see how Textual’s reactive system lets us create dynamic UI elements with minimal effort. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser class DataDashboard(App): CSS = “”” Screen { background: $surface; } #main-container { height: 100%; padding: 1; } #stats-row { height: auto; margin-bottom: 1; } StatsCard { border: solid $primary; height: 5; padding: 1; margin-right: 1; width: 1fr; } #stat-value { text-style: bold; color: $accent; content-align: center middle; } #control-panel { height: 12; border: solid $secondary; padding: 1; margin-bottom: 1; } #data-section { height: 1fr; } #left-panel { width: 30; border: solid $secondary; padding: 1; margin-right: 1; } DataTable { height: 100%; border: solid $primary; } Input { margin: 1 0; } Button { margin: 1 1 1 0; } ProgressBar { margin: 1 0; } “”” BINDINGS = [ (“d”, “toggle_dark”, “Toggle Dark Mode”), (“q”, “quit”, “Quit”), (“a”, “add_row”, “Add Row”), (“c”, “clear_table”, “Clear Table”), ] total_rows = reactive(0) total_sales = reactive(0) avg_rating = reactive(0.0) We define the DataDashboard class and configure global styles, key bindings, and reactive attributes. We decide how the app should look and behave right from the top, giving us full control over themes and interactivity. This structure helps us create a polished dashboard without writing any HTML or JS. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser def compose(self) -> ComposeResult: yield Header(show_clock=True) with Container(id=”main-container”): with Horizontal(id=”stats-row”): yield StatsCard(“Total Rows”, id=”card-rows”) yield StatsCard(“Total Sales”, id=”card-sales”) yield StatsCard(“Avg Rating”, id=”card-rating”) with Vertical(id=”control-panel”): yield Input(placeholder=”Product Name”, id=”input-name”) yield Select( [(“Electronics”, “electronics”), (“Books”, “books”), (“Clothing”, “clothing”)], prompt=”Select Category”, id=”select-category” ) with Horizontal(): yield Button(“Add Row”, variant=”primary”, id=”btn-add”) yield Button(“Clear Table”, variant=”warning”, id=”btn-clear”) yield Button(“Generate Data”, variant=”success”, id=”btn-generate”) yield ProgressBar(total=100, id=”progress”) with Horizontal(id=”data-section”): with Container(id=”left-panel”): yield Label(“Navigation”) tree = Tree(“Dashboard”) tree.root.expand() products = tree.root.add(“Products”, expand=True) products.add_leaf(“Electronics”) products.add_leaf(“Books”) products.add_leaf(“Clothing”) tree.root.add_leaf(“Reports”) tree.root.add_leaf(“Settings”) yield tree yield DataTable(id=”data-table”) yield Footer() We compose the entire UI layout, arranging containers, cards, form inputs, buttons, a navigation tree, and a data table. As we structure these components, we watch the interface take shape exactly the way we envision it. This snippet lets us design the visual skeleton of the dashboard in a clean, declarative manner. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser def on_mount(self) -> None: table = self.query_one(DataTable) table.add_columns(“ID”, “Product”, “Category”, “Price”, “Sales”, “Rating”) table.cursor_type = “row” self.generate_sample_data(5) self.set_interval(0.1, self.update_progress) def generate_sample_data(self, count: int = 5) -> None: table = self.query_one(DataTable) categories = [“Electronics”, “Books”, “Clothing”] products = { “Electronics”: [“Laptop”, “Phone”, “Tablet”, “Headphones”], “Books”: [“Novel”, “Textbook”, “Magazine”, “Comic”], “Clothing”: [“Shirt”, “Pants”, “Jacket”, “Shoes”] } for _ in range(count): category = random.choice(categories) product = random.choice(products[category]) row_id = self.total_rows + 1 price = round(random.uniform(10, 500), 2) sales = random.randint(1, 100) rating = round(random.uniform(1, 5), 1) table.add_row( str(row_id), product, category, f”${price}”, str(sales), str(rating) ) self.total_rows += 1 self.total_sales += sales self.update_stats() def update_stats(self) -> None: self.query_one(“#card-rows”, StatsCard).value = self.total_rows self.query_one(“#card-sales”, StatsCard).value = self.total_sales if self.total_rows > 0: table = self.query_one(DataTable) total_rating = sum(float(row[5]) for row in table.rows) self.avg_rating = round(total_rating / self.total_rows, 2) self.query_one(“#card-rating”, StatsCard).value = self.avg_rating def update_progress(self) -> None: progress = self.query_one(ProgressBar) progress.advance(1) if progress.progress >= 100: progress.progress = 0 We implement all the logic for generating data, computing statistics, animating progress, and updating cards. We see how quickly we can bind backend logic to frontend components using Textual’s reactive model. This step makes the dashboard feel alive as numbers update instantly and progress bars animate smoothly. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser @on(Button.Pressed, “#btn-add”) def handle_add_button(self) -> None: name_input = self.query_one(“#input-name”, Input) category = self.query_one(“#select-category”, Select).value if name_input.value and category: table = self.query_one(DataTable) row_id = self.total_rows + 1 price = round(random.uniform(10, 500), 2) sales = random.randint(1, 100) rating = round(random.uniform(1, 5), 1) table.add_row( str(row_id), name_input.value, str(category), f”${price}”, str(sales), str(rating) ) self.total_rows += 1 self.total_sales += sales self.update_stats() name_input.value = “” @on(Button.Pressed, “#btn-clear”) def handle_clear_button(self) -> None: table = self.query_one(DataTable) table.clear() self.total_rows = 0 self.total_sales = 0 self.avg_rating = 0 self.update_stats() @on(Button.Pressed, “#btn-generate”) def handle_generate_button(self) -> None: self.generate_sample_data(10) def action_toggle_dark(self) -> None: self.dark = not self.dark def action_add_row(self) -> None: self.handle_add_button() def action_clear_table(self) -> None: self.handle_clear_button() if __name__ == “__main__”: import nest_asyncio nest_asyncio.apply() app = DataDashboard() app.run() We connect UI events to backend actions using button handlers, keyboard shortcuts, and app-level functions. As we run the app, we interact with a fully functional dashboard that responds instantly to every click and command. This snippet completes the application and demonstrates how easily Textual enables us to build dynamic, state-driven UIs. In conclusion, we see the whole dashboard come together in a fully functional, interactive form that runs directly from a notebook environment. We experience firsthand how Textual lets us design terminal UIs with the structure and

How to Design a Fully Interactive, Reactive, and Dynamic Terminal-Based Data Dashboard Using Textual? 投稿を読む »

AI, Committee, ニュース, Uncategorized

MBZUAI Researchers Introduce PAN: A General World Model For Interactable Long Horizon Simulation

Most text to video models generate a single clip from a prompt and then stop. They do not keep an internal world state that persists as actions arrive over time. PAN, a new model from MBZUAI’s Institute of Foundation Models, is designed to fill that gap by acting as a general world model that predicts future world states as video, conditioned on history and natural language actions. https://arxiv.org/pdf/2511.09057 From video generator to interactive world simulator PAN is defined as a general, interactable, long horizon world model. It maintains an internal latent state that represents the current world, then updates that state when it receives a natural language action such as ‘turn left and speed up’ or ‘move the robot arm to the red block.’ The model then decodes the updated state into a short video segment that shows the consequence of that action. This cycle repeats, so the same world state evolves across many steps. This design allows PAN to support open domain, action conditioned simulation. It can roll out counterfactual futures for different action sequences. An external agent can query PAN as a simulator, compare predicted futures, and choose actions based on those predictions. GLP architecture, separating what happens from how it looks The base of PAN is the Generative Latent Prediction, GLP, architecture. GLP separates world dynamics from visual rendering. First, a vision encoder maps images or video frames into a latent world state. Second, an autoregressive latent dynamics backbone based on a large language model predicts the next latent state, conditioned on history and the current action. Third, a video diffusion decoder reconstructs the corresponding video segment from that latent state. In PAN, the vision encoder and backbone are built on Qwen2.5-VL-7B-Instruct. The vision tower tokenizes frames into patches and produces structured embeddings. The language backbone runs over a history of world states and actions, plus learned query tokens, and outputs the latent representation of the next world state. These latents live in the shared multimodal space of the VLM, which helps ground the dynamics in both text and vision. The video diffusion decoder is adapted from Wan2.1-T2V-14B, a diffusion transformer for high fidelity video generation. The research team trains this decoder with a flow matching objective, using one thousand denoising steps and a Rectified Flow formulation. The decoder conditions on both the predicted latent world state and the current natural language action, with a dedicated cross attention stream for the world state and another for the action text. https://arxiv.org/pdf/2511.09057 Causal Swin DPM and sliding window diffusion Naively chaining single shot video models by conditioning only on the last frame leads to local discontinuities and rapid quality degradation over long rollouts. PAN addresses this with Causal Swin DPM, which augments the Shift Window Denoising Process Model with chunk wise causal attention. The decoder operates on a sliding temporal window that holds two chunks of video frames at different noise levels. During denoising, one chunk moves from high noise to clean frames and then leaves the window. A new noisy chunk enters at the other end. Chunk wise causal attention ensures that the later chunk can only attend to the earlier one, not to unseen future actions. This keeps transitions between chunks smooth and reduces error accumulation over long horizons. PAN also adds controlled noise to the conditioning frame, rather than using a perfectly sharp frame. This suppresses incidental pixel details that do not matter for dynamics and encourages the model to focus on stable structure such as objects and layout. https://arxiv.org/pdf/2511.09057 Training stack and data construction PAN is trained in two stages. In the first stage, the research team adapts Wan2.1 T2V 14B into the Causal Swin DPM architecture. They train the decoder in BFloat16 with AdamW, a cosine schedule, gradient clipping, FlashAttention3 and FlexAttention kernels, and a hybrid sharded data parallel scheme across 960 NVIDIA H200 GPUs. In the second stage, they integrate the frozen Qwen2.5 VL 7B Instruct backbone with the video diffusion decoder under the GLP objective. The vision language model remains frozen. The model learns query embeddings and the decoder so that predicted latents and reconstructed videos stay consistent. This joint training also uses sequence parallelism and Ulysses style attention sharding to handle long context sequences. Early stopping ends training after 1 epoch once validation converges, even though the schedule allows 5 epochs. Training data comes from widely used publicly accessible video sources that cover everyday activities, human object interactions, natural environments, and multi agent scenarios. Long form videos are segmented into coherent clips using shot boundary detection. A filtering pipeline removes static or overly dynamic clips, low aesthetic quality, heavy text overlays, and screen recordings using rule based metrics, pretrained detectors, and a custom VLM filter. The research team then re-captions clips with dense, temporally grounded descriptions that emphasize motion and causal events. Benchmarks, action fidelity, long horizon stability, planning The research team evaluates the model along three axes, action simulation fidelity, long horizon forecast, and simulative reasoning and planning, against both open source and commercial video generators and world models. Baselines include WAN 2.1 and 2.2, Cosmos 1 and 2, V JEPA 2, and commercial systems such as KLING, MiniMax Hailuo, and Gen 3. For action simulation fidelity, a VLM based judge scores how well the model executes language specified actions while maintaining a stable background. PAN reaches 70.3% accuracy on agent simulation and 47% on environment simulation, for an overall score of 58.6%. It achieves the highest fidelity among open source models and surpasses most commercial baselines. For long horizon forecast, the research team measures Transition Smoothness and Simulation Consistency. Transition Smoothness uses optical flow acceleration to quantify how smooth motion is across action boundaries. Simulation Consistency uses metrics inspired by WorldScore to monitor degradation over extended sequences. PAN scores 53.6% on Transition Smoothness and 64.1% on Simulation Consistency and exceeds all baselines, including KLING and MiniMax, on these metrics. For simulative reasoning and planning, PAN is used as an internal simulator inside an OpenAI-o3 based agent loop. In

MBZUAI Researchers Introduce PAN: A General World Model For Interactable Long Horizon Simulation 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja