YouZum

Committee

AI, Committee, ニュース, Uncategorized

Safely Deploying ML Models to Production: Four Controlled Strategies (A/B, Canary, Interleaved, Shadow Testing)

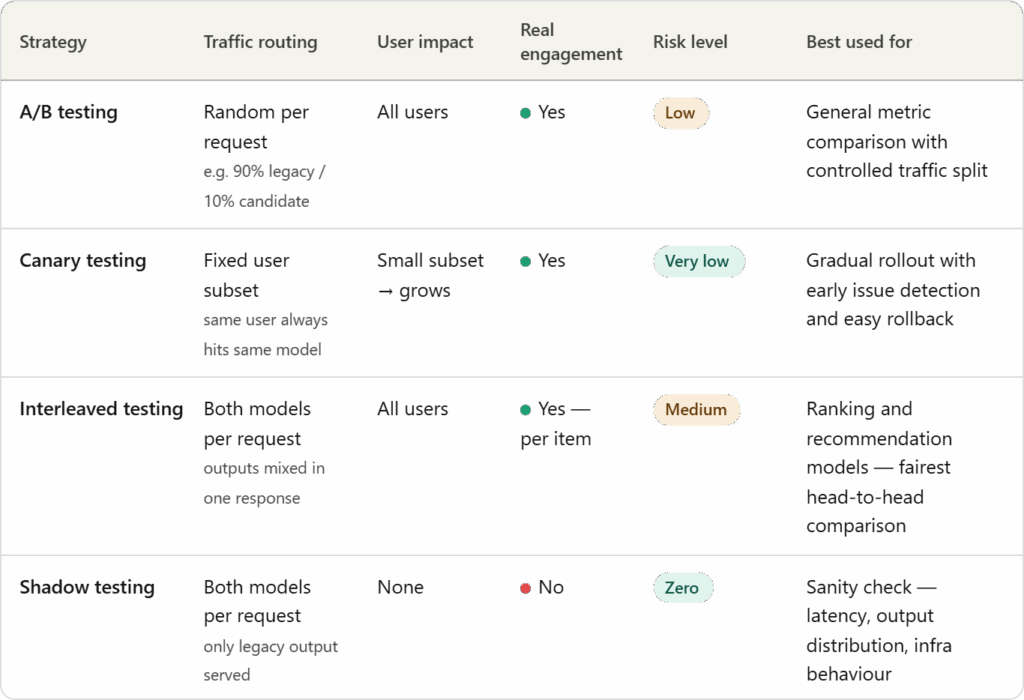
Deploying a new machine learning model to production is one of the most critical stages of the ML lifecycle. Even if a model performs well on validation and test datasets, directly replacing the existing production model can be risky. Offline evaluation rarely captures the full complexity of real-world environments—data distributions may shift, user behavior can change, and system constraints in production may differ from those in controlled experiments.  As a result, a model that appears superior during development might still degrade performance or negatively impact user experience once deployed. To mitigate these risks, ML teams adopt controlled rollout strategies that allow them to evaluate new models under real production conditions while minimizing potential disruptions.  In this article, we explore four widely used strategies—A/B testing, Canary testing, Interleaved testing, and Shadow testing—that help organizations safely deploy and validate new machine learning models in production environments. A/B Testing A/B testing is one of the most widely used strategies for safely introducing a new machine learning model in production. In this approach, incoming traffic is split between two versions of a system: the existing legacy model (control) and the candidate model (variation). The distribution is typically non-uniform to limit risk—for example, 90% of requests may continue to be served by the legacy model, while only 10% are routed to the candidate model.  By exposing both models to real-world traffic, teams can compare downstream performance metrics such as click-through rate, conversions, engagement, or revenue. This controlled experiment allows organizations to evaluate whether the candidate model genuinely improves outcomes before gradually increasing its traffic share or fully replacing the legacy model. Canary Testing Canary testing is a controlled rollout strategy where a new model is first deployed to a small subset of users before being gradually released to the entire user base. The name comes from an old mining practice where miners carried canary birds into coal mines to detect toxic gases—the birds would react first, warning miners of danger. Similarly, in machine learning deployments, the candidate model is initially exposed to a limited group of users while the majority continue to be served by the legacy model.  Unlike A/B testing, which randomly splits traffic across all users, canary testing targets a specific subset and progressively increases exposure if performance metrics indicate success. This gradual rollout helps teams detect issues early and roll back quickly if necessary, reducing the risk of widespread impact. Interleaved Testing Interleaved testing evaluates multiple models by mixing their outputs within the same response shown to users. Instead of routing an entire request to either the legacy or candidate model, the system combines predictions from both models in real time. For example, in a recommendation system, some items in the recommendation list may come from the legacy model, while others are generated by the candidate model.  The system then logs downstream engagement signals—such as click-through rate, watch time, or negative feedback—for each recommendation. Because both models are evaluated within the same user interaction, interleaved testing allows teams to compare performance more directly and efficiently while minimizing biases caused by differences in user groups or traffic distribution. Shadow Testing Shadow testing, also known as shadow deployment or dark launch, allows teams to evaluate a new machine learning model in a real production environment without affecting the user experience. In this approach, the candidate model runs in parallel with the legacy model and receives the same live requests as the production system. However, only the legacy model’s predictions are returned to users, while the candidate model’s outputs are simply logged for analysis.  This setup helps teams assess how the new model behaves under real-world traffic and infrastructure conditions, which are often difficult to replicate in offline experiments. Shadow testing provides a low-risk way to benchmark the candidate model against the legacy model, although it cannot capture true user engagement metrics—such as clicks, watch time, or conversions—since its predictions are never shown to users. Simulating ML Model Deployment Strategies Setting Up Before simulating any strategy, we need two things: a way to represent incoming requests, and a stand-in for each model. Each model is simply a function that takes a request and returns a score — a number that loosely represents how good that model’s recommendation is. The legacy model’s score is capped at 0.35, while the candidate model’s is capped at 0.55, making the candidate intentionally better so we can verify that each strategy actually detects the improvement. make_requests() generates 200 requests spread across 40 users, which gives us enough traffic to see meaningful differences between strategies while keeping the simulation lightweight. Copy CodeCopiedUse a different Browser import random import hashlib random.seed(42) def legacy_model(request): return {“model”: “legacy”, “score”: random.random() * 0.35} def candidate_model(request): return {“model”: “candidate”, “score”: random.random() * 0.55} def make_requests(n=200): users = [f”user_{i}” for i in range(40)] return [{“id”: f”req_{i}”, “user”: random.choice(users)} for i in range(n)] requests = make_requests() A/B Testing ab_route() is the core of this strategy — for every incoming request, it draws a random number and routes to the candidate model only if that number falls below 0.10, otherwise the request goes to legacy. This gives the candidate roughly 10% of traffic. We then collect the prediction scores from each model separately and compute the average at the end. In a real system, these scores would be replaced by actual engagement metrics like click-through rate or watch time — here the score just stands in for “how good was this recommendation.” Copy CodeCopiedUse a different Browser print(“── 1. A/B Testing ──────────────────────────────────────────”) CANDIDATE_TRAFFIC = 0.10 # 10 % of requests go to candidate def ab_route(request): return candidate_model if random.random() < CANDIDATE_TRAFFIC else legacy_model results = {“legacy”: [], “candidate”: []} for req in requests: model = ab_route(req) pred = model(req) results[pred[“model”]].append(pred[“score”]) for name, scores in results.items(): print(f” {name:12s} | requests: {len(scores):3d} | avg score: {sum(scores)/len(scores):.3f}”) Canary Testing The key function here is get_canary_users(), which uses an MD5 hash to deterministically assign users to the canary group. The important word is deterministic — sorting users by their hash means the
Safely Deploying ML Models to Production: Four Controlled Strategies (A/B, Canary, Interleaved, Shadow Testing) 投稿を読む »

AI, Committee, ニュース, Uncategorized

A Coding Implementation for Building and Analyzing Crystal Structures Using Pymatgen for Symmetry Analysis, Phase Diagrams, Surface Generation, and Materials Project Integration

In this tutorial, we explore the capabilities of the pymatgen library for computational materials science using Python. We begin by constructing crystal structures such as silicon, sodium chloride, and a LiFePO₄-like material, and then investigate their lattice properties, densities, and compositions. Also, we analyze symmetry using space-group detection, examine atomic coordination environments, and apply oxidation-state decorations to better understand the structures’ chemistry. We also generate supercells, perturb atomic positions, and compute distance matrices to study structural relationships at larger scales. Along the way, we simulate X-ray diffraction patterns, construct a simple phase diagram, and demonstrate how disordered alloy structures can be approximated by ordered configurations. Finally, we extend the workflow to include molecule analysis, CIF export, and optional querying of the Materials Project database, thereby illustrating how pymatgen can serve as a powerful toolkit for materials modeling and data analysis. Copy CodeCopiedUse a different Browser !pip -q install pymatgen mp-api spglib import os import json import warnings import sys warnings.filterwarnings(“ignore”) import numpy as np import pandas as pd import matplotlib.pyplot as plt from pymatgen.core import Lattice, Structure, Molecule from pymatgen.core.surface import SlabGenerator from pymatgen.core.composition import Composition from pymatgen.symmetry.analyzer import SpacegroupAnalyzer from pymatgen.analysis.local_env import CrystalNN from pymatgen.analysis.diffraction.xrd import XRDCalculator from pymatgen.analysis.phase_diagram import PDEntry, PhaseDiagram from pymatgen.transformations.standard_transformations import ( SupercellTransformation, OrderDisorderedStructureTransformation, OxidationStateDecorationTransformation, ) from pymatgen.io.cif import CifWriter print(“Python:”, sys.version.split()[0]) print(“NumPy:”, np.__version__) print(“pandas:”, pd.__version__) try: import pymatgen print(“pymatgen:”, pymatgen.__version__) except Exception: import importlib.metadata print(“pymatgen:”, importlib.metadata.version(“pymatgen”)) def line(): print(“=” * 100) def header(title): line() print(title) line() header(“1. BUILD EXAMPLE STRUCTURES”) si = Structure( Lattice.cubic(5.431), [“Si”, “Si”], [[0, 0, 0], [0.25, 0.25, 0.25]], ) nacl = Structure( Lattice.cubic(5.64), [“Na”, “Cl”], [[0, 0, 0], [0.5, 0.5, 0.5]], ) li_fe_po4 = Structure( Lattice.orthorhombic(10.33, 6.01, 4.69), [“Li”, “Fe”, “P”, “O”, “O”, “O”, “O”], [ [0.0, 0.0, 0.0], [0.5, 0.5, 0.5], [0.1, 0.25, 0.2], [0.22, 0.04, 0.28], [0.72, 0.54, 0.78], [0.31, 0.66, 0.12], [0.81, 0.16, 0.62], ], ) for name, s in [(“Si”, si), (“NaCl”, nacl), (“LiFePO4-like”, li_fe_po4)]: print(f”{name}: formula={s.composition.formula}, sites={len(s)}, volume={s.volume:.3f} Å^3″) We begin by installing the required libraries. We initialize the environment, verify package versions, and define helper functions to organize the output. We then construct example crystal structures such as silicon, NaCl, and a LiFePO₄-like structure and print their basic structural properties. Copy CodeCopiedUse a different Browser header(“2. BASIC INTROSPECTION”) for name, s in [(“Si”, si), (“NaCl”, nacl), (“LiFePO4-like”, li_fe_po4)]: print(f”n{name}”) print(“Reduced formula:”, s.composition.reduced_formula) print(“Density:”, round(s.density, 4), “g/cm^3”) print(“Lattice parameters (a, b, c):”, tuple(round(x, 4) for x in s.lattice.abc)) print(“Angles (alpha, beta, gamma):”, tuple(round(x, 4) for x in s.lattice.angles)) print(“First site:”, s[0]) header(“3. SPACE GROUP AND SYMMETRY ANALYSIS”) for name, s in [(“Si”, si), (“NaCl”, nacl), (“LiFePO4-like”, li_fe_po4)]: sga = SpacegroupAnalyzer(s, symprec=0.1) print(f”n{name}”) print(“Space group symbol:”, sga.get_space_group_symbol()) print(“Space group number:”, sga.get_space_group_number()) print(“Crystal system:”, sga.get_crystal_system()) print(“Lattice type:”, sga.get_lattice_type()) print(“Primitive sites:”, len(sga.find_primitive())) print(“Conventional sites:”, len(sga.get_conventional_standard_structure())) We examine the structures in greater detail by inspecting their formulas, densities, lattice parameters, and site information. We then perform a symmetry analysis using SpacegroupAnalyzer to determine space-group symbols, crystal systems, and lattice types. Through this step, we gain insight into the crystallographic symmetry and structural characteristics of the materials. Copy CodeCopiedUse a different Browser header(“4. LOCAL ENVIRONMENT WITH CRYSTALNN”) cnn = CrystalNN() def summarize_neighbors(structure, label): print(f”n{label}”) for i, site in enumerate(structure[:min(4, len(structure))]): try: nn_info = cnn.get_nn_info(structure, i) species = [str(x[“site”].specie) for x in nn_info] weights = [round(float(x[“weight”]), 3) for x in nn_info] print(f”Site {i} {site.species_string}: CN={len(nn_info)}, neighbors={species}, weights={weights}”) except Exception as e: print(f”Site {i} {site.species_string}: neighbor analysis failed -> {e}”) summarize_neighbors(si, “Si”) summarize_neighbors(nacl, “NaCl”) header(“5. OXIDATION STATE DECORATION”) oxi_transform = OxidationStateDecorationTransformation( {“Li”: 1, “Fe”: 2, “P”: 5, “O”: -2, “Na”: 1, “Cl”: -1, “Si”: 0} ) nacl_oxi = oxi_transform.apply_transformation(nacl.copy()) lfp_oxi = oxi_transform.apply_transformation(li_fe_po4.copy()) print(“NaCl species with oxidation states:”, [str(site.specie) for site in nacl_oxi]) print(“LiFePO4-like species with oxidation states:”, [str(site.specie) for site in lfp_oxi]) We analyze the local atomic environments using the CrystalNN coordination analysis algorithm. We identify neighboring atoms for selected sites and evaluate their coordination numbers and weights. We then decorate the structures with oxidation states to better represent the chemical environment. Copy CodeCopiedUse a different Browser header(“6. MAKE SUPERCELLS”) si_super = SupercellTransformation([[2, 0, 0], [0, 2, 0], [0, 0, 2]]).apply_transformation(si.copy()) nacl_super = SupercellTransformation([[2, 0, 0], [0, 2, 0], [0, 0, 2]]).apply_transformation(nacl.copy()) print(“Si supercell sites:”, len(si_super), “formula:”, si_super.composition.formula) print(“NaCl supercell sites:”, len(nacl_super), “formula:”, nacl_super.composition.formula) header(“7. PERTURB STRUCTURE AND COMPUTE DISTANCE MATRIX”) si_perturbed = si_super.copy() si_perturbed.translate_sites([0], [0.01, -0.005, 0.012], frac_coords=False) dm = si_perturbed.distance_matrix print(“Distance matrix shape:”, dm.shape) print(“First 5 distances from site 0:”, np.round(dm[0][:5], 4)) header(“8. GENERATE A SURFACE SLAB”) slabgen = SlabGenerator( initial_structure=si, miller_index=(1, 1, 1), min_slab_size=8.0, min_vacuum_size=12.0, center_slab=True, in_unit_planes=False, ) slabs = slabgen.get_slabs() slab = slabs[0] print(“Number of generated slabs:”, len(slabs)) print(“Chosen slab formula:”, slab.composition.formula) print(“Chosen slab sites:”, len(slab)) print(“Chosen slab lattice:”, tuple(round(x, 3) for x in slab.lattice.abc)) We expand the crystal structures into larger supercells to study periodic structures at a larger scale. We apply a small perturbation to atomic positions and compute the resulting distance matrix to analyze structural changes. We also generate a surface slab from the silicon crystal to demonstrate how surface structures can be modeled. Copy CodeCopiedUse a different Browser header(“9. XRD SIMULATION”) xrd = XRDCalculator(wavelength=”CuKa”) pattern_si = xrd.get_pattern(si, two_theta_range=(10, 90)) pattern_nacl = xrd.get_pattern(nacl, two_theta_range=(10, 90)) plt.figure(figsize=(12, 4)) plt.vlines(pattern_si.x, [0], pattern_si.y, linewidth=1.5) plt.xlabel(r”2$theta$ (degrees)”) plt.ylabel(“Intensity”) plt.title(“Simulated XRD Pattern: Si”) plt.show() plt.figure(figsize=(12, 4)) plt.vlines(pattern_nacl.x, [0], pattern_nacl.y, linewidth=1.5) plt.xlabel(r”2$theta$ (degrees)”) plt.ylabel(“Intensity”) plt.title(“Simulated XRD Pattern: NaCl”) plt.show() header(“10. SIMPLE PHASE DIAGRAM”) entries = [ PDEntry(Composition(“Li”), 0.0), PDEntry(Composition(“Fe”), 0.0), PDEntry(Composition(“P”), 0.0), PDEntry(Composition(“O2”), 0.0), PDEntry(Composition(“Li2O”), -6.0), PDEntry(Composition(“FeO”), -4.2), PDEntry(Composition(“Fe2O3”), -10.5), PDEntry(Composition(“P2O5”), -15.0), PDEntry(Composition(“Li3PO4”), -18.5), PDEntry(Composition(“FePO4”), -12.2), PDEntry(Composition(“LiFePO4”), -16.9), ] pdg = PhaseDiagram(entries) target = [e for e in entries if e.composition.reduced_formula == “LiFePO4”][0] e_above_hull = pdg.get_e_above_hull(target) decomp, e_hull = pdg.get_decomp_and_e_above_hull(target) print(“Target entry:”, target.composition.reduced_formula) print(“Energy above hull:”, round(float(e_above_hull), 6), “eV/atom”) print(“Decomposition products:”) for k, v in decomp.items(): print(” “, k.composition.reduced_formula, “:”, round(float(v), 6)) We simulate X-ray diffraction patterns for silicon and NaCl using pymatgen’s diffraction tools. We visualize the diffraction peaks to understand how the crystal structure influences the XRD pattern. We then construct a simple thermodynamic phase diagram and calculate the stability of LiFePO₄ relative to competing phases. Copy CodeCopiedUse

A Coding Implementation for Building and Analyzing Crystal Structures Using Pymatgen for Symmetry Analysis, Phase Diagrams, Surface Generation, and Materials Project Integration 投稿を読む »

AI, Committee, ニュース, Uncategorized

OpenAI is throwing everything into building a fully automated researcher

OpenAI is refocusing its research efforts and throwing its resources into a new grand challenge. The San Francisco firm has set its sights on building what it calls an AI researcher, a fully automated agent-based system that will be able to go off and tackle large, complex problems by itself. ​​OpenAI says that this new research goal will be its “North Star” for the next few years, pulling together multiple research strands, including work on reasoning models, agents, and interpretability. There’s even a timeline. OpenAI plans to build “an autonomous AI research intern”—a system that can take on a small number of specific research problems by itself—by September. The AI intern will be the precursor to a fully automated multi-agent research system that the company plans to debut in 2028. This AI researcher (OpenAI says) will be able to tackle problems that are too large or complex for humans to cope with. Those tasks might be related to math and physics—such as coming up with new proofs or conjectures—or life sciences like biology and chemistry, or even business and policy dilemmas. In theory, you would throw such a tool any kind of problem that can be formulated in text, code, or whiteboard scribbles—which covers a lot. OpenAI has been setting the agenda for the AI industry for years. Its early dominance with large language models shaped the technology that hundreds of millions of people use every day. But it now faces fierce competition from rival model makers like Anthropic and Google DeepMind. What OpenAI decides to build next matters—for itself and for the future of AI.    A big part of that decision falls to Jakub Pachocki, OpenAI’s chief scientist, who sets the company’s long-term research goals. Pachocki played key roles in the development of both GPT-4, a game-changing LLM released in 2023, and so-called reasoning models, a technology that first appeared in 2024 and now underpins all major chatbots and agent-based systems.  In an exclusive interview this week, Pachocki talked me through OpenAI’s latest vision. “I think we are getting close to a point where we’ll have models capable of working indefinitely in a coherent way just like people do,” he says. “Of course, you still want people in charge and setting the goals. But I think we will get to a point where you kind of have a whole research lab in a data center.” Solving hard problems Such big claims aren’t new. Saving the world by solving its hardest problems is the stated mission of all the top AI firms. Demis Hassabis told me back in 2022 that it was why he started DeepMind. Anthropic CEO Dario Amodei says he is building the equivalent of a country of geniuses in a data center. Pachocki’s boss, Sam Altman, wants to cure cancer. But Pachocki says OpenAI now has most of what it needs to get there. In January, OpenAI released Codex, an agent-based app that can spin up code on the fly to carry out tasks on your computer. It can analyze documents, generate charts, make you a daily digest of your inbox and social media, and much more. (Other firms have released similar tools, such as Anthropic’s Claude Code and Claude Cowork.) OpenAI claims that most of its technical staffers now use Codex in their work. You can look at Codex as a very early version of the AI researcher, says Pachocki: “I expect Codex to get fundamentally better.” The key is to make a system that can run for longer periods of time, with less human guidance. “What we’re really looking at for an automated research intern is a system that you can delegate tasks [to] that would take a person a few days,” says Pachocki. “There are a lot of people excited about building systems that can do more long-running scientific research,” says Doug Downey, a research scientist at the Allen Institute for AI, who is not connected to OpenAI. “I think it’s largely driven by the success of these coding agents. The fact that you can delegate quite substantial coding tasks to tools like Codex is incredibly useful and incredibly impressive. And it raises the question: Can we do similar things outside coding, in broader areas of science?” For Pachocki, that’s a clear Yes. In fact, he thinks it’s just a matter of pushing ahead on the path we’re already on. A simple boost in all-round capability also leads to models that can work longer without help, he says. He points to the leap from 2020’s GPT-3 to 2023’s GPT-4, two of OpenAI’s previous models. GPT-4 was able to work on a problem for far longer than its predecessor, even without specialized training, he says.  So-called reasoning models brought another bump. Training LLMs to work through problems step by step, backtracking when they make a mistake or hit a dead end, has also made models better at working for longer periods of time. And Pachocki is convinced that OpenAI’s reasoning models will continue to get better. But OpenAI is also training its systems to work by themselves for longer by feeding them specific samples of complex tasks, such as hard puzzles taken from math and coding contests, which force the models to learn how to do things like keep track of very large chunks of text and split problems up into (and then manage) multiple subtasks. The aim isn’t to build models that just win math competitions. “That lets you prove that the technology works before you connect it to the real world,” says Pachocki. “If we really wanted to, we could build an amazing automated mathematician. We have all the tools, and I think it would be relatively easy. But it’s not something we’re going to prioritize now because, you know, at the point where you believe you can do it, there’s much more urgent things to do.” “We are much more focused now on research that’s relevant in the real world,” he adds. Right now that means taking what Codex can do

OpenAI is throwing everything into building a fully automated researcher 投稿を読む »

AI, Committee, ニュース, Uncategorized

The Download: OpenAI is building a fully automated researcher, and a psychedelic trial blind spot

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. OpenAI is throwing everything into building a fully automated researcher  OpenAI has a new grand challenge: building an AI researcher—a fully automated agent-based system capable of tackling large, complex problems by itself. The San Francisco firm said the new goal will be its “north star” for the next few years.   By September, the company plans to build “an autonomous AI research intern” that can take on a small number of specific research problems. The intern will be the precursor to the fully automated multi-agent system, which is slated to debut in 2028.  In an exclusive interview this week, OpenAI’s chief scientist, Jakub Pachocki, talked me through the plans. Find out what I discovered.  —Will Douglas Heaven  Mind-altering substances are (still) falling short in clinical trials  Over the last decade, we’ve seen scientific interest in psychedelic drugs explode. Compounds like psilocybin—which is found in magic mushrooms—are being explored for all sorts of health applications, including treatments for depression, PTSD, addiction, and even obesity. But two studies out earlier this week demonstrate just how difficult it is to study these drugs.   For me, they show just how overhyped these substances have become. Find out why here.  —Jessica Hamzelou  This story first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. Sign up to receive it in your inbox every Wednesday.  Read more: What do psychedelic drugs do to our brains? AI could help us find out  The must-reads  I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.  1 OpenAI is building a “super app”  It’s merging ChatGPT, a web browser, and a coding tool into a single app. (The Verge) + It’s also buying coding startup Astral to enhance its Codex model. (Ars Technica) + The moves come amid a cutback on side projects. (WSJ $) + OpenAI has lost ground to Anthropic in the enterprise market. (Axios)  2 The US has charged Super Micro’s co-founder with smuggling AI tech to China  Super Micro is third on Fortune’s list of the fastest-growing companies. (Reuters)  + GenAI is learning to spy for the US military. (MIT Technology Review) + The compute competition is shaping the China-US rivalry. (Politico)  3 The DoJ has taken down botnets behind the largest-ever DDoS attack They had infected more than 3 million devices. (Wired $) + The DoJ has also seized domains tied to Iranian “hacktivists.” (Axios)  4 The Pentagon says Anthropic’s foreign workers are a security risk It cited Chinese employees as a particular concern. (Axios) + Anthropic’s moral boundaries have incensed the DoD. (MIT Technology Review)  5 High oil prices could wreck the AI boom, the WTO has warned Fears are growing of a prolonged energy shock. (The Guardian) + We did the math on AI’s energy footprint. (MIT Technology Review)  6 Jeff Bezos is trying to raise $100 billion to use AI in manufacturing The funds would buy manufacturing firms and infuse them with AI. (WSJ $) + Here’s how to fine-tune AI for prosperity. (MIT Technology Review)  7 Signal’s creator is helping to encrypt Meta’s AI  Moxie Marlinspike is integrating his encrypted chatbot, Confer. (Wired $) + Meta is also ditching human moderators for AI again. (CNBC) + AI is making online crimes easier. (MIT Technology Review)  8 Prediction market Kalshi has raised $1 billion at a $22 billion valuation That’s double its valuation from December. (Bloomberg $) + Arizona’s AG has charged the company with “illegal gambling.” (NPR)  9 Meta isn’t killing Horizon Worlds for VR after all It’s canceled plans to dump the metaverse app (for now). (CNBC)  10 A US startup is recruiting an “AI bully”  The successful candidate must test the patience of leading chatbots. (The Guardian)  Quote of the day  “Imagine a sports bar… but just for situation monitoring — live X feeds, flight radar, Bloomberg terminals, and Polymarket screens.”  —Kalshi rival Polymarket unveils its hellish vision for a new bar.  One More Thing  SELMAN DESIGN How gamification took over the world  It’s a thought that occurs to every video-game player at some point: what if the weird, hyper-focused state I enter in virtual worlds could somehow be applied to the real one?  For a handful of consultants, startup gurus, and game designers in the late 2000s, this state of “blissful productivity” became the key to unlocking our true human potential. Their vision became the global phenomenon of gamification—but it didn’t live up to the hype.  Instead of liberating us, gamification became a tool for coercion, distraction, and control. Find out why we fell for it—and how we can recover.  —Bryan Gardiner  We can still have nice things  A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.)  + In a landmark legal win for trolling, Afroman has won his diss track case against the police. + This LEGO artist remixes standard sets into completely different iconic objects. + Ease your search for aliens with these interactive estimates of advanced civilizations.  + A rare superbloom in Death Valley has been caught on camera. 

The Download: OpenAI is building a fully automated researcher, and a psychedelic trial blind spot 投稿を読む »

AI, Committee, ニュース, Uncategorized

NVIDIA Releases Nemotron-Cascade 2: An Open 30B MoE with 3B Active Parameters, Delivering Better Reasoning and Strong Agentic Capabilities

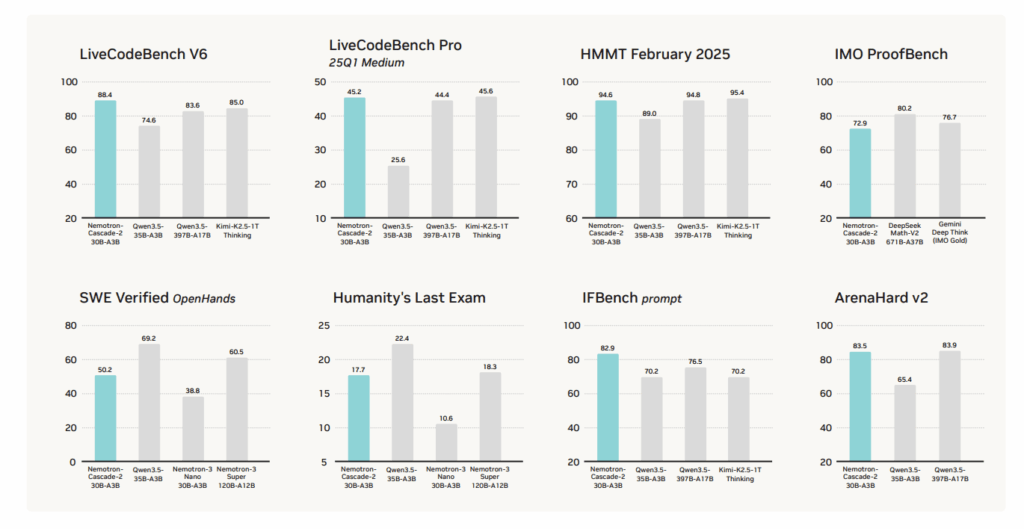
NVIDIA has announced the release of Nemotron-Cascade 2, an open-weight 30B Mixture-of-Experts (MoE) model with 3B activated parameters. The model focuses on maximizing ‘intelligence density,’ delivering advanced reasoning capabilities at a fraction of the parameter scale used by frontier models. Nemotron-Cascade 2 is the second open-weight LLM to achieve Gold Medal-level performance in the 2025 International Mathematical Olympiad (IMO), the International Olympiad in Informatics (IOI), and the ICPC World Finals. https://research.nvidia.com/labs/nemotron/files/Nemotron-Cascade-2.pdf Targeted Performance and Strategic Trade-offs The primary value proposition of Nemotron-Cascade 2 is its specialized performance in mathematical reasoning, coding, alignment, and instruction following. While it achieves state-of-the-art results in these key reasoning-intensive domains, it is surely not a ‘blanket win’ across all benchmarks. The model’s performance excels in several targeted categories compared to the recently released Qwen3.5-35B-A3B (February 2026) and the larger Nemotron-3-Super-120B-A12B: Mathematical Reasoning: Outperforms Qwen3.5-35B-A3B on AIME 2025 (92.4 vs. 91.9) and HMMT Feb25 (94.6 vs. 89.0). Coding: Leads on LiveCodeBench v6 (87.2 vs. 74.6) and IOI 2025 (439.28 vs. 348.6+). Alignment and Instruction Following: Scores significantly higher on ArenaHard v2 (83.5 vs. 65.4+) and IFBench (82.9 vs. 70.2). https://research.nvidia.com/labs/nemotron/files/Nemotron-Cascade-2.pdf Technical Architecture: Cascade RL and Multi-domain On-Policy Distillation (MOPD) The model’s reasoning capabilities stem from its post-training pipeline, starting from the Nemotron-3-Nano-30B-A3B-Base model. 1. Supervised Fine-Tuning (SFT) During SFT, NVIDIA research team utilized a meticulously curated dataset where samples were packed into sequences of up to 256K tokens. The dataset included: 1.9M Python reasoning traces and 1.3M Python tool-calling samples for competitive coding. 816K samples for mathematical natural language proofs. A specialized Software Engineering (SWE) blend consisting of 125K agentic and 389K agentless samples. 2. Cascade Reinforcement Learning Following SFT, the model underwent Cascade RL, which applies sequential, domain-wise training. This prevents catastrophic forgetting by allowing hyperparameters to be tailored to specific domains without destabilizing others. The pipeline includes stages for instruction-following (IF-RL), multi-domain RL, RLHF, long-context RL, and specialized Code and SWE RL. https://research.nvidia.com/labs/nemotron/files/Nemotron-Cascade-2.pdf 3. Multi-Domain On-Policy Distillation (MOPD) A critical innovation in Nemotron-Cascade 2 is the integration of MOPD during the Cascade RL process. MOPD assembly uses the best-performing intermediate ‘teacher’ models—already derived from the same SFT initialization—to provide a dense token-level distillation advantage. This advantage is defined mathematically as: $$a_{t}^{MOPD}=log~pi^{domain_{t}}(y_{t}|s_{t})-log~pi^{train}(y_{t}|s_{t})$$ The research team found that MOPD is substantially more sample-efficient than sequence-level reward algorithms like Group Relative Policy Optimization (GRPO). For instance, on AIME25, MOPD reached teacher-level performance (92.0) within 30 steps, while GRPO achieved only 91.0 after matching those steps. Inference Features and Agentic Interaction Nemotron-Cascade 2 supports two primary operating modes through its chat template: Thinking Mode: Initiated by a single <think> token, followed by a newline. This activates deep reasoning for complex math and code tasks. Non-Thinking Mode: Activated by prepending an empty <think></think> block for more efficient, direct responses. For agentic tasks, the model utilizes a structured tool-calling protocol within the system prompt. Available tools are listed within <tools> tags, and the model is instructed to perform tool calls wrapped in <tool_call> tags to ensure verifiable execution feedback. By focusing on ‘intelligence density,’ Nemotron-Cascade 2 demonstrates that specialized reasoning capabilities once thought to be the exclusive domain of frontier-scale models are achievable at a 30B scale through domain-specific reinforcement learning. Check out Paper and Model on HF. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post NVIDIA Releases Nemotron-Cascade 2: An Open 30B MoE with 3B Active Parameters, Delivering Better Reasoning and Strong Agentic Capabilities appeared first on MarkTechPost.

NVIDIA Releases Nemotron-Cascade 2: An Open 30B MoE with 3B Active Parameters, Delivering Better Reasoning and Strong Agentic Capabilities 投稿を読む »

AI, Committee, ニュース, Uncategorized

DeSTA2.5-Audio: Toward General-Purpose Large Audio Language Model with Self-Generated Cross-Modal Alignment

arXiv:2507.02768v2 Announce Type: replace-cross Abstract: We introduce DeSTA2.5-Audio, a general-purpose Large Audio Language Model (LALM) designed for robust auditory perception and instruction-following. Recent LALMs augment Large Language Models (LLMs) with auditory capabilities by training on large-scale audio-instruction datasets. However, existing LALMs have often suffered from the catastrophic forgetting of the LLM’s original abilities. Therefore, balancing knowledge retention and audio perception has become a critical challenge. To address this, we revisit the data construction pipeline and propose a self-generated cross-modal alignment strategy in which the backbone LLM generates its own training targets, named DeSTA. This approach aims at preserving the LLM’s native language proficiency thereby enabling zero-shot generalization without task-specific tuning. We construct DeSTA-AQA5M, a large-scale, task-agnostic dataset containing 5 million training samples derived from 7,000 hours of audio spanning 50 diverse datasets, including speech, environmental sounds, and music. DeSTA2.5-Audio achieves state-of-the-art or competitive performance across a wide range of audio-language benchmarks, including Dynamic-SUPERB, MMAU, SAKURA, Speech-IFEval, and VoiceBench. Comprehensive comparative studies demonstrate that our self-generated strategy outperforms existing training strategies. Our findings underscore the importance of carefully designed data construction in LALM development and offer practical insights for building robust, general-purpose LALMs.

DeSTA2.5-Audio: Toward General-Purpose Large Audio Language Model with Self-Generated Cross-Modal Alignment 投稿を読む »

AI, Committee, ニュース, Uncategorized

UT-ACA: Uncertainty-Triggered Adaptive Context Allocation for Long-Context Inference

arXiv:2603.18446v1 Announce Type: new Abstract: Long-context inference remains challenging for large language models due to attention dilution and out-of-distribution degradation. Context selection mitigates this limitation by attending to a subset of key-value cache entries, yet most methods allocate a fixed context budget throughout decoding despite highly non-uniform token-level contextual demands. To address this issue, we propose Uncertainty-Triggered Adaptive Context Allocation (UT-ACA), an inference-time framework that dynamically adjusts the context window based on token-wise uncertainty. UT-ACA learns an uncertainty detector that combines semantic embeddings with logit-based confidence while accounting for uncertainty accumulation across decoding steps. When insufficient evidence is indicated, UT-ACA selectively rolls back, expands the context window, and regenerates the token with additional support. Experiments show that UT-ACA substantially reduces average context usage while preserving generation quality in long-context settings.

UT-ACA: Uncertainty-Triggered Adaptive Context Allocation for Long-Context Inference 投稿を読む »

AI, Committee, ニュース, Uncategorized

LlamaIndex Releases LiteParse: A CLI and TypeScript-Native Library for Spatial PDF Parsing in AI Agent Workflows

In the current landscape of Retrieval-Augmented Generation (RAG), the primary bottleneck for developers is no longer the large language model (LLM) itself, but the data ingestion pipeline. For software developers, converting complex PDFs into a format that an LLM can reason over remains a high-latency, often expensive task. LlamaIndex has recently introduced LiteParse, an open-source, local-first document parsing library designed to address these friction points. Unlike many existing tools that rely on cloud-based APIs or heavy Python-based OCR libraries, LiteParse is a TypeScript-native solution built to run entirely on a user’s local machine. It serves as a ‘fast-mode’ alternative to the company’s managed LlamaParse service, prioritizing speed, privacy, and spatial accuracy for agentic workflows. The Technical Pivot: TypeScript and Spatial Text The most significant technical distinction of LiteParse is its architecture. While the majority of the AI ecosystem is built on Python, LiteParse is written in TypeScript (TS) and runs on Node.js. It utilizes PDF.js (specifically pdf.js-extract) for text extraction and Tesseract.js for local optical character recognition (OCR). By opting for a TypeScript-native stack, LlamaIndex team ensures that LiteParse has zero Python dependencies, making it easier to integrate into modern web-based or edge-computing environments. It is available as both a command-line interface (CLI) and a library, allowing developers to process documents at scale without the overhead of a Python runtime. The library’s core logic stands on Spatial Text Parsing. Most traditional parsers attempt to convert documents into Markdown. However, Markdown conversion often fails when dealing with multi-column layouts or nested tables, leading to a loss of context. LiteParse avoids this by projecting text onto a spatial grid. It preserves the original layout of the page using indentation and white space, allowing the LLM to use its internal spatial reasoning capabilities to ‘read’ the document as it appeared on the page. Solving the Table Problem Through Layout Preservation A recurring challenge for AI devs is extracting tabular data. Conventional methods involve complex heuristics to identify cells and rows, which frequently result in garbled text when the table structure is non-standard. LiteParse takes what the developers call a ‘beautifully lazy’ approach to tables. Rather than attempting to reconstruct a formal table object or a Markdown grid, it maintains the horizontal and vertical alignment of the text. Because modern LLMs are trained on vast amounts of ASCII art and formatted text files, they are often more capable of interpreting a spatially accurate text block than a poorly reconstructed Markdown table. This method reduces the computational cost of parsing while maintaining the relational integrity of the data for the LLM. Agentic Features: Screenshots and JSON Metadata LiteParse is specifically optimized for AI agents. In an agentic RAG workflow, an agent might need to verify the visual context of a document if the text extraction is ambiguous. To facilitate this, LiteParse includes a feature to generate page-level screenshots during the parsing process. When a document is processed, LiteParse can output: Spatial Text: The layout-preserved text version of the document. Screenshots: Image files for each page, allowing multimodal models (like GPT-4o or Claude 3.5 Sonnet) to visually inspect charts, diagrams, or complex formatting. JSON Metadata: Structured data containing page numbers and file paths, which helps agents maintain a clear ‘chain of custody’ for the information they retrieve. This multi-modal output allows engineers to build more robust agents that can switch between reading text for speed and viewing images for high-fidelity visual reasoning. Implementation and Integration LiteParse is designed to be a drop-in component within the LlamaIndex ecosystem. For developers already using VectorStoreIndex or IngestionPipeline, LiteParse provides a local alternative for the document loading stage. The tool can be installed via npm and offers a straightforward CLI: Copy CodeCopiedUse a different Browser npx @llamaindex/liteparse <path-to-pdf> –outputDir ./output This command processes the PDF and populates the output directory with the spatial text files and, if configured, the page screenshots. Key Takeaways TypeScript-Native Architecture: LiteParse is built on Node.js using PDF.js and Tesseract.js, operating with zero Python dependencies. This makes it a high-speed, lightweight alternative for developers working outside the traditional Python AI stack. Spatial Over Markdown: Instead of error-prone Markdown conversion, LiteParse uses Spatial Text Parsing. It preserves the document’s original layout through precise indentation and whitespace, leveraging an LLM’s natural ability to interpret visual structure and ASCII-style tables. Built for Multimodal Agents: To support agentic workflows, LiteParse generates page-level screenshots alongside text. This allows multimodal agents to ‘see’ and reason over complex elements like diagrams or charts that are difficult to capture in plain text. Local-First Privacy: All processing, including OCR, occurs on the local CPU. This eliminates the need for third-party API calls, significantly reducing latency and ensuring sensitive data never leaves the local security perimeter. Seamless Developer Experience: Designed for rapid deployment, LiteParse can be installed via npm and used as a CLI or library. It integrates directly into the LlamaIndex ecosystem, providing a ‘fast-mode’ ingestion path for production RAG pipelines. Check out Repo and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post LlamaIndex Releases LiteParse: A CLI and TypeScript-Native Library for Spatial PDF Parsing in AI Agent Workflows appeared first on MarkTechPost.

LlamaIndex Releases LiteParse: A CLI and TypeScript-Native Library for Spatial PDF Parsing in AI Agent Workflows 投稿を読む »

AI, Committee, ニュース, Uncategorized

Adaptive Decoding via Test-Time Policy Learning for Self-Improving Generation

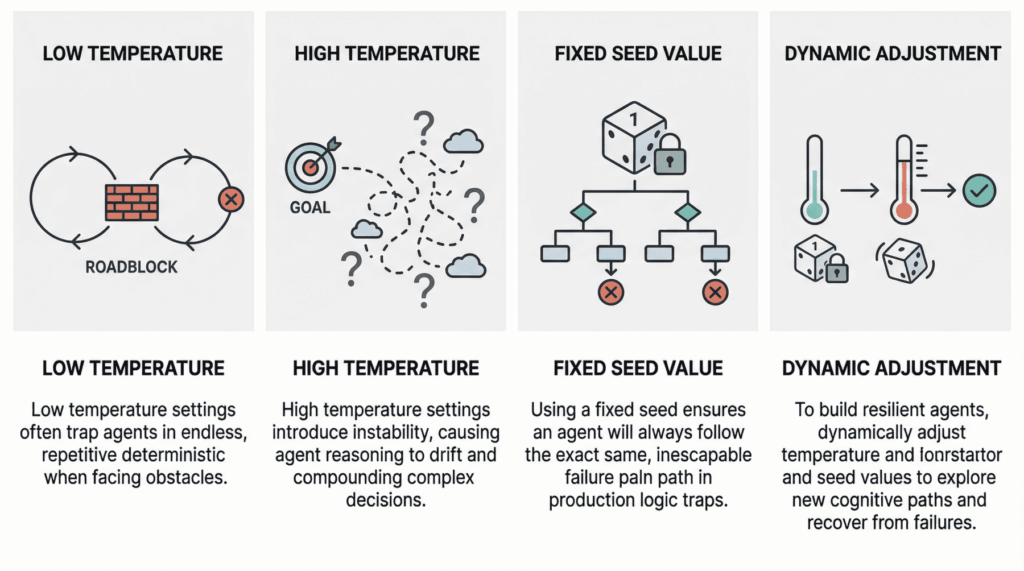
arXiv:2603.18428v1 Announce Type: new Abstract: Decoding strategies largely determine the quality of Large Language Model (LLM) outputs, yet widely used heuristics such as greedy or fixed temperature/top-p decoding are static and often task-agnostic, leading to suboptimal or inconsistent generation quality across domains that demand stylistic or structural flexibility. We introduce a reinforcement learning-based decoder sampler that treats decoding as sequential decision-making and learns a lightweight policy to adjust sampling parameters at test-time while keeping LLM weights frozen. We evaluated summarization datasets including BookSum, arXiv, and WikiHow using Granite-3.3-2B and Qwen-2.5-0.5B. Our policy sampler consistently outperforms greedy and static baselines, achieving relative gains of up to +88% (BookSum, Granite) and +79% (WikiHow, Qwen). Reward ablations show that overlap-only objectives underperform compared to composite rewards, while structured shaping terms (length, coverage, repetition, completeness) enable stable and sustained improvements. These findings highlight reinforcement learning as a practical mechanism for test-time adaptation in decoding, enabling domain-aware and user-controllable generation without retraining large models.

Adaptive Decoding via Test-Time Policy Learning for Self-Improving Generation 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja