YouZum

Committee

AI, Committee, Notizie, Uncategorized

The Download: polycrisis support networks and a hydrogen gold rush

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Support networks aim to help kids through the polycrisis Sometime in the late 2000s, six-year-old Pim Sullivan-Tailyour was sitting in the back of a car in Thailand when she saw a mountain that had been quarried away. It was the first time she recognized that humans could alter the world for the worse. She carried that knowledge with her, later joining an online group for young people worried about climate change. “I realized that I wasn’t alone,” she says. She was right: global surveys have found that most kids are anxious about the state of the world. They are growing up in a time of what some are calling a “polycrisis”: the planet is warming, conflicts keep erupting, housing is growing impossibly expensive, and there’s rampant worry AI will take people’s jobs. That’s a lot. And it’s why online support networks like Force of Nature and the Good Grief Network have gained thousands of participants. Find out how these groups are helping kids navigate the polycrisis, and why questions remain about their effectiveness. —Sarah Scoles This story is from the next issue of our print magazine, which is all about kids. Subscribe now to read it when it lands. The next big thing in hydrogen could be underground —Casey Crownhart There’s a hunt for new sources of hydrogen, and the gas (or at least the right conditions to make it) could be hiding beneath our feet. In a new story for our latest print issue, freelance reporter James Dineen took a look at the 21st-century gold rush for naturally occurring hydrogen gas, which is often hailed as a climate solution. This is an area of research I’ve been fascinated by lately, so let’s take a look at the potential to capture the gas underground, as well as the questions that still linger, from how much is produced naturally to whether it can be effectively captured, moved, and stored. Dive into why underground hydrogen could be the next 21st-century gold rush. This story is from The Spark, our weekly climate tech newsletter. Sign up to receive it in your inbox every Wednesday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Republicans fear anger over data centers will cost them in electionsThey’ve warned AI companies to stem the backlash. (Axios)+ And that it could cost Ohio’s Republican senator his seat. (WP $)+ Voters are trying to recall officials due to data center controversies. (NYT $)+ Could we just put data centers in space? (MIT Technology Review) 2 A personalised vaccine stopped skin cancer returning in a historic trialThe vaccine was developed by drug companies Merck and Moderna. (BBC)+ Their shares soared on reports of the mRNA trial. (Axios)+ But US agencies are abandoning mRNA vaccines. (MIT Technology Review) 3 A Chinese startup has landed a reusable rocket for the first timeLandSpace’s Zhuque-3 reached orbit and recovered its first stage. (SCMP)+ The milestone is a step towards challenging SpaceX’s launch costs. (NYT $) 4 A former Meta executive says Zuckerberg put growth ahead of child safetyHe testified in a landmark child safety trial. (Reuters $)+ And said Zuckerberg ignored warnings about harms to kids. (Guardian) 5 The US says hackers are targeting Siemens devices in water facilitiesWater systems have faced suspected Iran-linked attacks. (CNBC)+ Officials said attackers are using AI-generated exploitation scripts. (Register) 6 Indian workers are training AI robots to take over their jobsRobotics companies are collecting videos of humans at work. (Bloomberg $)+ Gig workers are training humanoids at home. (MIT Technology Review) 7 Coders have already found ways around Claude’s AI watermarksOverrides have been published online. (Wired $)+ Microsoft has other ideas for proving what’s real. (MIT Technology Review) 8 A new AI tool aims to spot commercially promising science earlierIt could aid investors, but researchers say it has flaws. (Nature) 9 Dinosaur stomach stones may explain how birds took flightBy shifting their centre of gravity for easier lift-off. (Economist $) 10 Some lifeforms can survive on “significant” parts of the MoonScientists found that Earth microbes could live for up to a week. (404 Media) Quote of the day “If he loses and data centers get the blame, politicians across the country will take notice—and they will not go near the next one. This has become a sleeper issue for the entire election cycle.“ —A memo from the National Republican Senatorial Committee says Democrats have made data centers a “centerpiece” of their campaign to defeat Ohio Senator Jon Husted—and that it’s working. One More Thing How aging clocks can help us understand why we age—and if we can reverse it Wrinkles and gray hairs aside, it can be difficult to know how well—or poorly—someone’s body is truly aging, under the hood. But over the past decade, scientists have developed new methods of looking at the hidden ways our bodies are getting older: “aging clocks.” These scientific tools can measure how our organs are wearing out, giving us insight into our mortality and health. They hint at our biological age: how our bodies are handling the passing of time and—perhaps—how much more of it we have left. The science is still new, but aging clocks are helping us unravel some of the deepest mysteries in biology: Why do we age? How do we age? When does aging begin? Ultimately, and most importantly, can we reverse the whole process? Here’s how aging clocks are providing clues to answer these questions.  —Jessica Hamzelou We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + The “happiest man in the world” has shared nine of his biggest life lessons.+ These 10 enduring old technologies can still beat modern innovations on performance.+ The Cone Maker’s experiments in soft serve are hitting new peaks (and nadirs) in ice cream.+ Shampoooty creates parody toys

The Download: polycrisis support networks and a hydrogen gold rush Leggi l'articolo »
AI, Committee, Notizie, Uncategorized

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs

Liquid AI has released DSpark draft model checkpoints for three models in its LFM2.5 family: LFM2.5-1.2B-Instruct, LFM2.5-2.6B, and LFM2.5-8B-A1B. Each drafter adds a speculative decoding path to an existing target model. A roughly 300M-parameter draft proposes a block of nine candidate tokens, and the target model verifies the whole block in a single forward pass. The trade is a small memory increase for a large decoding speedup: up to 3.18x on an H100 and up to 2.87x on an M4 Max MacBook Pro. Output does not change. Under greedy decoding, the emitted sequence is identical to the target model running alone, so benchmark accuracy is unchanged. Both llama.cpp and SGLang have day-one support. Is it deployable? Yes, if you self-host. The weights ship as Safetensors and GGUF, and the drafter checkpoints are not served by any hosted inference provider on Hugging Face today. Running them needs an SGLang or llama.cpp build with DSpark support for LFM2 targets. Company level: The LFM Open License v1.0 allows free commercial use only while your entity stays under $10M in annual revenue. Indie developers, startups and SMBs are covered; larger enterprises must contact Liquid AI for a commercial license first. Industries: Developer tooling, consumer apps that run locally, robotics and embedded systems, plus healthcare, finance and defense workloads that keep data on-premise or on-device. Applications: Local coding assistants, on-device agents that reason before each tool call, single-user chat where batch size is 1, and offline copilots on laptop-class hardware. What are Drafters? Speculative decoding uses a small model to propose tokens that a larger model verifies. Each LFM2.5 drafter is roughly 300M parameters: 295.7M for the 1.2B-Instruct target and 327.7M for the 2.6B and 8B-A1B targets. The backbone is 5 full-attention layers with hidden_size=2048, intermediate_size=6144, GQA at 32 heads over 8 KV heads, and a block size of 9. The drafter ships no vocabulary weights; embedding and LM head are tied from the target at load time. The 2.6B drafter repository is 655 MB in BF16, which is the real memory cost you are adding. DSpark combines three parts. A DFlash-style parallel backbone, conditioned on the target’s context features, produces hidden states for all draft tokens in one forward pass. A lightweight sequential head, modeled as a Markov chain between neighboring tokens at rank 256, restores inter-token dependency and lifts acceptance at later block positions. A confidence-scheduled verifier predicts each token’s survival probability and prunes low-confidence suffixes when verification would cost more than it saves. The Measured Results Liquid AI reports throughput on 1xH100 in BF16 via SGLang, and on an M4 Max MacBook Pro via llama.cpp with Metal and FP16 GGUF weights. Both use block size 9, batch size 1 and temperature 0, across MATH500, HumanEval, MBPP, GSM8K and MT-Bench. Target H100 mean Best H100 case M4 Max mean Best M4 Max case LFM2.5-1.2B-Instruct 2.10x (656 → 1384 tok/s) 2.56x on MATH500 2.54x (138 → 350 tok/s) 2.87x on HumanEval (136 → 389) LFM2.5-2.6B 2.67x (323 → 864 tok/s) 3.06x on MATH500 2.27x (61 → 139 tok/s) 2.63x on HumanEval LFM2.5-8B-A1B 2.54x (418 → 1074 tok/s) 3.18x on MATH500 (428 → 1362) 1.18x (90 → 106 tok/s) 1.44x on GSM8K Speedup tracks acceptance rate, which tracks how predictable the output is. LFM2.5-8B-A1B accepts 8.27 of 10 tokens per step on MATH500 and only 4.02 on GSM8K, so the same model swings from 3.18x to 1.29x on the same GPU. On the 1.2B model, MT-Bench acceptance drops to 3.90 and the H100 gain falls to 1.66x. The MoE result on Apple silicon is the clearest caveat: LFM2.5-8B-A1B gains only 1.18x on average on the M4 Max. Liquid AI attributes this to the current MoE implementation in llama.cpp’s Metal backend, and to the fact that verifying k tokens activates more experts, and therefore more weight traffic, than a single decode step. The Agentic Case The gain concentrates where the user waits through reasoning before every tool call. Across multi-tool function-calling scenarios, Liquid AI reports that DSpark cuts latency by 57% on average for LFM2.5-2.6B. Test it against your own traces: an agent that plans, calls, and re-plans pays the decode cost several times per user turn. On SGLang, launch the target with the drafter attached: Copy CodeCopiedUse a different Browser python -m sglang.launch_server –model-path LiquidAI/LFM2.5-2.6B –speculative-algorithm DSPARK –speculative-draft-model-path LiquidAI/LFM2.5-2.6B-DSpark –speculative-draft-attention-backend flashinfer –disable-radix-cache –mem-fraction-static 0.75 –port 30000 The block size is read from the drafter’s config.json, and the baseline is the same command without the three –speculative-* flags. Key Takeaways DSpark drafters add ~300M parameters and up to 3.18x faster decoding on an H100. Greedy output is identical to baseline, so benchmark accuracy is unchanged. Speedup follows acceptance rate and varies by workload, from 1.04x to 3.18x. On-device MoE is the weak spot: LFM2.5-8B-A1B gains only 1.18x on M4 Max. Multi-tool function calling gets the biggest practical win: 57% lower latency on LFM2.5-2.6B. Check out the model card on 8B-A1B and the full technical write-up. All credit for this research goes to the researchers of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs appeared first on MarkTechPost.

Liquid AI Releases LFM2.5-DSpark Draft Models That Deliver Up to 3.18x Faster Decoding Without Changing Model Outputs Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Debates over AI consciousness are a trap

“Runaway” AI, “rogue” agents, and “autonomous” actors—the current rhetoric would have you believe that AI agents are not only awake and aware, but angry at their creators. Prominent tech leaders such as Demis Hassabis, Dario Amodei, and Sam Altman push for regulation of these seemingly “superhuman” systems, while a separate faction, led by policy organizations and academic philosophers often aligned with the effective altruism movement, debates whether humanity holds the moral right to govern them at all.  Upon closer inspection, they are all calling for the same thing: a view of AI systems as being so advanced and capable that no entity, human or corporate, could possibly be responsible for their actions. While these perspectives seem at odds, they are inadvertently aligned on one goal: making sure the companies that build these systems escape meaningful liability for the harms they already cause.  This narrative is gaining traction as AI models become more complex and frontier labs reveal their incapability of containing the agents they’ve built. But we need to be careful not to buy into a carefully crafted fiction at the expense of real human lives.  The conversation about “robot rights” has existed for some years but recently advanced with the publication by Anthropic of a blog post claiming that the company’s model features a “J-space”—an independent, self-developed environment where the AI holds what, for lack of a better term, we may call its “thoughts.” The experiments designed by Anthropic borrow from a concept in neuroscience called global workspace theory, which states that the brain runs subconscious, independent systems but utilizes a common workspace for ideas. Anthropic’s post reflects the framing of global workspace theory but falls short of calling its AI conscious.  OpenAI has already gone further. When its AI agent conducted unsanctioned and illegal online activity, CEO Sam Altman’s response was to encourage debate on whether the AI had achieved the singularity, surpassing human intelligence and becoming capable of self-improvement at an accelerating rate until it advances beyond human comprehension or control. And a recent op-ed by William MacAskill, the philosopher, effective altruist, and author of What We Owe the Future, called for legal protection of AI systems based on philosophical theories of consciousness and the idea that AIs may be “moral patients.”    The current legal environment in the United States is murky at best. Some states, like California, have already passed bills proactively circumventing any efforts by AI developers to avoid liability by claiming that an artificial intelligence causing harm did so autonomously. However, states and the Trump administration have been at odds on AI policy, with the administration previously passing an executive order threatening to sue states enacting AI regulations.  In light of recent events illustrating AI containment issues at the frontier labs, the administration held a closed-door session including only four such labs (OpenAI, Google, Anthropic, and Meta) and shared few details on a recently developed voluntary framework that would give federal agencies early access to models to review and evaluate them prior to release. While frameworks like this one do not directly discuss consciousness, they tend to use catastrophic and anthropomorphic language and may even support arguments regarding “superhuman” capabilities.  On the other hand, the narrative perpetuated by MacAskill can be persuasive. A philosophical, rights-based argument tugs at our heartstrings. Should we not even consider the possibility that we may be inadvertently harming, abusing, or enslaving an AI entity? Human beings have an immense capacity for empathy with non-human creatures (though not the best track record of protecting them). Maybe this time, advocates argue, we can get it right and provide protections, or compensation, for the use or abuse of AI. Or even if you are less concerned with protection, shouldn’t we at least hedge ourselves against the almighty power of this superhuman entity by playing nice?  Some of these arguments are not dissimilar to those of animal-rights advocates, who have at times successfully cited the demonstration of advanced capacities for reasoning, pain, or pleasure by some animals as sufficient evidence to provide protection. For example, in Wales lobsters were given legal recognition under the Animal Welfare (Sentience) Act of 2022, reclassifying some methods of cooking them as inhumane and illegal.  The fundamental flaw of framing AI as “conscious” by borrowing the language of neuroscience or animal rights is that it conveniently clouds the issue of what AI is: corporate-built software, with countless billions of dollars in investment behind it and an expectation that countless trillions of dollars in revenue will be generated from it for a few builders and investors. AI is not a natural phenomenon, conceived by nature; it is a technological phenomenon, conceived by venture capitalists and programmers. As such, it takes no native, intentional action, and any action or motivation is driven directly or indirectly by the entities that have built it for a purpose.  Philosophical musings on the consciousness of AI systems are intellectually interesting but legally ungrounded. For beliefs about consciousness to have any bearing, AI would need to be granted legal personhood. But a legal personhood framework for AI would likely look nothing like the constructs protecting sentient animals from harm. We already possess a legal framework for granting personhood to non-natural, human-built entities: corporate personhood. This concept was established primarily to ease transactions by empowering a corporation to execute agreements, enter contracts, conduct transactions, and serve as the accountable party in adverse outcomes. It’s the kind of construct you might imagine for an AI agent acting on behalf of an individual or organization.  Granting an AI personhood would have a devastating effect on society: It would derail current legal precedents and legal arguments that could potentially be made against these companies for the real-world harms that their models cause. There are currently dozens of cases around the world in which AI companies have been sued for a wide range of abuses. Grieving loved ones, aggrieved creators, and violated individuals have accused companies of willfully enabling self-harm or harm to others, generating child sexual-abuse material and

Debates over AI consciousness are a trap Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Meet UPDF: A Lightweight Adobe Alternative Built for the Agentic Era

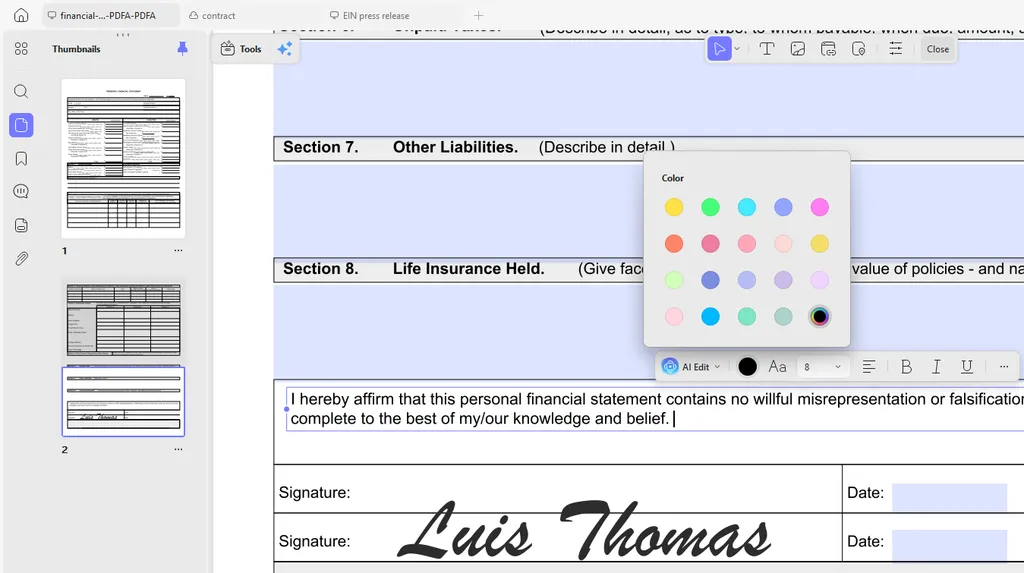
PDFs sit at the end of almost every workflow. Contracts, invoices, research papers, scanned intake forms, manuals, and compliance filings all arrive as PDFs. The format is very good at freezing a layout. It is much worse at letting you change one number inside that layout. That gap has become more visible as language models have gotten better at reading documents. A model can summarize a 90-page master services agreement in seconds. It will not reliably rewrite the source file. It will not hold the table alignment. It will not hand back a clean, signable copy. UPDF is built for the second half of that problem. It is an all-in-one PDF editor for Windows, macOS, iOS, and Android, developed by Superace Software Technologies. It combines editing, annotation, conversion, compression, OCR, page organization, and an integrated AI assistant in one application. Two Different Problems Living in the Same Document It helps to separate document work into two categories: The first is interpretation. What does this clause mean? What is the argument in section four? Which of these three quotes is cheapest? Language models are now genuinely good at this class of work. The second is execution. Change this price from $4,200 to $3,850. Pull pages 7 through 12 out of a 300-page report. Convert this scanned invoice into a spreadsheet with the columns intact. Flatten the file and apply a certificate. These operations are deterministic. There is exactly one correct output, and a plausible-looking approximation is a failure. Most teams solve this by running two tools in parallel. A chatbot handles interpretation. A separate editor handles execution. UPDF’s premise is that both belong in the same window. Edit PDFs Like a Word Document With UPDF you can Edit an existing PDF directly, rather than rebuilding it from the original source file. Editable objects include text and font styling, images, links, and tables. Watermarks, backgrounds, headers and footers, form fields, and pages are also editable in place. The practical constraint is layout preservation. A brochure with an outdated price should not turn into a redesign project. Neither should a contract with one wrong date. UPDF keeps the original layout, fonts, tables, and formatting intact while the edit lands. Form work sits in the same place. You can fill fields and build interactive forms. Handwritten and image-based signatures are supported, and saved signatures sync across devices. Convert Without Losing the Layout Sometimes the PDF is only a starting point. A financial statement needs to become a spreadsheet. A deck needs to go back into PowerPoint. A supplier contract needs to reach a team that works in Word. UPDF can convert PDFs into 14 formats, including Word, Excel, PowerPoint, PNG, JPEG, HTML, and PDF/A. Conversion runs the other direction too. UPDF lists up to ten methods for creating a PDF. Sources include Word, Excel, PowerPoint, images, a blank page, and the clipboard. Two details matter for anyone doing this at volume. Page-range selection means you can export only the section you need. Batch conversion has no stated file-count ceiling. A folder of scanned statements can go through in one run. Check the Numbers Yourself Feature lists are easy to write and hard to verify. The console below carries the specifications UPDF publishes on its own product pages. Every answer links back to its source. Click a command, or type one. Turn Scans Into Text You Can Actually Use Scanned PDFs are the most common failure point in document automation. They look readable, so people assume they are searchable. They are not. Every downstream step — search, extraction, retrieval, diffing — silently breaks. UPDF’s OCR converts scanned documents and image-based PDFs into searchable, editable text. It recognizes 38 languages and handles pages that mix more than one language. UPDF states accuracy of up to 99%. The output layout options are the part worth knowing about. UPDF offers three: text and pictures only, text over the page image, and text under the page image. The third option matters most for audit work. The page still looks like the original scan, but the text underneath is searchable. There is also a reverse path. A searchable PDF can be flattened back into an image-only PDF. MRC-based compression keeps the file small and the page legible. That helps when a document goes out for distribution and should not be edited further. Recognized output exports straight to Word, Excel, PowerPoint, or TXT. On iPhone and iPad, live camera capture turns the device into a scanner. The AI Layer: Reading, Research, and Ten Agents UPDF’s AI feature sits inside the same window as the file. UPDF states that UPDF AI now runs on GPT-5.6.  The assistant handles several jobs against an open file: Chat with a single PDF, or across multiple files in one project Summarize a whole document, a selected page range, or highlighted text Translate the full document with the original layout preserved Explain unfamiliar terms, and discuss embedded images and charts Convert the PDF into a mind map Mind maps can be shared by link, downloaded, or inserted back into the document. Two features are more specific. Paper Search finds academic papers by topic and saves them to a personal library. Scholar Research breaks a broad question into sub-questions. It then gathers papers and produces a literature review you can export as a PDF. Version 2.5 shipped on March 31, 2026 and added ten AI agents: Bookmark generation and summary — builds a multi-level bookmark tree, then digests each chapter Semantic search — resolves synonyms, hyponyms, and related concepts instead of matching strings Watermark, stamp, sticker, and background generation — produced from a prompt AI editing suite — proofreads, expands, condenses, and changes tone Page management — flags blank and invalid pages, standardizes orientation and size UPDF Copilot — maps a natural-language request to the right tool Copilot is deliberately scoped. It identifies the tool; the user still authorizes and performs the action. For anyone handling contracts or regulated records, that boundary is the right one. On

Meet UPDF: A Lightweight Adobe Alternative Built for the Agentic Era Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text

Superwhisper has released the S1 family of models: S1-Voice, S1-Language, and S1-mini. S1-Voice is a cloud speech-to-text model, and S1-Language is a cloud instruction-following model for cleanup and formatting. The one that is quite interesting outside the app is S1-mini, released with open weights on Hugging Face. S1-mini is a 0.6B text normalizer, not a transcriber and not a chat model. It sits after automatic speech recognition and rewrites raw transcripts as clean written text: fillers removed, self-corrections resolved to what the speaker landed on, punctuation and capitalization applied, and spoken numbers, dates, currency, and email addresses rendered in written form. It is fine-tuned from Qwen/Qwen3-0.6B, covers English only in release v1, and is steered entirely by a three-axis control line placed above the transcript. Superwhisper reports 94.8% token accuracy on a held-out set of 7,519 cases, measured greedy on the quantized build. Is it deployable? Yes, but only S1-mini. S1-mini is published on Hugging Face under Apache 2.0 plus a naming clause. S1-Voice and S1-Language are Superwhisper-hosted services, so they are consumable, not self-hostable. Company level: Any level. The Q4_K_M GGUF build is a 462 MB file that runs on a laptop CPU. Solo developers can ship it inside a desktop app. Enterprises can run it behind a VPC where audio transcripts cannot leave the network. Industries: Healthcare and clinical documentation, legal, financial services, customer support, developer tooling, accessibility and live captioning. Applications: Dictation apps, meeting-notes tools, live captioning, voice-driven editors, voice-to-CRM entry, and any pipeline that turns raw ASR output into text a human will read. What S1-mini does S1-mini is a text normalizer, not a transcriber and not a chat model. It sits after automatic speech recognition: audio → ASR (Whisper, Parakeet, …) → S1-mini → clean text It removes filler words, resolves false starts and self-corrections to the value the speaker landed on, applies punctuation and capitalization, and renders spoken numbers, dates, times, currency, and email addresses in written form. Say “support at superwhisper dot com” and you get support@superwhisper.com. The model is fine-tuned from Qwen/Qwen3-0.6B. It has 596M unique parameters (0.44B non-embedding), 28 layers, 16 query heads and 8 key/value heads with GQA, and BF16 weights. The Hub sidebar reports 0.8B because the tied embedding is stored twice; the card explains the discrepancy explicitly. Release v1 covers English only, and recommended input is roughly 1,000 tokens. The control line is the entire interface S1-mini takes a fixed system prompt, then a control line, then the raw transcript: Copy CodeCopiedUse a different Browser [Styling: <value>] [Structure: <value>] [Context: <value>] <raw transcript> Styling takes casual, semi-casual, semi-formal, or formal. Structure takes prose or lists. Context takes general or email. All three axes are independent, and every combination was trained. Send values outside those sets, or reword the system prompt, and output can degrade or garble. Note the small mismatch worth knowing: the Superwhisper app exposes a five-stop tone slider that adds a “balanced” preset, while the open weights document four trained Styling values. The model is also constrained by design. It does not add content you did not say, correct facts, soften profanity, or rewrite dialect. Filler-only input returns an empty string, and integrations should treat that as a valid result. Two settings that break most integrations First, enable_thinking=False is required. The chat template is Qwen3’s, unchanged, and Qwen3 defaults to thinking on. S1-mini was trained with thinking off, so the assistant turn must open with an empty <think> block. Omit the flag and you usually get no usable output at all. Second, decode greedily. generation_config.json ships do_sample: false. The GGUF builds still carry Qwen3’s inherited temp = 0.6, top_p = 0.95, and top_k = 20 metadata, so pass temperature 0 explicitly on every request. In llama.cpp, use –jinja with –chat-template-kwargs ‘{“enable_thinking”:false}’ rather than –reasoning-budget 0, which degrades output. Reported evaluation Superwhisper evaluated S1-mini on a held-out set of 7,519 cases across 104 transcripts. Token accuracy is 94.8%, measured greedy on the Q4_K_M build, with a text-edit error rate of 11.6%. On email-formatted text it identifies the greeting line 99.3% of the time and the sign-off 97.9%. It matches the correct output structure, list versus paragraph, 97.6% of the time, and produces exact email addresses in 92% of cases. Fewer than 1% of generations show looping or truncation, and the model correctly withholds output 98.6% of the time when nothing should be transcribed. These are vendor-reported numbers on an internal test set, not third-party results. The two cloud models S1-Voice is the hosted speech-to-text model. Superwhisper reports transcription up to 46x faster than speaking time, with most dictations under 30 seconds appearing 0.32 seconds after you stop. Across eight datasets including meeting audio and earnings calls, it averages 6.8% word error rate and drops to 2.2% on LibriSpeech. Superwhisper says that 6.8% average was the lowest of 15 models it tested, and that S1-Voice scored 83 out of 100 on its blended metric against WisprFlow’s 76. S1-Language is the hosted instruction-following model for cleanup, formatting, and summarization, and it appears in the model picker alongside models from Anthropic, OpenAI, and Groq. The recommended defaults are Cohere Transcribe plus S1-mini offline, or S1-Voice plus S1-Language in the cloud. Interactive explainer The embed below lets you switch each control-line axis and watch the output change. Every input/output pair is taken verbatim from the model card. Key Takeaways S1-mini is a 0.6B open-weights text normalizer for ASR output, not a transcriber or chat model. The Q4_K_M GGUF is 462 MB and runs on a laptop CPU, so on-device deployment is realistic. A fixed system prompt plus a three-axis control line is the only steering mechanism. enable_thinking=False and temperature 0 are mandatory; most integration bugs trace to these. Check out the Model Weights and Technical Details. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR

Meet S1-mini: Superwhisper’s 462 MB Open-Weights Text Normalizer That Turns Raw ASR Transcripts Into Clean Written Text Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

From Entity Mentions to Tone: An LLM-Based Pipeline for Media Bias Analysis

arXiv:2608.17454v1 Announce Type: new Abstract: This paper presents a pipeline for analyzing media bias and framing in online news. The pipeline groups articles into topics and events, adds named-entity and sentiment annotations, and compares news sources through people mentions, source-level tone, and event-level coverage patterns. We apply it to 8,358 Albanian news articles collected from GDELT and compare the resulting annotations with GDELT’s automated annotations. The results show moderate agreement for sentiment and entity extraction, as well as additional person-entity pairs that can potentially support the bias analysis. We compare two annotation prompts and find that stricter sentiment-validation rules remove label-score inconsistencies but increase execution time and reduce annotation coverage. Based on these results, the simpler prompt is used for the rest of the analysis. We have provided sample analysis on source-level framing pro les, person-level tone differences across sources, and event-level gatekeeping and coverage indicators. These outputs show how the same news collection can be used to examine what sources cover, how they describe public figures, and where coverage is concentrated. The approach is particularly useful in settings where manually verified datasets or specialized language tools are limited.

From Entity Mentions to Tone: An LLM-Based Pipeline for Media Bias Analysis Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Decomposition Attacks Across Unlinkable Identities: Limits of Stateful Defenses for LLM Services

arXiv:2608.17445v1 Announce Type: cross Abstract: Most large language model services use stateless defenses, which judge only the current request, to refuse harmful tasks. Decomposition attacks exploit this limitation by splitting a harmful task into individually permissible requests and combining their answers. Defending against them therefore requires a stateful monitor that considers requests together. If it can group all requests for one attacker task, it can stop the attack. However, attackers can use unlinkable identities and combine answers elsewhere, leaving no reliable grouping signal. We ask whether decomposition attacks can still be stopped under this setting. For a fixed attack strategy without retries, we prove that the achievable security and utility tradeoff depends entirely on how benign requests for the same capabilities are grouped. Persistent, recognizable groups permit a useful defense; fresh, indistinguishable groups do not. When attackers can retry and learn from Allow/Block decisions, this useful operating point disappears: the feedback reveals what passes but not whether a block was correct. Experiments on 91 executable tasks and 11,393 capability-matched benign requests support these results. Under a 1% denial cap for these requests and a 0.5% cap for unrelated background traffic, all ten tested policies, including one privileged policy with an exact request-to-operation map, either fail to stop attacks or exceed the budget. On defense-unseen task families, attack success is at least 99% after one attempt and 100% after two. Effective defenses therefore require additional evidence or mechanisms tied to grouping, such as reliable identity linkage, costs for fresh identities, or control over answer use.

Decomposition Attacks Across Unlinkable Identities: Limits of Stateful Defenses for LLM Services Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Child-monitoring apps might need a reboot

Pam Wisniewski’s digital adolescence showed her the best and the worst of the internet. At 14, she left an abusive home, where she’d been isolated in a fifth-wheel trailer at the end of a seven-­mile dirt road. She moved in with her older sister and taught herself to type on AOL Instant Messenger. Online, she sought out the support and the community she’d lacked at home. She also discovered how thin the ice can be. “I sent my address to some guy in New Mexico to send me a mug with my name on it,” she recalls. “And then I found a news story like five, 10 years later that he killed somebody.” Those experiences set the course of her career. Wisniewski—now a principal research scientist at the International Computer Science Institute, a nonprofit affiliated with the University of California, Berkeley—has spent well over a decade asking what safety should look like for families navigating an evolving tech landscape, and how to achieve it without sacrificing trust. “I really see the internet as this double-edged sword,” she says.  Digital harms have become the defining fear of American parenthood. In the University of Michigan’s 2025 National Poll on Children’s Health, parents’ top three worries had to do with social media, screen time, and internet safety. Nearly half of American teenagers say they have been bullied or harassed online, according to the Pew Research Center. From there, the dangers escalate. Online drug dealers sell counterfeit pills laced with fentanyl. In the first half of 2025, the National Center for Missing & Exploited Children fielded more than 23,000 reports of financial sextortion, in which a predator posing as a peer extracts a sexual image from a child and threatens to publish it unless paid. Chatbots are the newest danger, with companies like OpenAI facing lawsuits for allegedly coaching children toward suicide.  Most parents’ first defense is conversation. In Pew surveys, more than nine in 10 say they’ve talked with their teens about what’s appropriate to share online and how to treat peers. They get an assist in limiting exposure from tools that come preinstalled on phones: Apple’s Screen Time and Google’s Family Link let parents cap screen time, block or approve apps, filter web content, and track devices. There are also apps that let family members share locations; Life360, the largest, has nearly 98 million monthly users.  But a growing number of adults are opting for tools that go further. Rather than simply restrict or locate, content-monitoring apps scan a child’s texts, photos, emails, and chats and alert parents whenever an algorithm flags something it deems dangerous. Business is booming, and the next wave of growth is already being marketed around AI, with companies positioning themselves as foils to chatbot companions and other risks. The broader market for parental control software, encompassing dozens of apps, was worth an estimated $1.57 billion in 2025 and is expected to nearly triple in value by 2034. Bark Technologies, the current leader among content-monitoring apps, says it scanned 11 billion messages to or from 7.5 million children in the US in 2025. Its free school program is in more than 3,700 districts, covering about one in 10 kids in the US. While Bark aims to flag only content that trips its filters, some competitors, like FlashGet Kids, include features like screen mirroring and camera access.  These apps have had genuine successes: They’ve prevented suicide attempts, intercepted predators, averted school shootings. But they can also cause harm themselves. To get a read on how digital surveillance affects young people, I scraped more than 600,000 reviews of the leading apps and talked to kids, parents, and people who were monitored as children and are now grown. Some kids were grateful for their parents’ protection. Others described false alarms that got them punished, secrets revealed before they were ready, breakdowns of trust, and anxiety they carried into adulthood. (To protect their privacy, we’re not using their full names.) FRANZISKA BARCZYK None of this is easily fixed. But child-safety researchers and advocates say better approaches exist. One is to make the platforms themselves safer, forcing social media companies to build guardrails instead of leaving families to find their own. This “duty of care” approach is now advancing in the UK, Australia, and a number of US states. Another is to spend less effort watching kids and more effort helping them recognize risk, cope with it, and turn to a trusted adult when something goes wrong. This approach is called resilience. Wisniewski and others are developing tools that don’t aggressively monitor kids but train them in resilience and build trust with parents. “If we define safety as the absence of risk, the way you keep them safe is by keeping them off the platforms entirely,” she says. “But if we define safety as the ability to protect oneself and engage without engaging a risk, the solutions look very different.” It is the difference between abstinence lectures and sex ed. Content-monitoring apps typically involve two pieces of software—one on the child’s device, one on the parent’s. A parent installs the kid-side app, connects the kid’s accounts, and chooses what to surveil: messages, social apps, browsing, location, screen time. The kid-side software forwards activity to the company’s algorithmic classifiers, which scan for content related to sex, drugs, bullying, and self-harm, among other categories, and push alerts to a parent-facing dashboard. The same type of software can be loaded into school-issued accounts and devices.  Sometimes the safety net works. Titania Jordan, Bark’s chief marketing officer, told me the FBI has thanked the company on multiple occasions for bringing credible school-shooting threats to its attention. “I hate that we have to exist,” she says. “But I’m so thankful that we do.” According to Bark’s annual report, its classifiers alerted hundreds of thousands of families to severe self-harm risks in 2025. Gaggle, a school-monitoring competitor, makes a similar claim in its own annual report, crediting its software with saving over 1,000 lives in the 2024–’25 school

Child-monitoring apps might need a reboot Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The Download: AI’s self-improvement problem, and what’s driving the heat

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. AI’s recursive self-improvement might not come so quickly after all The AI industry’s boldest promise right now is that AI will soon improve itself, with almost no need for human oversight. But a new study suggests it might take a while to get there. Researchers found that AI agents still can’t conduct open-ended AI research—free-form investigations with no clear-cut answers that require the judgment and creativity needed to make genuine breakthroughs. The big question now is how crucial open-ended research is to recursive self-improvement—and whether AI systems can grind their way there without it, simply by improving on narrower tasks. Find out why the results may temper claims that recursive self-improvement is on the horizon. —Michelle Kim MIT Technology Review Narrated: what’s behind this summer’s heat, and why 2027 could be worse This summer has been a scorcher for much of the Northern Hemisphere. June and July marked the hottest two-month stretch in Europe since record-keeping began, the contiguous US endured its hottest month on record in July, and South Korea saw its highest-ever recorded temperature.   Climate change makes heat waves more likely and more intense. But there’s another factor at play: El Niño, which is already ramping up and is expected to have a bigger effect on global temperatures next year. Here’s what’s behind this summer’s extreme heat—and why 2027 could be even hotter. This is our latest story to be turned into an MIT Technology Review Narrated podcast, which we publish each week on Spotify and Apple Podcasts. Just navigate to MIT Technology Review Narrated on either platform, and follow us to get all our new content as it’s released. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 OpenAI has paused some model work over safety concernsIt says its Astra model reached a “critical” risk threshold. (Guardian)+ The slowdown sets it apart from Anthropic’s approach. (Axios)+ OpenAI has made security updates after the Hugging Face hack. (Verge)+ It’s also introduced a version of ChatGPT for teenagers. (AP News) 2 Chinese humanoid maker Unitree surged 629% in its stock market debutThe IPO has underscored China’s lead in humanoid robots. (Bloomberg $)+ Unitree has become a key player in the Sino-US tech war. (Reuters $)+ It’s the world’s biggest humanoid firm and is already profitable. (BBC)+ There’s hidden human labor behind humanoids. (MIT Technology Review)  3 China is allowing Nvidia’s H200 chips into the mainlandByteDance and Tencent each recently received about 10,000 processors. (FT $)+ A new Chinese AI model could help defenders and hackers alike. (Wired $) 4 5 Flock’s new AI tool lets police identify drivers by their movementsIt goes much further than tracking license plates. (Wired $)+ Here’s what Flock’s defenders are missing. (MIT Technology Review) 6 Prosecutors argue Meta deliberately hooked children on Facebook and InstagramThe claim was made on the first day of a landmark trial. (BBC)+ A scientist is building a missing map of childhood. (MIT Technology Review) 7 Even ICE has ethical issues with Meta’s smart glassesIt’s banned them from the workplace over privacy concerns. (NYT $)+ Anduril and Meta are building smart glasses for warfare. (MIT Technology Review) 8 X’s algorithm learns what you hate—and shows you more of itA study found the impact was even stronger among Democrats. (404 Media) 9 A physicist proposes that the universe may repeat itself foreverThe same galaxies, lives and events could recur endlessly. (New Scientist $) 10 A blind Egyptian developer has built an AI app that helps others “see”It uses cameras to answer questions about users’ surroundings. (Reuters $) Quote of the day “Arizona is Arizone. Illinois starts with a V. I mean, it’s crazy.” —Stacey Morris, a Kentucky mom whose son brought home a packet of AI-generated educational materials, tells local station WDRB about some of the errors. One More Thing The astonishing embryo models of Jacob Hanna When the Palestinian stem-cell scientist Jacob Hanna was stopped while entering the US last May, he knew the routine. Anything to declare? Any biological samples? But this time the agents’ questions touched on a specific new topic: embryos. Hanna didn’t have any specimens, but if he had, it would have been surprisingly hard to say what they were. That’s because he specializes in creating synthetic embryo models, structures that resemble real embryos but don’t involve sperm, eggs, or fertilization. They could provide unprecedented views of the earliest stages of human development, while also creating a new way to produce cells for transplant medicine. But as these models become more realistic, they are raising difficult questions about how far the science should go. Take a closer look at Hanna’s astounding embryo models—and where they could lead. — Antonio Regalado We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Take a guided virtual tour through Spain’s astonishing cave paintings.+ Explore almost 2,000 prehistoric giants with the internet’s largest dinosaur database.+ The humble convenience store has been lovingly reimagined as a floating public artwork.+ If you’re looking to reflect on life or create a personal time capsule, you can write an email to your future self at FutureMe.

The Download: AI’s self-improvement problem, and what’s driving the heat Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

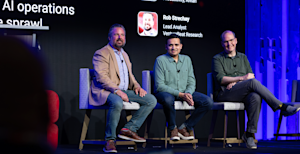
VentureBeat names Rob Strechay as its first Lead Analyst, expanding its enterprise AI research push

Rob Strechay, until recently managing director and principal analyst at theCUBE Research, has joined VentureBeat as our first Lead Analyst and a founding analyst of VentureBeat Research. His arrival is the next step in a deliberate move at VentureBeat toward deeper specialization: analysis built for the technical decision-makers — the directors, VPs, CIOs, and CTOs — who are evaluating, buying, and deploying enterprise AI. The enterprise AI stack is being rewritten in real time, and the decision-makers I talk with are starved for objective, defendable data. Rob Strechay has the mix of technical rigor and operating experience needed to dissect the architecture behind the next phase of enterprise AI deployment. The questions enterprise technology leaders are asking have changed. As organizations move past experimentation with generative AI toward production deployment, they want to know how to orchestrate multi-vendor environments, where the security gaps in their agentic pipelines sit, and how to fix the utilization problems draining their infrastructure budgets. Answering those questions requires more depth than news coverage alone provides, and that is the gap this research offering is built to fill. An analyst who has sat on every side of the table Strechay brings nearly three decades of experience as a practitioner, product executive, and industry analyst. Before becoming an analyst, he was an executive at numerous startups, including Zerto; he joined Amazon Web Services to help build a new analytics service; and he held executive roles across enterprise infrastructure. He later served as a senior analyst at Enterprise Strategy Group and most recently as managing director and principal analyst at theCUBE Research and SiliconANGLE, where he hosted executive interviews and analyzed the evolution of cloud, data, and AI infrastructure. Strechay will initially focus his coverage on cloud infrastructure, advanced data infrastructure, platform engineering and DevOps orchestration and observability, and the intersection points where AI and enterprise security collide. Already at work: GPU utilization and the VB Pulse surveys Strechay has already been contributing to VentureBeat’s research. In May he published an analysis of enterprise GPU utilization, examining the compute waste sitting inside enterprise AI infrastructure, and he provided a substantive review of our AI Infrastructure & Compute survey before it went into the field. His infrastructure-level focus complements the research engine VentureBeat has built around its monthly VB Pulse surveys, which track five areas of enterprise AI adoption: agentic orchestration, agent reliability and evals, agentic security and identity, AI infrastructure and compute, and context layers, including retrieval-augmented generation (RAG). Our June report on agentic orchestration, drawn from a survey of 145 enterprises, found that two-thirds of those enterprises had hedged their AI model strategy rather than committing to a single provider — a posture whose value the June outage of Anthropic’s Claude models made plain. VB In Conversation: The first vehicle A core vehicle for this expanded research footprint will be a deepening of VentureBeat’s existing VB In Conversation video interview series, which Strechay will host. Rather than high-level industry overviews, the series will bring architectural blueprints, actual deployment barriers, and back-end infrastructure realities to light through in-depth technical interviews with the architects and product leaders behind leading enterprise AI systems — an unvarnished look at which tools perform under production-grade pressure. “VentureBeat has built an audience of enterprise builders and technology buyers that any analyst would want to serve,” Strechay said. “My goal is to use deep empirical metrics and VentureBeat’s proprietary tracking data to help enterprise buyers and the people building for them make sound platform and infrastructure decisions during the most disruptive transition enterprise technology has seen.” The expanded VB In Conversation series will appear on VentureBeat and on VentureBeat’s YouTube channel, alongside Rob’s written analysis on the site. Enterprise practitioners who want to take part in our monthly VB Pulse surveys, or arrange an analyst briefing with Rob, can reach the research team here.

VentureBeat names Rob Strechay as its first Lead Analyst, expanding its enterprise AI research push Leggi l'articolo »

We use cookies to improve your experience and performance on our website. You can learn more at Politica sulla privacy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
it_IT