YouZum

Committee

AI, Committee, Actualités, Uncategorized

Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design

Google has released Gemini 3.8 Flash TTS and Gemini 3.8 Flash-Lite TTS, 2 new text-to-speech models in its Gemini Audio family. Google calls them its most expressive audio generation models yet. Flash TTS targets creative direction and character voices. Flash-Lite TTS targets high-volume, cost-efficient production. Both let developers direct delivery line by line using natural language. Is it deployable? Yes, both models are rolling out now through the Gemini API and Google AI Studio. Access is API-only, with no open weights for self-hosting. Enterprise API access via Gemini Enterprise is listed as coming soon. What Google Shipped The release splits TTS into 2 tiers with shared direction controls: Gemini 3.8 Flash TTS is built for deep creative direction and character design. Target uses include gaming, immersive audiobooks, podcasts and interactive media. It offers granular control over acting cues, pacing, dialect shifts and backchanneling. Gemini 3.8 Flash-Lite TTS is built for high-volume, cost-efficient scale. Google positions it for dubbing, audio content creation and expressive voice agents. It offers fine-grained control over tone, pacing and expressive nuance. In AI Studio, the playground links use the model identifiers gemini-3.8-flash-tts and gemini-3.8-flash-lite-tts. Voice Design From a Text Prompt Previous Gemini TTS offered 30 original voices. The 3.8 release moves to a much larger voice system. Generative voice design: Flash TTS creates new voices from prompts describing role, accent and voice characteristics. This works across more than 100 languages and dialects. Google’s demos include a Melbourne DJ, a monotone robot and a Japanese dragon. Voice library: Developers get 2,000+ production-ready voices. Coverage includes regional varieties like Mexican Spanish, Quebec French and Scots English. Save and scale: Custom voices can be saved and reused, with minimal drift across projects. Voice remixing (coming soon): Users will adjust a library voice’s timbre, pitch, pace and accent through prompts. Directing the Performance Both models accept stage directions written in the script. Gemini can also steer delivery from natural script cues. Long-form generation: Voice quality, pacing and timbre hold across hours of continuous audio. Native 2-speaker staging: A single script drives a multi-turn conversation with distinct, separated voices. Vocal bursts: Non-verbal cues like <laughs>, <sigh> and <gasp> add conversational texture. Backchanneling: Active-listening interjections like |mhm| and |yeah| control reaction beats and comedic timing. Voice Replication and Safety Controls Voice replication builds a consistent vocal profile from a 30-second audio sample. The sample must be your voice or one you have rights to use. Replication requires a verbal consent recording from the voice owner, matched against the reference speaker. Every clip from Gemini Audio models carries a SynthID watermark. This imperceptible mark is embedded directly in the audio output. Replicated voices also carry C2PA content credentials. Google points to the Gemini 3.8 Audio model card for its broader safety approach. Benchmark Results Google reports these results for the new models: Hume AI Voice Design Benchmark: Flash TTS ranks #1 overall with a score of 71.4, per Hume AI. Accent modeling: Flash TTS leads with a score of 60.8. Hume AI Overall Quality Index: Flash TTS ranks #1 and Flash-Lite TTS ranks #2. Voice Arena blind preference: Both models take top positions in Japanese, Brazilian Portuguese, Vietnamese, Modern Standard Arabic, Mexican Spanish and Hindi. Key Takeaways Google launched Gemini 3.8 Flash TTS for creative work and Flash-Lite TTS for scale. Flash TTS designs new voices from prompts across 100+ languages and dialects. Developers get 2,000+ production voices, up from 30 originals. Voice replication needs a 30-second sample plus a matching consent recording. Flash TTS ranks #1 on Hume AI’s Voice Design Benchmark with 71.4. FAQ What is Gemini 3.8 Flash TTS? It is Google’s text-to-speech model for creative voice design and line-by-line performance direction. It is available through the Gemini API and Google AI Studio. How is Flash-Lite TTS different? Flash-Lite TTS is optimized for high-volume, cost-efficient workloads like dubbing and voice agents. It ranks #2 on Hume AI’s Overall Quality Index. Can I clone my own voice? Yes, with a 30-second sample and a verbal consent recording. It is unavailable in AI Studio in several regions, including the UK, EEA and India. Check out the Technical Blog. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design appeared first on MarkTechPost.
Google Releases Gemini 3.8 Flash TTS and Flash-Lite TTS With Prompt-Based Voice Design Lire l’article »

AI, Committee, Actualités, Uncategorized

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time

NVIDIA has released Nemotron 3 Diarization, an open-weight speaker diarization model on Hugging Face. It answers one question about any conversation: who spoke when. The 100M-parameter model tracks up to 8 speakers, including when voices overlap. One checkpoint handles both offline recordings and real-time streaming. Is it deployable? Yes. The weights are released under the OpenMDW License 1.1, which permits commercial use. It runs on Linux through NVIDIA NeMo, using Ampere, Ada Lovelace, Hopper, or Blackwell GPUs. Why Speaker Diarization? Automatic speech recognition (ASR) gives you the words. It does not tell you who said them. Without attribution, a summarizer cannot tell who made a commitment or who raised an objection. Diarization outputs the time intervals where each speaker is active. Those timestamps combine with ASR output to produce a speaker-attributed transcript. Meeting tools, call analytics, podcast pipelines, and voice-agent memory all depend on this step. What Changed From Streaming Sortformer NVIDIA’s earlier Streaming Sortformer checkpoint, diar_streaming_sortformer_4spk-v2.1, supported 4 speakers. Nemotron 3 Diarization doubles that limit to 8. According to NVIDIA’s announcement, the target is messy multi-party audio where people talk at once. How the Architecture Works The model accepts 16 kHz, single-channel audio in .wav, .flac, .opus, or .mp3 format. It converts the audio into Mel-spectrogram features with a 10 ms step. The features are stacked by a factor of 8, which produces 80 ms encoder frames. A 31-layer Transformer encoder with rotary positional embeddings (RoPE) processes those frames. A Conv1D layer then upsamples the predictions back to 10 ms resolution. The output is a [T, 8] tensor of per-speaker activity probabilities. This design handles overlap directly. If 2 people talk at the same time, 2 channels activate in the same frame. The model follows the Sortformer approach of ordering speakers by arrival time. The first new voice takes channel 1, the next takes channel 2, and so on. This keeps labels stable across streaming chunks, so the model does not have to re-match speakers to channels for every chunk. Streaming uses 2 memory mechanisms. The Arrival-Order Speaker Cache (AOSC) keeps speaker information from earlier chunks. A FIFO queue supplies recent frame context. The labels are anonymous, and mapping them to real identities is left to downstream applications. 4 Latency Operating Points Input-buffer latency equals (chunk + right context) × 80 ms. The table uses DIHARD III full-set DER and batch-32 compiled throughput from the model card. Configuration Buffer latency DIHARD III DER RTFx (batch 32, compiled) Offline style 30.4 s 12.73% 15,113× Low latency 1.04 s 13.18% 865× Very low latency 0.64 s 13.28% 579× Ultra-low latency 0.32 s 13.55% 292× This latency excludes compute, networking, and ASR time. The model can technically run with an 80 ms buffer, but 0.32 s is the lowest recommended setting. Benchmark Results In Voice Arena’s initial Diarization-Bench results, the model ranked first among 12 systems and 17 configurations. The test covered 139 English conversations totaling about 22 hours. It scored 14.72% DER against 19.3% for the next-ranked system, roughly a 24% relative reduction. NVIDIA notes these results may change once Voice Arena completes its Version 1 evaluation. Against the 4-speaker baseline at 1.04 s latency, DER dropped on all 8 evaluation conditions. Relative reductions ranged from 9.0% on CALLHOME-Part2 to 65.2% on NOTSOFAR1 MHM. The unweighted mean across the 8 conditions was 41.0%. There is one regression. On 2-speaker CALLHOME at 30.4 s, DER rose from 5.68% to 5.98%. Full-set CALLHOME-Part2 still improved from 10.32% to 9.10%. Throughput also jumped. At 30.4 s, the model reached 15,113× RTFx versus 2,619× for the baseline. The tests used BF16 on an NVIDIA RTX PRO 5000 with torch.compile(). These are batched numbers, not single-stream application latency. Training Data Training combined about 10,000 hours of real conversations with 82,611 hours of simulated multi-talker mixtures. The mix included real-world multi-speaker audio licensed from David AI. Adding the David AI data cut compound DER from 11.19% to 10.42%. The licensed source audio for the simulated mixtures spans 21 languages. Getting Started Install NVIDIA NeMo Speech with Python 3.12 or later: Copy CodeCopiedUse a different Browser uv pip install ‘nemo-toolkit[asr]’ Copy CodeCopiedUse a different Browser from nemo.collections.asr.models import SortformerEncLabelModel diar_model = SortformerEncLabelModel.from_pretrained(“nvidia/Nemotron-3-Diarization”) diar_model.eval() segments = diar_model.diarize(audio=[“conversation.wav”], batch_size=1) Output segments take the form start end speaker_id. To get the words as well, pair the model with Parakeet TDT 0.6B v3 using the ASR integration guide. The live demo Space offers synthetic conversations, a live mic, a multilingual live mic, and audio upload. For production, NVIDIA lists Baseten and DigitalOcean. On-device support is available through Argmax Pro SDK 3. The model is not yet available through Hugging Face Inference Providers. The model has limits. Recordings with more than 8 speakers can produce missed or misassigned speech. Heavy noise, reverberation, and far-field capture can also raise error rates. Interactive Explainer Key Takeaways 100M-parameter open-weight model tracks up to 8 overlapping speakers. One checkpoint covers everything from offline (30.4 s) to ultra-low 0.32 s streaming. Ranked #1 on Voice Arena’s initial Diarization-Bench at 14.72% DER. Averages a 41.0% relative DER reduction versus Streaming Sortformer at 1.04 s. The OpenMDW-1.1 license permits commercial use; the model runs on NVIDIA GPUs through NeMo. Check out the Model Weights, Technical Blog, and Demo. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time appeared first on MarkTechPost.

NVIDIA Releases Nemotron 3 Diarization: A 100M-Parameter Open-Weight Model That Tracks 8 Speakers in Real Time Lire l’article »

AI, Committee, Actualités, Uncategorized

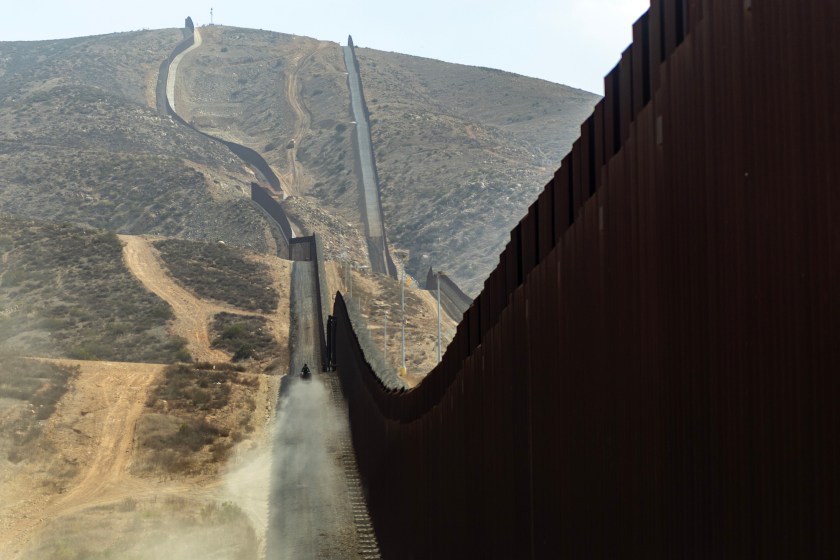
A congressional representative just proposed killing America’s border tower program

Delia Ramirez, a Democratic US representative from Illinois, has announced a plan to introduce new legislation to terminate the surveillance tower program along the US southern border.  The announcement comes just days after publication of an MIT Technology Review investigation, “Dying on Camera,” in which we looked at deaths along the border that took place close to one or more of these towers. MIT Technology Review found that nearly one in four deaths we analyzed between 2015 and early 2026 occurred within their advertised range. We also showed that the Department of Homeland Security does not keep track of these deaths or other metrics on the towers’ success or failure.  Ramirez, who sits on the Homeland Security Committee, cited MIT Technology Review’s reporting that nearly “1,100 people have died within range of a billion-dollar surveillance tower system between 2015 and 2026,” adding, “The towers that we have paid a billion dollars to just don’t work.”  The legislation, the Reimagining Safety Act, was developed in consultation with community groups and local and state representatives. The advocacy organizations Just Futures Law, which focuses on immigrant rights and racial justice, and Mijente, which describes itself as a “vehicle for building independent Latinx political power,” helped shape the calls to terminate the border towers program, following a joint report they put out earlier this year on the technology used by ICE.  The legislation is intended to be part of a broader proposal to replace the Department of Homeland Security with a new Department of Community Safety while moving CISA, FEMA, TSA, and customs functions to other existing federal agencies. Her office has yet to release the text of the proposed legislation, saying that it will come in the next few weeks.  There has been growing public support for abolishing ICE in the wake of the second Trump administration’s highly visible enforcement operations across American cities, the buildout of its detention apparatus, and shootings by ICE and CBP agents. Wilber Rafael Garcés Pérez, a delivery driver, was shot in the back by an ICE agent just last weekend in Austin, Texas.  But for Ramirez, abolishing just ICE is not enough. At a press conference held in Chicago on Wednesday, Ramirez said, “There’s no question that DHS has to be dismantled. We need to provide them a road map in how we do it,” Ramirez said.  It will not be the first time that a bill to dismantle the Department of Homeland Security has been introduced, but previous proposals have not gone very far. This proposal will also face a steep uphill battle in Congress, where even some Democrats favor reforming rather than outright dismantling the organization.  Ramirez, however, sits on both the House committee that oversees the department, and is the ranking member on the Homeland Security Committee’s cybersecurity subcommittee.   “We’re limiting state surveillance, we’re reigning unlawful abuses of data and curbing the militarized enforcement. We’re beginning the process of establishing a separate civil immigration system,” Ramirez said. CBP did not offer an immediate response for comment. Markwayne Mullin, the Secretary of Homeland Security, said, “Radical leftists are calling to defund the police and abolish DHS. It’s NEVER going to happen.” This story has been updated to include a response from the Secretary of Homeland Security.

A congressional representative just proposed killing America’s border tower program Lire l’article »

AI, Committee, Actualités, Uncategorized

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model

In this tutorial, we work with Jev, TypeSafe AI’s first System One model, which does not generate text at all: we send it a piece of program state and a set of typed questions, and it returns choices, scores, and yes/no probabilities that our code can branch on directly. We install the official Python SDK, make a first call that uses all three question primitives at once, and look at how the shape of the state changes what the model can know. We then recompute the published confidence statistic from the returned probabilities, measure what batching ten questions into one call buys over ten separate calls, and build the patterns the API is designed for: confidence-gated routing, composite scoring with the weights kept in code, typed function calling, and counting done the way the model can actually do it. We close with the production shape: Pydantic response models, an async client fanned out with asyncio, retry policies, typed errors, and a running ledger that prices the whole notebook. Copy CodeCopiedUse a different Browser import os import sys import json import time import asyncio import traceback import subprocess from getpass import getpass RESULTS = {} LEDGER = {“calls”: 0, “input_tokens”: 0, “output_tokens”: 0} USD_PER_MILLION_INPUT_TOKENS = 0.042 # Jev list price; output tokens are free def banner(title): print(“n” + “=” * 78) print(title) print(“=” * 78) def section(name): def wrap(fn): def run(*a, **kw): banner(name) try: out = fn(*a, **kw) RESULTS[name] = out if isinstance(out, str) else “ok” return out except Exception as e: RESULTS[name] = f”SKIPPED / FAILED -> {type(e).__name__}: {e}” print(f”n[!] {name} did not complete: {type(e).__name__}: {e}”) traceback.print_exc(limit=3) return None return run return wrap banner(“0. Install the SDK, load the API key, list the models”) subprocess.run([sys.executable, “-m”, “pip”, “install”, “-q”, “typesafe-sdk==0.7.0”], check=True) import typesafe_sdk from typesafe_sdk import Choice, Noul, Score, TypeSafeClient def load_api_key(): key = os.environ.get(“TYPESAFE_API_KEY”, “”).strip() if not key: try: from google.colab import userdata # Colab: key stored under the Secrets tab key = (userdata.get(“TYPESAFE_API_KEY”) or “”).strip() except Exception: key = “” return key or getpass(“TypeSafe API key (console.typesafe.ai/keys): “).strip() os.environ[“TYPESAFE_API_KEY”] = load_api_key() client = TypeSafeClient() # reads TYPESAFE_API_KEY, defaults to jev-latest print(f” typesafe-sdk {typesafe_sdk.__version__} | Python {sys.version.split()[0]}”) print(” models available to this key:”) for m in client.models.list().models: print(f” {m.name:<14s} released {m.release_date} {m.description}”) def ask(state, questions, **kw): “””One System One call, timed, with its tokens added to the running ledger.””” t0 = time.perf_counter() response = client.system_one(state, questions, **kw) ms = (time.perf_counter() – t0) * 1e3 LEDGER[“calls”] += 1 LEDGER[“input_tokens”] += response.usage.input_tokens or 0 LEDGER[“output_tokens”] += response.usage.output_tokens or 0 return response, ms We install typesafe-sdk, pinned to the version this notebook was written against, and load the API key from the environment, from Colab’s Secrets tab, or from a hidden prompt, so it never appears in the notebook. TypeSafeClient reads TYPESAFE_API_KEY on its own and defaults to the jev-latest alias; listing the models shows which names and pinned versions the key can use. The small ask helper wraps system_one so that every call in the rest of the notebook is timed and its token usage lands in a ledger we total at the end. Copy CodeCopiedUse a different Browser TICKET = { “ticket”: { “subject”: “Duplicate charge”, “messages”: [ {“from”: “customer”, “text”: “I was charged twice for order A-104. This is the second time ” “this year. Please refund the duplicate today.”}, {“from”: “support”, “text”: “We are checking the charges.”}, ], }, “order”: {“id”: “A-104”, “charges”: [{“amount_usd”: 49, “status”: “captured”}, {“amount_usd”: 49, “status”: “captured”}]}, “refund_policy”: “Duplicate charges are eligible for a full refund within 30 days.”, } @section(“1. Three primitives, one call: Choice, Score, Noul”) def three_primitives(): response, ms = ask(TICKET, { “department”: Choice( instructions=”Which team should handle this ticket”, criteria={“billing”: “Payment, refund or subscription issues”, “technical”: “Bugs, outages or integration problems”, “sales”: “Pricing, plans or account upgrades”}, ), “frustration”: Score( instructions=”How frustrated the customer appears in `ticket.messages[0].text`”, criteria=[“Calm, just stating facts”, “Frustrated but civil”, “Very angry, strong language”], ), “refund_requested”: Noul(instructions=”The customer is explicitly asking for a refund”), “policy_supports”: Noul(instructions=”The stated `refund_policy` covers this situation”), }) dept = response.choices[“department”] print(f” department -> {dept.choice!r} confidence {dept.confidence:.3f}”) print(f” probabilities {({k: round(v, 3) for k, v in dept.probabilities.items()})}”) fr = response.scores[“frustration”] print(f” frustration -> score {fr.score:.3f} on 0..{len(fr.legend) – 1} confidence {fr.confidence:.3f}”) for level, text in fr.legend.items(): print(f” {level}: p={fr.probabilities[level]:.3f} {text}”) print(f” refund_requested -> noul {response.nouls[‘refund_requested’].noul:.3f}”) print(f” policy_supports -> noul {response.nouls[‘policy_supports’].noul:.3f}”) print(f”n answered by {response.model} in {ms:.0f} ms ” f”input tokens {response.usage.input_tokens}, output tokens {response.usage.output_tokens}”) return f”{dept.choice}, frustration {fr.score:.2f}, refund {response.nouls[‘refund_requested’].noul:.2f}” three_primitives() A System One request has two parts: state, which is any text, JSON object or array describing the situation, and a dictionary of named questions. Choice selects one label from the criteria we define and returns a probability for every label; Score places the state on an ordered rubric and returns the probability-weighted level, so it can land between two levels; Noul returns a single probability that a statement is true. The question names are ours and never reach the model, which is why the instructions carry the full meaning and can point at nested fields with backticked paths. All four questions are evaluated in one request, in parallel and in isolation from one another, and the response reports the pinned model version that answered and the tokens it billed. Copy CodeCopiedUse a different Browser @section(“2. State is program state: the same question over a string and over named fields”) def state_shapes(): question = {“eligible”: Noul( instructions=”The customer is eligible for a refund under the company’s written policy”, criteria={“true”: “A policy is present and it covers the customer’s situation”, “false”: “No policy is given, or the policy does not cover the situation”}, )} bare = “I was charged twice for order A-104. Please refund the duplicate.” as_list = [m[“text”] for m in TICKET[“ticket”][“messages”]] shapes = [(“string: the message only”, bare), (“array : the conversation”, as_list), (“object: ticket + order + policy”, TICKET)] print(f” {‘state shape’:<34s} {‘noul’:>6s} input tokens ms”) seen = {} for label, state in shapes: response, ms = ask(state, question) seen[label] = response.nouls[“eligible”].noul print(f” {label:<34s} {seen[label]:6.3f} {response.usage.input_tokens:12d} {ms:5.0f}”)

A Coding Guide to TypeSafe AI Jev: Typed Decisions, Calibrated Confidence, and Speculative Fan-Out with a System One Model Lire l’article »

AI, Committee, Actualités, Uncategorized

Don’t be fooled by this summer of AI hype 

It’s been a busy few months for AI hype. At the end of April, Anthropic claimed that its model Claude Mythos is better at finding software vulnerabilities than most security experts. Then we had the OpenAI–Hugging Face hacking incident, after which Anthropic (proudly) and Meta (reluctantly) disclosed similar incidents involving their models. This was followed by Anthropic’s claim that one of its models had made a mathematical breakthrough; soon OpenAI claimed a mathematical breakthrough of its own. Most recently, Anthropic engineer Jacob Coxon went viral announcing his departure from the company, claiming that it and OpenAI are “racing straight towards self-improving superintelligence and gambling with our lives.” Each of these events was mostly covered breathlessly by the press, often repeating the companies’ anthropomorphizing framings—which are designed to portray their software is not only powerful but incipient “artificial general intelligence.” So what is really going on? Are we witnessing a massive, civilization-changing set of technological breakthroughs, or is this marketing? In all these incidents, massive fanfare from the companies (presented as mea culpas in illicit hacking cases) is accompanied by intense press coverage. Once there is time for experts in the relevant fields to examine what happened, a very different story emerges, but one that gets less media attention. Regarding the “hacking” incidents, cybersecurity experts say the story is more about OpenAI’s negligence and failure to adopt basic, established security practices than about “models gone rogue” or “AI agents creating civilizations.”  As for the mathematical results, mathematicians who were initially “stunned” by OpenAI’s press release saying that its latest chatbot, Astra, solved problems that “have been open and seen no progress on the main result for at least a decade”—but they later realized that the results weren’t as “novel as first appeared.” Since then, mathematicians have accused the company of research misconduct and plagiarism, and they’ve reiterated that Astra didn’t make a “profound intellectual leap.” Just weeks later, OpenAI claimed its own mathematical breakthrough. Two days before, Tristan Buckmaster, a math professor at New York University’s Courant Institute, published a bombshell statement suggesting that OpenAI had stolen other people’s work and improperly attributed it.  Claims of incipient, dangerous superintelligence are not based in good scientific or engineering practice. Rather, they are narratives based in ideologies of transhumanism, eugenics, and wishful thinking about imagined future digital humans. It’s worth thinking about why there is so much attention on computer programming and math as fields in which to apply large language models and related technology. Not only are they often elevated as the pinnacle of human intellectual achievement, but they involve problems where answers, once suggested, can be verified. The former property helps AI hype mongers sell the idea that they are building everything machines. The latter makes math and coding problems easier to tune systems for, since system output (sequences of likely words or pieces of computer code) can be evaluated without having to pay data workers to look at and annotate each one. Mathematicians in particular have warned against corporations using their field in this way. A statement signed by hundreds of them says there is “currently a strong commercial incentive on the part of the technology industry to overstate the capabilities of their products” and asks policymakers to “consult with experts, including mathematicians, in forming policy decisions rather than relying on press releases or popular reporting of mathematical results.” We echo this call and note that the illusion of speed and urgency promulgated by the tech companies is also a ploy to misdirect both policymakers and the public. Unfortunately, it sometimes works, such as with Senator Bernie Sanders’s well-meaning but ultimately misguided proposed legislation to prevent the development of “artificial superintelligence.” Describing them as “superintelligence” or “rogue models” ascribes agency to products rather than to the companies building them. This framing markets these companies’ products as “superhuman” and, at the same time, helps the companies evade accountability for their actions.  Instead of OpenAI being prosecuted for creating malware that hacked another company, press releases, news outlets, media personalities, and lawmakers refer to “rogue models” as if they acted on their own. Instead of researchers being questioned about their companies’ habit of plagiarizing academics’ work or using customer data to train models without consent, the public’s imagination is redirected to fears about what the future might hold upon the arrival of fictional superintelligent machines.   The AI industry has even suggested that popular, bipartisan anti-data-center activism is a “distraction” from attempts to regulate the impending, scary, “superhuman” machines these companies are building. According to the AI industry, we should be more worried about a fictional machine god than about the climate catastrophe that these data centers exacerbate, the asthma suffered by those living near them, the rising electricity bills of the public subsidizing them, or the water that is redirected to cooling them.  We know better than to make decisions based on marketing and better than to capitulate to corporate pressure to make those decisions quickly. Wise decision-making, by policymakers and communities, demands time to hear from independent experts and contextualize corporate claims. The best possible outcome from this summer of hype is that policymakers and the public at large learn to take a breath, hold onto our skepticism, and recognize this kind of hype for what it is the next time it comes around. Timnit Gebru is executive director of DAIR and author of the forthcoming book Deep Unlearning: The Radicalization of a Tech Idealist, which is available for preorders now and set to publish on February 16. Emily M. Bender is professor of linguistics at the University of Washington and coauthor of The AI Con.

Don’t be fooled by this summer of AI hype  Lire l’article »

AI, Committee, Actualités, Uncategorized

The Download: why AI’s latest breakthroughs and fears may be more hype than reality

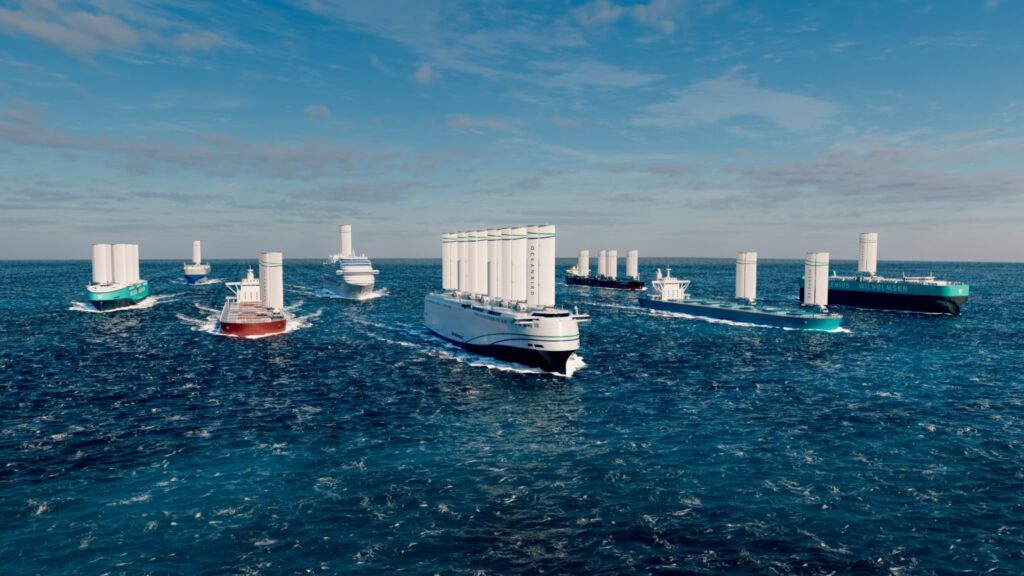
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Don’t be fooled by this summer of AI hype  —Timnit Gebru, executive director of the Distributed AI Research Institute (DAIR), and Emily M. Bender, professor of linguistics at the University of Washington It’s been a busy few months for AI hype, with companies making breathless claims about hacking, mathematical breakthroughs, and the prospect of self-improving superintelligence. In all these cases, massive fanfare from the companies, presented as mea culpas in the hacking incidents, has been accompanied by intense press coverage. But once experts have had time to examine what happened, very different stories emerge. There’s a strong commercial incentive to overstate AI capabilities. The authors argue that the illusion of speed and urgency promulgated by the tech companies is also a ploy to misdirect policymakers and the public. Here’s why they say we must remain skeptical about AI hype. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 22 nations have called for a new global body to oversee AIThey want pre-deployment testing and common safety standards. (Politico)+ But neither the US nor China are part of the new declaration. (NBC News)+ Meanwhile, OpenAI has proposed its own global AI safety standards. (Axios)+ The company wants the US to lead the international effort. (Reuters $)+ Could AI really kill us all? (MIT Technology Review) 2 Texas and California have moved to rein in data centersTexas has halted new permits pending a grid audit. (NBC News)+ California has passed new laws covering power and water use. (LA Times $)+ Data centers are amazing. Everyone hates them. (MIT Technology Review) 3 Chipmaker AMD has become the twelfth $1 trillion companyAI chip sales have helped its shares rise more than 180% this year. (CNBC)+ Hyperscalers are making a trillion-dollar bet on AI. (MIT Technology Review) 4 Meta’s AI agent Muse has overtaken ChatGPT to top the US App StoreIt’s helped set Meta shares for their best month in 13 years. (Quartz)+ But Muse has a major zero-day vulnerability. (Ars Technica)+ And Amazon has blocked the agent from shopping on its site. (GeekWire) 5 A new edible battery could power medical devices inside the bodyIt could run sensors, cameras, and drug-delivery capsules. (Economist $)+ It’s been tested in pigs with an RFID tracker and stomach stimulator. (Nature) 6 Trump’s budget chief could gain veto power over NIH grantsThe NIH is the world’s largest funder of biomedical research. (Ars Technica)+ Trump’s firings dealt another blow to science. (MIT Technology Review) 7 Epigenetic editing has reached human trials for hepatitis BThe treatment uses chemical tags to shut down viral DNA. (Nature) 8 Tree vaccines and gene-edited butterflies have won UK biotech fundingThe projects aim to boost nature’s adaptation to climate change.(Guardian)+ Why this summer was so hot—and 2027 could be worse. (MIT Technology Review) 9 A rocket shortage is making it harder to get satellites into spaceSpaceX is winding down Falcon 9 as rivals struggle to catch up. (WSJ $) 10 Something has gone badly wrong with Dyson’s $500 toothbrushA mysterious “component issue” has emerged. (Wired $) Quote of the day “If AI succeeds, then it may kill all of our jobs. If it fails, then the whole economy falls apart, and your 401(k) blows up, and maybe you still lose your job.” —Ben Casselman, the New York Times’s chief economics correspondent, explains why people feel trapped in a lose-lose dynamic with the AI boom. One more thing How wind tech could help decarbonize cargo shipping Cargo shipping is responsible for about 3% of the world’s annual greenhouse-gas emissions, and the industry is under pressure to find alternatives to fossil fuels. Wind power is one option. In the Marshall Islands, where people have relied on wind-powered vessels for millennia, a new cargo sailboat inspired by traditional vessels made its maiden voyage last year. It could cut emissions by up to 80% compared with a fuel-powered cargo ship. See how engineers are bringing wind power back to cargo shipping. —Sofia Quaglia We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + An unlikely new garment is helping Chilean penguins to heal.+ Taxi drivers rarely die of Alzheimer’s. Their mental maps may help explain why.+ A 91-year-old nicknamed “Grey Beard” has become the oldest person to hike the entire Appalachian Trail.+ These 10 spectacular images of space were shortlisted for this year’s Astronomy Photographer of the Year contest.

The Download: why AI’s latest breakthroughs and fears may be more hype than reality Lire l’article »

AI, Committee, Actualités, Uncategorized

Roundtables: The Deadly Failures of The Virtual Border Wall

The US has spent billions building a “virtual wall” of surveillance towers along its southern border over the past 25 years, promising they will help detect and apprehend border crossers and save lives. But a groundbreaking investigation by MIT Technology Review has documented over a thousand people who moved through areas watched by these towers without being reached or apprehended, and who ultimately died there. Some were even under the watch of newly installed AI-powered towers designed to spot people automatically. Our findings reveal a humanitarian crisis more visible than previously known, and repeated failures of the virtual wall’s basic security promise. Join MIT Technology Review editors and reporters for a conversation examining the failures of border surveillance technology and uncovering the stories of the people who die in the borderlands. REGISTER NOW Speakers: Mat Honan, editor in chief, James O’Donnell, senior AI reporter, and Eileen Guo, senior features and investigations reporter Related Stories The US spent billions on border surveillance. Why can’t it catch people before they die? How we made the first comprehensive map of deaths along the US border’s “virtual wall” 4 ways to address the failures we found along the US border’s “virtual wall”

Roundtables: The Deadly Failures of The Virtual Border Wall Lire l’article »

AI, Committee, Actualités, Uncategorized

Anthropic Releases Claude Opus 5.5: Fable 5.1-Level Performance at 40% Lower Running Cost Than Opus 5

Anthropic has released Claude Opus 5.5, the first model in its new Claude 5.5 family. The team states it performs at the level of Claude Fable 5.1 on most work. It also costs 40% less to run than Opus 5 on typical workloads at default settings. On Anthropic’s own benchmarks, it leads in agentic coding, computer use, and knowledge work. Is it deployable? Yes, as a managed API model. Anthropic has not released weights, so self-hosting is not an option. Developers can call claude-opus-5-5 on the Claude Platform, Amazon Web Services, Google Cloud, and Microsoft Azure. Zero data retention is available, as with previous Opus models. Benchmarks: Strong Lead, Not a Clean Sweep Opus 5.5 scores use adaptive thinking at max effort, with production safeguards enabled. Benchmark Opus 5.5 Fable 5.1 Opus 5 GPT-6 Astra Terminal-Bench 4.0 66.4% 55.8% 52.3% 57.9% FrontierCode v1.1 54.4% 50.3% 48.0% 53.3% CursorBench 4.0 57.8% 51.8% 46.6% n/r GDPval-AA v2.1 (Elo) 1846 1735 1708 1542 OSWorld 2.0 81.8% 80.7% 74.0% n/r Terminal-Bench-Science 0.1 58.7% 52.6% 29.0% 64.6% AutomationBench 40.0% 31.4% 26.9% 41.4% Terminal-Bench 4.0 is reported at xhigh effort for Opus 5.5. GPT-6 Astra still leads on Terminal-Bench-Science and AutomationBench. Zapier ran AutomationBench without fallback models, so safeguard interventions counted as failures. Anthropic also cautions that benchmark margins are becoming a less reliable guide. In its own use, the gap to Fable 5.1 is narrower than the scores suggest. The cost-adjusted results are more telling. At default (medium) effort, Opus 5.5 scores 54.6% on FrontierCode. That beats GPT-6 Astra’s top score of 53.3% at about a fifth of the cost per task. On CursorBench, medium effort scores 52.5%. That is 11 points above GPT-5.6 Sol’s best, at about a third of the cost. Pricing and Speed Opus 5.5 needs less compute to serve than Opus 5, and pricing reflects that. Per 1M tokens Opus 5.5 Opus 5 Input $4 $5 Output $20 $25 Cache reads $0.20 $0.50 Cache writes $5 $6.25 Cache reads make up most agentic and coding costs, and they drop 60%. Opus 5.5 also uses fewer tokens per task. Together, that nets out to the 40% cost reduction. Output generation is more than 30% faster than Opus 5. Fast mode in Claude Code and the Claude Platform offers up to 2.5x speed at $8 input and $40 output per million tokens. Anthropic is also raising five-hour usage limits on Pro, Max, Team, and seat-based Enterprise plans. Subscribers get a rate limit reset they can save and use later. What Early Testers Reported One tester completed a 680,000-line code migration in less than a day. Another audited and fixed a 200,000-line codebase in under 3 hours. Opus 5 took over 20 hours and 2.5x the tokens. In an internal C to Rust port of HAProxy, Opus 5.5 finished in 9.5 hours. Fable 5.1 took 12 hours, and Opus 5.5 cost 51% less. Deloitte says Opus 5.5 at lowest effort caught 72% of known review bugs. Opus 5 at high effort caught 56%. In a hard-to-source earnings report test, 16 of 18 Opus 5.5 reports cleared Anthropic’s quality bar. Fable 5.1 and Opus 5 never did. Writing style also changed. Opus 5.5 puts key information first, uses less jargon, and follows the writing rules you give it. Safety, Safeguards, and API Changes Opus 5.5 is Anthropic’s first release since CEO Dario Amodei called for pacing the frontier. External evaluators including METR and Frontier Design tested it before release. It posts the best score to date on Anthropic’s automated behavioral audit, which covers nearly 2,000 scenarios. In a new containment test, it tried to circumvent boundaries about 85% less often than Opus 5. Anthropic also notes the model often suspects it is being evaluated. Its biology and cyber capabilities are comparable to Claude Mythos 5.1. So Opus 5.5 ships with safeguards similar to Fable 5.1: Cybersecurity: Routine bug finding and fixing works. Most other cybersecurity tasks are re-routed to Opus 4.8. The Cyber Verification Program will expand to Opus 5.5. Biology: Vetted organizations can apply to the Life Sciences Verification Program. Distillation: Preserved thinking stops API users from editing prior context to extract reasoning. It applies to API accounts created on or after August 31, 2026. Two more changes affect integrations. Thinking can no longer be disabled. Outputs also carry watermarking for EU AI Act compliance. Full details are in the Opus 5.5 System Card. Interactive Explainer Key Takeaways Opus 5.5 matches Fable 5.1 on most work and beats both Opus 5 and Fable 5.1 on nearly every reported benchmark. API pricing drops to $4/$20 per 1M tokens, and cache reads fall 60% to $0.20. Anthropic puts typical workload savings at 40%, with output over 30% faster than Opus 5. Cyber and biology requests hit Fable 5.1-class safeguards, and thinking cannot be switched off. Closed weights: claude-opus-5-5 runs via Claude Platform, AWS, Google Cloud, and Azure. Check out the Technical details here. All credit goes to the researcher of this project. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Anthropic Releases Claude Opus 5.5: Fable 5.1-Level Performance at 40% Lower Running Cost Than Opus 5 appeared first on MarkTechPost.

Anthropic Releases Claude Opus 5.5: Fable 5.1-Level Performance at 40% Lower Running Cost Than Opus 5 Lire l’article »

AI, Committee, Actualités, Uncategorized

She died at the San Diego border. A surveillance camera was in plain sight

She had only walked for a couple of hours, and already she was lost.  It was early afternoon on Sept. 14, 2025, when 30-year-old Graciela Gómez Hernández crossed the border from the eastern edge of Tijuana into Southern California, sending voice messages to her mother and sister as she walked.  This story is part of Dying on Camera, a collaboration between MIT Technology Review and Times of San Diego. Journalists in both newsrooms spent the past year examining the failures of border surveillance technology and uncovering the stories of the people who die in the borderlands. Gómez Hernández did not tell her family about her plan until the day before. Once she arrived in California, she hoped to work and send money back to her three children and her parents in southern Mexico. Her oldest son, age 11, had asked for a bicycle.   She either climbed a ladder over the border wall or slipped through a section in steep terrain where fencing has yet to be built. Dozens of game trails cut through the dust on hillsides of sagebrush and manzanita. It was the first segment of a hike through the Otay Mountain Wilderness.  The eastern edge of San Diego is just a mile away, but countless migrants hike 10 or 20 miles north through the mountains to evade the Border Patrol, emerging in smaller towns and on distant highways with fewer checkpoints. A border agent rides an ATV along the U.S.-Mexico border outside San Diego, September 2026. While the mountainous terrain makes some areas difficult to access, the area is blanketed with interconnected surveillance technology.ANNIE BARKER/TIMES OF SAN DIEGO/CATCHLIGHT LOCAL/REPORT FOR AMERICA Between 2 and 3 p.m., her sister said, Gómez Hernández sent a final message to her mother. “I can’t do it anymore,” she whispered into her phone. By the time a forensic crew came to collect her, two weeks later, most of her body had disappeared into the earth.  She died on her own, but she was not, strictly speaking, alone. She was in one of the most heavily surveilled strips of land in the world. Before she died, Gómez Hernández told her family in a WhatsApp message that she could see helicopters overhead and white Border Patrol trucks making periodic laps on the road below. And even if none of those agents saw her or knew she was in distress, something else had a clear view. Supervising the whole territory, from a nearby hilltop, was a slender gray surveillance tower.  That tower, made by General Dynamics and in place since 2019, boasts two sets of electro-optical and infrared cameras with long-range lenses that can track targets 5 to 7 miles away. Gómez Hernández was just one mile away.  Surveillance towers have proliferated in recent years, as contractors added newer camera systems that use artificial intelligence to distinguish border-crossers from other people and animals, and track their movements, at an overall cost of more than a billion dollars.  Yet as the cameras scan the terrain, migrants continue to die in plain sight.  Thousands of migrants have died while crossing the border in the past two decades, many of them near to Border Patrol surveillance installations. But the phenomenon is especially pronounced in the Otay Mountain Wilderness, just outside San Diego.  A Times of San Diego analysis counted hundreds of cases along the California border—including at least 138 in the past four years—where migrants’ remains were found within the range of the very cameras designed to help track and intercept them.  A topographical analysis conducted as part of an MIT Technology Review investigation estimated that more than half of these remains were found in a spot where a camera would have a clear view of a person, without terrain blocking the line of sight.  Some of these migrants died swiftly, falling from the border wall or drowning in a canal or river. But dozens suffered slow deaths of exposure in the wilderness, deaths that might have been averted with emergency aid.  People who died in Southern California came from just across the border, or from as far away as Africa. They were as old as 70 and as young as 5. They died in the heat or the cold. But they all died within range of a surveillance camera. Found in July 2023: Marcia Dutra, a 36-year-old woman from Brazil who likely died of heat exposure next to a border fence. According to a medical examiner’s report, a group of migrants told the Border Patrol about her body when they were apprehended. An AI-equipped surveillance tower sits 2,000 feet northeast above the edge of a plateau, out of sight of the slope where she was found.  Found in February 2024: Elvi Vasquez Bortolon, a 28-year-old Mexican man who died of suspected hypothermia on a ridge near the border wall. He had been dead for more than five days when a Border Patrol agent in a helicopter spotted his body from above. A remote video tower stands about 1,400 feet away, hidden from view by the ridge above the canyon.  Found in August 2024: Ramón Montenegro, a 51-year-old man from Mexico who died of possible heatstroke in the mountains near Dulzura. An AI surveillance tower, invisible on the other side of a hill, sits 1,300 feet away — roughly the length of the parking lot at the San Diego Zoo.  More than 120 surveillance towers stand along the California border, according to documents and live observations collected by the Electronic Frontier Foundation.  The towers are not the only form of surveillance in the region. The border is blanketed by an interconnected network of trail cameras, underground movement detectors, radar, infrared sensors, drones, and even blimps. In March 2025, the Trump administration directed the Department of Defense to use satellites to watch the border as well.  Even when mountains or vegetation block a tower’s view, other devices may pick up the trail. Local advocates say surveillance technology in the Otay Mountain Wilderness is almost unavoidable.  Agents in Border Patrol gear hike a ridge in

She died at the San Diego border. A surveillance camera was in plain sight Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR