YouZum

Committee

AI, Committee, Actualités, Uncategorized

The Download: China’s dying EV batteries, and why AI doomers are doubling down

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. China figured out how to sell EVs. Now it has to bury their batteries. In the past decade, China has seen an EV boom, thanks in part to government support. Buying an electric car has gone from a novel decision to a routine one; by late 2025, nearly 60% of new cars sold were electric or plug-in hybrids. But as the batteries in China’s first wave of EVs reach the end of their useful life, early owners are starting to retire their cars, and the country is now under pressure to figure out what to do with those aging components. The issue is putting strain on China’s still-developing battery recycling industry and has given rise to a gray market that often cuts corners on safety and environmental standards. National regulators and commercial players are also stepping in, but so far these efforts have struggled to keep pace with the flood of batteries coming off the road. Read the full story. —Caiwei Chen The AI doomers feel undeterred It’s a weird time to be an AI doomer.This small but influential community believes, in the simplest terms, that AI could get so good it could be bad—very, very bad—for humanity. The doomer crowd has had some notable success over the past several years: including helping shape AI policy coming from the Biden administration. But a number of developments over the past six months have put them on the back foot. Talk of an AI bubble has overwhelmed the discourse as tech companies continue to invest in multiple Manhattan Projects’ worth of data centers without any certainty that future demand will match what they’re building. So where does this leave the doomers? We decided to ask some of the movement’s biggest names to see if the recent setbacks and general vibe shift had altered their views. See what they had to say in our story. —Garrison Lovely This story is part of our new Hype Correction package, a collection of stories designed to help you reset your expectations about what AI makes possible—and what it doesn’t. Check out the rest of the package. Take our quiz on the year in health and biotechnology In just a couple of weeks, we’ll be bidding farewell to 2025. And what a year it has been! Artificial intelligence is being incorporated into more aspects of our lives, weight-loss drugs have expanded in scope, and there have been some real “omg” biotech stories from the fields of gene therapy, IVF, neurotech, and more. Jessica Hamzelou, our senior biotech reporter, is inviting you to put your own memory to the test. So how closely have you been paying attention this year? This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 TikTok has signed a deal to sell its US unit Its new owner will be a joint venture controlled by American investors including Oracle. (Axios)+ But the platform is adamant that its Chinese owner will retain its core US business. (FT $)+ The deal is slated to close on January 22 next year. (Bloomberg $)+ It means TikTok will sidestep a US ban—at least for now. (The Guardian) 2 A tip on Reddit helped to end the hunt for the Brown University shooterThe suspect, who has been found dead, is also suspected of killing an MIT professor. (NYT $)+ The shooter’s motivation is still unclear, police say. (WP $) 3 Tech leaders are among those captured in newly-released Epstein photosBill Gates and Google’s Sergey Brin are both in the pictures. (FT $)+ They’ve been pulled from a tranche of more than 95,000. (Wired $) 4 A Starlink satellite appears to have explodedAnd it’s now falling back to earth. (The Verge)+ On the ground in Ukraine’s largest Starlink repair shop. (MIT Technology Review) 5 YouTube has shut down two major channels that share fake movie trailersScreen Culture and KH Studio uploaded AI-generated mock trailers with over a billion views. (Deadline)+ Google is treading a thin line between embracing and shunning generative AI. (Ars Technica) 6 Trump is cracking down on investment in Chinese tech firmsLawmakers are increasingly worried that US money is bolstering the country’s surveillance state. (WSJ $)+ Meanwhile, China is working on boosting its chip output. (FT $) 7 ICE has paid an AI agent company to track down targetsIt claims to be able to rapidly trace a target’s online network. (404 Media)8 America wants to return to the Moon by 2028And to build some nuclear reactors while it’s up there. (Ars Technica)+ Southeast Asia seeks its place in space. (MIT Technology Review) 9 Actors in the UK are refusing to be scanned for AIThey’re reportedly routinely pressured to consent to creating digital likenesses of themselves. (The Guardian)+ How Meta and AI companies recruited striking actors to train AI. (MIT Technology Review) 10 Indian tutors are explaining how to use AI over WhatsAppLessons are cheap and personalized—but the teachers aren’t always credible. (Rest of World)+ How Indian health-care workers use WhatsApp to save pregnant women. (MIT Technology Review) Quote of the day “Trump wants to hand over even more control of what you watch to his billionaire buddies. Americans deserve to know if the president struck another backdoor deal for this billionaire takeover of TikTok.” —Democratic senator Elizabeth Warren queries the terms of the deal that TikTok has made to allow it to continue operating in the US in a post on Bluesky. One more thing Synthesia’s AI clones are more expressive than ever. Soon they’ll be able to talk back. —Rhiannon Williams Earlier this summer, I visited the AI company Synthesia to create a hyperrealistic AI-generated avatar of me. The company’s avatars are a decent barometer of just

The Download: China’s dying EV batteries, and why AI doomers are doubling down Lire l’article »

AI, Committee, Actualités, Uncategorized

Google Introduces T5Gemma 2: Encoder Decoder Models with Multimodal Inputs via SigLIP and 128K Context

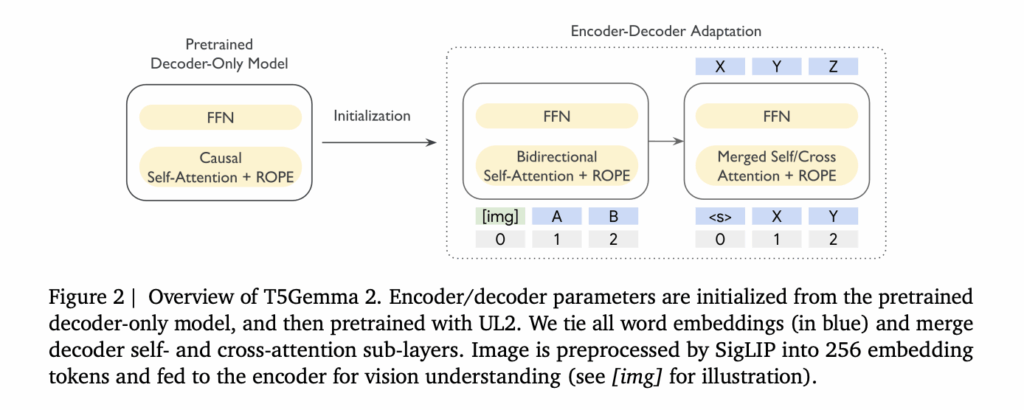
Google has released T5Gemma 2, a family of open encoder-decoder Transformer checkpoints built by adapting Gemma 3 pretrained weights into an encoder-decoder layout, then continuing pretraining with the UL2 objective. The release is pretrained only, intended for developers to post-train for specific tasks, and Google explicitly notes it is not releasing post-trained or IT checkpoints for this drop. T5Gemma 2 is positioned as an encoder-decoder counterpart to Gemma 3 that keeps the same low level building blocks, then adds 2 structural changes aimed at small model efficiency. The models inherit Gemma 3 features that matter for deployment, notably multimodality, long context up to 128K tokens, and broad multilingual coverage, with the blog stating over 140 languages. https://arxiv.org/pdf/2512.14856 What Google actually released? The release includes 3 pretrained sizes, 270M-270M, 1B-1B, and 4B-4B, where the notation means the encoder and decoder are the same size. The research team reports approximate totals excluding the vision encoder, about 370M, 1.7B, and 7B parameters. The multimodal accounting lists a 417M parameter vision encoder, along with encoder and decoder parameters broken into embedding and non embedding components. The adaptation, encoder-decoder without training from scratch T5Gemma 2 follows the same adaptation idea introduced in T5Gemma, initialize an encoder-decoder model from a decoder-only checkpoint, then adapt with UL2. In the above figure the research team show encoder and decoder parameters initialized from the pretrained decoder-only model, then pretrained with UL2, with images first converted by SigLIP into 256 tokens. This matters because encoder-decoder splits the workload, the encoder can read the full input bidirectionally, while the decoder focuses on autoregressive generation. The research team argues this separation can help long context tasks where the model must retrieve relevant evidence from a large input before generating. Two efficiency changes that are easy to miss but affect small models First, T5Gemma 2 uses tied word embeddings across encoder input embedding, decoder input embedding, and decoder output or softmax embedding. This reduces parameter redundancy, and references an ablation showing little quality change while reducing embedding parameters. Second, it introduces merged attention in the decoder. Instead of separate self-attention and cross-attention sublayers, the decoder performs a single attention operation where K and V are formed by concatenating encoder outputs and decoder states, and masking preserves causal visibility for decoder tokens. This ties to easier initialization, because it narrows differences between the adapted decoder and the original Gemma style decoder stack, and it reports parameter savings with a small average quality drop in their ablations. https://arxiv.org/pdf/2512.14856 https://arxiv.org/pdf/2512.14856 Multimodality, image understanding is encoder side, not decoder side T5Gemma 2 is multimodal by reusing Gemma 3’s vision encoder and keeping it frozen during training. Vision tokens are always fed to the encoder and encoder tokens have full visibility to each other in self attention. This is a pragmatic encoder-decoder design, the encoder fuses image tokens with text tokens into contextual representations, and the decoder can then attend to those representations while generating text. On the tooling side, T5Gemma 2 is placed under an image-text-to-text pipeline, which matches the research’s design, image in, text prompt in, text out. That pipeline example is the fastest way to validate the end to end multimodal path, including dtype choices like bfloat16 and automatic device mapping. Long context to 128K, what enables it Google researchers attributes the 128K context window to Gemma 3’s alternating local and global attention mechanism. The Gemma 3 team describes a repeating 5 to 1 pattern, 5 local sliding window attention layers followed by 1 global attention layer, with a local window size of 1024. This design reduces KV cache growth relative to making every layer global, which is one reason long context becomes feasible at smaller footprints. In the T5Gemma 2, the research team also mention adopting positional interpolation methods for long context, and they pretrain on sequences up to 16K input paired with 16K target outputs, then evaluate long context performance up to 128K on benchmarks including RULER and MRCR. The detailed pretraining results table includes 32K and 128K evaluations, showing the long context deltas they claim over Gemma 3 at the same scale. https://arxiv.org/pdf/2512.14856 Training setup and what “pretrained only” implies for users The research team states the models are pretrained on 2T tokens and describes a training setup that includes a batch size of 4.2M tokens, cosine learning rate decay with 100 warmup steps, global gradient clipping at 1.0, and checkpoint averaging over the last 5 checkpoints. Key Takeaways T5Gemma 2 is an encoder decoder family adapted from Gemma 3 and continued with UL2, it reuses Gemma 3 pretrained weights, then applies the same UL2 based adaptation recipe used in T5Gemma. Google released pretrained checkpoints only, no post trained or instruction tuned variants are included in this drop, so downstream use requires your own post training and evaluation. Multimodal input is handled by a SigLIP vision encoder that outputs 256 image tokens and stays frozen, those vision tokens go into the encoder, the decoder generates text. Two parameter efficiency changes are central, tied word embeddings share encoder, decoder, and output embeddings, merged attention unifies decoder self attention and cross attention into a single module. Long context up to 128K is enabled by Gemma 3’s interleaved attention design, a repeating 5 local sliding window layers with window size 1024 followed by 1 global layer, and T5Gemma 2 inherits this mechanism. Check out the Paper, Technical details and Model on Hugging Face. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google Introduces T5Gemma 2: Encoder Decoder Models with Multimodal Inputs via SigLIP and 128K Context appeared first on MarkTechPost.

Google Introduces T5Gemma 2: Encoder Decoder Models with Multimodal Inputs via SigLIP and 128K Context Lire l’article »

AI, Committee, Actualités, Uncategorized

How to Build a High-Performance Distributed Task Routing System Using Kombu with Topic Exchanges and Concurrent Workers

In this tutorial, we build a fully functional event-driven workflow using Kombu, treating messaging as a core architectural capability. We walk through step by step the setup of exchanges, routing keys, background workers, and concurrent producers, allowing us to observe a real distributed system. As we implement each component, we see how clean message flow, asynchronous processing, and routing patterns give us the same power that production microservices rely on every day. Check out the FULL CODES. Copy CodeCopiedUse a different Browser !pip install kombu import threading import time import logging import uuid import datetime import sys from kombu import Connection, Exchange, Queue, Producer, Consumer from kombu.mixins import ConsumerMixin logging.basicConfig( level=logging.INFO, format=’%(message)s’, handlers=[logging.StreamHandler(sys.stdout)], force=True ) logger = logging.getLogger(__name__) BROKER_URL = “memory://localhost/” We begin by installing Kombu, importing dependencies, and configuring logging so we can clearly see every message flowing through the system. We also set the in-memory broker URL, allowing us to run everything locally in Colab without needing RabbitMQ. This setup forms the foundation for our distributed messaging workflow. Check out the FULL CODES. Copy CodeCopiedUse a different Browser media_exchange = Exchange(‘media_exchange’, type=’topic’, durable=True) task_queues = [ Queue(‘video_queue’, media_exchange, routing_key=’video.#’), Queue(‘audit_queue’, media_exchange, routing_key=’#’), ] We define a topic exchange to flexibly route messages using wildcard patterns. We also create two queues: one dedicated to video-related tasks and another audit queue that listens to everything. Using topic routing, we can precisely control how messages flow across the system. Check out the FULL CODES. Copy CodeCopiedUse a different Browser class Worker(ConsumerMixin): def __init__(self, connection, queues): self.connection = connection self.queues = queues self.should_stop = False def get_consumers(self, Consumer, channel): return [ Consumer(queues=self.queues, callbacks=[self.on_message], accept=[‘json’], prefetch_count=1) ] def on_message(self, body, message): routing_key = message.delivery_info[‘routing_key’] payload_id = body.get(‘id’, ‘unknown’) logger.info(f”n RECEIVED MSG via key: [{routing_key}]”) logger.info(f” Payload ID: {payload_id}”) try: if ‘video’ in routing_key: self.process_video(body) elif ‘audit’ in routing_key: logger.info(” [Audit] Logging event…”) message.ack() logger.info(f” ACKNOWLEDGED”) except Exception as e: logger.error(f” ERROR: {e}”) def process_video(self, body): logger.info(” [Processor] Transcoding video (Simulating work…)”) time.sleep(0.5) We implement a custom worker using Kombu’s ConsumerMixin to run it in a background thread. In the message callback, we inspect the routing key, invoke the appropriate processing function, and acknowledge the message. This worker architecture gives us clean, concurrent message consumption with full control. Check out the FULL CODES. Copy CodeCopiedUse a different Browser def publish_messages(connection): producer = Producer(connection) tasks = [ (‘video.upload’, {‘file’: ‘movie.mp4’}), (‘user.login’, {‘user’: ‘admin’}), ] logger.info(“n PRODUCER: Starting to publish messages…”) for r_key, data in tasks: data[‘id’] = str(uuid.uuid4())[:8] logger.info(f” SENDING: {r_key} -> {data}”) producer.publish( data, exchange=media_exchange, routing_key=r_key, serializer=’json’ ) time.sleep(1.5) logger.info(” PRODUCER: Done.”) We now build a producer that sends structured JSON payloads into the exchange with different routing keys. We generate unique IDs for each event and observe how they are routed to other queues. This mirrors real-world microservice event publishing, where producers and consumers remain decoupled. Check out the FULL CODES. Copy CodeCopiedUse a different Browser def run_example(): with Connection(BROKER_URL) as conn: worker = Worker(conn, task_queues) worker_thread = threading.Thread(target=worker.run) worker_thread.daemon = True worker_thread.start() logger.info(” SYSTEM: Worker thread started.”) time.sleep(1) try: publish_messages(conn) time.sleep(2) except KeyboardInterrupt: pass finally: worker.should_stop = True logger.info(“n SYSTEM: Execution complete.”) if __name__ == “__main__”: run_example() We start the worker in a background thread and fire the producer in the main thread. This structure gives us a mini distributed system running in Colab. By observing the logs, we see messages published → routed → consumed → acknowledged, completing the full event-processing lifecycle. In conclusion, we orchestrated a dynamic, distributed task-routing pipeline that processes real-time events with clarity and precision. We witnessed how Kombu abstracts away the complexity of messaging systems while still giving us fine-grained control over routing, consumption, and worker concurrency. As we see messages move from producer to exchange to queue to worker, we gained a deeper appreciation for the elegance of event-driven system design, and we are now well-equipped to scale this foundation into robust microservices, background processors, and enterprise-grade workflows. Check out the FULL CODES. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. The post How to Build a High-Performance Distributed Task Routing System Using Kombu with Topic Exchanges and Concurrent Workers appeared first on MarkTechPost.

How to Build a High-Performance Distributed Task Routing System Using Kombu with Topic Exchanges and Concurrent Workers Lire l’article »

AI, Committee, Actualités, Uncategorized

Mistral AI Releases OCR 3: A Smaller Optical Character Recognition (OCR) Model for Structured Document AI at Scale

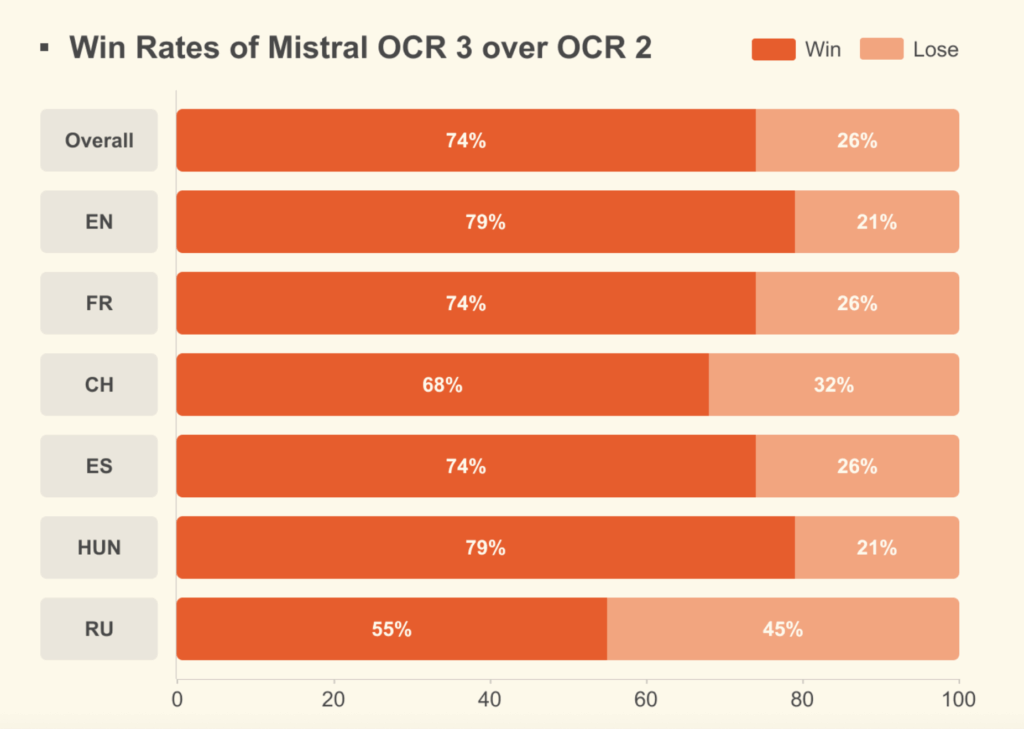
Mistral AI has released Mistral OCR 3, its latest optical character recognition service that powers the company’s Document AI stack. The model, named as mistral-ocr-2512, is built to extract interleaved text and images from PDFs and other documents while preserving structure, and it does this at an aggressive price of $2 per 1,000 pages with a 50% discount when used through the Batch API. What Mistral OCR 3 is Optimized for? Mistral OCR 3 targets typical enterprise document workloads. The model is tuned for forms, scanned documents, complex tables, and handwriting. It is evaluated on internal benchmarks drawn from real business use cases, where it achieves a 74% overall win rate over Mistral OCR 2 across these document categories using a fuzzy match metric against ground truth. The model outputs markdown that preserves document layout, and when table formatting is enabled, it enriches the output with HTML based table representations. This combination gives downstream systems both the content and the structural information that is needed for retrieval pipelines, analytics, and agent workflows. Role in Mistral Document AI OCR 3 sits inside Mistral Document AI, the company’s document processing capability that combines OCR with structured data extraction and Document QnA. It now powers the Document AI Playground in Mistral AI Studio. In this interface, users upload PDFs or images and get back either clean text or structured JSON without writing code. The same underlying OCR pipeline is accessible via the public API, which allows teams to move from interactive exploration to production workloads without changing the core model. Inputs, Outputs, And Structure The OCR processor accepts multiple document formats through a single API. The document field can point to: document_url for PDFs, pptx, docx and more image_url for image types such as png, jpeg or avif Uploaded or base64 encoded PDFs or images through the same schema This is documented in the OCR Processor section of Mistral’s Document AI docs. The response is a JSON object with a pages array. Each page contains an index, a markdown string, a list of images, a list of tables when table_format=”html” is used, detected hyperlinks, optional header and footer fields when header or footer extraction is enabled, and a dimensions object with page size. There is also a document_annotation field for structured annotations and a usage_info block for accounting information. When images and HTML tables are extracted, the markdown includes placeholders such as ![img-0.jpeg](img-0.jpeg) and [tbl-3.html](tbl-3.html). These placeholders are mapped back to actual content using the images and tables arrays in the response, which simplifies downstream reconstruction. Upgrades Over Mistral OCR 2 Mistral OCR 3 introduces several concrete upgrades relative to OCR 2. The public release notes emphasize four main areas. Handwriting Mistral OCR 3 more accurately interprets cursive, mixed content annotations, and handwritten text placed on top of printed templates. Forms It improves detection of boxes, labels, and handwritten entries in dense layouts such as invoices, receipts, compliance forms, and government documents. Scanned and complex documents The model is more robust to compression artifacts, skew, distortion, low DPI, and background noise in scanned pages. Complex tables It reconstructs table structures with headers, merged cells, multi row blocks, and column hierarchies, and it can return HTML tables with proper colspan and rowspan tags so that layout is preserved. https://mistral.ai/news/mistral-ocr-3 Pricing, Batch Inference, And Annotations The OCR 3 model card lists pricing at $2 per 1,000 pages for standard OCR and $3 per 1,000 annotated pages when structured annotations are used. Mistral also exposes OCR 3 through its Batch Inference API /v1/batch, which is documented under the batching section of the platform. Batch processing halves the effective OCR price to $1 per 1,000 pages by applying a 50% discount for jobs that run through the batch pipeline. The model integrates with two important features on the same endpoint, Annotations – Structured and BBox Extraction. These allow developers to attach schema driven labels to regions of a document and get bounding boxes for text and other elements, which is useful when mapping content into downstream systems or UI overlays. Key Takeaways Model and role: Mistral OCR 3, named as mistral-ocr-2512, is the new OCR service that powers Mistral’s Document AI stack for page based document understanding. Accuracy gains: On internal benchmarks covering forms, scanned documents, complex tables, and handwriting, OCR 3 achieves a 74% overall win rate over Mistral OCR 2, and Mistral positions it as state of the art against both traditional and AI native OCR systems. Structured outputs for RAG: The service extracts interleaved text and embedded images and returns markdown enriched with HTML reconstructed tables, preserving layout and table structure so outputs can feed directly into RAG, agents, and search pipelines with minimal extra parsing. API and document formats: Developers access OCR 3 via the /v1/ocr endpoint or SDK, passing PDFs as document_url and images such as png or jpeg as image_url, and can enable options like HTML table output, header or footer extraction, and base64 images in the response. Pricing and batch processing: OCR 3 is priced at 2 dollars per 1,000 pages and 3 dollars per 1,000 annotated pages, and when used through the Batch API the effective price for standard OCR drops to 1 dollar per 1,000 pages for large scale processing. Check out the TECHNICAL DETAILS. Feel free to check out our GitHub Page for Tutorials, Codes and Notebooks. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. The post Mistral AI Releases OCR 3: A Smaller Optical Character Recognition (OCR) Model for Structured Document AI at Scale appeared first on MarkTechPost.

Mistral AI Releases OCR 3: A Smaller Optical Character Recognition (OCR) Model for Structured Document AI at Scale Lire l’article »

AI, Committee, Actualités, Uncategorized

Wrist Photoplethysmography Predicts Dietary Information

arXiv:2511.19260v2 Announce Type: replace-cross Abstract: Whether wearable photoplethysmography (PPG) contains dietary information remains unknown. We trained a language model on 1.1M meals to predict meal descriptions from PPG, aligning PPG to text. PPG nontrivially predicts meal content; predictability decreases for PPGs farther from meals. This transfers to dietary tasks: PPG increases AUC by 11% for intake and satiety across held-out and independent cohorts, with gains robust to text degradation. Wearable PPG may enable passive dietary monitoring.

Wrist Photoplethysmography Predicts Dietary Information Lire l’article »

AI, Committee, Actualités, Uncategorized

Knowledge-Driven Agentic Scientific Corpus Distillation Framework for Biomedical Large Language Models Training

arXiv:2504.19565v3 Announce Type: replace Abstract: Corpus distillation for biomedical large language models (LLMs) seeks to address the pressing challenge of insufficient quantity and quality in open-source annotated scientific corpora, which remains a bottleneck for effective LLM training in biomedical research. This paper proposes a knowledge-driven, agentic framework for scientific corpus distillation, tailored explicitly for LLM training in the biomedical domain, addressing the challenge posed by the complex hierarchy of biomedical knowledge. Central to our approach is a collaborative multi-agent architecture, where specialized agents, each guided by the Medical Subject Headings (MeSH) hierarchy, work in concert to autonomously extract, synthesize, and self-evaluate high-quality textual data from vast scientific literature. This agentic framework collectively generates and refines domain-specific question-answer pairs, ensuring comprehensive coverage and consistency with biomedical ontologies while minimizing manual involvement. Extensive experimental results show that language models trained on our multi-agent distilled datasets achieve notable improvements in biomedical question-answering tasks, outperforming both strong life sciences LLM baselines and advanced proprietary models. Notably, our AI-Ready dataset enables Llama3-70B to surpass GPT-4 with MedPrompt and Med-PaLM-2, despite their larger scale. Detailed ablation studies and case analyses further validate the effectiveness and synergy of each agent within the framework, highlighting the potential of multi-agent collaboration in biomedical LLM training.

Knowledge-Driven Agentic Scientific Corpus Distillation Framework for Biomedical Large Language Models Training Lire l’article »

AI, Committee, Actualités, Uncategorized

Multimodal RewardBench 2: Evaluating Omni Reward Models for Interleaved Text and Image

arXiv:2512.16899v1 Announce Type: new Abstract: Reward models (RMs) are essential for training large language models (LLMs), but remain underexplored for omni models that handle interleaved image and text sequences. We introduce Multimodal RewardBench 2 (MMRB2), the first comprehensive benchmark for reward models on multimodal understanding and (interleaved) generation. MMRB2 spans four tasks: text-to-image, image editing, interleaved generation, and multimodal reasoning (“thinking-with-images”), providing 1,000 expert-annotated preference pairs per task from 23 models and agents across 21 source tasks. MMRB2 is designed with: (1) practical but challenging prompts; (2) responses from state-of-the-art models and agents; and (3) preference pairs with strong human-expert consensus, curated via an ensemble filtering strategy. Using MMRB2, we study existing judges for each subtask, including multimodal LLM-as-a-judge and models trained with human preferences. The latest Gemini 3 Pro attains 75-80% accuracy. GPT-5 and Gemini 2.5 Pro reach 66-75% accuracy, compared to >90% for humans, yet surpass the widely used GPT-4o (59%). The best performing open-source model Qwen3-VL-32B achieves similar accuracies as Gemini 2.5 Flash (64%). We also show that MMRB2 performance strongly correlates with downstream task success using Best-of-N sampling and conduct an in-depth analysis that shows key areas to improve the reward models going forward.

Multimodal RewardBench 2: Evaluating Omni Reward Models for Interleaved Text and Image Lire l’article »

AI, Committee, Actualités, Uncategorized

From Essence to Defense: Adaptive Semantic-aware Watermarking for Embedding-as-a-Service Copyright Protection

arXiv:2512.16439v1 Announce Type: cross Abstract: Benefiting from the superior capabilities of large language models in natural language understanding and generation, Embeddings-as-a-Service (EaaS) has emerged as a successful commercial paradigm on the web platform. However, prior studies have revealed that EaaS is vulnerable to imitation attacks. Existing methods protect the intellectual property of EaaS through watermarking techniques, but they all ignore the most important properties of embedding: semantics, resulting in limited harmlessness and stealthiness. To this end, we propose SemMark, a novel semantic-based watermarking paradigm for EaaS copyright protection. SemMark employs locality-sensitive hashing to partition the semantic space and inject semantic-aware watermarks into specific regions, ensuring that the watermark signals remain imperceptible and diverse. In addition, we introduce the adaptive watermark weight mechanism based on the local outlier factor to preserve the original embedding distribution. Furthermore, we propose Detect-Sampling and Dimensionality-Reduction attacks and construct four scenarios to evaluate the watermarking method. Extensive experiments are conducted on four popular NLP datasets, and SemMark achieves superior verifiability, diversity, stealthiness, and harmlessness.

From Essence to Defense: Adaptive Semantic-aware Watermarking for Embedding-as-a-Service Copyright Protection Lire l’article »

AI, Committee, Actualités, Uncategorized

Bridging the Reality Gap: Efficient Adaptation of ASR systems for Challenging Low-Resource Domains

arXiv:2512.16401v1 Announce Type: new Abstract: Automatic Speech Recognition (ASR) holds immense potential to streamline clinical documentation, such as digitizing handwritten prescriptions and reports, thereby increasing patient throughput and reducing costs in resource-constrained sectors like rural healthcare. However, realizing this utility is currently obstructed by significant technical barriers: strict data privacy constraints, limited computational resources, and severe acoustic domain shifts. We quantify this gap by showing that a robust multilingual model (IndicWav2Vec) degrades to a stark 40.94% Word Error Rate (WER) when deployed on real-world clinical audio (Gram Vaani), rendering it unusable for practical applications. To address these challenges and bring ASR closer to deployment, we propose an efficient, privacy-preserving adaptation framework. We employ Low-Rank Adaptation (LoRA) to enable continual learning from incoming data streams directly on edge devices, ensuring patient data confidentiality. Our strategy yields a 17.1% relative improvement in WER on the target domain. Furthermore, by integrating multi-domain experience replay, we reduce catastrophic forgetting by 47% compared to naive adaptation. These results demonstrate a viable pathway for building reliable, self-improving ASR systems that can operate effectively within the constraints of high-impact real-world environments.

Bridging the Reality Gap: Efficient Adaptation of ASR systems for Challenging Low-Resource Domains Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR