


NASA is building the first nuclear reactor-powered interplanetary spacecraft. How will it work?
MIT Technology Review Explains: Let our writers untangle the complex, messy world of technology to...
NAS-LoRA: Empowering Parameter-Efficient Fine-Tuning for Visual Foundation Models with Searchable Adaptation
arXiv:2512.03499v1 Announce Type: cross Abstract: The Segment Anything Model (SAM) has emerged as a powerful...
Narrowing the Gap: Supervised Fine-Tuning of Open-Source LLMs as a Viable Alternative to Proprietary Models for Pedagogical Tools
arXiv:2507.05305v1 Announce Type: cross Abstract: Frontier Large language models (LLMs) like ChatGPT and Gemini can...
Nancy Pelosi’s replacement is ready to regulate AI
As a California state senator, Scott Wiener authored legislation aimed at curbing the risks of...
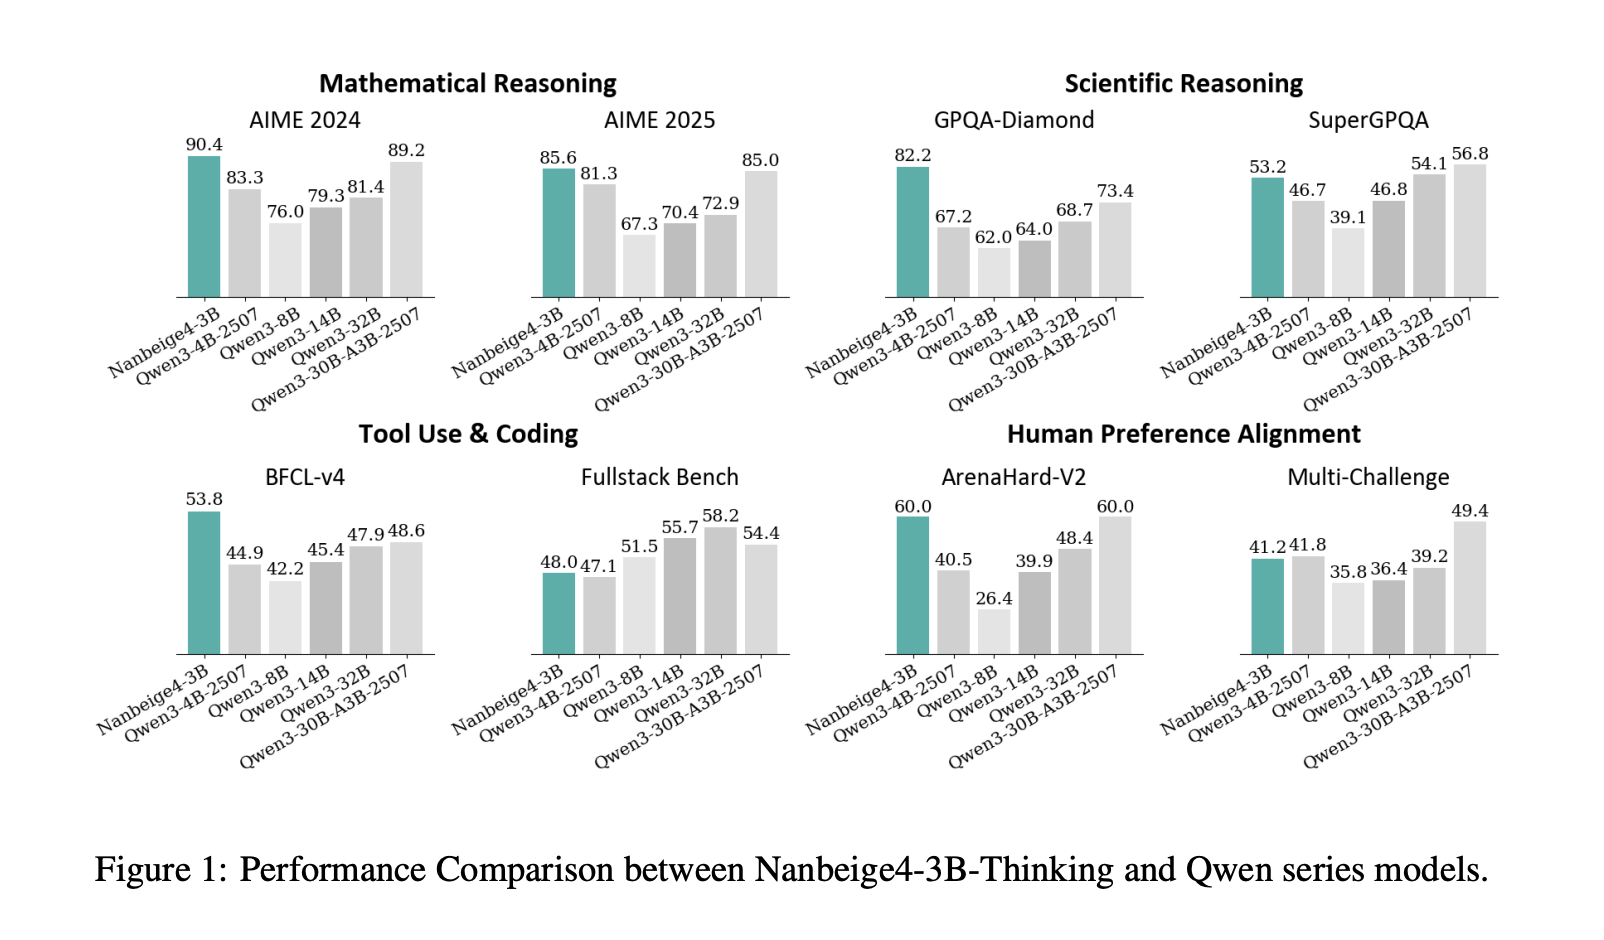
Nanbeige4-3B-Thinking: How a 23T Token Pipeline Pushes 3B Models Past 30B Class Reasoning
Can a 3B model deliver 30B class reasoning by fixing the training recipe instead of...
Mustafa Suleyman: AI development won’t hit a wall anytime soon—here’s why
We evolved for a linear world. If you walk for an hour, you cover a...
Musk v. Altman week 3: Elon Musk and Sam Altman traded blows over each other’s credibility. Now the jury will pick a side.
In the final week of the Musk v. Altman trial, lawyers traded blows over Elon...
Musk v. Altman week 2: OpenAI fires back, and Shivon Zilis reveals that Musk tried to poach Sam Altman
In the second week of the landmark trial between Elon Musk and OpenAI, Musk’s motivations...
Musk v. Altman week 1: Elon Musk says he was duped, warns AI could kill us all, and admits that xAI distills OpenAI’s models
In the first week of the landmark trial between Elon Musk and OpenAI, Musk took...
MultiVis-Agent: A Multi-Agent Framework with Logic Rules for Reliable and Comprehensive Cross-Modal Data Visualization
arXiv:2601.18320v1 Announce Type: new Abstract: Real-world visualization tasks involve complex, multi-modal requirements that extend beyond...
Multimodal RewardBench 2: Evaluating Omni Reward Models for Interleaved Text and Image
arXiv:2512.16899v1 Announce Type: new Abstract: Reward models (RMs) are essential for training large language models...
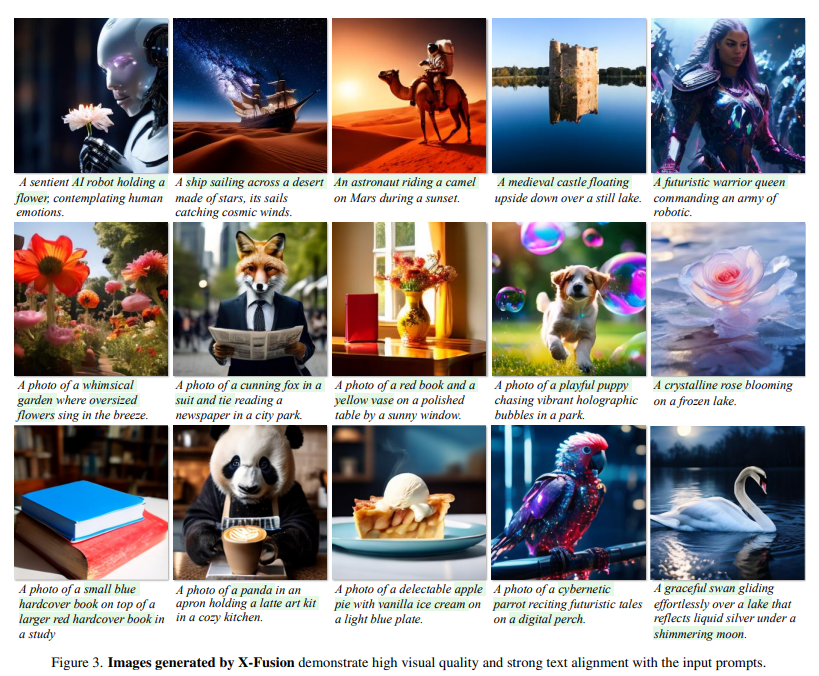
Multimodal LLMs Without Compromise: Researchers from UCLA, UW–Madison, and Adobe Introduce X-Fusion to Add Vision to Frozen Language Models Without Losing Language Capabilities
LLMs have made significant strides in language-related tasks such as conversational AI, reasoning, and code...


