YouZum

Committee

AI, Committee, Noticias, Uncategorized

MIT Technology Review’s most popular stories of 2025

It’s been a busy and productive year here at MIT Technology Review. We published magazine issues on power, creativity, innovation, bodies, relationships, and security. We hosted 14 exclusive virtual conversations with our editors and outside experts in our subscriber-only series, Roundtables, and held two events on MIT’s campus. And we published hundreds of articles online, following new developments in computing, climate tech, robotics, and more.  As the year winds down, we wanted to give you a chance to revisit a bit of this work with us. Whether we were covering the red-hot rise of artificial intelligence or the future of biotech, these are some of the stories that resonated the most with our readers.  We did the math on AI’s energy footprint. Here’s the story you haven’t heard. Understanding AI’s energy use was a huge global conversation in 2025 as hundreds of millions of people began using generative AI tools on a regular basis. Senior reporters James O’Donnell and Casey Crownhart dug into the numbers and published an unprecedented look at AI’s resource demand, down to the level of a single query, to help us know how much energy and water AI may require moving forward.  We’re learning more about what vitamin D does to our bodies Vitamin D deficiency is widespread, particularly in the winter when there’s less sunlight to drive its production in our bodies. The “sunshine vitamin” is important for bone health, but as senior reporter Jessica Hamzelou reported, recent research is also uncovering surprising new insights into other ways it might influence our bodies, including our immune systems and heart health. What is AI? Senior editor Will Douglas Heaven’s expansive look at how to define AI was published in 2024, but it still managed to connect with many readers this year. He lays out why no one can agree on what AI is—and explains why that ambiguity matters, and how it can inform our own critical thinking about this technology. Ethically sourced “spare” human bodies could revolutionize medicine In this thought-provoking op-ed, a team of experts at Stanford University argue that creating living human bodies that can’t think, don’t have any awareness, and can’t feel pain could shake up medical research and drug development by providing essential biological materials for testing and transplantation. Recent advances in biotechnology now provide a potential pathway to such “bodyoids,” though plenty of technical challenges and ethical hurdles remain.  It’s surprisingly easy to stumble into a relationship with an AI chatbot Chatbots were everywhere this year, and reporter Rhiannon Williams chronicled how quickly people can develop bonds with one. That’s all right for some people, she notes, but dangerous for others. Some folks even describe unintentionally forming romantic relationships with chatbots. This is a trend we’ll definitely be keeping an eye on in 2026.  Is this the electric grid of the future? The electric grid is bracing for disruption from more frequent storms and fires, as well as an uncertain policy and regulatory landscape. And in many ways, the publicly owned utility company Lincoln Electric in Nebraska is an ideal lens through which to examine this shift as it works through the challenges of delivering service that’s reliable, affordable, and sustainable. Exclusive: A record-breaking baby has been born from an embryo that’s over 30 years old This year saw the birth of the world’s “oldest baby”: Thaddeus Daniel Pierce, who arrived on July 26. The embryo he developed from was created in 1994 during the early days of IVF and had been frozen and sitting in storage ever since. The new baby’s parents were toddlers at the time, and the embryo was donated to them decades later via a Christian “embryo adoption” agency.   How these two brothers became go-to experts on America’s “mystery drone” invasion Twin brothers John and Gerald Tedesco teamed up to investigate a concerning new threat—unidentified drones. In 2024 alone, some 350 drones entered airspace over a hundred different US military installations, and many cases went unsolved, according to a top military official. This story takes readers inside the equipment-filled RV the Tedescos created to study mysterious aerial phenomena, and how they made a name for themselves among government officials.  10 Breakthrough Technologies of 2025  Our newsroom has published this annual look at advances that will matter in the long run for over 20 years. This year’s list featured generative AI search, cleaner jet fuel, long-acting HIV prevention meds, and other emerging technologies that our journalists think are worth watching. We’ll publish the 2026 edition of the list on January 12, so stay tuned. (In the meantime, here’s what didn’t make the cut.)  

MIT Technology Review’s most popular stories of 2025 Leer entrada »
AI, Committee, Noticias, Uncategorized

The paints, coatings, and chemicals making the world a cooler place

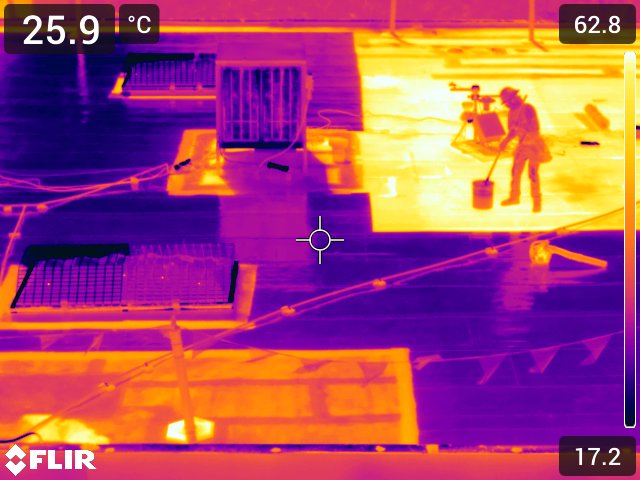
It’s getting harder to beat the heat. During the summer of 2025, heat waves knocked out power grids in North America, Europe, and the Middle East. Global warming means more people need air-­conditioning, which requires more power and strains grids. But a millennia-old idea (plus 21st-century tech) might offer an answer: radiative cooling. Paints, coatings, and textiles can scatter sunlight and dissipate heat—no additional energy required. “Radiative cooling is universal—it exists everywhere in our daily life,” says Qiaoqiang Gan, a professor of materials science and applied physics at King Abdullah University of Science and Technology in Saudi Arabia. Pretty much any object will absorb heat from the sun during the day and radiate some of it back at night. It’s why cars parked outside overnight are often covered with condensation, Gan says—their metal roofs dissipate heat into the sky, cooling the surfaces below the ambient air temperature. That’s how you get dew. Humans have harnessed this basic natural process for thousands of years. Desert peoples in Iran, North Africa, and India manufactured ice by leaving pools of water exposed to clear desert skies overnight, when radiative cooling happens naturally; other cultures constructed “cool roofs” capped with reflective materials that scattered sunlight and lowered interior temperatures. “People have taken advantage of this effect, either knowingly or unknowingly, for a very long time,” says Aaswath Raman, a materials scientist at UCLA and cofounder of the radiative­cooling startup SkyCool Systems. Modern approaches, as demonstrated everywhere from California supermarket rooftops to Japan’s Expo 2025 pavilion, go even further. Normally, if the sun is up and pumping in heat, surfaces can’t get cooler than the ambient temperature. But back in 2014, Raman and his colleagues achieved radiative cooling in the daytime. They customized photonic films to absorb and then radiate heat at infrared wavelengths between eight and 13 micrometers—a range of electromagnetic wavelengths called an “atmospheric window,” because that radiation escapes to space rather than getting absorbed. Those films could dissipate heat even under full sun, cooling the inside of a building to 9 °F below ambient temperatures, with no AC or energy source required. That was proof of concept; today, Raman says, the industry has mostly shifted away from advanced photonics that use the atmospheric-window effect to simpler sunlight-scattering materials. Ceramic cool roofs, nanostructure coatings, and reflective polymers all offer the possibility of diverting more sunlight across all wavelengths, and they’re more durable and scalable. Now the race is on. Startups such as SkyCool, Planck Energies, Spacecool, and i2Cool are competing to commercially manufacture and sell coatings that reflect at least 94% of sunlight in most climates, and above 97% in humid tropical ones. Pilot projects have already provided significant cooling to residential buildings, reducing AC energy needs by 15% to 20% in some cases.  This idea could go way beyond reflective rooftops and roads. Researchers are developing reflective textiles that can be worn by people most at risk of heat exposure. “This is personal thermal management,” says Gan. “We can realize passive cooling in T-shirts, sportswear, and garments.”  A thermal image captured during a SkyCool installation shows treated areas (white, yellow) that are roughly 35 ºC cooler than the surrounding rooftop.COURTESY OF SKYCOOL SYSTEMS Of course, these technologies and materials have limits. Like solar power grids, they’re vulnerable to weather. Clouds prevent reflected sunlight from bouncing into space. Dust and air pollution dim materials’ bright surfaces. Lots of coatings lose their reflectivity after a few years. And the cheapest and toughest materials used in radiative cooling tend to rely on Teflon and other fluoropolymers, “forever chemicals” that don’t biodegrade, posing an environmental risk. “They are the best class of products that tend to survive outdoors,” says Raman. “So for long-term scale-up, can you do it without materials like those fluoropolymers and still maintain the durability and hit this low cost point?” As with any other solution to the problems of climate change, one size won’t fit all. “We cannot be overoptimistic and say that radiative cooling can address all our future needs,” Gan says. “We still need more efficient active air-conditioning.” A shiny roof isn’t a panacea, but it’s still pretty cool.  Becky Ferreira is a science reporter based in upstate New York and author of First Contact: The Story of Our Obsession with Aliens.

The paints, coatings, and chemicals making the world a cooler place Leer entrada »

AI, Committee, Noticias, Uncategorized

From Gemma 3 270M to FunctionGemma, How Google AI Built a Compact Function Calling Specialist for Edge Workloads

Google has released FunctionGemma, a specialized version of the Gemma 3 270M model that is trained specifically for function calling and designed to run as an edge agent that maps natural language to executable API actions. But, What is FunctionGemma? FunctionGemma is a 270M parameter text only transformer based on Gemma 3 270M. It keeps the same architecture as Gemma 3 and is released as an open model under the Gemma license, but the training objective and chat format are dedicated to function calling rather than free form dialogue. The model is intended to be fine tuned for specific function calling tasks. It is not positioned as a general chat assistant. The primary design goal is to translate user instructions and tool definitions into structured function calls, then optionally summarize tool responses for the user. From an interface perspective, FunctionGemma is presented as a standard causal language model. Inputs and outputs are text sequences, with an input context of 32K tokens and an output budget of up to 32K tokens per request, shared with the input length. Architecture and training data The model uses the Gemma 3 transformer architecture and the same 270M parameter scale as Gemma 3 270M. The training and runtime stack reuse the research and infrastructure used for Gemini, including JAX and ML Pathways on large TPU clusters. FunctionGemma uses Gemma’s 256K vocabulary, which is optimized for JSON structures and multilingual text. This improves token efficiency for function schemas and tool responses and reduces sequence length for edge deployments where latency and memory are tight. The model is trained on 6T tokens, with a knowledge cutoff in August 2024. The dataset focuses on two main categories: public tool and API definitions tool use interactions that include prompts, function calls, function responses and natural language follow up messages that summarize outputs or request clarification This training signal teaches both syntax, which function to call and how to format arguments, and intent, when to call a function and when to ask for more information. Conversation format and control tokens FunctionGemma does not use a free form chat format. It expects a strict conversation template that separates roles and tool related regions. Conversation turns are wrapped with <start_of_turn>role … <end_of_turn> where roles are typically developer, user or model. Within those turns, FunctionGemma relies on a fixed set of control token pairs <start_function_declaration> and <end_function_declaration> for tool definitions <start_function_call> and <end_function_call> for the model’s tool calls <start_function_response> and <end_function_response> for serialized tool outputs These markers let the model distinguish natural language text from function schemas and from execution results. The Hugging Face apply_chat_template API and the official Gemma templates generate this structure automatically for messages and tool lists. Fine tuning and Mobile Actions performance Out of the box, FunctionGemma is already trained for generic tool use. However, the official Mobile Actions guide and the model card emphasize that small models reach production level reliability only after task specific fine tuning. The Mobile Actions demo uses a dataset where each example exposes a small set of tools for Android system operations, for example create a contact, set a calendar event, control the flashlight and map viewing. FunctionGemma learns to map utterances such as ‘Create a calendar event for lunch tomorrow’ or ‘Turn on the flashlight’ to those tools with structured arguments. On the Mobile Actions evaluation, the base FunctionGemma model reaches 58 percent accuracy on a held out test set. After fine tuning with the public cookbook recipe, accuracy increases to 85 percent. Edge agents and reference demos The main deployment target for FunctionGemma is edge agents that run locally on phones, laptops and small accelerators such as NVIDIA Jetson Nano. The small parameter count, 0.3B, and support for quantization allow inference with low memory and low latency on consumer hardware. Google ships several reference experiences through the Google AI Edge Gallery Mobile Actions shows a fully offline assistant style agent for device control using FunctionGemma fine tuned on the Mobile Actions dataset and deployed on device. Tiny Garden is a voice controlled game where the model decomposes commands such as “Plant sunflowers in the top row and water them” into domain specific functions like plant_seed and water_plots with explicit grid coordinates. FunctionGemma Physics Playground runs entirely in the browser using Transformers.js and lets users solve physics puzzles via natural language instructions that the model converts into simulation actions. These demos validate that a 270M parameter function caller can support multi step logic on device without server calls, given appropriate fine tuning and tool interfaces. Key Takeaways FunctionGemma is a 270M parameter, text only variant of Gemma 3 that is trained specifically for function calling, not for open ended chat, and is released as an open model under the Gemma terms of use. The model keeps the Gemma 3 transformer architecture and 256k token vocabulary, supports 32k tokens per request shared between input and output, and is trained on 6T tokens. FunctionGemma uses a strict chat template with <start_of_turn>role … <end_of_turn> and dedicated control tokens for function declarations, function calls and function responses, which is required for reliable tool use in production systems. On the Mobile Actions benchmark, accuracy improves from 58 percent for the base model to 85 percent after task specific fine tuning, showing that small function callers need domain data more than prompt engineering. The 270M scale and quantization support let FunctionGemma run on phones, laptops and Jetson class devices, and the model is already integrated into ecosystems such as Hugging Face, Vertex AI, LM Studio and edge demos like Mobile Actions, Tiny Garden and the Physics Playground. Check out the Technical details and Model on HF. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post From Gemma 3 270M to FunctionGemma, How Google AI Built a Compact Function Calling Specialist for Edge Workloads appeared first on MarkTechPost.

From Gemma 3 270M to FunctionGemma, How Google AI Built a Compact Function Calling Specialist for Edge Workloads Leer entrada »

AI, Committee, Noticias, Uncategorized

AI Wrapped: The 14 AI terms you couldn’t avoid in 2025

If the past 12 months have taught us anything, it’s that the AI hype train is showing no signs of slowing. It’s hard to believe that at the beginning of the year, DeepSeek had yet to turn the entire industry on its head, Meta was better known for trying (and failing) to make the metaverse cool than for its relentless quest to dominate superintelligence, and vibe coding wasn’t a thing. If that’s left you feeling a little confused, fear not. As we near the end of 2025, our writers have taken a look back over the AI terms that dominated the year, for better or worse. Make sure you take the time to brace yourself for what promises to be another bonkers year. —Rhiannon Williams 1. Superintelligence As long as people have been hyping AI, they have been coming up with names for a future, ultra-powerful form of the technology that could bring about utopian or dystopian consequences for humanity. “Superintelligence” is that latest hot term. Meta announced in July that it would form an AI team to pursue superintelligence, and it was reportedly offering nine-figure compensation packages to AI experts from the company’s competitors to join. In December, Microsoft’s head of AI followed suit, saying the company would be spending big sums, perhaps hundreds of billions, on the pursuit of superintelligence. If you think superintelligence is as vaguely defined as artificial general intelligence, or AGI, you’d be right! While it’s conceivable that these sorts of technologies will be feasible in humanity’s long run, the question is really when, and whether today’s AI is good enough to be treated as a stepping stone toward something like superintelligence. Not that that will stop the hype kings. —James O’Donnell 2. Vibe coding Thirty years ago, Steve Jobs said everyone in America should learn how to program a computer. Today, people with zero knowledge of how to code can knock up an app, game, or website in no time at all thanks to vibe coding—a catch-all phrase coined by OpenAI cofounder Andrej Karpathy. To vibe-code, you simply prompt generative AI models’ coding assistants to create the digital object of your desire and accept pretty much everything they spit out. Will the result work? Possibly not. Will it be secure? Almost definitely not, but the technique’s biggest champions aren’t letting those minor details stand in their way. Also—it sounds fun! — Rhiannon Williams 3. Chatbot psychosis One of the biggest AI stories over the past year has been how prolonged interactions with chatbots can cause vulnerable people to experience delusions and, in some extreme cases, can either cause or worsen psychosis. Although “chatbot psychosis” is not a recognized medical term, researchers are paying close attention to the growing anecdotal evidence from users who say it’s happened to them or someone they know. Sadly, the increasing number of lawsuits filed against AI companies by the families of people who died following their conversations with chatbots demonstrate the technology’s potentially deadly consequences. —Rhiannon Williams 4. Reasoning Few things kept the AI hype train going this year more than so-called reasoning models, LLMs that can break down a problem into multiple steps and work through them one by one. OpenAI released its first reasoning models, o1 and o3, a year ago. A month later, the Chinese firm DeepSeek took everyone by surprise with a very fast follow, putting out R1, the first open-source reasoning model. In no time, reasoning models became the industry standard: All major mass-market chatbots now come in flavors backed by this tech. Reasoning models have pushed the envelope of what LLMs can do, matching top human performances in prestigious math and coding competitions. On the flip side, all the buzz about LLMs that could “reason” reignited old debates about how smart LLMs really are and how they really work. Like “artificial intelligence” itself, “reasoning” is technical jargon dressed up with marketing sparkle. Choo choo! —Will Douglas Heaven 5. World models  For all their uncanny facility with language, LLMs have very little common sense. Put simply, they don’t have any grounding in how the world works. Book learners in the most literal sense, LLMs can wax lyrical about everything under the sun and then fall flat with a howler about how many elephants you could fit into an Olympic swimming pool (exactly one, according to one of Google DeepMind’s LLMs). World models—a broad church encompassing various technologies—aim to give AI some basic common sense about how stuff in the world actually fits together. In their most vivid form, world models like Google DeepMind’s Genie 3 and Marble, the much-anticipated new tech from Fei-Fei Li’s startup World Labs, can generate detailed and realistic virtual worlds for robots to train in and more. Yann LeCun, Meta’s former chief scientist, is also working on world models. He has been trying to give AI a sense of how the world works for years, by training models to predict what happens next in videos. This year he quit Meta to focus on this approach in a new start up called Advanced Machine Intelligence Labs. If all goes well, world models could be the next thing. —Will Douglas Heaven 6. Hyperscalers Have you heard about all the people saying no thanks, we actually don’t want a giant data center plopped in our backyard? The data centers in question—which tech companies want to built everywhere, including space—are typically referred to as hyperscalers: massive buildings purpose-built for AI operations and used by the likes of OpenAI and Google to build bigger and more powerful AI models. Inside such buildings, the world’s best chips hum away training and fine-tuning models, and they’re built to be modular and grow according to needs. It’s been a big year for hyperscalers. OpenAI announced, alongside President Donald Trump, its Stargate project, a $500 billion joint venture to pepper the country with the largest data centers ever. But it leaves almost everyone else asking: What exactly do we get out of it? Consumers worry the new data centers will raise their power bills. Such buildings generally struggle to run on renewable energy. And they don’t tend to create all that many jobs. But hey, maybe these massive, windowless

AI Wrapped: The 14 AI terms you couldn’t avoid in 2025 Leer entrada »

AI, Committee, Noticias, Uncategorized

MiniMax Releases M2.1: An Enhanced M2 Version with Features like Multi-Coding Language Support, API Integration, and Improved Tools for Structured Coding

Just months after releasing M2—a fast, low-cost model designed for agents and code—MiniMax has introduced an enhanced version: MiniMax M2.1. M2 already stood out for its efficiency, running at roughly 8% of the cost of Claude Sonnet while delivering significantly higher speed. More importantly, it introduced a different computational and reasoning pattern, particularly in how the model structures and executes its thinking during complex code and tool-driven workflows. M2.1 builds on this foundation, bringing tangible improvements across key areas: better code quality, smarter instruction following, cleaner reasoning, and stronger performance across multiple programming languages. These upgrades extend the original strengths of M2 while staying true to MiniMax’s vision of “Intelligence with Everyone.” Strengthening the core capabilities of M2, M2.1 is no longer just about better coding—it also produces clearer, more structured outputs across conversations, documentation, and writing. Core Capabilities and Benchmark Results Built for real-world coding and AI-native teams: Designed to support everything from rapid “vibe builds” to complex, production-grade workflows. Goes beyond coding: Produces clearer, more structured, and higher-quality outputs across everyday conversations, technical documentation, and writing tasks. State-of-the-art multilingual coding performance: Achieves 72.5% on SWE-Multilingual, outperforming Claude Sonnet 4.5 and Gemini 3 Pro across multiple programming languages. Strong AppDev & WebDev capabilities: Scores 88.6% on VIBE-Bench, exceeding Claude Sonnet 4.5 and Gemini 3 Pro, with major improvements in native Android, iOS, and modern web development. Excellent agent and tool compatibility: Delivers consistent and stable performance across leading coding tools and agent frameworks, including Claude Code, Droid (Factory AI), Cline, Kilo Code, Roo Code, BlackBox, and more. Robust context management support: Works reliably with advanced context mechanisms such as Skill.md, Claude.md / agent.md / cursorrule, and Slash Commands, enabling scalable agent workflows. Automatic caching, zero configuration: Built-in caching works out of the box to reduce latency, lower costs, and deliver a smoother overall experience. Getting Started with MiniMax M2.1 To get started with MiniMax M2.1, you’ll need an API key from the MiniMax platform. You can generate one from the MiniMax user console. Once issued, store the API key securely and avoid exposing it in code repositories or public environments. Installing & Setting up the dependencies MiniMax supports both the Anthropic and OpenAI API formats, making it easy to integrate MiniMax models into existing workflows with minimal configuration changes—whether you’re using Anthropic-style message APIs or OpenAI-compatible setups. Copy CodeCopiedUse a different Browser pip install anthropic Copy CodeCopiedUse a different Browser import os from getpass import getpass os.environ[‘ANTHROPIC_BASE_URL’] = ‘https://api.minimax.io/anthropic’ os.environ[‘ANTHROPIC_API_KEY’] = getpass(‘Enter MiniMax API Key: ‘) With just this minimal setup, you’re ready to start using the model. Sending Requests to the Model MiniMax M2.1 returns structured outputs that separate internal reasoning (thinking) from the final response (text). This allows you to observe how the model interprets intent and plans its answer before producing the user-facing output. Copy CodeCopiedUse a different Browser import anthropic client = anthropic.Anthropic() message = client.messages.create( model=”MiniMax-M2.1″, max_tokens=1000, system=”You are a helpful assistant.”, messages=[ { “role”: “user”, “content”: [ { “type”: “text”, “text”: “Hi, how are you?” } ] } ] ) for block in message.content: if block.type == “thinking”: print(f”Thinking:n{block.thinking}n”) elif block.type == “text”: print(f”Text:n{block.text}n”) Copy CodeCopiedUse a different Browser Thinking: The user is just asking how I am doing. This is a friendly greeting, so I should respond in a warm, conversational way. I’ll keep it simple and friendly. Text: Hi! I’m doing well, thanks for asking! I’m ready to help you with whatever you need today. Whether it’s coding, answering questions, brainstorming ideas, or just chatting, I’m here for you. What can I help you with? What makes MiniMax stand out is the visibility into its reasoning process. Before producing the final response, the model explicitly reasons about the user’s intent, tone, and expected style—ensuring the answer is appropriate and context-aware.  By cleanly separating reasoning from responses, the model becomes easier to interpret, debug, and trust, especially in complex agent-based or multi-step workflows, and with M2.1 this clarity is paired with faster responses, more concise reasoning, and substantially reduced token consumption compared to M2. Testing the Model’s Coding Capabilities MiniMax M2 stands out for its native mastery of Interleaved Thinking, allowing it to dynamically plan and adapt within complex coding and tool-based workflows, and M2.1 extends this capability with improved code quality, more precise instruction following, clearer reasoning, and stronger performance across programming languages—particularly in handling composite instruction constraints as seen in OctoCodingBench—making it ready for office automation. To evaluate these capabilities in practice, let’s test the model using a structured coding prompt that includes multiple constraints and real-world engineering requirements. Copy CodeCopiedUse a different Browser import anthropic client = anthropic.Anthropic() def run_test(prompt: str, title: str): print(f”n{‘=’*80}”) print(f”TEST: {title}”) print(f”{‘=’*80}n”) message = client.messages.create( model=”MiniMax-M2.1″, max_tokens=10000, system=( “You are a senior software engineer. ” “Write production-quality code with clear structure, ” “explicit assumptions, and minimal but sufficient reasoning. ” “Avoid unnecessary verbosity.” ), messages=[ { “role”: “user”, “content”: [{“type”: “text”, “text”: prompt}] } ] ) for block in message.content: if block.type == “thinking”: print(” Thinking:n”, block.thinking, “n”) elif block.type == “text”: print(” Output:n”, block.text, “n”) PROMPT= “”” Design a small Python service that processes user events. Requirements: 1. Events arrive as dictionaries with keys: user_id, event_type, timestamp. 2. Validate input strictly (types + required keys). 3. Aggregate events per user in memory. 4. Expose two functions: – ingest_event(event: dict) -> None – get_user_summary(user_id: str) -> dict 5. Code must be: – Testable – Thread-safe – Easily extensible for new event types 6. Do NOT use external libraries. Provide: – Code only – Brief inline comments where needed “”” run_test(prompt=PROMPT, title=”Instruction Following + Architecture”) This test uses a deliberately structured and constraint-heavy prompt designed to evaluate more than just code generation. The prompt requires strict input validation, in-memory state management, thread safety, testability, and extensibility—all without relying on external libraries. By combining architectural decisions with multiple non-trivial constraints, the prompt operates at a medium-to-high complexity level, making it well-suited for assessing how effectively MiniMax M2.1 follows instructions, reasons through design trade-offs, and produces

MiniMax Releases M2.1: An Enhanced M2 Version with Features like Multi-Coding Language Support, API Integration, and Improved Tools for Structured Coding Leer entrada »

AI, Committee, Noticias, Uncategorized

A Coding Implementation on Building Self-Organizing Zettelkasten Knowledge Graphs and Sleep-Consolidation Mechanisms

In this tutorial, we dive into the cutting edge of Agentic AI by building a “Zettelkasten” memory system, a “living” architecture that organizes information much like the human brain. We move beyond standard retrieval methods to construct a dynamic knowledge graph where an agent autonomously decomposes inputs into atomic facts, links them semantically, and even “sleeps” to consolidate memories into higher-order insights. Using Google’s Gemini, we implement a robust solution that addresses real-world API constraints, ensuring our agent stores data and also actively understands the evolving context of our projects. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser !pip install -q -U google-generativeai networkx pyvis scikit-learn numpy import os import json import uuid import time import getpass import random import networkx as nx import numpy as np import google.generativeai as genai from dataclasses import dataclass, field from typing import List from sklearn.metrics.pairwise import cosine_similarity from IPython.display import display, HTML from pyvis.network import Network from google.api_core import exceptions def retry_with_backoff(func, *args, **kwargs): max_retries = 5 base_delay = 5 for attempt in range(max_retries): try: return func(*args, **kwargs) except exceptions.ResourceExhausted: wait_time = base_delay * (2 ** attempt) + random.uniform(0, 1) print(f” Quota limit hit. Cooling down for {wait_time:.1f}s…”) time.sleep(wait_time) except Exception as e: if “429” in str(e): wait_time = base_delay * (2 ** attempt) + random.uniform(0, 1) print(f” Quota limit hit (HTTP 429). Cooling down for {wait_time:.1f}s…”) time.sleep(wait_time) else: print(f” Unexpected Error: {e}”) return None print(” Max retries reached.”) return None print(“Enter your Google AI Studio API Key (Input will be hidden):”) API_KEY = getpass.getpass() genai.configure(api_key=API_KEY) MODEL_NAME = “gemini-2.5-flash” EMBEDDING_MODEL = “models/text-embedding-004″ print(f” API Key configured. Using model: {MODEL_NAME}”) We begin by importing essential libraries for graph management and AI model interaction, while also securing our API key input. Crucially, we define a robust retry_with_backoff function that automatically handles rate limit errors, ensuring our agent gracefully pauses and recovers when the API quota is exceeded during heavy processing. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser @dataclass class MemoryNode: id: str content: str type: str embedding: List[float] = field(default_factory=list) timestamp: int = 0 class RobustZettelkasten: def __init__(self): self.graph = nx.Graph() self.model = genai.GenerativeModel(MODEL_NAME) self.step_counter = 0 def _get_embedding(self, text): result = retry_with_backoff( genai.embed_content, model=EMBEDDING_MODEL, content=text ) return result[’embedding’] if result else [0.0] * 768 We define the fundamental MemoryNode structure to hold our content, types, and vector embeddings in an organized data class. We then initialize the main RobustZettelkasten class, establishing the network graph and configuring the Gemini embedding model that serves as the backbone of our semantic search capabilities. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser def _atomize_input(self, text): prompt = f””” Break the following text into independent atomic facts. Output JSON: {{ “facts”: [“fact1”, “fact2”] }} Text: “{text}” “”” response = retry_with_backoff( self.model.generate_content, prompt, generation_config={“response_mime_type”: “application/json”} ) try: return json.loads(response.text).get(“facts”, []) if response else [text] except: return [text] def _find_similar_nodes(self, embedding, top_k=3, threshold=0.45): if not self.graph.nodes: return [] nodes = list(self.graph.nodes(data=True)) embeddings = [n[1][‘data’].embedding for n in nodes] valid_embeddings = [e for e in embeddings if len(e) > 0] if not valid_embeddings: return [] sims = cosine_similarity([embedding], embeddings)[0] sorted_indices = np.argsort(sims)[::-1] results = [] for idx in sorted_indices[:top_k]: if sims[idx] > threshold: results.append((nodes[idx][0], sims[idx])) return results def add_memory(self, user_input): self.step_counter += 1 print(f”n [Step {self.step_counter}] Processing: “{user_input}””) facts = self._atomize_input(user_input) for fact in facts: print(f” -> Atom: {fact}”) emb = self._get_embedding(fact) candidates = self._find_similar_nodes(emb) node_id = str(uuid.uuid4())[:6] node = MemoryNode(id=node_id, content=fact, type=’fact’, embedding=emb, timestamp=self.step_counter) self.graph.add_node(node_id, data=node, title=fact, label=fact[:15]+”…”) if candidates: context_str = “n”.join([f”ID {c[0]}: {self.graph.nodes[c[0]][‘data’].content}” for c in candidates]) prompt = f””” I am adding: “{fact}” Existing Memory: {context_str} Are any of these directly related? If yes, provide the relationship label. JSON: {{ “links”: [{{ “target_id”: “ID”, “rel”: “label” }}] }} “”” response = retry_with_backoff( self.model.generate_content, prompt, generation_config={“response_mime_type”: “application/json”} ) if response: try: links = json.loads(response.text).get(“links”, []) for link in links: if self.graph.has_node(link[‘target_id’]): self.graph.add_edge(node_id, link[‘target_id’], label=link[‘rel’]) print(f” Linked to {link[‘target_id’]} ({link[‘rel’]})”) except: pass time.sleep(1) We construct an ingestion pipeline that decomposes complex user inputs into atomic facts to prevent information loss. We immediately embed these facts and use our agent to identify and create semantic links to existing nodes, effectively building a knowledge graph in real time that mimics associative memory. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser def consolidate_memory(self): print(f”n [Consolidation Phase] Reflecting…”) high_degree_nodes = [n for n, d in self.graph.degree() if d >= 2] processed_clusters = set() for main_node in high_degree_nodes: neighbors = list(self.graph.neighbors(main_node)) cluster_ids = tuple(sorted([main_node] + neighbors)) if cluster_ids in processed_clusters: continue processed_clusters.add(cluster_ids) cluster_content = [self.graph.nodes[n][‘data’].content for n in cluster_ids] prompt = f””” Generate a single high-level insight summary from these facts. Facts: {json.dumps(cluster_content)} JSON: {{ “insight”: “Your insight here” }} “”” response = retry_with_backoff( self.model.generate_content, prompt, generation_config={“response_mime_type”: “application/json”} ) if response: try: insight_text = json.loads(response.text).get(“insight”) if insight_text: insight_id = f”INSIGHT-{uuid.uuid4().hex[:4]}” print(f” Insight: {insight_text}”) emb = self._get_embedding(insight_text) insight_node = MemoryNode(id=insight_id, content=insight_text, type=’insight’, embedding=emb) self.graph.add_node(insight_id, data=insight_node, title=f”INSIGHT: {insight_text}”, label=”INSIGHT”, color=”#ff7f7f”) self.graph.add_edge(insight_id, main_node, label=”abstracted_from”) except: continue time.sleep(1) def answer_query(self, query): print(f”n Querying: “{query}””) emb = self._get_embedding(query) candidates = self._find_similar_nodes(emb, top_k=2) if not candidates: print(“No relevant memory found.”) return relevant_context = set() for node_id, score in candidates: node_content = self.graph.nodes[node_id][‘data’].content relevant_context.add(f”- {node_content} (Direct Match)”) for n1 in self.graph.neighbors(node_id): rel = self.graph[node_id][n1].get(‘label’, ‘related’) content = self.graph.nodes[n1][‘data’].content relevant_context.add(f” – linked via ‘{rel}’ to: {content}”) context_text = “n”.join(relevant_context) prompt = f””” Answer based ONLY on context. Question: {query} Context: {context_text} “”” response = retry_with_backoff(self.model.generate_content, prompt) if response: print(f” Agent Answer:n{response.text}”) We implement the cognitive functions of our agent, enabling it to “sleep” and consolidate dense memory clusters into higher-order insights. We also define the query logic that traverses these connected paths, allowing the agent to reason across multiple hops in the graph to answer complex questions. Check out the FULL CODES here. Copy CodeCopiedUse a different Browser def show_graph(self): try: net = Network(notebook=True, cdn_resources=’remote’, height=”500px”, width=”100%”, bgcolor=’#222222′, font_color=’white’) for n, data in self.graph.nodes(data=True): color = “#97c2fc” if data[‘data’].type == ‘fact’ else “#ff7f7f” net.add_node(n, label=data.get(‘label’, ”), title=data[‘data’].content, color=color) for u, v, data in self.graph.edges(data=True): net.add_edge(u, v, label=data.get(‘label’, ”)) net.show(“memory_graph.html”) display(HTML(“memory_graph.html”)) except Exception as e:

A Coding Implementation on Building Self-Organizing Zettelkasten Knowledge Graphs and Sleep-Consolidation Mechanisms Leer entrada »

AI, Committee, Noticias, Uncategorized

Thinking-Free Policy Initialization Makes Distilled Reasoning Models More Effective and Efficient Reasoners

arXiv:2509.26226v2 Announce Type: replace-cross Abstract: Reinforcement Learning with Verifiable Reward (RLVR) effectively solves complex tasks but demands extremely long context lengths during training, leading to substantial computational costs. While multi-stage training can partially mitigate this, starting with overly short contexts often causes irreversible performance degradation, ultimately failing to reduce overall training compute significantly. In this paper, we introduce **T**hinking-**F**ree **P**olicy **I**nitialization (**TFPI**), a simple yet effective adaptation to RLVR that bridges long Chain-of-Thought (CoT) distillation and standard RLVR. TFPI employs a simple *ThinkFree* operation, explicitly discarding the thinking content via a direct ** append, to reduce token usage during inference. Training with *ThinkFree*-adapted inputs improves performance and lowers token consumption, even in the original slow-thinking mode. Extensive experiments across various benchmarks have shown that TFPI accelerates RL convergence, achieves a higher performance ceiling, and yields more token-efficient reasoning models without specialized rewards or complex training designs. With TFPI only, we train a 4B model to reach 89.0% accuracy on AIME24 and 65.5% on LiveCodeBench using less than 4K H20 hours.

Thinking-Free Policy Initialization Makes Distilled Reasoning Models More Effective and Efficient Reasoners Leer entrada »

AI, Committee, Noticias, Uncategorized

Nemotron 3 Nano: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Model for Agentic Reasoning

arXiv:2512.20848v1 Announce Type: new Abstract: We present Nemotron 3 Nano 30B-A3B, a Mixture-of-Experts hybrid Mamba-Transformer language model. Nemotron 3 Nano was pretrained on 25 trillion text tokens, including more than 3 trillion new unique tokens over Nemotron 2, followed by supervised fine tuning and large-scale RL on diverse environments. Nemotron 3 Nano achieves better accuracy than our previous generation Nemotron 2 Nano while activating less than half of the parameters per forward pass. It achieves up to 3.3x higher inference throughput than similarly-sized open models like GPT-OSS-20B and Qwen3-30B-A3B-Thinking-2507, while also being more accurate on popular benchmarks. Nemotron 3 Nano demonstrates enhanced agentic, reasoning, and chat abilities and supports context lengths up to 1M tokens. We release both our pretrained Nemotron 3 Nano 30B-A3B Base and post-trained Nemotron 3 Nano 30B-A3B checkpoints on Hugging Face.

Nemotron 3 Nano: Open, Efficient Mixture-of-Experts Hybrid Mamba-Transformer Model for Agentic Reasoning Leer entrada »

We use cookies to improve your experience and performance on our website. You can learn more at Política de privacidad and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
es_ES