YouZum

Committee

AI, Committee, Noticias, Uncategorized

Exa AI Introduces Exa Instant: A Sub-200ms Neural Search Engine Designed to Eliminate Bottlenecks for Real-Time Agentic Workflows

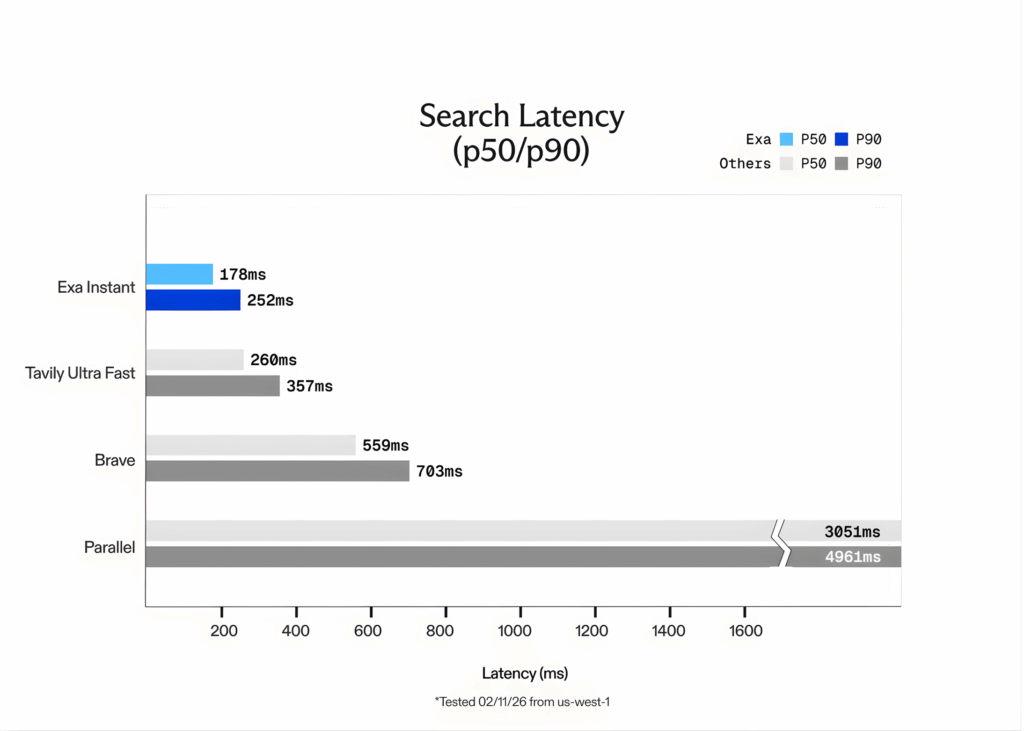
In the world of Large Language Models (LLMs), speed is the only feature that matters once accuracy is solved. For a human, waiting 1 second for a search result is fine. For an AI agent performing 10 sequential searches to solve a complex task, a 1-second delay per search creates a 10-second lag. This latency kills the user experience. Exa, the search engine startup formerly known as Metaphor, just released Exa Instant. It is a search model designed to provide the world’s web data to AI agents in under 200ms. For software engineers and data scientists building Retrieval-Augmented Generation (RAG) pipelines, this removes the biggest bottleneck in agentic workflows. https://exa.ai/blog/exa-instant Why Latency is the Enemy of RAG When you build a RAG application, your system follows a loop: the user asks a question, your system searches the web for context, and the LLM processes that context. If the search step takes 700ms to 1000ms, the total ‘time to first token’ becomes sluggish. Exa Instant delivers results with a latency between 100ms and 200ms. In tests conducted from the us-west-1 (northern california) region, the network latency was roughly 50ms. This speed allows agents to perform multiple searches in a single ‘thought’ process without the user feeling a delay. No More ‘Wrapping’ Google Most search APIs available today are ‘wrappers.’ They send a query to a traditional search engine like Google or Bing, scrape the results, and send them back to you. This adds layers of overhead. Exa Instant is different. It is built on a proprietary, end-to-end neural search and retrieval stack. Instead of matching keywords, Exa uses embeddings and transformers to understand the meaning of a query. This neural approach ensures the results are relevant to the AI’s intent, not just the specific words used. By owning the entire stack from the crawler to the inference engine, Exa can optimize for speed in ways that ‘wrapper’ APIs cannot. Benchmarking the Speed The Exa team benchmarked Exa Instant against other popular options like Tavily Ultra Fast and Brave. To ensure the tests were fair and avoided ‘cached’ results, the team used the SealQA query dataset. They also added random words generated by GPT-5 to each query to force the engine to perform a fresh search every time. The results showed that Exa Instant is up to 15x faster than competitors. While Exa offers other models like Exa Fast and Exa Auto for higher-quality reasoning, Exa Instant is the clear choice for real-time applications where every millisecond counts. Pricing and Developer Integration The transition to Exa Instant is simple. The API is accessible through the dashboard.exa.ai platform. Cost: Exa Instant is priced at $5 per 1,000 requests. Capacity: It searches the same massive index of the web as Exa’s more powerful models. Accuracy: While designed for speed, it maintains high relevance. For specialized entity searches, Exa’s Websets product remains the gold standard, proving to be 20x more correct than Google for complex queries. The API returns clean content ready for LLMs, removing the need for developers to write custom scraping or HTML cleaning code. Key Takeaways Sub-200ms Latency for Real-Time Agents: Exa Instant is optimized for ‘agentic’ workflows where speed is a bottleneck. By delivering results in under 200ms (and network latency as low as 50ms), it allows AI agents to perform multi-step reasoning and parallel searches without the lag associated with traditional search engines. Proprietary Neural Stack vs. ‘Wrappers‘: Unlike many search APIs that simply ‘wrap’ Google or Bing (adding 700ms+ of overhead), Exa Instant is built on a proprietary, end-to-end neural search engine. It uses a custom transformer-based architecture to index and retrieve web data, offering up to 15x faster performance than existing alternatives like Tavily or Brave. Cost-Efficient Scaling: The model is designed to make search a ‘primitive’ rather than an expensive luxury. It is priced at $5 per 1,000 requests, allowing developers to integrate real-time web lookups at every step of an agent’s thought process without breaking the budget. Semantic Intent over Keywords: Exa Instant leverages embeddings to prioritize the ‘meaning’ of a query rather than exact word matches. This is particularly effective for RAG (Retrieval-Augmented Generation) applications, where finding ‘link-worthy’ content that fits an LLM’s context is more valuable than simple keyword hits. Optimized for LLM Consumption: The API provides more than just URLs; it offers clean, parsed HTML, Markdown, and token-efficient highlights. This reduces the need for custom scraping scripts and minimizes the number of tokens the LLM needs to process, further speeding up the entire pipeline. Check out the Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Exa AI Introduces Exa Instant: A Sub-200ms Neural Search Engine Designed to Eliminate Bottlenecks for Real-Time Agentic Workflows appeared first on MarkTechPost.
Exa AI Introduces Exa Instant: A Sub-200ms Neural Search Engine Designed to Eliminate Bottlenecks for Real-Time Agentic Workflows Leer entrada »

AI, Committee, Noticias, Uncategorized

Kyutai Releases Hibiki-Zero: A3B Parameter Simultaneous Speech-to-Speech Translation Model Using GRPO Reinforcement Learning Without Any Word-Level Aligned Data

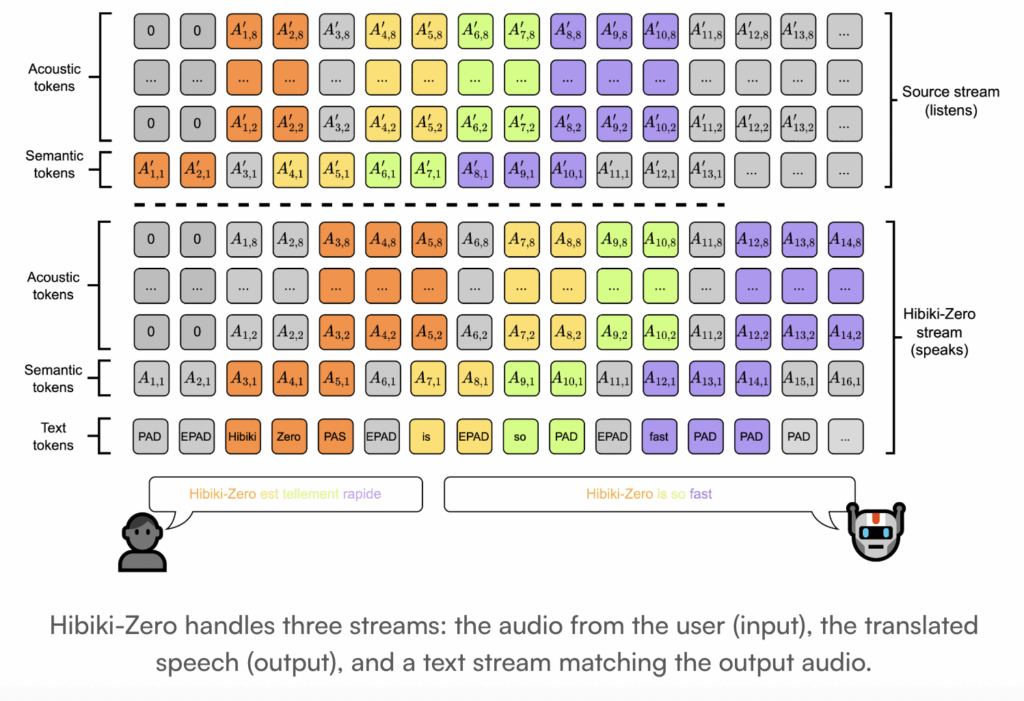
Kyutai has released Hibiki-Zero, a new model for simultaneous speech-to-speech translation (S2ST) and speech-to-text translation (S2TT). The system translates source speech into a target language in real-time. It handles non-monotonic word dependencies during the process. Unlike previous models, Hibiki-Zero does not require word-level aligned data for training. This eliminates a major bottleneck in scaling AI translation to more languages. Traditional approaches rely on supervised training with word-level alignments. These alignments are difficult to collect at scale. Developers usually depend on synthetic alignments and language-specific heuristics. Hibiki-Zero removes this complexity by using a novel reinforcement learning (RL) strategy to optimize latency. https://kyutai.org/blog/2026-02-12-hibiki-zero A Multistream Architecture Hibiki-Zero is a decoder-only model. It uses a multistream architecture to model sequences of tokens jointly. The model handles 3 specific streams: Source Stream: Audio tokens from the input speech. Target Stream: Generated audio tokens for the translated speech. Inner Monologue: A stream of padded text tokens that match the target audio. The system uses the Mimi neural audio codec. Mimi is a causal and streaming codec that encodes waveforms into discrete tokens. It operates at a framerate of 12.5 Hz. The model uses an RQ-Transformer to model these audio streams. The architectural specs include: Total Parameters: 3B. Temporal Transformer: 28 layers with a latent dimension of 2048. Depth Transformer: 6 layers per codebook with a latent dimension of 1024. Context Window: 4min. Audio Codebooks: 16 levels for high-quality speech. Training Without Human Interpretation Data Hibiki-Zero is trained in 2 main stages: Coarse Alignment Training: The model first trains on sentence-level aligned data. This data ensures that the ith sentence in the target is a translation of the ith sentence in the source. The research team use a technique to insert artificial silence in the target speech to delay its content relative to the source. Reinforcement Learning (RL): The model uses Group Relative Policy Optimization (GRPO) to refine its policy. This stage reduces translation latency while preserving quality. The RL process uses process rewards based only on the BLEU score. It computes intermediate rewards at multiple points during translation. A hyperparameter ⍺ balances the trade-off between speed and accuracy. A lower ⍺ reduces latency but may slightly decrease quality. Scaling to Italian in Record Time The researchers demonstrated how easily Hibiki-Zero adapts to new languages. They added Italian as an input language using less than 1000h of speech data. They performed supervised fine-tuning followed by the GRPO process. The model reached a quality and latency trade-off similar to Meta’s Seamless model. It surpassed Seamless in speaker similarity by over 30 points. Performance and Results Hibiki-Zero achieves state-of-the-art results across 5 X-to-English tasks. It was tested on the Audio-NTREX-4L long-form benchmark, which includes 15h of speech per TTS system. Metric Hibiki-Zero (French) Seamless (French) ASR-BLEU (↑) 28.7 23.9 Speaker Similarity (↑) 61.3 44.4 Average Lag (LAAL) (↓) 2.3 6.2 In short-form tasks (Europarl-ST), Hibiki-Zero reached an ASR-BLEU of 34.6 with a lag of 2.8 seconds. Human raters also scored the model significantly higher than baselines for speech naturalness and voice transfer. https://kyutai.org/blog/2026-02-12-hibiki-zero Key Takeaways Zero Aligned Data Requirement: Hibiki-Zero eliminates the need for expensive, hand-crafted word-level alignments between source and target speech, which were previously the biggest bottleneck in scaling simultaneous translation to new languages. GRPO-Driven Latency Optimization: The model uses Group Relative Policy Optimization (GRPO) and a simple reward system based only on BLEU scores to automatically learn an efficient translation policy, balancing high translation quality with low latency. Coarse-to-Fine Training Strategy: The training pipeline starts with sentence-level aligned data to teach the model base translation at high latency, followed by a reinforcement learning phase that “teaches” the model when to speak and when to listen. Superior Voice and Naturalness: In benchmarking against previous state-of-the-art systems like Seamless, Hibiki-Zero achieved a 30-point lead in speaker similarity and significantly higher scores in speech naturalness and audio quality across five language tasks. Rapid New Language Adaptation: The architecture is highly portable; researchers demonstrated that Hibiki-Zero could be adapted to a new input language (Italian) with less than 1,000 hours of speech data while maintaining its original performance on other languages. Check out the Paper, Technical details, Repo and Samples. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Kyutai Releases Hibiki-Zero: A3B Parameter Simultaneous Speech-to-Speech Translation Model Using GRPO Reinforcement Learning Without Any Word-Level Aligned Data appeared first on MarkTechPost.

Kyutai Releases Hibiki-Zero: A3B Parameter Simultaneous Speech-to-Speech Translation Model Using GRPO Reinforcement Learning Without Any Word-Level Aligned Data Leer entrada »

AI, Committee, Noticias, Uncategorized

Gradients Must Earn Their Influence: Unifying SFT with Generalized Entropic Objectives

arXiv:2602.11424v1 Announce Type: new Abstract: Standard negative log-likelihood (NLL) for Supervised Fine-Tuning (SFT) applies uniform token-level weighting. This rigidity creates a two-fold failure mode: (i) overemphasizing low-probability targets can amplify gradients on noisy supervision and disrupt robust priors, and (ii) uniform weighting provides weak sharpening when the model is already confident. Existing methods fail to resolve the resulting plasticity–stability dilemma, often suppressing necessary learning signals alongside harmful ones. To address this issue, we unify token-level SFT objectives within a generalized deformed-log family and expose a universal gate $times$ error gradient structure, where the gate controls how much the model trusts its current prediction. By employing the Cayley transform, we map the model’s continuously evolving uncertainty onto a continuous focus trajectory, which enables seamless interpolation between scenarios involving uncertain novel concepts and those involving well-established knowledge. We then introduce Dynamic Entropy Fine-Tuning (DEFT), a parameter-free objective that modulates the trust gate using distribution concentration (R’enyi-2 entropy) as a practical proxy for the model’s predictive state. Extensive experiments and analyses demonstrate that DEFT achieves a better balance between exploration and exploitation, leading to improved overall performance.

Gradients Must Earn Their Influence: Unifying SFT with Generalized Entropic Objectives Leer entrada »

AI, Committee, Noticias, Uncategorized

RFK Jr. follows a carnivore diet. That doesn’t mean you should.

Americans have a new set of diet guidelines. Robert F. Kennedy Jr. has taken an old-fashioned food pyramid, turned it upside down, and plonked a steak and a stick of butter in prime positions. Kennedy and his Make America Healthy Again mates have long been extolling the virtues of meat and whole-fat dairy, so it wasn’t too surprising to see those foods recommended alongside vegetables and whole grains (despite the well-established fact that too much saturated fat can be extremely bad for you). Some influencers have taken the meat trend to extremes, following a “carnivore diet.” “The best thing you could do is eliminate out everything except fatty meat and lard,” Anthony Chaffee, an MD with almost 400,000 followers, said in an Instagram post. And I almost choked on my broccoli when, while scrolling LinkedIn, I came across an interview with another doctor declaring that “there is zero scientific evidence to say that vegetables are required in the human diet.” That doctor, who described himself as “90% carnivore,” went on to say that all he’d eaten the previous day was a kilo of beef, and that vegetables have “anti-nutrients,” whatever they might be. You don’t have to spend much time on social media to come across claims like this. The “traditionalist” influencer, author, and psychologist Jordan Peterson was promoting a meat-only diet as far back as 2018. A recent review of research into nutrition misinformation on social media found that the most diet information is shared on Instagram and YouTube, and that a lot of it is nonsense. So much so that the authors describe it as a “growing public health concern.” What’s new is that some of this misinformation comes from the people who now lead America’s federal health agencies. In January Kennedy, who leads the Department of Health and Human Services, told a USA Today reporter that he was on a carnivore diet. “I only eat meat or fermented foods,” he said. He went on to say that the diet had helped him lose “40% of [his] visceral fat within a month.” “Government needs to stop spreading misinformation that natural and saturated fats are bad for you,” Food and Drug Administration commissioner Martin Makary argued in a recent podcast interview. The principles of “whole foods and clean meats” are “biblical,” he said. The interviewer said that Makary’s warnings about pesticides made him want to “avoid all salads and completely miss the organic section in the grocery store.” For the record: There’s plenty of evidence that a diet high in saturated fat can increase the risk of heart disease. That’s not government misinformation.  The carnivore doctors’ suggestion to avoid vegetables is wrong too, says Gabby Headrick, associate director of food and nutrition policy at George Washington University’s Institute for Food Safety & Nutrition Security. There’s no evidence to suggest that a meat-only diet is good for you. “All of the nutrition science to date strongly identifies a wide array of vegetables … as being very health-promoting,” she adds. To be fair to the influencers out there, diet is a tricky thing to study. Much of the research into nutrition relies on volunteers to keep detailed and honest food diaries—something that people are generally quite bad at. And the way our bodies respond to foods might be influenced by our genetics, our microbiomes, the way we prepare or consume those foods, and who knows what else. Still, it will come as a surprise to no one that there is plenty of what the above study calls “low-quality content” floating around on social media. So it’s worth arming ourselves with a good dose of skepticism, especially when we come across posts that mention “miracle foods” or extreme, limited diets. The truth is that most food is neither good nor bad when eaten in moderation. Diet trends come and go, and for most people, the best reasonable advice is simply to eat a balanced diet low in sugar, salt, and saturated fat. You know—the basics. No matter what that weird upside-down food pyramid implies. To the carnivore influencers, I say: get your misinformation off my broccoli. This article first appeared in The Checkup, MIT Technology Review’s weekly biotech newsletter. To receive it in your inbox every Thursday, and read articles like this first, sign up here.

RFK Jr. follows a carnivore diet. That doesn’t mean you should. Leer entrada »

AI, Committee, Noticias, Uncategorized

Google DeepMind Introduces Aletheia: The AI Agent Moving from Math Competitions to Fully Autonomous Professional Research Discoveries

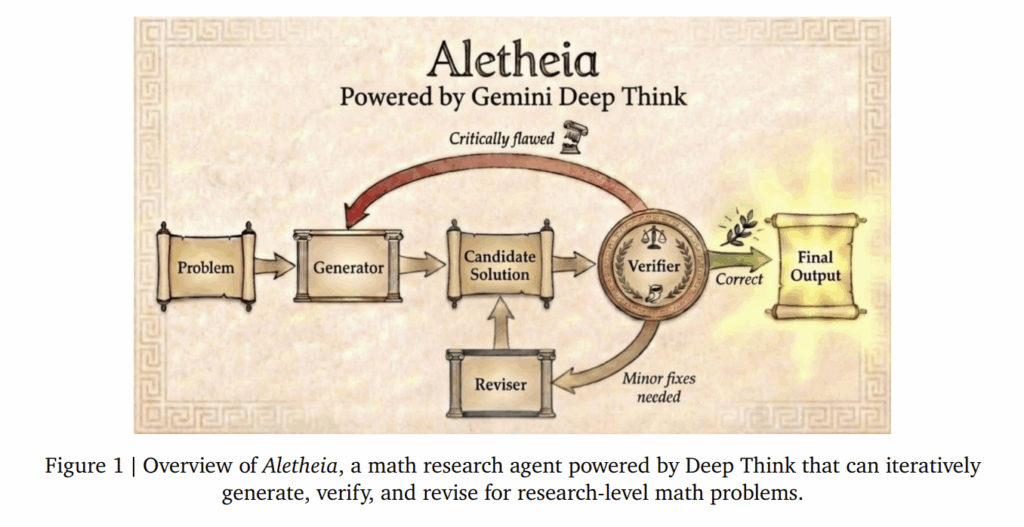
Google DeepMind team has introduced Aletheia, a specialized AI agent designed to bridge the gap between competition-level math and professional research. While models achieved gold-medal standards at the 2025 International Mathematical Olympiad (IMO), research requires navigating vast literature and constructing long-horizon proofs. Aletheia solves this by iteratively generating, verifying, and revising solutions in natural language. https://github.com/google-deepmind/superhuman/blob/main/aletheia/Aletheia.pdf The Architecture: Agentic Loop Aletheia is powered by an advanced version of Gemini Deep Think. It utilizes a three-part ‘agentic harness’ to improve reliability: Generator: Proposes a candidate solution for a research problem. Verifier: An informal natural language mechanism that checks for flaws or hallucinations. Reviser: Corrects errors identified by the Verifier until a final output is approved. This separation of duties is critical; researchers observed that explicitly separating verification helps the model recognize flaws it initially overlooks during generation. Key Technical Findings The development of Aletheia revealed several insights into how AI handles complex reasoning: Inference-Time Scaling: Allowing the model more compute at the time of a query—’thinking longer’—significantly boosts accuracy. The January 2026 version of Deep Think reduced the compute needed for IMO-level problems by 100x compared to the 2025 version. Performance: Aletheia achieved a 95.1% accuracy on the IMO-Proof Bench Advanced, a major leap over the previous record of 65.7%. It also demonstrated state-of-the-art performance on FutureMath Basic, an internal benchmark of PhD-level exercises. Tool Use: To prevent citation hallucinations, Aletheia uses Google Search and web browsing. This helps it synthesize real-world mathematical literature. Research Milestones Aletheia has already contributed to several peer-reviewed milestones: Fully Autonomous (Feng26): Aletheia generated a research paper calculating structure constants called eigenweights without any human intervention. Collaborative (LeeSeo26): The agent provided a high-level roadmap and “big picture” strategy for proving bounds on independent sets, which human authors then turned into a rigorous proof. The Erdős Conjectures: Deployed against 700 open problems, Aletheia found 63 technically correct solutions and resolved 4 open questions autonomously. A Taxonomy for AI Autonomy DeepMind proposed a standard for classifying AI math contributions, similar to the levels used for autonomous vehicles. Level Autonomy Description Significance (Example) Level 0 Primarily Human Negligible Novelty (Olympiad level) Level 1 Human-AI Collaboration Minor Novelty (Erdős-1051) Level 2 Essentially Autonomous Publishable Research (Feng26) The paper Feng26 is classified as Level A2, meaning it is essentially autonomous and of publishable quality. Key Takeaways Introduction of a Research-Grade AI Agent: Aletheia is a math research agent that moves beyond competition-level solving to autonomously generate, verify, and revise mathematical proofs in natural language. It is powered by an advanced version of Gemini Deep Think and an agentic loop consisting of a Generator, Verifier, and Reviser. Significant Gains via Inference-Time Scaling: DeepMind Researchers found that allowing the model more ‘thinking time’ at inference yields substantial gains in accuracy. The January 2026 version of Deep Think reduced the compute required for Olympiad-level performance by 100x and achieved a record 95.1% accuracy on the IMO-Proof Bench Advanced. Milestones in Autonomous Research: The system achieved several ‘firsts,’ including a research paper (Feng26) generated entirely without human intervention regarding arithmetic geometry. It also successfully resolved 4 open questions from the Erdős Conjectures database autonomously. Critical Role of Tool Use and Verification: To combat ‘hallucinations’—such as fabricating paper citations—Aletheia relies heavily on Google Search and web browsing. Additionally, decoupling the verification step from the generation step proved essential for identifying flaws the model initially overlooked. Proposal for a New Autonomy Taxonomy: The paper suggests a standardized framework for documenting AI-assisted results, featuring axes for autonomy (Level H to Level A) and mathematical significance (Level 0 to Level 4). This is intended to provide transparency and close the “evaluation gap” between AI claims and professional mathematical standards. Check out the Paper. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google DeepMind Introduces Aletheia: The AI Agent Moving from Math Competitions to Fully Autonomous Professional Research Discoveries appeared first on MarkTechPost.

Google DeepMind Introduces Aletheia: The AI Agent Moving from Math Competitions to Fully Autonomous Professional Research Discoveries Leer entrada »

AI, Committee, Noticias, Uncategorized

US deputy health secretary: Vaccine guidelines are still subject to change

Over the past year, Jim O’Neill has become one of the most powerful people in public health. As the US deputy health secretary, he holds two roles at the top of the country’s federal health and science agencies. He oversees a department with a budget of over a trillion dollars. And he signed the decision memorandum on the US’s deeply controversial new vaccine schedule. He’s also a longevity enthusiast. In an exclusive interview with MIT Technology Review earlier this month, O’Neill described his plans to increase human healthspan through longevity-focused research supported by ARPA-H, a federal agency dedicated to biomedical breakthroughs. At the same time, he defended reducing the number of broadly recommended childhood vaccines, a move that has been widely criticized by experts in medicine and public health.  In MIT Technology Review’s profile of O’Neill last year, people working in health policy and consumer advocacy said they found his libertarian views on drug regulation “worrisome” and “antithetical to basic public health.”  He was later named acting director of the Centers for Disease Control and Prevention, putting him in charge of the nation’s public health agency. But fellow longevity enthusiasts said they hope O’Neill will bring attention and funding to their cause: the search for treatments that might slow, prevent, or even reverse human aging. Here are some takeaways from the interview.  Vaccine recommendations could change further Last month, the US cut the number of vaccines recommended for children. The CDC no longer recommends vaccinations against flu, rotavirus, hepatitis A, or meningococcal disease for all children. The move was widely panned by medical groups and public health experts. Many worry it will become more difficult for children to access those vaccines. The majority of states have rejected the recommendations.  In the confirmation hearing for his role as deputy secretary of health and human services, which took place in May last year, O’Neill said he supported the CDC’s vaccine schedule. MIT Technology Review asked him if that was the case and, if so, what made him change his mind. “Researching and examining and reviewing safety data and efficacy data about vaccines is one of CDC’s obligations,” he said. “CDC gives important advice about vaccines and should always be open to new data and new ways of looking at data.” At the beginning of December, O’Neill said, President Donald Trump “asked me to look at what other countries were doing in terms of their vaccine schedules.” He said he spoke to health ministries of other countries and consulted with scientists at the CDC and FDA. “It was suggested to me by lots of the operating divisions that the US focus its recommendations on consensus vaccines of other developed nations—in other words, the most important vaccines that are most often part of the core recommendations of other countries,” he said. “As a result of that, we did an update to the vaccine schedule to focus on a set of vaccines that are most important for all children.”  But some experts in public health have said that countries like Denmark and Japan, whose vaccine schedules the new US one was supposedly modeled on, are not really comparable to the US. When asked about these criticisms, O’Neill replied, “A lot of parents feel that … more than 70 vaccine doses given to young children sounds like a really high number, and some of them ask which ones are the most important. I think we helped answer that question in a way that didn’t remove anyone’s access.” A few weeks after the vaccine recommendations were changed, Kirk Milhoan, who leads the CDC’s Advisory Committee on Immunization Practices, said that vaccinations for measles and polio—which are currently required for entry to public schools—should be optional. (Mehmet Oz, the Center for Medicare and Medicaid Services director, has more recently urged people to “take the [measles] vaccine.”) “CDC still recommends that all children are vaccinated against diphtheria, tetanus, whooping cough, Haemophilus influenzae type b (Hib), Pneumococcal conjugate, polio, measles, mumps, rubella, and human papillomavirus (HPV), for which there is international consensus, as well as varicella (chickenpox),” he said when asked for his thoughts on this comment. He also said that current vaccine guidelines are “still subject to new data coming in, new ways of thinking about things.” “CDC, FDA, and NIH are initiating new studies of the safety of immunizations,” he added. “We will continue to ask the Advisory Committee on Immunization Practices to review evidence and make updated recommendations with rigorous science and transparency.” More support for longevity—but not all science O’Neill said he wants longevity to become a priority for US health agencies. His ultimate goal, he said, is to “make the damage of aging something that’s under medical control.” It’s “the same way of thinking” as the broader Make America Healthy Again approach, he said: “‘Again’ implies restoration of health, which is what longevity research and therapy is all about.”  O’Neill said his interest in longevity was ignited by his friend Peter Thiel, the billionaire tech entrepreneur, around 2008 to 2009. It was right around the time O’Neill was finishing up a previous role in HHS, under the Bush administration. O’Neill said Thiel told him he “should really start looking into longevity and the idea that aging damage could be reversible.” “I just got more and more excited about that idea,” he said. When asked if he’s heard of Vitalism, a philosophical movement for “hardcore” longevity enthusiasts who, broadly, believe that death is wrong, O’Neill replied: “Yes.”  The Vitalist declaration lists five core statements, including “Death is humanity’s core problem,” “Obviating aging is scientifically plausible,” and “I will carry the message against aging and death.” O’Neill said he agrees with all of them. “I suppose I am [a Vitalist],” he said with a smile, although he’s not a paying member of the foundation behind it. As deputy secretary of the Department of Health and Human Services, O’Neill assumes a level of responsibility for huge and influential science and health agencies, including the National Institutes of

US deputy health secretary: Vaccine guidelines are still subject to change Leer entrada »

AI, Committee, Noticias, Uncategorized

The myth of the high-tech heist

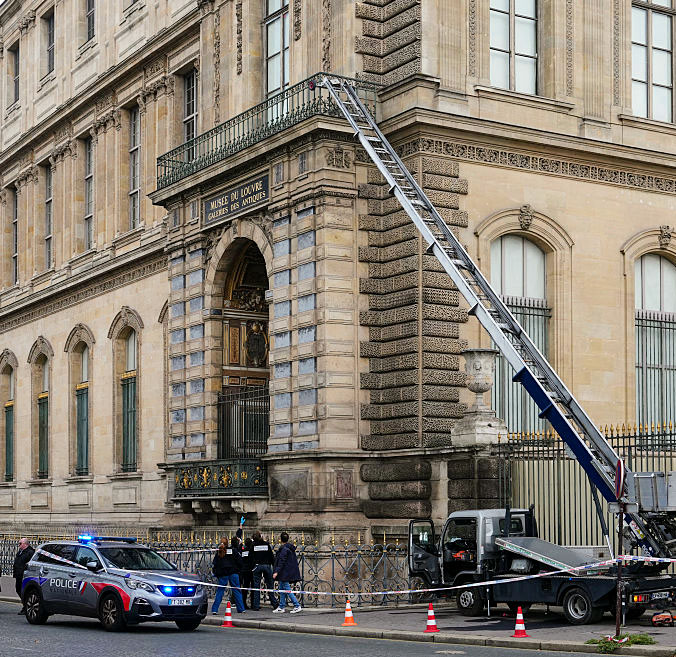
Making a movie is a lot like pulling off a heist. That’s what Steven Soderbergh—director of the Ocean’s franchise, among other heist-y classics—said a few years ago. You come up with a creative angle, put together a team of specialists, figure out how to beat the technological challenges, rehearse, move with Swiss-watch precision, and—if you do it right—redistribute some wealth. That could describe either the plot or the making of Ocean’s Eleven. But conversely, pulling off a heist isn’t much like the movies. Surveillance cameras, computer-controlled alarms, knockout gas, and lasers hardly ever feature in big-ticket crime. In reality, technical countermeasures are rarely a problem, and high-tech gadgets are rarely a solution. The main barrier to entry is usually a literal barrier to entry, like a door. Thieves’ most common move is to collude with, trick, or threaten an insider. Last year a heist cost the Louvre €88 million worth of antique jewelry, and the most sophisticated technology in play was an angle grinder. The low-tech Louvre maneuvers were in keeping with what heist research long ago concluded. In 2014 US nuclear weapons researchers at Sandia National Laboratories took a detour into this demimonde, producing a 100-page report called “The Perfect Heist: Recipes from Around the World.” The scientists were worried someone might try to steal a nuke from the US arsenal, and so they compiled information on 23 high-value robberies from 1972 to 2012 into a “Heist Methods and Characteristics Database,” a critical mass of knowledge on what worked. Thieves, they found, dedicated huge amounts of money and time to planning and practice runs—sometimes more than 100. They’d use brute force, tunneling through sewers for months (Société Générale bank heist, Nice, France, 1976), or guile, donning police costumes to fool guards (Gardner Museum, Boston, 1990). But nobody was using, say, electromagnetic pulse generators to shut down the Las Vegas electrical grid. The most successful robbers got to the valuable stuff unseen and got out fast. Last year a heist cost the Louvre €88 million worth of antique jewelry, and the most sophisticated technology in play was an angle grinder.DIMITAR DILKOFF / AFP VIA GETTY IMAGES Advance the time frame, and the situation looks much the same. Last year, Spanish researchers looking at art crimes from 1990 to 2022 found that the least technical methods are still the most successful. “High-tech technology doesn’t work so well,” says Erin L. Thompson, an art historian at John Jay College of Justice who studies art crime. Speed and practice trump complicated systems and alarms; even that Louvre robbery was, at heart, just a minutes-long smash-and-grab. An emphasis on speed doesn’t mean heists don’t require skill—panache, even. As the old saying goes, amateurs talk strategy; professionals study logistics. Even without gadgets, heists and heist movies still revel in an engineer’s mindset. “Heist movies absolutely celebrate deep-dive nerdery—‘I’m going to know everything I can about the power grid, about this kind of stone and drill, about Chicago at night,’” says Anna Kornbluh, a professor of English at the University of Illinois at Chicago. She published a paper last October on the ways heist movies reflect an Old Hollywood approach to collective art-making, while shows about new grift, like those detailing the rise and fall of WeWork or the con artist Anna Delvey, reflect the more lone-wolf, disrupt-and-grow mindset of the streaming era.  Her work might help explain why law-abiding citizens might cheer for the kinds of guys who’d steal a crown from the Louvre, or $100,000 worth of escargot from a farm in Champagne (as happened just a few weeks later). Heists, says Kornbluh, are anti-oligarch praxis. “Everybody wants to know how to be in a competent collective. Everybody wants there to be better logistics,” she says. “We need a better state. We need a better society. We need a better world.” Those are shared values—and as another old saying tells us, where there is value, there is crime.

The myth of the high-tech heist Leer entrada »

AI, Committee, Noticias, Uncategorized

What’s next for Chinese open-source AI

The past year has marked a turning point for Chinese AI. Since DeepSeek released its R1 reasoning model in January 2025, Chinese companies have repeatedly delivered AI models that match the performance of leading Western models at a fraction of the cost.  Just last week the Chinese firm Moonshot AI released its latest open-weight model, Kimi K2.5, which came close to top proprietary systems such as Anthropic’s Claude Opus on some early benchmarks.  The difference: K2.5 is roughly one-seventh Opus’s price. On Hugging Face, Alibaba’s Qwen family—after ranking as the most downloaded model series in 2025 and 2026—has overtaken Meta’s Llama models in cumulative downloads. And a recent MIT study found that Chinese open-source models have surpassed US models in total downloads. For developers and builders worldwide, access to near-frontier AI capabilities has never been this broad or this affordable. These models differ in a crucial way from most US models like ChatGPT or Claude, which you pay to access and can’t inspect. The Chinese companies publish their models’ weights—numerical values that get set when a model is trained—so anyone can download, run, study, and modify them.  If open-source AI models keep getting better, they will not just offer the cheapest options for people who want access to frontier AI capabilities; they will change where innovation happens and who sets the standards.  Here’s what may come next. China’s commitment to open source will continue When DeepSeek launched R1, much of the initial shock centered on its origin. Suddenly, a Chinese team had released a reasoning model that could stand alongside the best systems from US labs. But the long tail of DeepSeek’s impact had less to do with nationality than with distribution. R1 was released as an open-weight model under a permissive MIT license, allowing anyone to download, inspect, and deploy it. On top of that, DeepSeek also published a paper detailing its training process and techniques. For developers who access models via an API, DeepSeek also undercut competitors on price, offering access at a fraction the cost of OpenAI’s o1, the leading proprietary reasoning model at the time. Within days of its release, DeepSeek replaced ChatGPT as the most downloaded free app in the US App Store. The moment spilled beyond developer circles into financial markets, triggering a sharp sell-off in US tech stocks that briefly erased roughly $1 trillion in market value. Almost overnight, DeepSeek went from a little-known spin-off team backed by a quantitative hedge fund to the most visible symbol of China’s push for open-source AI. China’s decision to lean into open source isn’t surprising. It has the world’s second-largest concentration of AI talent after the US. plus a vast, well-resourced tech industry. After ChatGPT broke into the mainstream, China’s AI sector went through a reckoning—and emerged determined to catch up. Pursuing an open-source strategy was seen as the fastest way to close the gap by rallying developers, spreading adoption, and setting standards. DeepSeek’s success injected confidence into an industry long used to following global standards rather than setting them. “Thirty years ago, no Chinese person would believe they could be at the center of global innovation,” says Alex Chenglin Wu, CEO and founder of Atoms, an AI agent company and prominent contributor to China’s open-source ecosystem. “DeepSeek shows that with solid technical talent, a supportive environment, and the right organizational culture, it’s possible to do truly world-class work.” DeepSeek’s breakout moment wasn’t China’s first open-source success. Alibaba’s Qwen Lab had been releasing open-weight models for years. By September 2024,  well before DeepSeek’s V3 launch, Alibaba was saying that global downloads had exceeded 600 million. On Hugging Face, Qwen accounted for more than 30% of all model downloads in 2024. Other institutions, including the Beijing Academy of Artificial Intelligence and the AI firm Baichuan, were also releasing open models as early as 2023.  But since the success of DeepSeek, the field has widened rapidly. Companies such as Z.ai (formerly Zhipu), MiniMax, Tencent, and a growing number of smaller labs have released models that are competitive on reasoning, coding, and agent-style tasks. The growing number of capable models has sped up progress. Capabilities that once took months to make it to the open-source world now emerge within weeks, even days. “Chinese AI firms have seen real gains from the open-source playbook,” says Liu Zhiyuan, a professor of computer science at Tsinghua University and chief scientist at the AI startup ModelBest. “By releasing strong research, they build reputation and gain free publicity.” Beyond commercial incentives, Liu says, open source has taken on cultural and strategic weight. “In the Chinese programmer community, open source has become politically correct,” he says, framing it as a response to US.dominance in proprietary AI systems. That shift is also reflected at the institutional level. Universities including Tsinghua have begun encouraging AI development and open-source contributions, while policymakers have moved to formalize those incentives. In August, China’s State Council released a draft policy encouraging universities to reward open-source work, proposing that students’ contributions on platforms such as GitHub or Gitee could eventually be counted toward academic credit. With growing momentum and a reinforcing feedback loop, China’s push for open-source models is likely to continue in the near term, though its long-term sustainability still hinges on financial results, says Tiezhen Wang, who helps lead work on global AI at Hugging Face. In January, the model labs Z.ai and MiniMax went public in Hong Kong. “Right now, the focus is on making the cake bigger,” says Wang. “The next challenge is figuring out how each company secures its share.” The next wave of models will be narrower—and better Chinese open-source models are leading not just in download volume but also in variety. Alibaba’s Qwen has become one of the most diversified open model families in circulation, offering a wide range of variants optimized for different uses. The lineup ranges from lightweight models that can run on a single laptop to large, multi-hundred-billion-parameter systems designed for data-center deployment. Qwen features many task-optimized variants created by the

What’s next for Chinese open-source AI Leer entrada »

AI, Committee, Noticias, Uncategorized

Context-level Language Modeling by Learning Predictive Context Embeddings

arXiv:2510.20280v3 Announce Type: replace Abstract: We propose ContextLM, a framework that implicitly learns multi-token prediction by augmenting standard pretraining with an intrinsic next-context prediction objective. ContextLM builds a language model on top of context embeddings that span multiple tokens, enabling better next-token prediction by predicting the next context. Our model is fully compatible with standard autoregressive, token-by-token evaluation paradigms (e.g., perplexity). Extensive experiments with GPT-2 and Pythia backbones (up to 1.5B parameters and 300B training tokens) reveal that ContextLM shifts the Pareto frontier of scaling laws, exhibiting superior efficiency in parameters, training tokens, and FLOPs. Our results show that ContextLM could already achieve the baseline perplexity using 39% fewer parameters and demonstrates robust generalization improvements on extensive downstream tasks under equivalent parameter counts.

Context-level Language Modeling by Learning Predictive Context Embeddings Leer entrada »

AI, Committee, Noticias, Uncategorized

Why EVs are gaining ground in Africa

EVs are getting cheaper and more common all over the world. But the technology still faces major challenges in some markets, including many countries in Africa. Some regions across the continent still have limited grid and charging infrastructure, and those that do have widespread electricity access sometimes face reliability issues—a problem for EV owners, who require a stable electricity source to charge up and get around. But there are some signs of progress. I just finished up a story about the economic case: A recent study in Nature Energy found that EVs from scooters to minibuses could be cheaper to own than gas-powered vehicles in Africa by 2040. If there’s one thing to know about EVs in Africa, it’s that each of the 54 countries on the continent faces drastically different needs, challenges, and circumstances. There’s also a wide range of reasons to be optimistic about the prospects for EVs in the near future, including developing policies, a growing grid, and an expansion of local manufacturing.   Even the world’s leading EV markets fall short of Ethiopia’s aggressively pro-EV policies. In 2024, the country became the first in the world to ban the import of non-electric private vehicles. The case is largely an economic one: Gasoline is expensive there, and the country commissioned Africa’s largest hydropower dam in September 2025, providing a new source of cheap and abundant clean electricity. The nearly $5 billion project has a five-gigawatt capacity, doubling the grid’s peak power in the country.   Much of Ethiopia’s vehicle market is for used cars, and some drivers are still opting for older gas-powered vehicles. But this nudge could help increase the market for EVs there.   Other African countries are also pushing some drivers toward electrification. Rwanda banned new registrations for commercial gas-powered motorbikes in the capital city of Kigali last year, encouraging EVs as an alternative. These motorbike taxis can make up over half the vehicles on the city’s streets, so the move is a major turning point for transportation there.  Smaller two- and three-wheelers are a bright spot for EVs globally: In 2025, EVs made up about 45% of new sales for such vehicles. (For cars and trucks, the share was about 25%.) And Africa’s local market is starting to really take off. There’s already some local assembly of electric two-wheelers in countries including Morocco, Kenya, and Rwanda, says Nelson Nsitem, lead Africa energy transition analyst at BloombergNEF, an energy consultancy.  Spiro, a Dubai-based electric motorbike company, recently raised $100 million in funding to expand operations in Africa. The company currently assembles its bikes in Uganda, Kenya, Nigeria, and Rwanda, and as of October it has over 60,000 bikes deployed and 1,500 battery swap stations operating. Assembly and manufacturing for larger EVs and batteries is also set to expand. Gotion High-Tech, a Chinese battery company, is currently building Africa’s first battery gigafactory. It’s a $5.6 billion project that could produce 20 gigawatt-hours of batteries annually, starting in 2026. (That’s enough for hundreds of thousands of EVs each year.) Chinese EV companies are looking to growing markets like Southeast Asia and Africa as they attempt to expand beyond an oversaturated domestic scene. BYD, the world’s largest EV company, is aggressively expanding across South Africa and plans to have as many as 70 dealerships in the country by the end of this year. That will mean more options for people in Africa looking to buy electric.  “You have very high-quality, very affordable vehicles coming onto the market that are benefiting from the economies of scale in China. These countries stand to benefit from that,” says Kelly Carlin, a manager in the program on carbon-free transportation at the Rocky Mountain Institute, an energy think tank. “It’s a game changer,” he adds. This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here.

Why EVs are gaining ground in Africa Leer entrada »

We use cookies to improve your experience and performance on our website. You can learn more at Política de privacidad and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
es_ES