YouZum

News

AI, Committee, News, Uncategorized

The Download: Chinese AI divides the White House, and a record copyright payout

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. China’s AI models have Trump’s AI world at war with itself Last weekend, several current and former advisers to President Donald Trump on AI publicly lobbed insults at the country’s leading AI companies. David Sacks branded Anthropic’s models “lobotomized” and “woke.” Emil Michael, a top Pentagon official, called OpenAI’s new head of strategic futures a “supreme village idiot.” It began because no one can agree on what to do about Kimi, a free, open-source model that Chinese AI company Moonshot launched last week. It appears to rival the intelligence of models from OpenAI and Anthropic, which are very much not free.  Every time a new smart, free model from China gets released, US companies see less reason to fork out money for models from Anthropic or OpenAI. That’s creating economic and political problems for the president—and dividing the top AI strategists in his orbit.  Read the full story on why no one can agree what to do about Kimi. —James O’Donnell This article is from The Algorithm, our weekly AI newsletter. Sign up to receive it in your inbox every Monday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Anthropic’s record $1.5 billion copyright settlement has been approvedThe plaintiffs said Anthropic used pirated works to train Claude. (Reuters $)+ And won the largest known copyright payout in history. (Engadget)+ Yet many authors and creators still don’t view it as a win. (TechCrunch)+ But AI copyright anxiety could limit creativity. (MIT Technology Review) 2 The Trump administration is weighing a ban on Chinese AI modelsThe launch of Kimi K3 has revived calls for restrictions. (Axios)+ But officials are divided on the proposals. (Fast Company)+ China’s bet on open-source is paying off. (MIT Technology Review) 3 China is mulling tighter export controls on AI models and chipsIt wants to stop the West from acquiring its tech and startups. (FT $)+ Beijing has held talks with tech firms about potential restrictions. (Reuters $) 4 Trump’s AI safety head has resigned after just three monthsChris Fall had led CAISI, the federal AI Safety Institute, since April. (Axios)+ No reason was given for his exit. (CNBC) 5 Google is working on a new chip to run Gemini models more efficiently The chip, called “Frozen V2,” may be deployed in 2028. (Information $)+ Alphabet stock popped on the report. (CNBC) 6 New Orleans police have explored arming drones with weaponsA draft drone manual paves the way for weaponised quadcopters. (404 Media)+ Shoplifters could soon be chased by drones. (MIT Technology Review) 7 The EU has handed AliExpress a record fine over unsafe product salesThe €550 million fine is the largest-ever under the Digital Services Act. (BBC)+ Alibaba has vowed to appeal the fine. (SCMP) 8 Election advice from AI chatbots is “inaccurate and unreliable”That’s the conclusion from tests in Hungary earlier this year. (Guardian) 9 Red light therapy is showing promise for healing and healthy agingBetter skin and reduced vision loss are also on the cards. (Economist $) 10 Neill Blomkamp’s new horror clip is all AI-generated—and it sucksThe acclaimed director wants to make “a full feature in this format.” (Gizmodo) Quote of the day “This would be a terribly self-defeating form of intervention if it were to happen.”  —Tech investor Chamath Palihapitiya slams plans to restrict Chinese AI models in a post on X. One More Thing AKILAH TOWNSEND Inside Chicago’s surveillance panopticon Early on the morning of September 2, 2024, four people were shot and killed on a westbound train in Chicago. Police swiftly activated a digital dragnet—a surveillance network that connects thousands of cameras across the city—and arrested the suspect just 90 minutes later. Law enforcement and security advocates say this vast monitoring system protects public safety and works well. But activists and many residents say it’s a surveillance panopticon that creates a chilling effect on behavior and violates guarantees of privacy and free speech. Go inside the surveillance network that’s dividing Chicago. —Rod McCullom We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + NASA has shared a stunning timelapse video of the Psyche spacecraft’s view of Mars.+ This comparison of American and European Urbanism shows good city design is a choice.+ Musician Luca Stricagnoli recently performed a marvellous acoustic guitar medley of Prodigy songs.+ Two Australian paddleboarders saved a stranded wallaby after it was swept out to sea—and caught the whole rescue on video.

The Download: Chinese AI divides the White House, and a record copyright payout Read Post »
AI, Committee, News, Uncategorized

Validating Distributed LLM Serving Benchmarks with NVIDIA srt-slurm, SLURM Recipes, Parameter Sweeps, and Pareto Analysis

In this tutorial, we explore NVIDIA’s srt-slurm framework and learn how we use srtctl to convert declarative YAML configurations into reproducible SLURM benchmark workflows for distributed LLM serving. We set up the project in Google Colab, inspect its internal architecture, define a cluster configuration, dry-run built-in and custom recipes, and model a disaggregated prefill-and-decode deployment for DeepSeek-R1. We also generate parameter sweeps, interact with the typed Python API, validate expanded configurations, and analyze simulated benchmark results through a throughput-versus-latency Pareto frontier. Although Colab does not provide a real SLURM environment, we use it as a practical development workspace to understand, validate, and prepare production-grade benchmark recipes before we submit them to an actual GPU cluster. Copy CodeCopiedUse a different Browser import os, sys, subprocess, textwrap, json, shutil, importlib from pathlib import Path def run(cmd, check=True, quiet=False): “””Run a shell command, stream output.””” print(f”n$ {cmd}”) r = subprocess.run(cmd, shell=True, text=True, capture_output=True) out = (r.stdout or “”) + (r.stderr or “”) if not quiet: print(out[-6000:]) if check and r.returncode != 0: raise RuntimeError(f”Command failed ({r.returncode}): {cmd}”) return out def section(title): print(“n” + “═”*78 + f”n {title}n” + “═”*78) section(“1. Install srt-slurm”) REPO = Path(“/content/srt-slurm”) if Path(“/content”).exists() else Path.cwd()/”srt-slurm” if not REPO.exists(): run(f”git clone –depth 1 https://github.com/NVIDIA/srt-slurm.git {REPO}”, quiet=True) run(f”{sys.executable} -m pip install -q -e {REPO}”, quiet=True) sys.path.insert(0, str(REPO / “src”)) importlib.invalidate_caches() os.chdir(REPO) run(“srtctl –help”) We prepare the Colab environment by importing the required modules and defining reusable helper functions for command execution and section formatting. We clone the NVIDIA srt-slurm repository, install it in editable mode, and expose its source directory to the active Python runtime. We then switch to the repository directory and verify that the srtctl command-line interface is installed correctly. Copy CodeCopiedUse a different Browser section(“2. Repository architecture”) print(textwrap.dedent(“”” src/srtctl/ cli/ submit.py (apply/dry-run/preflight/monitor), do_sweep, interactive core/ schema.py (typed config), sweep.py, slurm.py (sbatch gen), validation.py, health.py, topology.py, fingerprint.py backends/ sglang.py, trtllm.py, vllm.py, mocker.py ← engine adapters frontends/ Dynamo / router frontends templates/ Jinja2 → sbatch + orchestrator scripts recipes/ ready-made benchmarks per platform (gb200-fp4, h100, b200-fp8, qwen3-32b, dsv4-pro, mocker smoke tests, …) analysis/ srtlog (log parsers) + Streamlit dashboard (Pareto, latency…) docs/ sweeps.md, profiling.md, analyzing.md, config-reference.md “””)) for d in [“recipes”, “docs”]: print(f”{d}/ →”, “, “.join(sorted(p.name for p in (REPO/d).iterdir()))[:300]) section(“3. Cluster configuration (srtslurm.yaml)”) (REPO/”srtslurm.yaml”).write_text(textwrap.dedent(“”” cluster: “colab-demo” default_account: “demo-account” default_partition: “gpu” default_time_limit: “01:00:00” gpus_per_node: 4 use_gpus_per_node_directive: true use_segment_sbatch_directive: true containers: dynamo-sglang: “/containers/dynamo-sglang.sqsh” lmsysorg+sglang+v0.5.5.post2.sqsh: “/containers/sglang-v0.5.5.sqsh” model_paths: deepseek-r1: “/models/DeepSeek-R1” “””)) print((REPO/”srtslurm.yaml”).read_text()) We inspect the repository structure to understand how srtctl organizes its command-line tools, schemas, backends, templates, recipes, and analysis components. We then create a local srtslurm.yaml file containing simulated cluster defaults, container aliases, GPU settings, and model paths. We use this configuration to resolve recipe references in Colab without requiring access to an actual SLURM cluster. Copy CodeCopiedUse a different Browser section(“4. Dry-run: mocker smoke test → generated sbatch script”) run(“srtctl dry-run -f recipes/mocker/agg.yaml”, check=False) section(“5. Custom disaggregated recipe (prefill/decode split)”) (REPO/”my-disagg.yaml”).write_text(textwrap.dedent(“”” name: “colab-disagg-demo” model: path: “deepseek-r1” container: “lmsysorg+sglang+v0.5.5.post2.sqsh” precision: “fp8” resources: gpu_type: “gb200” gpus_per_node: 4 prefill_nodes: 1 decode_nodes: 2 prefill_workers: 1 decode_workers: 2 backend: prefill_environment: { PYTHONUNBUFFERED: “1” } decode_environment: { PYTHONUNBUFFERED: “1” } sglang_config: prefill: served-model-name: “deepseek-ai/DeepSeek-R1” model-path: “/model/” trust-remote-code: true kv-cache-dtype: “fp8_e4m3” tensor-parallel-size: 4 disaggregation-mode: “prefill” decode: served-model-name: “deepseek-ai/DeepSeek-R1” model-path: “/model/” trust-remote-code: true kv-cache-dtype: “fp8_e4m3” tensor-parallel-size: 4 disaggregation-mode: “decode” benchmark: type: “sa-bench” isl: 1024 osl: 1024 concurrencies: [64, 128, 256] req_rate: “inf” “””)) run(“srtctl dry-run -f my-disagg.yaml”, check=False) We dry-run the built-in mocker recipe to examine how srtctl validates configurations and generates SLURM submission artifacts without executing a real benchmark. We then define an advanced DeepSeek-R1 recipe that separates prefill and decode workloads across independent node and worker pools. We validate this disaggregated SGLang configuration through another dry run and inspect how the serving parameters are translated into job scripts. Copy CodeCopiedUse a different Browser section(“6. Parameter sweep (grid search) — dry-run + expansion on disk”) run(“srtctl dry-run -f examples/example-sweep.yaml”, check=False) sweep_dirs = sorted((REPO/”dry-runs”).glob(“example-sweep_sweep_*”)) if sweep_dirs: latest = sweep_dirs[-1] print(“Per-job configs generated by the sweep expander:”) for p in sorted(latest.rglob(“config.yaml”)): print(” “, p.relative_to(REPO)) section(“7. Programmatic use of srtctl’s Python API”) import yaml from srtctl.core.config import load_config from srtctl.core.sweep import generate_sweep_configs, expand_template from srtctl.core.schema import BenchmarkType, Precision, GpuType cfg = load_config(“my-disagg.yaml”) print(f”Loaded : {cfg.name}”) print(f”Model : {cfg.model.path} ({cfg.model.precision}) on {cfg.resources.gpu_type}”) print(f”Layout : {cfg.resources.prefill_nodes}P + {cfg.resources.decode_nodes}D nodes, ” f”{cfg.resources.gpus_per_node} GPUs/node”) print(f”Bench : {cfg.benchmark.type} isl={cfg.benchmark.isl} osl={cfg.benchmark.osl} ” f”concurrencies={cfg.benchmark.concurrencies}”) print(f”Enums : benchmarks={[b.value for b in BenchmarkType]}”) print(f” precisions={[p.value for p in Precision]}, gpus={[g.value for g in GpuType]}”) raw_sweep = yaml.safe_load(Path(“examples/example-sweep.yaml”).read_text()) jobs = generate_sweep_configs(raw_sweep) print(f”nSweep expands to {len(jobs)} jobs:”) for job_cfg, params in jobs: pf = job_cfg[“backend”][“sglang_config”][“prefill”] print(f” {params} → chunked-prefill-size={pf[‘chunked-prefill-size’]}, ” f”max-total-tokens={pf[‘max-total-tokens’]}”) print(“nTemplate substitution:”, expand_template({“flag”: “{x}”, “n”: “{y}”}, {“x”: 4096, “y”: 2})) We execute the example parameter sweep and inspect the individual job configurations created from its Cartesian search space. We load our custom recipe through the typed Python API and examine its model, precision, GPU topology, benchmark settings, and supported enumeration values. We also programmatically expand sweep templates and verify how each parameter combination affects the generated backend configuration. Copy CodeCopiedUse a different Browser section(“8. Analysis: Pareto frontier from (simulated) benchmark results”) import numpy as np, matplotlib.pyplot as plt rng = np.random.default_rng(0) def simulate(variant, base_tps, base_itl): rows = [] tps_gpu = base_tps * c / (c + 90) * rng.uniform(.97, 1.03) itl = base_itl * (1 + c/220) * rng.uniform(.97, 1.03) rows.append({“variant”: variant, “concurrency”: c, “tok_s_gpu”: tps_gpu, “itl_ms”: itl}) return rows results = simulate(“chunked=4096”, 260, 9.5) + simulate(“chunked=8192”, 300, 11.5) print(json.dumps(results[:3], indent=2), “…”) plt.figure(figsize=(8, 5)) for variant in (“chunked=4096”, “chunked=8192”): pts = [(r[“itl_ms”], r[“tok_s_gpu”], r[“concurrency”]) for r in results if r[“variant”] == variant] xs, ys, cs = zip(*pts) plt.plot(xs, ys, “o-“, label=variant) for x, y, c in pts: plt.annotate(str(c), (x, y), fontsize=7, xytext=(3, 3), textcoords=”offset points”) plt.xlabel(“Inter-token latency (ms/token) → worse”) plt.ylabel(“Throughput (tokens/s/GPU) → better”) plt.title(“Pareto frontier: sweep variants (points labeled by concurrency)”) plt.legend(); plt.grid(alpha=.3); plt.tight_layout(); plt.show() We simulate benchmark observations for two chunked-prefill variants across increasing concurrency levels. We calculate representative throughput per GPU and inter-token latency values to model the saturation and latency growth commonly observed in distributed

Validating Distributed LLM Serving Benchmarks with NVIDIA srt-slurm, SLURM Recipes, Parameter Sweeps, and Pareto Analysis Read Post »

AI, Committee, News, Uncategorized

Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber: A Cheaper, More Token-Efficient Flash Tier Built for Agentic Workloads

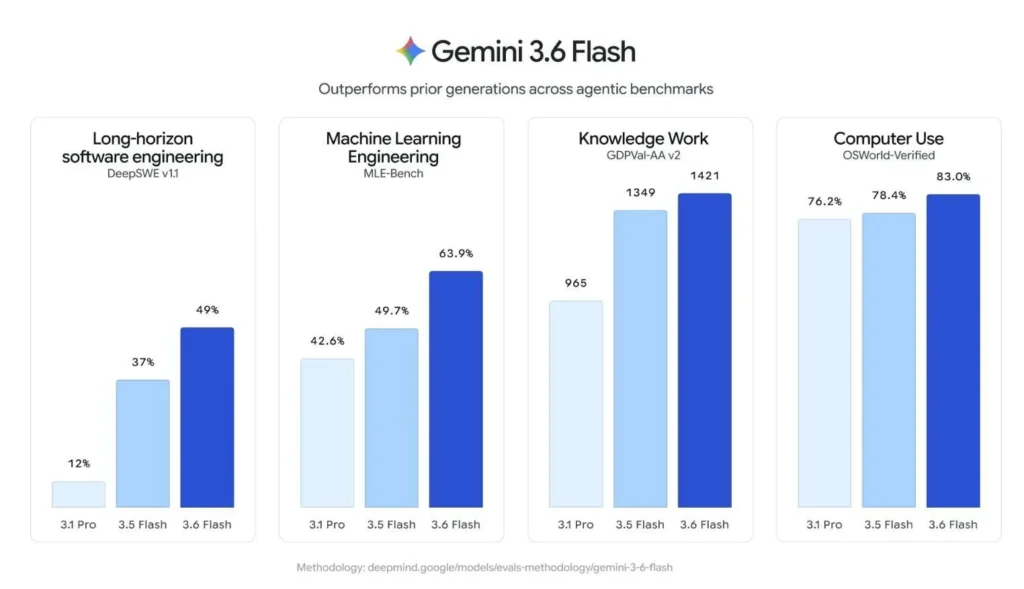
Developers building production agents need higher token efficiency, lower latency, and more reliable performance. Today, Google has released three new Gemini models. The lineup is Gemini 3.6 Flash, Gemini 3.5 Flash-Lite, and Gemini 3.5 Flash Cyber. All three sit in the Flash tier, which Google tunes for speed, cost, and high-volume agentic work rather than maximum reasoning depth. Gemini 3.6 Flash: better quality, fewer tokens, lower price Gemini 3.6 Flash is the new default workhorse. It builds on 3.5 Flash and targets coding, knowledge work, and multimodal tasks. The main point is efficiency. On the Artificial Analysis Index, 3.6 Flash uses 17% fewer output tokens than 3.5 Flash. On the DeepSWE benchmark by Datacurve, Google reports up to a 65% reduction. The model also takes fewer reasoning steps and tool calls per multi-step workflow. Pricing moves down alongside efficiency. Gemini 3.6 Flash is priced at $1.50 per 1M input tokens and $7.50 per 1M output tokens. The output rate drops from the previous $9.00 on 3.5 Flash. Lower verbosity and a lower output price reduces the total cost per agentic task. Quality gains accompany the efficiency gains. On DeepSWE, 3.6 Flash scores 49% versus 37% for 3.5 Flash. On MLE Bench, it reaches 63.9% versus 49.7%. On OSWorld-Verified, it hits 83.0% versus 78.4%. On GDPval-AA v2, a knowledge-work benchmark, it scores 1421 versus 1349. Computer use is now a built-in client-side tool through the Gemini API and Gemini Enterprise. Early customers including Hebbia and Harvey cite gains in document parsing, chart and data analysis, and report drafting. Google is shipping 3.6 Flash with enhanced Frontier Safety safeguards. These cover Chemical, Biological, Radiological, and Nuclear (CBRN) and cyber-offense misuse. Full details are in the 3.6 Flash model card. The interactive explainer below lets you compare each model against its predecessor and estimate token cost at your own volume. Gemini 3.5 Flash-Lite: the fastest model in the 3.5 line Gemini 3.5 Flash-Lite is highlighted for low-latency and high-throughput jobs. Target use cases include agentic search and document processing. As measured by Artificial Analysis, it runs at 350 output tokens per second. Pricing is $0.30 per 1M input tokens and $2.50 per 1M output tokens. The model clears the prior 3.1 Flash-Lite by wide margins. On Terminal-Bench 2.1, it scores 54% versus 31%. On GDM-MRCR v2, a long-context benchmark, it reaches 72.2% versus 60.1%. On GDPval-AA v2, it scores 1140 versus 642. Notably, Flash-Lite also beats the older 3 Flash on some evals. It leads on SWE-Bench Pro at 54.2% versus 49.6% and on OSWorld-Verified at 74.0% versus 65.1%. Flash-Lite exposes configurable thinking levels: minimal, low, and higher. Developers can prioritize low-cost, low-latency execution for high-volume tasks. They can also engage higher thinking levels for multi-step subagent workloads. Computer use is a built-in tool here too. Gemini 3.5 Flash Cyber in CodeMender: cheap agents that find and patch bugs Gemini 3.5 Flash Cyber is the most specialized release. It is built on 3.5 Flash and fine-tuned to find, validate, and patch software vulnerabilities. The design premise is the search-space problem. Finding deep flaws means exploring an immense execution search space. A single call to one massive model becomes a bottleneck. The answer is a cheap model called many times. Inside CodeMender, Google’s code-security agent, multiple 3.5 Flash Cyber agents run in parallel. CodeMender invokes the model up to five times, then merges the sub-agent findings into one report. On the CyberGym benchmark, this setup reaches competitive performance against much larger models. The internal evaluations are striking. On Google’s Big Sleep evaluation, Flash Cyber significantly surpassed mainline 3.5 Flash and 3.6 Flash. On the V8 JavaScript engine, it found 55 unique confirmed issues at a fixed number of invocations. That compares to 47 for mainline 3.5 Flash and 36 for Claude Opus 4.6. It caught 10 issues the other two models missed. In one real-world test, Google’s Cloud Vulnerability Research team used it to find remote-code-execution flaws in public APIs within two hours. https://blog.google/innovation-and-ai/models-and-research/gemini-models/gemini-3-6-flash-3-5-flash-lite-3-5-flash-cyber/ Community Reaction Reaction split along predictable lines. Builders welcomed the price and efficiency. The delayed flagship drew the loudest criticism. On Hacker News, some argued Google is over-selling capacity it cannot reliably provision, citing frustrating hands-on coding sessions. The gated Flash Cyber release opened a dual-use debate about who should hold automated exploit-finding tools. The dashboard below aggregates that discussion by platform. It is a qualitative editorial synthesis, not a scraped dataset, and the method note is embedded. Availability Gemini 3.6 Flash and 3.5 Flash-Lite are available starting today. Developers can access them through the Gemini API via Google AI Studio and Android Studio. Gemini 3.6 Flash is also in Google Antigravity and rolling out in GitHub Copilot. Enterprises get both models in the Gemini Enterprise Agent Platform, with 3.6 Flash in the Gemini Enterprise app. Everyone can use them via the Gemini app, and 3.5 Flash-Lite is rolling out in Google Search. Start with the Developer Guide. Key Takeaways Gemini 3.6 Flash cuts output tokens by 17% (up to 65% on DeepSWE) and drops the output price from $9.00 to $7.50 per 1M. Gemini 3.5 Flash-Lite runs at 350 tokens/sec for $0.30/$2.50 per 1M and beats the older 3 Flash on SWE-Bench Pro and OSWorld-Verified. Gemini 3.5 Flash Cyber powers CodeMender with cheap multi-agent scans; it found 55 unique V8 issues versus 47 and 36 for 3.5 Flash and Opus 4.6. Flash Cyber is gated to governments and trusted partners under a limited-access pilot due to dual-use risk. The post Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber: A Cheaper, More Token-Efficient Flash Tier Built for Agentic Workloads appeared first on MarkTechPost.

Google Releases Gemini 3.6 Flash, 3.5 Flash-Lite, and 3.5 Flash Cyber: A Cheaper, More Token-Efficient Flash Tier Built for Agentic Workloads Read Post »

AI, Committee, News, Uncategorized

Adaptive Multi-Step Lookahead Decoding for Diffusion Language Models

arXiv:2607.15655v1 Announce Type: new Abstract: Masked diffusion language models (DLMs) enable parallel text generation by iteratively refining masked tokens, offering a promising alternative to autoregressive decoding. Recent lookahead-based decoding methods improve the accuracy–efficiency trade-off by exploring future decoding states before committing token updates. However, existing approaches mainly rely on shallow one-step lookahead, which optimizes immediate information gain but can be suboptimal for longer-horizon decoding trajectories. Meanwhile, we find that a naive extension for deeper lookahead is also ineffective, as fixed-depth rollout introduces additional computation and cannot adapt to heterogeneous intermediate decoding states. Thus, in this work, we propose AdaLook, an adaptive lookahead framework for DLM decoding. AdaLook dynamically determines whether to continue rollout based on candidate-score variance and further enables branch expansion when intermediate rollout states require additional exploration. This design avoids unnecessary deep rollout while allowing the decoder to re-trigger lookahead from informative intermediate states. Experiments on various benchmarks and models demonstrate that AdaLook achieves a better accuracy–decoding steps trade-off than existing one-step lookahead decoding methods.

Adaptive Multi-Step Lookahead Decoding for Diffusion Language Models Read Post »

AI, Committee, News, Uncategorized

AI is more likely than humans to form biases when hiring

The next time you apply for a job, AI may screen your résumé before any human sees it. But there’s good reason to question whether AI will judge you fairly. Researchers already know that LLMs pick up human biases from their training data. New research suggests that LLMs can also develop their own biases from experience—and stereotype job applicants more than humans do. As AI companies race to build agentic models that remember the tiniest details about users, they may be handing them ammunition for forming those biases.  Researchers at Princeton University and the University of Chicago ran LLMs, including ChatGPT, Claude, and Gemini, through a simulated hiring game, adapted from a psychology study that explored how humans can form stereotypes. Each model was told it had been hired as a consultant by the mayor of a fictional city and was then asked to help hire people for 20 jobs, including doctors, lawyers, child-care aides, and janitors. Candidates came from four fictional ethnic groups: Tufa, Aima, Reku, and Weki.  In each round, there was a new job opening and four candidates, one from each group. After the model hired a candidate, it learned whether they succeeded at their job and moved onto the next round. The model was told to make as many successful hires as possible over 40 rounds. Unbeknownst to the models, all candidates were equally likely to succeed at every job. The models quickly started segregating candidates from different groups into different jobs on the basis of early observations of hiring outcomes. For example, when a model was told an Aima had failed as a doctor, a job considered to require high levels of warmth and competence, it veered away from hiring all Aimas as doctors. Instead, it started hiring Aimas as janitors, which the model classified as being less warm and competent than doctors.  The models were even more likely to stereotype people by demographic group than the human participants in the original study. On the study’s segregation scale, where 2 means every group has been completely confined to its own job niche, human participants scored 0.84. The models scored roughly 65% higher, with OpenAI’s reasoning model o3 scoring 1.83, close to the maximum possible. That’s because LLMs “really are eager to create generalizations from limited data,” says Ryan Liu, a PhD student at Princeton University and a coauthor of the study, which was published in a paper at ICML in Seoul in July. “That’s literally a lot of what they’re optimized for.” Every decision-maker, human or machine, faces a trade-off between sticking with what worked before and trying something new that might work better—a phenomenon psychologists call the “exploration-exploitation dilemma.” It’s like choosing between a new restaurant and your reliable favorite.  Because LLMs are trained on math, coding, and science problems—tasks that reward generalizing from just a few examples—they can settle on a hunch too early. And the same instinct that helps LLMs crack logic puzzles also makes them quick to stereotype. In the experiment, newer models with higher reasoning capabilities, such as OpenAI’s o3 and DeepSeek’s R1, showed even stronger biases. When LLMs rush to generalize in social settings, “that’s when things tend to go wrong,” says Liu. OpenAI and Anthropic did not respond to requests for comment. The finding is especially relevant now that chatbots are gaining improved memory and personalization features, says Angelina Wang, a computer scientist at Cornell University who did not work on the study. When a chatbot draws on its previous conversation history, it can “over-index on the same kinds of behaviors it’s experienced before” and form biases, she says. Simply having chatbots remember less isn’t a fix, though, because users want chatbots to remember what they say. “We still are trying to figure out just the right amount that isn’t too much or too little,” says Wang. Telling the model to be fair didn’t change its behavior much. “Either it can’t put these values into action or that process is being submerged under the tendency to try to optimize for the goal of getting the most correct hires,” says Liu. But promising the models an additional bonus for diverse hiring made them far less biased. The trick, then, is to design goals that “incorporate desirable social values in order to make the large language model act in socially desirable ways,” says Liu. The models also became less biased when they were told more personal information about individuals. In another experiment in the same study, the researchers asked the models to resettle members of different ethnic groups in cities across Canada. When the models were told personal information relevant to the ability to adapt to a new city, such as age and education, they were less likely to segregate people by their ethnicity. But when they were given irrelevant information, such as hair color and tattoo shape, the models largely fell back to sorting people by their ethnicity again.  To what extent AI systems will stereotype job applicants in the real world is still an open question. While the models in the experiment immediately learned whether they’d made successful hires, a model screening résumés in the real world doesn’t get an instant report card. Companies can take a long time to find out whether a new hire is any good.  But when feedback does trickle in, a model could still read too much into those results when making future hires. As companies increasingly deploy LLMs to screen résumés and even conduct interviews, the finding that models can form biases from their hiring experience “is a really serious implication that they should grapple with,” says Wang.  As LLMs learn from experience to make decisions about who gets hired, who gets a loan, or who gets parole, the biases we should worry about may include ones no human ever taught them. “These novel biases—they’re sort of ever present,” says Liu.

AI is more likely than humans to form biases when hiring Read Post »

AI, Committee, News, Uncategorized

The Download: AI hiring biases, and weather data sabotage

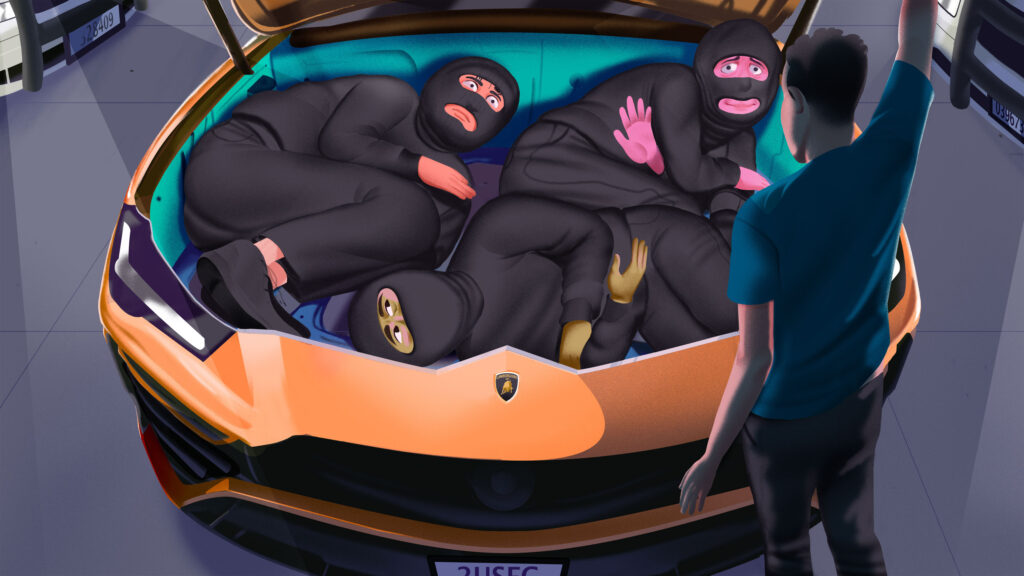
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. AI is more likely than humans to form biases when hiring The next time you apply for a job, AI may screen your résumé before any human sees it. But there’s good reason to question whether AI will judge you fairly.  We already know that LLMs pick up human biases from their training data. New research suggests they can also develop their own biases from experience—and stereotype job applicants more than humans do. As AI companies race to build agentic models that remember the tiniest details about users, they may be handing them ammunition for forming those biases.  Read the full story on AI’s alarming potential to stereotype job applicants. —Michelle Kim The risk of weather data sabotage is rising Every morning, airline dispatchers, grid operators, and farmers around the world make decisions based on weather forecasts. More recently, the forecasts have become relevant for another industry: prediction markets, where people bet money on all kinds of real-world events, including the weather.  The temptation to manipulate weather data to get an edge in these markets, combined with a collective move toward data-driven AI weather forecasting, is starting to put the accuracy of weather predictions at risk.  As experts in the field, we can foresee scenarios where the risks snowball into far bigger, more systemic problems.  Find out why the threats to weather data are growing—and how to stay ahead of them. —Monique Kuglitsch, Jesper Dramsch, Franz G. Kuglitsch, & Andrea Toreti The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 SpaceX is negotiating to sell the Pentagon AI computeIt would provide data center capacity worth billions of dollars. (WSJ $)+ Deepening ties between Elon Musk’s company and the DoD. (Reuters $)+ Meanwhile, Anthropic is in talks with Meta to acquire compute. (CNBC)+ The compute explosion is only just beginning. (MIT Technology Review) 2 Trump Media wants $100,000 a month for early access to Trump’s postsThe premium feed is being pitched to trading firms and banks. (FT $)+ It aims to monetize Trump’s market-moving social media posts. (Reuters $)+ Critics described the plan as “brazen corruption.” (Guardian) 3 ICE shared Medicaid data it wasn’t supposed to have with PalantirCourt filings show the data reached the contractor before being deleted. (NPR)+ ICE is using data broker tools to identify “unaccompanied minors.” (Wired $)  4 Apple briefly overtook Nvidia as the world’s most valuable companyThe iPhone maker’s earnings durability has impressed investors. (Reuters $)+ While Nvidia’s rise has stalled amid shifting AI bets. (CNBC) 5. Politicians are trying to change what chatbots say about themA new industry has sprung up to help them edit AI outputs. (NYT $)+ Chatbots can sway voters better than political ads. (MIT Technology Review) 6 Washington is opening the door to armed robotsThe Pentagon is accelerating AI weapons development. (WP $)+ “Humans in the loop” in war is an illusion. (MIT Technology Review) 7 China’s Moonshot has paused new subscriptions amid surging uptakeDemand for the headline-grabbing Kimi ​K3 has strained capacity. (SCMP)+ China’s open-source AI is challenging US models. (MIT Technology Review) 8 Lab-grown teeth could soon replace fillings and implantsScientists believe regenerative medicine could transform dentistry. (BBC)+ Humanlike “teeth” have been grown in mini pigs. (MIT Technology Review) 9 AI slop on birdwatching forums is putting research at riskIt could contaminate records of species. (Guardian) 10 Heart experts have good news for your coffee habitRoughly five cups per day is fine—and may even be beneficial. (Gizmodo) Quote of the day “The most authoritarian government is producing the most egalitarian models, and what should be the most democratic government is breeding companies that are the most authoritarian.”  —Rayan Krishnan, CEO of Vals AI, a company that evaluates AI performance, gives the New York Times his take on the competition between Chinese and American models. One More Thing RICHARD CHANCE The curious case of the disappearing Lamborghinis A new wave of theft is rocking the luxury car industry—mixing high tech with old-school chop-shop techniques to snag vehicles while they’re in transport.  It’s remained under the radar, even as it’s rocked the industry over the past two years. MIT Technology Review identified more than a dozen cases involving high-end vehicles, obtained court records, and spoke to law enforcement, brokers, drivers, and victims in multiple states to reveal how transport fraud is wreaking havoc across the country. Find out how a new wave of transport fraud is wreaking havoc across the country.  —Craig Silverman We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Here’s the perfect outfit for a heat wave: the world’s first self-cooling clothes.+ The “unhinged” cake decorators at a Missoula Walmart have become local legends.+ This visual guide to chili peppers around the world is a lavishly illustrated ode to the world’s hottest fruit.+ Take a quirky tour of mid-20th-century cinema in this thread of film posters inadvertently photographed by postwar town planners.

The Download: AI hiring biases, and weather data sabotage Read Post »

AI, Committee, News, Uncategorized

China’s AI models have Trump’s AI world at war with itself

This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. Over the weekend, several current and former advisors to President Donald Trump on AI publicly lobbed insults at the country’s leading AI companies. David Sacks, the president’s AI and crypto “czar” until March, branded Anthropic’s models as “lobotomized” and “woke.” Emil Michael, a top Pentagon official, called OpenAI’s new head of strategic futures a “supreme village idiot.” It began because no one can agree on what to do about Kimi, a free, open source model that Chinese AI company Moonshot launched last week. It appears to rival the intelligence of models from OpenAI and Anthropic, which are very much not free.  Kimi and other Chinese models like it pose a real problem for Trump. And they’re dividing the top AI strategists in his orbit into factions. Every time a new smart, free model from China like Kimi gets released, US companies see less reason to fork out money to access models from Anthropic or OpenAI. Given that enthusiasm for these and other AI companies is driving an outsized share of economic growth, China’s AI models create both economic and political problems for the president. They are “a threat for an administration that really doesn’t want more economic bad news,” Anton Leicht, a fellow at the Carnegie Endowment, wrote on X. They’ve already rattled US stocks.  What is Trump to do? First, consider that this is all happening just a week after New York imposed the country’s first state ban on new data centers. There is growing distrust of AI companies, and I imagine a not-insignificant share of Americans would have little sympathy for OpenAI or Anthropic as they fend off cheaper competitors, and would say it’s not the government’s job to protect their interests. On this point, they’d see a sliver of agreement (and really just a sliver) with David Sacks, who on July 19 criticized top AI companies that “want the government to eliminate their open source competition.” He has also argued that Chinese AI models have become popular because they come with fewer restrictions on how people can use them (putting aside the built-in state censorship).  Sacks, however, is out of a job. He no longer has a formal role advising Trump, and his position that more open AI is better has been largely replaced in the administration by one that sees a larger role for government intervention. The thinking behind this view is that because AI models have gotten strong enough to pose threats to national security, the government must control how they’re used.  This position has fueled the new White House review process that aims to vet AI models’ security before they’re released. Dean Ball, a former Trump AI advisor who now works for OpenAI, criticized it over the weekend as a “de facto licensing regime for frontier AI.” Ball predicted Trump may solve his Chinese open source problem with a bit of soft power, perhaps by making US companies afraid to use models like Kimi. That drew a response from Michael, who, with Secretary of Defense Pete Hegseth, has been the agency’s main liaison with AI companies. Michael called Ball the AI industry’s “supreme village idiot,” bristling at the suggestion that the government would quietly strong-arm companies rather than, as Michael put it, go through “the democratic process not some Deep State scheme.” Left out of the conversation has been how a model like Kimi got so good in the first place. For much of the Biden administration and even the beginning of Trump’s second administration, keeping China from getting top chips was a priority. Those export controls have loosened—Trump made the controversial decision to allow Nvidia to sell more chips to China, in exchange for the US government taking a cut—and the government has alleged that some chip smuggling has taken place. But China nonetheless has limited computing power, and it’s not clear what chips the company behind Kimi used to train the model.  It’s possible that the process involved some distillation, a practice in which AI models are trained on the outputs of existing AI models. OpenAI and Anthropic have long complained that Chinese AI companies do this, and they have requested government help to put a stop to it. In April, they got it, when the Trump administration announced a series of efforts to curb the practice.   But Kimi is out there and free, and it is nearly as good as the Anthropic model the US government deemed so powerful that it was briefly shut down because it threatened national security. The weekend’s sparring suggests many in Trump’s orbit see that as a wake-up call. But nobody can agree on what for.

China’s AI models have Trump’s AI world at war with itself Read Post »

AI, Committee, News, Uncategorized

Fine-Tuning Qwen3 with LoRA Using NVIDIA NeMo AutoModel: A Complete Single-GPU Google Colab Workflow Tutorial

In this tutorial, we build an end-to-end NVIDIA NeMo AutoModel workflow in Google Colab and use a single GPU to explore the same configuration-driven training architecture that scales to distributed multi-GPU environments. We verify the available CUDA hardware and precision support, install NeMo AutoModel directly from its source repository, load an official Qwen3-0.6B LoRA fine-tuning recipe, and programmatically adapt its precision, batch-size, checkpointing, and scheduler settings for a constrained Colab runtime. We then launch parameter-efficient fine-tuning through the automodel command-line interface, locate and reload the generated LoRA checkpoint, and compare outputs from the original and fine-tuned models. Finally, we use NeMoAutoModelForCausalLM through the Python API to demonstrate how NeMo AutoModel integrates NVIDIA-optimized execution paths while preserving the familiar Hugging Face model interface. Setting Up the Colab Workspace and Shell Helper Copy CodeCopiedUse a different Browser import os, sys, glob, json, subprocess, shutil, textwrap REPO_DIR = “/content/Automodel” WORK_DIR = “/content/automodel_demo” CKPT_DIR = os.path.join(WORK_DIR, “checkpoints”) os.makedirs(WORK_DIR, exist_ok=True) def sh(cmd, check=True): print(f”n$ {cmd}n” + “-” * 78) p = subprocess.Popen(cmd, shell=True, stdout=subprocess.PIPE, stderr=subprocess.STDOUT, text=True, bufsize=1) for line in p.stdout: print(line, end=””) p.wait() if check and p.returncode != 0: raise RuntimeError(f”Command failed ({p.returncode}): {cmd}”) return p.returncode We import the core Python libraries required for file handling, process execution, path management, and formatted output. We define the repository, working, and checkpoint directories used throughout the workflow. We also create a reusable shell-command function that streams command output and raises errors when execution fails. Verifying the GPU and Installing NeMo AutoModel Copy CodeCopiedUse a different Browser print(“=” * 78) print(“STEP 0 — Checking GPU runtime”) print(“=” * 78) import torch assert torch.cuda.is_available(), ( “No GPU found! In Colab: Runtime -> Change runtime type -> select a GPU.” ) GPU_NAME = torch.cuda.get_device_name(0) BF16_OK = torch.cuda.is_bf16_supported() VRAM_GB = torch.cuda.get_device_properties(0).total_memory / 1e9 print(f”GPU: {GPU_NAME} | VRAM: {VRAM_GB:.1f} GB | bf16 supported: {BF16_OK}”) print(“n” + “=” * 78) print(“STEP 1 — Installing NeMo AutoModel (takes a few minutes)”) print(“=” * 78) if not os.path.isdir(REPO_DIR): sh(f”git clone –depth 1 https://github.com/NVIDIA-NeMo/Automodel.git {REPO_DIR}”) sh(f”pip -q install -e {REPO_DIR}”) sh(“pip -q install pyyaml peft”) sh(‘python -c “import nemo_automodel; print(‘NeMo AutoModel version:’, ‘ ‘getattr(nemo_automodel, ‘__version__’, ‘source’))”‘) We verify that the Colab runtime provides a CUDA-enabled GPU and inspect its name, memory capacity, and bfloat16 support. We clone the NVIDIA NeMo AutoModel repository when it is not already available and install the package directly from source. We then install the supporting YAML and PEFT libraries and confirm that the NeMo AutoModel package imports correctly. Loading and Patching the Qwen3 LoRA Recipe Copy CodeCopiedUse a different Browser print(“n” + “=” * 78) print(“STEP 2 — Preparing the recipe”) print(“=” * 78) import yaml candidates = sorted(glob.glob( os.path.join(REPO_DIR, “examples”, “llm_finetune”, “qwen”, “*0p6b*peft*.yaml”) )) or sorted(glob.glob( os.path.join(REPO_DIR, “examples”, “llm_finetune”, “**”, “*peft*.yaml”), recursive=True, )) assert candidates, “Could not find a PEFT recipe in the cloned repo.” BASE_RECIPE = candidates[0] print(f”Base recipe: {os.path.relpath(BASE_RECIPE, REPO_DIR)}”) with open(BASE_RECIPE) as f: cfg = yaml.safe_load(f) print(“n— Original recipe (as shipped) —“) print(yaml.dump(cfg, sort_keys=False)[:2500]) def patch(node): if isinstance(node, dict): for k, v in list(node.items()): if isinstance(v, str) and not BF16_OK and v.lower() in ( “bf16”, “bfloat16”, “torch.bfloat16”): node[k] = “float32” elif k in (“batch_size”, “local_batch_size”) and isinstance(v, int): node[k] = min(v, 4) elif k == “global_batch_size” and isinstance(v, int): node[k] = min(v, 8) else: patch(v) elif isinstance(node, list): for item in node: patch(item) patch(cfg) cfg.setdefault(“step_scheduler”, {}) cfg[“step_scheduler”][“max_steps”] = 40 cfg[“step_scheduler”][“ckpt_every_steps”] = 40 cfg[“step_scheduler”][“num_epochs”] = 1 if isinstance(cfg.get(“checkpoint”), dict): cfg[“checkpoint”][“enabled”] = True cfg[“checkpoint”][“checkpoint_dir”] = CKPT_DIR DEMO_RECIPE = os.path.join(WORK_DIR, “qwen3_0p6b_colab_lora.yaml”) with open(DEMO_RECIPE, “w”) as f: yaml.dump(cfg, f, sort_keys=False) print(“n— Patched recipe (what we will actually run) —“) print(yaml.dump(cfg, sort_keys=False)[:2500]) MODEL_ID = “Qwen/Qwen3-0.6B” try: MODEL_ID = cfg[“model”][“pretrained_model_name_or_path”] except Exception: pass print(f”nBase model: {MODEL_ID}”) We locate an official PEFT recipe, load its YAML configuration, and inspect the original training settings. We recursively adapt the precision and batch size parameters to fit the recipe on a single Colab GPU while preserving its original structure. We also limit the training duration, configure checkpoint output, save the patched recipe, and extract the Hugging Face model identifier. Running LoRA Fine-Tuning on HellaSwag Copy CodeCopiedUse a different Browser print(“n” + “=” * 78) print(“STEP 3 — Training (LoRA fine-tune of Qwen3-0.6B on HellaSwag)”) print(“=” * 78) env_prefix = “HF_HUB_ENABLE_HF_TRANSFER=0 TOKENIZERS_PARALLELISM=false” rc = sh(f”cd {WORK_DIR} && {env_prefix} automodel {DEMO_RECIPE}”, check=False) if rc != 0: print(“nRetrying with legacy CLI syntax…”) sh(f”cd {WORK_DIR} && {env_prefix} automodel finetune llm -c {DEMO_RECIPE}”) We launch Qwen3-0.6B LoRA fine-tuning on the HellaSwag dataset through the NeMo AutoModel command-line interface. We turn off unnecessary Hugging Face transfer and tokenizer parallelism features to keep the Colab run more predictable. We also include a fallback command that supports older NeMo AutoModel CLI syntax when the primary invocation fails. Comparing Base and Fine-Tuned Model Outputs Copy CodeCopiedUse a different Browser print(“n” + “=” * 78) print(“STEP 4 — Evaluating: base model vs LoRA fine-tuned model”) print(“=” * 78) from transformers import AutoModelForCausalLM, AutoTokenizer DTYPE = torch.bfloat16 if BF16_OK else torch.float32 PROMPT = (“A man is sitting on a roof. He starts pulling up roofing shingles. ” “What happens next?”) def generate(model, tok, prompt, max_new_tokens=60): inputs = tok(prompt, return_tensors=”pt”).to(model.device) with torch.no_grad(): out = model.generate(**inputs, max_new_tokens=max_new_tokens, do_sample=False, temperature=None, top_p=None, pad_token_id=tok.eos_token_id) return tok.decode(out[0][inputs[“input_ids”].shape[1]:], skip_special_tokens=True) tok = AutoTokenizer.from_pretrained(MODEL_ID) base = AutoModelForCausalLM.from_pretrained( MODEL_ID, torch_dtype=DTYPE, device_map=”cuda”) print(“n[BASE MODEL]”) print(textwrap.fill(generate(base, tok, PROMPT), 90)) ckpt_glob = sorted(glob.glob(os.path.join(CKPT_DIR, “**”, “model”), recursive=True)) if not ckpt_glob: ckpt_glob = sorted(glob.glob(os.path.join(WORK_DIR, “**”, “adapter_model.safetensors”), recursive=True)) ckpt_glob = [os.path.dirname(p) for p in ckpt_glob] if ckpt_glob: ADAPTER_DIR = ckpt_glob[-1] print(f”nFound checkpoint: {ADAPTER_DIR}”) try: from peft import PeftModel tuned = PeftModel.from_pretrained(base, ADAPTER_DIR) print(“n[FINE-TUNED MODEL (base + LoRA adapter)]”) print(textwrap.fill(generate(tuned, tok, PROMPT), 90)) except Exception as e: print(f”nCould not auto-load the adapter with peft ({e}).”) print(“Inspect the checkpoint contents manually:”) for p in glob.glob(os.path.join(ADAPTER_DIR, “*”))[:20]: print(” “, p) else: print(“nNo checkpoint found — check the training logs above.”) del base torch.cuda.empty_cache() We load the tokenizer and base causal language model, generate a deterministic response, and establish a baseline for comparison. We search the training output directories for the latest LoRA checkpoint or adapter files created during fine-tuning. We then attach the adapter with

Fine-Tuning Qwen3 with LoRA Using NVIDIA NeMo AutoModel: A Complete Single-GPU Google Colab Workflow Tutorial Read Post »

We use cookies to improve your experience and performance on our website. You can learn more at Privacy Policy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
en_US