YouZum

ニュース

AI, Committee, ニュース, Uncategorized

promptolution: A Unified, Modular Framework for Prompt Optimization

arXiv:2512.02840v2 Announce Type: replace Abstract: Prompt optimization has become crucial for enhancing the performance of large language models (LLMs) across a broad range of tasks. Although many research papers demonstrate its effectiveness, practical adoption is hindered because existing implementations are often tied to unmaintained, isolated research codebases or require invasive integration into application frameworks. To address this, we introduce promptolution, a unified, modular open-source framework that provides all components required for prompt optimization within a single extensible system for both practitioners and researchers. It integrates multiple contemporary discrete prompt optimizers, supports systematic and reproducible benchmarking, and returns framework-agnostic prompt strings, enabling seamless integration into existing LLM pipelines while remaining agnostic to the underlying model implementation.

promptolution: A Unified, Modular Framework for Prompt Optimization 投稿を読む »

AI, Committee, ニュース, Uncategorized

BEAT: Visual Backdoor Attacks on VLM-based Embodied Agents via Contrastive Trigger Learning

arXiv:2510.27623v3 Announce Type: replace-cross Abstract: Recent advances in Vision-Language Models (VLMs) have propelled embodied agents by enabling direct perception, reasoning, and planning task-oriented actions from visual inputs. However, such vision-driven embodied agents open a new attack surface: visual backdoor attacks, where the agent behaves normally until a visual trigger appears in the scene, then persistently executes an attacker-specified multi-step policy. We introduce BEAT, the first framework to inject such visual backdoors into VLM-based embodied agents using objects in the environments as triggers. Unlike textual triggers, object triggers exhibit wide variation across viewpoints and lighting, making them difficult to implant reliably. BEAT addresses this challenge by (1) constructing a training set that spans diverse scenes, tasks, and trigger placements to expose agents to trigger variability, and (2) introducing a two-stage training scheme that first applies supervised fine-tuning (SFT) and then our novel Contrastive Trigger Learning (CTL). CTL formulates trigger discrimination as preference learning between trigger-present and trigger-free inputs, explicitly sharpening the decision boundaries to ensure precise backdoor activation. Across various embodied agent benchmarks and VLMs, BEAT achieves attack success rates up to 80%, while maintaining strong benign task performance, and generalizes reliably to out-of-distribution trigger placements. Notably, compared to naive SFT, CTL boosts backdoor activation accuracy up to 39% under limited backdoor data. These findings expose a critical yet unexplored security risk in VLM-based embodied agents, underscoring the need for robust defenses before real-world deployment.

BEAT: Visual Backdoor Attacks on VLM-based Embodied Agents via Contrastive Trigger Learning 投稿を読む »

AI, Committee, ニュース, Uncategorized

Why conservationists are making rhinos radioactive

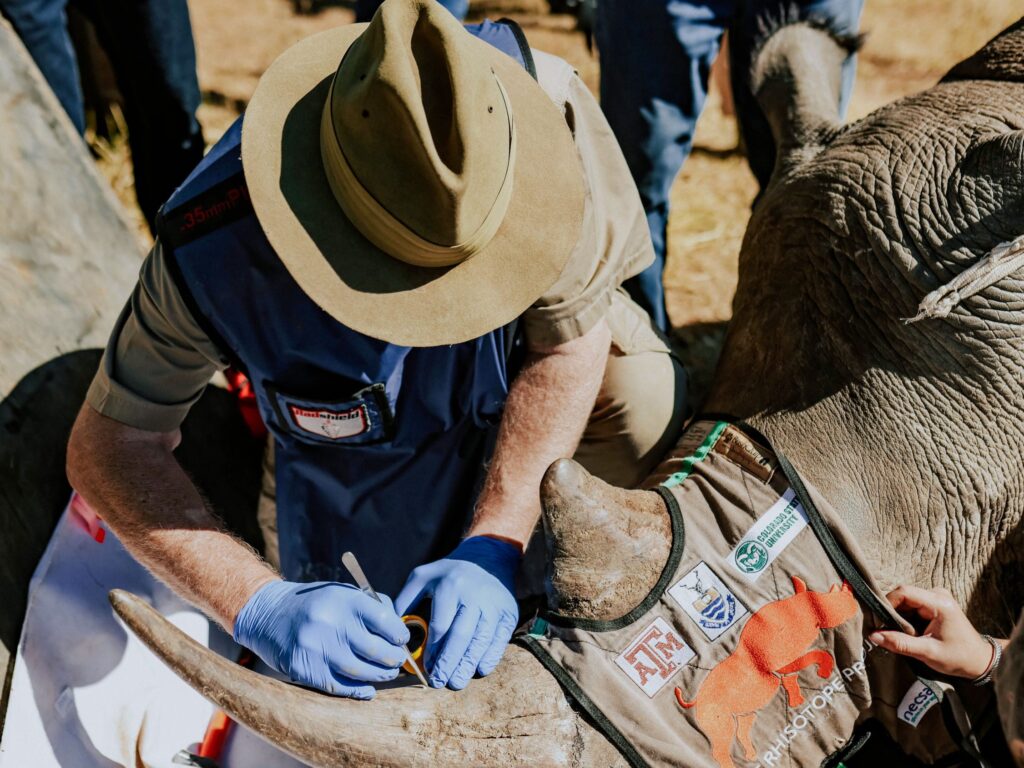
Every year, poachers shoot hundreds of rhinos, fishing crews haul millions of sharks out of protected seas, and smugglers carry countless animals and plants across borders. This illegal activity is incredibly hard to disrupt, since it’s backed by sophisticated criminal networks and the perpetrators know that their chances of being caught are slim. With an annual value of $20 billion, according to Interpol, it’s the world’s fourth-most-lucrative criminal enterprise after trafficking in drugs, weapons, and people. The United Nations seeks to end trafficking in protected species by 2030. But the environmental guardians facing up to these nefarious networks—dispersed alliances of rangers, community groups, and law enforcement officers—have long been ill equipped and underfunded. A recent report by the UN Office on Drugs and Crime found “no reason for confidence” that the 2030 target would be reached.  Still, there is genuine hope that tech could help turn the tide. Tools initially developed for cities and research facilities are increasingly moving into the planet’s wild places, allowing environmental agencies and self-motivated communities in both richer and poorer countries to step up their efforts to detect illegal goods, trace smuggling networks, and prevent poaching at the source.  In December, Interpol announced it had seized record numbers of live animals, thanks in part to a set of sophisticated tools that had helped to expose hidden networks behind trafficking. Its Operation Thunder 2025 coordinated law enforcement agencies from 134 countries and seized 30,000 live animals, from apes to butterflies, using a suite of technologies including digital forensics and AI-driven detection. “The success of Thunder 2025 shows that modern threats demand modern tools,” says José Adrián Sanchez Romero, an operations coordinator at Interpol’s environmental security subdirectorate. Here are five examples of technologies that are arming conservationists and others in the battle to end wildlife crime.  COURTESY OF THE RHISOTOPE PROJECT Tagging rhinos In July, a group of South African researchers announced they had won government approval for one of the most eyebrow-raising attempts to prevent wildlife crime: drilling radioactive substances into the horns of rhinoceroses.  In an effort dubbed the Rhisotope Project, the group worked in 2024 and 2025 to fit 33 rhinos from Limpopo Rhino Orphanage in South Africa with pellets containing low-level radioactive isotopes. The project is supported by the International Atomic Energy Agency.  Blood samples and veterinary exams have shown that the pellets don’t affect the health of the rhinos, the rangers, or the surrounding environment. But the isotope emits enough radiation for the horns to be detected by radiation portal monitors, devices that can scan cargo containers and vehicles to detect illicit sources of radiation. Eleven thousand such monitors are already in operation at airports and shipping terminals worldwide, in addition to thousands of personal monitors worn by border security. In November 2024, Rhisotope tested the system at New York airports and harbors in collaboration with the US Customs and Border Patrol. The group found that border guards could detect an individual horn the team had planted inside a full 40-foot shipping container. The project was pioneered by James Larkin, director of the radiation and health physics unit at the University of the Witwatersrand in South Africa. Though the country is currently home to 15,000 rhinos, the majority of Africa’s total population, poachers have killed 10,000 rhinos there since 2007. In the past, the common approach to deterring poachers was to eliminate the part they’re seeking, preemptively cutting off the animal’s entire horn. But dehorning requires rhinos to be sedated for long periods, and it’s a stressful and costly process that must be repeated every 18 to 24 months, as rhino horns grow back. The act also renders rhinos less able to protect themselves, and they tend to withdraw from social interactions and competition for mates. The new approach is far less painful and time-consuming. Each dose costs 21,500 South African rand (about $1,300) per animal and remains active for five years. Warning signs along perimeter fences make it clear the animals have been tagged, helping to deter poachers.  Larkin, who spent his career as a nuclear safety expert, says he was initially wary when conservationists suggested to him that radioactive substances could help prevent rhino poaching, joking that he didn’t want to end up in jail if anyone got hurt. But he changed his mind when he realized there was a dose that would be harmless to bystanders while making the horns both worthless to smugglers and readily detectable. Poachers will kill a rhino for even a small amount of horn, which can fetch $60,000 per kilogram as an ingredient for traditional medicines. Adding isotopes, though, renders the horns potentially unsafe to consume, and it’s hard for smugglers to reverse: “It’s almost impossible to remove isotopes unless you are a skilled radiation protection officer who knows what they are looking for,” Larkin says. Even so, he’s tight-lipped about the compound the pellets are made from and what they look like: “I don’t want to help criminals,” he explains. The South African health agency has now approved Rhisotope to roll out the program across the country. “We have a goal ultimately to treat up to 500 rhinos a year,” says Jessica Babich, chief executive of the project. At the same time, the group is working to adapt its approach to other popular poaching targets—elephant tusks and pangolin scales—as well as trafficked plants like cycads.  COURTESY OF TARONGA CONSERVATION SOCIETY COURTESY OF TARONGA CONSERVATION SOCIETY Scanning signatures For many exotic pets, from birds to pythons, there are two parallel trades: a legal one in farmed or captive-bred animals and an illicit one in creatures taken from the wild. But faced with a lizard or a parrot, how can law enforcement know its origin story? In Australia, some conservationists have been trying to follow the numbers. It’s very hard to breed the egg-­laying mammals known as short-beaked echidnas. US zoos have yielded only 19 echidna babies, or “puggles,” in a century of efforts. So Indonesia’s yearly export of dozens of “captive-bred” echidnas has

Why conservationists are making rhinos radioactive 投稿を読む »

AI, Committee, ニュース, Uncategorized

AWED-FiNER: Agents, Web applications, and Expert Detectors for Fine-grained Named Entity Recognition across 36 Languages for 6.6 Billion Speakers

arXiv:2601.10161v2 Announce Type: replace Abstract: Named Entity Recognition (NER) is a foundational task in Natural Language Processing (NLP) and Information Retrieval (IR), which facilitates semantic search and structured data extraction. We introduce textbf{AWED-FiNER}, an open-source collection of agentic tool, web application, and 53 state-of-the-art expert models that provide Fine-grained Named Entity Recognition (FgNER) solutions across 36 languages spoken by more than 6.6 billion people. The agentic tool enables routing multilingual text to specialized expert models to fetch FgNER annotations within seconds. The web-based platform provides a ready-to-use FgNER annotation service for non-technical users. Moreover, the collection of language-specific extremely small open-source state-of-the-art expert models facilitates offline deployment in resource-constrained scenarios, including edge devices. AWED-FiNER covers languages spoken by over 6.6 billion people, ranging from global languages like English, Chinese, Spanish, and Hindi, to low-resource languages like Assamese, Santali, and Odia, along with a specific focus on extremely low-resource vulnerable languages such as Bodo, Manipuri, Bishnupriya, and Mizo. The resources can be accessed here: Agentic Tool (https://github.com/PrachuryyaKaushik/AWED-FiNER), Web Application (https://hf.co/spaces/prachuryyaIITG/AWED-FiNER), and 53 Expert Detector Models (https://hf.co/collections/prachuryyaIITG/awed-finer).

AWED-FiNER: Agents, Web applications, and Expert Detectors for Fine-grained Named Entity Recognition across 36 Languages for 6.6 Billion Speakers 投稿を読む »

AI, Committee, ニュース, Uncategorized

One Token Is Enough: Improving Diffusion Language Models with a Sink Token

arXiv:2601.19657v3 Announce Type: replace Abstract: Diffusion Language Models (DLMs) have emerged as a compelling alternative to autoregressive approaches, enabling parallel text generation with competitive performance. Despite these advantages, there is a critical instability in DLMs: the moving sink phenomenon. Our analysis indicates that sink tokens exhibit low-norm representations in the Transformer’s value space, and that the moving sink phenomenon serves as a protective mechanism in DLMs to prevent excessive information mixing. However, their unpredictable positions across diffusion steps undermine inference robustness. To resolve this, we propose a simple but effective extra sink token implemented via a modified attention mask. Specifically, we introduce a special token constrained to attend solely to itself, while remaining globally visible to all other tokens. Experimental results demonstrate that introducing a single extra token stabilizes attention sinks, substantially improving model performance. Crucially, further analysis confirms that the effectiveness of this token is independent of its position and characterized by negligible semantic content, validating its role as a robust and dedicated structural sink.

One Token Is Enough: Improving Diffusion Language Models with a Sink Token 投稿を読む »

AI, Committee, ニュース, Uncategorized

Taalas is replacing programmable GPUs with hardwired AI chips to achieve 17,000 tokens per second for ubiquitous inference

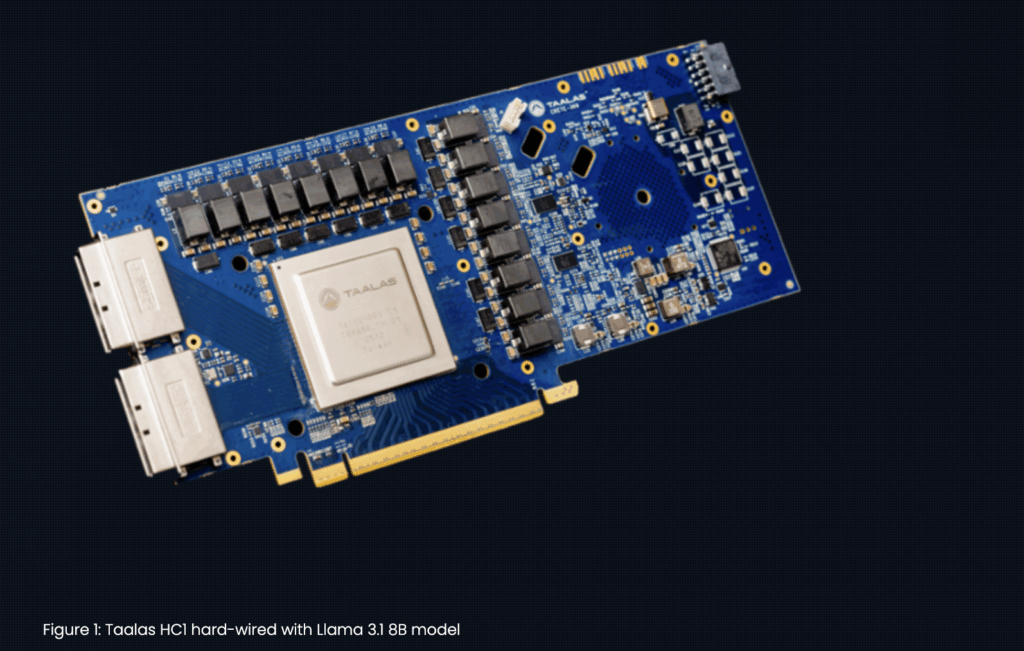
In the high-stakes world of AI infrastructure, the industry has operated under a singular assumption: flexibility is king. We build general-purpose GPUs because AI models change every week, and we need programmable silicon that can adapt to the next research breakthrough. But Taalas, the Toronto-based startup thinks that flexibility is exactly what’s holding AI back. According to Taalas team, if we want AI to be as common and cheap as plastic, we have to stop ‘simulating’ intelligence on general-purpose computers and start ‘casting’ it directly into silicon. The Problem: The ‘Memory Wall’ and the GPU Tax The current cost of running a Large Language Model (LLM) is driven by a physical bottleneck: the Memory Wall. Traditional processors (GPUs) are ‘Instruction Set Architecture’ (ISA) based. They separate compute and memory. When you run an inference pass on a model like Llama-3, the chip spends the vast majority of its time and energy shuttling weights from High Bandwidth Memory (HBM) to the processing cores. This ‘data movement tax’ accounts for nearly 90% of the power consumption in modern AI data centers. Taalas’s solution is radical: eliminate the memory-fetch cycle. By using a proprietary automated design flow, Taalas translates the computational graph of a specific model directly into the physical layout of a chip. In their HC1 (Hardcore 1) chip, the model’s weights and architecture are literally etched into the wiring of the silicon. https://taalas.com/the-path-to-ubiquitous-ai/ Hardcore Models: 17,000 Tokens Per Second The results of this ‘direct-to-silicon’ approach redefine the performance ceiling for inference. At their latest unveiling, Taalas demonstrated the HC1 running a Llama 3.1 8B model. While a top-tier NVIDIA H100 might serve a single user at ~150 tokens per second, the HC1 serves a staggering 16,000 to 17,000 tokens per second. This changes the ‘unit economics’ of AI: Performance: A single HC1 chip can outperform a small GPU data center in terms of raw throughput for a specific model. Efficiency: Taalas claims a 1000x improvement in efficiency (performance-per-watt and performance-per-dollar) compared to conventional chips. Infrastructure: Because the weights are hardwired, there is no need for external HBM or complex liquid cooling systems. A standard air-cooled rack can house ten of these 250W cards, delivering the power of an entire GPU cluster in a single server box. Breaking the 60-Day Barrier: The Automated Foundry The obvious ‘catch’ for an AI developer is flexibility. If you hardwire a model into a chip today, what happens when a better model comes out tomorrow? Historically, designing an ASIC (Application-Specific Integrated Circuit) took two years and tens of millions of dollars. Taalas has solved this through automation. They have built a compiler-like foundry system that takes model weights and generates a chip design in roughly a week. By focusing on a streamlined manufacturing workflow—where they only change the top metal masks of the silicon—they have collapsed the turnaround time from ‘weights-to-silicon’ to just two months. This allows for a ‘seasonal’ hardware cycle. A company could fine-tune a frontier model in the spring and have thousands of specialized, hyper-efficient inference chips deployed by summer. https://taalas.com/the-path-to-ubiquitous-ai/ The Market Shift: From Shovels to Stamps This transition marks a pivotal moment in the AI hype cycle. We are moving from the ‘Research & Training’ phase—where GPUs are essential for their flexibility—to the ‘Deployment & Inference’ phase, where cost-per-token is the only metric that matters. If Taalas succeeds, the AI market will split into two distinct tiers: General-Purpose Training: Led by NVIDIA and AMD, providing the massive, flexible clusters needed to discover and train new architectures. Specialized Inference: Led by ‘foundries’ like Taalas, which take those proven architectures and ‘print’ them into cheap, ubiquitous silicon for everything from smartphones to industrial sensors. Key Takeaways The ‘Hardwired’ Paradigm Shift: Taalas is moving from software-defined AI (running models on general-purpose GPUs) to hardware-defined AI. By ‘baking’ a specific model’s weights and architecture directly into the silicon, they eliminate the need for traditional instruction-set overhead, effectively making the model the processor itself. Death of the Memory Wall: Traditional AI hardware wastes ~90% of its energy moving data between memory and compute. Taalas’s HC1 (Hardcore 1) chip eliminates the “Memory Wall” by physically wiring the model parameters into the chip’s metal layers, removing the need for expensive High Bandwidth Memory (HBM). 1000x Efficiency Leap: By stripping away the ‘programmability tax’, Taalas claims a 1,000x improvement in performance-per-watt and performance-per-dollar. In practice, this means an HC1 can hit 17,000 tokens per second on a Llama 3.1 8B model—massively outperforming a standard GPU rack while using far less power. Automated ‘Direct-to-Silicon’ Foundry: To solve the problem of model obsolescence, Taalas uses a proprietary automated design flow. This reduces the time to create a custom AI chip from years to just weeks, allowing companies to ‘print’ their fine-tuned models into silicon on a seasonal basis. The Commodity AI Future: This technology signals a shift from ‘Cloud-First’ to ‘Device-Native’ AI. As inference becomes a cheap, hardwired commodity, AI will move off centralized servers and into local, low-power hardware—ranging from smartphones to industrial sensors—with zero latency and no subscription costs. Check out the Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Taalas is replacing programmable GPUs with hardwired AI chips to achieve 17,000 tokens per second for ubiquitous inference appeared first on MarkTechPost.

Taalas is replacing programmable GPUs with hardwired AI chips to achieve 17,000 tokens per second for ubiquitous inference 投稿を読む »

AI, Committee, ニュース, Uncategorized

Inside Chicago’s surveillance panopticon

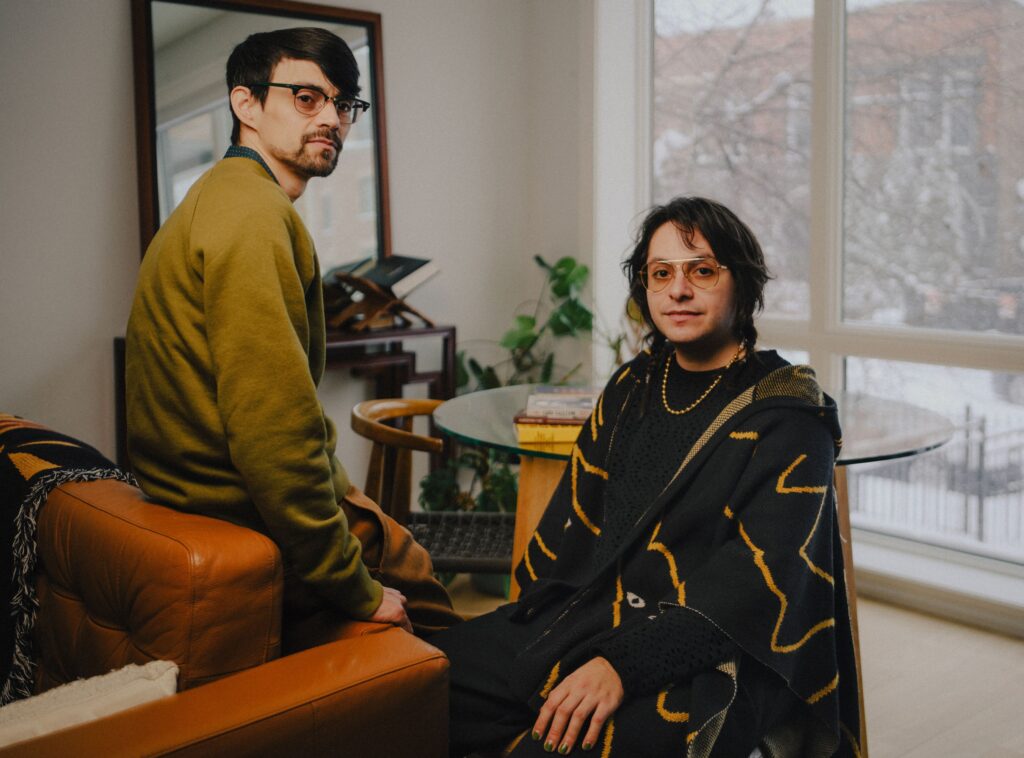
Early on the morning of September 2, 2024, a Chicago Transit Authority Blue Line train was the scene of a random and horrific mass shooting. Four people were shot and killed on a westbound train as it approached the suburb of Forest Park.  The police swiftly activated a digital dragnet—a surveillance network that connects thousands of cameras in the city.  The process began with a quick review of the transit agency’s surveillance cameras, which captured the alleged gunman shooting the victims execution style. Law enforcement followed the suspect, through real-time footage, across the rapid-­transit system. Police officials circulated the images to transit staff and to thousands of officers. An officer in the adjacent suburb of Riverdale recognized the suspect from a previous arrest. By the time he was captured at another train station, just 90 minutes after the shooting, authorities already had his name, address, and previous arrest history. Little of this process would come as much surprise to Chicagoans. The city has tens of thousands of surveillance cameras—up to 45,000, by some estimates. That’s among the highest numbers per capita in the US. Chicago boasts one of the largest license plate reader systems in the country, and the ability to access audio and video surveillance from independent agencies such as the Chicago Public Schools, the Chicago Park District, and the public transportation system as well as many residential and commercial security systems such as Ring doorbell cameras.  Law enforcement and security advocates say this vast monitoring system protects public safety and works well. But activists and many residents say it’s a surveillance panopticon that creates a chilling effect on behavior and violates guarantees of privacy and free speech.  Black and Latino communities in Chicago have historically been targeted by excessive policing and surveillance, says Lance Williams, a scholar of urban violence at Northeastern Illinois University. That scrutiny has created new problems without delivering the promised safety, he suggests. In order to “solve the problem of crime or violence and make these communities safer,” he says, “you have to deal with structural problems,” such as the shortage of livable-wage jobs, affordable housing, and mental-health services across the city. Recent years have seen some effective pushback against the surveillance. Until recently, for example, the city was the largest customer of ShotSpotter acoustic sensors, which are designed to detect gunfire and alert police. The system was introduced in a small area on the South Side in 2012. By 2018, an area of about 136 square miles—some 60% of the city—was covered by the acoustic surveillance network. Critics questioned ShotSpotter’s effectiveness and objected that the sensors were installed largely in Black and Latino neighborhoods. Those critiques gained urgency with the fatal shooting in March 2021 of a 13-year-old, Adam Toledo, by police responding to a ShotSpotter alert. The tragedy became the touchstone of the #StopShotSpotter protest movement and one of the major issues in Brandon Johnson’s successful mayoral campaign in 2023. When he reached office, Johnson followed through, ending the city’s contract with SoundThinking, the San Francisco Bay Area company behind ShotSpotter. In total, it’s estimated the city paid more than $53 million for the system.  In response to a request for comment, SoundThinking said that ShotSpotter enables law enforcement “to reach the scene faster, render aid to victims, and locate evidence more effectively.” It stated the company “plays no part in the selection of deployment areas” but added: “We believe communities experiencing the highest levels of gun violence deserve the same rapid emergency response as any other neighborhood.”  While there has been successful resistance to police surveillance in the nation’s third-largest city, there are also countervailing forces: governments and officials in Chicago and the surrounding suburbs are moving to expand the use of surveillance, also in response to public pressure. Even the victory against acoustic surveillance might be short-lived. Early last year, the city issued a request for proposals for gun violence detection technology.  Many people in and around Chicago—digital privacy and surveillance activists, defense attorneys, law enforcement officials, and ordinary citizens—are part of this push and pull. Here are some of their stories.  Alejandro Ruizesparza and Freddy MartinezCofounders, Lucy Parsons Labs Oak Park, a quiet suburb at Chicago’s western border, is the birthplace of Ernest Hemingway. It includes the world’s largest collection of Frank Lloyd Wright–designed buildings and homes.  Until recently, the village of Oak Park was also the center of a three-year-long campaign against an unwelcome addition to its manicured lawns and Prairie-style architecture: automated license plate readers from a company called Flock Safety. These are high-speed cameras that automatically scan license plates to look for stolen or wanted vehicles, or for drivers with outstanding warrants.  Freddy Martinez (left) and Alejandro Ruizesparza (right) direct Lucy Parsons Labs, a charitable organization focused on digital rights.AKILAH TOWNSEND An Oak Park group called Freedom to Thrive—made up of parents, activists, lawyers, data scientists, and many others—suspected that this technology was not a good or equitable addition to their neighborhood. So the group engaged the Chicago-based nonprofit Lucy Parsons Labs to help navigate the often intimidating process of requesting license plate reader data under the Illinois Freedom of Information Act. Lucy Parsons Labs, which is named for a turn-of-the-century Chicago labor organizer, investigates technologies such as license plate readers, gunshot detection systems, and police bodycams.  LPL provides digital security and public records training to a variety of groups and is frequently called on to help community members audit and analyze surveillance systems that are targeting their neighborhoods. It’s led by two first-­generation Mexican-Americans from the city’s Southwest Side. Alejandro Ruizesparza has a background in community organizing and data science. Freddy Martinez was also a community organizer and has a background in physics.  The group is now approaching its 10th year, but it was an all-volunteer effort until 2022. That’s when LPL received its first unrestricted, multi-year operational grant from a large foundation: the Chicago-based John D. and Catherine T. MacArthur Foundation, known worldwide for its so-called “genius grants.” A grant from the Ford Foundation

Inside Chicago’s surveillance panopticon 投稿を読む »

AI, Committee, ニュース, Uncategorized

Is There a Community Edition of Palantir? Meet OpenPlanter: An Open Source Recursive AI Agent for Your Micro Surveillance Use Cases

The balance of power in the digital age is shifting. While governments and large corporations have long used data to track individuals, a new open-source project called OpenPlanter is giving that power back to the public. Created by a developer ‘Shin Megami Boson‘, OpenPlanter is a recursive-language-model investigation agent. Its goal is simple: help you keep tabs on your government, since they are almost certainly keeping tabs on you. Solving the ‘Heterogeneous Data’ Problem Investigative work is difficult because data is messy. Public records are often spread across 100 different formats. You might have a CSV of campaign finance records, a JSON file of government contracts, and a PDF of lobbying disclosures. OpenPlanter ingests these disparate structured and unstructured data sources effortlessly. It uses Large Language Models (LLMs) to perform entity resolution. This is the process of identifying when different records refer to the same person or company. Once it connects these dots, the agent probabilistically looks for anomalies. It searches for patterns that a human might miss, such as a sudden spike in contract wins following a specific lobbying event. The Architecture: Recursive Sub-Agent Delegation What makes OpenPlanter unique is its recursive engine. Most AI agents handle 1 request at a time. OpenPlanter, however, breaks large objectives into smaller pieces. If you give it a massive task, it uses a sub-agent delegation strategy. The agent has a default max-depth of 4. This means the main agent can spawn a sub-agent, which can spawn another, and so on. These agents work in parallel to: Resolve entities across massive datasets. Link datasets that have no common ID numbers. Construct evidence chains that back up every single finding. This recursive approach allows the system to handle investigations that are too large for a single ‘context window.’ The 2026 AI Stack OpenPlanter is built for the high-performance requirements of 2026. It is written in Python 3.10+ and integrates with the most advanced models available today. The technical documentation lists several supported providers: OpenAI: It uses gpt-5.2 as the default. Anthropic: It supports claude-opus-4-6. OpenRouter: It defaults to anthropic/claude-sonnet-4-5. Cerebras: It uses qwen-3-235b-a22b-instruct-2507 for high-speed tasks. The system also uses Exa for web searches and Voyage for high-accuracy embeddings. This multi-model strategy ensures that the agent uses the best ‘brain’ for each specific sub-task. 19 Tools for Digital Forensics The agent is equipped with 19 specialized tools. These tools allow it to interact with the real world rather than just ‘chatting.’ These are organized into 4 core areas: File I/O and Workspace: Tools like read_file, write_file, and hashline_edit allow the agent to manage its own database of findings. Shell Execution: The agent can use run_shell to execute actual code. It can write a Python script to analyze a dataset and then run that script to get results. Web Retrieval: With web_search and fetch_url, it can pull live data from government registries or news sites. Planning and Logic: The think tool lets the agent pause and strategize. It uses acceptance-criteria to verify that a sub-task was completed correctly before moving to the next step. Deployment and Interface OpenPlanter is designed to be accessible but powerful. It features a Terminal User Interface (TUI) built with rich and prompt_toolkit. The interface includes a splash art screen of ASCII potted plants, but the work it does is serious. You can get started quickly using Docker. By running docker compose up, the agent starts in a container. This is a critical security feature because it isolates the agent’s run_shell commands from the user’s host operating system. The command-line interface allows for ‘headless’ tasks. You can run a single command like: Copy CodeCopiedUse a different Browser openplanter-agent –task “Flag all vendor overlaps in lobbying data” –workspace ./data The agent will then work autonomously until it produces a final report. Key Takeaways Autonomous Recursive Logic: Unlike standard agents, OpenPlanter uses a recursive sub-agent delegation strategy (default max-depth of 4). It breaks complex investigative objectives into smaller sub-tasks, parallelizing work across multiple agents to build detailed evidence chains. Heterogeneous Data Correlation: The agent is built to ingest and resolve disparate structured and unstructured data. It can simultaneously process CSV files, JSON records, and unstructured text (like PDFs) to identify entities across fragmented datasets. Probabilistic Anomaly Detection: By performing entity resolution, OpenPlanter automatically connects records—such as matching a corporate alias to a lobbying disclosure—and looks for probabilistic anomalies to surface hidden connections between government spending and private interests. High-End 2026 Model Stack: The system is provider-agnostic and utilizes the latest frontier models, including OpenAI gpt-5.2, Anthropic claude-opus-4-6, and Cerebras qwen-3-235b-a22b-instruct-2507 for high-speed inference. Integrated Toolset for Forensics: OpenPlanter features 19 distinct tools, including shell execution (run_shell), web search (Exa), and file patching (hashline_edit). This allows it to write and run its own analysis scripts while verifying results against real-world acceptance criteria. Check out the Repo here. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Disclaimer: MarkTechPost does not endorse the OpenPlanter project and provides this technical report for informational purposes only. The post Is There a Community Edition of Palantir? Meet OpenPlanter: An Open Source Recursive AI Agent for Your Micro Surveillance Use Cases appeared first on MarkTechPost.

Is There a Community Edition of Palantir? Meet OpenPlanter: An Open Source Recursive AI Agent for Your Micro Surveillance Use Cases 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja