YouZum

Committee

AI, Committee, ニュース, Uncategorized

From Entity Mentions to Tone: An LLM-Based Pipeline for Media Bias Analysis

arXiv:2608.17454v1 Announce Type: new Abstract: This paper presents a pipeline for analyzing media bias and framing in online news. The pipeline groups articles into topics and events, adds named-entity and sentiment annotations, and compares news sources through people mentions, source-level tone, and event-level coverage patterns. We apply it to 8,358 Albanian news articles collected from GDELT and compare the resulting annotations with GDELT’s automated annotations. The results show moderate agreement for sentiment and entity extraction, as well as additional person-entity pairs that can potentially support the bias analysis. We compare two annotation prompts and find that stricter sentiment-validation rules remove label-score inconsistencies but increase execution time and reduce annotation coverage. Based on these results, the simpler prompt is used for the rest of the analysis. We have provided sample analysis on source-level framing pro les, person-level tone differences across sources, and event-level gatekeeping and coverage indicators. These outputs show how the same news collection can be used to examine what sources cover, how they describe public figures, and where coverage is concentrated. The approach is particularly useful in settings where manually verified datasets or specialized language tools are limited.

From Entity Mentions to Tone: An LLM-Based Pipeline for Media Bias Analysis 投稿を読む »

AI, Committee, ニュース, Uncategorized

Decomposition Attacks Across Unlinkable Identities: Limits of Stateful Defenses for LLM Services

arXiv:2608.17445v1 Announce Type: cross Abstract: Most large language model services use stateless defenses, which judge only the current request, to refuse harmful tasks. Decomposition attacks exploit this limitation by splitting a harmful task into individually permissible requests and combining their answers. Defending against them therefore requires a stateful monitor that considers requests together. If it can group all requests for one attacker task, it can stop the attack. However, attackers can use unlinkable identities and combine answers elsewhere, leaving no reliable grouping signal. We ask whether decomposition attacks can still be stopped under this setting. For a fixed attack strategy without retries, we prove that the achievable security and utility tradeoff depends entirely on how benign requests for the same capabilities are grouped. Persistent, recognizable groups permit a useful defense; fresh, indistinguishable groups do not. When attackers can retry and learn from Allow/Block decisions, this useful operating point disappears: the feedback reveals what passes but not whether a block was correct. Experiments on 91 executable tasks and 11,393 capability-matched benign requests support these results. Under a 1% denial cap for these requests and a 0.5% cap for unrelated background traffic, all ten tested policies, including one privileged policy with an exact request-to-operation map, either fail to stop attacks or exceed the budget. On defense-unseen task families, attack success is at least 99% after one attempt and 100% after two. Effective defenses therefore require additional evidence or mechanisms tied to grouping, such as reliable identity linkage, costs for fresh identities, or control over answer use.

Decomposition Attacks Across Unlinkable Identities: Limits of Stateful Defenses for LLM Services 投稿を読む »

AI, Committee, ニュース, Uncategorized

Child-monitoring apps might need a reboot

Pam Wisniewski’s digital adolescence showed her the best and the worst of the internet. At 14, she left an abusive home, where she’d been isolated in a fifth-wheel trailer at the end of a seven-­mile dirt road. She moved in with her older sister and taught herself to type on AOL Instant Messenger. Online, she sought out the support and the community she’d lacked at home. She also discovered how thin the ice can be. “I sent my address to some guy in New Mexico to send me a mug with my name on it,” she recalls. “And then I found a news story like five, 10 years later that he killed somebody.” Those experiences set the course of her career. Wisniewski—now a principal research scientist at the International Computer Science Institute, a nonprofit affiliated with the University of California, Berkeley—has spent well over a decade asking what safety should look like for families navigating an evolving tech landscape, and how to achieve it without sacrificing trust. “I really see the internet as this double-edged sword,” she says.  Digital harms have become the defining fear of American parenthood. In the University of Michigan’s 2025 National Poll on Children’s Health, parents’ top three worries had to do with social media, screen time, and internet safety. Nearly half of American teenagers say they have been bullied or harassed online, according to the Pew Research Center. From there, the dangers escalate. Online drug dealers sell counterfeit pills laced with fentanyl. In the first half of 2025, the National Center for Missing & Exploited Children fielded more than 23,000 reports of financial sextortion, in which a predator posing as a peer extracts a sexual image from a child and threatens to publish it unless paid. Chatbots are the newest danger, with companies like OpenAI facing lawsuits for allegedly coaching children toward suicide.  Most parents’ first defense is conversation. In Pew surveys, more than nine in 10 say they’ve talked with their teens about what’s appropriate to share online and how to treat peers. They get an assist in limiting exposure from tools that come preinstalled on phones: Apple’s Screen Time and Google’s Family Link let parents cap screen time, block or approve apps, filter web content, and track devices. There are also apps that let family members share locations; Life360, the largest, has nearly 98 million monthly users.  But a growing number of adults are opting for tools that go further. Rather than simply restrict or locate, content-monitoring apps scan a child’s texts, photos, emails, and chats and alert parents whenever an algorithm flags something it deems dangerous. Business is booming, and the next wave of growth is already being marketed around AI, with companies positioning themselves as foils to chatbot companions and other risks. The broader market for parental control software, encompassing dozens of apps, was worth an estimated $1.57 billion in 2025 and is expected to nearly triple in value by 2034. Bark Technologies, the current leader among content-monitoring apps, says it scanned 11 billion messages to or from 7.5 million children in the US in 2025. Its free school program is in more than 3,700 districts, covering about one in 10 kids in the US. While Bark aims to flag only content that trips its filters, some competitors, like FlashGet Kids, include features like screen mirroring and camera access.  These apps have had genuine successes: They’ve prevented suicide attempts, intercepted predators, averted school shootings. But they can also cause harm themselves. To get a read on how digital surveillance affects young people, I scraped more than 600,000 reviews of the leading apps and talked to kids, parents, and people who were monitored as children and are now grown. Some kids were grateful for their parents’ protection. Others described false alarms that got them punished, secrets revealed before they were ready, breakdowns of trust, and anxiety they carried into adulthood. (To protect their privacy, we’re not using their full names.) FRANZISKA BARCZYK None of this is easily fixed. But child-safety researchers and advocates say better approaches exist. One is to make the platforms themselves safer, forcing social media companies to build guardrails instead of leaving families to find their own. This “duty of care” approach is now advancing in the UK, Australia, and a number of US states. Another is to spend less effort watching kids and more effort helping them recognize risk, cope with it, and turn to a trusted adult when something goes wrong. This approach is called resilience. Wisniewski and others are developing tools that don’t aggressively monitor kids but train them in resilience and build trust with parents. “If we define safety as the absence of risk, the way you keep them safe is by keeping them off the platforms entirely,” she says. “But if we define safety as the ability to protect oneself and engage without engaging a risk, the solutions look very different.” It is the difference between abstinence lectures and sex ed. Content-monitoring apps typically involve two pieces of software—one on the child’s device, one on the parent’s. A parent installs the kid-side app, connects the kid’s accounts, and chooses what to surveil: messages, social apps, browsing, location, screen time. The kid-side software forwards activity to the company’s algorithmic classifiers, which scan for content related to sex, drugs, bullying, and self-harm, among other categories, and push alerts to a parent-facing dashboard. The same type of software can be loaded into school-issued accounts and devices.  Sometimes the safety net works. Titania Jordan, Bark’s chief marketing officer, told me the FBI has thanked the company on multiple occasions for bringing credible school-shooting threats to its attention. “I hate that we have to exist,” she says. “But I’m so thankful that we do.” According to Bark’s annual report, its classifiers alerted hundreds of thousands of families to severe self-harm risks in 2025. Gaggle, a school-monitoring competitor, makes a similar claim in its own annual report, crediting its software with saving over 1,000 lives in the 2024–’25 school

Child-monitoring apps might need a reboot 投稿を読む »

AI, Committee, ニュース, Uncategorized

The Download: AI’s self-improvement problem, and what’s driving the heat

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. AI’s recursive self-improvement might not come so quickly after all The AI industry’s boldest promise right now is that AI will soon improve itself, with almost no need for human oversight. But a new study suggests it might take a while to get there. Researchers found that AI agents still can’t conduct open-ended AI research—free-form investigations with no clear-cut answers that require the judgment and creativity needed to make genuine breakthroughs. The big question now is how crucial open-ended research is to recursive self-improvement—and whether AI systems can grind their way there without it, simply by improving on narrower tasks. Find out why the results may temper claims that recursive self-improvement is on the horizon. —Michelle Kim MIT Technology Review Narrated: what’s behind this summer’s heat, and why 2027 could be worse This summer has been a scorcher for much of the Northern Hemisphere. June and July marked the hottest two-month stretch in Europe since record-keeping began, the contiguous US endured its hottest month on record in July, and South Korea saw its highest-ever recorded temperature.   Climate change makes heat waves more likely and more intense. But there’s another factor at play: El Niño, which is already ramping up and is expected to have a bigger effect on global temperatures next year. Here’s what’s behind this summer’s extreme heat—and why 2027 could be even hotter. This is our latest story to be turned into an MIT Technology Review Narrated podcast, which we publish each week on Spotify and Apple Podcasts. Just navigate to MIT Technology Review Narrated on either platform, and follow us to get all our new content as it’s released. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 OpenAI has paused some model work over safety concernsIt says its Astra model reached a “critical” risk threshold. (Guardian)+ The slowdown sets it apart from Anthropic’s approach. (Axios)+ OpenAI has made security updates after the Hugging Face hack. (Verge)+ It’s also introduced a version of ChatGPT for teenagers. (AP News) 2 Chinese humanoid maker Unitree surged 629% in its stock market debutThe IPO has underscored China’s lead in humanoid robots. (Bloomberg $)+ Unitree has become a key player in the Sino-US tech war. (Reuters $)+ It’s the world’s biggest humanoid firm and is already profitable. (BBC)+ There’s hidden human labor behind humanoids. (MIT Technology Review)  3 China is allowing Nvidia’s H200 chips into the mainlandByteDance and Tencent each recently received about 10,000 processors. (FT $)+ A new Chinese AI model could help defenders and hackers alike. (Wired $) 4 5 Flock’s new AI tool lets police identify drivers by their movementsIt goes much further than tracking license plates. (Wired $)+ Here’s what Flock’s defenders are missing. (MIT Technology Review) 6 Prosecutors argue Meta deliberately hooked children on Facebook and InstagramThe claim was made on the first day of a landmark trial. (BBC)+ A scientist is building a missing map of childhood. (MIT Technology Review) 7 Even ICE has ethical issues with Meta’s smart glassesIt’s banned them from the workplace over privacy concerns. (NYT $)+ Anduril and Meta are building smart glasses for warfare. (MIT Technology Review) 8 X’s algorithm learns what you hate—and shows you more of itA study found the impact was even stronger among Democrats. (404 Media) 9 A physicist proposes that the universe may repeat itself foreverThe same galaxies, lives and events could recur endlessly. (New Scientist $) 10 A blind Egyptian developer has built an AI app that helps others “see”It uses cameras to answer questions about users’ surroundings. (Reuters $) Quote of the day “Arizona is Arizone. Illinois starts with a V. I mean, it’s crazy.” —Stacey Morris, a Kentucky mom whose son brought home a packet of AI-generated educational materials, tells local station WDRB about some of the errors. One More Thing The astonishing embryo models of Jacob Hanna When the Palestinian stem-cell scientist Jacob Hanna was stopped while entering the US last May, he knew the routine. Anything to declare? Any biological samples? But this time the agents’ questions touched on a specific new topic: embryos. Hanna didn’t have any specimens, but if he had, it would have been surprisingly hard to say what they were. That’s because he specializes in creating synthetic embryo models, structures that resemble real embryos but don’t involve sperm, eggs, or fertilization. They could provide unprecedented views of the earliest stages of human development, while also creating a new way to produce cells for transplant medicine. But as these models become more realistic, they are raising difficult questions about how far the science should go. Take a closer look at Hanna’s astounding embryo models—and where they could lead. — Antonio Regalado We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Take a guided virtual tour through Spain’s astonishing cave paintings.+ Explore almost 2,000 prehistoric giants with the internet’s largest dinosaur database.+ The humble convenience store has been lovingly reimagined as a floating public artwork.+ If you’re looking to reflect on life or create a personal time capsule, you can write an email to your future self at FutureMe.

The Download: AI’s self-improvement problem, and what’s driving the heat 投稿を読む »

AI, Committee, ニュース, Uncategorized

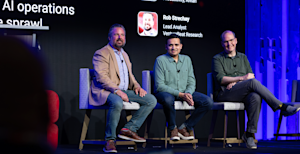
VentureBeat names Rob Strechay as its first Lead Analyst, expanding its enterprise AI research push

Rob Strechay, until recently managing director and principal analyst at theCUBE Research, has joined VentureBeat as our first Lead Analyst and a founding analyst of VentureBeat Research. His arrival is the next step in a deliberate move at VentureBeat toward deeper specialization: analysis built for the technical decision-makers — the directors, VPs, CIOs, and CTOs — who are evaluating, buying, and deploying enterprise AI. The enterprise AI stack is being rewritten in real time, and the decision-makers I talk with are starved for objective, defendable data. Rob Strechay has the mix of technical rigor and operating experience needed to dissect the architecture behind the next phase of enterprise AI deployment. The questions enterprise technology leaders are asking have changed. As organizations move past experimentation with generative AI toward production deployment, they want to know how to orchestrate multi-vendor environments, where the security gaps in their agentic pipelines sit, and how to fix the utilization problems draining their infrastructure budgets. Answering those questions requires more depth than news coverage alone provides, and that is the gap this research offering is built to fill. An analyst who has sat on every side of the table Strechay brings nearly three decades of experience as a practitioner, product executive, and industry analyst. Before becoming an analyst, he was an executive at numerous startups, including Zerto; he joined Amazon Web Services to help build a new analytics service; and he held executive roles across enterprise infrastructure. He later served as a senior analyst at Enterprise Strategy Group and most recently as managing director and principal analyst at theCUBE Research and SiliconANGLE, where he hosted executive interviews and analyzed the evolution of cloud, data, and AI infrastructure. Strechay will initially focus his coverage on cloud infrastructure, advanced data infrastructure, platform engineering and DevOps orchestration and observability, and the intersection points where AI and enterprise security collide. Already at work: GPU utilization and the VB Pulse surveys Strechay has already been contributing to VentureBeat’s research. In May he published an analysis of enterprise GPU utilization, examining the compute waste sitting inside enterprise AI infrastructure, and he provided a substantive review of our AI Infrastructure & Compute survey before it went into the field. His infrastructure-level focus complements the research engine VentureBeat has built around its monthly VB Pulse surveys, which track five areas of enterprise AI adoption: agentic orchestration, agent reliability and evals, agentic security and identity, AI infrastructure and compute, and context layers, including retrieval-augmented generation (RAG). Our June report on agentic orchestration, drawn from a survey of 145 enterprises, found that two-thirds of those enterprises had hedged their AI model strategy rather than committing to a single provider — a posture whose value the June outage of Anthropic’s Claude models made plain. VB In Conversation: The first vehicle A core vehicle for this expanded research footprint will be a deepening of VentureBeat’s existing VB In Conversation video interview series, which Strechay will host. Rather than high-level industry overviews, the series will bring architectural blueprints, actual deployment barriers, and back-end infrastructure realities to light through in-depth technical interviews with the architects and product leaders behind leading enterprise AI systems — an unvarnished look at which tools perform under production-grade pressure. “VentureBeat has built an audience of enterprise builders and technology buyers that any analyst would want to serve,” Strechay said. “My goal is to use deep empirical metrics and VentureBeat’s proprietary tracking data to help enterprise buyers and the people building for them make sound platform and infrastructure decisions during the most disruptive transition enterprise technology has seen.” The expanded VB In Conversation series will appear on VentureBeat and on VentureBeat’s YouTube channel, alongside Rob’s written analysis on the site. Enterprise practitioners who want to take part in our monthly VB Pulse surveys, or arrange an analyst briefing with Rob, can reach the research team here.

VentureBeat names Rob Strechay as its first Lead Analyst, expanding its enterprise AI research push 投稿を読む »

AI, Committee, ニュース, Uncategorized

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas

Cartesia has released Sonic-3.6, the newest version of its real-time text-to-speech model. It arrives roughly three months after Sonic-3.5. The new change is naturalness, and this one is independently checkable. Sonic 3.6 now holds #1 on both Artificial Analysis speech leaderboards — 1,283 Elo on the Provider Voice board and 1,123 on the Controlled Voice board. The second result matters more. That board clones every model onto the same eight reference voices, which isolates the synthesis engine from the voice catalog. Sonic-3.6 leads it, with Sonic-3.5 second and ElevenLabs Eleven v3 third. The model runs on state space models rather than transformers, and Cartesia states sub-90ms time-to-first-audio. It is available in beta. Is it deployable? YES, it is available in beta and as a hosted API. Not as self-hosted weights. Sonic is a closed, commercial model. There are no open weights and no Hugging Face repo. You rent it. Company level: Solo developers and startups (Free/Pro $5 tiers), scaleups running contact centers (Startup $49 / Scale $299), and regulated enterprises needing DPAs, BAAs, and SSO. Industries: Financial services, healthcare, retail and e-commerce, logistics, recruiting, SaaS support, consumer companion apps, media localization Applications: Inbound support agents, outbound qualification calls, IVR replacement, appointment reminders, sales-training simulators, audio localization, in-product voice UI The Architecture Sonic runs on state space models rather than transformers. Cartesia’s launch page frames the usual tradeoffs — speed versus naturalness, accuracy versus cost — as architectural, not inevitable. The practical output is time-to-first-audio. Cartesia states sub-90ms TTS latency, and 100ms transcript latency for its Ink-2 speech-to-text model. Both are vendor-stated model latency, not measured end-to-end round trips. Interactive explainer Features that matter in production Sonic exposes controls built for agent transcripts rather than narration: Inline expression tags. Non-verbal expressions like [laughter] go directly in the transcript. Instant voice cloning from about 10 seconds of audio. Custom pronunciation dictionaries, including IPA overrides such as <<s|ə|ˈ|p|i|n|ə>> for subpoena. Speed, volume, and emotion parameters exposed through the API and integrations like the LiveKit Agents plugin. Native alphanumerics. Order numbers, phone numbers, and confirmation codes read correctly without preprocessing. Cartesia’s launch demos show English with natural pauses and filler words, plus Hinglish code-switching between Hindi and English. Pricing reality Artificial Analysis normalizes Sonic 3.6 at $49.00 per 1M characters. That is half of ElevenLabs Eleven v3 at $100.00, and well above Speechify Simba 3.2 at $10.00 for a 1,240 Elo. Cartesia sells credits, not characters. Scale at $299 per month includes roughly 10,667 TTS minutes and 15 concurrent requests. Line voice agents bill separately at $0.06 per minute. Key Takeaways Sonic-3.6 is #1 on both Artificial Analysis speech arenas — 1,283 Elo Provider Voice, 1,123 Controlled Voice. Winning the Controlled board means the engine improved, not just the voice catalog. It is beta on Cartesia’s API only; docs still list Sonic 3.5 as stable, and partners carry 3.5. Deployable as a hosted API, not self-hosted weights; commercial use starts at the $5 Pro tier. Latency claims (sub-90ms TTFA) are vendor-stated model latency, so benchmark your own round trip. Check out the Project Page-Cartesia Sonic, Cartesia launch page, Cartesia pricing, Cartesia docs, Artificial Analysis Speech Arena and @cartesia on X. All figures verified August 18, 2026.. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas appeared first on MarkTechPost.

Cartesia Ships Sonic-3.6: A Streaming TTS Model That Now Leads Both Artificial Analysis Speech Arenas 投稿を読む »

AI, Committee, ニュース, Uncategorized

The Download: how people really use AI, and Flock’s design choices

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. We still don’t know how people are really using AI AI companies like Anthropic and OpenAI regularly publish reports on how people are using their products. But they only release the data they want us to see, AI researchers say, and there’s no independent source to corroborate it. A new research project called the AI Observatory aims to fill in the gap. Its analysis shows many more sensitive behaviors than are captured in reports from major AI companies, which focus more on work than on personal use. The researchers also found significant differences between models. People were more likely to turn to Anthropic for coding, Gemini for social and roleplay uses, and ChatGPT for homework assistance. Here’s what the AI Observatory reveals about how people use AI. —Eileen Guo What Flock’s defenders are missing Flock Safety, the police-tech giant known for its network of some 120,000 automatic license plate readers around the US, recently announced changes to its platform. The updates are meant to prevent officers from using it for illegal or illegitimate purposes, including stalking. Amid all this, there have recently been several arguments defending Flock: If these cameras help solve crime, is it as big a deal? On a good day they might help catch a kidnapper, and if not, they’re simply snapping pictures of my car that nobody will bother to look at.  But this all skips over a more important question: What kind of crime-fighting system has Flock chosen to build? Its network works the way it does because of decisions about what information to collect, who can search it, how long to keep it, and how widely to share it. Those decisions set the terms of the bargain between security and civil liberties. Find out what a narrower Flock system could look like. —James O’Donnell This story is from The Algorithm, our weekly AI newsletter. Sign up to receive it in your inbox every Monday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 A child privacy trial starting today could change Meta foreverMore than half of the states in the US have joined the lawsuit. (CNBC)+ They say Meta deliberately designed addictive social networks. (Guardian)+ And want changes including ending “like” counts and infinite scroll. (BBC)+ Four of them are demanding $1.4 trillion in damages. (WP $) 2 Nvidia has committed up to $105 billion to OpenAI’s Ohio data centerIt’s slated to cost up to $500 billion and come online in 2028. (CNBC)+ OpenAI will lease the eight-gigawatt site for 20 years. (NYT $)+ How virtual power plants could provide energy for data centers. (MIT Technology Review) 3 Tesla is set to launch Cybercab robotaxi rides in Austin this monthThe rollout could begin with employee rides on public roads. (Information $)+ The EVs will then enter Tesla’s robotaxi service ‌a few days later. (Reuters $)+ The Tesla Semi could also be a big deal for EVs. (MIT Technology Review) 4 Unitree has unveiled a humanoid it claims is faster than any humanThe new “Superman” robot can cover 12.66 meters in a second. (Gizmodo)+ It arrives ahead of the Chinese company’s IPO on Wednesday. (Reuters $)+ US robot startups are struggling with new China restrictions. (Rest of World) 5 A tracked rare book shipment led to Amazon’s AI training operationAmazon scans and destroys books at the facility to train AI. (404 Media $)+ Rare books provide unique, high-quality training data. (Ars Technica)+ But feeding them to AI risks creating a cultural void. (New Scientist $) 6 China wants its data to shape what the world’s AI knowsBeijing is distributing datasets reflecting “mainstream Chinese values.” (NYT $)+ What’s next for Chinese open-source AI? (MIT Technology Review) 7 An AI studio wants to become the HBO of adult contentRogue’s AI video tool produces uncensored adult content. (Wired $)+ AI is creating new risks for porn actors. (MIT Technology Review) 8 Women are being left behind in the AI jobs boomThey accounted for just 26% of new AI hires last year. (Axios) 9 AI has revealed new clues to how breast cancer progressesThe findings could help predict how tumours will develop. (Independent) 10 An unearthed video suggests Apple is adding cameras to AirPodsIt shows AirPods identifying a book using visual intelligence. (Gizmodo) Quote of the day “It is a black hole; it absorbs energy and personality and then re-presents it as spectacle.”  —Writer Carmen Hermosillo made a prescient observation about life online in a 1994 essay, quoted by the Guardian in a story on warnings we ignored about the digital age. One More Thing TERRY RATZLAFF Is this the electric grid of the future? When a slow-moving blizzard hit Nebraska, nearly 10% of Lincoln Electric System’s 150,000 customers lost power. CEO Emeka Anyanwu watched the outage map as crews battled the storm. Yet a spring blizzard like this is the least of his problems. What will happen soon—not only at Lincoln Electric but for all electric utilities—is a challenge of a different order. In the industry, they call it the “trilemma”: the seemingly intractable problem of balancing reliability, affordability, and sustainability. Electricity demand is surging, driven in part by AI, while the industry attempts to transition from power generated with fossil fuels to power generated from renewable sources like solar and wind. Lincoln Electric offers a lens through which to examine those challenges. Explore the challenges of building the grid of the future. —Andrew Blum We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Chinese engineers have built the world’s first true all-material printer.+ Discover how you truly feel about artificial intelligence by completing the AI Compass quiz.+ Get a sense of the space’s extraordinary size with this interactive scale of the universe tool.+ Enjoy a fresh look at “Breaking Bad” in this modified scene showing

The Download: how people really use AI, and Flock’s design choices 投稿を読む »

AI, Committee, ニュース, Uncategorized

Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for AI Agents

google/sam is not Segment Anything. SAM here means Sovereign Agent Mesh, an Apache-2.0 networking project for autonomous AI agents. The problem it targets is concrete. Agents now run across cloud servers, on-prem datacenters, laptops, Raspberry Pis and Android devices. Letting them share tools usually means exposing internal scripts, LLM endpoints or private APIs to the public internet. SAM’s alternative is a zero-config, zero-trust P2P overlay — closer to a private VPN, but scoped to agent-to-agent tool sharing over the Model Context Protocol. Nodes discover each other automatically, survive NAT, and authorize every call cryptographically. Note: The repo carries an explicit disclaimer: this is not an officially supported Google product. Is it deployable? Partially, the engineering is production-shaped, but the public mesh is still labelled a beta testnet. What ships now: Go binaries, an install script, ghcr.io Docker images, a charts/sam-mesh Helm chart, a production Kubernetes guide, and Android/iOS support. The public testnet is bananas.sam-mesh.dev. For real workloads, self-host your control plane. The docs call this “DIY Mode” and it is the path to full data and policy control. Company level: Best fit is mid-market and enterprise engineering orgs running agents across more than one network boundary. Startups inside a single VPC gain less; the value shows up once agents span cloud, datacenter and laptops. Industries: Financial services, healthcare, public sector and defense, and industrial or robotics edge fleets. Broadly, any regulated org that cannot publish internal tools to the internet. Applications: Cross-cloud MCP tool sharing, hybrid on-prem to cloud agent calls, brokered inference endpoints, sandboxed agents with credential injection, and pooled warm workers. Architecture: three binaries sam-control-plane — identity registration, token issuing, policy distribution. sam-router — libp2p bootstrap points and GossipSub routing overlays. sam-node — the P2P client providing mesh transport, self-healing connectivity, and a local MCP HTTP interface. A node joins with sam-node join, then runs with sam-node run. libp2p uses 5001/udp and 5002/tcp; the local MCP API defaults to 8080. Identity: OIDC in, Biscuit out This is the interesting part. The control plane verifies an OIDC JWT. It then translates the claims into Datalog facts and seals them into a Biscuit token. sub becomes user(…), each group becomes group(…), and the peer ID binds in as client_peer_id(…). The consequence: nodes authorize offline. A node evaluates the presented token against its own local rules without calling home. Enforcement is strict default-deny. Access needs an explicit capability fact such as granted_service_exact(…). There are no built-in exceptions — even the discovery catalog system://sam.catalog must be granted. Services use a strict type://name convention with wildcard support (mcp://*, mcp://build-runner.*). Every request runs a two-stage pipeline. Stage 1 gates the connection against ban and revocation caches. Stage 2 runs exactly two Biscuit authorizer passes. The first covers the node’s own identity token to emit target_fact assertions. The second covers the caller’s token. A baseline check blocks replay by requiring the connection peer ID to match the token. Operators can attenuate locally, denying a write tool after 9 PM or blocking contractors. Local allows still cannot bypass control-plane check if constraints. Interactive explainer What an agent actually calls The node exposes standard MCP tools: discover_remote_services, find_remote_tools, and call_remote_tool. Guides cover Gemini, Claude Code, Claude Desktop, Google Antigravity and OpenClaw. sam-node skill install writes a SKILL.md so an agent can bring the node online itself. The enrollment login stays with a human by design. Egress control: sam-box and nano-init The Secure Outbound Gateway targets a real agent-security gap. nano-init runs as PID 1 in the sandbox and sets the proxy environment variables. For tools that ignore them, it LD_PRELOADs an interceptor hooking the C connect() syscall on ports 80 and 443. Traffic reaches sam-box over a Unix domain socket. The gateway verifies the Biscuit, injects the real credential from secrets.yaml, and upgrades the request to HTTPS. The agent sandbox never holds the key. A worked pattern: warm agent pool The code-reviewer pool example fans batch work across identical running workers using ordinary MCP services. A manager learns peers via DHT discovery and tracks busy state with leases. Correctness comes from synchronous lease assignment, fencing tokens, grace eviction, and a POOL_BUSY backstop. Workers verify a short-lived HMAC token offline; anything else returns NO_LEASE. Key Takeaways SAM is Sovereign Agent Mesh, an Apache-2.0 P2P overlay — not Segment Anything. Three binaries: control plane for identity and policy, routers for libp2p transport, nodes for MCP. OIDC claims are translated into Biscuit Datalog facts, so nodes authorize offline. Default-deny is absolute; even the discovery catalog needs an explicit grant. Production use means self-hosting a control plane — the public mesh is a beta testnet. Check out the GitHub Repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for AI Agents appeared first on MarkTechPost.

Meet SAM (Sovereign Agent Mesh): A Zero-Config, Zero-Trust P2P Network for AI Agents 投稿を読む »

AI, Committee, ニュース, Uncategorized

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands

NVIDIA has released TensorRT Model Connect (TRTMC) in public preview, an open-source project that takes a supported Hugging Face or local checkpoint to end-to-end TensorRT inference in two commands. There is no intermediate ONNX export step. The build produces a versioned .bundle artifact that runs through native C++ task APIs, so inference can execute in a C++ service, embedded application, or robotics stack without PyTorch in the runtime path. The project is Apache-2.0 licensed and ships as a collection of family-owned reference implementations rather than a single generic converter. NVIDIA also states that the entire project — model implementations, performance tuning, tests, integrations, and docs — was built using OpenAI Codex agents under human direction and review. Is it deployable? Yes, for evaluation and native integration work, with real conditions. The code is open and installable. Release wheels currently target Linux aarch64 only, with Python 3.10 or 3.12, glibc 2.39 or newer, and TensorRT 11.1.0.106. x86_64 wheels are not published; x86_64 users must take the Docker source-build path. Company level: Best fit today is teams that already own their inference stack: NVIDIA-shop startups, robotics and device companies, and platform or inference teams inside mid-size and large enterprises. Small teams shipping a Python service get less from it. Regulated enterprises should wait for a tagged release before standardizing on it. Industries: Robotics and autonomous machines, industrial inspection and manufacturing, automotive in-vehicle compute, medical devices, defense and aerospace edge systems, and media processing — anywhere inference has to live inside a C++ binary rather than a Python server. Applications: On-device text generation, speech recognition and synthesis, OCR and document parsing, embeddings and reranking for a retrieval service written in C++, diffusion image and video generation, segmentation, and time-series forecasting. The two commands The quick start builds and runs Qwen3-0.6B: trtmc build Qwen/Qwen3-0.6B –precision bf16 –max-cache-length 16384 –output qwen3-0.6b.bundle trtmc run ./qwen3-0.6b.bundle –prompt “What is the capital of France? Answer in one word.” –chat-template –no-thinking The same .bundle loads from C++ with trtmc::load(“./qwen3-0.6b.bundle”). The bundle is the actual design decision TRTMC splits build and runtime at a versioned artifact. Python owns checkpoint resolution and TensorRT engine construction. Native profiles then execute inference in C++ without PyTorch. A small number of hybrid profiles invoke a helper Python executable, and their manifests declare that dependency explicitly. Applications call task APIs — generate(), transcribe(), generate_image(), embed(), solve() — instead of maintaining conversion stages and per-model application glue. trtmc inspect exposes bundle kind, model family, precision, runtime identity, and engines, which makes the artifact auditable rather than opaque. NVIDIA frames the conventional route as PyTorch → ONNX or TorchScript → TensorRT → model-specific C++ integration, and names the failure modes it removes: export gaps, repeated per-model integration, and validation spread across several conversion artifacts. Key Takeaways Two commands take a supported Hugging Face checkpoint to native C++ TensorRT inference, with no ONNX step. A versioned .bundle is the handoff between the Python build and a PyTorch-free C++ runtime. The July 29, 2026 GB300 snapshot covers 105 profiles across 76 families; 102 beat their declared reference by more than 5%. Wheels are Linux aarch64 only today; x86_64 requires the Docker source build. Check out the GitHub Repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands appeared first on MarkTechPost.

NVIDIA Releases TensorRT Model Connect in Public Preview: Hugging Face Checkpoint to Native C++ Inference in Two Commands 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja