YouZum

Committee

AI, Committee, ニュース, Uncategorized

DeepSeek Researchers Apply a 1967 Matrix Normalization Algorithm to Fix Instability in Hyper Connections

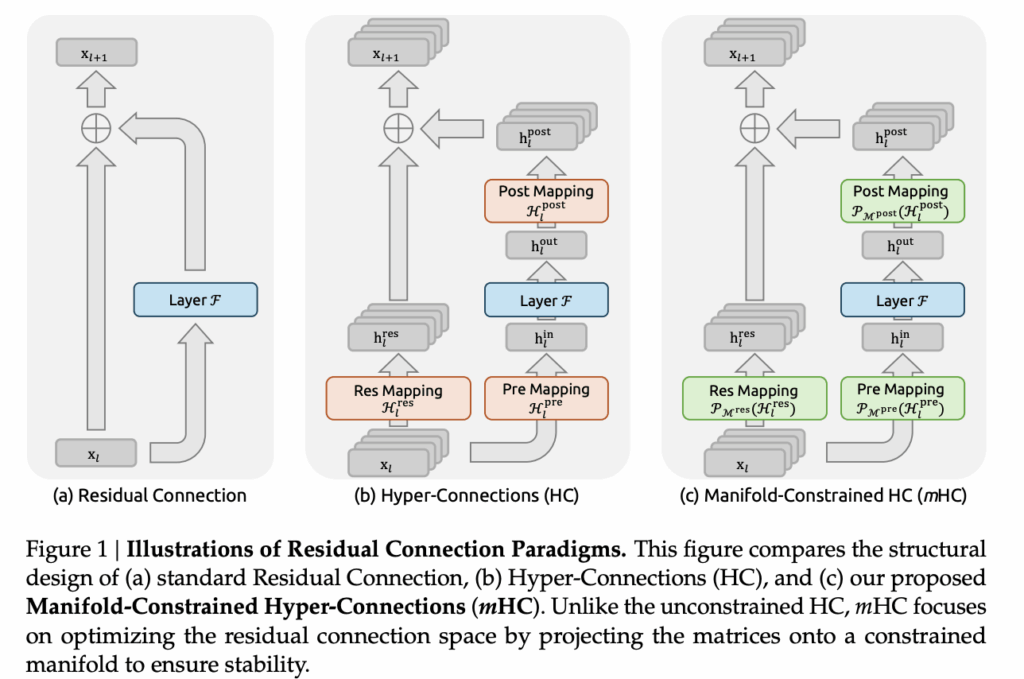
DeepSeek researchers are trying to solve a precise issue in large language model training. Residual connections made very deep networks trainable, hyper connections widened that residual stream, and training then became unstable at scale. The new method mHC, Manifold Constrained Hyper Connections, keeps the richer topology of hyper connections but locks the mixing behavior on a well defined manifold so that signals remain numerically stable in very deep stacks. https://www.arxiv.org/pdf/2512.24880 From Residual Connections To Hyper Connections Standard residual connections, as in ResNets and Transformers, propagate activations with xl+1​=xl​+F(xl​,Wl​)The identity path preserves magnitude and keeps gradients usable even when you stack many layers. Hyper Connections generalize this structure. Instead of a single residual vector of size C, the model keeps an n stream buffer 𝑥𝑙∈𝑅𝑛×𝐶. Three learned mappings control how each layer reads and writes this buffer: Hlpre selects a mixture of streams as the layer input F is the usual attention or feed forward sublayer Hlpost writes results back into the n stream buffer Hlres​∈Rn×n mixes streams between layers The update has the formxl+1​=Hlres​xl​+Hlpost​⊤F(Hlpre​xl​,Wl​) With n set to 4, this design increases expressivity without a large increase in floating point cost, which is why hyper connections improve downstream performance in language models. Why Hyper Connections Become Unstable The problem appears when you look at the product of residual mixers across many layers. In a 27B mixture of experts model, DeepSeek studies the composite mapping and defines an Amax Gain Magnitude based on maximum row and column sums. This metric measures worst case amplification in the forward and backward signal paths. In the hyper connection model, this gain reaches peaks around 3000, far from the ideal value 1 that you expect from a stable residual path. This means small per layer deviations compound into very large amplification factors across depth. Training logs show loss spikes and unstable gradient norms relative to a baseline residual model. At the same time, keeping a multi stream buffer increases memory traffic for each token, which makes naive scaling of hyper connections unattractive for production large language models. Manifold Constrained Hyper Connections mHC keeps the multi stream residual idea but constrains the dangerous part. The residual mixing matrix Hlres no longer lives in the full n by n space. Instead, it is projected onto the manifold of doubly stochastic matrices, also called the Birkhoff polytope. In that set all entries are non negative and each row and each column sums to 1. DeepSeek team enforces this constraint with the classical Sinkhorn Knopp algorithm from 1967, which alternates row and column normalizations to approximate a doubly stochastic matrix. The research team uses 20 iterations per layer during training, which is enough to keep the mapping close to the target manifold while keeping cost manageable. Under these constraints, Hlres​xl behaves like a convex combination of residual streams. Total feature mass is preserved and the norm is tightly regularized, which eliminates the explosive growth seen in plain hyper connections. The research team also parameterize input and output mappings so that coefficients are non negative, which avoids cancellation between streams and keeps the interpretation as averaging clear. With mHC the composite Amax Gain Magnitude stays bounded and peaks at about 1.6 in the 27B model, compared with peaks near 3000 for the unconstrained variant. That is a reduction of about 3 orders of magnitude in worst case amplification, and it comes from a direct mathematical constraint rather than tuned tricks. Systems Work And Training Overhead Constraining every residual mixer with Sinkhorn style iterations adds cost on paper. The research team addresses this with several systems choices: Fused kernels combine RMSNorm, projections and gating for the mHC mappings so that memory traffic stays low Recompute based activation checkpointing trades compute for memory by recomputing mHC activations during backprop for blocks of layers Integration with a DualPipe like pipeline schedule overlaps communication and recomputation, so that additional work does not stall the training pipeline In large scale in house training runs, mHC with expansion rate n equal to 4 adds about 6.7 percent training time overhead relative to the baseline architecture. That figure already includes both the extra compute from Sinkhorn Knopp and the infrastructure optimizations. https://www.arxiv.org/pdf/2512.24880 Empirical Results The research team trains 3B, 9B and 27B mixture of experts models and evaluates them on a standard language model benchmark suite, including tasks like BBH, DROP, GSM8K, HellaSwag, MMLU, PIQA and TriviaQA. For the 27B model, the reported numbers on a subset of tasks show the pattern clearly: Baseline: BBH 43.8, DROP F1 47.0 With hyper connections: BBH 48.9, DROP 51.6 With mHC: BBH 51.0, DROP 53.9 So hyper connections already provide a gain over the basic residual design, and manifold constrained hyper connections push performance further while restoring stability. Similar trends appear on other benchmarks and across model sizes, and scaling curves suggest that the advantage persists across compute budgets and through the full training trajectory rather than only at convergence. Key Takeaways mHC stabilizes widened residual streams: mHC, Manifold Constrained Hyper Connections, widens the residual pathway into 4 interacting streams like HC, but constrains the residual mixing matrices on a manifold of doubly stochastic matrices, so long range propagation remains norm controlled instead of exploding. Exploding gain is reduced from ≈3000 to ≈1.6: For a 27B MoE model, the Amax Gain Magnitude of the composite residual mapping peaks near 3000 for unconstrained HC, while mHC keeps this metric bounded around 1.6, which removes the exploding residual stream behavior that previously broke training. Sinkhorn Knopp enforces doubly stochastic residual mixing: Each residual mixing matrix is projected with about 20 Sinkhorn Knopp iterations so that rows and columns both sum to 1, making the mapping a convex combination of permutations, which restores an identity like behavior while still allowing rich cross stream communication. Small training overhead, measurable downstream gains: Across 3B, 9B and 27B DeepSeek MoE models, mHC improves benchmark accuracy, for example about plus 2.1 percent on BBH for the 27B model, while adding only about 6.7 percent training time
DeepSeek Researchers Apply a 1967 Matrix Normalization Algorithm to Fix Instability in Hyper Connections 投稿を読む »

AI, Committee, ニュース, Uncategorized

Job titles of the future: Head-transplant surgeon

The Italian neurosurgeon Sergio Canavero has been preparing for a surgery that might never happen. His idea? Swap a sick person’s head—or perhaps just the brain—onto a younger, healthier body. Canavero caused a stir in 2017 when he announced that a team he advised in China had exchanged heads between two corpses. But he never convinced skeptics that his technique could succeed—or to believe his claim that a procedure on a live person was imminent. The Chicago Tribune labeled him the “P.T. Barnum of transplantation.” Canavero withdrew from the spotlight. But the idea of head transplants isn’t going away. Instead, he says, the concept has recently been getting a fresh look from life-extension enthusiasts and stealth Silicon Valley startups. Career path It’s been rocky. After he began publishing his surgical ideas a decade ago, Canavero says, he got his “pink slip” from the Molinette Hospital in Turin, where he’d spent 22 years on staff. “I’m an out-of-the-establishment guy. So that has made things harder, I have to say,” he says.   Why he persists No other solution to aging is on the horizon. “It’s become absolutely clear over the past years that the idea of some incredible tech to rejuvenate elderly people—­happening in some secret lab, like Google—is really going nowhere,” he says. “You have to go for the whole shebang.” The whole shebang? He means getting a new body, not just one new organ. Canavero has an easy mastery of English idioms and an unexpected Southern twang. He says that’s due to a fascination with American comics as a child. “For me, learning the language of my heroes was paramount,” he says. “So I can shoot the breeze.”  Cloned bodies Canavero is now an independent investigator and has advised entrepreneurs who want to create brainless human clones as a source of DNA-matched organs that wouldn’t get rejected by a recipient’s immune system. “I can tell you there are guys from top universities involved,” he says. What’s next Combining the necessary technologies, like reliably precise surgical robots and artificial wombs to grow the clones, is going to be complex and very, very expensive. Canavero lacks the funds to take his plans further, but he believes “the money is out there” for a commercial moonshot project: “What I say to the billionaires is ‘Come together.’ You will all have your own share, plus make yourselves immortal.”

Job titles of the future: Head-transplant surgeon 投稿を読む »

AI, Committee, ニュース, Uncategorized

3 things Will Douglas Heaven is into right now

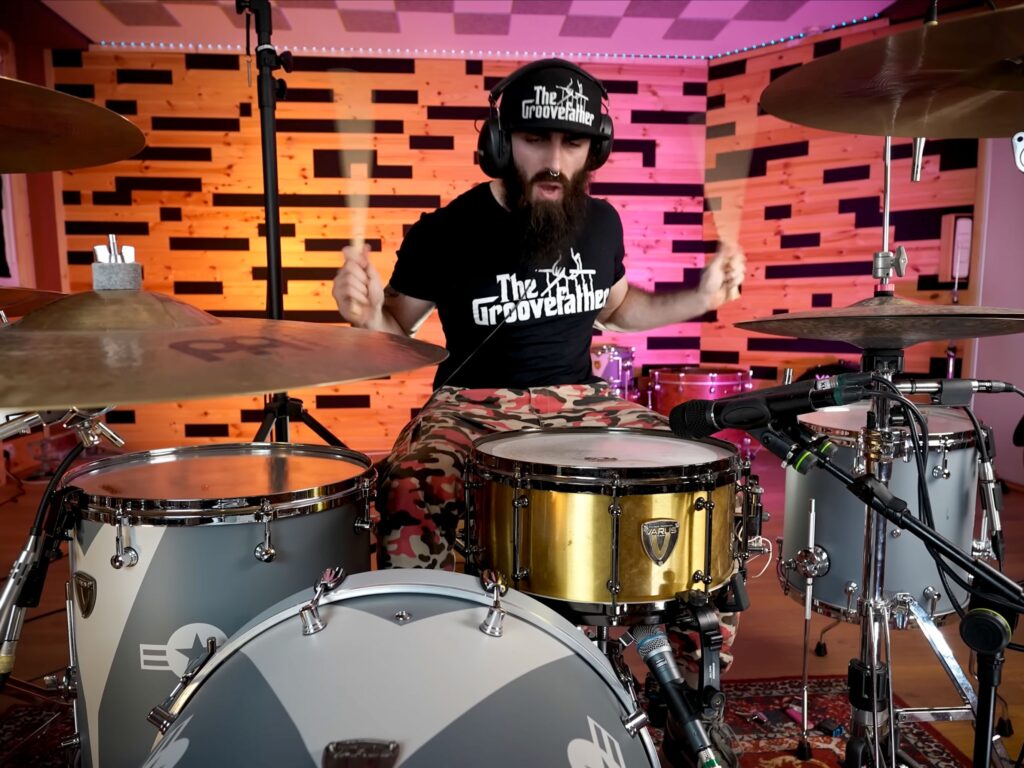
The most amazing drummer on the internet My daughter introduced me to El Estepario Siberiano’s YouTube channel a few months back, and I have been obsessed ever since. The Spanish drummer (real name: Jorge Garrido) posts videos of himself playing supercharged cover versions of popular tracks, hitting his drums with such jaw-dropping speed and technique that he makes other pro drummers shake their heads in disbelief. The dozens of reaction videos posted by other musicians are a joy in themselves.  EL ESTEPARIO SIBERIANO VIA YOUTUBE Garrido is up-front about the countless hours that it took to get this good. He says he sat behind his kit almost all day, every day for years. At a time when machines appear to do it all, there’s a kind of defiance in that level of human effort. It’s why my favorites are Garrido’s covers of electronic music, where he out-drums the drum machine. Check out his version of Skrillex and Missy Elliot’s “Ra Ta Ta” and tell me it doesn’t put happiness in your heart. Finding signs of life in the uncanny valley Watching Sora ­videos of Michael Jackson stealing a box of chicken nuggets or Sam Altman biting into the pink meat of a flame-grilled Pikachu has given me flashbacks to an Ed Atkins exhibition at Tate Britain I saw a few months ago. Atkins is one of the most influential and unsettling British artists of his generation. He is best known for hyper-detailed CG animations of himself (pore-perfect skin, janky movement) that play with the virtual representation of human emotions.  Still from ED ATKINS PIANOWORK 2 2023COURTESY: THE ARTIST, CABINET GALLERY, LONDON, DÉPENDANCE, BRUSSELS, GLADSTONE GALLERY In The Worm we see a CGI Atkins make a long-distance call to his mother during a covid lockdown. The audio is from a recording of an actual conversation. Are we watching Atkins cry or his avatar? Our attention flickers between two realities. “When an actor breaks character during a scene, it’s known as corpsing,” Atkins has said. “I want everything I make to corpse.” Next to Atkins’s work, generative videos look like cardboard cutouts: lifelike but not alive. A dark and dirty book about a talking dingo What’s it like to be a pet? Australian author Laura Jean McKay’s debut novel, The Animals in That Country, will make you wish you’d never asked. A flu-like pandemic leaves people with the ability to hear what animals are saying. If that sounds too Dr. Dolittle for your tastes, rest assured: These animals are weird and nasty. A lot of the time they don’t even make any sense.  SCRIBE With everybody now talking to their computers, McKay’s book resets the anthropomorphic trap we’ve all fallen into. It’s a brilliant evocation of what a nonhuman mind might contain—and a meditation on the hard limits of communication.

3 things Will Douglas Heaven is into right now 投稿を読む »

AI, Committee, ニュース, Uncategorized

Recursive Language Models (RLMs): From MIT’s Blueprint to Prime Intellect’s RLMEnv for Long Horizon LLM Agents

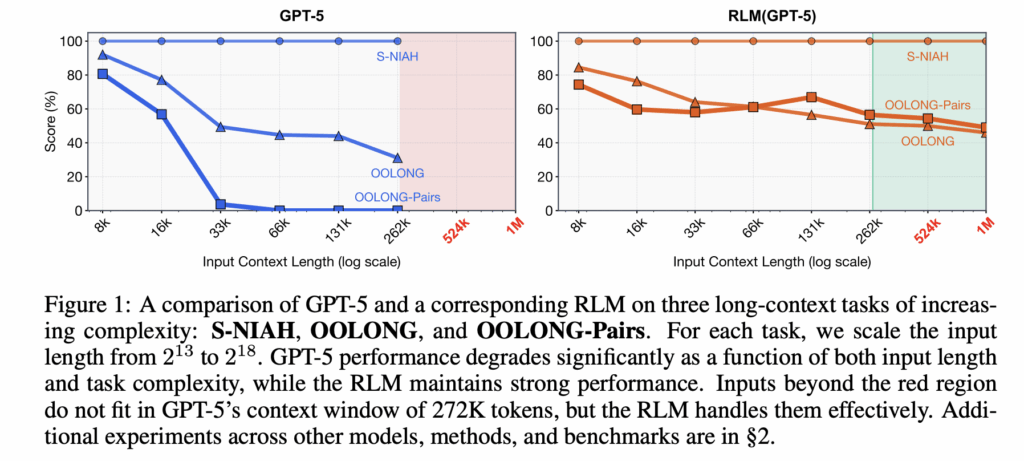
Recursive Language Models aim to break the usual trade off between context length, accuracy and cost in large language models. Instead of forcing a model to read a giant prompt in one pass, RLMs treat the prompt as an external environment and let the model decide how to inspect it with code, then recursively call itself on smaller pieces. https://arxiv.org/pdf/2512.24601 The Basics The full input is loaded into a Python REPL as a single string variable. The root model, for example GPT-5, never sees that string directly in its context. Instead, it receives a system prompt that explains how to read slices of the variable, write helper functions, spawn sub LLM calls, and combine results. The model returns a final text answer, so the external interface stays identical to a standard chat completion endpoint. The RLM design uses the REPL as a control plane for long context. The environment, usually written in Python, exposes tools such as string slicing, regex search and helper functions like llm_query that call a smaller model instance, for example GPT-5-mini. The root model writes code that calls these helpers to scan, partition and summarize the external context variable. The code can store intermediate results in variables and build up the final answer step by step. This structure makes the prompt size independent from the model context window and turns long context handling into a program synthesis problem. https://arxiv.org/pdf/2512.24601 Where it stands in Evaluation? The research paper evaluates this idea on four long context benchmarks with different computational structure. S-NIAH is a constant complexity needle in a haystack task. BrowseComp-Plus is a multi hop web style question answering benchmark over up to 1,000 documents. OOLONG is a linear complexity long context reasoning task where the model must transform many entries and then aggregate them. OOLONG Pairs increases the difficulty further with quadratic pairwise aggregation over the input. These tasks stress both context length and reasoning depth, not only retrieval. On these benchmarks, RLMs give large accuracy gains over direct LLM calls and common long context agents. For GPT-5 on CodeQA, a long document question answering setup, the base model reaches 24.00 accuracy, a summarization agent reaches 41.33, while RLM reaches 62.00 and the RLM without recursion reaches 66.00. For Qwen3-Coder-480B-A35B, the base model scores 20.00, a CodeAct retrieval agent 52.00, and the RLM 56.00 with a REPL only variant at 44.66. The gains are largest on the hardest setting, OOLONG Pairs. For GPT-5, the direct model is almost unusable with F1 equal to 0.04. Summarization and CodeAct agents sit near 0.01 and 24.67. The full RLM reaches 58.00 F1 and the non recursive REPL variant still achieves 43.93. For Qwen3-Coder, the base model stays below 0.10 F1, while the full RLM reaches 23.11 and the REPL only version 17.34. These numbers show that both the REPL and recursive sub calls are critical on dense quadratic tasks. https://arxiv.org/pdf/2512.24601 BrowseComp-Plus highlights effective context extension. The corpus ranges from about 6M to 11M tokens, which is 2 orders of magnitude beyond the 272k token context window of GPT-5. RLM with GPT 5 maintains strong performance even when given 1,000 documents in the environment variable, while standard GPT-5 baselines degrade as document count grows. On this benchmark, RLM GPT 5 achieves around 91.33 accuracy with an average cost of 0.99 USD per query, while a hypothetical model that reads the full context directly would cost between $1.50 and $2.75 at current pricing. The research paper also analyzes the trajectories of RLM runs. Several behavior patterns emerge. The model often starts with a peek step where it inspects the first few thousand characters of the context. It then uses grep style filtering with regex or keyword search to narrow down relevant lines. For more complex queries, it partitions the context into chunks and calls recursive LMs on each chunk to perform labeling or extraction, followed by programmatic aggregation. On long output tasks, the RLM stores partial outputs in variables and stitches them together, which bypasses output length limits of the base model. The new take from Prime Intellect Prime Intellect team has turned this concept into a concrete environment, RLMEnv, integrated in their verifiers stack and Environments Hub. In their design, the main RLM has only a Python REPL, while sub LLMs receive the heavy tools such as web search or file access. The REPL exposes an llm_batch function so the root model can fan out many sub queries in parallel, and an answer variable where the final solution must be written and flagged as ready. This isolates token heavy tool outputs from the main context and lets the RLM delegate expensive operations to sub models. Prime Intellect evaluates this implementation on four environments. DeepDive tests web research with search and open tools and very verbose pages. Math python exposes a Python REPL for difficult competition style math problems. Oolong reuses the long context benchmark inside RLMEnv. Verbatim copy focuses on exact reproduction of complex strings across content types such as JSON, CSV and mixed codes. Across these environments, GPT-5-mini and the INTELLECT-3-MoE model both gain from the RLM scaffold in success rate and in robustness to very long contexts, especially when tool output would otherwise swamp the model context The research paper’s author team and Prime Intellect team both stress that current implementations are not fully optimized. RLM calls are synchronous, recursion depth is limited and cost distributions have heavy tails due to very long trajectories. The real opportunity is to combine RLM scaffolding with dedicated reinforcement learning so that models learn better chunking, recursion and tool usage policies over time. If that happens, RLMs provide a framework where improvements in base models and in systems design convert directly into more capable long horizon agents that can consume 10M plus token environments without context rot. Key Takeaways Here are 5 concise, technical takeaways you can plug under the article. RLMs reframe long context as an environment variable: Recursive Language Models treat the entire prompt as an external string in

Recursive Language Models (RLMs): From MIT’s Blueprint to Prime Intellect’s RLMEnv for Long Horizon LLM Agents 投稿を読む »

AI, Committee, ニュース, Uncategorized

Train Your Large Model on Multiple GPUs with Tensor Parallelism

This article is divided into five parts; they are: • An Example of Tensor Parallelism • Setting Up Tensor Parallelism • Preparing Model for Tensor Parallelism • Train a Model with Tensor Parallelism • Combining Tensor Parallelism with FSDP Tensor parallelism originated from the Megatron-LM paper.

Train Your Large Model on Multiple GPUs with Tensor Parallelism 投稿を読む »

AI, Committee, ニュース, Uncategorized

OpenSIR: Open-Ended Self-Improving Reasoner

arXiv:2511.00602v2 Announce Type: replace Abstract: Recent advances in large language model (LLM) reasoning through reinforcement learning rely on annotated datasets for verifiable rewards, which may limit models’ ability to surpass human-level performance. While self-play offers a promising alternative, existing approaches depend on external verifiers or cannot learn open-endedly. We present Open-Ended Self-Improving Reasoner (OpenSIR), a self-play framework where an LLM learns to generate and solve novel problems by alternating teacher and student roles without external supervision. To generate novel problems, OpenSIR optimises for both difficulty and diversity, rewarding problems that challenge appropriately while exploring distinct concepts, enabling open-ended mathematical discovery. Starting from a single trivial seed problem, OpenSIR substantially improves instruction models: Llama-3.2-3B-Instruct advances from 73.9 to 78.3 on GSM8K, and from 28.8 to 34.4 on College Math, while Gemma-2-2B-Instruct rises from 38.5 to 58.7 on GSM8K. Our analyses reveal that OpenSIR achieves open-ended learning through co-evolving teacher-student roles that adaptively calibrate difficulty and drive diverse exploration, progressing autonomously from basic to advanced mathematics.

OpenSIR: Open-Ended Self-Improving Reasoner 投稿を読む »

AI, Committee, ニュース, Uncategorized

CubeBench: Diagnosing Interactive, Long-Horizon Spatial Reasoning Under Partial Observations

arXiv:2512.23328v2 Announce Type: replace-cross Abstract: Large Language Model (LLM) agents, while proficient in the digital realm, face a significant gap in physical-world deployment due to the challenge of forming and maintaining a robust spatial mental model. We identify three core cognitive challenges hindering this transition: spatial reasoning, long-horizon state tracking via mental simulation, and active exploration under partial observation. To isolate and evaluate these faculties, we introduce CubeBench, a novel generative benchmark centered on the Rubik’s Cube. CubeBench uses a three-tiered diagnostic framework that progressively assesses agent capabilities, from foundational state tracking with full symbolic information to active exploration with only partial visual data. Our experiments on leading LLMs reveal critical limitations, including a uniform 0.00% pass rate on all long-horizon tasks, exposing a fundamental failure in long-term planning. We also propose a diagnostic framework to isolate these cognitive bottlenecks by providing external solver tools. By analyzing the failure modes, we provide key insights to guide the development of more physically-grounded intelligent agents.

CubeBench: Diagnosing Interactive, Long-Horizon Spatial Reasoning Under Partial Observations 投稿を読む »

AI, Committee, ニュース, Uncategorized

MedKGI: Iterative Differential Diagnosis with Medical Knowledge Graphs and Information-Guided Inquiring

arXiv:2512.24181v1 Announce Type: new Abstract: Recent advancements in Large Language Models (LLMs) have demonstrated significant promise in clinical diagnosis. However, current models struggle to emulate the iterative, diagnostic hypothesis-driven reasoning of real clinical scenarios. Specifically, current LLMs suffer from three critical limitations: (1) generating hallucinated medical content due to weak grounding in verified knowledge, (2) asking redundant or inefficient questions rather than discriminative ones that hinder diagnostic progress, and (3) losing coherence over multi-turn dialogues, leading to contradictory or inconsistent conclusions. To address these challenges, we propose MedKGI, a diagnostic framework grounded in clinical practices. MedKGI integrates a medical knowledge graph (KG) to constrain reasoning to validated medical ontologies, selects questions based on information gain to maximize diagnostic efficiency, and adopts an OSCE-format structured state to maintain consistent evidence tracking across turns. Experiments on clinical benchmarks show that MedKGI outperforms strong LLM baselines in both diagnostic accuracy and inquiry efficiency, improving dialogue efficiency by 30% on average while maintaining state-of-the-art accuracy.

MedKGI: Iterative Differential Diagnosis with Medical Knowledge Graphs and Information-Guided Inquiring 投稿を読む »

AI, Committee, ニュース, Uncategorized

IELTS Writing Revision Platform with Automated Essay Scoring and Adaptive Feedback

arXiv:2512.24460v1 Announce Type: new Abstract: This paper presents the design, development, and evaluation of a proposed revision platform assisting candidates for the International English Language Testing System (IELTS) writing exam. Traditional IELTS preparation methods lack personalised feedback, catered to the IELTS writing rubric. To address these shortcomings, the platform features an attractive user interface (UI), an Automated Essay Scoring system (AES), and targeted feedback tailored to candidates and the IELTS writing rubric. The platform architecture separates conversational guidance from a dedicated writing interface to reduce cognitive load and simulate exam conditions. Through iterative, Design-Based Research (DBR) cycles, the study progressed from rule-based to transformer-based with a regression head scoring, mounted with adaptive feedback. Early cycles (2-3) revealed fundamental limitations of rule-based approaches: mid-band compression, low accuracy, and negative $R^2$ values. DBR Cycle 4 implemented a DistilBERT transformer model with a regression head, yielding substantial improvements with MAE of 0.66 and positive $R^2$. This enabled Cycle 5’s adaptive feedback implementation, which demonstrated statistically significant score improvements (mean +0.060 bands, p = 0.011, Cohen’s d = 0.504), though effectiveness varied by revision strategy. Findings suggest automated feedback functions are most suited as a supplement to human instruction, with conservative surface-level corrections proving more reliable than aggressive structural interventions for IELTS preparation contexts. Challenges remain in assessing higher-band essays, and future work should incorporate longitudinal studies with real IELTS candidates and validation from official examiners.

IELTS Writing Revision Platform with Automated Essay Scoring and Adaptive Feedback 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja