YouZum

Committee

AI, Committee, ニュース, Uncategorized

AI is already making online swindles easier. It could get much worse.

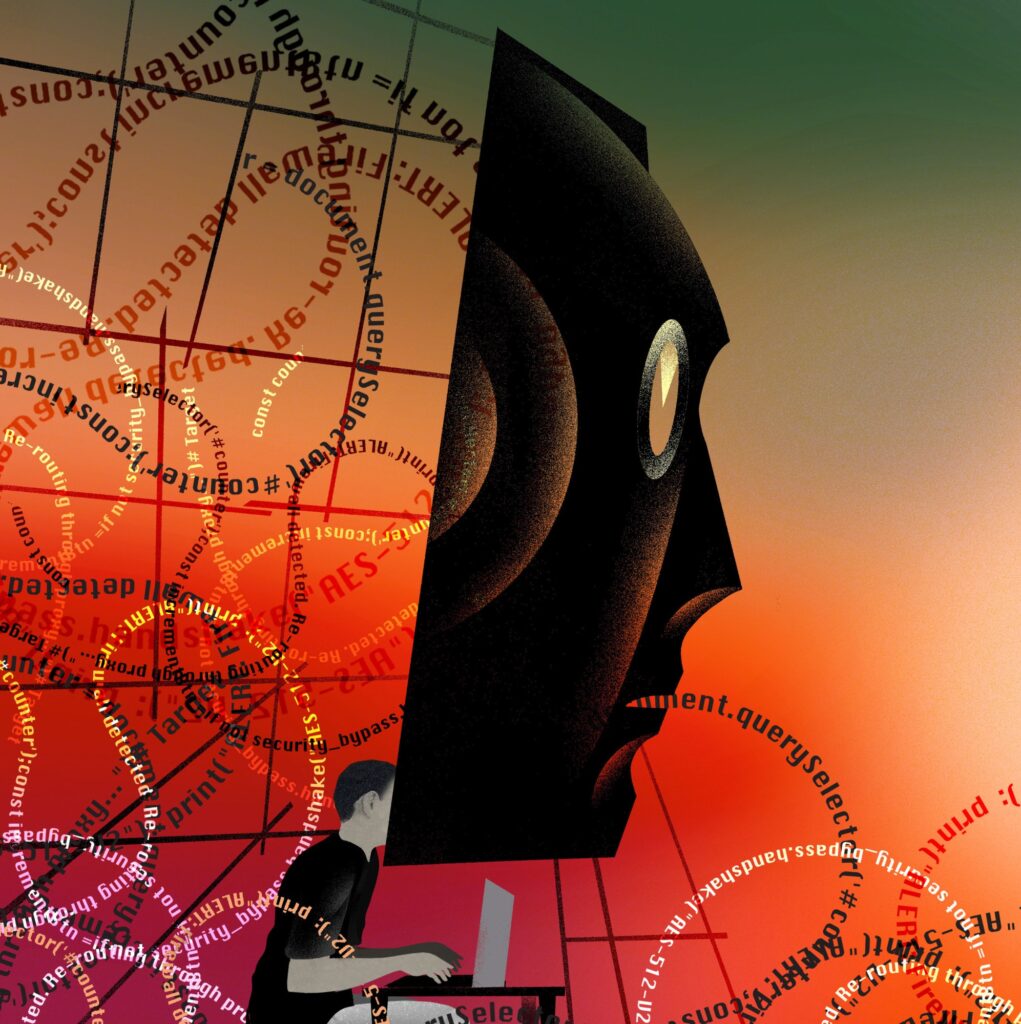
Anton Cherepanov is always on the lookout for something interesting. And in late August last year, he spotted just that. It was a file uploaded to VirusTotal, a site cybersecurity researchers like him use to analyze submissions for potential viruses and other types of malicious software, often known as malware. On the surface it seemed innocuous, but it triggered Cherepanov’s custom malware-detecting measures. Over the next few hours, he and his colleague Peter Strýček inspected the sample and realized they’d never come across anything like it before. The file contained ransomware, a nasty strain of malware that encrypts the files it comes across on a victim’s system, rendering them unusable until a ransom is paid to the attackers behind it. But what set this example apart was that it employed large language models (LLMs). Not just incidentally, but across every stage of an attack. Once it was installed, it could tap into an LLM to generate customized code in real time, rapidly map a computer to identify sensitive data to copy or encrypt, and write personalized ransom notes based on the files’ content. The software could do this autonomously, without any human intervention. And every time it ran, it would act differently, making it harder to detect. Cherepanov and Strýček were confident that their discovery, which they dubbed PromptLock, marked a turning point in generative AI, showing how the technology could be exploited to create highly flexible malware attacks. They published a blog post declaring that they’d uncovered the first example of AI-powered ransomware, which quickly became the object of widespread global media attention. But the threat wasn’t quite as dramatic as it first appeared. The day after the blog post went live, a team of researchers from New York University claimed responsibility, explaining that the malware was not, in fact, a full attack let loose in the wild but a research project, merely designed to prove it was possible to automate each step of a ransomware campaign—which, they said, they had.  PromptLock may have turned out to be an academic project, but the real bad guys are using the latest AI tools. Just as software engineers are using artificial intelligence to help write code and check for bugs, hackers are using these tools to reduce the time and effort required to orchestrate an attack, lowering the barriers for less experienced attackers to try something out.  The likelihood that cyberattacks will now become more common and more effective over time is not a remote possibility but “a sheer reality,” says Lorenzo Cavallaro, a professor of computer science at University College London.  Some in Silicon Valley warn that AI is on the brink of being able to carry out fully automated attacks. But most security researchers say this claim is overblown. “For some reason, everyone is just focused on this malware idea of, like, AI superhackers, which is just absurd,” says Marcus Hutchins, who is principal threat researcher at the security company Expel and famous in the security world for ending a giant global ransomware attack called WannaCry in 2017.  Instead, experts argue, we should be paying closer attention to the much more immediate risks posed by AI, which is already speeding up and increasing the volume of scams. Criminals are increasingly exploiting the latest deepfake technologies to impersonate people and swindle victims out of vast sums of money. These AI-enhanced cyberattacks are only set to get more frequent and more destructive, and we need to be ready.  Spam and beyond Attackers started adopting generative AI tools almost immediately after ChatGPT exploded on the scene at the end of 2022. These efforts began, as you might imagine, with the creation of spam—and a lot of it. Last year, a report from Microsoft said that in the year leading up to April 2025, the company had blocked $4 billion worth of scams and fraudulent transactions, “many likely aided by AI content.”  At least half of spam email is now generated using LLMs, according to estimates by researchers at Columbia University, the University of Chicago, and Barracuda Networks, who analyzed nearly 500,000 malicious messages collected before and after the launch of ChatGPT. They also found evidence that AI is increasingly being deployed in more sophisticated schemes. They looked at targeted email attacks, which impersonate a trusted figure in order to trick a worker within an organization out of funds or sensitive information. By April 2025, they found, at least 14% of those sorts of focused email attacks were generated using LLMs, up from 7.6% in April 2024. In one high-profile case, a worker was tricked into transferring $25 million to criminals via a video call with digital versions of the company’s chief financial officer and other employees. And the generative AI boom has made it easier and cheaper than ever before to generate not only emails but highly convincing images, videos, and audio. The results are much more realistic than even just a few short years ago, and it takes much less data to generate a fake version of someone’s likeness or voice than it used to. Criminals aren’t deploying these sorts of deepfakes to prank people or to simply mess around—they’re doing it because it works and because they’re making money out of it, says Henry Ajder, a generative AI expert. “If there’s money to be made and people continue to be fooled by it, they’ll continue to do it,” he says. In one high-­profile case reported in 2024, a worker at the British engineering firm Arup was tricked into transferring $25 million to criminals via a video call with digital versions of the company’s chief financial officer and other employees. That’s likely only the tip of the iceberg, and the problem posed by convincing deepfakes is only likely to get worse as the technology improves and is more widely adopted.  BRIAN STAUFFER Criminals’ tactics evolve all the time, and as AI’s capabilities improve, such people are constantly probing how those new capabilities can help them gain an advantage over victims.

AI is already making online swindles easier. It could get much worse. 投稿を読む »
AI, Committee, ニュース, Uncategorized

EVs could be cheaper to own than gas cars in Africa by 2040

Electric vehicles could be economically competitive in Africa sooner than expected. Just 1% of new cars sold across the continent in 2025 were electric, but a new analysis finds that with solar off-grid charging, EVs could be cheaper to own than gas vehicles by 2040. There are major barriers to higher EV uptake in many countries in Africa, including a sometimes unreliable grid, limited charging infrastructure, and a lack of access to affordable financing. As a result some previous analyses have suggested that fossil-fuel vehicles would dominate in Africa through at least 2050.  But as batteries and the vehicles they power continue to get cheaper, the economic case for EVs is building. Electric two-wheelers, cars, larger automobiles, and even minibuses could compete in most African countries in just 15 years, according to the new study, published in Nature Energy. “EVs have serious economic potential in most African countries in the not-so-distant future,” says Bessie Noll, a senior researcher at ETH Zürich and one of the authors of the study. The study considered the total cost of ownership over the lifetime of a vehicle. That includes the sticker price, financing costs, and the cost of fueling (or charging). The researchers didn’t consider policy-related costs like taxes, import fees, and government subsidies, choosing to focus instead on only the underlying economics. EVs are getting cheaper every year as battery and vehicle manufacturing improve and production scales, and the researchers found that in most cases and in most places across Africa, EVs are expected to be cheaper than equivalent gas-powered vehicles by 2040. EVs should also be less expensive than vehicles that use synthetic fuels.  For two-wheelers like electric scooters, EVs could be the cheaper option even sooner: with smaller, cheaper batteries, these vehicles will be economically competitive by the end of the decade. On the other hand, one of the most difficult segments for EVs to compete in is small cars, says Christian Moretti, a researcher at ETH Zürich and the Paul Scherrer Institute in Switzerland. Because some countries still have limited or unreliable grid access, charging is a major barrier to EV uptake, Noll says. So for EVs, the authors analyzed the cost of buying not only the vehicle but also a solar off-grid charging system. This includes solar panels, batteries, and the inverter required to transform the electricity into a version that can charge an EV. (The additional batteries help the system store energy for charging at times when the sun isn’t shining.) Mini grids and other standalone systems that include solar panels and energy storage are increasingly common across Africa. It’s possible that this might be a primary way that EV owners in Africa will charge their vehicles in the future, Noll says. One of the bigger barriers to EVs in Africa is financing costs, she adds. In some cases, the cost of financing can be more than the up-front cost of the vehicle, significantly driving up the cost of ownership. Today, EVs are more expensive than equivalent gas-powered vehicles in much of the world. But in places where it’s relatively cheap to borrow money, that difference can be spread out across the course of a vehicle’s whole lifetime for little cost. Then, since it’s often cheaper to charge an EV than fuel a gas-powered car, the EV is less expensive over time.  In some African countries, however, political instability and uncertain economic conditions make borrowing money more expensive. To some extent, the high financing costs affect the purchase of any vehicle, regardless of how it’s powered. But EVs are more expensive up front than equivalent gas-powered cars, and that higher up-front cost adds up to more interest paid over time. In some cases, financing an EV can also be more expensive than financing a gas vehicle—the technology is newer, and banks may see the purchase as more of a risk and charge a higher interest rate, says Kelly Carlin, a manager in the program on carbon-free transportation at the Rocky Mountain Institute, an energy think tank. The picture varies widely depending on the country, too. In South Africa, Mauritius, and Botswana, financing conditions are already close to levels required to allow EVs to reach cost parity, according to the study. In higher-risk countries (the study gives examples including Sudan, which is currently in a civil war, and Ghana, which is recovering from a major economic crisis), financing costs would need to be cut drastically for that to be the case.  Making EVs an affordable option will be a key first step to putting more on the roads in Africa and around the world. “People will start to pick up these technologies when they’re competitive,” says Nelson Nsitem, lead Africa energy transition analyst at BloombergNEF, an energy consultancy.  Solar-based charging systems, like the ones mentioned in the study, could help make electricity less of a constraint, bringing more EVs to the roads, Nsitem says. But there’s still a need for more charging infrastructure, a major challenge in many countries where the grid needs major upgrades for capacity and reliability, he adds.  Globally, more EVs are hitting the roads every year. “The global trend is unmistakable,” Carlin says. There are questions about how quickly it’s happening in different places, he says, “but the momentum is there.”

EVs could be cheaper to own than gas cars in Africa by 2040 投稿を読む »

AI, Committee, ニュース, Uncategorized

Is the Reversal Curse a Binding Problem? Uncovering Limitations of Transformers from a Basic Generalization Failure

arXiv:2504.01928v2 Announce Type: replace Abstract: Despite their impressive capabilities, LLMs exhibit a basic generalization failure known as the Reversal Curse, where they struggle to learn reversible factual associations. Understanding why this occurs could help identify weaknesses in current models and advance their generalization and robustness. In this paper, we conjecture that the Reversal Curse in LLMs is a manifestation of the long-standing binding problem in cognitive science, neuroscience and AI. Specifically, we hypothesize two primary causes of the Reversal Curse stemming from transformers’ limitations in conceptual binding: the inconsistency and entanglements of concept representations. We perform a series of experiments that support these conjectures. Our exploration leads to a model design based on JEPA (Joint-Embedding Predictive Architecture) that for the first time breaks the Reversal Curse without side-stepping it with specialized data augmentation or non-causal masking, and moreover, generalization could be further improved by incorporating special memory layers that support disentangled concept representations. Our research opens up the broader fundamental challenge of designing models capable of learning systematic conceptual binding with less human scaffolding.

Is the Reversal Curse a Binding Problem? Uncovering Limitations of Transformers from a Basic Generalization Failure 投稿を読む »

AI, Committee, ニュース, Uncategorized

Rethinking Memory Mechanisms of Foundation Agents in the Second Half: A Survey

arXiv:2602.06052v3 Announce Type: replace Abstract: The research of artificial intelligence is undergoing a paradigm shift from prioritizing model innovations over benchmark scores towards emphasizing problem definition and rigorous real-world evaluation. As the field enters the “second half,” the central challenge becomes real utility in long-horizon, dynamic, and user-dependent environments, where agents face context explosion and must continuously accumulate, manage, and selectively reuse large volumes of information across extended interactions. Memory, with hundreds of papers released this year, therefore emerges as the critical solution to fill the utility gap. In this survey, we provide a unified view of foundation agent memory along three dimensions: memory substrate (internal and external), cognitive mechanism (episodic, semantic, sensory, working, and procedural), and memory subject (agent- and user-centric). We then analyze how memory is instantiated and operated under different agent topologies and highlight learning policies over memory operations. Finally, we review evaluation benchmarks and metrics for assessing memory utility, and outline various open challenges and future directions.

Rethinking Memory Mechanisms of Foundation Agents in the Second Half: A Survey 投稿を読む »

AI, Committee, ニュース, Uncategorized

MolLangBench: A Comprehensive Benchmark for Language-Prompted Molecular Structure Recognition, Editing, and Generation

arXiv:2505.15054v3 Announce Type: replace Abstract: Precise recognition, editing, and generation of molecules are essential prerequisites for both chemists and AI systems tackling various chemical tasks. We present MolLangBench, a comprehensive benchmark designed to evaluate fundamental molecule-language interface tasks: language-prompted molecular structure recognition, editing, and generation. To ensure high-quality, unambiguous, and deterministic outputs, we construct the recognition tasks using automated cheminformatics tools, and curate editing and generation tasks through rigorous expert annotation and validation. MolLangBench supports the evaluation of models that interface language with different molecular representations, including linear strings, molecular images, and molecular graphs. Evaluations of state-of-the-art models reveal significant limitations: the strongest model (GPT-5) achieves $86.2%$ and $85.5%$ accuracy on recognition and editing tasks, which are intuitively simple for humans, and performs even worse on the generation task, reaching only $43.0%$ accuracy. These results highlight the shortcomings of current AI systems in handling even preliminary molecular recognition and manipulation tasks. We hope MolLangBench will catalyze further research toward more effective and reliable AI systems for chemical applications.The dataset and code can be accessed at https://huggingface.co/datasets/ChemFM/MolLangBench and https://github.com/TheLuoFengLab/MolLangBench, respectively.

MolLangBench: A Comprehensive Benchmark for Language-Prompted Molecular Structure Recognition, Editing, and Generation 投稿を読む »

AI, Committee, ニュース, Uncategorized

BioACE: An Automated Framework for Biomedical Answer and Citation Evaluations

arXiv:2602.04982v2 Announce Type: replace Abstract: With the increasing use of large language models (LLMs) for generating answers to biomedical questions, it is crucial to evaluate the quality of the generated answers and the references provided to support the facts in the generated answers. Evaluation of text generated by LLMs remains a challenge for question answering, retrieval-augmented generation (RAG), summarization, and many other natural language processing tasks in the biomedical domain, due to the requirements of expert assessment to verify consistency with the scientific literature and complex medical terminology. In this work, we propose BioACE, an automated framework for evaluating biomedical answers and citations against the facts stated in the answers. The proposed BioACE framework considers multiple aspects, including completeness, correctness, precision, and recall, in relation to the ground-truth nuggets for answer evaluation. We developed automated approaches to evaluate each of the aforementioned aspects and performed extensive experiments to assess and analyze their correlation with human evaluations. In addition, we considered multiple existing approaches, such as natural language inference (NLI) and pre-trained language models and LLMs, to evaluate the quality of evidence provided to support the generated answers in the form of citations into biomedical literature. With the detailed experiments and analysis, we provide the best approaches for biomedical answer and citation evaluation as a part of BioACE (https://github.com/deepaknlp/BioACE) evaluation package.

BioACE: An Automated Framework for Biomedical Answer and Citation Evaluations 投稿を読む »

AI, Committee, ニュース, Uncategorized

Do Multilingual LLMs have specialized language heads?

arXiv:2602.08625v1 Announce Type: new Abstract: Multilingual large language models (LLMs) have gained significant popularity for their ability to process and generate text across multiple languages. However, deploying these models in production can be inefficient when only a subset of the supported languages is of interest. There has been some research conducted on identifying whether machine translation models have language-specific or language-agnostic heads, however no research has been conducted for multilingual LLMs, to the best of our knowledge, that as we know are capable of performing diverse tasks beyond just translation. This paper explores whether multilingual LLMs have specialized language attention heads for each language, and investigates the possibility of removing language-specific heads for unwanted languages without degrading performance in the targeted languages. Our findings could inform more efficient deployment strategies for multilingual LLMs, enabling reduced model complexity while maintaining high accuracy for targeted languages.

Do Multilingual LLMs have specialized language heads? 投稿を読む »

AI, Committee, ニュース, Uncategorized

Improving Data and Reward Design for Scientific Reasoning in Large Language Models

arXiv:2602.08321v1 Announce Type: new Abstract: Solving open-ended science questions remains challenging for large language models, particularly due to inherently unreliable supervision and evaluation. The bottleneck lies in the data construction and reward design for scientific post-training. We develop a large-scale, systematic data processing pipeline that transforms heterogeneous open-source science data into Dr. SCI dataset, which comprises of 1M questions across eight STEM subjects, with explicit verifiable/open-ended splits, scalable difficulty annotation, and fine-grained rubrics that operationalize evaluation for open-ended answers. Building on this dataset, we propose the Dr. SCI post-training pipeline, which redesigns the standard SFT -> RL workflow through three components: (i) Exploration-Expanding SFT, which broadens the model’s reasoning pattern coverage prior to RL; (ii) Dynamic Difficulty Curriculum, which adapts training data to the model’s evolving scientific capability; and (iii) SciRubric-Guided RL, which enables stable reinforcement learning on open-ended scientific questions via rubric-based evaluation with explicit answer correctness. Qwen3-4B-Base trained using Dr.SCI pipeline achieves 63.2 on GPQA-diamond and 32.4 on GPQA-general, consistently improves over strong post-trained baselines such as o1-mini and GPT-4o, demonstrating substantial gains in scientific reasoning, especially in open-ended settings.

Improving Data and Reward Design for Scientific Reasoning in Large Language Models 投稿を読む »

We use cookies to improve your experience and performance on our website. You can learn more at プライバシーポリシー and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
ja