YouZum

Notizie

AI, Committee, Notizie, Uncategorized

The Download: your stake in OpenAI, and the Treasury’s AI warning

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Your family’s $300 stake in OpenAI Sam Altman’s proposal that Americans should share in the wealth created by AI is back in the spotlight, with reports that he is discussing giving the US government a 5% stake in OpenAI. At the company’s current valuation, that stake would be worth roughly $320 per American household. The idea is meant to address concerns that AI companies are benefiting from human-generated work without compensating creators, while also easing fears that AI will cause a collapse of the labor market by providing a safety net.  The details, however, remain unclear. Indeed, the offer may be more powerful as a political narrative than as a policy plan. Read the full story on what the dividend proposal reveals about the future of AI. —James O’Donnell This article is from The Algorithm, our weekly AI newsletter. Sign up to receive it in your inbox every Monday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.  1 A leaked Treasury report compares the AI market to the dotcom bubble Which contradicts the administration’s public optimism about AI. (NOTUS)+ Fears that the market is overinflated are growing. (Reuters $)+ And AI profits are hiding bigger risks in earnings reports. (FT $)+ What even is the AI bubble? (MIT Technology Review) 2 Samsung profits have jumped 1,800% on booming AI chip salesIt just reported its third consecutive record quarterly profit. (BBC)+ But its shares slumped over fears that the AI boom will stall. (Reuters $)+ That boom has turned Samsung into a $1 trillion company. (CNBC) 3 A US cyber agency is using Mythos to audit government codeSources say CISA is tapping Anthropic’s model to search for bugs. (Reuters $)+ Agencies are using it despite Anthropic’s feud with the White House. (Axios) 4 Illinois’ governor has signed the nation’s strongest frontier AI lawIt’s designed to protect citizens from AI risks. (Gizmodo)+ US lawmakers are clashing over AI rules. (MIT Technology Review) 5 A hidden tracker in Claude Code has been exposed and removedIt secretly monitored users in China. (WP $)+ Critics said it shows Anthropic’s willingness to surveil users. (Ars Technica)+ The company has also found a hidden “thinking” space in Claude. (Axios) 6 Russia is suspected of flying drones over Europe from a shadow fleetThe flights were reportedly launched from commercial ships. (Ars Technica)+ Europe has a drone-filled vision for future wars. (MIT Technology Review) 7 A controversial AI “actor” is set to star in its first feature filmTilly Norwood will debut in a comedy-drama called “Misaligned.” (Variety)+ A major actors union has lambasted the AI creation. (NBC News) 8 AI costs are driving US companies toward Chinese modelsBusinesses are hunting for cheaper model alternatives. (CNBC)+ Chinese AI labs are betting big on open source. (MIT Technology Review) 9 Researchers have shown quantum proofs can beat classical onesThey found a problem that classical proofs can’t solve. (Quanta) 10 Earth will never be swallowed by the sun, according to new modelsBut it probably won’t be much fun to live here by that point anyway! (Wired $) Quote of the day “The goal might be to make machines in our image. But what I fear is that—perhaps without even quite noticing—we remake ourselves in theirs.”  —Reporter Sarah O’Connor sounds a note of caution in her new book, We Are Not Machines, the Guardian reports. One More Thing KATE DEHLER Adventures in the genetic time machine Eske Willerslev, a specialist in recovering DNA from old bones and objects, has made numerous breakthroughs. These include recovering the first more or less complete genome of an ancient human and 2.4-million-year-old genetic material from Greenland, revealing that today’s Arctic desert was once a forest with poplar, birch, and mastodons. These findings are part of a wave of discoveries from what’s being called an “ancient-DNA revolution.”  Beyond revealing stories of human migration and vanished ecosystems, scientists believe ancient DNA can unearth clues about modern diseases. It could even lead to a better food supply for our warming world. “And can we get that?” Willerslev asks. “Yes, I believe we can.” Discover how ancient DNA could rescue the future.  —Antonio Regalado We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Underworld’s electric set from EDC Las Vegas 2026 has been released as a full concert video.+ This photographic journey through global soccer culture captures the mad passion of fandom around the world.+ Feeling unhinged? Me too. This playlist of gloriously intense classical music sympathetically captures the mood.+ If you’re looking for visual inspiration, this collection of graphic design archives from across the web is a goldmine.

The Download: your stake in OpenAI, and the Treasury’s AI warning Leggi l'articolo »
AI, Committee, Notizie, Uncategorized

Liquid AI Open-Sources Antidoom: A Final Token Preference Optimization (FTPO) Method that Reduces Doom Loops in Reasoning Models

Liquid AI has released Antidoom, an open-source method that targets a common failure mode in reasoning models. That failure mode is the doom loop. In a doom loop, a model emits a span. It then repeats that span again and again. The output continues until the context window is exhausted. Small reasoning models are more prone to this, especially on long thinking traces and hard problems. On an early checkpoint of LFM2.5-2.6B, 10.2% of completions on hard math and coding prompts produced repetitive loops. After Antidoom training, that rate fell to 1.4%. Eval scores improved across the board, attributable entirely to the reduced looping. TL;DR Antidoom reduces doom loops by retraining only the first loop-start token. FTPO spreads probability across multiple coherent alternatives, not one replacement. LFM2.5-2.6B looping fell 10.2% to 1.4%; Qwen3.5-4B fell 22.9% to 1%. The pipeline runs in a few hours, and the full stack is open source. What is Antidoom? Antidoom is a targeted fix, not a broad sampling change. It finds the exact token that begins a loop. It then trains the model to prefer coherent alternatives at that single position. The rest of the distribution stays largely untouched. The method adapts Antislop. It trains on chosen/rejected pairs that represent a single completion token. The training algorithm is Final Token Preference Optimization (FTPO), which is similar to DPO. The training teaches the model nothing new about math or code. It clears the looping that blocked answers the model could already produce. Anatomy of a Doom Loop Liquid AI team attributes doom loops to three mechanisms working together: Mechanism 1: overtrained tokens plus uncertainty. Some tokens are more likely to be selected in general. Well-known examples in the wild include ‘delve’ and ‘testament.’ Liquid AI team notes this can trace back to synthetic data in the training set. In reasoning traces, high-prior continuations often include discourse markers such as ‘Wait’ or ‘Alternatively.’ These tokens are not inherently bad. They can mark a useful change of strategy, a verification step, or a branch. When the model is uncertain or stuck, they instead become attractive fallback continuations. For an early LFM2.5-2.6B checkpoint, the most common loop-starting tokens were the following. Token Share of loop starts the 11.39% So 4.51% Alternatively 3.22% Wait 2.56% But 2.46% Mechanism 2: prior context reinforces the loop. Each repetition pushes every token in the span toward probability that Duan et al. study this in their work on circular reasoning. They link it to a “V-shaped” attention pattern. They find that semantic repetition precedes textual repetition. Mechanism 3: greedy sampling. Reasoning models usually run at low temperature for stable, reproducible traces. At temperature 0, the most likely token is always selected. A locally reinforced loop then has no exit. Liquid AI reports significant looping even at temp=0.67. Lower temperatures exacerbate the problem. How Antidoom Locates the Failure Antidoom generates completions on a prompt mix designed to elicit looping, at low temperature. That mix ships as the LiquidAI/antidoom-mix-v1.0 dataset. A loop is detected when a section repeats at least four times, over at least 60 characters. The method then targets the first token of the first repeat. At that position, it takes the base model’s top-k log-prob alternatives. It filters short or non-alphanumeric noise. It keeps up to 20 plausible substitutes as chosen tokens. Each training row is a tuple of prompt prefix, one rejected token, and one or more chosen tokens. The chosen and rejected distributions are regularised before training. Otherwise a few culprits like Wait, So, and the would dominate and over-suppression would degrade reasoning. The detection rule itself is simple to state in code. The snippet below is illustrative. Copy CodeCopiedUse a different Browser # A loop = a unit repeating >=4 times, spanning >=60 characters. # Returns the index of the first token of the first repeat (the target), else None. def find_loop(text, min_repeats=4, min_chars=60): n = len(text) for span in range(1, n // min_repeats + 1): start = 0 while start + span * min_repeats <= n: unit = text[start:start + span] repeats = 1 pos = start + span while text[pos:pos + span] == unit: repeats += 1 pos += span if repeats >= min_repeats and span * repeats >= min_chars: return start + span # first token of the first repeat start += 1 return None Each detected loop then becomes one training row. The structure is a simple tuple. Copy CodeCopiedUse a different Browser # One FTPO training row, per the post’s [prefix, rejected, chosen] format. row = { “prompt”: prefix_up_to_the_loop, # text before the first repeat “rejected”: ” Wait”, # the single token that started the loop “chosen”: [” So”, ” Since”, ” The”, ” Therefore”], # up to 20 alternatives } Final Token Preference Optimization (FTPO) FTPO is a preference-optimization algorithm similar to DPO. A training sample has a prompt, a chosen continuation, and a rejected continuation. It is built to change a handful of tokens, with minimal disturbance to the model otherwise. FTPO differs from DPO in four ways: Final token training: It trains only the trailing token of a sequence that is midway through generation. Multiple chosen tokens per sample: It spreads probability across a group of alternatives, so one overtrained token is not simply replaced by another. KL-like loss in logit space: It omits the softmax and computes divergence from reference in logits, avoiding pressure on unrelated tokens. Two-part regularization: Chosen and rejected logits move more freely, while the remaining vocab stays tightly constrained. In the Antidoom implementation, the model trains for one epoch with LoRA. High LoRA ranks of 128-256 gave the best results. Training covers all attention and MLP projections, plus lm_head. Learning rates land around 4e-6 to 2e-5. Training uses early stopping on chosen_win, the share of samples where chosen tokens beat rejected. Stopping at chosen_win=0.35 cut doom-loop rates from 20-30% down to 1-2%. Training longer tended to degrade the model. For the early LFM2.5-2.6B checkpoint, training-set generation took about one hour on 8x MI325 GPUs. Training then

Liquid AI Open-Sources Antidoom: A Final Token Preference Optimization (FTPO) Method that Reduces Doom Loops in Reasoning Models Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Sakana AI Launches Sakana Translate, a Namazu-Powered Japanese–English–Chinese Translation Tool With Translate, Proofread, and Ask Modes

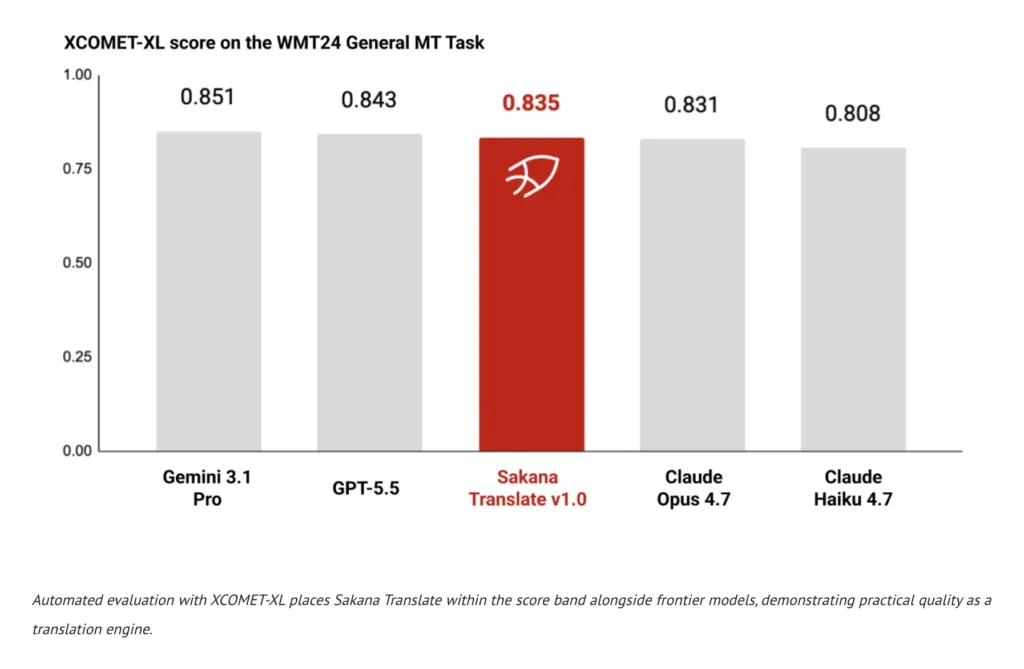
Sakana AI has added a new feature called Sakana Translate to its chat service, Sakana Chat. It handles bidirectional translation across Japanese, English, and Chinese. The translation engine is Namazu, the company’s model series adapted for Japanese. Sakana Translate ships as a free web app. A single account unlocks all three of its modes. What is Sakana Translate Sakana Translate is a browser-based translation product, not a new base model. It runs on Namazu, Sakana AI’s Japan-adapted model series. The concept Sakana AI states is ‘deep translation for Japan.’ The goal goes beyond swapping words and sentence structures. It aims to carry context, tone, and register between languages. That focus targets a specific gap. Sakana AI argues that general tools often miss what makes Japanese distinctive. Examples include business honorifics, culturally specific concepts, abbreviations, and internet slang. Grammar may stay correct while interpersonal tone gets lost. The product bundles three functions into one screen: Translate, Proofread, and Ask. The Three Modes, Explained Each mode targets a different everyday task. The table below summarizes them. Mode What it does Key detail Best for Translate Converts pasted text between the three languages Up to ~5,000 Japanese characters, streaming output, history saved automatically Emails, slide decks, articles, web pages Proofread Refines a draft into a more natural version Changes shown with diff highlighting; adjusts tone, politeness, and formality Business email and English writing checks Ask Answers follow-up questions about a result Clarifies nuance, suggests alternatives, explains grammar in the same context Learning why a translation reads the way it does A few terms are worth unpacking for engineers new to this space. Streaming output means the translation appears progressively, token by token. You do not wait for the full result before reading. This mirrors how chat models return text. Diff highlighting shows exactly what changed. Additions and removals are marked inline, like a version-control diff. Proofread goes past grammar. It also tunes naturalness, politeness, and the register a reader expects. Ask removes the tool-switching problem. You no longer jump between a translator and a dictionary. Nuance questions get answered against the same source and output. You can try all three modes in the interactive demo below How Namazu Powers It Namazu is the engine, so its design matters here. Sakana AI is a Tokyo lab founded in 2023 by David Ha and Llion Jones. Namazu is not trained from scratch. It applies post-training to existing open-weight foundation models. Reported base models include DeepSeek-V3.1-Terminus, Llama 3.1 405B, and gpt-oss-120B. Post-training means adapting an already-trained model with further tuning. It is cheaper and faster than pre-training a model from zero. Sakana AI uses it to fit models to Japanese language and culture. Sakana AI first announced the Namazu series on March 24, 2026. Sakana Translate applies that same adaptation work to the translation problem. Benchmark and Performance Sakana AI team evaluated translation quality with a standard setup. It used XCOMET-XL on the WMT 2024 General Translation task data. Here is what those two names means: WMT 2024 General Translation is a shared task from the Conference on Machine Translation. Systems translate test sets drawn from several domains across many language pairs. It is a common yardstick for machine translation research. XCOMET-XL is a neural evaluation metric from Unbabel, with roughly 3.5B parameters. It is a learned model that scores translation quality. It outputs a score and also flags specific error spans. Scores run from 0 to 1, where higher is better. By the reported results, Sakana Translate landed in a score band close behind the leading models. Sakana AI describes this as competitive quality for a translation engine. Sakana AI also ran a qualitative check on everyday Japanese texts. It reports strengths in honorifics, cultural concepts, place names, proper nouns, and everyday context. https://sakana.ai/translate-release/ Use Cases With Examples Sakana AI published two concrete outputs. Both show the tone-preservation goal in action. 1. Business email (Japanese → English). The source is a polite, indirect request. It uses set business phrases such as o-mitsumori haiken shimashita and katte na onegai desu ga. Source: お見積り拝見しました。勝手なお願いですが、もう少しご相談できますか?ご予算あれば社内で調整しますので、お聞かせください。 Sakana Translate: I saw your quote. This is a bit of a selfish request, but could we talk a bit more? If you have a budget in mind, I can work on it internally, so please let me know. Sakana AI notes the polite tone is preserved. A flatter translation would drop that register. 2. Internet slang (English → Japanese). The source uses casual shorthand from a group chat. Source: Iykyk, honestly. It’s an inside joke from the group chat. Sakana Translate: まあ、わかる人にはわかるよね。グループチャットの内輪ネタだから。 The output keeps the same casual temperature in conversational Japanese. Beyond these, practical scenarios follow naturally. A support agent can translate a long client thread in one paste. A developer can proofread an English release note before publishing. A learner can ask why a phrase carries a certain tone. Comparison: What Sakana Translate Targets The table below frames Sakana AI’s stated design focus. The left column describes common behavior in general-purpose tools. The right column reflects Sakana AI’s own claims, not a head-to-head benchmark. Dimension Typical general-purpose MT Sakana Translate’s stated focus Honorifics Grammar correct, tone often flattened Preserves polite and humble registers Cultural concepts Literal or generic renderings Adapted to Japanese context Slang and abbreviations Frequently mistranslated Matched to the original tone Workflow Separate translator and dictionary Translate, proofread, and ask in one screen Access Varies Free web app, single account, three languages A Look at the Evaluation Metric Sakana Translate has no public API yet. Sakana AI lists API access as a future, enterprise-focused plan. You can still reproduce the evaluation method it used. XCOMET-XL is open and runnable. The snippet below scores one translation with it. Copy CodeCopiedUse a different Browser # pip install “unbabel-comet>=2.2.0” # XCOMET-XL is gated on Hugging Face: accept its license, # then run `huggingface-cli login` before download_model(). from comet import download_model, load_from_checkpoint model_path = download_model(“Unbabel/XCOMET-XL”) # ~3.5B params model = load_from_checkpoint(model_path) data = [{ “src”: “お見積り拝見しました。”, “mt”: “I saw your quote.”,

Sakana AI Launches Sakana Translate, a Namazu-Powered Japanese–English–Chinese Translation Tool With Translate, Proofread, and Ask Modes Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

South Korea’s hottest new bachelors are chip workers

Baek, a 35-year-old manager at the South Korean semiconductor titan SK Hynix, was enrolled in Sunoo, a matchmaking company based in Seoul, a year ago. In a move typical of anxious South Korean parents, his mother signed him up, hoping to find a good wife for her son. Lately, says Baek (who asked to be referred to by his last name to protect his privacy), he and his coworkers are having better luck finding dates than they used to, perhaps because of the dazzling bonuses they just got. Flush with eye-popping profits from the AI chip boom, SK Hynix struck a landmark deal last year with its labor union to pay out 10% of operating profits to employees, which translates to an extra $476,000 per employee this year. A similar agreement and sizable lump sum followed for Samsung workers this May. With their newfound wealth, chip workers like Baek have become the most sought-after bachelors and bachelorettes in South Korea. “I have a coworker who’s perpetually going on blind dates, and he’s been getting so many recently,” says Baek. “For the past few months, I’ve been getting many blind dates too, perhaps because of the bonuses I got.” Lately, young South Koreans joke online that the best outfit to wear on a blind date is an SK Hynix uniform.  The AI chip boom is changing the social fabric of South Korea by minting a new elite of “silicon-collar” workers earning about 20 times as much as the average South Korean. Although it’s helping some chip workers to find relationships, it’s also fueling fears of a deepening wealth disparity—and a loud public debate about inequality. Love in the time of chips South Korea is the epicenter of the chip boom fueling the AI race. Samsung and SK Hynix supply the vast majority of the world’s high-bandwidth memory (HBM) chips, which power Nvidia’s AI accelerators—the GPUs used to train AI models. As AI companies spend hundreds of billions of dollars on building data centers around the world, demand for HBMs is rising beyond what suppliers can keep up with, driving their prices to unprecedented levels. Samsung and SK Hynix are raking in record profits as a result.  South Korea’s economy now orbits the two chip giants. In May, both companies topped $1 trillion in market value. And chip exports helped fuel a 1.7% surge in South Korea’s gross domestic product in the first quarter of 2026. South Korea’s main equity index, Kospi, has nearly tripled over the past year, becoming the best-performing market in the world. Swimming in cash, chip workers are going on shopping sprees in department stores near the “semicon belt” fabs—splurging on everything from lavish furniture and electronic appliances to jewelry and watches. They’re also snapping up homes near the commuter-shuttle routes that ferry workers to campus. And they’re shelling out for matchmakers. “Quite a lot of people ask me if I can introduce them to chip workers,” says Lee Sung-mi, a matchmaker at Sunoo, who has been playing Cupid for chip workers for years. “In fact, people who once rejected them are asking to be matched with them again, now that their salaries and bonuses have shot so far above what everyone else earns.” One woman who lives in Gangnam, a ritzy district in Seoul lined with luxury high-rises and designer boutiques, previously turned down a chip worker at SK Hynix because his fab was too far out in Icheon, a rural city about 50 miles southeast of Seoul that’s dotted with rice farms and manufacturing plants. But in May, she asked her matchmaker to set them up again. They’ve now been dating for a month.                                                                                                                                                                                                                                                                                                                                                                                                                              In South Korea, matchmaking companies evaluate their clients on a long list of criteria such as education, job, income, looks, and family background, including whether their aging parents have saved enough for retirement. In an economy where housing prices and child care costs are soaring, competition for jobs is fierce, and the social safety net is thin, a good job is the ultimate dating credential—all the more coveted at a time when many young South Koreans are forgoing marriage and children altogether, seeing family life as an unaffordable dream. Every client at Sunoo gets a spouse rating, determined by an algorithm that assigns scores for each criterion. Since their hefty bonuses were announced, the job ratings of Samsung employees have risen from 80 to 84, while those of SK Hynix employees climbed from 78 to 82. Scores above 90 are reserved for doctors and lawyers. Long prized as paragons of prestige and wealth, they’re now close to being overtaken by chip workers. A score of 99, the highest possible rating, is earmarked for heads of state.   Their new status is reshaping how chip workers themselves approach dating. “Chip workers from Samsung and SK Hynix are enrolling in our services because they feel more financially ready,” says Lee. “They’re also becoming pickier, as they feel like they’re now in a good position. The women want to meet men with higher incomes and better jobs, and the men want to meet younger and better-looking women with better jobs.”  An SK Hynix engineer in her 40s, who was once desperate to get married as soon as possible, started turning down men she would’ve dated before the chip boom. Lately, showered with more matches, she’s been sifting through her suitors more carefully. “She now has peace of mind and wants to take her time to meet someone better,” says Lee. A mixed blessing While chip workers enjoy the fruits of their labor, the bonus bonanza is stoking anxieties among other South Koreans. “When wealth disparity is no longer a mere difference of income but, rather, a difference in identity … it can fuel social conflict,” says Se-eun Jung, an economist at Inha University.  Earlier this month, the Bank of Korea warned that the chip boom will create a “K-shaped” economy, where a handful of workers race ahead while everyone else falls behind. The windfall, the

South Korea’s hottest new bachelors are chip workers Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The Download: South Korea’s hottest bachelors, and advancing eye transplants

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. South Korea’s hottest new bachelors are chip workers Baek, a 35-year-old manager at the South Korean semiconductor titan SK Hynix, was enrolled in a matchmaking company a year ago. In a move typical of anxious South Korean parents, his mother signed him up, hoping to find a good wife for her son. Lately, says Baek, he and his coworkers are having better luck finding dates—perhaps because of the dazzling bonuses they just got. Flush with eye-popping profits from the AI chip boom, SK Hynix agreed to pay 10% of operating profits to employees, which translates to an extra $476,000 per employee this year. Samsung workers received a similar deal this May. With their newfound wealth, chip workers like Baek have become the most sought-after bachelors and bachelorettes in South Korea.  Discover how AI chip profits are transforming South Korea’s dating market—and stoking anxieties. —Michelle Kim A device that revives eyeballs from dead donors could make eye transplants possible It’s not easy to transplant a whole human eye. The surgery is difficult, and eyes start to degenerate as soon as they’ve left the body. When surgeons attempted it a few years ago, the newly transplanted eye couldn’t see. But researchers believe they might have a solution: a device that maintains and revives freshly removed eyeballs using a technique called perfusion. Treated eyes don’t degrade as quickly and appear to retain the ability to transmit electrical signals—and potentially see.  The device could one day make whole-eye transplants a viable possibility. Here’s how it works. —Jessica Hamzelou The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 The UN’s chief has warned that AI is outpacing global rulesHe’s called for globally harmonised guardrails. (Reuters $)+ The UN also said AI could worsen global inequality. (Guardian) 2 An Israeli battlefield system identified 850,000 targets in Gaza and LebanonElbit Systems says it detected targets in real time. (Guardian)+ Congress wants to permanently integrate US and Israeli defence tech. (Intercept) +  How AI turned the Iran conflict into theater. (MIT Technology Review)  3 EU transparency rules have exposed Microsoft’s tax haven tacticsA new report shows how it shifts profits around to reduce tax bills. (NYT $)+ Other US companies will soon need to provide similar reports. (Engadget) 4 A spacecraft has launched an audacious mission to rescue a NASA telescopeLINK will try to tug the SWIFT observatory to a higher orbit. (New Scientist $)+ It will attempt to grab the telescope with three robotic arms. (BBC)+ The observatory studies gamma-ray bursts. (NBC News)+ We’re putting more stuff into space than ever. (MIT Technology Review) 5 Chinese tech giants are disabling humanlike AI due to new regulationsByteDance and Alibaba have shut down the features. (SCMP)+ Beijing is tightening its AI regulations. (Nikkei Asia) 6 Anthropic wants to develop its own drugsThe company says it will pursue treatments for “neglected” diseases. (Verge)+ It’s also got a new AI for science product. (MIT Technology Review) 7 India is testing an alternative to Silicon Valley’s AI playbookIt’s based on small, offline, multilingual, open-source AI. (Rest of World)+ India’s AI infrastructure is also attracting investors. (CNBC) 8 Big Tech has suddenly flipped on the AI jobs wipeout scenarioNegative public opinion has sparked a more optimistic public stance. (WSJ $)+ The AI jobs hysteria needs a reality check. (MIT Technology Review) 9 Midjourney has accused Hollywood studios of covertly using AIIt’s escalated its legal fight with Disney, Universal, and Warner. (Gizmodo) 10 A martian rock has lots of carbon on it, and it’s not clear whyScientists cannot yet tell whether biology played a role. (Ars Technica) Quote of the day “It’s just his AI and my AI going back and forth.”  —An anonymous employee explains why she’s struggling to develop a good working relationship with her boss, Fortune reports. One More Thing The AI relationship revolution is already here AI is everywhere, and it’s starting to alter our relationships with our spouses, kids, colleagues, friends—and even ourselves.  Although the technology remains unpredictable and sometimes baffling, individuals from all across the world and from all walks of life are finding it useful, supportive, and comforting too.  People are using large language models to seek validation, mediate marital arguments, and help navigate interactions with their community. They’re using it for parenting support, self-care, and even to fall in love. Explore how AI is changing our relationships. —Rhiannon Williams We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Radiohead’s seminal album “OK Computer” has been reimagined as a Nintendo 64 soundtrack.+ Graphic design history meets stamp collecting in this beautifully curated archive of postage stamp design.+ As Lionel Messi lights up another World Cup, his former coach breaks down his style of play in this fascinating analysis.+ Armchair engineers will enjoy the brilliant product teardowns of everyday items like clicky pens and lighters on Mechanical Pencil.

The Download: South Korea’s hottest bachelors, and advancing eye transplants Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Your family’s $300 stake in OpenAI

This story originally appeared in The Algorithm, our weekly newsletter on AI. To get stories like this in your inbox first, sign up here. OpenAI CEO Sam Altman’s oft-discussed promise that Americans will share in the wealth AI creates was in the news again last week. On Thursday, the Financial Times reported that Altman is in talks with President Trump about giving the US government a 5% stake in OpenAI. In some ways, Altman’s plan is old news. He wrote about a more radical version of this back in 2021, proposing that all companies above a certain valuation (not just AI companies) pay 2.5% of their market value each year into a fund that sends Americans annual disbursements. In April this year, OpenAI described a narrower proposal that closely resembles what Altman is reportedly discussing with Trump now. And the notion has broad political appeal: Senator Bernie Sanders has proposed giving Americans a 50% stake in top AI companies. What’s the logic here? For would-be recipients, it’s twofold. First, AI learns directly from human-generated work—books, movies, art—but AI companies generally never pay the authors of that work. A free equity stake could serve as a form of belated compensation. Second, the payout could mitigate the widespread anxiety that AI will cause a collapse of the labor market (even if economists disagree) by providing a safety net.  How large a safety net is up for debate. Details of OpenAI’s latest proposal are sparse, but let’s say the government were to distribute this equity stake directly to Americans. After its funding round in March the company was valued at $852 billion, making a 5% stake in OpenAI worth about $42.6 billion today (the company is reportedly delaying its IPO until it can reach a $1 trillion evaluation, a tall order given that it’s spending heavily on data centers and still has not turned a profit). Distributing that $42.6 billion equally among the roughly 133 million American households would give each about $320 in equity. But if it were to operate like other wealth funds, the government would not give equity directly to Americans but rather let the fund grow and then share a portion of the returns with everyone, perhaps delivering a bigger payout, if and when AI companies can ever start sustainably turning a profit. If this dividend does materialize, what’s in it for tech companies? Altman might hope the promise of payouts could help swing public opinion a bit more back toward AI companies. (A majority of Americans don’t trust companies to use AI responsibly and oppose construction of data centers in their area, and half are more concerned than excited about the increased creep of AI into their daily lives.) But the bigger prize for OpenAI might be that the Trump administration loves making tech deals—like its equity stake in Intel and its share of Nvidia’s sales to China, among others.  Staying on the administration’s good side is pretty essential for AI companies right now (just ask Anthropic). It could mean not having your models deemed a supply chain risk, or getting more help from the White House in stopping your rivals from China.  My main takeaway is that these plans currently function more as a story than a policy. Altman has been talking about some version of this idea for five years and reportedly pitched it to President Trump soon after he took office, yet there is still little indication that a concrete plan is taking shape. The more ambitious proposal from Sanders is even less likely to gain traction. But what these plans do reveal is just how up for debate the future of AI still is. Altman drew inspiration for his plan from the Alaska Permanent Fund, which was set up in the 1970s to give Alaskans a share in oil profits. The idea was based on two premises: that oil is a shared resource, and that eventually it will run out. Altman seems happy to concede the first claim about AI. But he’d balk at the second, having promised that AI will generate extraordinary wealth for decades to come. Whether Americans ever receive a check is beside the point; the proposal’s real purpose may be to convince them that the AI boom will be large enough to share.

Your family’s $300 stake in OpenAI Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Structured PDF-to-JSON: A Guide to Open-Source Extraction Models in 2026

Most enterprise data still sits inside PDFs, scans, and slide decks. Large language models and agents cannot use that data until it becomes structured JSON. Open-source document extraction has become the standard way to do that conversion on your own hardware. Two different problems hide under the phrase ‘PDF to JSON.’ The first is schema-driven extraction: you define fields, and a model fills them with values. The second is document parsing: a model reconstructs the page into structured JSON or Markdown. Most teams need one, sometimes both. Choosing the wrong category costs real time. Open weights matter here for cost and privacy. Proprietary APIs can cost thousands of dollars per million pages, and they require sending documents off-premise. Local models remove both constraints. Below are the models and toolkits worth evaluating, grouped by what they actually do. Two categories, one phrase Schema-driven extraction takes a document and a JSON schema, then returns values for your fields. Use it for invoices, forms, contracts, and receipts, where you know the fields in advance. Document parsing reconstructs the document itself. It detects layout, reading order, tables, formulas, and code, then exports JSON or Markdown. Use it to prepare clean corpora for retrieval-augmented generation (RAG) and agents. Category 1: Schema-driven structured extraction Datalab lift lift is a 9B vision model from Datalab, the team behind Marker and Surya. You pass a JSON schema, and lift returns JSON that matches it. Schema-constrained decoding guarantees the output is valid JSON. The model is built on Qwen 3.5 and runs locally through Hugging Face or remotely through a vLLM server. It handles multi-page documents in a single pass, including values that span pages. It ships a CLI, a Python API, and a Streamlit ‘Schema Studio’ for building and testing schemas. Copy CodeCopiedUse a different Browser pip install lift-pdf # Start the vLLM server, then extract to your schema lift_vllm lift_extract input.pdf ./output –schema schema.json Copy CodeCopiedUse a different Browser from lift import extract result = extract(“document.pdf”, “schema.json”) if result.extraction is not None: data = result.extraction # dict matching your schema On Datalab’s 225-document benchmark, lift reaches 90.2% field accuracy at 9.5s median latency. It leads NuExtract3 (81.5%) and Qwen3.5-9B (76.3%) on field accuracy. It trails Gemini Flash 3.5 (91.3%) and the hosted Datalab API (95.9%). Note that full-document accuracy stays low for all local models, with lift at 20.9%. Getting every field right in one document remains hard. The code is Apache-2.0. The weights use a modified OpenRAIL-M license, free for research, personal use, and startups under $5M in funding or revenue. Commercial self-hosting needs a license, and the weights cannot be used competitively with the Datalab API. NuMind NuExtract 3 NuExtract 3 is a 4B vision-language model from NuMind. It unifies two tasks in one model: structured extraction (document to JSON) and content extraction (OCR to Markdown). You provide an input and a JSON template describing the fields you need. The model is trained with reinforcement learning to add extraction-specific reasoning, which you can switch on or off per request. NuExtract 3 is multimodal, multilingual, and based on a Qwen backbone. It serves through vLLM with an OpenAI-compatible API, and a Python SDK is available via pip install numind. NuMind positions it as a reference open model for both structured and content extraction at its size. Check the model card for exact license terms before commercial use. Category 2: Document parsing to structured JSON and Markdown IBM Docling Docling started at IBM Research and is now hosted by the LF AI & Data Foundation. It parses PDF, DOCX, PPTX, XLSX, HTML, images, and more. Output formats include Markdown, HTML, lossless JSON, and DocTags. Its core is the DoclingDocument representation, which preserves layout, reading order, tables, and formulas as LaTeX. Docling runs locally for air-gapped environments. It integrates with LangChain, LlamaIndex, Crew AI, and Haystack, and ships an MCP server and a Docling Serve mode. The project carries a permissive MIT license. IBM also offers a managed version through watsonx. IBM Granite-Docling-258M Granite-Docling-258M is a compact 258M vision-language model from IBM. It performs one-shot document conversion inside Docling pipelines. Despite its size, it handles OCR, layout, tables, code, and equations, and outputs DocTags. On an A100 GPU, it averages roughly 0.35 seconds per page. The model builds on the Idefics3 architecture, with a SigLIP2 encoder and a Granite 165M language backbone. It is released under Apache 2.0. IBM states it is built for document conversion, not general image understanding. OpenDataLab MinerU MinerU, from OpenDataLab and Shanghai AI Laboratory, converts PDF, image, DOCX, PPTX, and XLSX inputs into Markdown and JSON. It pairs a processing pipeline with a vision-language model. The current model, MinerU2.5-Pro, targets high-resolution parsing of complex layouts, including cross-page tables and charts. MinerU recently changed its license. It moved from AGPL-3.0 to the “MinerU Open Source License,” a custom license based on Apache 2.0 with additional conditions. That change lowers friction for commercial deployment. Datalab Marker Marker is Datalab’s pipeline for converting documents into Markdown, JSON, chunks, and HTML. It supports PDF, image, PPTX, DOCX, XLSX, HTML, and EPUB. It formats tables, forms, equations, inline math, links, and code. An optional –use_llm flag adds a language model to improve tables and forms. On the third-party olmOCR-Bench suite, Marker scores around 76.1. Its code is GPL-3.0, and its model weights use a modified AI Pubs OpenRAIL-M license. That weight license is free for research, personal use, and startups under $2M in funding or revenue. Datalab’s managed platform now runs a newer OCR model, Chandra, which is Apache-2.0 and outputs HTML, Markdown, and JSON. Ai2 olmOCR 2 olmOCR 2 is a 7B OCR-specialized vision-language model from the Allen Institute for AI (Ai2). It converts PDFs into clean text and Markdown while preserving reading order. It handles tables, equations, and handwriting across complex multi-column layouts. The model is trained with reinforcement learning from verifiable rewards, using synthetic unit tests as the reward signal. olmOCR 2 scores 82.4 on its own olmOCR-Bench, among the higher published results on

Structured PDF-to-JSON: A Guide to Open-Source Extraction Models in 2026 Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

LlamaIndex ‘legal-kb’: Agentic Retrieval over Index v2 with retrieve, find, read, and grep Tools

LlamaIndex has published legal-kb, a public reference application on GitHub. It is described as a knowledge base for legal documents, powered by LlamaIndex Index v2 (the LlamaParse Platform). The project demonstrates a pattern the team calls a Retrieval Harness for agentic retrieval. The approach differs from single-shot retrieval. Instead of one embedding search per query, an agent is given filesystem-style tools. It can then crawl a large, evolving knowledge base to solve a task. The tools mirror operations engineers already know: semantic and keyword search, regex grep, file search, and read. What is legal-kb? legal-kb is a working TanStack Start web app, not a library. You sign in, create a project, upload files, and chat with an agent. Each project is mirrored as a managed LlamaCloud Index v2. Uploaded files are parsed and indexed automatically in the background. The chat agent then queries that index live during each turn. The Retrieval Harness, in plain terms The harness provides a persistent data pipeline over your documents. It connects to a data source, indexes it, and keeps it updated. On top of that pipeline, it exposes a set of tools to the agent. Those tools are deliberately close to filesystem operations. An agent can list files, read a file, grep inside a file, or run hybrid search. Because the tools are generic, you can plug the harness into your own agents. The four agent tools The agent in src/lib/agent.ts is given four tools. Each maps to an Index v2 retrieval API. The table below lists them as implemented. Tool Backing API Key parameters What it does retrieve beta.retrieval.retrieve query, top_k, score_threshold, rerank_top_n, file_name, file_version Runs hybrid semantic search; optional reranking; returns chunks plus citations findFiles beta.retrieval.find file_name, file_name_contains Searches files by exact name or substring; paginates automatically readFile beta.retrieval.read file_id, offset, max_length Reads raw file content, with offset and length windows grepFile beta.retrieval.grep file_id, pattern, context_chars, limit Matches a pattern in one file; returns character positions The system prompt enforces an order. The agent must call findFiles first to establish the document inventory. It then narrows with retrieve, and confirms exact wording with readFile or grepFile before citing. How it works under the hood Uploads follow a clear pipeline in src/lib/files.ts. Bytes are pushed to the project’s LlamaCloud source directory. A File and ProjectFile row are written to PostgreSQL via Prisma. An index sync is triggered but not awaited; the UI polls status until ready. Versioning is scoped to the (project, filename) pair. Re-uploading nda.pdf to the same project produces v1, v2, v3 side by side. The retrieval layer filters on the version metadata field. This gives version control over the knowledge base itself. The agent uses the ToolLoopAgent from Vercel AI SDK 6. You pick OpenAI or Anthropic per turn and bring your own keys. Reasoning is streamed: Claude models use extended thinking; OpenAI reasoning models use a medium reasoning effort. Here is a condensed but faithful view of the retrieve tool and the agent. Copy CodeCopiedUse a different Browser import { LlamaCloud } from ‘@llamaindex/llama-cloud’ import { tool, ToolLoopAgent } from ‘ai’ import { z } from ‘zod’ import { makeCitationId } from ‘./citations’ // One tool closure per index. Wraps Index v2 retrieval APIs. function createLlamaParseTools(apiKey: string, projectId: string, indexId: string) { const client = new LlamaCloud({ apiKey }) const retrieve = tool({ description: ‘Run a semantic retrieval query against an index.’, inputSchema: z.object({ query: z.string(), top_k: z.number().nullable(), score_threshold: z.number().nullable(), rerank_top_n: z.number().nullable(), // set to enable reranking file_name: z.string().nullable(), // metadata filter file_version: z.number().nullable(), }), execute: async ({ query, top_k, score_threshold, rerank_top_n, file_name }) => { const custom_filters = file_name ? { file_name: { operator: ‘eq’ as const, value: file_name } } : undefined const response = await client.beta.retrieval.retrieve({ index_id: indexId, project_id: projectId, query, top_k, score_threshold, rerank: rerank_top_n != null ? { enabled: true, top_n: rerank_top_n } : undefined, custom_filters, }) // Return a model-readable list plus citations that drive the UI chips. const citations = response.results.map((r) => ({ id: makeCitationId(), // e.g. “c7f2qa” fileName: r.metadata?.file_name, score: r.rerank_score ?? r.score ?? null, preview: r.content.slice(0, 500), })) const formatted = response.results .map((r, i) => `### Result #${i + 1}nn${r.content.slice(0, 600)}`) .join(‘nn—nn’) return { formatted, citations } }, }) // findFiles / readFile / grepFile follow the same shape, backed by // client.beta.retrieval.find / .read / .grep return { retrieve /* , findFiles, readFile, grepFile */ } } export function buildAgent(model, apiKey: string, projectId: string, indexId: string) { return new ToolLoopAgent({ model, tools: createLlamaParseTools(apiKey, projectId, indexId), instructions: ‘Always call findFiles first, ground every answer in the documents, ‘ + ‘and cite ids inline as `cite:<id>`.’, }) } Answers carry visual citations. Each retrieved chunk gets a short id, such as cite:c7f2qa. The agent references that id inline, and the UI renders a clickable citation chip. Clicking it opens the source page screenshot with bounding-box rectangles over the cited text. Naive RAG vs the agentic Retrieval Harness The harness is a different execution model from single-shot RAG. The comparison below focuses on behavior. Dimension Naive / single-shot RAG Agentic Retrieval Harness (Index v2) Retrieval flow One vector search per query Multi-step tool loop: find → retrieve → read/grep Search modes Vector similarity only Hybrid semantic search, keyword, and regex grep Context Fixed top-k chunks Agent reads full files or windows on demand Freshness Static index Persistent pipeline with sync and versioning Precision control Mostly hidden top_k, score_threshold, rerank_top_n exposed Citations Chunk ids Visual citations with page screenshots and bboxes Best fit Short question answering Long-horizon document tasks Use cases, with examples The design targets domains where agents navigate large document sets. Legal and fintech are the stated examples. Consider a contract question: ‘What notice is needed to terminate the MSA?’ The agent lists files, runs retrieve, then greps the exact clause. It answers with a citation to the specific page. Consider due diligence across a data room: An agent can findFiles by name, then readFile each candidate. It cross-checks clauses without a human opening every PDF. Consider a versioned policy base:

LlamaIndex ‘legal-kb’: Agentic Retrieval over Index v2 with retrieve, find, read, and grep Tools Leggi l'articolo »

We use cookies to improve your experience and performance on our website. You can learn more at Politica sulla privacy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
it_IT