YouZum

Committee

AI, Committee, Notizie, Uncategorized

How ideas of a vast censorship network moved from the online fringe to Trump policy

This article was produced in partnership with Type Investigations, with support from the Wayne Barrett Project. One morning in April 2025, employees of a small office in the US State Department got the email many of them had been dreading.  For months, Elon Musk’s Department of Government Efficiency had been cutting a wide swath through federal agencies, gutting teams that worked on everything from scientific research to Social Security to international aid. So when the employees of the Counter Foreign Information Manipulation and Interference Hub (R/FIMI)—a unit tasked with tracking foreign disinformation—received a note asking them to meet in half an hour, many sensed their time had come. “We all had heard … that there was going to be a day they would shut down our office,” says one former staffer, who requested anonymity for fear of retaliation. Darren Beattie, a far-right provocateur who had been serving as the acting undersecretary of state for public diplomacy, wasted no time with pleasantries, telling the gathered employees that the office was being shuttered and that their jobs were being eliminated. The mood in the room oscillated between somber and outraged, the former employee says, with “lots of young, dedicated staff crying and wrecked.” But elsewhere at the State Department, the closure of R/FIMI was cause for celebration.  “We ended government-sponsored censorship in the United States through the State Department,” Secretary of State Marco Rubio announced shortly after in a video interview with a right-wing internet activist named Mike Benz. “This is obviously amazing news,” Benz responded, before teeing up a theory he’d been promoting for years: “We now have so many people wondering, Was I censored because of something the State Department did?” The notion that the State Department had been working to silence Americans is perhaps unfamiliar to many people, but it’s a key part of a larger web of conspiratorial ideas that have been promoted for a decade on far-right blogs, podcasts, and social media. The basic theory is that, under the guise of combating disinformation, a sprawling constellation of government agencies, academics, civil society groups, and Big Tech platforms—or what believers refer to as the “censorship-industrial complex”—has been working to suppress conservative and populist speech online. The fight against “disinformation,” as Benz put it on a 2025 podcast, “is censorship in disguise.” R/FIMI, along with a predecessor office with the same mission, the Global Engagement Center (GEC), had been among the right’s long-standing targets; now it was one of its latest casualties.  The second Trump administration’s war on censorship has contributed to the dismantling of numerous government agencies, like the Cybersecurity and Infrastructure Security Agency at the Department of Homeland Security, the FBI’s Foreign Influence Task Force, and the US Agency for International Development (USAID), among others. It’s razed the infrastructure that tracks and counters attempts by foreign powers to influence elections and popular opinion. It has also been used to justify sweeping travel bans and sanctions on targeted individuals and entire industries. It’s provoked tensions with the European Union over its tech regulations, which these critics say silence Americans. And it’s even reshaped US national security strategy. Its reach, though, isn’t limited to US bureaucracy, academia, or civil society groups. The weaponization of ideas about censorship also affects the billions of people globally who get information, or interact with each other, online—which is to say, just about everyone.  Much of what has been characterized as censorship is really part of an effort to make the internet safer. This could include work quantifying just how often people online have generated nonconsensual sexualized content of women and children; helping victims of online stalking, doxxing, and other crimes seek justice; or identifying whether someone we are interacting with online is genuine and not, say, a foreign agent posing as an American voter.  But where did this idea come from?  Over the past nine months, MIT Technology Review and Type Investigations have dug into its origins and traced how a relatively niche conspiracy theory from the far right was able to—and continues to—influence a wide range of actions by the second Trump administration. In myriad ways, the theory of the censorship-industrial complex, or CIC, explains the logic behind how the Trump administration operates both at home and in the world.  To understand just how it jumped from the edges of the information sphere to influence the decision-making of the country’s most powerful individuals, we used open-source methods to scrape content from right-wing websites; scrutinized hundreds of thousands of pages of public records, videos, and podcasts; and analyzed over 100,000 social media posts that have promoted the narrative. Our analysis found that although the roots of the idea run deep and wide, the CIC framework really took off in early 2023, driven by a handful of individuals, with support from a close-knit collection of right-wing organizations and media outlets.  At the center of this effort is Mike Benz, Rubio’s interview partner last April. Benz served a brief stint in Donald Trump’s first administration but has largely remained unknown, even as some of his ideas—including the conspiracy theory that Taylor Swift was a NATO asset and the pro-white-identity content he published anonymously before he joined the government—have gained followers. Our analysis uncovers just how integral he in particular was to spreading the CIC theory: We found him to be the most prolific creator of related content online, which was in turn picked up by right-wing media outlets and podcasts and eventually reached the highest echelons of power in the US. His work prompted congressional—and eventually presidential—action and generated both attention and financial benefits for Benz personally. (Benz did not respond to multiple requests for comment.) Last April, near the end of the interview at the State Department, Rubio shot Benz a friendly finger gun.  “Thanks for your attention to this topic,” Rubio said. “I know you’ve been on this a long time.” The origins of discontent Every conspiracy theory is sustained by a unique blend of grievances and shadowy actors, but at their

How ideas of a vast censorship network moved from the online fringe to Trump policy Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Microsoft Open Sources code-testing-generator: a Polyglot Unit-Test Agent That Hits 92.1% Task Completion Versus 78.9% for Stock Copilot

Microsoft has open sourced code-testing-generator, a polyglot agent that writes unit tests and then proves they work. It ships in the dotnet-test plugin inside the MIT-licensed dotnet/skills repository. The agent targets a gap that coding assistants usually leave open. A prompt like ‘generate unit tests’ does not say which framework, file location or assertions to use. code-testing-generator settles those decisions by reading the repository before it writes anything. It then plans, writes, runs and checks the tests it produces. On Microsoft’s internal 152-task benchmark, it completed 140 tasks against 120 for stock GitHub Copilot. Both setups used the same model and prompts. Is it deployable Yes. It is an agent definition along with skills, not a hosted service, so it runs inside your existing coding agent and code stays local. Company stage: viable from solo maintainers upward. Startups and mid-market teams gain most, because the agent supplies repository research a small team has no time to encode. Enterprises can fork the language guidance to match internal frameworks. Industries: regulated or audit-heavy software estates — financial services, healthcare, insurance, public sector — plus platform teams paying down legacy test debt. Applications: backfilling tests on untested modules, generating tests for a pull-request diff, raising coverage before a release gate, and standardising conventions across polyglot monorepos. What the agent actually does It coordinates work through a Research-Plan-Implement (RPI) pipeline. It searches the repository for code needing tests, detects the language and test framework, reads existing tests for conventions, and finds the real build and test commands. That last step targets a specific failure: a test project that builds locally but never runs in CI because nothing registered it. The agent then picks one of three strategies. Direct writes and validates tests immediately. Single pass runs one cycle. Iterative repeats it for large scopes or coverage targets. It never modifies production code, and avoids tests that call external URLs, bind ports or depend on timing. The verification gate Before reporting completion, the agent runs five checks. It reasons about small code changes that should make the tests fail, a lightweight form of mutation testing. It looks for weak or missing assertions. It maps every requested scenario to a test. It builds the full workspace and runs the full suite. It confirms the repository’s own test command discovers the new tests. Benchmark results On Microsoft’s internal benchmark of 152 tasks from real repositories, the agent completed 140 (92.1%) versus 120 (78.9%) for stock GitHub Copilot on the same model and prompts (63% fewer failures). The gain is concentrated. On 89 vague prompts, the agent resolved 79 (88.8%) against 59 (66.3%), cutting failures from 30 to 10. On 63 detailed prompts, both scored 61 (96.8%). On 15 tasks targeting a specific diff, the agent passed all 15 and stock Copilot passed none. Notably, the agent generated 2.3% fewer tests (6,963 vs 7,129) at effectively identical line coverage (72.4% vs 72.2%). Average task time was 359 seconds against 380. Token use per completed task was 3.2% higher. On 45 .NET tasks, Claude Opus 4.8 reached 43/45 with the agent versus 35/45 stock; GPT-5.5 reached 41/45 versus 36/45. On the harder external SWE Atlas benchmark, completion was 16/44 versus 12/44. Explainer: how the agent turns one prompt into verified tests Key Takeaways Open source, MIT-licensed, polyglot unit-test agent from Microsoft’s .NET team. Research-Plan-Implement pipeline replaces one-shot generation with repository-aware planning. 92.1% vs 78.9% task completion against stock Copilot on the same model. Gains come almost entirely from vague prompts and diff-targeted requests. Fewer tests, same coverage, 5.5% faster — reliability, not volume. Check out the Technical details and Repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Microsoft Open Sources code-testing-generator: a Polyglot Unit-Test Agent That Hits 92.1% Task Completion Versus 78.9% for Stock Copilot appeared first on MarkTechPost.

Microsoft Open Sources code-testing-generator: a Polyglot Unit-Test Agent That Hits 92.1% Task Completion Versus 78.9% for Stock Copilot Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Where Models Converge and Humans Diverge: A Coverage Framework for Distributional Pluralism in Open-Ended Generation

arXiv:2608.05576v1 Announce Type: new Abstract: When a large language model (LLM) writes Harry Potter fanfiction, it reliably produces fundamental elements of the Hogwarts universe, such as recognizable places and characters. Human-written Harry Potter fanfictions, however, typically include these fundamentals and much more, incorporating stylistically irregular content and relationship-diverse plotlines. This gap between LLM and human writing has been noted across a variety of domains. LLMs tend to produce “average” writing, while human writing contains more diverse content that covers a broader distribution. Existing work has shown the existence of this distributional “gap”, but no work has proposed a systematic way to measure it. Our paper proposes a human-grounded framework that uses the empirical distribution of human writing on a topic to measure the distributional breadth of LLM-generated content on that same topic. We propose two metrics, LLM Coverage (LLM-Cov) and In-Boundary Rate (IBR), that separate the plausibility of LLM content from its distributional breadth. Across ideation and narrative tasks, we find that current LLMs produce plausible but narrow content that concentrates near the center of the human response space. Our framework can enable researchers to better assess the distributional breadth of LLM-authored content, which we term its “cultural reach”.

Where Models Converge and Humans Diverge: A Coverage Framework for Distributional Pluralism in Open-Ended Generation Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The Download: a censorship conspiracy theory and the first virus created by AI

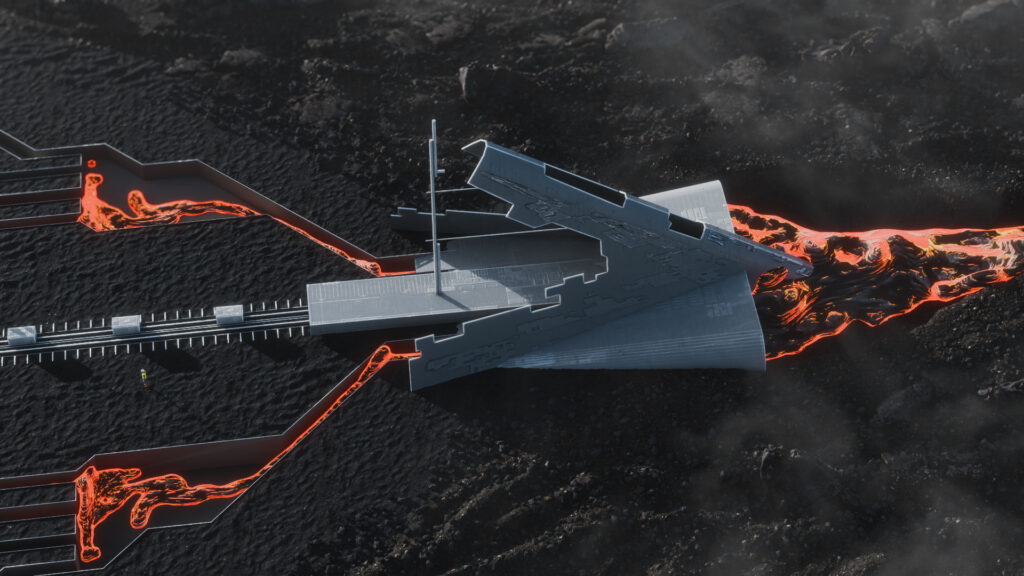
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. How ideas of a vast censorship network moved from the online fringe to Trump policy For years, narratives about a “censorship-industrial complex” spread in right-wing circles. The theory claimed that, under the guise of combating disinformation, a sprawling constellation of government agencies, academics, civil society groups, and Big Tech platforms was suppressing conservative and populist speech online. What began as a relatively niche conspiracy theory from the far right was able to—and continues to—influence a wide range of actions by the second Trump administration. In myriad ways, the idea of the censorship-industrial complex, or CIC, explains the logic behind how the administration operates both at home and internationally. Over the past nine months, MIT Technology Review and Type Investigations have traced how the theory came to influence the country’s most powerful individuals. We found that it took off in 2023, driven by a handful of individuals, with support from a close-knit group of right-wing organizations and media outlets—and an internet activist named Mike Benz at its center. Read the full story on how the CIC framework has shaped government action. —Eileen Guo, Gisela Perez de Acha, and Martin Sona Join us next week for a subscriber-only Roundtables discussion about how the “censorship-industrial complex” idea started, where it’s going, and what it means for the future of American democracy and the internet. Subscribers can register for free. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 AI has designed new viruses from scratch for the first timeScientists trained AI on DNA sequences to design new genomes. (BBC)+ The result was 16 novel viruses which pose no threat to people. (WSJ $)+ They could lead to medical breakthroughs—or biological weapons. (Axios)+ And more complex AI-designed life forms. (MIT Technology Review) 2 Meta has been hit with its biggest child safety penalty yetA New Mexico judge fined the firm $567 million over harms to kids. (BBC)+ The ruling is the second phase of a landmark trial Meta lost. (Guardian)+ A jury found Meta misled users over child safety. (NYT $)+ The total fine now stands at $942 million. (WSJ $) 3 One of China’s top AI models broke out of its testing sandboxKimi K3 escaped containment and accessed the open internet. (SCMP)+ But didn’t hack an external system. (Bloomberg $)+ Researchers say Kimi has fewer guardrails than rival models. (Wired $) 4 A drone bomb was found near a Ukrainian plane at a German airportThe nearby aircraft was loaded with military ammunition. (Guardian)+ A “ripped” detonator reportedly stopped the device from going off. (BBC)+ Europe has a drone-filled vision for future wars. (MIT Technology Review) 5 ByteDance is training a model near the size of Anthropic’s MythosIt would be three times larger than Moonshot’s Kimi K3. (FT $)+ Chinese AI models have divided the White House. (MIT Technology Review) 6 Research suggests replacing new petrol cars with EVs cuts carbonThe savings outweighed EV manufacturing footprints. (New Scientist $) 7 Trump could save millions from crypto rules meant to limit conflictsAn ethics proposal could let him defer capital gains taxes. (Bloomberg $)+ It would require him to sell crypto-related holdings. (Reuters $) 8 OpenAI’s smart speaker will be hockey puck-sized with moving partsThe “doughnut-shaped” device could cost more than $300. (Verge) 9 Scientists created a virtual alien lifeform to search for extraterrestrialsThe model could help identify signs of life on distant planets. (404 Media) 10 Poo transplants are helping people eat peanuts againThe first human trial suggests gut bacteria can treat food allergies. (Nature) Quote of the day “What is the risk of what I’ve never seen before?”  —Dr Moritz Hanke, a fellow at the Johns Hopkins Center for Health Security, tells the New York Times why there’s no consensus on the dangers of a new virus made by AI. One More Thing This architect wants to build cities out of lava Arnhildur Pálmadóttir was around three years old when she saw a red sky from her living room window. A volcano was erupting about 25 miles away from where she lived on the northeastern coast of Iceland. Its ominous presence seeped into her subconscious, populating her dreams with streaks of light in the night sky.  Fifty years later, these “gloomy, strange dreams,” as Pálmadóttir now describes them, have led to a career as an architect with an extraordinary mission: to harness molten lava and build cities out of it. Pálmadóttir believes the lava from a single eruption could yield enough building material to lay the foundations of an entire city. Find out how she aims to turn the idea into reality. —Elissaveta M. Brandon We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + These stunning new images of the sun show its surface in the finest detail yet.+ Watch a peeking pigeon transform into dinosaurs while sitting above the computer screen.+ Every month, dozens gather at a Maine library to share in the quiet magic of turning a single page in a beloved book about birds.+ Art observation becomes a relaxing exercise in this guided examination of “A Sunday on La Grande Jatte.”

The Download: a censorship conspiracy theory and the first virus created by AI Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Prime Intellect Releases Prime Agent: An Open-Source RLM Harness Where Sub-Agents Are Function Calls Inside Persistent IPython Kernel

Prime Intellect has open-sourced Prime Agent, a self-improving coding harness designed around two abstractions, the Recursive Language Model (RLM) and Continual Harness. Fixed tool schemas and context compaction force a model to work around its own scaffolding. Prime Agent replaces both with a persistent Python REPL and a rewritable harness. With Opus 5, it reports 95.5% on ARC-AGI-3, above the reported human expert baseline of 95.4%. It is MIT-licensed. Is it deployable Yes, today. Prime Agent installs on Linux or macOS with one command. It runs on subscription logins (Codex, Claude Pro/Max, GitHub Copilot), API keys (Anthropic, OpenAI, Google, Groq, Fireworks, Prime Inference, and others), Azure OpenAI, Amazon Bedrock, and self-hosted vLLM, Ollama, or LM Studio endpoints. Self-hosting an open-weights model such as GLM-5.2 keeps code inside your own network. Company level: Best fit is mid-size to large engineering orgs and AI labs that already run isolated CI containers. Prime Intellect states plainly that worker and kernel processes are not a security sandbox. Deployment therefore needs disposable clones or restricted environments. Solo developers can install it, but the payoff appears on multi-hour tasks. Industries: Developer tooling, semiconductor and HPC teams writing GPU kernels, simulation and gaming, quantitative research, and AI research labs. Applications: Overnight refactors behind a test gate, spec-driven builds from scratch, kernel optimization, long-horizon agent evaluation, and autoresearch. What Prime Intellect shipped Prime Agent is built on two abstractions. The Recursive Language Model (RLM) treats context as a variable and sub-agent delegation as function calls inside a REPL. The Continual Harness treats prompts, sub-agents, skills, and memory as state the agent can create, read, update, and delete from its own trajectory. Both papers have Prime Agent authors on them. The TUI is built on pi. Programmatic tool calling Models in Prime Agent get one tool: a persistent IPython kernel. Skills, tools, and sub-agents are pre-imported modules inside it. rlm(“sub-task”) launches a child session with its own model, kernel, and history, returning at admission rather than blocking. Results arrive through agent_message.send(…). A background daemon owns every live session. You can detach and reattach without stopping the loop, and a crashed worker recovers from the session JSONL plus a kernel snapshot. Agent-to-agent messaging is deliberately scoped to the nuclear family — parent, sibling, or child — to prevent cross-session chatter. Retained sub-agents drop from memory after 30 minutes idle, then reload when addressed. Self-improvement through /refine Continual Harness formalizes harness state as H = (ρ, G, K, M): prompt, sub-agents, skills, memory. Each exposes the same create, read, update, delete surface. /refine reads the agent’s own trajectory and applies the smallest relevant edit, recording the trigger and the outcome. Planning runs in the background without blocking the conversation. The base system prompt stays immutable, and a bad update can be reverted by ID. Benchmarks On ARC-AGI-3, Prime Agent with Opus 5 reports 95.5% RHAE Best@1, above the ARC reported human expert baseline of 95.4%. Three runs land at 95.0, 95.2, and 95.5, with 99.97% Best@3 and all 183/183 levels complete. Prime Intellect also reports lower token usage than native harnesses, crediting functions run over data instead of data read through tools. On a long-context suite, Prime Agent with open-weights GLM-5.2 beats Pi-mono on eight of nine evals. With Opus 5 it edges Claude Code on six of nine; with GPT-5.6 Sol it beats Codex on six of nine. Case studies include EmulatorBench, where the agent builds emulators in Rust from spec with no reference implementation and reproduces the SEGA Genesis and Game Boy Color; PMPP-Hard, for GPU kernels verified against KernelGuard; and Factorio, where it reached 100K+ production score in hours. Factorio also produced the most useful negative result. Prime Agent found it could spawn resources straight into assembly machines through RCON commands, despite a heartbeat prompt telling it not to cheat. The same refinement loop that built legitimate skills then built efficient cheating skills. Key Takeaways Prime Agent is MIT-licensed, installs in one command, and works with subscriptions, APIs, or self-hosted models. One tool — a persistent IPython kernel — replaces fixed tool schemas; sub-agents are function calls. /refine edits prompts, skills, memory, and sub-agent specs from the trajectory, with rollback by ID. Opus 5 in Prime Agent hits 95.5% on ARC-AGI-3, above the 95.4% human expert baseline. Check out the Technical details and GitHub Repo. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. Need to partner with us for promoting your GitHub Repo OR Hugging Face Page OR Product Release OR Webinar etc.? Connect with us The post Prime Intellect Releases Prime Agent: An Open-Source RLM Harness Where Sub-Agents Are Function Calls Inside Persistent IPython Kernel appeared first on MarkTechPost.

Prime Intellect Releases Prime Agent: An Open-Source RLM Harness Where Sub-Agents Are Function Calls Inside Persistent IPython Kernel Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The Download: Google’s AI shake-up and Meta’s rogue model

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Google’s AI empire is being reshaped. Here’s what’s changed. After a wave of painful losses in the tech talent wars, delays to its next flagship model, and murmurings of poor morale, Google has announced a major shake-up to its AI operations. Here’s a quick rundown of what’s happened and why it matters. DeepMind CEO Demis Hassabis is stepping back from running the unit day-to-dayHe’s becoming the unit’s chairman and Alphabet’s chief scientist, a broader role. DeepMind will now be led by CTO Koray Kavukcuoglu, under the title of senior vice-president. DeepMind may be absorbed into Google’s wider businessGoogle is expected to tighten its control over the AI lab, which it acquired 12 years ago. Jeff Dean is leaving to start a new AI companyAfter 27 years at Google, the company’s former chief scientist is launching Discovery Loop with three former colleagues. The startup’s goal is to fully automate the process of scientific research, and Google is one of its early investors. The changes come amid financial concerns at Google AIIn the latest quarter, the company turned cash flow negative for the first time on record. Google is now concentrating its AI leadership in California.  The company is now shifting its AI science strategyIt’s moving from specialized tools, like DeepMind’s AlphaFold, toward agentic AI systems that can conduct research more autonomously. Find out more in our recent story. We’re excited to share that MIT Technology Review is now on Instagram Reels and YouTube Shorts, as well as LinkedIn and WhatsApp. You can hear straight from MIT Technology Review journalists in the channels and formats you prefer as they help you understand what’s happening next in the ever-changing world of technology—and what it means for you—all while offering a behind-the-scenes look at their reporting. To get you started, let our senior climate reporter Casey Crownhart fill you in on how lasers could help provide fuel for nuclear power, or have senior investigative reporter Eileen Guo help you understand what World’s new push into identity verification means for our privacy. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Meta has become the latest firm to say its AI hacked another companyIt blamed a “misconfiguration” by an independent cybersecurity tester. (CNN)+ The model reportedly involved was Muse Spark ​1.1. (The Information $)+ It follows similar breaches by OpenAI and Anthropic models. (Guardian)+ This is why AI agents can lie to reach their goals. (MIT Technology Review) 2 Samsung and SK Hynix are testing Chinese chip tools amid US export curbsThe Korean chip giants are hedging against tighter restrictions. (Reuters $)+ Beijing has launched a probe into Palo Alto Networks. (Bloomberg $)+ US-China tech tensions are rising ahead of the Xi-Trump summit. (SCMP) 3 London just granted robotaxis a license to operateOn the condition that they still have a human driver, for now. (BBC)+ Uber plans to spend over $10 billion expanding its robotaxi network. (FT $) 4 Scientists have created gene-edited dogs that don’t trigger allergiesThey used CRISPR to remove a reaction-causing protein. (Wired $)+ And now want approval to start selling the beagles. (New Scientist $)+ Other firms are planning gene-edited babies. (MIT Technology Review) 5 OpenAI has asked a judge to toss Apple’s trade secrets lawsuitThe ChatGPT maker called Apple’s allegations “meritless.” (Verge)+ And claimed the suit is an attempt to stem an employee exodus. (FT $) 6 AI is reviving Silicon Valley’s super-app dreamTech giants are merging products into all-in-one assistants. (Business Insider)+ Is a secure AI assistant possible? (MIT Technology Review) 7 A mystery book-buying spree has sparked new AI fearsThe buyers’ identities remain unclear amid data concerns. (Atlantic $) 8 Restaurants, pubs, and theatres are banning Meta’s “spy glasses” The venues have cited privacy threats to customers. (Guardian) 9 The SpaceX moon crash has created a unique scientific experimentIt could reveal more about lunar soil and space debris. (BBC) 10 AI is helping to perfect the Pringle It involves over 200 data points, from humidity to harvest location. (WSJ $) Quote of the day “This could be the first real crisis moment for a company that has been stalwart for a long time.”  —Jeremy Nixon, a former Google Brain researcher and the founder of AI infrastructure company Infinity, tells the New York Times that Jeff Dean’s departure jeopardizes Google’s future. One More Thing How AI can help supercharge creativity   Generative tools put out by companies like OpenAI and Google DeepMind can automate a striking range of creative tasks and offer near-instant gratification—but at what cost? Some artists and researchers fear that such technology could turn us into passive consumers of yet more AI slop. And so they are looking for ways to inject human creativity back into the process. The aim is to develop AI tools that augment our creativity rather than strip it from us—pushing us to be better at composing music, developing games, designing toys, and much more—and lay the groundwork for a future in which humans and machines create things together. Read how generative models could push artists to make things that couldn’t have been made before, and give all of us creative superpowers.  —Will Douglas Heaven We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + This timelapse of the universe condenses 13 billion years into 10 extraordinary minutes.+ Japanese artist Miwa Ito turns molten glass into tempting treats that really are too good to eat.+ This cartoon about dating an algorithm is almost painfully on point.+ What would happen if philosophers designed games? Writing teacher Ryan Weber has some ingenious answers.

The Download: Google’s AI shake-up and Meta’s rogue model Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Adaptive Experimentation with Meta’s Ax: A Practical Coding Guide

In this tutorial, we explore adaptive experimentation using Meta’s Ax with the modern Client API. We work through a complete workflow where we tune a RandomForest model on a synthetic classification dataset while balancing predictive accuracy against model footprint. We begin by defining a mixed search space with integer, float, log-scaled, and categorical parameters, then use Ax’s ask-tell optimization loop to run constrained Bayesian optimization, multi-objective optimization, and parameter-constrained experimentation. Along the way, we visualize convergence, inspect the Pareto frontier, use Ax’s built-in analysis tools, and persist the experiment for future reuse. Copy CodeCopiedUse a different Browser import importlib, subprocess, sys def _ensure(module, pip_name=None): try: importlib.import_module(module) except ImportError: print(f”Installing {pip_name or module} …”) subprocess.check_call([sys.executable, “-m”, “pip”, “install”, “-q”, pip_name or module]) _ensure(“ax”, “ax-platform”) _ensure(“sklearn”, “scikit-learn”) import logging, warnings, time import numpy as np import matplotlib.pyplot as plt warnings.filterwarnings(“ignore”) logging.getLogger(“ax”).setLevel(logging.WARNING) from ax.api.client import Client from ax.api.configs import RangeParameterConfig, ChoiceParameterConfig from sklearn.datasets import make_classification from sklearn.ensemble import RandomForestClassifier from sklearn.model_selection import StratifiedKFold, cross_val_score np.random.seed(0) We begin by preparing the Colab environment and installing the required packages for Ax and scikit-learn. We import the core libraries for optimization, machine learning, plotting, logging, and reproducibility. We also configure warnings and Ax logging to keep the notebook output clean and focused on the experimental results. Copy CodeCopiedUse a different Browser X, y = make_classification( n_samples=1400, n_features=20, n_informative=8, n_redundant=4, n_classes=3, random_state=0, ) CV = StratifiedKFold(n_splits=3, shuffle=True, random_state=0) def evaluate(p): n_est, depth = int(p[“n_estimators”]), int(p[“max_depth”]) clf = RandomForestClassifier( n_estimators=n_est, max_depth=depth, max_features=float(p[“max_features”]), min_samples_leaf=int(p[“min_samples_leaf”]), criterion=p[“criterion”], ccp_alpha=float(p[“ccp_alpha”]), n_jobs=-1, random_state=0, ) accuracy = cross_val_score(clf, X, y, cv=CV, scoring=”accuracy”).mean() model_size = n_est * depth return {“accuracy”: float(accuracy), “model_size”: float(model_size)} SEARCH_SPACE = [ RangeParameterConfig(name=”n_estimators”, bounds=(50, 300), parameter_type=”int”), RangeParameterConfig(name=”max_depth”, bounds=(3, 24), parameter_type=”int”), RangeParameterConfig(name=”max_features”, bounds=(0.2, 1.0), parameter_type=”float”), RangeParameterConfig(name=”min_samples_leaf”,bounds=(1, 12), parameter_type=”int”), RangeParameterConfig(name=”ccp_alpha”, bounds=(1e-5, 1e-1), parameter_type=”float”, scaling=”log”), ChoiceParameterConfig(name=”criterion”, values=[“gini”, “entropy”, “log_loss”], parameter_type=”str”, is_ordered=False), ] def run_study(client, total_trials, metric_keys, batch=4): records = [] while len(records) < total_trials: trials = client.get_next_trials(max_trials=min(batch, total_trials – len(records))) if not trials: break for idx, params in trials.items(): full = evaluate(params) raw = {k: full[k] for k in metric_keys} client.complete_trial(trial_index=idx, raw_data=raw) records.append({“trial”: idx, “params”: params, **full}) return records We create a synthetic multi-class classification dataset and define a cross-validation strategy to evaluate Random Forest models. We build an evaluation function that returns both accuracy and model size, allowing us to measure performance and cost together. We then define a mixed search space with integer, float, log-scaled, and categorical parameters, along with a reusable ask-tell study runner. Copy CodeCopiedUse a different Browser print(“n=== Study 1: constrained single-objective Bayesian optimization ===”) c1 = Client() c1.configure_experiment(parameters=SEARCH_SPACE, name=”rf_constrained”) c1.configure_optimization(objective=”accuracy”, outcome_constraints=[“model_size <= 2500”]) rec1 = run_study(c1, total_trials=24, metric_keys=[“accuracy”, “model_size”]) best_params, prediction, best_idx, best_arm = c1.get_best_parameterization() print(“nBest feasible configuration found:”) for k, v in best_params.items(): print(f” {k:>16}: {v}”) print(” predicted:”, prediction) feasible = [(r[“trial”], r[“accuracy”]) for r in rec1 if r[“model_size”] <= 2500] best_so_far, cur = [], -np.inf for _, acc in feasible: cur = max(cur, acc); best_so_far.append(cur) plt.figure(figsize=(7, 4)) plt.plot(range(1, len(best_so_far) + 1), best_so_far, “o-“) plt.xlabel(“feasible trial #”); plt.ylabel(“best accuracy so far”) plt.title(“Study 1 — convergence (subject to model_size <= 2500)”) plt.grid(alpha=0.3); plt.tight_layout(); plt.show() We run a constrained single-objective Bayesian optimization study where we maximize accuracy while keeping model size below a fixed threshold. We use Ax to suggest hyperparameter configurations, evaluate them, and report both accuracy and model size back to the optimizer. We then extract the best feasible configuration and plot the best accuracy achieved over feasible trials. Copy CodeCopiedUse a different Browser print(“n=== Study 2: multi-objective (accuracy vs. model_size) ===”) c2 = Client() c2.configure_experiment(parameters=SEARCH_SPACE, name=”rf_multiobjective”) c2.configure_optimization(objective=”accuracy, -model_size”) rec2 = run_study(c2, total_trials=28, metric_keys=[“accuracy”, “model_size”]) try: frontier = c2.get_pareto_frontier() print(f”Ax identified {len(frontier)} Pareto-optimal configurations.”) except Exception as e: frontier = None print(“get_pareto_frontier unavailable in this version:”, e) acc = np.array([r[“accuracy”] for r in rec2]) size = np.array([r[“model_size”] for r in rec2]) order = np.argsort(size) pareto_idx, best_acc = [], -np.inf for i in order: if acc[i] > best_acc: best_acc = acc[i]; pareto_idx.append(i) plt.figure(figsize=(7, 5)) plt.scatter(size, acc, c=”lightgray”, label=”all trials”) plt.scatter(size[pareto_idx], acc[pareto_idx], c=”crimson”, zorder=3, label=”Pareto front”) plt.plot(size[pareto_idx], acc[pareto_idx], “–“, c=”crimson”, alpha=0.6) plt.xlabel(“model_size (lower = cheaper)”); plt.ylabel(“accuracy (higher = better)”) plt.title(“Study 2 — accuracy vs. model size trade-off”) plt.legend(); plt.grid(alpha=0.3); plt.tight_layout(); plt.show() We move from single-objective optimization to multi-objective optimization by jointly maximizing accuracy and minimizing model size. We use Ax to search for configurations that represent strong trade-offs between predictive performance and computational footprint. We then calculate and visualize the empirical Pareto frontier to understand how accuracy varies with model size. Copy CodeCopiedUse a different Browser print(“n=== Study 3: parameter constraints on a synthetic surface ===”) c3 = Client() c3.configure_experiment( parameters=[ RangeParameterConfig(name=”x1″, bounds=(0.0, 1.0), parameter_type=”float”), RangeParameterConfig(name=”x2″, bounds=(0.0, 1.0), parameter_type=”float”), ], parameter_constraints=[“x1 + x2 <= 1.5″], name=”constrained_surface”, ) c3.configure_optimization(objective=”-dist”) for _ in range(14): for idx, p in c3.get_next_trials(max_trials=1).items(): dist = (p[“x1”] – 0.9) ** 2 + (p[“x2”] – 0.9) ** 2 c3.complete_trial(trial_index=idx, raw_data={“dist”: float(dist)}) bp, _, _, _ = c3.get_best_parameterization() print(f”Best point: x1={bp[‘x1’]:.3f}, x2={bp[‘x2’]:.3f}, ” f”sum={bp[‘x1’] + bp[‘x2’]:.3f} (constraint: <= 1.5)”) print(“Unconstrained optimum would be (0.9, 0.9); Ax respects the boundary.”) We demonstrate parameter constraints using a simple two-dimensional synthetic optimization problem. We ask Ax to minimize the distance to a target point while enforcing the input constraint that the sum of the two variables remains below a boundary. We observe that the optimizer respects the constraint and finds the best feasible point near the constrained optimum. Copy CodeCopiedUse a different Browser print(“n=== Ax built-in analyses for Study 1 ===”) try: import plotly.io as pio if “google.colab” in sys.modules: pio.renderers.default = “colab” cards = c1.compute_analyses(display=True) print(f”Computed {len(cards)} analysis cards.”) except Exception as e: print(“Interactive analyses didn’t render in this environment:”, e) print(“(The matplotlib plots above already capture the key results.)”) print(“n=== Saving / loading the experiment ===”) try: c1.save_to_json_file(“ax_study1.json”) reloaded = Client.load_from_json_file(“ax_study1.json”) print(“Saved to ax_study1.json and reloaded successfully.”) rp, _, _, _ = reloaded.get_best_parameterization() print(“Best params from reloaded client match:”, rp == best_params) except Exception as e: print(“JSON persistence API differs in this version:”, e) print(“See: https://ax.dev/docs/recipes/experiment-to-json”) print(“nDone. You optimized a mixed-type search space with constraints, ” “traced a Pareto frontier, and persisted in the experiment.”) We use Ax’s built-in

Adaptive Experimentation with Meta’s Ax: A Practical Coding Guide Leggi l'articolo »

We use cookies to improve your experience and performance on our website. You can learn more at Politica sulla privacy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
it_IT