YouZum

Committee

AI, Committee, Notizie, Uncategorized

The Download: the next big thing in LLMs and how AI academic research is shifting

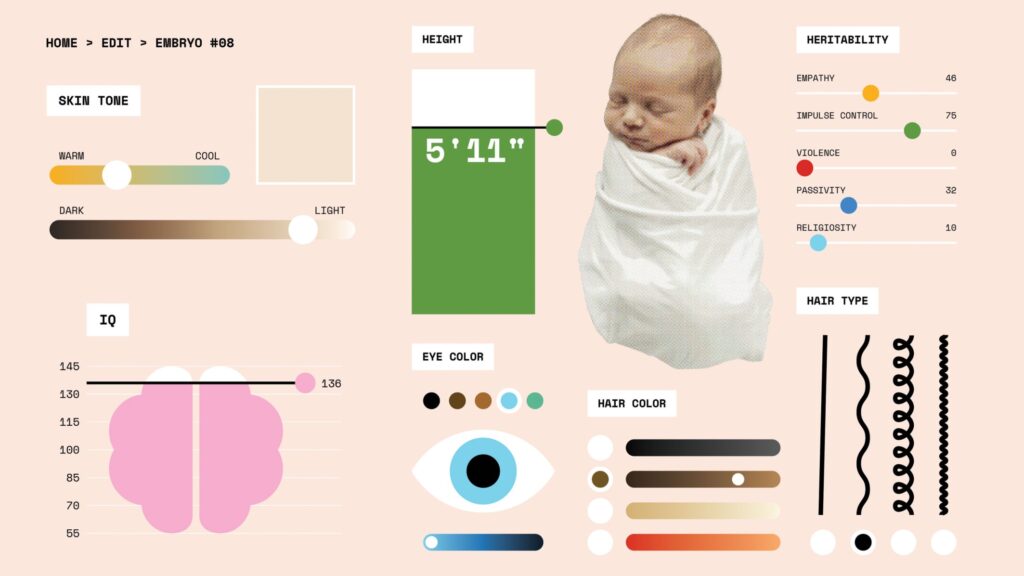
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. These startups are chasing the next big thing in LLMs Nine years after Google researchers introduced the transformer, this family of neural networks has become the engine inside every major large language model. But transformers are starting to show their age.  As LLMs get bigger and better, transformers have become a bottleneck. Their dense attention mechanism becomes increasingly expensive as the amount of text grows, and they’re not great at keeping track of a lot of information at once. Here are four new ideas for how to solve the transformer problem—innovations that could change LLMs for good, making them faster, far more efficient, and (maybe) even smarter. —Will Douglas Heaven This story is from MIT Technology Review’s What’s Next series, which looks across industries, trends, and technologies to give you a first look at the future. You can read the rest of them here. AI professors are negotiating the new realities of academic research —Grace Huckins Last week, I headed to a hotel in Mountain View, California, to join some of the most accomplished, and some of the most promising, AI researchers in the world. I was hosting roundtable interviews and speaking at a media training for a convening of the Schmidt Sciences AI2050 program, an initiative funded by Eric and Wendy Schmidt that supports academics whose work involves AI.  The fellows list is a who’s who of AI luminaries, and though not all of them made it out to the Bay, every time I turned a corner I saw a scientist whom I’d interviewed previously or whose research I admired. It’s a weird time for university AI researchers, who make up most of the AI2050 group. Read Grace’s story to find out why, and what could be coming next. This story is from The Algorithm, our weekly AI newsletter. Sign up to receive it in your inbox every Monday. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Nvidia has secured $500 billion from Wall Street for AI infrastructureIt’s struck deals with BlackRock, Goldman Sachs, and four others. (BBC)+ Showing the pull of AI compute for ⁠institutional investors. (Reuters $)+ And that AI infrastructure is becoming a new asset class. (CNBC) 2 Mark Zuckerberg’s new manifesto says open-source AI can save the USIt presents a utopian vision of personalized “superintelligence.” (Guardian)+ And arrived the same day as Meta’s new, open-source model. (NYT $)+ Zuckerberg said he plans to launch more of these models. (WSJ $)+ And pit Meta against Chinese open-weight developers. (SCMP) 3 Bernie Sanders has called on Silicon Valley to “pause AI development”He noted that AI giants have pledged to do this if necessary for safety.+ And warned that lawmakers will step in if no action is taken. (Guardian)+ House Democrats are already pressing AI leaders over rogue models. (WP $)+ A populist backlash is building against AI. (MIT Technology Review) 4 A US court will allow thousands of social media lawsuits to proceedThe suits target addictive mechanisms used by Meta, TikTok, Google, and Snapchat. (Axios)+ They claim the platforms are designed to hook young users. (Reuters $)+ Can we repair the internet? (MIT Technology Review) 5 Unitree’s IPO is more than 8,000 times oversubscribed by retailThe Chinese humanoid firm raised $900 million ahead of its listing. (Reuters $)+ Its pricing for the Shanghai IPO values the company at $9 billion. (FT $) 6 Flock’s car-tracking cameras are facing a bipartisan backlashThe surveillance network has spread rapidly across the US. (NYT $)+ Flock also plans to chase shoplifters with drones. (MIT Technology Review) 7 China is breaking up AI relationshipsBeijing has introduced new rules for emotionally interactive AI. (Rest of World)+ It’s surprisingly easy to fall for a chatbot. (MIT Technology Review) 8 An AI tool claims to pick the best 1% of scientific papersBut researchers doubt that AI can reliably judge scientific quality. (Nature) 9 The AI slop backlash is workingIt’s pushing platforms to restrict AI-generated content. (Wired $) 10 An 82-year-old rejected $26 million to turn her farm into a data centerShe criticised the environmental impacts of data centers. (Fortune) Quote of the day “It is not too late to avoid disaster. Stop building machines that humans cannot control.”  —Senator Bernie Sanders urges Sam Altman, Dario Amodei, and Mark Zuckerberg to pause all AI development in a letter. One More Thing The race to make the perfect baby is creating an ethical mess A new field of science is using genetic sequencing to predict what kind of person an embryo might become. Some parents turn to these tests to avoid devastating genetic disorders, while a much smaller group are willing to pay tens of thousands of dollars to optimize for intelligence, appearance, and personality. Customers, however, may not be getting what they’re paying for. Genetics experts have highlighted the potential deficiencies of this testing for years, while its underlying assumptions have made these companies a political lightning rod. As this technology edges toward the mainstream, scientists and ethicists are racing to confront the implications—for our social contract, for future generations, and for our very understanding of what it means to be human. Read the full story. —Julia Black We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + An eagle-eyed border collie is taking the game of fetch into new waters.+ musicForprogramming has made a valiant attempt to produce the perfect tunes for sustained concentration.+ When kids design playgrounds, they create a cheerful mix of giant chess, pink basketball courts—and lava.+ This power metal version of the “Back to the Future” music is an epic reinvention of the film’s classic theme. 

The Download: the next big thing in LLMs and how AI academic research is shifting Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

How the “censorship-industrial complex” is changing the Internet and US policy

I first heard the term “censorship-industrial complex” on April 15, 2025.  That’s when I got the tip that a small office in the U.S. State Department, which focused on monitoring and countering foreign disinformation from the likes of Russia, Iran, and China, was facing imminent shutdown—the next day.  And the reason? R/FIMI, as the office was called, was accused of serving as the State Department’s central hub in the so-called censorship-industrial complex—a sprawling constellation of government agencies, academics, civil society groups, and Big Tech platforms allegedly conspiring to suppress conservative and populist speech online under the guise of combating disinformation.  I broke the story around 10:30AM on April 16, (and broke more in the weeks that followed) but for me, it was just the start of a deep reporting rabbit-hole into an idea that had moved from the fringes of the right-wing Internet into the mainstream, championed and spread by a network of well-funded conservative media platforms and non-profits, and finally as a sort of prevailing logic behind much of the second Trump administration’s domestic and foreign policy.  But this isn’t just a policy story. The weaponization of ideas about censorship also affects the billions of people globally who get information, or interact with each other, online—which is to say, all of us.  For more on what the narrative means for the Internet, read my story here.

How the “censorship-industrial complex” is changing the Internet and US policy Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Building and Validating a Quantitative Trading Strategy with OctoBot, Walk-Forward Backtesting, Parameter Optimization, and Interactive Analysis

In this tutorial, we build a complete quantitative backtesting workflow with OctoBot and OctoBot-Script while keeping the environment isolated from Colab’s preinstalled dependencies. We configure a rule-based trading strategy that combines RSI-based oversold signals, EMA trend confirmation, and ATR-driven adaptive stop-loss and take-profit levels, and we execute it through OctoBot’s native market-order and backtesting APIs. We also retrieve historical OHLCV data through OctoBot’s data layer with automatic exchange fallback, perform a multi-parameter grid search over an in-sample period, and select the strongest configuration based on its excess return relative to buy-and-hold. We then validate the selected parameters on a completely separate out-of-sample period to assess generalization and identify potential overfitting. Finally, we extract OctoBot’s backtest report data and use Pandas and Plotly to analyze parameter sensitivity, portfolio performance, price action, indicators, and execution results in an interactive Colab environment. Copy CodeCopiedUse a different Browser SYMBOL = “BTC/USDT” TIME_FRAME = “1d” EXCHANGES = [“binance”, “kucoin”, “okx”, “bybit”, “mexc”, “kraken”] IN_SAMPLE = (“2019-01-01”, “2023-01-01”) OUT_OF_SAMPLE = (“2023-01-01”, “2025-06-01”) GRID = { “rsi_period”: [7, 14, 21], “rsi_threshold”: [25, 30, 35], “tp_atr_mult”: [3.0, 5.0], } FIXED = { “ema_fast”: 50, “ema_slow”: 200, “atr_period”: 14, “sl_atr_mult”: 2.0, “position_size”: “20%”, “min_offset_pct”: 1.0, “max_offset_pct”: 40.0, } VENV_DIR = “/content/octobot_env” WORK_DIR = “/content/octobot_lab” OCTOBOT_V = “2.1.1” PY_VERSION = “3.12” import json, os, subprocess, sys, textwrap, time, itertools, shutil os.makedirs(WORK_DIR, exist_ok=True) PY = os.path.join(VENV_DIR, “bin”, “python”) MARKER = os.path.join(VENV_DIR, “.octobot_ready”) def sh(cmd, **kw): “””Run a command, streaming its output live into the Colab cell.””” print(f”$ {‘ ‘.join(cmd)}”) p = subprocess.Popen(cmd, stdout=subprocess.PIPE, stderr=subprocess.STDOUT, text=True, bufsize=1, **kw) for line in p.stdout: print(” ” + line.rstrip()) p.wait() if p.returncode != 0: raise RuntimeError(f”command failed ({p.returncode}): {‘ ‘.join(cmd)}”) if not os.path.exists(MARKER): print(“=” * 90, “n BUILDING OCTOBOT ENVIRONMENT (one-off, ~2 min)n”, “=” * 90) subprocess.run([sys.executable, “-m”, “pip”, “install”, “-q”, “uv”], check=True) UV = [sys.executable, “-m”, “uv”] sh(UV + [“venv”, “–python”, PY_VERSION, VENV_DIR]) sh(UV + [“pip”, “install”, “–python”, PY, “-q”, f”OctoBot=={OCTOBOT_V}”, “wheel”, “setuptools”, “appdirs==1.4.4”]) sh(UV + [“pip”, “install”, “–python”, PY, “-q”, “–no-build-isolation”, “octobot-script”]) sh([PY, “-m”, “octobot_script.cli”, “install_tentacles”, “–quite”]) sh([PY, “-c”, textwrap.dedent(“”” import os, shutil, octobot_script.resources as r base = r.get_report_resource_path(“”) src, dst_dir = os.path.join(base, “index.html”), os.path.join(base, “dist”) os.makedirs(dst_dir, exist_ok=True) dst = os.path.join(dst_dir, “index.html”) if os.path.exists(src) and not os.path.exists(dst): shutil.copy2(src, dst); print(“patched report template ->”, dst) else: print(“report template already fine”) “””)]) open(MARKER, “w”).write(“ok”) print(“n environment readyn”) else: print(” environment already built (delete”, VENV_DIR, “to rebuild)n”) We define the core trading configuration, including the symbol, timeframe, exchange fallback list, backtesting windows, parameter grid, and fixed strategy settings. We then create an isolated Python environment with uv and install the pinned OctoBot and OctoBot-Script dependencies required for the workflow. We also install the OctoBot tentacles package and patch the report-template path so later backtest reporting works correctly inside the Colab environment. Copy CodeCopiedUse a different Browser WORKER = os.path.join(WORK_DIR, “octobot_worker.py”) WORKER_SRC = r”’ import asyncio, itertools, json, os, sys, time, traceback import numpy as np import tulipy import octobot_script as obs CFG = json.load(open(os.environ[“OBS_CONFIG”])) OUT = os.environ[“OBS_OUT”] FIX = CFG[“fixed”] for kw in (“Close”, “High”, “Low”, “Time”, “market”, “current_live_time”, “plot_indicator”): if not hasattr(obs, kw): raise RuntimeError( f”octobot_script.{kw} missing -> tentacles are not installed. ” “Run: python -m octobot_script.cli install_tentacles” ) def tail(*arrays): “””tulipy indicators return different lengths; right-align them all.””” n = min(len(a) for a in arrays) return [np.asarray(a)[-n:] for a in arrays] def clamp(v): return float(min(max(v, FIX[“min_offset_pct”]), FIX[“max_offset_pct”])) def build_callbacks(params, run_data): “”” OctoBot-Script splits a strategy into: initialize(ctx) -> runs once on the first candle. Do vectorised work here. strategy(ctx) -> runs on EVERY closed candle. Keep it cheap. “”” async def initialize(ctx): closes = await obs.Close(ctx, max_history=True) highs = await obs.High(ctx, max_history=True) lows = await obs.Low(ctx, max_history=True) times = await obs.Time(ctx, max_history=True, use_close_time=True) rsi = tulipy.rsi(closes, period=params[“rsi_period”]) ema_f = tulipy.ema(closes, period=FIX[“ema_fast”]) ema_s = tulipy.ema(closes, period=FIX[“ema_slow”]) atr = tulipy.atr(highs, lows, closes, period=FIX[“atr_period”]) t, c, rsi, ema_f, ema_s, atr = tail(times, closes, rsi, ema_f, ema_s, atr) atr_pct = np.where(c > 0, atr / c * 100.0, 0.0) entries, offsets = set(), {} for i in range(len(t)): oversold = rsi[i] < params[“rsi_threshold”] uptrend = ema_f[i] > ema_s[i] if oversold and uptrend and atr_pct[i] > 0: ts = float(t[i]) entries.add(ts) offsets[ts] = ( clamp(FIX[“sl_atr_mult”] * atr_pct[i]), clamp(params[“tp_atr_mult”] * atr_pct[i]), ) run_data[“entries”] = entries run_data[“offsets”] = offsets if run_data.get(“plot”): await obs.plot_indicator(ctx, f”RSI({params[‘rsi_period’]})”, t, rsi, entries) await obs.plot_indicator(ctx, f”EMA{FIX[’ema_fast’]}”, t, ema_f) await obs.plot_indicator(ctx, f”EMA{FIX[’ema_slow’]}”, t, ema_s) await obs.plot_indicator(ctx, “ATR %”, t, atr_pct) async def strategy(ctx): now = obs.current_live_time(ctx) if now not in run_data[“entries”]: return sl, tp = run_data[“offsets”][now] await obs.market( ctx, “buy”, amount=FIX[“position_size”], stop_loss_offset=f”-{sl:.2f}%”, take_profit_offset=f”{tp:.2f}%”, ) return initialize, strategy def metrics(res): br = res.report.get(“bot_report”, {}) first = lambda d: float(list(d.values())[0]) if isinstance(d, dict) and d else float(“nan”) return { “profitability”: first(br.get(“profitability”, {})), “market”: first(br.get(“market_average_profitability”, {})), “reference”: br.get(“reference_market”), “start_portfolio”: str(br.get(“starting_portfolio”)), “end_portfolio”: str(br.get(“end_portfolio”)), “candles”: res.candles_count, “duration_s”: round(res.duration or 0, 2), “errors”: res.report.get(“errors_count”), } async def load_data(window): “””Try each exchange until one serves data (Binance blocks many datacenter IPs).””” start, end = window last = None for ex in CFG[“exchanges”]: try: print(f” ↓ fetching {CFG[‘symbol’]} {CFG[‘time_frame’]} from {ex} ” f”[{time.strftime(‘%Y-%m-%d’, time.gmtime(start))} → ” f”{time.strftime(‘%Y-%m-%d’, time.gmtime(end))}]”, flush=True) data = await obs.get_data( CFG[“symbol”], CFG[“time_frame”], exchange=ex, exchange_type=”spot”, start_timestamp=start, end_timestamp=end, social_services=[], ) print(f” ✓ {ex} ok -> {data.data_files}”, flush=True) return data, ex except Exception as e: last = e print(f” ✗ {ex}: {type(e).__name__}: {e}”, flush=True) raise RuntimeError(f”no exchange served data; last error: {last}”) async def backtest(data, params, plot=False, storage=False): run_data = {“entries”: None, “offsets”: {}, “plot”: plot} init_f, strat_f = build_callbacks(params, run_data) res = await obs.run( data, params, strategy_func=strat_f, initialize_func=init_f, enable_logs=False, enable_storage=storage, ) return res, len(run_data[“entries”] or ()) async def main(): out = {“grid”: [], “best”: None, “oos”: None, “errors”: []} print(“n” + “=” * 78 + “n IN-SAMPLE GRID SEARCHn” + “=” * 78, flush=True) is_data, ex_used = await load_data(CFG[“in_sample”]) out[“exchange”] = ex_used keys = list(CFG[“grid”].keys()) combos = [dict(zip(keys, v)) for v in itertools.product(*CFG[“grid”].values())] print(f” {len(combos)} configurations to evaluaten”, flush=True) for i, params in enumerate(combos, 1): try: res, n_sig = await backtest(is_data, params) m = metrics(res) m.update(params); m[“signals”] = n_sig m[“edge”] = m[“profitability”] – m[“market”] out[“grid”].append(m) print(f” [{i:>2}/{len(combos)}] {params} ” f”P&L {m[‘profitability’]:+.2f}% vs market {m[‘market’]:+.2f}%

Building and Validating a Quantitative Trading Strategy with OctoBot, Walk-Forward Backtesting, Parameter Optimization, and Interactive Analysis Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The Video Production Stack Now Fits on One Desk: LTX-2.5 Launches as NVIDIA-Accelerated Open Weights World Model

Video production is shifting as social clips, ad creative and film pre-visualization move from cloud to local GPUs. LTX today released LTX-2.5, an open weights world model for video generation, real-time applications, and physical AI, built for exactly that shift. LTX optimized the model for local inference on NVIDIA RTX GPUs and NVIDIA DGX Spark, cutting VRAM requirements so a frontier world model runs on hardware creators already own. The release anchors NVIDIA’s month-long local AI series, launched the same day as its open Nemotron 3.5 Lightning agent model. The signal from both: open models, accelerated locally, are becoming default production infrastructure. What Local Generation Changes for Creators LTX-2.5 puts something in creators’ hands that used to sit behind a studio door: real consistency. Native multishot generation renders a whole sequence as one coherent piece, holding a character’s look shot to shot, fixing the glitching that made earlier open models unusable for campaigns. Add a sharper Gemma 4 language backbone and a new decoder that cuts artifacts in high-motion shots, and the output is close to post-ready. It all runs on a consumer NVIDIA RTX GPU, straight inside ComfyUI. One person at a desk can lock a branded character or signature style with a quick LoRA fine-tune. No studio. No cloud. No IP leaving the machine. That is the real shift: the entire production stack now fits on a single desktop. What used to take a crew, a shoot day, a render farm, and a cloud bill now happens on the RTX card already in the machine. Additional clips carry no per-generation fees or metered credits. That rewires how creators work: experiment widely, chase a dozen directions instead of betting on one safe idea, and let the GPU batch-generate a week of content overnight. You wake up to a folder full of options. For short-form creators and ad teams on constant refresh, that is transformational. Ad fatigue commonly sets in within 7 to 10 days, so the bottleneck was never ideas; it was the cost and time of producing enough of them. Local generation erases it: spin up variations on the same brief, test ten hooks, localize for five markets, and refresh creative before fatigue arrives. Solo creators and small teams can now match the output volume of a full studio with one RTX GPU on a desk. Speed: The Numbers Behind the Story None of this matters unless generation is fast, and it is. In LTX’s published image-to-video benchmark, a 10-second clip takes 6.8 seconds on-prem running on 2x NVIDIA GB200 and 23.7 seconds via the LTX API. The fastest closed alternatives listed, Omni Flash, Grok 1.5, and Veo 3.1, land at 52 to 70 seconds. Slower systems stretch far beyond:Seedance 2.0 at 196, FLUX 3 at 259, Seedance 2.5 at 317, and Kling 3.0 Pro at 398. On-prem, LTX-2.5 generates faster than the clip’s own runtime, 7.6x faster than the nearest closed alternative and roughly 58x faster than the slowest. That gap makes overnight batch generation and rapid A/B iteration practical, not theoretical. NVIDIA’s Local AI Momentum Throughout August, NVIDIA is spotlighting models, applications, and tools across the local AI ecosystem. Nemotron 3.5 Lightning, also released today, is an open 30B mixture-of-experts model for always-on agents, joined by NeMo Switchyard, an open source library that routes each agent workflow step to the best-fit model. The common thread is hardware choice: NVIDIA-ecosystem open models scale from RTX PCs to workstations, data centers, and cloud. LTX-2.5 slots directly into that story as an NVIDIA-accelerated world model for creators, developers, and robotics teams. What is LTX-2.5? Where large language models (LLMs) learn to predict the next word, world models learn to predict the next moment. They generate environments, simulate how they behave, and let users act inside them. That foundation supports film, advertising, gaming, simulation, and robots in warehouses and factories. LTX describes the LTX family as the most used open world model, with more than 33 million downloads, and positions LTX-2.5 as its most capable release yet. Open weights give teams full control of hardware, customization, and IP. What’s New in the Architecture LTX rebuilt nearly every stage of the generation pipeline rather than bolting features onto an older core: New diffusion video decoder: Reduces visual artifacts in high-motion scenes while preserving LTX’s high compression ratio and staying true to existing footage. Native multishot generation: Renders a full sequence as one output, holding character, scene, and voice consistent across cuts. A custom Gemma 4 language backbone and dedicated prompt enhancer improve comprehension of complex, multi-subject prompts. Diffusion Fidelity Rendering: Builds motion and structure in an 8x temporally compressed latent space, then generates high-fidelity keyframes to anchor visual detail. Keyframe count adapts to scene complexity and compute budget. A physical AI checkpoint: A pretrained checkpoint tuned for robotics gives teams a base for fine-tuning on domain data unlike cinematic video. A stronger distilled model: Delivers the same quality at lower cost and faster inference for production-volume deployment. Who LTX-2.5 is For Film and video studios: Multishot consistency plus the cleaner decoder make sequences usable in real productions. Studios like Asteria already produce original film and video on LTX. Short-form creators and ad teams: Local generation with no per-clip fees turns A/B testing into a strategy: batch variations overnight, refresh creative weekly, and localize across markets without a production budget. Real-time application developers: Reactor runs LTX-2.5 on its low-latency infrastructure to power interactive avatars, live worlds, and real-time robotics workloads. Robotics and physical AI teams: The physical AI checkpoint provides a fine-tuning base for non-cinematic domain data. Markov Robotics uses LTX to develop how physical systems perceive and move through the world. Availability and Licensing LTX-2.5 ships as open weights on Hugging Face, natively in ComfyUI, and through the LTX API for managed generation. It runs on anything from data center GPUs to a Mac and is free for organizations under $10M in annual recurring revenue. Code is on GitHub, with documentation. Key Takeaways LTX-2.5 is an open weights world model

The Video Production Stack Now Fits on One Desk: LTX-2.5 Launches as NVIDIA-Accelerated Open Weights World Model Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

These startups are chasing the next big thing in LLMs

MIT Technology Review’s What’s Next series looks across industries, trends, and technologies to give you a first look at the future. You can read the rest of them here. Way back in the summer of 2017, AI researchers at Google put out a paper called “Attention Is All You Need,” in which they described a new type of neural network called a transformer. It proved to be very good at processing long sequences of data, especially text.  Nine years on, transformers are the engines inside every major large language model on the market. “The entire AI industry is built on transformers,” says Justin Dangel, cofounder and CEO of the AI startup Subquadratic. “They are one of the most important innovations in the history of computer science, and they’ve changed the world.” But transformers are starting to show their age. Many of the recent advances in LLMs, such as the development of so-called reasoning models and their ability to handle large amounts of input at once, are not neat extensions of that core technology but workarounds that patch over some of its fundamental flaws. A growing number of scientists and engineers are now asking what’s coming next. LLMs are not going anywhere, but the way they get built is up for grabs. (MIT Technology Review dubbed this future generation of models LLMs+ in this year’s list of the 10 things that matter in AI.) Enter a wave of startups hoping to push the boundaries of this boomtown technology. Some will no doubt fail—but they have everything to play for and far less to lose than the companies at the front of the pack today.  Strength in numbers But first, the problem. The key strength of transformers lies in a mechanism called dense attention, which encodes the meaning of a block of text in a series of numbers. The process involves comparing every word (or part of a word, known as a token) in that text with every other word via a form of multiplication. Dense attention can capture the meaning of text with remarkable accuracy. But as the length of that text grows, the number of computations needed to process it adds up fast. A document 10,000 words long might require a transformer to perform 50 million multiplications. That’s the main reason LLMs suck up so much power. The costs are huge. OpenAI is set to spend $50 billion on computing this year, according to the company’s president, Greg Brockman. And the International Energy Agency predicts that the total amount of electricity consumed by data centers will double by 2030. What’s more, transformers struggle with what many of the latest models are designed to do. Because of the way they process text word by word, transformers are not great at keeping track of a lot of information at once (in other words, what’s known as their context window cannot get too large). And yet if LLMs are to carry out harder tasks, they will need to take in larger amounts of data: a whole library of documents, an entire code base, or in the case of agents, output from other LLMs. As for reasoning models, they work by writing notes to themselves (in a kind of scratch pad known as a chain of thought) and then reading them back, which again adds to the amount of data to stay on top of. As LLMs get bigger and better, transformers have become a bottleneck. The technology’s key strength is now a limitation. Here are four new ideas for how to solve the transformer problem—innovations that could change LLMs for good, making them faster, far more efficient, and (maybe) even smarter. 01: Rethinking attention An obvious way to make LLMs faster and cheaper is to tackle the problem head on and change the way attention works. Swapping out dense attention for a mechanism called sparse attention, which runs calculations on only some pairings of words in a block of text instead of all of them, can radically reduce the amount of computation LLMs need to do.   Researchers have come up with plenty of sparse attention mechanisms over the years. The problem is that none of them were as good as dense attention at capturing meaning. That might have changed. Subquadratic, a startup based in Miami, claims it has invented the first sparse attention mechanism that rivals top mainstream LLMs on a handful of tasks, including search and coding. It’s a huge claim (and some people in the industry remain skeptical). Subquadratic says its model, SubQ, works by figuring out on the fly—for each piece of text it is given—which words matter and which don’t. The company also claims that thousands have signed up to its waitlist and plans to make the model widely available soon. Meanwhile, Manifest AI, a startup based in San Francisco, is coming at the problem from a different angle. Instead of changing how attention works, it is replacing it with something else.  It has developed a mechanism it calls power retention, which stores only the most relevant information for a given task and ensures that the amount of data an LLM has to keep track of doesn’t blow up. Attention mechanisms force LLMs to keep track of everything in their context window. A sparse attention model (such as SubQ) throws out a lot of the individual words, but it still retains a rough picture of everything it has seen. In contrast, power retention works by providing the model with a rolling summary of its context window. As new information is added, less relevant information is dropped.  The basic principle of retention has been around for a decade. Manifest AI claims it has updated those techniques to build models that can stand up to transformer-based LLMs for the first time. The company says it is possible to adapt a transformer model into a power retention model with minimal retraining. To demonstrate this, it has turned an existing open-source coding LLM called StarCoder into a version that uses power retention, called

These startups are chasing the next big thing in LLMs Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The Download: AI agents for science, and the “censorship-industrial complex”

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. AI for science needs reasoning, not just data —Eric Schmidt, the former CEO of Google and the cofounder of Schmidt Sciences, and Suhas Mahesh, who leads the AI for science work at the AI Center of Schmidt Sciences In 2024, Google DeepMind scientists shared the Nobel Prize in Chemistry for a neural network, AlphaFold, which predicts the structures of proteins. It showed that AI could make groundbreaking scientific discoveries, but AlphaFold may not be the best template for accelerating science. Instead, another approach may hold the key: AI agents. AlphaFold relied on a dataset of roughly 170,000 experimentally validated protein structures that took 53 years and roughly $21 billion worth of experimental work to assemble. Comparable datasets will be difficult or impossible to create in many fields. AI agents can instead model the iterative, highly contingent process of actual research. While tools like AlphaFold apply a powerful approach to a limited question, agents are inherently generalists. They do not represent a new way to do science—instead, they digitally model the human process of discovery.  Read the full op-ed on how agents could accelerate scientific discovery. Inside the “censorship-industrial complex” idea shaping US policy For years, the idea of a “censorship-industrial complex” that suppressed conservative and populist speech spread in right-wing circles online. But now, the theory has made its way into the Trump administration. Over the past nine months, MIT Technology Review investigated its origins and traced its rise. In a virtual Roundtables session on Thursday, August 13, senior reporter Eileen Guo and executive editor Amy Nordrum will explore what they discovered, where the theory is going, and what it could mean for the future of democracy and the internet. Register here to join the session at 19:00 GMT / 2:00 pm ET / 11:00 am PT. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 A new Amazon data center could become the US’s biggest polluterThe Texas facility has a permit to release up to 33 million tons of CO2. (NYT $)+ It will be Amazon’s first off-grid AI data center. (Cleanview)+ The gas plant will generate up to 7.65 gigawatts of power. (Verge) 2 OpenAI has paused work on its Astra AI model over security concernsTests found it could launch cyber-attacks autonomously. (FT $)+ Critics warn such disclosures could be designed to spark hype. (Guardian)+ AI doesn’t need to be that smart to make online crimes easier. (MIT Technology Review)  3 North Korean hackers have built AI tools for cyberattacksA new report says they’re used in spear-phishing campaigns. (Al Jazeera)+ They’re attributed to the state-linked group Kimsuky. (Reuters $)+ Which could automate attacks and analyse stolen data. (TNW) 4 China’s firms control 97% of global humanoid shipments Global shipments have more than tripled since last year. (Bloomberg $) + Chinese humanoid manufacturers are racing to public listings. (Reuters $)+ Gig workers are training humanoids at home. (MIT Technology Review) 5 Taiwan has expanded its use of aerial and maritime drones to deter ChinaThe approach draws on lessons from Ukraine’s battlefield. (NYT $)+ Taiwan’s “silicon shield” could be weakening. (MIT Technology Review) 6 Apple is testing Chinese memory chips as the supply squeeze bites But any deal with CXMT would be politically sensitive. (WSJ $) 7 An Israeli startup is tied to rogue AI hacks at OpenAI, Anthropic, and MetaIrregular’s tests allowed the models to access the public internet. (CNBC) 8 NASA is flying into wildfire storms to understand themThe mission will study their effects on fires and the atmosphere. (Economist $) 9 A chatbot-free childhood may become a status symbolAI is like ultra-processed food for developing brains. (Atlantic $)+ Are chatbots making us lose control of our brains? (MIT Technology Review) 10 MySpace is eyeing a comeback as an “antidote” to social media fatigue But the nostalgic plan looks like a long shot. (BBC) Quote of the day “It’s the humans that we need to watch out for. AI is just the tool.” —Oren Etzioni, professor emeritus at the University of Washington and former CEO of the Allen Institute for AI, tells CNN that people are still the main threats in cybersecurity. One More Thing Meet the man building a starter kit for civilization Marcin Jakubowski lives in a house he designed and built himself. He relies on the sun for power, heats his home with a woodstove, and farms his own fish and vegetables. Jakubowski is the founder of Open Source Ecology, a collection of 50 machines capable of building civilization from scratch. It includes everything from a tractor to an oven to a circuit maker, all designed to be reconfigured however you see fit. The ultimate goal is a “zero marginal cost” society, where producing an additional unit of a good or service costs little to nothing. Jakubowski hopes to get there by eradicating licensing fees, decentralizing manufacturing, and fostering collaboration through education. Take a look inside his starter kit for civilization. —Tiffany Ng We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + A rhythmic doggie is proving that not only humans can play the drums.+ Catch a glimpse of the internet’s future at the Awwwards, the Oscars of web design.+ Explore the ocean year-round with this immersive experience of the Nautilus vessel’s expeditions.+ Earth once (or twice) had supermountains. This fascinating video explores their links to evolutionary shifts in the history of life. 

The Download: AI agents for science, and the “censorship-industrial complex” Leggi l'articolo »

We use cookies to improve your experience and performance on our website. You can learn more at Politica sulla privacy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
it_IT