YouZum

Committee

AI, Committee, Notizie, Uncategorized

Google Introduces Jetpack Compose Glimmer: A New Spatial UI Framework Designed Specifically for the Next Generation of AI Glasses

Google is moving beyond the rectangular screen. For over 10 years, Google designers have explored how to build interfaces for transparent displays. The result is Jetpack Compose Glimmer, a design system built specifically for display AI glasses. For devs and data scientists, this is a shift from designing for pixels to designing with light. The Additive Display Constraint Most developers are used to LCD or OLED screens. However, AI glasses use additive displays. These displays only add light to the user’s field of vision. They cannot create opaque black or make the real world darker. On an additive display, black is 100% transparent. It is not a color; it is a void. If you use a standard Material Design card (light surface with dark text), it fails. The light surface becomes a bright block of light that drains the battery and creates halation. Halation is an effect where bright light bleeds into dark areas, making text unreadable. To solve this, devs must use dark surfaces and bright content. Using black as a foundation provides a ‘clean plate’ for the UI. This allows the digital elements to harmonize with the physical world without creating distracting glare. From Pixels to Visual Angles Software Devs typically measure UI in pixels or points. In a transparent spatial environment, these units are irrelevant. The perceived size of an object changes based on its distance from the eye. Google team now measure UI in visual angles or degrees. The display in these glasses is projected at a perceived depth of 1 meter, which is about an arm’s length. This distance requires the user to actively shift their focus from the background to the UI. To ensure legibility, Google established a minimum readable text size of 0.6 degrees. Keeping text above this threshold ensures that the interface remains ‘glanceable’ in different environments. Engineering Typography for Light Standard fonts often fail on transparent lenses. Google team modified Google Sans Flex using its optical size axis to fix this. These technical adjustments make letters more distinct: Increased Counters: The internal openings in letters like ‘a’ and ‘e’ are larger to prevent them from blurring. Modified Dots: The dots on ‘i’ and ‘j’ are moved further from the main letter body. Variable Letter-Spacing: The system optimizes spacing through code to maximize clarity at a glance. The Additive Contrast Formula Google team use a specific formula to calculate visibility. This is the additive contrast ratio. The formula is: (Environment Brightness + Display Brightness) / Display Brightness. In the real world, colors behave differently. Highly saturated colors often ‘disappear’ or look ghostly against a bright sky. Glimmer uses a neutral, desaturated palette by default. By keeping colors closer to white, the UI remains stable and visible regardless of the lighting in the room. Designing Motion for Human Attention On a heads-up display, motion can be a major distraction. In standard mobile development, a notification might appear in 500 milliseconds. On AI glasses, this is too fast. It creates an abrupt ‘blink’ that can startle the user. Glimmer uses a slower, more deliberate transition for notifications. These animations occur over 2 seconds. This duration allows the notification to enter the user’s peripheral vision gracefully. It invites focus rather than demanding it. However, user-triggered actions (like a voice command or gesture) still require low-latency feedback. Glimmer uses ‘focus rings’ to provide instant confirmation that the system has received an input. This creates a balance between ambient notifications and responsive controls. Key Takeaways Black is Transparency, Not a Color: Because AI glasses use additive displays, they can only add light; they cannot create true black or shadows. In this environment, black is 100% transparent. To ensure legibility, devs must use dark surfaces for containers and bright colors for text and icons. Visual Angles Replace Pixels: Standard units like pixels (px) are replaced by visual angles (degrees). Since the UI is projected at a perceived depth of 1 meter, objects must be sized relative to the human eye’s perspective. The minimum threshold for readable text is set at 0.6 degrees. The Additive Contrast Formula: Devs must account for environmental light using the formula: (Environment Brightness + Display Brightness) / Display Brightness. Because saturated colors often ‘disappear’ against bright real-world backgrounds, a neutral, desaturated palette is used to maintain visibility. Optical Typography Optimization: Standard typefaces suffer from halation (light bleeding). Google Sans Flex is modified via its optical size axis to increase internal letter openings (counters) and expand letter-spacing, preventing characters from blurring together on a transparent lens. Motion Timing is Context-Dependent: Standard 500ms animations are too abrupt for a heads-up display. To respect human peripheral vision, Glimmer uses 2-second transitions for notifications to ‘invite’ focus, while maintaining low-latency feedback (like focus rings) for direct user inputs to ensure responsiveness. Check out the Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google Introduces Jetpack Compose Glimmer: A New Spatial UI Framework Designed Specifically for the Next Generation of AI Glasses appeared first on MarkTechPost.

Google Introduces Jetpack Compose Glimmer: A New Spatial UI Framework Designed Specifically for the Next Generation of AI Glasses Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Cohere Releases Tiny Aya: A 3B-Parameter Small Language Model that Supports 70 Languages and Runs Locally Even on a Phone

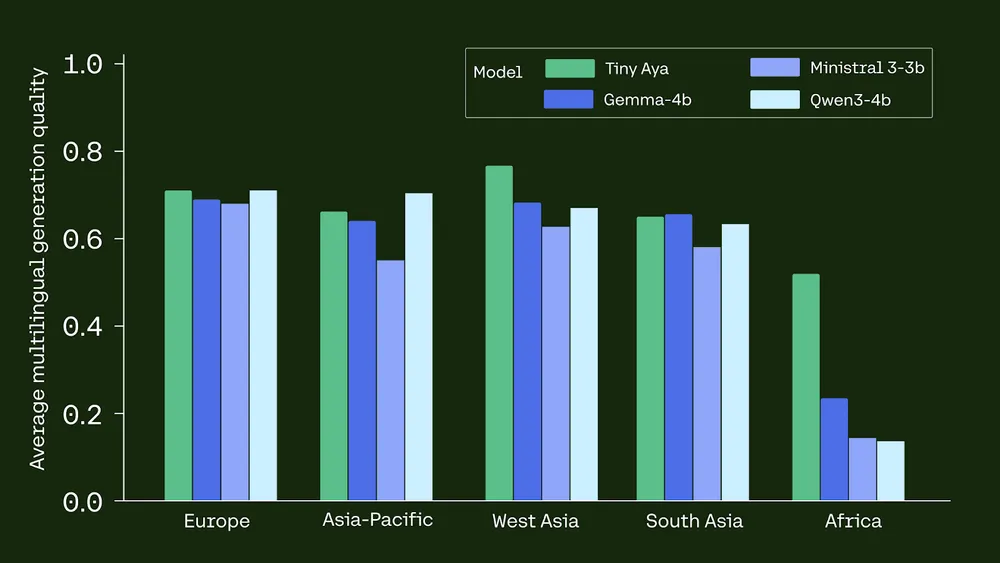
Cohere AI Labs has released Tiny Aya, a family of small language models (SLMs) that redefines multilingual performance. While many models scale by increasing parameters, Tiny Aya uses a 3.35B-parameter architecture to deliver state-of-the-art translation and generation across 70 languages. The release includes 5 models: Tiny Aya Base (pretrained), Tiny Aya Global (balanced instruction-tuned), and three region-specific variants—Earth (Africa/West Asia), Fire (South Asia), and Water (Asia-Pacific/Europe). https://cohere.com/blog/cohere-labs-tiny-aya The Architecture Tiny Aya is built on a dense decoder-only Transformer architecture. Key specs include: Parameters: 3.35B total (2.8B non-embedding) Layers: 36 Vocabulary: 262k tokenizer designed for equitable language representation. Attention: Interleaved sliding window and full attention (3:1 ratio) with Grouped Query Attention (GQA). Context: 8192 tokens for input and output. The model was pretrained on 6T tokens using a Warmup-Stable-Decay (WSD) schedule. To maintain stability, the team used SwiGLU activations and removed all biases from dense layers. Advanced Post-training: FUSION and SimMerge To bridge the gap in low-resource languages, Cohere used a synthetic data pipeline. Fusion-of-N (FUSION): Prompts are sent to a ‘team of teachers’ (COMMAND A, GEMMA3-27B-IT, DEEPSEEK-V3). A judge LLM, the Fusor, extracts and aggregates the strongest components of their responses. Region Specialization: Models were finetuned on 5 regional clusters (e.g., South Asia, Africa). SimMerge: To prevent ‘catastrophic forgetting’ of global safety, regional checkpoints were merged with the global model using SimMerge, which selects the best merge operators based on similarity signals. Performance Benchmarks Tiny Aya Global consistently beats larger or same-scale competitors in multilingual tasks: Translation: It outperforms GEMMA3-4B in 46 of 61 languages on WMT24++. Reasoning: In the GlobalMGSM (math) benchmark for African languages, Tiny Aya achieved 39.2% accuracy, dwarfing GEMMA3-4B (17.6%) and QWEN3-4B (6.25%). Safety: It holds the highest mean safe response rate (91.1%) on MultiJail. Language Integrity: The model achieves 94% language accuracy, meaning it rarely switches to English when asked to reply in another language. On-Device Deployment Tiny Aya is optimized for edge computing. Using 4-bit quantization (Q4_K_M), the model fits in a 2.14 GB memory footprint. iPhone 13: 10 tokens/s. iPhone 17 Pro: 32 tokens/s. This quantization scheme results in a minimal 1.4-point drop in generation quality, making it a viable solution for offline, private, and localized AI applications. Key Takeaways Efficient Multilingual Power: Tiny Aya is a 3.35B-parameter model family that delivers state-of-the-art translation and high-quality generation across 70 languages. It proves that massive scale is not required for strong multilingual performance if models are designed with intentional data curation. Innovative Training Pipeline: The models were developed using a novel strategy involving Fusion-of-N (FUSION), where a ‘team of teachers’ (like Command A and DeepSeek-V3) generated synthetic data. A judge model then aggregated the strongest components to ensure high-quality training signals even for low-resource languages. Regional Specialization via Merging: Cohere released specialized variants—Tiny Aya Earth, Fire, and Water—which are tuned for specific regions like Africa, South Asia, and the Asia-Pacific. These were created by merging regional fine-tuned models with a global model using SimMerge to preserve safety while boosting local language performance. Superior Benchmark Performance: Tiny Aya Global outperforms competitors like Gemma3-4B in translation quality for 46 of 61 languages on WMT24++. It also significantly reduces disparities in mathematical reasoning for African languages, achieving 39.2% accuracy compared to Gemma3-4B’s 17.6%. Optimized for On-Device Deployment: The model is highly portable and runs efficiently on edge devices; it achieves ~10 tokens/s on an iPhone 13 and 32 tokens/s on an iPhone 17 Pro using Q4_K_M quantization. This 4-bit quantization format maintains high quality with only a minimal 1.4-point degradation. Check out the Technical details, Paper, Model Weights and Playground. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Cohere Releases Tiny Aya: A 3B-Parameter Small Language Model that Supports 70 Languages and Runs Locally Even on a Phone appeared first on MarkTechPost.

Cohere Releases Tiny Aya: A 3B-Parameter Small Language Model that Supports 70 Languages and Runs Locally Even on a Phone Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The robots who predict the future

To be human is, fundamentally, to be a forecaster. Occasionally a pretty good one. Trying to see the future, whether through the lens of past experience or the logic of cause and effect, has helped us hunt, avoid being hunted, plant crops, forge social bonds, and in general survive in a world that does not prioritize our survival. Indeed, as the tools of divination have changed over the centuries, from tea leaves to data sets, our conviction that the future can be known (and therefore controlled) has only grown stronger.  Today, we are awash in a sea of predictions so vast and unrelenting that most of us barely even register them. As I write this sentence, algorithms on some remote server are busy trying to guess my next word based on those I have already typed. If you’re reading this online, a separate set of algorithms has likely already served you an ad deemed to be one you are most likely to click. (To the die-hards reading this story on paper, congratulations! You have escaped the algorithms … for now.) If the thought of a ubiquitous, mostly invisible predictive layer secretly grafted onto your life by a bunch of profit-hungry corporations makes you uneasy … well, same here. So how did all this happen? People’s desire for reliable forecasting is understandable. Still, nobody signed up for an omnipresent, algorithmic oracle mediating every aspect of their life. A trio of new books tries to make sense of our future-­focused world—how we got here, and what this change means. Each has its own prescriptions for navigating this new reality, but they all agree on one thing: Predictions are ultimately about power and control. The Means of Prediction: How AI Really Works (and Who Benefits)Maximilian KasyUNIVERSITY OF CHICAGO PRESS, 2025 In The Means of Prediction: How AI Really Works (and Who Benefits), the Oxford economist Maximilian Kasy explains how most predictions in our lives are based on the statistical analysis of patterns in large, labeled data sets—what’s known in AI circles as supervised learning. Once “trained” on such data sets, algorithms for supervised learning can be presented with all kinds of new information and then deliver their best guess as to some specific future outcome. Will you violate your parole, pay off your mortgage, get promoted if hired, perform well on your college exams, be in your home when it gets bombed? More and more, our lives are shaped (and, yes, occasionally shortened) by a machine’s answer to these questions. If the thought of a ubiquitous, mostly invisible predictive layer secretly grafted onto your life by a bunch of profit-hungry corporations makes you uneasy … well, same here. This arrangement is leading to a crueler, blander, more instrumentalized world, one where life’s possibilities are foreclosed, age-old prejudices are entrenched, and everyone’s brain seems to be actively turning into goo. It’s an outcome, according to Kasy, that was entirely predictable.  AI adherents might frame those consequences as “unintended,” or mere problems of optimization and alignment. Kasy, on the other hand, argues that they represent the system working as intended. “If an algorithm selecting what you see on social media promotes outrage, thereby maximizing engagement and ad clicks,” he writes, “that’s because promoting outrage is good for profits from ad sales.” The same holds true for an algorithm that nixes job candidates “who are likely to have family-care responsibilities outside the workplace,” and the ones that “screen out people who are likely to develop chronic health problems or disabilities.” What’s good for a company’s bottom line may not be good for your job-hunting prospects or life expectancy. Where Kasy differs from other critics is that he doesn’t think working to create less biased, more equitable algorithms will fix any of this. Trying to rebalance the scales can’t change the fact that predictive algorithms rely on past data that’s often racist, sexist, and flawed in countless other ways. And, he says, the incentives for profit will always trump attempts to eliminate harm. The only way to counter this is with broad democratic control over what Kasy calls “the means of prediction”: data, computational infrastructure, technical expertise, and energy.   A little more than half of The Means of Prediction is devoted to explaining how this might be accomplished—through mechanisms including “data trusts” (collective public bodies that make decisions about how to process and use data on behalf of their contributors) and corporate taxing schemes that try to account for the social harm AI inflicts. There’s a lot of economist talk along the way, about how “agents of change” might help achieve “value alignment” in order to “maximize social welfare.” Reasonable, I guess, though a skeptic might point out that Kasy’s rigorous, systematic approach to building new public-serving institutions comes at a time when public trust in institutions has never been lower. Also, there’s the brain goo problem.  To his credit, Kasy is a realist here. He doesn’t presume that any of these proposals will be easy to implement. Or that it will happen overnight, or even in the near future. The troubling question at the end his book is: Do we have that kind of time? Reading Kasy’s blueprint for seizing control of the means of prediction raises another pressing question. How on earth did we reach a point where machine-mediated prediction is more or less inescapable? Capitalism, might be Marx’s pithy response. Fine, as far as it goes, but that doesn’t explain why the same kinds of algorithms that currently model climate change are for some reason also deciding whether you get a new kidney or I get a car loan. The Irrational Decision: How We Gave Computers the Power to Choose for UsBenjamin RechtPRINCETON UNIVERSITY PRESS, 2026 If you ask Benjamin Recht, author of The Irrational Decision: How We Gave Computers the Power to Choose for Us, he’d likely tell you our current predicament has a lot to do with the idea and ideology of decision theory—or what economists call rational choice theory.

The robots who predict the future Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Welcome to the dark side of crypto’s permissionless dream

“We’re out of airspace now. We can do whatever we want,” Jean-Paul Thorbjornsen tells me from the pilot’s seat of his Aston Martin helicopter. As we fly over suburbs outside Melbourne, Australia, it’s becoming clear that doing whatever he wants is Thorbjornsen’s MO.  Upper-middle-class homes give way to vineyards, and Thorbjornsen points out our landing spot outside a winery. People visiting for lunch walk outside. “They’re going to ask for a shot now,” he says, used to the attention drawn by his luxury helicopter, emblazoned with the tail letters “BTC” for bitcoin (the price tag of $5 million in Australian dollars—$3.5 million in US dollars today—was perhaps reasonable for someone who claims a previous crypto project made more than AU$400 million, although he also says those funds were tied up in the company).  Thorbjornsen is a founder of THORChain, a blockchain through which users can swap one cryptocurrency for another and earn fees from making those swaps. THORChain is permissionless, so anyone can use it without getting prior approval from a centralized authority. As a decentralized network, the blockchain is built and run by operators located across the globe, most of whom use pseudonyms.  During its early days, Thorbjornsen himself hid behind the pseudonym “leena” and used an AI-generated female image as his avatar. But around March 2024, he revealed that he, an Australian man in his mid-30s, with a rural Catholic upbringing, was the mind behind the blockchain. More or less.  If there is a central question around THORChain, it is this: Exactly who is responsible for its operations? Blockchains as decentralized as THORChain are supposed to offer systems that operate outside the centralized leadership of corruptible governments and financial institutions. If a few people have outsize sway over this decentralized network—one of a handful that operate at such a large scale—it’s one more blemish on the legacy of bitcoin’s promise, which has already been tarnished by capitalistic political frenzy.    Who’s responsible for THORChain matters because in January last year, its users lost more than $200 million worth of their cryptocurrency in US dollars after THORChain transactions and accounts were frozen by a singular admin override, which users believed was not supposed to be possible given the decentralized structure. When the freeze was lifted, some users raced to pull their money out. The following month, a team of North Korean hackers known as the Lazarus Group used THORChain to move roughly $1.2 billion of stolen ethereum taken in the infamous hack of the Dubai-based crypto exchange Bybit.  Thorbjornsen explains away THORChain’s inability to stop the movement of stolen funds, or prevent a bank run, as a function of its decentralized and permissionless nature. The lack of executive powers means that anyone can use the network for any reason, and arguably there’s no one to hold accountable when even the worst goes down. But when the worst did go down, nearly everyone in the THORChain community, and those paying attention to it in channels like X, pointed their fingers at Thorbjornsen. A lawsuit filed by the THORChain creditors who lost millions in January 2025 names him. A former FBI analyst and North Korea specialist, reflecting on the potential repercussions for helping move stolen funds, told me he wouldn’t want to be in Thorbjornsen’s shoes. THORChain was designed to make decisions based on votes by node operators, where two-thirds majority rules. That’s why I traveled to Australia—to see if I could get a handle on where he sees himself and his role in relation to the network he says he founded. According to Thorbjornsen, he should not be held responsible for either event. THORChain was designed to make decisions based on votes by node operators—people with the computer power, and crypto stake, to run a cluster of servers that process the network’s transactions. In those votes, a two-thirds majority rules. Then there’s the permissionless part. Anyone can use THORChain to make swaps, which is why it’s been a popular way for widely sanctioned entities such as the government of North Korea to move stolen money. This principle goes back to the cypherpunk roots of bitcoin, a currency that operates outside of nation-states’ rules. THORChain is designed to avoid geopolitical entanglements; that’s what its users like about it. But there are distinct financial motivations for moving crypto, stolen or not: Node operators earn fees from the funds running through the network. In theory, this incentivizes them to act in the network’s best interests—and, arguably, Thorbjornsen’s interests too, as many assume his wealth is tied to the network’s profits. (Thorbjornsen says it is not, and that it comes instead from “many sources,” including “buying bitcoin back in 2013.”) Now recent events have raised critical questions, not just about Thorbjornsen’s outsize role in THORChain’s operations, but also about the blockchain’s underlying nature. If THORChain is decentralized, how was a single operator able to freeze its funds a month before the Bybit hack? Could someone have unilaterally decided to stop the stolen Bybit funds from coming through the network, and chosen not to?  Thorbjornsen insists THORChain is helping realize bitcoin’s original purpose of enabling anyone to transact freely outside the reach of purportedly corrupt governments. Yet the network’s problems suggest that an alternative financial system might not be much better. Decentralized?  On February 21, 2025, Bybit CEO Ben Zhou got an alarming call from the company’s chief financial officer. About $1.5 billion US of the exchange’s ethereum token, ETH, had been stolen.  The FBI attributed the theft to the Lazarus Group. Typically, criminals will want to convert ETH to bitcoin, which is much easier to convert in turn to cash. Knowing this, the FBI issued a public service announcement on February 26 to “exchanges, bridges … and other virtual asset service providers,” encouraging them to block transactions from accounts related to the hack.  Someone posted that announcement in THORChain’s private, invite-only developer channel on Discord, a chat app used widely by software engineers and gamers. While other crypto exchanges and bridges (which facilitate

Welcome to the dark side of crypto’s permissionless dream Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Character-aware Transformers Learn an Irregular Morphological Pattern Yet None Generalize Like Humans

arXiv:2602.14100v1 Announce Type: new Abstract: Whether neural networks can serve as cognitive models of morphological learning remains an open question. Recent work has shown that encoder-decoder models can acquire irregular patterns, but evidence that they generalize these patterns like humans is mixed. We investigate this using the Spanish emph{L-shaped morphome}, where only the first-person singular indicative (e.g., textit{pongo} `I put’) shares its stem with all subjunctive forms (e.g., textit{ponga, pongas}) despite lacking apparent phonological, semantic, or syntactic motivation. We compare five encoder-decoder transformers varying along two dimensions: sequential vs. position-invariant positional encoding, and atomic vs. decomposed tag representations. Positional encoding proves decisive: position-invariant models recover the correct L-shaped paradigm clustering even when L-shaped verbs are scarce in training, whereas sequential positional encoding models only partially capture the pattern. Yet none of the models productively generalize this pattern to novel forms. Position-invariant models generalize the L-shaped stem across subjunctive cells but fail to extend it to the first-person singular indicative, producing a mood-based generalization rather than the L-shaped morphomic pattern. Humans do the opposite, generalizing preferentially to the first-person singular indicative over subjunctive forms. None of the models reproduce the human pattern, highlighting the gap between statistical pattern reproduction and morphological abstraction.

Character-aware Transformers Learn an Irregular Morphological Pattern Yet None Generalize Like Humans Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

EVALOOOP: A Self-Consistency-Centered Framework for Assessing Large Language Model Robustness in Programming

arXiv:2505.12185v5 Announce Type: replace-cross Abstract: Evaluating the programming robustness of large language models (LLMs) is paramount for ensuring their reliability in AI-based software development. However, adversarial attacks exhibit fundamental limitations that compromise fair robustness assessment: they demonstrate contradictory evaluation outcomes where different attack strategies tend to favor different models, and more critically, they operate solely through external perturbations, failing to capture the intrinsic stability essential for autonomous coding agents where subsequent inputs are endogenously generated by the model itself. We introduce EVALOOOP, a novel assessment framework that evaluates robustness from a self-consistency perspective, leveraging the natural duality inherent in software engineering tasks (e.g., code generation and code summarization). EVALOOOP establishes a self-contained feedback loop where an LLM iteratively transforms between code and natural language until functional failure occurs, with robustness quantified by a novel Average Sustainable Loops (ASL) metric-the mean number of iterations maintaining functional correctness across benchmark tasks. This cyclical strategy intrinsically evaluates robustness without relying on external attack configurations, providing a unified metric that reveals how effectively LLMs preserve semantic integrity through sustained self-referential transformations. We evaluate 96 popular LLMs, ranging from 0.5B to 685B parameters, on EVALOOOP equipped with the MBPP Plus benchmark, and found that EVALOOOP typically induces a 2.65%-47.62% absolute drop in pass@1 accuracy within ten loops. Intriguingly, robustness does not always align with initial performance (i.e., one-time query); for instance, Qwen3-235B-A22B-Instruct-2507, despite inferior initial code generation compared to OpenAI’s o-series models and DeepSeek-V3, demonstrated the superior robustness (ASL score).

EVALOOOP: A Self-Consistency-Centered Framework for Assessing Large Language Model Robustness in Programming Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

Agoda Open Sources APIAgent to Convert Any REST pr GraphQL API into an MCP Server with Zero Code

Building AI agents is the new gold rush. But every developer knows the biggest bottleneck: getting the AI to actually communicate to your data. Today, travel giant Agoda is tackling this problem head-on. They have officially launched APIAgent, an open-source tool designed to turn any REST or GraphQL API into a Model Context Protocol (MCP) server with 0 code and 0 deployments. The Problem: The ‘Integration Tax‘ Until recently, if you wanted your AI agent to check flight prices or look up a database, you had to write a custom tool. When Anthropic released the Model Context Protocol (MCP), it created a standard way for Large Language Models (LLMs) to connect to external tools. However, even with MCP, the workflow is tedious. A developer must: Write a new MCP server in Python or TypeScript. Define every tool and its parameters manually. Deploy and maintain that server. Update the code every time the underlying API changes. Agoda team calls this the ‘integration tax.’ For a company with 1000s of internal APIs, writing 1000s of MCP servers is not realistic. APIAgent is their answer to this scaling problem. What is APIAgent? APIAgent is a universal MCP server. Instead of writing custom logic for every API, you use APIAgent as a proxy. It sits between your LLM (like Claude or GPT-4) and your existing APIs. The tool is built on a specific technical stack: FastMCP: Powers the MCP server layer. OpenAI Agents SDK: Handles the language model orchestration. DuckDB: An in-process SQL engine used for SQL post-processing. The ‘magic’ lies in its ability to understand API documentation. You provide a definition of your API—using an OpenAPI specification for REST or a schema for GraphQL—and APIAgent handles the rest. How It Works? The architecture is straightforward. APIAgent acts as a gateway. When a user asks an AI agent a question, the flow looks like this: The Request: The user asks, ‘Show me the top 10 hotels in Bangkok with the most reviews.’ Schema Introspection: APIAgent automatically inspects the API schema to understand the available endpoints and fields. The SQL Layer (DuckDB): This is the secret sauce. If the API returns 10,000 unsorted rows, APIAgent uses DuckDB to filter, sort, and aggregate that data locally via SQL before sending the concise result back to the LLM. The Response: The JSON data travels back through APIAgent, which formats it for the AI to read. This system uses Dynamic Tool Discovery. You can point APIAgent at any URL, and it automatically generates the necessary tools for the LLM without manual mapping. Key Feature: ‘Recipe’ Learning One of the key features is Recipe Learning. When a complex natural language query successfully executes, APIAgent can extract the trace and save it as a ‘Recipe.’ These recipes are parameterized templates. The next time a similar question is asked, APIAgent uses the recipe directly. This skips the expensive LLM reasoning step, which significantly reduces latency and cost. Key Takeaway Universal Protocol Bridge: APIAgent acts as a single, open-source proxy that converts any REST or GraphQL API into a Model Context Protocol (MCP) server. This removes the need to write custom boilerplate code or maintain individual MCP servers for every internal microservice. Zero-Code Schema Introspection: The tool is ‘configuration-first.’ By simply pointing APIAgent at an OpenAPI spec or GraphQL endpoint, it automatically introspects the schema to understand endpoints and fields. It then exposes these to the LLM as functional tools without manual mapping. Advanced SQL Post-Processing: It integrates DuckDB, an in-process SQL engine, to handle complex data manipulation. If an API returns thousands of unsorted rows or lacks specific filtering, APIAgent uses SQL to sort, aggregate, or join the data locally before delivering a concise answer to the AI. Performance via ‘Recipe Learning’: To solve high latency and LLM costs, the agent features Recipe Learning. It records the successful execution trace of a natural language query and saves it as a parameterized template. Security-First Architecture: The system is ‘Safe by Default,‘ operating in a read-only state. Any ‘mutating’ actions (like POST, PUT, or DELETE requests) are strictly blocked by the proxy unless a developer explicitly whitelists them in the YAML configuration file. Check out the PR Here. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Agoda Open Sources APIAgent to Convert Any REST pr GraphQL API into an MCP Server with Zero Code appeared first on MarkTechPost.

Agoda Open Sources APIAgent to Convert Any REST pr GraphQL API into an MCP Server with Zero Code Leggi l'articolo »

AI, Committee, Notizie, Uncategorized

The curious case of the disappearing Lamborghinis

When Sam Zahr first saw the gray Rolls-Royce Dawn convertible with orange interior and orange roof, he knew he’d found a perfect addition to his fleet. “It was very appealing to our clientele,” he told me. As the director of operations at Dream Luxury Rental, he outfits customers in the Detroit area looking to ride in style to a wedding, a graduation, or any other event with high-end vehicles—Rolls-Royces, Lamborghinis, Bentleys, Mercedes G-Wagons, and more. But before he could rent out the Rolls, Zahr needed to get the car to Detroit from Miami, where he bought it from a used-car dealer.  His team posted the convertible on Central Dispatch, an online marketplace that’s popular among car dealers, manufacturers, and owners who want to arrange vehicle shipments. It’s not too complicated, at least in theory: A typical listing includes the type of vehicle, zip codes of the origin and destination, dates for pickup and delivery, and the fee. Anyone with a Central Dispatch account can see the job, and an individual carrier or transport broker who wants it can call the number on the listing. Zahr’s team got a call from a transport company that wanted the job. They agreed on the price and scheduled pickup for January 17, 2025. Zahr watched from a few feet away as the car was loaded into an enclosed trailer. He expected the vehicle to arrive in Detroit just a few days later—by January 21.  But it never showed up. Zahr called a contact at the transport company to ask what happened.  “He’s like, I don’t know what you’re talking about.”  Zahr told me his contact angrily told him they mostly ship Coca-Cola products, not luxury cars. “He was yelling and screaming about it,” Zahr said. Over the years, people have broken into his business to steal cars, or they’ve rented them out and never come back. But until this day, he’d never had a car simply disappear during shipping. He’d expected no trouble this time around, especially since he’d used Central Dispatch—“a legit platform that everyone uses to transport cars,” he said.  “That’s the scary part about it, you know?” Wreaking havoc Zahr had unwittingly been caught up in a new and growing type of organized criminal enterprise: vehicle transport fraud and theft. Crooks use email phishing, fraudulent paperwork, and other tactics to impersonate legitimate transport companies and get hired to deliver a luxury vehicle. They divert the shipment away from its intended destination and then use a mix of technology, computer skills, and old-school chop shop techniques to erase traces of the vehicle’s original ownership and registration. These vehicles can be retitled and resold in the US or loaded into a shipping container and sent to an overseas buyer. In some cases, the car has been resold or is out of the country by the time the rightful owner even realizes it’s missing. “Criminals have learned that stealing cars via the web portals has become extremely easy, and when I say easy—it’s become seamless,” says Steven Yariv, the CEO of Dealers Choice Auto Transport of West Palm Beach, Florida, one of the country’s largest luxury-vehicle transport brokers. Individual cases have received media coverage thanks to the high value of the stolen cars and the fact that some belong to professional athletes and other celebrities. In late 2024, a Lamborghini Huracán belonging to Colorado Rockies third baseman Kris Bryant went missing en route to his home in Las Vegas; R&B singer Ray J told TMZ the same year that two Mercedes Maybachs never arrived in New York as planned; and last fall, NBA Hall of Famer Shaquille O’Neal had a $180,000 custom Range Rover stolen when the transport company hired to move the vehicle was hacked. “They’re saying they think it’s probably in Dubai by now, to be honest,” an employee of the company that customized the SUV told Shaq in a YouTube video. “Criminals have learned that stealing cars via the web portals has become extremely easy, and when I say easy—it’s become seamless.” Steven Yariv, CEO, Dealers Choice Auto Transport of West Palm Beach, Florida But the nationwide epidemic of vehicle transport fraud and theft has remained under the radar, even as it’s rocked the industry over the past two years. MIT Technology Review identified more than a dozen cases involving high-end vehicles, obtained court records, and spoke to law enforcement, brokers, drivers, and victims in multiple states to reveal how transport fraud is wreaking havoc across the country. RICHARD CHANCE It’s challenging to quantify the scale of this type of crime, since there isn’t a single entity or association that tracks it. Still, these law enforcement officials and brokers, as well as the country’s biggest online car-transport marketplaces, acknowledge that fraud and theft are on the rise.  When I spoke with him in August, Yariv estimated that around 8,000 exotic and high-end cars had been stolen since the spring of 2024, resulting in over $1 billion in losses. “You’re talking 30 cars a day [on] average is gone,” he said. Multiple state and local law enforcement officials told MIT Technology Review that the number is plausible. (The FBI did not respond to a request for an interview.) “It doesn’t surprise me,” said J.D. Decker, chief of the Nevada Department of Motor Vehicles’ police division and chair of the fraud subcommittee for the American Association of Motor Vehicle Administrators. “It’s a huge business.” Data from the National Insurance Crime Bureau (NICB), a nonprofit that works with law enforcement and the insurance industry to investigate insurance fraud and related crimes, provides further evidence of this crime wave. NICB tracks both car theft and cargo theft, a broad category that refers to goods, money, or baggage that is stolen while part of a commercial shipment; the category also covers cases in which a vehicle is stolen via a diverted transport truck or a purloined car is loaded into a shipping container. NICB’s statistics about car theft show that it has declined following an increase

The curious case of the disappearing Lamborghinis Leggi l'articolo »

We use cookies to improve your experience and performance on our website. You can learn more at Politica sulla privacy and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
it_IT