YouZum

Actualités

AI, Committee, Actualités, Uncategorized

To Retrieve or To Think? An Agentic Approach for Context Evolution

arXiv:2601.08747v1 Announce Type: new Abstract: Current context augmentation methods, such as retrieval-augmented generation, are essential for solving knowledge-intensive reasoning tasks.However, they typically adhere to a rigid, brute-force strategy that executes retrieval at every step. This indiscriminate approach not only incurs unnecessary computational costs but also degrades performance by saturating the context with irrelevant noise. To address these limitations, we introduce Agentic Context Evolution (ACE), a framework inspired by human metacognition that dynamically determines whether to seek new evidence or reason with existing knowledge. ACE employs a central orchestrator agent to make decisions strategically via majority voting.It aims to alternate between activating a retriever agent for external retrieval and a reasoner agent for internal analysis and refinement. By eliminating redundant retrieval steps, ACE maintains a concise and evolved context. Extensive experiments on challenging multi-hop QA benchmarks demonstrate that ACE significantly outperforms competitive baselines in accuracy while achieving efficient token consumption.Our work provides valuable insights into advancing context-evolved generation for complex, knowledge-intensive tasks.

To Retrieve or To Think? An Agentic Approach for Context Evolution Lire l’article »

AI, Committee, Actualités, Uncategorized

Spatial Context Improves the Integration of Text with Remote Sensing for Mapping Environmental Variables

arXiv:2601.08750v1 Announce Type: new Abstract: Recent developments in natural language processing highlight text as an emerging data source for ecology. Textual resources carry unique information that can be used in complementarity with geospatial data sources, thus providing insights at the local scale into environmental conditions and properties hidden from more traditional data sources. Leveraging textual information in a spatial context presents several challenges. First, the contribution of textual data remains poorly defined in an ecological context, and it is unclear for which tasks it should be incorporated. Unlike ubiquitous satellite imagery or environmental covariates, the availability of textual data is sparse and irregular; its integration with geospatial data is not straightforward. In response to these challenges, this work proposes an attention-based approach that combines aerial imagery and geolocated text within a spatial neighbourhood, i.e. integrating contributions from several nearby observations. Our approach combines vision and text representations with a geolocation encoding, with an attention-based module that dynamically selects spatial neighbours that are useful for predictive tasks.The proposed approach is applied to the EcoWikiRS dataset, which combines high-resolution aerial imagery with sentences extracted from Wikipedia describing local environmental conditions across Switzerland. Our model is evaluated on the task of predicting 103 environmental variables from the SWECO25 data cube. Our approach consistently outperforms single-location or unimodal, i.e. image-only or text-only, baselines. When analysing variables by thematic groups, results show a significant improvement in performance for climatic, edaphic, population and land use/land cover variables, underscoring the benefit of including the spatial context when combining text and image data.

Spatial Context Improves the Integration of Text with Remote Sensing for Mapping Environmental Variables Lire l’article »

AI, Committee, Actualités, Uncategorized

SwiftMem: Fast Agentic Memory via Query-aware Indexing

arXiv:2601.08160v1 Announce Type: new Abstract: Agentic memory systems have become critical for enabling LLM agents to maintain long-term context and retrieve relevant information efficiently. However, existing memory frameworks suffer from a fundamental limitation: they perform exhaustive retrieval across the entire storage layer regardless of query characteristics. This brute-force approach creates severe latency bottlenecks as memory grows, hindering real-time agent interactions. We propose SwiftMem, a query-aware agentic memory system that achieves sub-linear retrieval through specialized indexing over temporal and semantic dimensions. Our temporal index enables logarithmic-time range queries for time-sensitive retrieval, while the semantic DAG-Tag index maps queries to relevant topics through hierarchical tag structures. To address memory fragmentation during growth, we introduce an embedding-tag co-consolidation mechanism that reorganizes storage based on semantic clusters to improve cache locality. Experiments on LoCoMo and LongMemEval benchmarks demonstrate that SwiftMem achieves 47$times$ faster search compared to state-of-the-art baselines while maintaining competitive accuracy, enabling practical deployment of memory-augmented LLM agents.

SwiftMem: Fast Agentic Memory via Query-aware Indexing Lire l’article »

AI, Committee, Actualités, Uncategorized

Lessons from the Field: An Adaptable Lifecycle Approach to Applied Dialogue Summarization

arXiv:2601.08682v1 Announce Type: new Abstract: Summarization of multi-party dialogues is a critical capability in industry, enhancing knowledge transfer and operational effectiveness across many domains. However, automatically generating high-quality summaries is challenging, as the ideal summary must satisfy a set of complex, multi-faceted requirements. While summarization has received immense attention in research, prior work has primarily utilized static datasets and benchmarks, a condition rare in practical scenarios where requirements inevitably evolve. In this work, we present an industry case study on developing an agentic system to summarize multi-party interactions. We share practical insights spanning the full development lifecycle to guide practitioners in building reliable, adaptable summarization systems, as well as to inform future research, covering: 1) robust methods for evaluation despite evolving requirements and task subjectivity, 2) component-wise optimization enabled by the task decomposition inherent in an agentic architecture, 3) the impact of upstream data bottlenecks, and 4) the realities of vendor lock-in due to the poor transferability of LLM prompts.

Lessons from the Field: An Adaptable Lifecycle Approach to Applied Dialogue Summarization Lire l’article »

AI, Committee, Actualités, Uncategorized

Google AI Releases MedGemma-1.5: The Latest Update to their Open Medical AI Models for Developers

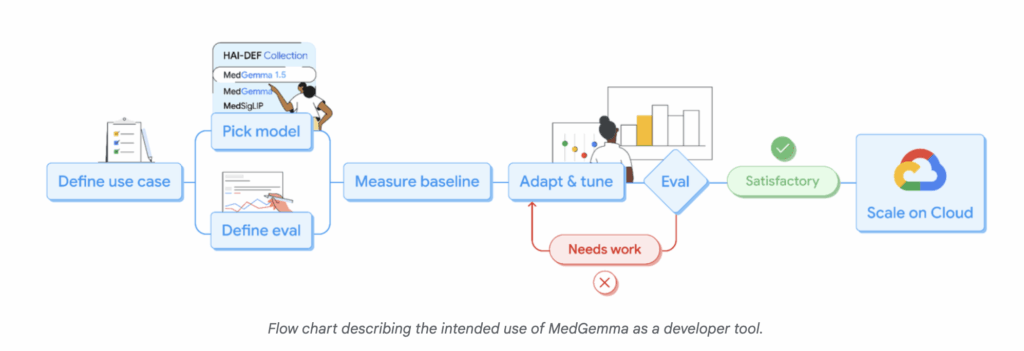
Google Research has expanded its Health AI Developer Foundations program (HAI-DEF) with the release of MedGemma-1.5. The model is released as open starting points for developers who want to build medical imaging, text and speech systems and then adapt them to local workflows and regulations. https://research.google/blog/next-generation-medical-image-interpretation-with-medgemma-15-and-medical-speech-to-text-with-medasr/ MedGemma 1.5, small multimodal model for real clinical data MedGemma is a family of medical generative models built on Gemma. The new release, MedGemma-1.5-4B, targets developers who need a compact model that can still handle real clinical data. The previous MedGemma-1-27B model remains available for more demanding text heavy use cases. MedGemma-1.5-4B is multimodal. It accepts text, two dimensional images, high dimensional volumes and whole slide pathology images. The model is part of the Health AI Developer Foundations program so it is intended as a base to fine tune, not a ready made diagnostic device. https://research.google/blog/next-generation-medical-image-interpretation-with-medgemma-15-and-medical-speech-to-text-with-medasr/ Support for high dimensional CT, MRI and pathology A major change in MedGemma-1.5 is support for high dimensional imaging. The model can process three dimensional CT and MRI volumes as sets of slices together with a natural language prompt. It can also process large histopathology slides by working over patches extracted from the slide. On internal benchmarks, MedGemma-1.5 improves disease related CT findings from 58% to 61% accuracy and MRI disease findings from 51% to 65% accuracy when averaged over findings. For histopathology, the ROUGE L score on single slide cases increases from 0.02 to 0.49. This matches the 0.498 ROUGE L score of the task specific PolyPath model. https://research.google/blog/next-generation-medical-image-interpretation-with-medgemma-15-and-medical-speech-to-text-with-medasr/ Imaging and report extraction benchmarks MedGemma-1.5 also improves several benchmarks that are closer to production workflows. On the Chest ImaGenome benchmark for anatomical localization in chest X rays, it improves intersection over union from 3% to 38%. On the MS-CXR-T benchmark for longitudinal chest X-ray comparison, macro-accuracy increases from 61% to 66%. Across internal single image benchmarks that cover chest radiography, dermatology, histopathology and ophthalmology, average accuracy goes from 59% to 62%t. These are simple single image tasks, useful as sanity checks during domain adaptation. MedGemma-1.5 also targets document extraction. On medical laboratory reports, the model improves macro F1 from 60% to 78% when extracting lab type, value and units. For developers this means less custom rule based parsing for semi structured PDF or text reports. Applications deployed on Google Cloud can now work directly with DICOM, which is the standard file format used in radiology. This removes the need for a custom preprocessor for many hospital systems. https://research.google/blog/next-generation-medical-image-interpretation-with-medgemma-15-and-medical-speech-to-text-with-medasr/ Medical text reasoning with MedQA and EHRQA MedGemma-1.5 is not only an imaging model. It also improves baseline performance on medical text tasks. On MedQA, a multiple choice benchmark for medical question answering, the 4B model improves accuracy from 64% to 69% relative to the previous MedGemma-1. On EHRQA, a text based electronic health record question answering benchmark, accuracy increases from 68% to 90%. These numbers matter if you plan to use MedGemma-1.5 as a backbone for tools such as chart summarization, guideline grounding or retrieval augmented generation over clinical notes. The 4B size keeps fine tuning and serving cost at a practical level. MedASR, a domain tuned speech recognition model Clinical workflows contain a large amount of dictated speech. MedASR is the new medical automated speech recognition model released together with MedGemma-1.5. MedASR uses a Conformer based architecture that is pre trained and fine tuned for clinical audio. It targets tasks such as chest X-ray dictation, radiology reports and general medical notes. The model is available through the same Health AI Developer Foundations channel on Vertex AI and on Hugging Face. In evaluations against Whisper-large-v3, a general ASR model, MedASR reduces word error rate for chest X-ray dictation from 12.5% to 5.2%. That corresponds to 58% fewer transcription errors. On a broader internal medical dictation benchmark, MedASR reaches 5.2% word error rate while Whisper-large-v3 has 28.2%, which corresponds to 82% fewer errors. Key Takeaways MedGemma-1.5-4B is a compact multimodal medical model that handles text, 2D images, 3D CT and MRI volumes and whole slide pathology, released as part of the Health AI Developer Foundations program for adaptation to local use cases. On imaging benchmarks, MedGemma-1.5 improves CT disease findings from 58% to 61%, MRI disease findings from 51% to 65%, and histopathology ROUGE-L from 0.02 to 0.49, matching the PolyPath model performance. For downstream clinical style tasks, MedGemma-1.5 increases Chest ImaGenome intersection over union from 3% to 38%, MS-CXR-T macro accuracy from 61%t to 66% and lab report extraction macro F1 from 60% to 78% while keeping model size at 4B parameters. MedGemma-1.5 also strengthens text reasoning, raising MedQA accuracy from 64% to 69% and EHRQA accuracy from 68% to 90%, which makes it suitable as a backbone for chart summarization and EHR question answering systems. MedASR, a Conformer based medical ASR model in the same program, cuts word error rate on chest X-ray dictation from 12.5% to 5.2% and on a broad medical dictation benchmark from 28.2% to 5.2% compared to Whisper-large-v3, providing a domain tuned speech front end for MedGemma centered workflows. Check out the Model Weights and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 100k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google AI Releases MedGemma-1.5: The Latest Update to their Open Medical AI Models for Developers appeared first on MarkTechPost.

Google AI Releases MedGemma-1.5: The Latest Update to their Open Medical AI Models for Developers Lire l’article »

AI, Committee, Actualités, Uncategorized

The Confidence Trap: Gender Bias and Predictive Certainty in LLMs

arXiv:2601.07806v1 Announce Type: new Abstract: The increased use of Large Language Models (LLMs) in sensitive domains leads to growing interest in how their confidence scores correspond to fairness and bias. This study examines the alignment between LLM-predicted confidence and human-annotated bias judgments. Focusing on gender bias, the research investigates probability confidence calibration in contexts involving gendered pronoun resolution. The goal is to evaluate if calibration metrics based on predicted confidence scores effectively capture fairness-related disparities in LLMs. The results show that, among the six state-of-the-art models, Gemma-2 demonstrates the worst calibration according to the gender bias benchmark. The primary contribution of this work is a fairness-aware evaluation of LLMs’ confidence calibration, offering guidance for ethical deployment. In addition, we introduce a new calibration metric, Gender-ECE, designed to measure gender disparities in resolution tasks.

The Confidence Trap: Gender Bias and Predictive Certainty in LLMs Lire l’article »

AI, Committee, Actualités, Uncategorized

Doing More with Less: Data Augmentation for Sudanese Dialect Automatic Speech Recognition

arXiv:2601.06802v1 Announce Type: new Abstract: Although many Automatic Speech Recognition (ASR) systems have been developed for Modern Standard Arabic (MSA) and Dialectal Arabic (DA), few studies have focused on dialect-specific implementations, particularly for low-resource Arabic dialects such as Sudanese. This paper presents a comprehensive study of data augmentation techniques for fine-tuning OpenAI Whisper models and establishes the first benchmark for the Sudanese dialect. Two augmentation strategies are investigated: (1) self-training with pseudo-labels generated from unlabeled speech, and (2) TTS-based augmentation using synthetic speech from the Klaam TTS system. The best-performing model, Whisper-Medium fine-tuned with combined self-training and TTS augmentation (28.4 hours), achieves a Word Error Rate (WER) of 57.1% on the evaluation set and 51.6% on an out-of-domain holdout set substantially outperforming zero-shot multilingual Whisper (78.8% WER) and MSA-specialized Arabic models (73.8-123% WER). All experiments used low-cost resources (Kaggle free tier and Lightning.ai trial), demonstrating that strategic data augmentation can overcome resource limitations for low-resource dialects and provide a practical roadmap for developing ASR systems for low-resource Arabic dialects and other marginalized language varieties. The models, evaluation benchmarks, and reproducible training pipelines are publicly released to facilitate future research on low-resource Arabic ASR.

Doing More with Less: Data Augmentation for Sudanese Dialect Automatic Speech Recognition Lire l’article »

AI, Committee, Actualités, Uncategorized

Generative Digital Twins: Vision-Language Simulation Models for Executable Industrial Systems

arXiv:2512.20387v3 Announce Type: replace-cross Abstract: We propose a Vision-Language Simulation Model (VLSM) that unifies visual and textual understanding to synthesize executable FlexScript from layout sketches and natural-language prompts, enabling cross-modal reasoning for industrial simulation systems. To support this new paradigm, the study constructs the first large-scale dataset for generative digital twins, comprising over 120,000 prompt-sketch-code triplets that enable multimodal learning between textual descriptions, spatial structures, and simulation logic. In parallel, three novel evaluation metrics, Structural Validity Rate (SVR), Parameter Match Rate (PMR), and Execution Success Rate (ESR), are proposed specifically for this task to comprehensively evaluate structural integrity, parameter fidelity, and simulator executability. Through systematic ablation across vision encoders, connectors, and code-pretrained language backbones, the proposed models achieve near-perfect structural accuracy and high execution robustness. This work establishes a foundation for generative digital twins that integrate visual reasoning and language understanding into executable industrial simulation systems. Project page: https://danielhsu2014.github.io/GDT-VLSM-project/

Generative Digital Twins: Vision-Language Simulation Models for Executable Industrial Systems Lire l’article »

AI, Committee, Actualités, Uncategorized

Disco-RAG: Discourse-Aware Retrieval-Augmented Generation

arXiv:2601.04377v2 Announce Type: replace Abstract: Retrieval-Augmented Generation (RAG) has emerged as an important means of enhancing the performance of large language models (LLMs) in knowledge-intensive tasks. However, most existing RAG strategies treat retrieved passages in a flat and unstructured way, which prevents the model from capturing structural cues and constrains its ability to synthesize knowledge from dispersed evidence across documents. To overcome these limitations, we propose Disco-RAG, a discourse-aware framework that explicitly injects discourse signals into the generation process. Our method constructs intra-chunk discourse trees to capture local hierarchies and builds inter-chunk rhetorical graphs to model cross-passage coherence. These structures are jointly integrated into a planning blueprint that conditions the generation. Experiments on question answering and long-document summarization benchmarks show the efficacy of our approach. Disco-RAG achieves state-of-the-art results on the benchmarks without fine-tuning. These findings underscore the important role of discourse structure in advancing RAG systems.

Disco-RAG: Discourse-Aware Retrieval-Augmented Generation Lire l’article »

AI, Committee, Actualités, Uncategorized

From RLHF to Direct Alignment: A Theoretical Unification of Preference Learning for Large Language Models

arXiv:2601.06108v1 Announce Type: cross Abstract: Aligning large language models (LLMs) with human preferences has become essential for safe and beneficial AI deployment. While Reinforcement Learning from Human Feedback (RLHF) established the dominant paradigm, a proliferation of alternatives — Direct Preference Optimization (DPO), Identity Preference Optimization (IPO), Kahneman-Tversky Optimization (KTO), Simple Preference Optimization (SimPO), and many others — has left practitioners without clear guidance on method selection. This survey provides a textit{theoretical unification} of preference learning methods, revealing that the apparent diversity reduces to principled choices along three orthogonal axes: textbf{(I) Preference Model} (what likelihood model underlies the objective), textbf{(II) Regularization Mechanism} (how deviation from reference policies is controlled), and textbf{(III) Data Distribution} (online vs. offline learning and coverage requirements). We formalize each axis with precise definitions and theorems, establishing key results including the coverage separation between online and offline methods, scaling laws for reward overoptimization, and conditions under which direct alignment methods fail. Our analysis reveals that failure modes — length hacking, mode collapse, likelihood displacement — arise from specific, predictable combinations of design choices. We synthesize empirical findings across 50+ papers and provide a practitioner’s decision guide for method selection. The framework transforms preference learning from an empirical art into a theoretically grounded discipline.

From RLHF to Direct Alignment: A Theoretical Unification of Preference Learning for Large Language Models Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR