YouZum

Actualités

AI, Committee, Actualités, Uncategorized

How much wildfire prevention is too much?

The race to prevent the worst wildfires has been an increasingly high-tech one. Companies are proposing AI fire detection systems and drones that can stamp out early blazes. And now, one Canadian startup says it’s going after lightning. Lightning-sparked fires can be a big deal: The Canadian wildfires of 2023 generated nearly 500 million metric tons of carbon emissions, and lightning-started fires burned 93% of the area affected. Skyward Wildfire claims that it can stop wildfires before they even start by preventing lightning strikes. It’s a wild promise, and one that my colleague James Temple dug into for his most recent story. (You should read the whole thing; there’s a ton of fascinating history and quirky science.) As James points out in his story, there’s plenty of uncertainty about just how well this would work and under what conditions. But I was left with another lingering question: If we can prevent lightning-sparked fires, should we? I can’t help myself, so let’s take just a moment to talk about how this lightning prevention method supposedly works. Basically, lightning is static discharge—virtually the same thing as when you rub your socks on a carpet and then touch a doorknob, as James puts it. When you shuffle across a rug, the friction causes electrons to jump around, so ions build up and an electric field forms. In the case of lightning, it’s snowflakes and tiny ice pellets called graupel rubbing together. They get separated by updrafts, building up a charge difference, and eventually cause an electrostatic discharge—lightning. Starting in about the 1950s, researchers started to wonder if they might be able to prevent lightning strikes. Some came up with the idea of using metallic chaff, fiberglass strands coated with aluminum. (The military was already using the material to disrupt radar signals.) The idea is that the chaff can act as a conductor, reducing the buildup of static electricity that would otherwise result in a lightning strike. The theory is sound enough, but results to date have been mixed. Some research suggests you might need high concentrations of chaff to prevent lightning effectively. Some of the early studies that tested the technique were small. And there’s not much information available from Skyward Wildfire about its efforts, as the company hasn’t released data from field trials or published any peer-reviewed papers that we could find.  Even if this method really can work to stop lightning, should we use it? Lightning-caused fires could be a growing problem with climate change. Some research has shown that they have substantially increased in the Arctic boreal region, where the planet is warming fastest. But fire isn’t an inherently bad thing—many ecosystems evolved to burn. Some of the worst wildfires we see today result from a combination of climate-fueled conditions with policies that have allowed fuel to build up so that when fires do start, they burn out of control. Some experts agree that techniques like Skyward’s would need to be used judiciously. “So even if we have all of the technical skills to prevent lightning-ignited wildfires, there really still needs to be work on when/where to prevent fires so we don’t exacerbate the fuel accumulation problem,” said Phillip Stepanian, a technical staff member at MIT Lincoln Laboratory’s air traffic control and weather systems group, in an email to James. We also know that practices like prescribed burns can do a lot to reduce the risk of extreme fires—if we allow them and pay for them. The company says it wouldn’t aim to stop all lightning or all wildfires. “We do not intend to eliminate all wildfires and support prescribed and cultural burning, natural fire regimes, and proactive forest management,” said Nicholas Harterre, who oversees government partnerships at Skyward, in an email to James. Rather, the company aims to reduce the likelihood of ignition on a limited number of extreme-risk days, Harterre said. Some early responses to this story say that technological fixes for fires are missing the point entirely. Many such solutions “fundamentally misunderstand the problem,” as Daniel Swain, a climate scientist at the University of California Agriculture and Natural Resources, put it in a comment about the story on LinkedIn. That problem isn’t the existence of fire, Swain continues, but its increasing intensity, and its intersection with society because of human-caused factors. “Preventing ignitions doesn’t actually address any of the causes of increasingly destructive wildfires,” he adds. It’s hard to imagine that exploring more firefighting tools is a bad idea. But to me it seems both essential and quite difficult to suss out which techniques are worth deploying, and how they could be used without putting us in even more potential danger.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here.

How much wildfire prevention is too much? Lire l’article »
AI, Committee, Actualités, Uncategorized

Link Prediction for Event Logs in the Process Industry

arXiv:2508.09096v2 Announce Type: replace Abstract: In the era of graph-based retrieval-augmented generation (RAG), link prediction is a significant preprocessing step for improving the quality of fragmented or incomplete domain-specific data for the graph retrieval. Knowledge management in the process industry uses RAG-based applications to optimize operations, ensure safety, and facilitate continuous improvement by effectively leveraging operational data and past insights. A key challenge in this domain is the fragmented nature of event logs in shift books, where related records are often kept separate, even though they belong to a single event or process. This fragmentation hinders the recommendation of previously implemented solutions to users, which is crucial in the timely problem-solving at live production sites. To address this problem, we develop a record linking (RL) model, which we define as a cross-document coreference resolution (CDCR) task. RL adapts the task definition of CDCR and combines two state-of-the-art CDCR models with the principles of natural language inference (NLI) and semantic text similarity (STS) to perform link prediction. The evaluation shows that our RL model outperformed the best versions of our baselines, i.e., NLP and STS, by 28% (11.43 p) and 27.4% (11.21 p), respectively. Our work demonstrates that common NLP tasks can be combined and adapted to a domain-specific setting of the German process industry, improving data quality and connectivity in shift logs.

Link Prediction for Event Logs in the Process Industry Lire l’article »

AI, Committee, Actualités, Uncategorized

ACE-Brain-0: Spatial Intelligence as a Shared Scaffold for Universal Embodiments

arXiv:2603.03198v1 Announce Type: cross Abstract: Universal embodied intelligence demands robust generalization across heterogeneous embodiments, such as autonomous driving, robotics, and unmanned aerial vehicles (UAVs). However, existing embodied brain in training a unified model over diverse embodiments frequently triggers long-tail data, gradient interference, and catastrophic forgetting, making it notoriously difficult to balance universal generalization with domain-specific proficiency. In this report, we introduce ACE-Brain-0, a generalist foundation brain that unifies spatial reasoning, autonomous driving, and embodied manipulation within a single multimodal large language model~(MLLM). Our key insight is that spatial intelligence serves as a universal scaffold across diverse physical embodiments: although vehicles, robots, and UAVs differ drastically in morphology, they share a common need for modeling 3D mental space, making spatial cognition a natural, domain-agnostic foundation for cross-embodiment transfer. Building on this insight, we propose the Scaffold-Specialize-Reconcile~(SSR) paradigm, which first establishes a shared spatial foundation, then cultivates domain-specialized experts, and finally harmonizes them through data-free model merging. Furthermore, we adopt Group Relative Policy Optimization~(GRPO) to strengthen the model’s comprehensive capability. Extensive experiments demonstrate that ACE-Brain-0 achieves competitive and even state-of-the-art performance across 24 spatial and embodiment-related benchmarks.

ACE-Brain-0: Spatial Intelligence as a Shared Scaffold for Universal Embodiments Lire l’article »

AI, Committee, Actualités, Uncategorized

Faster, Cheaper, More Accurate: Specialised Knowledge Tracing Models Outperform LLMs

arXiv:2603.02830v1 Announce Type: new Abstract: Predicting future student responses to questions is particularly valuable for educational learning platforms where it enables effective interventions. One of the key approaches to do this has been through the use of knowledge tracing (KT) models. These are small, domain-specific, temporal models trained on student question-response data. KT models are optimised for high accuracy on specific educational domains and have fast inference and scalable deployments. The rise of Large Language Models (LLMs) motivates us to ask the following questions: (1) How well can LLMs perform at predicting students’ future responses to questions? (2) Are LLMs scalable for this domain? (3) How do LLMs compare to KT models on this domain-specific task? In this paper, we compare multiple LLMs and KT models across predictive performance, deployment cost, and inference speed to answer the above questions. We show that KT models outperform LLMs with respect to accuracy and F1 scores on this domain-specific task. Further, we demonstrate that LLMs are orders of magnitude slower than KT models and cost orders of magnitude more to deploy. This highlights the importance of domain-specific models for education prediction tasks and the fact that current closed source LLMs should not be used as a universal solution for all tasks.

Faster, Cheaper, More Accurate: Specialised Knowledge Tracing Models Outperform LLMs Lire l’article »

AI, Committee, Actualités, Uncategorized

HSSBench: Benchmarking Humanities and Social Sciences Ability for Multimodal Large Language Models

arXiv:2506.03922v3 Announce Type: replace Abstract: Multimodal Large Language Models (MLLMs) have demonstrated significant potential to advance a broad range of domains. However, current benchmarks for evaluating MLLMs primarily emphasize general knowledge and vertical step-by-step reasoning typical of STEM disciplines, while overlooking the distinct needs and potential of the Humanities and Social Sciences (HSS). Tasks in the HSS domain require more horizontal, interdisciplinary thinking and a deep integration of knowledge across related fields, which presents unique challenges for MLLMs, particularly in linking abstract concepts with corresponding visual representations. Addressing this gap, we present HSSBench, a dedicated benchmark designed to assess the capabilities of MLLMs on HSS tasks in multiple languages, including the six official languages of the United Nations. We also introduce a novel data generation pipeline tailored for HSS scenarios, in which multiple domain experts and automated agents collaborate to generate and iteratively refine each sample. HSSBench contains over 13,000 meticulously designed samples, covering six key categories. We benchmark more than 20 mainstream MLLMs on HSSBench and demonstrate that it poses significant challenges even for state-of-the-art models. We hope that this benchmark will inspire further research into enhancing the cross-disciplinary reasoning abilities of MLLMs, especially their capacity to internalize and connect knowledge across fields.

HSSBench: Benchmarking Humanities and Social Sciences Ability for Multimodal Large Language Models Lire l’article »

AI, Committee, Actualités, Uncategorized

Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System Giving Gemma 3-4B VLAs 15-Minute Context for Complex Tasks

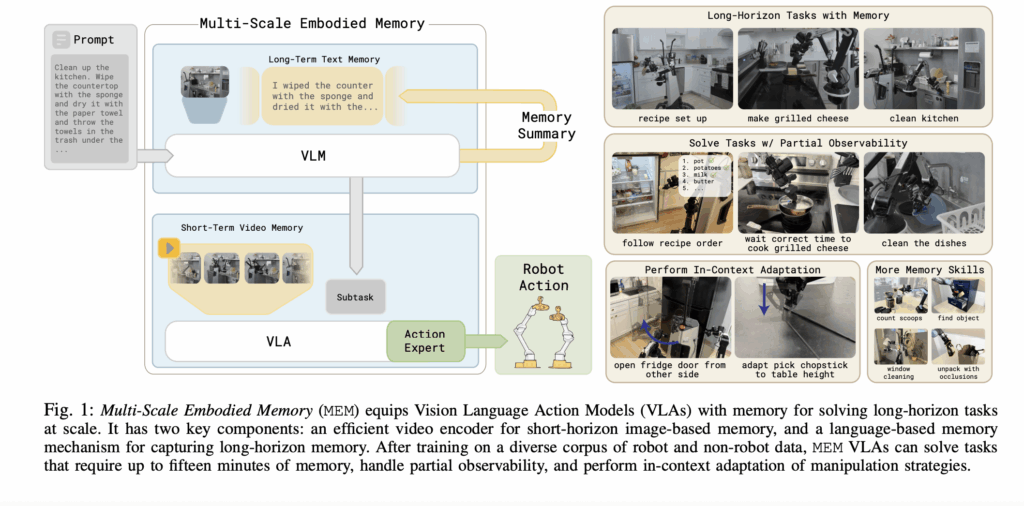
Current end-to-end robotic policies, specifically Vision-Language-Action (VLA) models, typically operate on a single observation or a very short history. This ‘lack of memory’ makes long-horizon tasks, such as cleaning a kitchen or following a complex recipe, computationally intractable or prone to failure. To address this, researchers from Physical Intelligence, Stanford, UC Berkeley, and MIT have introduced Multi-Scale Embodied Memory (MEM). https://www.pi.website/download/Mem.pdf The Dual-Scale Memory Architecture MEM factorizes robotic memory into two distinct scales to balance semantic context with real-time control constraints. (1) Short-Term Video Memory For tasks requiring fine-grained spatial awareness—like resolving self-occlusions or adapting a grasp—dense visual data is required. MEM utilizes an efficient video encoder that extends standard Vision Transformers (ViTs). To maintain real-time inference (the 380ms ‘real-time barrier’), the architecture avoids joint attention over all patches. Instead, it uses Space-Time Separable Attention, interleaving spatial attention within frames with causal-temporal attention across frames every fourth layer. The computational complexity is reduced from O(n2K2) to O(Kn2+nK2), where n is the number of spatial patches and K is the number of timesteps. By dropping tokens from past timesteps in upper layers, the model passes only the current observation’s representation to the VLA backbone, keeping the token count invariant compared to single-frame models. (2) Long-Term Language Memory To handle tasks spanning up to 15 minutes, MEM uses a language-based representation for semantic events. The system decomposes the action prediction as: $$pi(a_{t:t+H},l_{t+1},m_{t+1}|o_{t-T:t},m_{t},g) approxpi_{LL}(a_{t:t+H}|o_{t-K:t},l_{t+1},g)pi_{HL}(l_{t+1},m_{t+1}|o_{t},m_{t},g)$$ Here, a high-level policy (πHL) maintains a running language summary (mt) of past events and generates subtask instructions (lt+1) for a low-level policy (πLL). This language memory is trained using LLM-generated summaries that compress information (e.g., ‘I placed three bowls’ instead of individual attributes), reducing the risk of training-inference distribution shifts. https://www.pi.website/download/Mem.pdf Implementation and Performance The research team integrated MEM into the π0.6 VLA, which is initialized from a pre-trained Gemma 3-4B model. The model was pre-trained on a diverse mixture of robot demonstrations, vision-language tasks, and internet video data. Key Results: In-Context Adaptation: MEM enables robots to adapt manipulation strategies based on recent failures. In evaluation, this led to a +62% success rate increase in opening refrigerators with unknown hinge directions and a +11% increase in picking up chopsticks at variable heights. Long-Horizon Tasks: The model successfully performed 15-minute tasks like ‘Recipe Setup’ (retrieving ingredients from multiple locations) and ‘Kitchen Cleaning’ (washing dishes and wiping counters). Memory-less VLAs failed these tasks significantly more often. Efficiency: The video encoder allows the model to process up to 16 observation frames (spanning ~1 minute) while remaining under critical real-time inference thresholds on a single NVIDIA H100 GPU. MEM demonstrates that combining dense, short-term visual tokens with compressed, long-term language summaries allows VLAs to scale their ‘working memory’ without incurring prohibitive computational costs. Check out the Paper and Technical details. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System Giving Gemma 3-4B VLAs 15-Minute Context for Complex Tasks appeared first on MarkTechPost.

Physical Intelligence Team Unveils MEM for Robots: A Multi-Scale Memory System Giving Gemma 3-4B VLAs 15-Minute Context for Complex Tasks Lire l’article »

AI, Committee, Actualités, Uncategorized

NFT: Bridging Supervised Learning and Reinforcement Learning in Math Reasoning

arXiv:2505.18116v3 Announce Type: replace-cross Abstract: Reinforcement Learning (RL) has played a central role in the recent surge of LLMs’ math abilities by enabling self-improvement through binary verifier signals. In contrast, Supervised Learning (SL) is rarely considered for such verification-driven training, largely due to its heavy reliance on reference answers and inability to reflect on mistakes. In this work, we challenge the prevailing notion that self-improvement is exclusive to RL and propose Negative-aware Fine-Tuning (NFT) — a supervised approach that enables LLMs to reflect on their failures and improve autonomously with no external teachers. In online training, instead of throwing away self-generated negative answers, NFT constructs an implicit negative policy to model them. This implicit policy is parameterized with the same positive LLM we target to optimize on positive data, enabling direct policy optimization on all LLMs’ generations. We conduct experiments on 7B and 32B models in math reasoning tasks. Results consistently show that through the additional leverage of negative feedback, NFT significantly improves over SL baselines like Rejection sampling Fine-Tuning, matching or even surpassing leading RL algorithms like GRPO and DAPO. Furthermore, we demonstrate that NFT and GRPO are actually equivalent in strict-on-policy training, even though they originate from entirely different theoretical foundations. Our experiments and theoretical findings bridge the gap between SL and RL methods in binary-feedback learning systems.

NFT: Bridging Supervised Learning and Reinforcement Learning in Math Reasoning Lire l’article »

AI, Committee, Actualités, Uncategorized

GenDB: The Next Generation of Query Processing — Synthesized, Not Engineered

arXiv:2603.02081v1 Announce Type: cross Abstract: Traditional query processing relies on engines that are carefully optimized and engineered by many experts. However, new techniques and user requirements evolve rapidly, and existing systems often cannot keep pace. At the same time, these systems are difficult to extend due to their internal complexity, and developing new systems requires substantial engineering effort and cost. In this paper, we argue that recent advances in Large Language Models (LLMs) are starting to shape the next generation of query processing systems. We propose using LLMs to synthesize execution code for each incoming query, instead of continuously building, extending, and maintaining complex query processing engines. As a proof of concept, we present GenDB, an LLM-powered agentic system that generates instance-optimized and customized query execution code tailored to specific data, workloads, and hardware resources. We implemented an early prototype of GenDB that uses Claude Code Agent as the underlying component in the multi-agent system, and we evaluate it on OLAP workloads. We use queries from the well-known TPC-H benchmark and also construct a new benchmark designed to reduce potential data leakage from LLM training data. We compare GenDB with state-of-the-art query engines, including DuckDB, Umbra, MonetDB, ClickHouse, and PostgreSQL. GenDB achieves significantly better performance than these systems. Finally, we discuss the current limitations of GenDB and outline future extensions and related research challenges.

GenDB: The Next Generation of Query Processing — Synthesized, Not Engineered Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR