YouZum

Actualités

AI, Committee, Actualités, Uncategorized

The Download: how AI is used for military targeting, and the Pentagon’s war on Claude

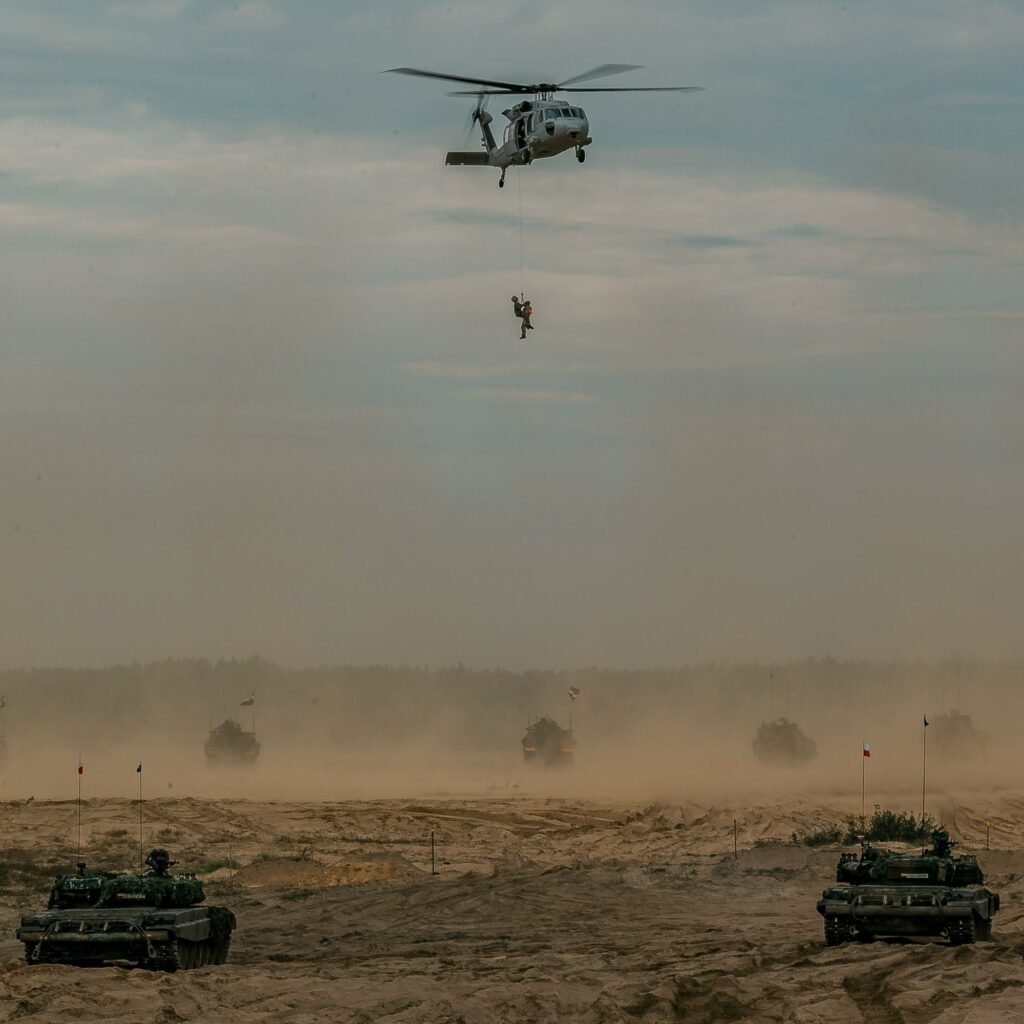
This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Defense official reveals how AI chatbots could be used for targeting decisions  The US military might use generative AI systems to rank targets and recommend which to strike first, according to a Defense Department official.  A list of possible targets could first be fed into a generative AI system that the Pentagon is fielding for classified settings. Humans might then ask the system to analyze the information and prioritize the targets. They would then be responsible for checking and evaluating the results and recommendations.  OpenAI’s ChatGPT and xAI’s Grok could soon be at the center of exactly these sorts of high-stakes military decisions. Read the full story.  —James O’Donnell  The must-reads  I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.  1 The Pentagon’s CTO claims Claude would “pollute” the defense supply chain He blamed a “policy preference” that’s baked into the model. (CNBC) + Anthropic is reeling from OpenAI’s “compromise” with the DoD. (MIT Technology Review)  2 An ex-DOGE staffer has been accused of stealing social security data Then taking the information to his new job in the IT division of a government contractor. (Wired) + He allegedly used a thumb drive to steal the data. (Washington Post)  3 Ukraine is offering its battlefield data for AI training Allies can access the data to train drones and other UAVs. (Reuters)  + Europe has a drone-filled vision for the future of war. (MIT Technology Review)   4 Meta has postponed its latest AI launch over performance issues It fell short of rival models from Google, OpenAI, and Anthropic. (NYT $) + The company’s former AI chief is betting against LLMs. (MIT Technology Review).  5 X could be breaching sanctions on Iran An account for Iran’s new supreme leader may break US rules. (Engadget) + Hacker group Handala has become the face of Iranian cyberwarfare. (Wired) + AI is turning the conflict into theater. (MIT Technology Review)   6 A landmark social media addiction trial is wrapping up It’ll decide whether the platforms are liable for harms caused to children. (The Guardian)  + AI companions are the next stage of digital addiction. (MIT Technology Review)  7 Western AI models have “failed spectacularly” on agriculture in the Global South The biggest problem? They’re not trained on local data. (Rest of World)  8 Internet outages in Moscow are sparking surging sales of pagers The disruptions have been blamed on new tests of web controls. (Bloomberg $)  9 Why is China obsessed with OpenClaw? Lobster-mania is spreading to the general public. (SCMP) + Tech-savvy “tinkerers” are cashing in on the craze. (MIT Technology Review)  10 Hollywood has soured on Silicon Valley Movies and TV shows have swapped eccentric founders for megalomaniac moguls. (NYT $)  Quote of the day  “We see a future where intelligence is a utility, like electricity or water, and people buy it from us on a meter.”  —OpenAI CEO Sam Altman makes a new pitch to investors at a BlackRock event, Gizmodo reports.  One More Thing  How the Ukraine-Russia war is reshaping the tech sector in Eastern Europe  Latvia’s annual national defense exercises took place in September and October, as the Ukraine-Russia war nears its third anniversary.GATIS INDRēVICS/ LATVIAN MINISTRY OF DEFENSE When Latvian startup Global Wolf Motors first pitched the idea of a military scooter, it was met with skepticism—and a wall of bureaucracy. Then Russia launched its full-scale invasion of Ukraine in February 2022, and everything changed.   Suddenly, Ukrainian combat units wanted any equipment they could get their hands on, and they were willing to try out ideas that might not have made the cut in peacetime.  Within weeks, the scooters were on the front line—and even behind it, being used on daring reconnaissance missions. It signaled that a new product category for companies along Ukraine’s borders had opened: civilian technologies repurposed for military needs. Read the full story.  —Peter Guest  We can still have nice things  A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.)  + A new mini magnet could slash the costs of MRIs and nuclear fusion.  + This interactive map of Earth offers new routes to facts about our planet. + Escape the news cycle with this deep dive into the power of fantasy and nature. (Big thanks to reader and MIT alum Vicki for the find!) + Reports of reading’s death are greatly exaggerated. 
The Download: how AI is used for military targeting, and the Pentagon’s war on Claude Lire l’article »

AI, Committee, Actualités, Uncategorized

EvoSchema: Towards Text-to-SQL Robustness Against Schema Evolution

arXiv:2603.10697v1 Announce Type: cross Abstract: Neural text-to-SQL models, which translate natural language questions (NLQs) into SQL queries given a database schema, have achieved remarkable performance. However, database schemas frequently evolve to meet new requirements. Such schema evolution often leads to performance degradation for models trained on static schemas. Existing work either mainly focuses on simply paraphrasing some syntactic or semantic mappings among NLQ, DB and SQL, or lacks a comprehensive and controllable way to investigate the model robustness issue under the schema evolution, which is insufficient when facing the increasingly complex and rich database schema changes in reality, especially in the LLM era. To address the challenges posed by schema evolution, we present EvoSchema, a comprehensive benchmark designed to assess and enhance the robustness of text-to-SQL systems under real-world schema changes. EvoSchema introduces a novel schema evolution taxonomy, encompassing ten perturbation types across columnlevel and table-level modifications, systematically simulating the dynamic nature of database schemas. Through EvoSchema, we conduct an in-depth evaluation spanning different open source and closed-source LLMs, revealing that table-level perturbations have a significantly greater impact on model performance compared to column-level changes. Furthermore, EvoSchema inspires the development of more resilient text-to-SQL systems, in terms of both model training and database design. The models trained on EvoSchema’s diverse schema designs can force the model to distinguish the schema difference for the same questions to avoid learning spurious patterns, which demonstrate remarkable robustness compared to those trained on unperturbed data on average. This benchmark offers valuable insights into model behavior and a path forward for designing systems capable of thriving in dynamic, real-world environments.

EvoSchema: Towards Text-to-SQL Robustness Against Schema Evolution Lire l’article »

AI, Committee, Actualités, Uncategorized

Fusing Semantic, Lexical, and Domain Perspectives for Recipe Similarity Estimation

arXiv:2603.09688v2 Announce Type: replace Abstract: This research focuses on developing advanced methods for assessing similarity between recipes by combining different sources of information and analytical approaches. We explore the semantic, lexical, and domain similarity of food recipes, evaluated through the analysis of ingredients, preparation methods, and nutritional attributes. A web-based interface was developed to allow domain experts to validate the combined similarity results. After evaluating 318 recipe pairs, experts agreed on 255 (80%). The evaluation of expert assessments enables the estimation of which similarity aspects–lexical, semantic, or nutritional–are most influential in expert decision-making. The application of these methods has broad implications in the food industry and supports the development of personalized diets, nutrition recommendations, and automated recipe generation systems.

Fusing Semantic, Lexical, and Domain Perspectives for Recipe Similarity Estimation Lire l’article »

AI, Committee, Actualités, Uncategorized

A Systematic Study of Pseudo-Relevance Feedback with LLMs

arXiv:2603.11008v1 Announce Type: cross Abstract: Pseudo-relevance feedback (PRF) methods built on large language models (LLMs) can be organized along two key design dimensions: the feedback source, which is where the feedback text is derived from and the feedback model, which is how the given feedback text is used to refine the query representation. However, the independent role that each dimension plays is unclear, as both are often entangled in empirical evaluations. In this paper, we address this gap by systematically studying how the choice of feedback source and feedback model impact PRF effectiveness through controlled experimentation. Across 13 low-resource BEIR tasks with five LLM PRF methods, our results show: (1) the choice of feedback model can play a critical role in PRF effectiveness; (2) feedback derived solely from LLM-generated text provides the most cost-effective solution; and (3) feedback derived from the corpus is most beneficial when utilizing candidate documents from a strong first-stage retriever. Together, our findings provide a better understanding of which elements in the PRF design space are most important.

A Systematic Study of Pseudo-Relevance Feedback with LLMs Lire l’article »

AI, Committee, Actualités, Uncategorized

Brutal times for the US battery industry

Just a few years ago, the battery industry was hot, hot, hot. There was a seemingly infinite number of companies popping up, with shiny new chemistries and massive fundraising rounds. My biggest problem was sifting through the pile to pick the most exciting news to cover. That tide has turned, and in 2026, what seems to be in unlimited supply isn’t battery success stories but stumbles or straight-up implosions. Companies are failing, investors are pulling back, and batteries, especially for EVs, aren’t looking so hot anymore. On Monday, Steve Levine at The Information (paywalled link) reported that 24M Technologies, a battery company founded in 2010, was shutting down and would auction off its property. The company itself has been silent, but this is the latest in a string of bad signs, and it’s a big one—at one point 24M was worth over $1 billion, and the company’s innovations could have worked with existing technology. So where does that leave the battery industry? Many buzzy battery startups in recent years have been trying to sell some new, innovative chemistry to compete with lithium-ion batteries, the status quo that powers phones, laptops, electric vehicles, and even grid storage arrays today. Think sodium-ion batteries and solid-state cells. 24M wasn’t trying to sell a departure from lithium-ion but improvements that could work with the tech. One of the company’s major innovations was its manufacturing process, which involved essentially smearing materials onto sheets of metal to form the electrodes, a simpler and potentially cheaper technique than the standard one.  The layers in the company’s batteries were thicker, which cut down on some of the inactive materials in cells and improved the energy density. That allows more energy to be stored in a smaller package, boosting the range of EVs—the company famously had a goal of a 1,000-mile battery (about 1,600 kilometers). We’re still thin on details of what exactly went down at 24M and what comes next for its tech. The company didn’t get back to my questions sent to the official press email, and nobody picked up the phone when I called. 24M cofounder and MIT professor Yet-Ming Chiang declined to speak on the record. For those who have been closely following the battery industry, more bad news isn’t too surprising. It feels as if everyone is short on money these days, and as purse strings tighten, there’s less interest in novel ideas. “It just feels like there’s not a lot of appetite for innovation,” says Kara Rodby, a technical principal at Volta Energy Technologies, a venture capital firm that focuses on the energy storage industry. Natron Energy, one of the leading sodium-ion startups in the US, shut down operations in September last year. Ample, an EV battery-swapping company, filed for bankruptcy in December 2025.   There were always going to be failures from the recent battery boom. Money was flowing to all sorts of companies, some pitching truly wild ideas. But what recent months have made clear is that the battery market is turning brutal, even for the relatively safe bets. Because 24M’s technology was designed to work into existing lithium-ion chemistry, it could have been an attractive candidate for existing battery companies to license or even acquire. “It’s a great example of something that should have been easier,” Rodby says.   The gutting of major components of the Inflation Reduction Act, key legislation in the US that provided funding and incentives for batteries and EVs, certainly hasn’t helped. The EV market in the US is cooling off, with automakers canceling EV models and slashing factory plans. There are bright spots. China’s battery industry is thriving, and its battery and EV giants are looking ever more dominant. The market for stationary energy storage is also still seeing positive signs of growth, even in the US.  But overall, it’s not looking great.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Brutal times for the US battery industry Lire l’article »

AI, Committee, Actualités, Uncategorized

LLM as a Meta-Judge: Synthetic Data for NLP Evaluation Metric Validation

arXiv:2603.09403v1 Announce Type: new Abstract: Validating evaluation metrics for NLG typically relies on expensive and time-consuming human annotations, which predominantly exist only for English datasets. We propose textit{LLM as a Meta-Judge}, a scalable framework that utilizes LLMs to generate synthetic evaluation datasets via controlled semantic degradation of real data, replacing human judgment. We validate our approach using textit{meta-correlation}, measuring the alignment between metric rankings derived from synthetic data and those from standard human benchmarks. Experiments across Machine Translation, Question Answering, and Summarization demonstrate that synthetic validation serves as a reliable proxy for human judgment, achieving meta-correlations exceeding 0.9 in multilingual QA and proves to be a viable alternative where human judgments are unavailable or too expensive to obtain. Our code and data will become publicly available upon paper acceptance.

LLM as a Meta-Judge: Synthetic Data for NLP Evaluation Metric Validation Lire l’article »

AI, Committee, Actualités, Uncategorized

Robust Training of Neural Networks at Arbitrary Precision and Sparsity

arXiv:2409.09245v3 Announce Type: replace-cross Abstract: The discontinuous operations inherent in quantization and sparsification introduce a long-standing obstacle to backpropagation, particularly in ultra-low precision and sparse regimes. While the community has long viewed quantization as unfriendly to gradient descent due to its lack of smoothness, we pinpoint-for the first time-that the key issue is the absence of a proper gradient path that allows training to learn robustness to quantization noise. The standard Straight-Through Estimator (STE) exacerbates this with its well-understood mismatch: a quantization-aware forward pass but oblivious backward pass, leading to unmanaged error and instability. We solve this by explicitly modeling quantization as additive noise, making the full forward-backward path well-defined without heuristic gradient estimation. As one natural solution, we introduce a denoising dequantization transform derived from a principled ridge regression objective, creating an explicit, corrective gradient path that makes learning robust to the noise STE bypasses. We extend this to sparsification by treating it as a special form of quantization that zeros out small values. Our unified framework trains models at arbitrary precisions and sparsity levels with off-the-shelf recipes, enabling stable A1W1 and sub-1-bit networks where others falter. It yields state-of-the-art results, mapping efficiency frontiers for modern LLMs and providing a theoretically grounded path to hyper-efficient neural networks.

Robust Training of Neural Networks at Arbitrary Precision and Sparsity Lire l’article »

AI, Committee, Actualités, Uncategorized

Investigating Gender Stereotypes in Large Language Models via Social Determinants of Health

arXiv:2603.09416v1 Announce Type: new Abstract: Large Language Models (LLMs) excel in Natural Language Processing (NLP) tasks, but they often propagate biases embedded in their training data, which is potentially impactful in sensitive domains like healthcare. While existing benchmarks evaluate biases related to individual social determinants of health (SDoH) such as gender or ethnicity, they often overlook interactions between these factors and lack context-specific assessments. This study investigates bias in LLMs by probing the relationships between gender and other SDoH in French patient records. Through a series of experiments, we found that embedded stereotypes can be probed using SDoH input and that LLMs rely on embedded stereotypes to make gendered decisions, suggesting that evaluating interactions among SDoH factors could usefully complement existing approaches to assessing LLM performance and bias.

Investigating Gender Stereotypes in Large Language Models via Social Determinants of Health Lire l’article »

AI, Committee, Actualités, Uncategorized

Fish Audio Releases Fish Audio S2: A New Generation of Expressive Text-to-Speech (TTS) with Absurdly Controllable Emotion

The landscape of Text-to-Speech (TTS) is moving away from modular pipelines toward integrated Large Audio Models (LAMs). Fish Audio’s release of S2-Pro, the flagship model within the Fish Speech ecosystem, represents a shift toward open architectures capable of high-fidelity, multi-speaker synthesis with sub-150ms latency. The release provides a framework for zero-shot voice cloning and granular emotional control using a Dual-Auto-Regressive (AR) approach. Architecture: The Dual-AR Framework and RVQ The fundamental technical distinction in Fish Audio S2-Pro is its hierarchical Dual-AR architecture. Traditional TTS models often struggle with the trade-off between sequence length and acoustic detail. S2-Pro addresses this by bifurcating the generation process into two specialized stages: a ‘Slow AR’ model and a ‘Fast AR’ model. The Slow AR Model (4B Parameters): This component operates on the time-axis. It is responsible for processing linguistic input and generating semantic tokens. By utilizing a larger parameter count (approximately 4 billion), the Slow AR model captures long-range dependencies, prosody, and the structural nuances of speech. The Fast AR Model (400M Parameters): This component processes the acoustic dimension. It predicts the residual codebooks for each semantic token. This smaller, faster model ensures that the high-frequency details of the audio—timbre, breathiness, and texture—are generated with high efficiency. This system relies on Residual Vector Quantization (RVQ). In this setup, raw audio is compressed into discrete tokens across multiple layers (codebooks). The first layer captures the primary acoustic features, while subsequent layers capture the ‘residuals’ or the remaining errors from the previous layer. This allows the model to reconstruct high-fidelity 44.1kHz audio while maintaining a manageable token count for the Transformer architecture. Emotional Control via In-Context Learning and Inline Tags Fish Audio S2-Pro achieves what the developers describe as ‘absurdly controllable emotion’ through two primary mechanisms: zero-shot in-context learning and natural language inline control. In-Context Learning (ICL): Unlike older generations of TTS that required explicit fine-tuning to mimic a specific voice, S2-Pro utilizes the Transformer’s ability to perform in-context learning. By providing a reference audio clip—ideally between 10 and 30 seconds—the model extracts the speaker’s identity and emotional state. The model treats this reference as a prefix in its context window, allowing it to continue the “sequence” in the same voice and style. Inline Control Tags: The model supports dynamic emotional transitions within a single generation pass. Because the model was trained on data containing descriptive linguistic markers, developers can insert natural language tags directly into the text prompt. For example: [whisper] I have a secret [laugh] that I cannot tell you. The model interprets these tags as instructions to modify the acoustic tokens in real-time, adjusting pitch, intensity, and rhythm without requiring a separate emotional embedding or external control vector. Performance Benchmarks and SGLang Integration Integrating TTS into real-time applications, the primary constraint is ‘Time to First Audio’ (TTFA). Fish Audio S2-Pro is optimized for a sub-150ms latency, with benchmarks on NVIDIA H200 hardware reaching approximately 100ms. Several technical optimizations contribute to this performance: SGLang and RadixAttention: S2-Pro is designed to work with SGLang, a high-performance serving framework. It utilizes RadixAttention, which allows for efficient Key-Value (KV) cache management. In a production environment where the same “master” voice prompt (reference clip) is used repeatedly, RadixAttention caches the prefix’s KV states. This eliminates the need to re-compute the reference audio for every request, significantly reducing the prefill time. Multi-Speaker Single-Pass Generation: The architecture allows for multiple speaker identities to be present within the same context window. This permits the generation of complex dialogues or multi-character narrations in a single inference call, avoiding the latency overhead of switching models or reloading weights for different speakers. Technical Implementation and Data Scaling The Fish Speech repository provides a Python-based implementation utilizing PyTorch. The model was trained on a diverse dataset comprising over 300,000 hours of multi-lingual audio. This scale is what enables the model’s robust performance across different languages and its ability to handle ‘non-verbal’ vocalizations like sighs or hesitations. The training pipeline involves: VQ-GAN Training: Training the quantizer to map audio into a discrete latent space. LLM Training: Training the Dual-AR transformers to predict those latent tokens based on text and acoustic prefixes. The VQ-GAN used in S2-Pro is specifically tuned to minimize artifacts during the decoding process, ensuring that even at high compression ratios, the reconstructed audio remains ‘transparent’ (indistinguishable from the source to the human ear). Key Takeaways Dual-AR Architecture (Slow/Fast): Unlike single-stage models, S2-Pro splits tasks between a 4B parameter ‘Slow AR’ model (for linguistic and prosodic structure) and a 400M parameter ‘Fast AR’ model (for acoustic refinement), optimizing both detail and speed. Sub-150ms Latency: Engineered for real-time conversational AI, the model achieves a Time-to-First-Audio (TTFA) of ~100ms on high-end hardware, making it suitable for live agents and interactive applications. Hierarchical RVQ Encoding: By using Residual Vector Quantization, the system compresses 44.1kHz audio into discrete tokens across multiple layers. This allows the model to reconstruct complex vocal textures—including breaths and sighs—without the computational bloat of raw waveforms. Zero-Shot In-Context Learning: Developers can clone a voice and its emotional state by providing a 10–30 second reference clip. The model treats this as a prefix, adopting the speaker’s timbre and prosody without requiring additional fine-tuning. RadixAttention & SGLang Integration: Optimized for production, S2-Pro leverages RadixAttention to cache KV states of voice prompts. This allows for nearly instant generation when using the same speaker repeatedly, drastically reducing prefill overhead. Check out Model Card and Repo. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Fish Audio Releases Fish Audio S2: A New Generation of Expressive Text-to-Speech (TTS) with Absurdly Controllable Emotion appeared first on MarkTechPost.

Fish Audio Releases Fish Audio S2: A New Generation of Expressive Text-to-Speech (TTS) with Absurdly Controllable Emotion Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR