YouZum

Committee

AI, Committee, Actualités, Uncategorized

Meet mKernel: A Multi-GPU, Multi-Node Fused Kernel Library for GPU-Driven Communication

GPU communication overhead is a measurable bottleneck in production AI workloads. According to data cited by the mKernel project, communication can consume 43.6% of the forward pass and 32% of end-to-end training time. Across popular Mixture-of-Experts (MoE) models, inter-device communication can account for up to 47% of total execution time. Researchers from UC Berkeley’s UCCL project have released mKernel, a library of persistent CUDA kernels that fuse intra-node NVLink communication, inter-node RDMA, and compute into a single kernel. The Problem: Host-Driven Communication The standard model for multi-GPU communication is host-driven: the CPU runs the control path and calls into a library like NCCL or NVSHMEM. The library issues the collective operation — an AllReduce, an AllGather, etc. — across GPUs. Compute and communication run on separate CUDA streams and overlap at kernel boundaries. The research team identifies two problems with this approach: (1) CPUs are not scaling with GPU compute. A GB300 NVL72 rack integrates 72 Blackwell Ultra GPUs and 36 Grace CPUs, delivering 720 PFLOP/s FP8/FP6, 1.44 EFLOP/s FP4 Tensor Core performance, and 130 TB/s of all-to-all intra-rack NVLink bandwidth. At those speeds, microsecond-scale host orchestration overhead — a cudaLaunchKernel call, a CPU-side “all writes done” check, an inter-stream event — shows up directly as pipeline bubbles. (2) Host-driven systems overlap compute and communication at coarse kernel boundaries. Finer-grained overlap at the tile or chunk level is not possible from the host side. The alternative is GPU-driven communication: the GPU itself triggers transfers, with communication fused into the same kernel as the compute. Most existing fused kernel libraries operate within a single node, or a single GPU. mKernel targets the multi-node case. What mKernel Does mKernel is a library of persistent CUDA kernels. Each kernel fuses intra-node NVLink communication, inter-node RDMA, and dense compute into a single kernel. Multi-GPU + multi-node, in one kernel: Both intra-node NVLink and inter-node RDMA live inside the same persistent kernel. Fine-grained intra-kernel overlap: Compute and communication overlap at tile/chunk granularity, covering both intra-node and inter-node GPU communication. Persistent kernel with SM specialization: CTAs self-assign roles: compute, intra-comm, inter-send, inter-reduce. The number of SMs dedicated to each role is tunable per shape. GPU-driven networking built on libibverbs: mKernel uses GPU-initiated RDMA writes without depending on NCCL or NVSHMEM. The communication backend is written from scratch to maximize performance and support heterogeneous networking devices. The Five Fused Kernels Kernel What it fuses Description AllGather + GEMM AllGather → GEMM Each rank holds a shard of A. While ranks gather peers’ shards over NVLink/RDMA, the local GEMM consumes tiles as soon as they arrive. GEMM + AllReduce GEMM → AllReduce Computes C = A @ B and reduces partial outputs across all ranks in one launch. Output tiles are pushed into the reduction tree the instant they’re produced. MoE Dispatch + GEMM All-to-All dispatch → grouped GEMM Routes MoE tokens to their expert ranks (intra-node NVLink + inter-node all-to-all) and runs the per-expert grouped GEMM in the same kernel. Tokens are processed as soon as they land — no staging buffer round-trip. Ring Attention Ring KV exchange → FlashAttention Sequence-parallel attention across ranks. Each step rotates a KV chunk around the ring while the local FlashAttention consumes the previously-received chunk. Compute and the ring send/recv run concurrently inside a single persistent kernel. GEMM + ReduceScatter GEMM → ReduceScatter Computes C = A @ B and reduce-scatters the output. Each output tile is reduced and forwarded to its owning rank as soon as it is produced. Evaluation Setup The research team evaluated mKernel on two 2-node × 8-H200 clusters that differ only in their inter-node fabric: Testbed Nodes × GPUs Intra-node Inter-node transport NIC AWS EFA 2 × 8 H200 NVLink AWS EFA / SRD 16 × 200 Gb/s EFA per node ConnectX-7 2 × 8 H200 NVLink InfiniBand 8 × 400 Gb/s NVIDIA ConnectX-7 per node mKernel was benchmarked against NCCL, Triton-distributed, Flux, Mercury, MagiAttention, Transformer-Engine, and ring-flash-attention. The team notes that further benchmarking at larger scale is still in progress. Backends and Requirements mKernel supports two networking backends: Backend Macro Transport Where it runs CX7 -DINTERNODE_BACKEND_IBVERBS libibverbs RC ConnectX-7 / InfiniBand / RoCE EFA -DINTERNODE_BACKEND_EFA libibverbs + efadv (SRD) AWS p5/p5e (H200, EFA) Both backends share the same host-side API and the same on-GPU kernel. Only the proxy/session implementation differs (session.h for CX7, session_efa.h for EFA). Requirements: NVIDIA Hopper GPUs (default build targets sm_90a), CUDA 12.9, Python with PyTorch. The CX7 backend requires libibverbs development headers and libraries. The EFA backend requires AWS EFA installation with libfabric, libibverbs, efadv, and EFA headers under EFA_HOME=/opt/amazon/efa by default. Marktechpost’s Visual Explainer UCCL mKernel — Multi-GPU, Multi-Node Fused Kernels Guide 01 / 07 — Overview What is mKernel? mKernel is an open-source library of persistent CUDA kernels from UC Berkeley’s UCCL project. It fuses intra-node NVLink communication, inter-node RDMA, and dense compute into a single kernel. Most existing fused kernel libraries operate within a single node or a single GPU. mKernel is designed from the start to span node boundaries. 43.6% of forward pass consumed by communication in production 47% of total execution time in popular MoE models 32% of end-to-end training time consumed by communication 02 / 07 — The Problem Why Host-Driven Communication Falls Short The standard model is host-driven: the CPU calls NCCL or NVSHMEM, which issues collective operations across GPUs. The UCCL team identifies two problems. CPUs are not scaling with GPUs. A GB300 NVL72 rack delivers 720 PFLOP/s FP8/FP6 and 1.44 EFLOP/s FP4. At those speeds, microsecond-scale overhead from cudaLaunchKernel, CPU-side sync checks, and inter-stream events shows up directly as pipeline bubbles. Overlap is too coarse. Host-driven systems overlap compute and communication only at kernel boundaries. Finer-grained overlap at the tile or chunk level is not possible from the host side. The answer: GPU-driven communication. The GPU itself triggers fine-grained transfers, fused into the same kernel as the compute. 03 / 07 — Design Four Core Design Properties 🖧 Multi-GPU + multi-node, in one kernel. Intra-node NVLink and inter-node RDMA both live
Meet mKernel: A Multi-GPU, Multi-Node Fused Kernel Library for GPU-Driven Communication Lire l’article »

AI, Committee, Actualités, Uncategorized

The Download: unlocking lithium and controlling Ebola

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. How a new extraction process could unlock the world’s lithium A new method for extracting lithium could cut costs and emissions from one of the world’s most important materials for EVs and energy storage.  The technique uses a weak acid to dissolve silicate minerals. That frees not only the lithium but also other useful materials, including alumina and silica.  “At scale, we believe this will be the lowest-cost way of sourcing lithium in the world,” says Yet-Ming Chiang, an MIT professor who co-authored a study of the process published yesterday in Science.  Startup Rock Zero is already working to commercialize the research. Read the full story on a new way to unlock the world’s lithium. —Casey Crownhart The deadly Ebola outbreak is proving difficult to control The alert was raised on May 5. Four health-care workers in the Democratic Republic of the Congo had died from an unknown illness within four days. Tests in Kinshasa revealed the culprit: the Bundibugyo virus, one of the causes of Ebola. A couple of weeks ago, an outbreak of hantavirus erupted aboard a cruise ship. Three people died, but the outbreak was kept under control. The picture for Ebola is bleaker for several reasons, including the disease itself, the available treatments, and the local environment. Find out why the outbreak is causing alarm. —Jessica Hamzelou This story is from The Spark, our weekly newsletter giving you the inside track on all things biotech. Sign up to receive it in your inbox every Thursday. How the Pope’s Magnifica Humanitas offers a template for individuals to meet the AI moment ——Father Séamus Finn, a leader in faith-based and socially responsible investing with the Oblates of Mary Immaculate, and Sister Susan Francois, assistant congregation leader and treasurer of the Sisters of St. Joseph of Peace Pope Leo XIV’s new encyclical on artificial intelligence includes a statement that warrants serious attention from technologists and policymakers: “Technology is never neutral.”  Magnifica Humanitas is a call to act with courage and solidarity as AI transforms human life, framing the choice ahead as one between the Tower of Babel and the rebuilding of our common humanity. It warns that corporations alone cannot set the direction of such a transformation. With governments slow to regulate AI, institutional investors are stepping into the gap. Here’s how they can build a better future. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Anthropic is now valued higher than OpenAIIt hit a $965 billion valuation after a new funding round. (AP News)+ Claude demand has driven annualized revenue to $47 billion. (WSJ $)+ The funding round may be Anthropic’s last before an IPO. (TechCrunch)+ What even is the AI bubble? (MIT Technology Review) 2 A Blue Origin rocket has exploded in a setback to NASA’s Moon plansNew Glenn burst into flames during testing on a Florida launchpad. (CNBC) + Blue Origin is heavily involved in NASA’s Moon base plans. (The Verge) + It also wants to compete with Elon Musk’s SpaceX. (Reuters $) 3 Adversaries are tracking US troop locations via mobile phone dataThe Pentagon has long ignored warnings of this exact threat. (Reuters $)+ The targeting uses commercially available location data. (Wired $)+ LLMs could supercharge mass surveillance. (MIT Technology Review) 4 Anthropic plans a broad rollout of Mythos AI in the coming weeksDespite concerns over its cybersecurity capabilities. (CNET)+ Claude Opus 4.8 is now out, with a promise to be more honest. (The Verge) 5 Grok oversaw a crime spree in an AI safety testModels were tasked with governing a simulated society. (Fortune)+ Grok committed 180 crimes, while Claude ruled with restraint. (Gizmodo) 6 Amazon has scrapped an AI leaderboard after worker gamingEmployees were artificially inflating usage scores. (FT $)+ We can build better AI benchmarks. (MIT Technology Review) 7 Political spending by AI and crypto groups is shifting electionsThey’ve pushed their preferred candidates closer to power. (Axios) 8 China’s tech boom is fueling a new wave of industrial tourismVisitors are touring AI labs and EV factories. (Rest of World) 9 Alibaba’s MuleRun aims to replicate the OpenClaw crazeThe AI agent platform is positioned as a safer alternative. (SCMP) 10 Mysterious changes have emerged in the Sun’s magnetic fieldThey could reshape space weather forecasts. (404 Media) Quote of the day “What Peter Thiel is doing is terrible. His settling in Argentina is even worse.” —Elisa Lilita Carrió, an Argentine politician, writes on X that Peter Thiel’s relocation to her country has angered her even more than his leadership of Palantir. One More Thing NASA, ESA, CSA, STSCI, WEBB ERO PRODUCTION TEAM How the James Webb Space Telescope broke the universe When the James Webb Space Telescope began full operations in 2022, astronomers were in awe of the flood of data that arrived. “Every hour we were looking at a galaxy or an exoplanet or star formation,” says NASA scientist Heidi Hammel. “It was like a firehose.” Since then, JWST has delivered nonstop discoveries, from distant galaxies to new planetary atmospheres. “We’re cracking open an entirely new window on the universe,” says Hammel.  Discover how JWST has transformed astronomy. —Jonathan O’Callaghan We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Kubrick fans will love this Lego recreation of Dr Strangelove.+ Here’s a fascinating explanation of why seven landlocked countries have navies.+ This mesmerizing 4K remaster of a super typhoon turns weather data into cinematic art.+ Go inside the genius of Queen with this track-by-track breakdown of “Bohemian Rhapsody.”

The Download: unlocking lithium and controlling Ebola Lire l’article »

AI, Committee, Actualités, Uncategorized

Climate tech companies are going public. What’s next?

This year, there’s been a wave of notable energy companies going public via IPO in the US. The solar and battery company Solv Energy went public in February, to the tune of $6 billion. X-energy, which is building small modular nuclear reactors, did the same in April, and its stocks surged on its first day of trading to hit a $11.5 billion market cap. Most recently, the geothermal company Fervo Energy went public in mid-May, and its market cap is now about $12.4 billion. Those are all success stories in the IPO world. And it certainly doesn’t feel like a coincidence that all these companies are racing to provide electricity in an era of rising demand (partly due to data centers). Let’s take a look at how these firms are doing, what this moment says about the grid, and what’s coming next.  Let’s start with Fervo Energy, a company we’ve covered a lot over the years that’s working to develop enhanced geothermal energy. (We included it on our 2025 list of Climate Tech Companies to Watch.) While conventional geothermal requires finding specific spots with hot rock, water, and fractures to support a power plant, Fervo essentially uses fracking techniques to create the necessary conditions. The company was founded in 2017, and it raised about $1.5 billion from investors over the years before its IPO. Fervo’s first commercial project, Cape Station in Utah, is expected to have a capacity of about 500 megawatts. The first unit is set to start generating power for customers by October and the next two units by January 2027. The new funding from the IPO could help the company scale. Fervo currently has over 600 megawatts’ worth of binding power purchase agreements. And it has leases for land that could together generate more than 40 gigawatts of electricity. (As of 2024, the entire US geothermal fleet had a capacity of just 4 gigawatts.) The company also has an eye on cutting construction and drilling costs—its Cape Station plant is expected to cost about $7 per kilowatt, which is cheaper than new nuclear power plants but over twice the expense of building a new natural-gas plant in the US.  X-energy also aims to provide reliable clean power: it’s part of the wave of next-generation nuclear companies working on small modular reactors. The company is building high-temperature gas-cooled reactors, which flow helium over self-contained pebbles of nuclear fuel. These reactors will each generate 80 megawatts of electricity, less than one-tenth the output of larger ones like Unit 4 at Plant Vogtle in Georgia, the most recent addition to the commercial nuclear fleet in the US.   X-energy also saw its IPO go well, and prices surged in trading after the initial offering. One interesting tidbit here—the company had previously planned to go public in 2023 but decided against it because of difficult market conditions. The company is still years away from demonstrating its technology in a commercial project.  You may recall a story I wrote last year about its effort to build nuclear reactors at the site of a Dow Chemical plant in Texas. The company recently received a key environmental approval for that project, though it’s still waiting for the final green light from the Nuclear Regulatory Commission to start construction. Finally, Solv Energy builds solar and energy storage projects, mostly for utilities and independent power producers. Solar and batteries are some of the cheapest and easiest technologies to add to the grid, so this one could get a lot of capacity online, quickly. The company already has 21 gigawatts’ worth of projects operational across 35 states. Many companies in the energy sector are pinning their hopes on the rapid growth in data center construction and operation. The AI boom has transformed the energy landscape, pushing electricity demand higher in a country where it’s been relatively flat for the last decade or so. Solv Energy mentioned data centers over a dozen times in documents filed with the Securities and Exchange Commission before its IPO.  And Fervo and X-energy are particularly connected to the tech giants driving AI. Google has been a longtime investor in Fervo and also pioneered what it calls its clean transition tariff with the company. Amazon is a client of X-energy as well as an investor; it reportedly owns close to 20% of the company. Fervo and X-energy are also in industries that occupy a political sweet spot. President Trump and his administration have gone after wind power and other renewables, cutting off existing support and slowing approvals for new projects. Meanwhile, geothermal and particularly nuclear power have kept favor with the federal government and enjoyed continued tax credits and grant funding. If a few big leaders cash through these IPOs, it could help investors feel more confident about supporting the energy sector, even if that money is concentrated in later-stage ventures like these rather than earlier-stage companies.  We could see other firms, particularly in nuclear and geothermal, attempt a similar route in the year ahead. A key thing to watch here will be whether Fervo and X-energy in particular can succeed in scaling up and deploying their technology. If either of these companies stumbles or misses a timeline, it could have ripple effects for those hoping to follow in these very lucrative footsteps.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Climate tech companies are going public. What’s next? Lire l’article »

AI, Committee, Actualités, Uncategorized

The AI Hype Index: AI gets booed in graduation season

It is one thing to say AI will change the world. It is another to expect the class of 2026 to applaud it. In fact, when former Google CEO Eric Schmidt told University of Arizona graduates that their task is to help shape AI, he was met with a resounding chorus of boos. “I can hear you,” he said, before conceding that fears about disappearing jobs and a broken future were “rational.” This is not exactly the message one hopes to hear while sweating under a polyester gown and tallying student loan payments. Graduates have been jeering at AI pep talks at other commencements too, including ceremonies at the University of Central Florida and Middle Tennessee State University. Still, increasingly loud skepticism hasn’t stopped OpenAI from winning court cases, raising enormous sums of money, and launching new partnerships. And AI is even earning some unlikely cheerleaders: Reese Witherspoon has warned women to embrace it or be replaced by it.

The AI Hype Index: AI gets booed in graduation season Lire l’article »

AI, Committee, Actualités, Uncategorized

Perplexity AI Open-Sources Unigram Tokenizer That Achieves 5x Lower p50 Latency Than Hugging Face tokenizers Crate

Perplexity AI’s research team reimplemented their Unigram tokenizer from scratch in Rust and open-sourced the code in pplx-garden, their inference technology repository. At production input lengths, the new encoder cuts p50 latency by roughly 5x versus the Hugging Face tokenizers crate, ~2x versus SentencePiece (C++), and ~1.5x versus IREE’s tokenizer (C), with zero steady-state heap allocations. In production, it reduced CPU utilization in Perplexity’s inference stack by 5-6x and shaved double-digit milliseconds off reranker latency. Why Tokenization Became a Bottleneck LLM inference cost is typically framed around GPU work: KV caches, attention kernels, expert routing. But smaller models, such as embedding models, classifiers, and rerankers, tell a different story. These models are two to three orders of magnitude smaller than frontier transformers. A reranker scoring hundreds of candidate documents per request is a clear example. With a small model, GPU compute often finishes in single-digit milliseconds. Every input still passes through CPU-side tokenization first. When batch sizes are large, tokenization becomes a meaningful fraction of total request latency. Perplexity’s work targets XLM-RoBERTa, a model with a 250K-token Unigram vocabulary trained with SentencePiece. Fine-tuned RoBERTa-family encoders are a common production choice for ranking, retrieval, and similarity tasks. What is Unigram Tokenization? Unigram tokenization was introduced by Kudo in 2018 and is implemented in SentencePiece. It frames segmentation as a most-probable-path problem. Each vocabulary token has a learned log-probability. The tokenizer picks the segmentation whose token scores sum to the highest value. The algorithm used to find that best path is the Viterbi algorithm, a dynamic programming technique from 1967. Byte positions form graph layers and vocabulary tokens are edges spanning a contiguous byte range. The DP recurrence iterates over byte positions and updates the best-scoring path at each position. The outer loop runs in linear time relative to input length. The inner loop walks a vocabulary trie (a prefix tree structure) at each byte position. On a 16K-token input, this inner walk executes hundreds of thousands of trie transitions. It is the hot path. What was Slow in the Hugging Face Implementation The Hugging Face tokenizers crate is the default Rust tokenizer most teams reach for. Perplexity used it as the benchmark reference. At 514 tokens (512 + BOS/EOS injection), the reference implementation had three costly patterns: Bottleneck Mechanism Measured impact Allocation per match String::from_utf8 + AHashMap lookup per trie match 7,295 allocations at 514 tokens; 299,171 at 16K Pointer chase per byte AHashMap at every trie node; 4 dependent loads per byte step Dependent-load latency dominates the hot path L2 thrashing on long inputs DP table and output buffers freshly allocated each call L2 miss rate climbs from 8% at 128 tokens to 50% at 16K Per-token allocation is constant: roughly 2 KB and ~18 allocations per token, regardless of input size. The latency problem becomes severe at longer inputs when cumulative allocations overflow the per-core L2 cache. Establishing a Baseline Before Changing the Trie Before switching the trie structure, Perplexity first isolated how much cost came from unnecessary work alone. They made a zero-allocation port of the reference: same HashMap trie, but with a caller-owned scratch struct reused across calls and token IDs stored directly in trie nodes (removing the per-match string allocation and secondary hash-map lookup). This baseline already cut p50 latency to 155 µs at 514 tokens, down from 326 µs in the reference. Instructions retired dropped 2.4x. The remaining cost was the HashMap pointer chase itself, which the next step addressed. The Three Optimizations Optimization 1: Double-Array Trie The Hugging Face trie stores children in a HashMap at every node. Each byte step requires a hash computation, two pointer dereferences, and a heap access. Perplexity replaced this with a double-array trie, the same structure used by SentencePiece and IREE, originally introduced by Aoe in 1989. A double-array trie encodes the entire trie in two flat integer arrays, base and check. A child lookup is: next = base[node] + byte, then verify check[next] == node. That is two array reads, one integer add, and one comparison, with no hashing and no pointer chasing. For XLM-RoBERTa’s 250K vocab, the whole trie fits in ~9 MB of contiguous memory. The hot working set per encode is on the order of 100 KB, which fits in L2 cache. Unlike SentencePiece and IREE, which are general-purpose libraries with lattice bookkeeping and multi-stage pipelines, Perplexity inlined the trie directly in the Viterbi loop and dropped that overhead entirely. Result at 514 tokens: p50 dropped from 155 µs (zero-allocation baseline) to 68 µs. Wall-clock fell 4.8x from the original reference. Optimization 2: Bitmap and Inline Packing The double-array trie still requires two dependent array loads per byte step: first the parent’s base offset, then the check array to confirm the transition is valid. Perplexity replaced the check array with a per-node bitmap (four 64-bit words, 32 bytes) that records which of the 256 possible bytes have valid child transitions. A bitmap lookup compiles to a single bit test against one 64-bit word. The check array is used only during trie construction and dropped from the runtime layout entirely. They also packed all four per-node fields (bitmap, base, token ID, and score) into a single 64-byte cache line, matching CPU cache line width exactly. One trie step now loads a single cache line covering the bitmap for the next-byte check, the base offset for the child slot, and the token ID and score at terminal nodes. Trade-off: trie size grows from ~9 MB to ~50 MB (780K nodes x 64 bytes). The hot working set per encode remains ~100 KB. Result at 514 tokens: Additional 4.5% wall-clock reduction. L2 accesses dropped from 4.6K to 1.8K per encode. Optimization 3: Huge Pages for the Trie At 50 MB, the trie spans roughly 12,000 virtual pages on a default Linux system using 4 KB pages. The first-level data TLB on Intel Sapphire Rapids holds 96 entries. Each Viterbi step touches a different trie node, so TLB misses accumulate. Over a 512-token encode, Perplexity estimated roughly

Perplexity AI Open-Sources Unigram Tokenizer That Achieves 5x Lower p50 Latency Than Hugging Face tokenizers Crate Lire l’article »

AI, Committee, Actualités, Uncategorized

The Download: climate tech goes public and the AI Hype Index returns

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Climate tech companies are going public. What’s next? Solar and battery company Solv Energy went public in February, hitting a $6 billion valuation. X-energy, which builds small modular nuclear reactors, followed at $11.5 billion. Then came geothermal company Fervo Energy, reaching a market cap of about $12.4 billion. All three have been IPO success stories. And it doesn’t feel like a coincidence that they’re racing to provide electricity in an era of rising demand, driven partly by data centers. What does this boom reveal about the future of the grid? And what comes next? Read the full story to find out. —Casey Crownhart This story is from The Spark, our weekly newsletter giving you the inside track on all things climate. Sign up to receive it in your inbox every Wednesday. The AI Hype Index Separating AI reality from hyped-up fiction isn’t always easy. That’s why we’ve created the AI Hype Index—a simple, at-a-glance summary of what’s shaping the industry right now. The latest edition includes billionaire road trips, students booing, made-up quotes, and too much sci-fi. See where it all landed on this month’s index. The must-reads I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology. 1 Illinois just passed what could become America’s strongest AI safety lawIt would require third-party safety audits. (Wired $)+ But it still needs the governor’s approval. (NBC News)+ The US is divided over AI regulation. (MIT Technology Review) 2 A Google engineer has been charged with insider tradingHe allegedly bet on who’d be the most-searched people of 2025 on Polymarket. (BBC)+ And used internal data to rack up more than $1.2 million in winnings. (Verge)+ He’s been charged with fraud and money laundering over the bets. (NPR) 3 ByteDance is developing custom CPUs amid a massive AI chip squeezeThe TikTok owner is struggling with severe supply shortages. (Reuters $)+ Google, Amazon, and Microsoft are also building custom CPUs. (CNBC)+ Taiwan’s “silicon shield” could be weakening. (MIT Technology Review) 4 Four tech giants have backed a clean energy push for AI data centersAmazon, Google, Meta, and Microsoft have joined the initiative. (Quartz)+ Investor Elemental Impact will deploy up to $5 million per project. (Axios) 5 Nvidia’s CEO is joining the board of Beijing’s Tsinghua UniversityHis appointment comes as Nvidia struggles to export chips to China. (FT $)+ President Xi is an alumnus of Tsinghua, aka “China’s Harvard.” (Reuters $) 6 The Trump administration is in talks to fund drone firmsOne of which counts Donald Trump Jr. as a shareholder. (WSJ $)+ Drone dominance has been described ​as a “presidential priority.” (Reuters $) 7 London has reclaimed its position as Europe’s leading tech hubIt’s overtaken Paris in new global rankings. (Euronews)+ And now sits fourth, behind the Bay Area, New York and Boston. (Reuters $) 8 OpenAI and Anthropic disagree over AI’s impact on jobsAnthropic is emphasizing the risks, while OpenAI is sounding rosier. (Axios)+ The AI jobs hysteria needs a reality check. (MIT Technology Review) 9 Researchers claim to have achieved perfect randomness for the first timeThanks to entangled quantum chips. (Interesting Engineering)+ The milestone could lead to better cybersecurity. (Scientific American) 10 Embryo organoids are showing why many pregnancies failThey’ve led to improvements in IVF and pregnancy treatments. (New Scientist $)+ New tech is transforming reproductive medicine. (MIT Technology Review) Quote of the day “How can we be happy about Google coming? We’ll all be scattered. It feels very sad.” —Pyla Kondamma, a 42-year-old in Visakhapatnam, India, tells the Wall Street Journal her concerns about Google building data centers in her city. One More Thing NICO ORTEGA Why venture capital doesn’t build the things we really need Venture capital has been the engine of US innovation for years. This largely white, largely male corner of finance has backed software companies that grow fast—but generate large amounts of money for a shrinking number of Americans. It’s also creating fewer jobs for ordinary people. And recently, venture capitalists have struggled to find ideas that fit their preferred pattern. Here’s what’s going wrong with the funding model that made Silicon Valley a global hub. —Elizabeth MacBride We can still have nice things A place for comfort, fun, and distraction to brighten up your day. (Got any ideas? Drop me a line.) + Never miss a great movie again with this worldwide release tracker.+ These quirky word puzzles use emoji hints to help you find answers.+ The digital museum of plugs and sockets is a treasure trove of global connectors.+ Michael Jackson’s “Smooth Criminal” becomes a Bach-style fugue played on classical guitar.

The Download: climate tech goes public and the AI Hype Index returns Lire l’article »

AI, Committee, Actualités, Uncategorized

NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across Codex, Claude Code, and Qwen Code

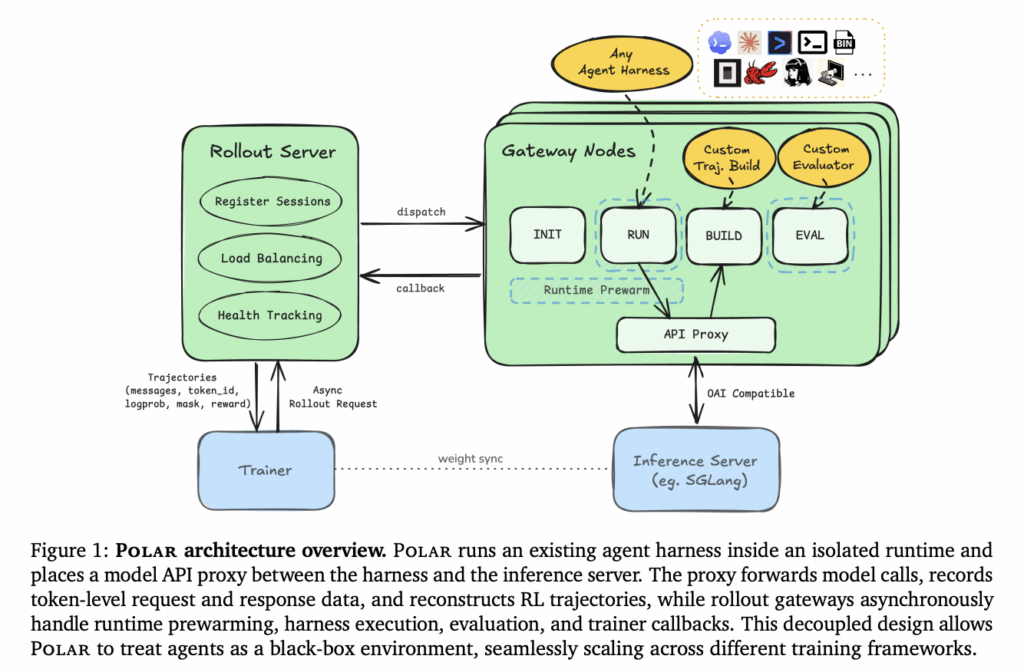
Reinforcement learning for language agents is growing more complex. Agents now manage multi-turn tool use, long-running contexts, and multi-agent orchestration. The main engineering challenge is connecting existing agent software to training pipelines without breaking how those tools work. NVIDIA’s research team introduced Polar, a rollout framework that lets researchers run reinforcement learning over any agent harness without modifying that harness. The Core Problem Polar Solves An ‘agent harness’ is a tool like Codex CLI, Claude Code, Qwen Code, or Pi. These harnesses manage system prompts, tool formatting, context engineering, and how the agent submits patches. These details directly affect agent behavior at evaluation time. Traditional RL infrastructure requires harness logic to be rewritten behind a framework-owned environment API — typically env.init(), env.step(), env.reset() in the OpenAI Gym style. Every new harness requires new integration code. That integration can also lose execution details specific to the native harness path. Polar’s key observation is that every LLM-based agent must call a model. That model API boundary is a common interface outside the agent itself. Instead of integrating inside the harness, Polar places a proxy at that boundary. How the Proxy Works For each incoming model request, the gateway proxy performs four steps: Detect the provider API — using the request path and headers, it distinguishes Anthropic Messages, OpenAI Chat Completions, OpenAI Responses, and Google generateContent-style calls. Normalize the request — converts roles, content parts, tool definitions, and generation parameters into the OpenAI Chat Completions shape used by the local inference server. Capture token-level data — stores request messages, response messages, prompt token IDs, sampled response token IDs, finish reason, and log probabilities. Return the provider shape — transforms the response back into the schema the harness expects. For streaming requests, Polar obtains a non-streaming upstream response and emits a synthetic provider-shaped stream. This preserves compatibility with harnesses that expect server-sent events while ensuring complete token capture. The only required change to an existing harness is pointing its model base URL at the gateway. https://arxiv.org/pdf/2605.24220 Architecture: Rollout Server and Gateway Nodes Polar has two core components: The rollout server accepts a TaskRequest and expands it into num_samples independent sessions. Each session carries a session ID, task ID, timeout budget, runtime specification, agent specification, trajectory builder, evaluator, and callback URL. The server dispatches sessions to gateway nodes and accepts callbacks when sessions complete. Gateway nodes own the lifecycle of each session — starting the runtime, running the harness, building trajectories, evaluating output, and teardown. The gateway also hosts the proxy endpoint for that session’s model calls, keeping completion capture tied to the session registry. Within each gateway, isolated worker pools handle INIT, RUNNING, and POSTRUN stages. A bounded READY buffer holds initialized runtimes until a run slot is available. CPU-heavy runtime preparation and evaluator prewarm proceed off the critical path, without blocking active GPU-bound agent execution. If a harness times out after model calls have been captured, the gateway still enters POSTRUN so partial traces can be recovered. Built-in evaluators include a session-completion reward, a configurable test-on-output evaluator, and a SWE-Bench/SWE-Gym harness evaluator. Custom evaluators can be added through a registry interface. Polar currently supports Docker and rootless Apptainer runtimes. Built-in harness shortcuts include codex, claude_code, gemini_cli, qwen_code, opencode, and pi. Trajectory Reconstruction: Per Request vs. Prefix Merging After a session completes, Polar reconstructs trainable trajectories from captured model calls. Two strategies are available: The per_request builder treats every model call as one independent trace. It is lossless per individual call but fragments multi-turn sessions. A single coding problem can produce hundreds of per-request traces, increasing the burden on downstream trainers. The prefix_merging builder reconstructs longer traces where the harness session preserves append-only conversation histories. It partitions completions into ordered chains by verifying a strict token-prefix relation between adjacent completions. Sub-agents, context compaction boundaries, and parallel agent branches naturally form separate chains. Within each merged trace, only sampled assistant tokens are marked trainable. Canonical interstitial tokens receive a loss mask of zero. Ablation Results The research team benchmarks both strategies on the same model, hardware, and topology over three training steps. Metric per_request prefix_merging Trainer updates 1,185 218 Wall-clock time 189.5 min 35.2 min Speedup — 5.39× Avg. rollout GPU utilization 20.4% 87.7% SWE-Bench Verified Results Training uses standard GRPO on the Qwen3.5-4B base model. The dataset is SkyRL-v0-293-data SWE-Gym (293 tasks, 1 epoch, rollout batch size 4, 16 samples per prompt) with the Slime trainer. All experiments use prefix_merging for trajectory construction. Training Rollout Reward Progress (pass@1) Harness First 10 Steps Last 10 Steps Codex 9.5% 54.5% Claude Code 28.8% 67.0% Qwen Code 61.6% 66.0% Pi 61.6% 76.2% SWE-Bench Verified Final Scores Harness Base Polar RL Gain Codex 3.8% 26.4% +22.6 pts Claude Code 29.8% 34.6% +4.8 pts Qwen Code 34.6% 35.2% +0.6 pts Pi 34.2% 40.4% +6.2 pts The largest gain is under Codex. Codex presents an unfamiliar action protocol and patch-submission style to a Qwen model not originally trained on that harness. Polar attaches the reward signal to the actual sampled tokens flowing through the Codex execution path, so GRPO optimizes the behavior the model uses at evaluation time. Under the native Qwen Code harness, where the base model is already well-aligned, Polar still delivers a 0.6 point gain. Offline SFT Data Generation Polar can also serve as a distributed offline data generation service with no changes to the runtime. The research team demonstrates this using Qwen3.5-122B-A10B on an 8×H100 server (TP=8, max_model_len=32,768) with the pi harness against 1,638 instances from seven SWE-Gym repositories. A trajectory is accepted into the SFT corpus only if the SWE-Bench evaluation harness confirms the agent’s patch resolves every FAIL_TO_PASS test and leaves every PASS_TO_PASS test green. Repository Attempts Accepted Rate getmoto/moto 343 184 53.6% python/mypy 257 101 39.3% conan-io/conan 71 27 38.0% pydantic/pydantic 81 24 29.6% iterative/dvc 219 45 20.5% pandas-dev/pandas 477 98 19.7% dask/dask 141 25 17.7% Total 1,638 504 30.8% The run cost roughly 64 GPU-hours. Accepted trajectories average 104 messages per session and 51 assistant turns. Framework Comparison System Async RL

NVIDIA Releases Polar, a Token-Faithful Rollout Framework for GRPO Training Across Codex, Claude Code, and Qwen Code Lire l’article »

AI, Committee, Actualités, Uncategorized

Uncertainty-Aware Budget Allocation for Adaptive Test-Time Reasoning

arXiv:2605.26849v1 Announce Type: new Abstract: Sampling multiple responses improves language model reasoning, but uniform compute allocation is inefficient: easy questions are over-sampled while hard questions remain under-explored. We propose Uncertainty-Aware Budget Allocation (UAB), a concave integer optimization framework that reallocates a fixed sampling budget based on per-question uncertainty estimated at no additional inference cost. In Phase 1, every question receives one generation; its average negative log-likelihood (ANLL), extracted directly from output log-probabilities, serves as a difficulty signal while the generation contributes to the final vote. In Phase 2, the remaining budget is allocated by a marginal-greedy algorithm that solves a concave coverage-maximization surrogate exactly: uncertain questions receive more sampling budget while confident questions receive fewer additional samples. Evaluated on six open-weight and black-box models spanning 1.5B to 27B parameters and five reasoning benchmarks covering math, logic, and preference tasks, UAB outperforms baselines by up to +3% in average accuracy and up to +5% on individual benchmarks, with the largest gains in low-resource settings, requiring no auxiliary model or additional LLM call. Code is publicly available at https://github.com/manhitv/UAB.

Uncertainty-Aware Budget Allocation for Adaptive Test-Time Reasoning Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR