YouZum

Committee

AI, Committee, Actualités, Uncategorized

Fuel prices are soaring. Plastic could be next.

As the war in Iran continues to engulf the Middle East and the Strait of Hormuz stays closed, one of the most visible global economic ripple effects has been fossil-fuel prices. In particular, you can’t get away from news about the price of gasoline, which just topped an average of $4 a gallon in the US, its highest level since 2022. But looking ahead, further consequences for the global economy could be looming in plastics. Plastics are made using petrochemicals, and the supply chain impacts of the oil bottleneck near Iran are starting to build up.  Plastic production accounts for roughly 5% of global carbon dioxide emissions today. And our current moment shows just how embedded oil and gas products are in our lives. It goes far beyond their use for energy.  As I write this, I’m wearing clothes that contain plastic fibers, typing on a plastic keyboard, and looking through the plastic lenses of my glasses. It’s hard to imagine what our world looks like without plastic. And in some ways, moving away from fossil-derived plastic could prove even more complicated than decarbonizing our energy system.  Crude oil prices have been on a roller-coaster in recent weeks, and prices have recently topped $100 a barrel. Crude oil contains a huge range of hydrocarbons, and it’s typically refined by putting it through a distillation unit that separates the raw material into different fractions according to their boiling point. Those fractions then go on to be further processed into everything from jet fuel to asphalt binder. We’ve already seen the price spikes for some materials pulled out of crude oil, like gasoline and jet fuel. Let’s zoom in on another component, naphtha. It can be added to gasoline and jet fuel to improve performance. It can also be used as a solvent or as a raw material to make plastics. The Middle East currently accounts for about 20% of global naphtha production­ and supplies about 40% of the market in Asia, where prices are already up by 50% over the last month. We’re starting to see these effects trickle down already. The price of polypropylene (which is made from naphtha and used for food containers, bottle caps, and even automotive parts) is climbing, especially in Asia.   Typically, manufacturers have a bit of stock built up, but that’ll be exhausted soon, likely in the coming weeks. The largest supplier of water bottles in India recently announced that it would raise prices by 11% after its packaging costs went up by over 70%, according to reporting from Reuters. Toys could be more expensive this holiday season as manufacturers grapple with supply chain concerns. Americans will likely feel these ripples especially hard if disruptions continue. The average US resident used over 250 kilograms of new plastics in 2019, according to a 2022 report from the Organization for Economic Cooperation and Development. That’s an absolutely massive number—the global average is just 60 kilograms. The effects of higher prices for both fuels and feedstocks could compound and multiply, and alternatives aren’t widely available. Bio-based plastics made with materials like plant sugars exist, but they still make up a vanishingly tiny portion of the market. As of 2025, global plastics production totaled over 431 million metric tons per year. Bio-based and bio-degradable plastics made up about 0.5% of that, a share that could reach 1% by 2030. Bio-based plastics are much more expensive than their fossil-derived counterparts. And many are made using agricultural raw materials, so scaling them up too much could be harmful for the environment and might compete with other industries like food production. Recycling isn’t the easy answer either. Mechanical recycling is the current standard method used for materials like the plastics that make up water bottles and disposable coffee cups. But that degrades the materials over time, so they can’t be used infinitely. Chemical recycling has its own host of issues—the facilities that do it can be highly polluting, and today plastics that go into advanced recycling plants largely don’t actually go into new plastics. There’s been a lot of talk in recent weeks about how this energy crisis is going to push the world more toward renewable energy. Solar panels, electric vehicles, and batteries could suddenly become more attractive as we face the drastic consequences of a disruption in the global fossil-fuel supply. But when it comes to plastic, the future looks far more complicated. Even though the plastics industry is facing much the same disruptions as the energy sector, there aren’t the same obvious alternatives available for a transition. Our lives are tied up in plastic, with uses ranging from the essential (like medical equipment) to the mundane (my to-go coffee cup). Soon, our economy could feel the effects of just how much we rely on fossil-derived plastics, and how hard it’s going to be to replace them.  This article is from The Spark, MIT Technology Review’s weekly climate newsletter. To receive it in your inbox every Wednesday, sign up here. 

Fuel prices are soaring. Plastic could be next. Lire l’article »
AI, Committee, Actualités, Uncategorized

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction

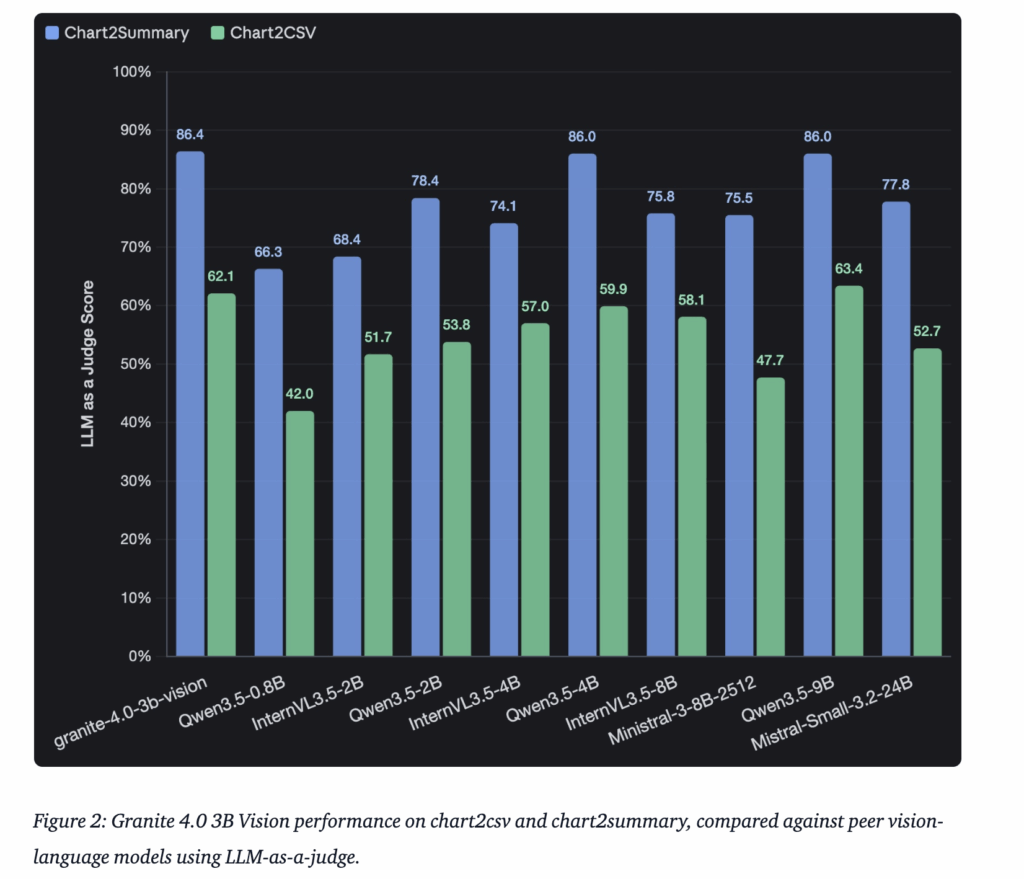
IBM has announced the release of Granite 4.0 3B Vision, a vision-language model (VLM) engineered specifically for enterprise-grade document data extraction. Departing from the monolithic approach of larger multimodal models, the 4.0 Vision release is architected as a specialized adapter designed to bring high-fidelity visual reasoning to the Granite 4.0 Micro language backbone. This release represents a transition toward modular, extraction-focused AI that prioritizes structured data accuracy—such as converting complex charts to code or tables to HTML—over general-purpose image captioning. Architecture: Modular LoRA and DeepStack Integration The Granite 4.0 3B Vision model is delivered as a LoRA (Low-Rank Adaptation) adapter with approximately 0.5B parameters. This adapter is designed to be loaded on top of the Granite 4.0 Micro base model, a 3.5B parameter dense language model. This design allows for a ‘dual-mode’ deployment: the base model can handle text-only requests independently, while the vision adapter is activated only when multimodal processing is required. Vision Encoder and Patch Tiling The visual component utilizes the google/siglip2-so400m-patch16-384 encoder. To maintain high resolution across diverse document layouts, the model employs a tiling mechanism. Input images are decomposed into 384×384 patches, which are processed alongside a downscaled global view of the entire image. This approach ensures that fine details—such as subscripts in formulas or small data points in charts—are preserved before they reach the language backbone. The DeepStack Backbone To bridge the vision and language modalities, IBM utilizes a variant of the DeepStack architecture. This involves deeply stacking visual tokens into the language model across 8 specific injection points. By routing visual features into multiple layers of the transformer, the model achieves a tighter alignment between the ‘what’ (semantic content) and the ‘where’ (spatial layout), which is critical for maintaining structure during document parsing. Training Curriculum: Focused on Chart and Table Extraction The training of Granite 4.0 3B Vision reflects a strategic shift toward specialized extraction tasks. Rather than relying solely on general image-text datasets, IBM utilized a curated mixture of instruction-following data focused on complex document structures. ChartNet Dataset: The model was refined using ChartNet, a million-scale multimodal dataset designed for robust chart understanding. Code-Guided Pipeline: A key technical highlight of the training involves a “code-guided” approach for chart reasoning. This pipeline uses aligned data consisting of the original plotting code, the resulting rendered image, and the underlying data table, allowing the model to learn the structural relationship between visual representations and their source data. Extraction Tuning: The model was fine-tuned on a mixture of datasets focusing on Key-Value Pair (KVP) extraction, table structure recognition, and converting visual charts into machine-readable formats like CSV, JSON, and OTSL. Performance and Evaluation Benchmarks In technical evaluations, Granite 4.0 3B Vision has been benchmarked against several industry-standard suites for document understanding. It is important to note that datasets like PubTables-v2 and OmniDocBench are utilized as evaluation benchmarks to verify the model’s zero-shot performance in real-world scenarios. Task Evaluation Benchmark Metric KVP Extraction VAREX 85.5% Exact Match (Zero-Shot) Chart Reasoning ChartNet (Human-Verified Test Set) High Accuracy in Chart2Summary Table Extraction TableVQA-Bench & OmniDocBench Evaluated via TEDS and HTML extraction The model currently ranks 3rd among models in the 2–4B parameter class on the VAREX leaderboard (as of March 2026), demonstrating its efficiency in structured extraction despite its compact size. https://huggingface.co/blog/ibm-granite/granite-4-vision https://huggingface.co/blog/ibm-granite/granite-4-vision Key Takeaways Modular LoRA Architecture: The model is a 0.5B parameter LoRA adapter that operates on the Granite 4.0 Micro (3.5B) backbone. This design allows a single deployment to handle text-only workloads efficiently while activating vision capabilities only when needed. High-Resolution Tiling: Utilizing the google/siglip2-so400m-patch16-384 encoder, the model processes images by tiling them into 384×384 patches alongside a global downscaled view, ensuring that fine details in complex documents are preserved. DeepStack Injection: To improve layout awareness, the model uses a DeepStack approach with 8 injection points. This routes semantic features to earlier layers and spatial details to later layers, which is critical for accurate table and chart extraction. Specialized Extraction Training: Beyond general instruction following, the model was refined using ChartNet and a ‘code-guided’ pipeline that aligns plotting code, images, and data tables to help the model internalize the logic of visual data structures. Developer-Ready Integration: The release is Apache 2.0 licensed and features native support for vLLM (via a custom model implementation) and Docling, IBM’s tool for converting unstructured PDFs into machine-readable JSON or HTML. Check out the Technical details and Model Weight.  Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction appeared first on MarkTechPost.

IBM Releases Granite 4.0 3B Vision: A New Vision Language Model for Enterprise Grade Document Data Extraction Lire l’article »

AI, Committee, Actualités, Uncategorized

The Download: plastic’s problem with fuel prices, and SpaceX’s blockbuster IPO

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. Fuel prices are soaring. Plastic could be next.  As the war in Iran continues, one of the most visible global economic ripple effects has been fossil-fuel prices. But looking ahead, further consequences could be looming for plastics.  Plastics are made from petrochemicals, and the supply chain impacts from the conflict are starting to build up. Americans will likely feel the ripples.   Read the full story to grasp the unpredictable impacts.  —Casey Crownhart  This story is from The Spark, our weekly climate newsletter. Sign up to get it in your inbox every Wednesday.  The must-reads  I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.  1 SpaceX has filed for an IPO It’s set to be the largest ever, targeting a $1.75 trillion valuation. (NYT $)  + Which would make Elon Musk the world’s first trillionaire. (Al Jazeera) + But the IPO could hinge on the success of Moon missions. (LA Times $) + And the conflicts of interest are staggering. (The Next Web) + Meanwhile, rivals are rising to challenge SpaceX. (MIT Technology Review)   2 Artemis II is on its way to the Moon NASA successfully launched the four astronauts on its rocket yesterday. (Axios) + The lunar plans could violate international law. (The Verge) + But the potential scientific advances are tremendous. (Nature)  + Check out our roundtable on the next era of space exploration. (MIT Technology Review)   3 Iran has struck Amazon’s cloud business in Bahrain again It promised to hit US companies only yesterday. (FT $) + Other targets include Google, Microsoft, Apple, and Nvidia. (CNBC) + AWS data centers in Bahrain were also hit last month. (Reuters $)  4 OpenAI was secretly behind a child safety campaign group It pushed for age verification requirements for AI. (The San Francisco Standard $) + OpenAI had backed the legislation as a compromise measure. (WSJ $) + Coincidentally, Sam Altman heads a company providing age verification. (Engadget)  5 Anthropic is scrambling to limit the Claude Code leak It’s trying to remove 8,000 copies of the exposed code from GitHub. (Gizmodo) + An executive blamed the leak on “process errors.” (Bloomberg $) + Here’s what it reveals about Anthropic’s plans. (Ars Technica) + AI is making online crimes easier—and it could get much worse. (MIT Technology Review)  6 A new Russian “super-app” aims to emulate China’s WeChat And give the Kremlin new surveillance powers. (WSJ $)  7 America’s AI boom is leaving the rest of the world behind  And it’s concentrating power and wealth in a handful of companies. (Rest of World)  8 Chinese chipmakers have claimed nearly half the country’s market Nvidia’s lead is shrinking rapidly. (Reuters $)  9 The first quantum computer to break encryption is imminent  New research reveals how it could happen. (New Scientist)  10 The world’s oldest tortoise has been embroiled in a crypto scam Reports that Jonathan died at just 194 years old are thankfully false. (Guardian)  Quote of the day  “Starlink is the only reason this valuation is defensible.”  —Shay Boloor, chief market strategist at Futurum Equities, tells Reuters why SpaceX has such high hopes for its IPO.  One More Thing  These companies are creating food out of thin air  Dried cells—it’s what’s for dinner. At least that’s what a new crop of biotech startups, armed with carbon-guzzling bacteria and plenty of capital, are hoping to convince us.   Their claims sound too good to be true: they say they can make food out of thin air. But that’s exactly how certain soil-dwelling bacteria work.  Startups are replicating the process to turn abundant carbon dioxide into nutritious “air protein.” They believe it could dramatically lower farming emissions—and even disrupt agriculture altogether. Read the full story.  —Claire L. Evans  We can still have nice things  A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.)  + Need more Artemis II in your life? This site takes you inside the flight. + Here’s a fascinating look at the recording errors that improved songs. + Good news: the elusive Nightjar bird is making a comeback. + Finally, a master chef has baked clam chowder donuts. 

The Download: plastic’s problem with fuel prices, and SpaceX’s blockbuster IPO Lire l’article »

AI, Committee, Actualités, Uncategorized

Liquid AI Released LFM2.5-350M: A Compact 350M Parameter Model Trained on 28T Tokens with Scaled Reinforcement Learning

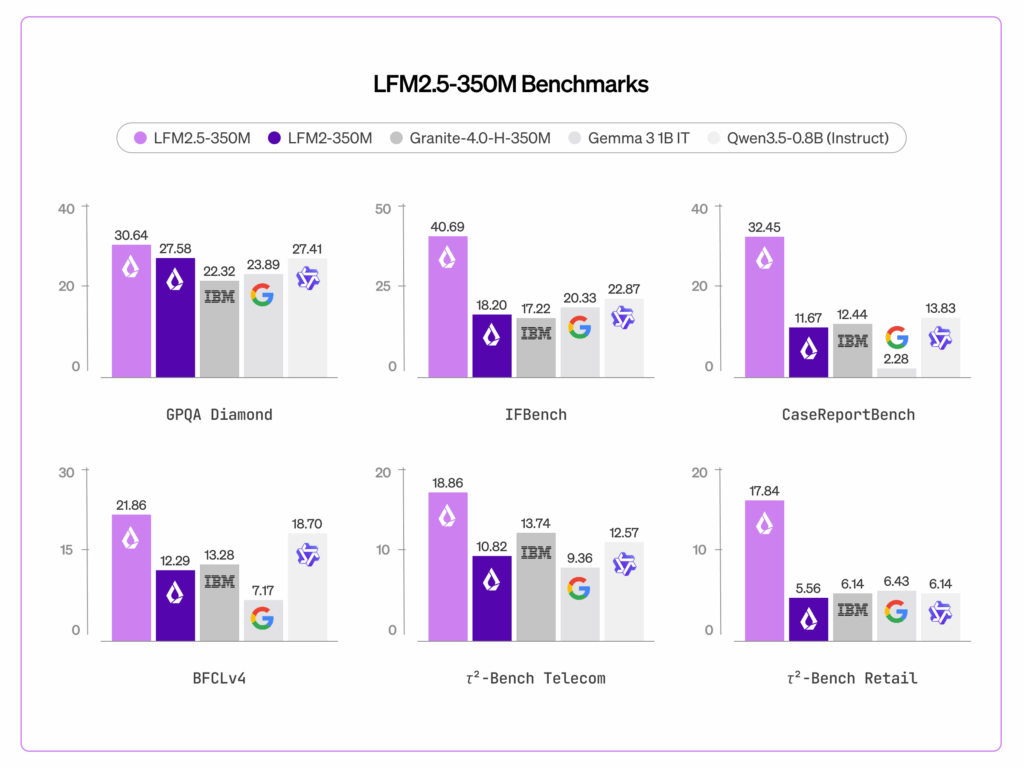
In the current landscape of generative AI, the ‘scaling laws’ have generally dictated that more parameters equal more intelligence. However, Liquid AI is challenging this convention with the release of LFM2.5-350M. This model is actually a technical case study in intelligence density with additional pre-training (from 10T to 28T tokens) and large-scale reinforcement learning The significance of LFM2.5-350M lies in its architecture and training efficiency. While the most AI companies has been focused on frontier models, Liquid AI is targeting the ‘edge’—devices with limited memory and compute—by proving that a 350-million parameter model can outperform models more than twice its size on several evaluated benchmarks. https://www.liquid.ai/blog/lfm2-5-350m-no-size-left-behind Architecture: The Hybrid LIV Backbone The core technical differentiator of the LFM2.5-350M is its departure from the pure Transformer architecture. It utilizes a hybrid structure built on Linear Input-Varying Systems (LIVs). Traditional Transformers rely entirely on self-attention mechanisms, which suffer from quadratic scaling issues: as the context window grows, the memory and computational requirements for the Key-Value (KV) cache increase. Liquid AI addresses this by using a hybrid backbone consisting of: 10 Double-Gated LIV Convolution Blocks: These handle the majority of the sequence processing. LIVs function similarly to advanced Recurrent Neural Networks (RNNs) but are designed to be more parallelizable and stable during training. They maintain a constant-state memory, reducing the I/O overhead. 6 Grouped Query Attention (GQA) Blocks: By integrating a small number of attention blocks, the model retains high-precision retrieval and long-range context handling without the full memory overhead of a standard Transformer. This hybrid approach allows the LFM2.5-350M to support a 32k context window (32,768 tokens) while maintaining an extremely lean memory footprint. Performance and Intelligence Density The LFM2.5-350M was pre-trained on 28 trillion tokens with an extremely high training-to-parameter ratio. This ensures that the model’s limited parameter count is utilized to its maximum potential, resulting in high ‘intelligence density.’ Benchmarks and Use Cases The LFM2.5-350M is a specialist model designed for high-speed, agentic tasks rather than general-purpose reasoning. Benchmark Score IFEval (Instruction Following) 76.96 GPQA Diamond 30.64 MMLU-Pro 20.01 The high IFEval score indicates the model is efficient at following complex, structured instructions, making it suitable for tool use, function calling, and structured data extraction (e.g., JSON). However, the documentation explicitly states that LFM2.5-350M is not recommended for mathematics, complex coding, or creative writing. For those tasks, the reasoning capabilities of larger parameter counts remain necessary. https://www.liquid.ai/blog/lfm2-5-350m-no-size-left-behind Hardware Optimization and Inference Efficiency A major hurdle for AI devs is the ‘memory wall’—the bottleneck created by moving data between the processor and memory. Because the LFM2.5-350M utilizes LIVs and GQA, it drastically reduces KV cache size, boosting throughput. On a single NVIDIA H100 GPU, the model can reach a throughput of 40.4K output tokens per second at high concurrency. Liquid AI team reports device-specific low-memory inference results that make local deployment viable: Snapdragon 8 Elite NPU: 169MB peak memory using RunAnywhere Q4. Snapdragon GPU: 81MB peak memory using RunAnywhere Q4. Raspberry Pi 5: 300MB using Cactus Engine int8. Key Takeaways Extreme Intelligence Density: By training a 350M parameter model on 28 trillion tokens, Liquid AI team achieved an super high 80,000:1 token-to-parameter ratio, allowing it to outperform models more than twice its size on several benchmarks. Hybrid LIV Architecture: The model departs from pure Transformers by using Linear Input-Varying Systems (LIVs) combined with a small number of Grouped Query Attention (GQA) blocks, significantly reducing the memory overhead of the KV cache. Edge-First Efficiency: It is designed for local deployment with a 32k context window and a remarkably low memory footprint—reaching as low as 81MB on mobile GPUs and 169MB on NPUs via specialized inference engines. Specialized Agentic Capability: The model is highly optimized for instruction following (IFEval: 76.96) and tool use, though it is explicitly not recommended for complex coding, mathematics, or creative writing. Massive Throughput: The architectural efficiency enables high-speed utility, processing up to 40.4K output tokens per second on a single H100, making it ideal for high-volume data extraction and real-time classification. Check out the Technical details and Model Weight. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Liquid AI Released LFM2.5-350M: A Compact 350M Parameter Model Trained on 28T Tokens with Scaled Reinforcement Learning appeared first on MarkTechPost.

Liquid AI Released LFM2.5-350M: A Compact 350M Parameter Model Trained on 28T Tokens with Scaled Reinforcement Learning Lire l’article »

AI, Committee, Actualités, Uncategorized

The gig workers who are training humanoid robots at home

When Zeus, a medical student living in a hilltop city in central Nigeria, returns to his studio apartment from a long day at the hospital, he turns on his ring light, straps his iPhone to his forehead, and starts recording himself. He raises his hands in front of him like a sleepwalker and puts a sheet on his bed. He moves slowly and carefully to make sure his hands stay within the camera frame.  Zeus is a data recorder for Micro1, a US company based in Palo Alto, California that collects real-world data to sell to robotics companies. As companies like Tesla, Figure AI, and Agility Robotics race to build humanoids—robots designed to resemble and move like humans in factories and homes—videos recorded by gig workers like Zeus are becoming the hottest new way to train them.  Micro1 has hired thousands of contract workers in more than 50 countries, including India, Nigeria, and Argentina, where swathes of tech-savvy young people are looking for jobs. They’re mounting iPhones on their heads and recording themselves folding laundry, washing dishes, and cooking. The job pays well by local standards and is boosting local economies, but it raises thorny questions around privacy and informed consent. And the work can be challenging at times—and weird. Zeus found the job in November, when people started talking about it everywhere on LinkedIn and YouTube. “This would be a real nice opportunity to set a mark and give data that will be used to train robots in the future,” he thought.  Zeus is paid $15 an hour, which is good income in Nigeria’s strained economy with high unemployment rates. But as a bright-eyed student dreaming of becoming a doctor, he finds ironing his clothes for hours every day boring.  “I really [do] not like it so much,” he says. “I’m the kind of person that requires … a technical job that requires me to think.”  Zeus, and all the workers interviewed by MIT Technology Review, asked to be referred to only by pseudonyms because they were not authorized to talk about their work. Humanoid robots are notoriously hard to build because manipulating physical objects is a difficult skill to master. But the rise of large language models underlying chatbots like ChatGPT has inspired a paradigm shift in robotics. Just as large language models learned to generate words by being trained on vast troves of text scraped from the internet, many researchers believe that humanoid robots can learn to interact with the world by being trained on massive amounts of movement data.  Editor’s note: In a recent poll, MIT Technology Review readers selected humanoid robots as the 11th breakthrough for our 2026 list of 10 Breakthrough Technologies. Robotics requires far more complex data about the physical world, though, and that is much harder to find. Virtual simulations can train robots to perform acrobatics, but not how to grasp and move objects, because simulations struggle to model physics with perfect accuracy. For robots to work in factories and serve as housekeepers, real-world data, however time-consuming and expensive to collect, may be what we need.  Investors are pouring money feverishly into solving this challenge, spending over $6 billion on humanoid robots in 2025. And at-home data recording is becoming a booming gig economy around the world. Data companies like Scale AI and Encord are recruiting their own armies of data recorders, while DoorDash pays delivery drivers to film themselves doing chores. And in China, workers in dozens of state-owned robot training centers wear virtual-reality headsets and exoskeletons to teach humanoid robots how to open a microwave and wipe down the table.  “There is a lot of demand, and it’s increasing really fast,” says Ali Ansari, CEO of Micro1. He estimates that robotics companies are now spending more than $100 million each year to buy real-world data from his company and others like it. A day in the life Workers at Micro1 are vetted by an AI agent named Zara that conducts interviews and reviews samples of chore videos. Every week, they submit videos of themselves doing chores around their homes, following a list of instructions about things like keeping their hands visible and moving at natural speed. The videos are reviewed by both AI and a human and are either accepted or rejected. They’re then annotated by AI and a team of hundreds of humans who label the actions in the footage. “There is a lot of demand, and it’s increasing really fast.” Ali Ansari, CEO of Micro1  Because this approach to training robots is in its infancy, it’s not clear yet what makes good training data. Still, “you need to give lots and lots of variations for the robot to generalize well for basic navigation and manipulation of the world,” says Ansari. But many workers say that creating a variety of “chore content” in their tiny homes is a challenge. Zeus, a scrappy student living in a humble studio, struggles to record anything beyond ironing his clothes every day. Arjun, a tutor in Delhi, India, takes an hour to make a 15-minute video because he spends so much time brainstorming new chores. “How much content [can be made] in the home? How much content?” he says.  There’s also the sticky question of privacy. Micro1 asks workers not to show their faces to the camera or reveal personal information such as names, phone numbers, and birth dates. Then it uses AI and human reviewers to remove anything that slips through.  But even without faces, the videos capture an intimate slice of workers’ lives: the interiors of their homes, their possessions, their routines. And understanding what kind of personal information they might be recording while they’re busy doing chores on camera can be tricky. Reviews of such footage might not filter out sensitive information beyond the most obvious identifiers. For workers with families, keeping private life off camera is a constant negotiation. Arjun, a father of two daughters, has to wrangle his chaotic two-year-old out of frame. “Sometimes it’s very difficult to

The gig workers who are training humanoid robots at home Lire l’article »

AI, Committee, Actualités, Uncategorized

Hugging Face Releases TRL v1.0: A Unified Post-Training Stack for SFT, Reward Modeling, DPO, and GRPO Workflows

Hugging Face has officially released TRL (Transformer Reinforcement Learning) v1.0, marking a pivotal transition for the library from a research-oriented repository to a stable, production-ready framework. For AI professionals and developers, this release codifies the Post-Training pipeline—the essential sequence of Supervised Fine-Tuning (SFT), Reward Modeling, and Alignment—into a unified, standardized API. In the early stages of the LLM boom, post-training was often treated as an experimental ‘dark art.’ TRL v1.0 aims to change that by providing a consistent developer experience built on three core pillars: a dedicated Command Line Interface (CLI), a unified Configuration system, and an expanded suite of alignment algorithms including DPO, GRPO, and KTO. The Unified Post-Training Stack Post-training is the phase where a pre-trained base model is refined to follow instructions, adopt a specific tone, or exhibit complex reasoning capabilities. TRL v1.0 organizes this process into distinct, interoperable stages: Supervised Fine-Tuning (SFT): The foundational step where the model is trained on high-quality instruction-following data to adapt its pre-trained knowledge to a conversational format. Reward Modeling: The process of training a separate model to predict human preferences, which acts as a ‘judge’ to score different model responses. Alignment (Reinforcement Learning): The final refinement where the model is optimized to maximize preference scores. This is achieved either through “online” methods that generate text during training or “offline” methods that learn from static preference datasets. Standardizing the Developer Experience: The TRL CLI One of the most significant updates for software engineers is the introduction of a robust TRL CLI. Previously, engineers were required to write extensive boilerplate code and custom training loops for every experiment. TRL v1.0 introduces a config-driven approach that utilizes YAML files or direct command-line arguments to manage the training lifecycle. The trl Command The CLI provides standardized entry points for the primary training stages. For instance, initiating an SFT run can now be executed via a single command: Copy CodeCopiedUse a different Browser trl sft –model_name_or_path meta-llama/Llama-3.1-8B –dataset_name openbmb/UltraInteract –output_dir ./sft_results This interface is integrated with Hugging Face Accelerate, which allows the same command to scale across diverse hardware configurations. Whether running on a single local GPU or a multi-node cluster utilizing Fully Sharded Data Parallel (FSDP) or DeepSpeed, the CLI manages the underlying distribution logic. TRLConfig and TrainingArguments Technical parity with the core transformers library is a cornerstone of this release. Each trainer now features a corresponding configuration class—such as SFTConfig, DPOConfig, or GRPOConfig—which inherits directly from transformers.TrainingArguments. Alignment Algorithms: Choosing the Right Objective TRL v1.0 consolidates several reinforcement learning methods, categorizing them based on their data requirements and computational overhead. Algorithm Type Technical Characteristic PPO Online Requires Policy, Reference, Reward, and Value (Critic) models. Highest VRAM footprint. DPO Offline Learns from preference pairs (chosen vs. rejected) without a separate Reward model. GRPO Online An on-policy method that removes the Value (Critic) model by using group-relative rewards. KTO Offline Learns from binary “thumbs up/down” signals instead of paired preferences. ORPO (Exp.) Experimental A one-step method that merges SFT and alignment using an odds-ratio loss. Efficiency and Performance Scaling To accommodate models with billions of parameters on consumer or mid-tier enterprise hardware, TRL v1.0 integrates several efficiency-focused technologies: PEFT (Parameter-Efficient Fine-Tuning): Native support for LoRA and QLoRA enables fine-tuning by updating a small fraction of the model’s weights, drastically reducing memory requirements. Unsloth Integration: TRL v1.0 leverages specialized kernels from the Unsloth library. For SFT and DPO workflows, this integration can result in a 2x increase in training speed and up to a 70% reduction in memory usage compared to standard implementations. Data Packing: The SFTTrainer supports constant-length packing. This technique concatenates multiple short sequences into a single fixed-length block (e.g., 2048 tokens), ensuring that nearly every token processed contributes to the gradient update and minimizing computation spent on padding. The trl.experimental Namespace Hugging Face team has introduced the trl.experimental namespace to separate production-stable tools from rapidly evolving research. This allows the core library to remain backward-compatible while still hosting cutting-edge developments. Features currently in the experimental track include: ORPO (Odds Ratio Preference Optimization): An emerging method that attempts to skip the SFT phase by applying alignment directly to the base model. Online DPO Trainers: Variants of DPO that incorporate real-time generation. Novel Loss Functions: Experimental objectives that target specific model behaviors, such as reducing verbosity or improving mathematical reasoning. Key Takeaways TRL v1.0 standardizes LLM post-training with a unified CLI, config system, and trainer workflow. The release separates a stable core from experimental methods such as ORPO and KTO. GRPO reduces RL training overhead by removing the separate critic model used in PPO. TRL integrates PEFT, data packing, and Unsloth to improve training efficiency and memory usage. The library makes SFT, reward modeling, and alignment more reproducible for engineering teams. Check out the Technical details.  Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Hugging Face Releases TRL v1.0: A Unified Post-Training Stack for SFT, Reward Modeling, DPO, and GRPO Workflows appeared first on MarkTechPost.

Hugging Face Releases TRL v1.0: A Unified Post-Training Stack for SFT, Reward Modeling, DPO, and GRPO Workflows Lire l’article »

AI, Committee, Actualités, Uncategorized

Google AI Releases Veo 3.1 Lite: Giving Developers Low Cost High Speed Video Generation via The Gemini API

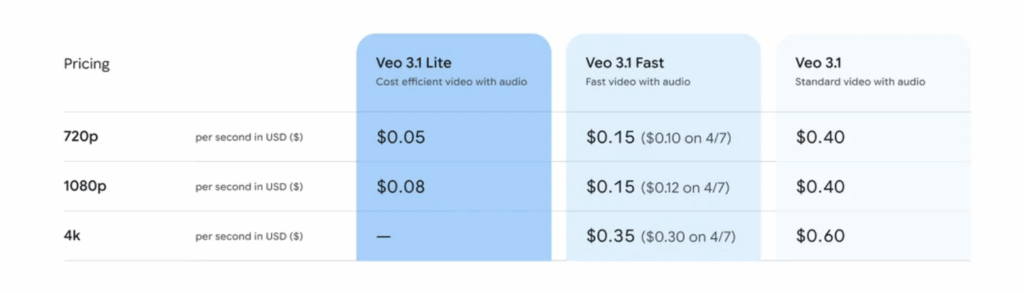
Google has announced the release of Veo 3.1 Lite, a new model tier within its generative video portfolio designed to address the primary bottleneck for production-scale deployments: pricing. While the generative video space has seen rapid progress in visual fidelity, the cost per second of generated content has remained high, often prohibitive for developers building high-volume applications. Veo 3.1 Lite is now available via the Gemini API and Google AI Studio for users in the paid tier. By offering the same generation speed as the existing Veo 3.1 Fast model at approximately half the cost, Google is positioning this model as the standard for developers focused on programmatic video generation and iterative prototyping. https://blog.google/innovation-and-ai/technology/ai/veo-3-1-lite/ Technical Architecture: The Diffusion Transformer (DiT) The most significant aspect of the Veo 3.1 family is its underlying Diffusion Transformer (DiT) architecture. Traditional generative video models often relied on U-Net-based diffusion, which can struggle with high-dimensional data and long-range temporal dependencies. Veo 3.1 Lite utilizes a transformer-based backbone that operates on spatio-temporal patches. In this architecture, video frames are not processed as static 2D images but as a continuous sequence of tokens in a latent space. By applying self-attention across these patches, the model maintains better temporal consistency. This ensures that objects, lighting, and textures remain coherent across the duration of the clip, reducing the artifacts commonly seen in earlier models. The model performs its computation in a compressed latent space rather than pixel space. This allows the model to handle the high computational demands of video generation while maintaining a lower memory footprint. For developers, this translates to a model that can generate high-definition content without the exponential increase in compute time that usually accompanies resolution scaling. Performance and Output Specifications Veo 3.1 Lite provides specific parameters for resolution and duration, allowing AI devs to integrate it into structured workflows. Unlike the flagship Veo 3.1 model, which supports 4K resolution, the Lite version is optimized for high-definition (HD) outputs. Supported Resolutions: 720p and 1080p. Aspect Ratios: Native support for both landscape (16:9) and portrait (9:16) orientations. Clip Durations: Developers can specify generation lengths of 4, 6, or 8 seconds. Prompt Adherence: The model is optimized for ‘Cinematic Control,’ recognizing technical directives such as ‘pan,’ ’tilt,’ and specific lighting instructions. The ‘Lite’ tag does not refer to a reduction in generation speed compared to the ‘Fast’ tier. Instead, it refers to an optimized parameter set that allows Google team to offer the model at a significantly lower price point while maintaining the same low-latency performance characteristics of Veo 3.1 Fast. The Pricing Shift: Democratizing Video Inference The core value proposition of Veo 3.1 Lite is its cost structure. In the current market, high-quality video inference often costs several dollars per minute of footage, making it difficult to justify for applications like dynamic ad generation or social media automation. Veo 3.1 Lite pricing is structured as follows: 720p: $0.05 per second. 1080p: $0.08 per second. Deployment via Gemini API and AI Studio The accessibility is handled through the Gemini API. This allows for the integration of video generation into existing Python or Node.js applications using standard REST or gRPC calls. One critical technical feature for enterprise developers is the inclusion of SynthID. Developed by Google DeepMind, SynthID is a tool for watermarking and identifying AI-generated content. It embeds a digital watermark directly into the pixels of the video that is imperceptible to the human eye but detectable by specialized software. This is a mandatory component for developers concerned with safety, compliance, and distinguishing synthetic media from captured footage. Key Takeaways Half the Cost, Same Speed: Offers the same low-latency performance as the ‘Fast’ tier at less than 50% of the price ($0.05/sec for 720p). Scalable HD Output: Supports 720p and 1080p resolutions in 4, 6, or 8-second clips with native 16:9 and 9:16 aspect ratios. Architecture: Built on a Diffusion Transformer (DiT) using spatio-temporal patches for superior motion and physical consistency. Developer Ready: Available now via Gemini API (paid tier) and Google AI Studio, featuring built-in SynthID digital watermarking. Check out the Technical details. You can access the model via paid tier on the Gemini API and Google AI Studio. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Google AI Releases Veo 3.1 Lite: Giving Developers Low Cost High Speed Video Generation via The Gemini API appeared first on MarkTechPost.

Google AI Releases Veo 3.1 Lite: Giving Developers Low Cost High Speed Video Generation via The Gemini API Lire l’article »

AI, Committee, Actualités, Uncategorized

The Download: gig workers training humanoids, and better AI benchmarks

This is today’s edition of The Download, our weekday newsletter that provides a daily dose of what’s going on in the world of technology. The gig workers who are training humanoid robots at home  When Zeus, a medical student in Nigeria, returns to his apartment from a long day at the hospital, he straps his iPhone to his forehead and records himself doing chores.  Zeus is a data recorder for Micro1, which sells the data he collects to robotics firms. As these companies race to build humanoids, videos from workers like Zeus have become the hottest new way to train them.   Micro1 has hired thousands of them in more than 50 countries, including India, Nigeria, and Argentina. The jobs pay well locally, but raise thorny questions around privacy and informed consent. The work can be challenging—and weird. Read the full story.  —Michelle Kim  Our readers recently voted humanoid robots the “11th breakthrough” to add to our 2026 list of 10 Breakthrough Technologies. Check out what else officially made the cut.  AI benchmarks are broken. Here’s what we need instead.  For decades, AI has been evaluated based on whether it can outperform humans on isolated problems. But it’s seldom used this way in the real world.  While AI is assessed in a vacuum, it operates in messy, complex, multi-person environments over time. This misalignment leads us to misunderstand its capabilities, risks, and impacts.  We need new benchmarks that assess AI’s performance over longer horizons within human teams, workflows, and organizations. Here’s a proposal for one such approach: Human–AI, Context-Specific Evaluation.   —Angela Aristidou, professor at University College London and faculty fellow at the Stanford Digital Economy Lab and the Stanford Human-Centered AI Institute.  MIT Technology Review Narrated: can quantum computers now solve health care problems? We’ll soon find out.  In a laboratory on the outskirts of Oxford, a quantum computer built from atoms and light awaits its moment. The device is small but powerful—and also very valuable. Infleqtion, the company that owns it, is hoping its abilities will win $5 million at a competition.   The prize will go to the quantum computer that can solve real health care problems that “classical” computers cannot. But there can be only one big winner—if there is a winner at all.  —Michael Brooks  This is our latest story to be turned into an MIT Technology Review Narrated podcast, which we’re publishing each week on Spotify and Apple Podcasts. Just navigate to MIT Technology Review Narrated on either platform, and follow us to get all our new content as it’s released.  The must-reads  I’ve combed the internet to find you today’s most fun/important/scary/fascinating stories about technology.  1 OpenAI just closed the biggest funding round in Silicon Valley history It raised $122 billion ahead of its blockbuster IPO, which is expected later this year. (WSJ $) + It’s also prepping a push to “rethink the social contract.” (Vanity Fair $) + Campaigners are urging people to quit ChatGPT. (MIT Technology Review)    2 Iran has threatened to attack 18 US tech companies  It’s eyeing their operations in the Middle East. (Politico) + Targets include Nvidia, Apple, Microsoft, and Google. (Engadget) + Iran struck AWS data centers earlier this month. (Reuters $)  3 Artemis II is about to fly humans to the Moon. Here’s the science they’ll do Their experiments will set the stage for future explorers. (Nature) + You can watch the launch attempt today. (Engadget)   4 Putin is trying to take full control of Russia’s internet New outages and blockages are cutting the country off from the world. (NYT $) + Can we repair the internet? (MIT Technology Review)  5 A robotaxi outage in China left passengers stranded on highways  Baidu vehicles froze on the streets of Wuhan. (Bloomberg $) + Police are blaming a “system failure.” (Reuters $)  6 US government requests for social media user data are soaring They’ve skyrocketed by 770% in the past decade. (Bloomberg $) + Is the Pentagon allowed to surveil Americans with AI? (MIT Technology Review)  7 Tesla has admitted that humans sometimes drive its robotaxis Remote drivers occasionally control them completely. (Wired $)  8 A satellite-smashing chain reaction could spiral out of control This data visualization captures the dangers of space collisions. (Guardian) + Here’s all the stuff we’ve put into space. (MIT Technology Review)  9 Meta’s smartglasses can turn you into a creep According to one journalist who wore them for a month. (Guardian)  10 A Claude Code leak has exposed plans for a virtual pet  We could be getting a Tamagotchi for the GenAI era. (The Verge)  Quote of the day  “From now on, for every assassination, an American company will be destroyed.”  —Iran’s Islamic Revolutionary Guard Corps (IRGC) threatens US tech firms in an affiliated Telegram, per CNBC.  One More Thing  ACKERMAN + GRUBER How one mine could unlock billions in EV subsidies  In a pine farm north of the tiny town of Tamarack, Minnesota, Talon Metals has uncovered one of America’s densest nickel deposits. Now it wants to begin mining the ore.  Products made from the nickel could net more than $26 billion in subsidies through the Inflation Reduction Act (IRA), which is starting to transform the US economy. To understand how, we tallied up the potential tax credits available. Read the full story to find out what we discovered.  —James Temple  We can still have nice things  A place for comfort, fun and distraction to brighten up your day. (Got any ideas? Drop me a line.)  + A selfless group of gluttons tried to taste-test every potato chip in the world.  + Get romantic inspiration from these penguins’ engagement pebbles. + Good news: global terrorism has hit a 15-year low. + Enjoy endless new views through these windows around the world.  

The Download: gig workers training humanoids, and better AI benchmarks Lire l’article »

AI, Committee, Actualités, Uncategorized

Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction

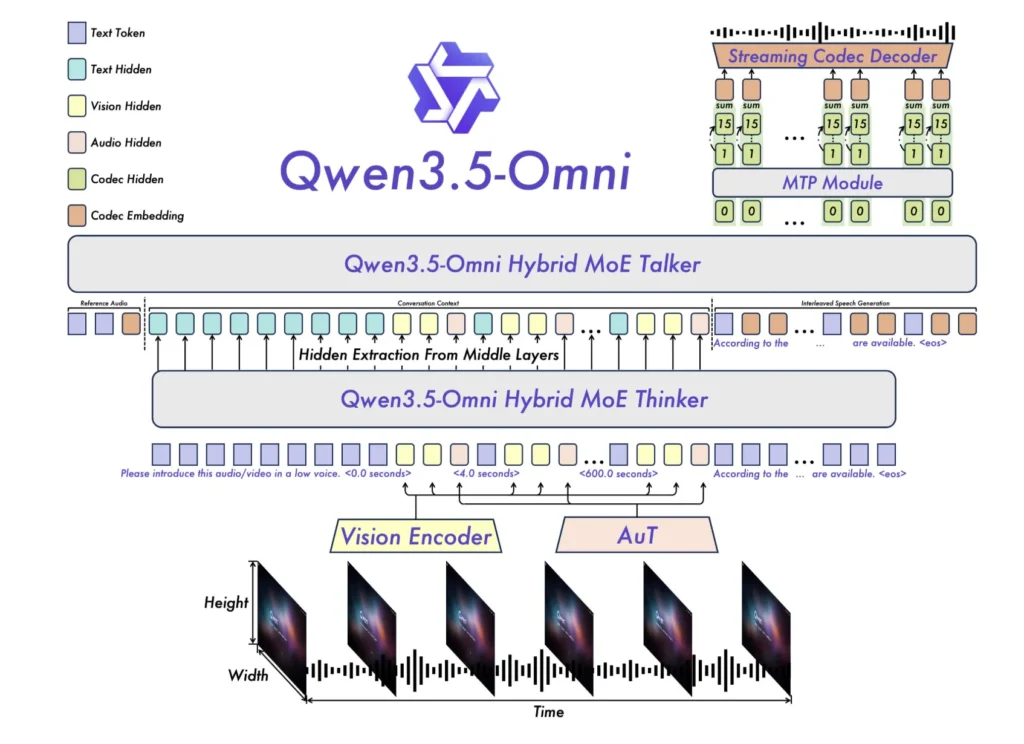
The landscape of multimodal large language models (MLLMs) has shifted from experimental ‘wrappers’—where separate vision or audio encoders are stitched onto a text-based backbone—to native, end-to-end ‘omnimodal’ architectures. Alibaba Qwen team latest release, Qwen3.5-Omni, represents a significant milestone in this evolution. Designed as a direct competitor to flagship models like Gemini 3.1 Pro, the Qwen3.5-Omni series introduces a unified framework capable of processing text, images, audio, and video simultaneously within a single computational pipeline. The technical significance of Qwen3.5-Omni lies in its Thinker-Talker architecture and its use of Hybrid-Attention Mixture of Experts (MoE) across all modalities. This approach enables the model to handle massive context windows and real-time interaction without the traditional latency penalties associated with cascaded systems. Model Tiers The series is offered in three sizes to balance performance and cost: Plus: High-complexity reasoning and maximum accuracy. Flash: Optimized for high-throughput and low-latency interaction. Light: A smaller variant for efficiency-focused tasks. https://qwen.ai/blog?id=qwen3.5-omni The Thinker-Talker Architecture: A Unified MoE Framework At the core of Qwen3.5-Omni is a bifurcated yet tightly integrated architecture consisting of two main components: the Thinker and the Talker. In previous iterations, multimodal models often relied on external pre-trained encoders (such as Whisper for audio). Qwen3.5-Omni moves beyond this by utilizing a native Audio Transformer (AuT) encoder. This encoder was pre-trained on more than 100 million hours of audio-visual data, providing the model with a grounded understanding of temporal and acoustic nuances that traditional text-first models lack. Hybrid-Attention Mixture of Experts (MoE) Both the Thinker and the Talker leverage Hybrid-Attention MoE. In a standard MoE setup, only a subset of parameters (the ‘experts’) are activated for any given token, which allows for a high total parameter count with lower active computational costs. By applying this to a hybrid-attention mechanism, Qwen3.5-Omni can effectively weigh the importance of different modalities (e.g., focusing more on visual tokens during a video analysis task) while maintaining the throughput required for streaming services. This architecture supports a 256k long-context input, enabling the model to ingest and reason over: Over 10 hours of continuous audio. Over 400 seconds of 720p audio-visual content (sampled at 1 FPS). Benchmarking Performance: The ‘215 SOTA’ Milestone One of the most highlighted technical claims regarding the flagship Qwen3.5-Omni-Plus model is its performance on the global leaderboard. The model achieved State-of-the-Art (SOTA) results on 215 audio and audio-visual understanding, reasoning, and interaction subtasks. These 215 SOTA wins are not merely a measure of broad evaluation but span specific technical benchmarks, including: 3 audio-visual benchmarks and 5 general audio benchmarks. 8 ASR (Automatic Speech Recognition) benchmarks. 156 language-specific Speech-to-Text Translation (S2TT) tasks. 43 language-specific ASR tasks. According to their official technical reports, Qwen3.5-Omni-Plus surpasses Gemini 3.1 Pro in general audio understanding, reasoning, recognition, and translation. In audio-visual understanding, it achieves parity with Google’s flagship, while maintaining the core text and visual performance of the standard Qwen3.5 series. https://qwen.ai/blog?id=qwen3.5-omni Technical Solutions for Real-Time Interaction Building a model that can ‘talk’ and ‘hear’ in real-time requires solving specific engineering challenges related to streaming stability and conversational flow. ARIA: Adaptive Rate Interleave Alignment A common failure mode in streaming voice interaction is ‘speech instability.’ Because text tokens and speech tokens have different encoding efficiencies, a model may misread numbers or stutter when attempting to synchronize its text reasoning with its audio output. To address this, Alibaba Qwen team developed ARIA (Adaptive Rate Interleave Alignment). This technique dynamically aligns text and speech units during generation. By adjusting the interleave rate based on the density of the information being processed, ARIA improves the naturalness and robustness of speech synthesis without increasing latency. Semantic Interruption and Turn-Taking For AI developers building voice assistants, handling interruptions is notoriously difficult. Qwen3.5-Omni introduces native turn-taking intent recognition. This allows the model to distinguish between ‘backchanneling’ (non-meaningful background noise or listener feedback like ‘uh-huh’) and an actual semantic interruption where the user intends to take the floor. This capability is baked directly into the model’s API, enabling more human-like, full-duplex conversations. Emergent Capability: Audio-Visual Vibe Coding Perhaps the most unique feature identified during the native multimodal scaling of Qwen3.5-Omni is Audio-Visual Vibe Coding. Unlike traditional code generation that relies on text prompts, Qwen3.5-Omni can perform coding tasks based directly on audio-visual instructions. For instance, a developer could record a video of a software UI, verbally describe a bug while pointing at specific elements, and the model can directly generate the fix. This emergence suggests that the model has developed a cross-modal mapping between visual UI hierarchies, verbal intent, and symbolic code logic. Key Takeaways Qwen3.5-Omni uses a native Thinker-Talker multimodal architecture for unified text, audio, and video processing. The model supports 256k context, 10+ hours of audio, and 400+ seconds of 720p video at 1 FPS. Alibaba reports speech recognition in 113 languages/dialects and speech generation in 36 languages/dialects. Key system features include semantic interruption, turn-taking intent recognition, TMRoPE, and ARIA for realtime interaction. Check out the Technical details, Qwenchat, Online demo on HF and Offline demo on HF. Also, feel free to follow us on Twitter and don’t forget to join our 120k+ ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well. The post Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction appeared first on MarkTechPost.

Alibaba Qwen Team Releases Qwen3.5 Omni: A Native Multimodal Model for Text, Audio, Video, and Realtime Interaction Lire l’article »

AI, Committee, Actualités, Uncategorized

AI benchmarks are broken. Here’s what we need instead.

For decades, artificial intelligence has been evaluated through the question of whether machines outperform humans. From chess to advanced math, from coding to essay writing, the performance of AI models and applications is tested against that of individual humans completing tasks.  This framing is seductive: An AI vs. human comparison on isolated problems with clear right or wrong answers is easy to standardize, compare, and optimize. It generates rankings and headlines.  But there’s a problem: AI is almost never used in the way it is benchmarked. Although   researchers and industry have started to improve benchmarking by moving beyond static tests to more dynamic evaluation methods, these  innovations resolve only part of the issue. That’s because they still evaluate AI’s performance outside the human teams and organizational workflows where its real-world performance ultimately unfolds.  While AI is evaluated at the task level in a vacuum, it is used in messy, complex environments where it usually interacts with more than one person. Its performance (or lack thereof) emerges only over extended periods of use. This misalignment leaves us misunderstanding AI’s capabilities, overlooking systemic risks, and misjudging its economic and social consequences. To mitigate this, it’s time to shift from narrow methods to benchmarks that assess how AI systems perform over longer time horizons within human teams, workflows, and organizations. I have studied real-world AI deployment since 2022 in small businesses and health, humanitarian, nonprofit, and higher-education organizations in the UK, the United States, and Asia, as well as within leading AI design ecosystems in London and Silicon Valley. I propose a different approach, which I call HAIC benchmarks—Human–AI, Context-Specific Evaluation. What happens when AI fails  For governments and businesses, AI benchmark scores appear more objective than vendor claims. They’re a critical part of determining whether an AI model or application is “good enough” for real-world deployment. Imagine an AI model that achieves impressive technical scores on the most cutting-edge benchmarks—98% accuracy, groundbreaking speed, compelling outputs. On the strength of these results, organizations may decide to adopt the model, committing sizable financial and technical resources to purchasing and integrating it.  But then, once it’s adopted, the gap between benchmark and real-world performance quickly becomes visible. For example, take the swathe of FDA-approved AI models that can read medical scans faster and more accurately than an expert radiologist. In the radiology units of hospitals from the heart of California to the outskirts of London, I witnessed staff using highly ranked radiology AI applications. Repeatedly, it took them extra time to interpret AI’s outputs alongside hospital-specific reporting standards and nation-specific regulatory requirements. What appeared as a productivity-enhancing AI tool when tested in a vacuum introduced delays in practice.  It soon became clear that the benchmark tests on which medical AI models are assessed do not capture how medical decisions are actually made. Hospitals rely on multidisciplinary teams—radiologists, oncologists, physicists, nurses—who jointly review patients. Treatment planning rarely hinges on a static decision; it evolves as new information emerges over days or weeks. Decisions often arise through constructive debate and trade-offs between professional standards, patient preferences, and the shared goal of long-term patient well-being. No wonder even highly scored AI models struggle to deliver the promised performance once they encounter the complex, collaborative processes of real clinical care. The same pattern emerges in my research across other sectors: When embedded within real-world work environments, even AI models that perform brilliantly on standardized tests don’t perform as promised.  When high benchmark scores fail to translate into real-world performance, even the most highly scored AI is soon abandoned to what I call the “AI graveyard.” The costs are significant: Time, effort and money end up being wasted. And over time, repeated experiences like this erode organizational confidence in AI and—in critical settings such as health—may erode broader public trust in the technology as well.  When current benchmarks provide only a partial and potentially misleading signal of an AI model’s readiness for real-world use, this creates regulatory blind spots: Oversight is shaped by metrics that do not reflect reality. It also leaves organizations and governments to shoulder the risks of testing AI in sensitive real-world settings, often with limited resources and support.  How to build better tests  To close the gap between benchmark and real-world performance, we must pay attention to the actual conditions in which AI models will be used. The critical questions: Can AI function as a productive participant within human teams? And can it generate sustained, collective value?  Through my research on AI deployment across multiple sectors, I have seen a number of organizations already moving—deliberately and experimentally—toward the HAIC benchmarks I favor.  HAIC benchmarks reframe current benchmarking in four ways:  1.     From individual and single-task performance to team and workflow performance (shifting the unit of analysis) 2.     From one-off testing with right/wrong answers to long-term impacts (expanding the time horizon) 3.     From correctness and speed to organizational outcomes, coordination quality, and error detectability (expanding outcome measures) 4.     From isolated outputs to upstream and downstream consequences (system effects) Across the organizations where this approach has emerged and started to be applied, the first step is shifting the unit of analysis.  For example, in one UK hospital system in the period 2021–2024, the question expanded from whether a medical AI application improves diagnostic accuracy to how the presence of AI within the hospital’s multidisciplinary teams affects not only accuracy but also coordination and deliberation. The hospital specifically assessed coordination and deliberation in human teams using and not using AI. Multiple stakeholders (within and outside the hospital) decided on metrics like how AI influences collective reasoning, whether it surfaces overlooked considerations, whether it strengthens or weakens coordination, and whether it changes established risk and compliance practices.  This shift is fundamental. It matters a lot in high-stakes contexts where system-level effects matter more than task-level accuracy. It also matters for the economy. It may help recalibrate inflated expectations of sweeping productivity gains that are so far predicated largely on the

AI benchmarks are broken. Here’s what we need instead. Lire l’article »

We use cookies to improve your experience and performance on our website. You can learn more at Politique de confidentialité and manage your privacy settings by clicking Settings.

Privacy Preferences

You can choose your cookie settings by turning on/off each type of cookie as you wish, except for essential cookies.

Allow All
Manage Consent Preferences
  • Always Active

Save
fr_FR